DCM Projects for data pipelines
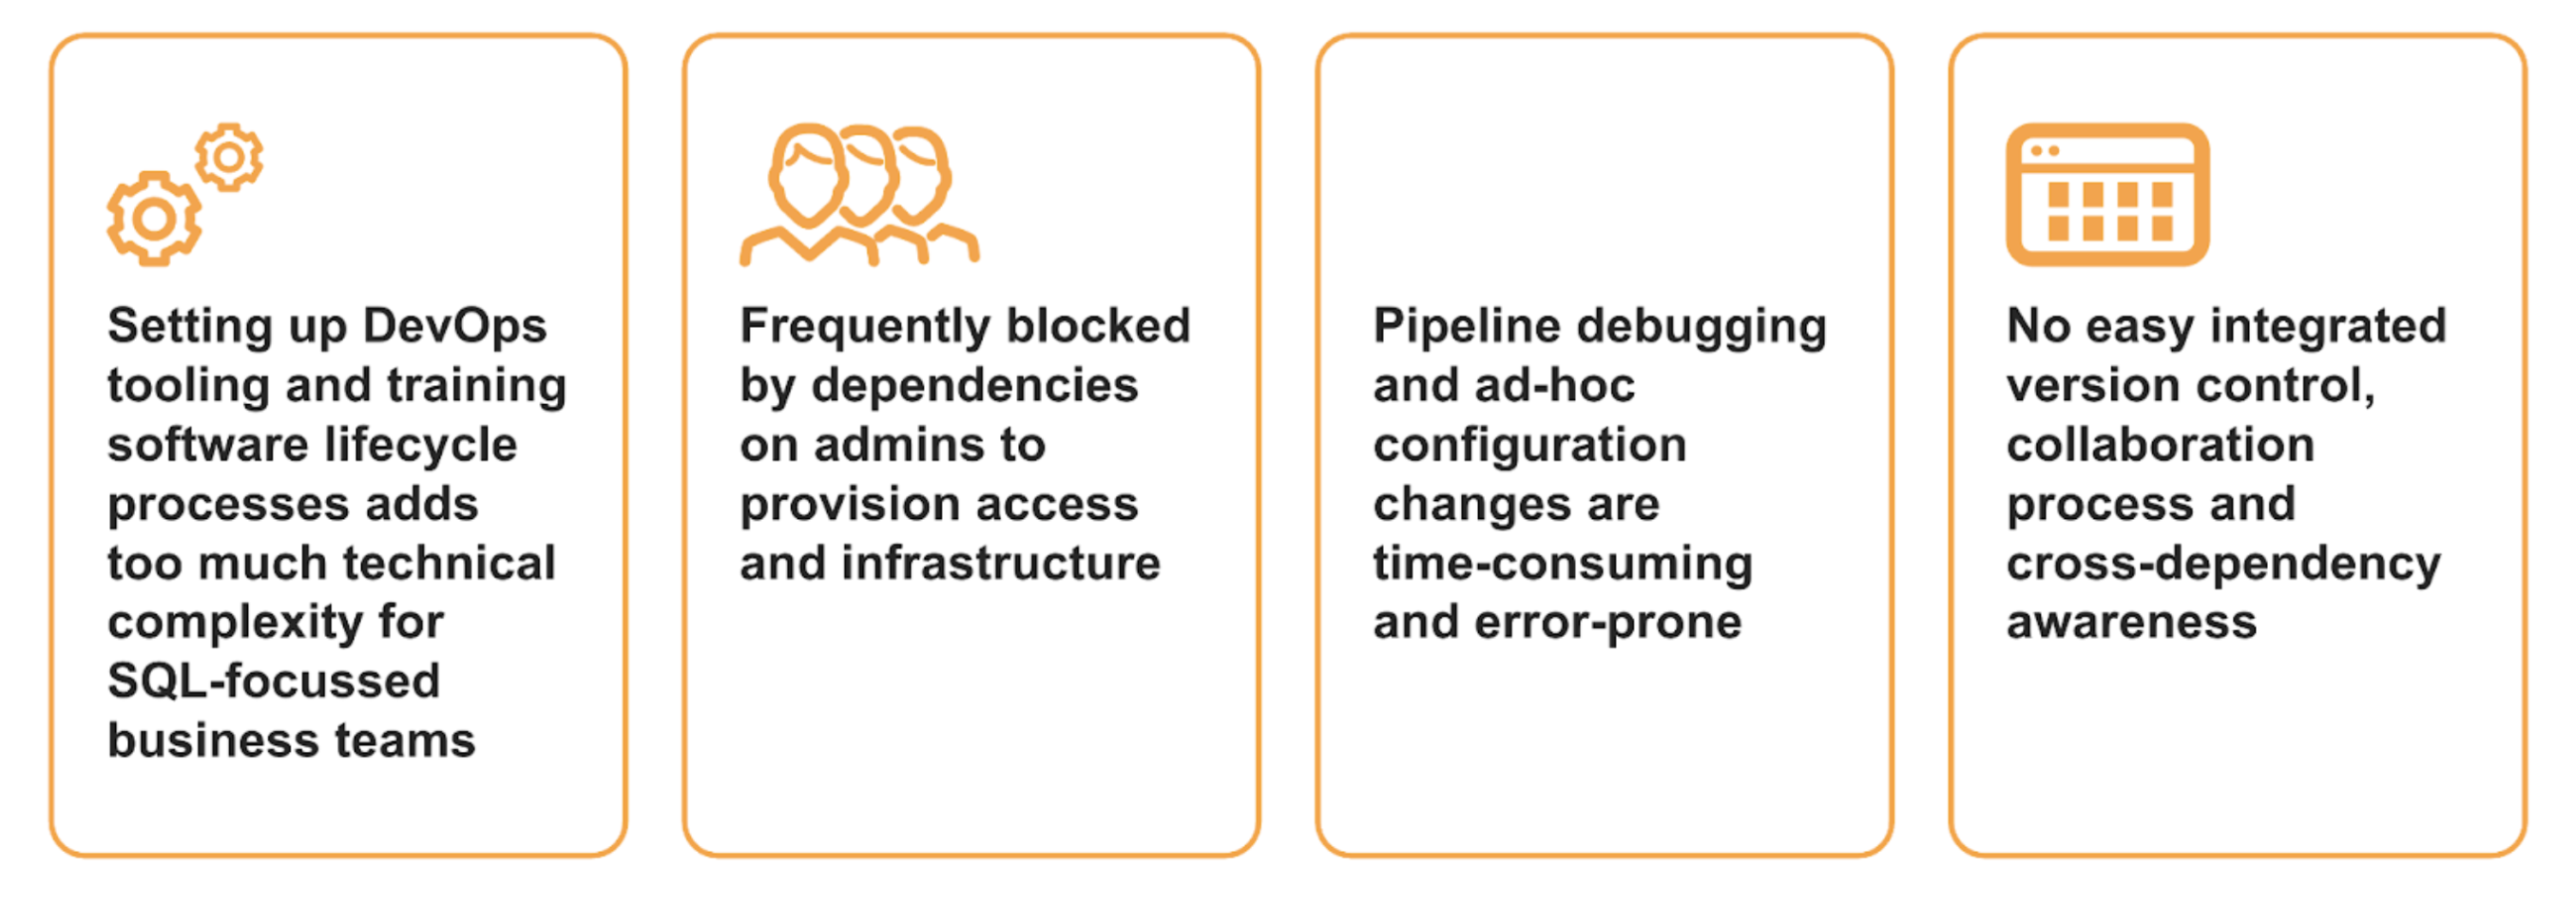
DCM Projects help address the following challenges that feature teams often encounter:
Business units that want to easily author and manage their data pipelines can use DCM Projects to define, test, deploy, and iterate over their business logic.
You can:
- Manage Snowflake object types like tables, dynamic tables, views, warehouses, roles, grants, data metric functions, and expectations all in one project.
- Test and deploy incremental changes to pipelines. You can change configurations, implement transformation logic, and add columns and views.
- Preview data samples to validate transformation logic before deploying objects.
- Deploy the same pipeline definition to multiple environments.
For step-by-step examples, see the following developer guides:
- Build data pipelines with Snowflake DCM Projects
- DCM Projects for dynamic tables
- DCM Projects for tasks
Pipelines that combine multiple object types
A single DCM project can define a pipeline that spans ingestion, transformation, orchestration, and the semantic layer, so you can plan and deploy all of its objects together:
- Ingestion: Define pipes to load data and streams to capture changes.
- Declarative transformation: Define dynamic tables and views.
- Orchestration: Define tasks and task
graphs that schedule and run the following:
- Procedures.
- Code Bundles (preview), which package notebooks and other non-SQL code that the DCM project defines and deploys.
- dbt models or entire dbt projects, by running EXECUTE DBT PROJECT.
- Manual refreshes of dynamic tables.
- Semantic layer: Define semantic views on top of the transformed data.
Pipeline Builder
Pipeline Builder is a visual, AI-assisted designer in Workspaces for defining the scheduling and orchestration of data pipelines. You add notebooks, Python files, ML Jobs, and SQL to a canvas, connect them to set the order they run in, and configure schedules and compute. Pipeline Builder then generates the tasks, task graphs, and Code Bundles for you.
Each pipeline that you build in Pipeline Builder is a DCM project, so you can start with Pipeline Builder to simplify creating and configuring the project, and then switch to the DCM Projects interface to extend and configure the same project manually. For example, you can add dynamic tables, views, schemas, warehouses, roles, grants, procedures, or functions to the project’s definition files, and then plan and deploy all objects together.
How Pipeline Builder definitions coexist with SQL definitions
Pipeline Builder writes the pipeline to a dedicated YAML definition file inside the sources/definitions/ folder of the project, and it
maintains that file as you edit the canvas. This YAML file can complement any other SQL definition files in the project, whether they
existed before or you add them later. The YAML file and the SQL definition files can’t overlap: each object must be defined in exactly one
place, so you can’t define the same object in both the Pipeline Builder YAML file and a SQL definition file.
Pipeline Builder only renders the tasks and task graphs that are defined in its YAML file. If you open an existing DCM project in Pipeline Builder, tasks and scheduling dependencies that are defined in SQL definition files don’t appear on the canvas.
For details about building and deploying pipelines, see Build and configure pipelines with Pipeline Builder and Deploy, run, and monitor pipelines.
Recommendations for pipeline objects
- Dynamic tables: Define dynamic tables with
INITIALIZE = ON_SCHEDULErather thanINITIALIZE = ON_CREATE. WithON_CREATE, each new dynamic table is initialized during deployment, which can significantly prolong the deployment. - Tasks and task graphs: Specify the target state of each task as
STARTEDorSUSPENDEDin its definition. Newly deployed tasks are suspended by default, so tasks that should run on their schedule after deployment need theSTARTEDtarget state. For details, see Task.
Pipeline-specific commands
DCM Projects provide a full-lifecycle developer experience that includes capabilities tailored to managing data pipelines.
The pipeline-specific commands don’t apply to all object types. They extend the core commands for the following pipeline use cases:
- TEST command for data quality expectations attached to managed objects.
- PREVIEW command for checking sample output from a dynamic table, view, or table before deploying.
TEST command for data quality expectations
You can set data quality expectations as quality gates on all stages of your data transformation:
- Attach expectations to raw data in your bronze layer landing tables to ensure your raw input meets expectations and does not cause errors during transformation.
- Attach expectations as quality gates to your silver layer to make it easier to debug data issues by having checkpoints at different transformation stages.
- Attach expectations to your gold layer to ensure the output quality of your data product.
- Attach expectations from downstream consumers of your data product to your gold layer so you can validate those expectations before deploying breaking changes.
See ATTACH Data Metric Function for how to attach expectations in DCM projects.
You can test all data quality expectations attached to tables, dynamic tables, or views that are managed by the DCM project with one command.
Data metric functions that are attached without expectations are not checked.
Run TEST after your tasks and dynamic tables have finished processing new data. TEST evaluates the current state of the data in your environment, so running it before your pipelines have processed new transformation logic may produce results that don’t reflect your latest changes.
You can use the CLI commands to set up automated testing as part of your CI/CD workflow. For example, if you have production-like data on a QA, test, or staging environment, you can follow these steps:
- PLAN against QA to verify the expected project definition changes.
- DEPLOY to QA.
- Allow your tasks and dynamic tables to process new data.
- TEST ALL data quality expectations attached to table objects on the QA environment to verify that the newly deployed logic works as expected and has no negative side effects on the expected shape of your data output.
- If all expectations are met on QA, continue with PLAN and DEPLOY to your production environment.
To run the TEST command:
For the TEST ALL output format, including the JSON schema and examples, see the TEST ALL output section of the EXECUTE DCM PROJECT command reference.
PREVIEW command
When you write or alter the SELECT statement of a dynamic table or view, a sample output helps validate the shape of the data. For complex lineage graphs with multiple transformation steps, you can check the output of a downstream view or dynamic table when making changes further upstream.
To validate that the transformation in your code results in the expected data output before deploying, run the PREVIEW command.
The PREVIEW command runs PLAN to compile the current definitions, independent of any deployed state, and then returns a data sample for a specified dynamic table, view, or regular table.
Keep the following requirements and considerations in mind:
- The PREVIEW command must always reference a fully qualified name of a table object, without Jinja variables.
- To see sample data in the output, you must ensure that data is already available in the source tables.
- PREVIEW queries all SELECT statements of referenced dynamic tables and views, but it does not run tasks or CREATE TABLE AS SELECT statements.
To run the PREVIEW command: