## General Overview pages, getting started guides, and general documentation. --- title: Alerts and Notifications source: https://docs.snowflake.cn/en/guides-overview-alerts.md section: General --- # Alerts and Notifications You can use Snowflake alerts to send notifications and perform actions automatically. In SQL, you can send a notification to an email address or queue by calling a built-in stored procedure.
[Snowflake Alerts](/user-guide/alerts)
If you need to send a notification or perform an action when data in Snowflake meets certain conditions, you can set up a Snowflake Alert. You can also [pass configuration values](#label-alerts-config) to an alert to parameterize its condition and action logic. Learn how to create, configure, and maintain Snowflake alerts.
[Notifications in Snowflake](/user-guide/notifications/about-notifications)
You can configure Snowflake to send notifications about [Snowpipe](/user-guide/data-load-snowpipe-intro) and [task](/user-guide/tasks-intro) errors to a cloud provider queue (Amazon SNS, Microsoft Azure Event Grid, or Google Cloud Pub/Sub). You can also use a SQL statement to send a notification to an email address, a cloud provider queue, or a webhook. Learn how to configure Snowflake to send notifications.
--- title: API Reference source: https://docs.snowflake.cn/en/api-reference.md section: General --- # API Reference These topics provide reference information for the APIs available in Snowflake. **APIs for connecting to Snowflake**
Connector / Driver / Client API Resources Go Driver - [Developer Guide](/developer-guide/golang/go-driver) - API Reference (https://pkg.go.dev/github.com/snowflakedb/gosnowflake#pkg-index) JDBC Driver - [Developer Guide](/developer-guide/jdbc/jdbc) - [JDBC API Support Reference](/developer-guide/jdbc/jdbc-api) .NET Driver - [Developer Guide](/developer-guide/dotnet/dotnet-driver) - Source code in GitHub (https://github.com/snowflakedb/snowflake-connector-net/) Node.js Driver - [Developer Guide](/developer-guide/node-js/nodejs-driver) - Source code in GitHub (https://github.com/snowflakedb/snowflake-connector-nodejs/) ODBC Driver - [Developer Guide](/developer-guide/odbc/odbc) - [ODBC Driver API Support Reference](/developer-guide/odbc/odbc-api) PHP PDO Driver - [Developer Guide](/developer-guide/php-pdo/php-pdo-driver) - Source code in GitHub (https://github.com/snowflakedb/pdo_snowflake/) Snowflake Connector for Kafka - [Developer Guide](/user-guide/kafka-connector/index) - Source code in GitHub (https://github.com/snowflakedb/snowflake-kafka-connector) Snowflake Connector for Python - [Developer Guide](/developer-guide/python-connector/python-connector) - [API Reference](/developer-guide/python-connector/python-connector-api) - Getting Started With Python (https://quickstarts.snowflake.com/guide/getting_started_with_python/index.html?index=..%2F..index) Snowflake Connector for Spark - [Developer Guide](/user-guide/spark-connector) - Source code in GitHub (https://github.com/snowflakedb/spark-snowflake) %sf-python% - [Developer Guide](/developer-guide/snowflake-python-api/snowflake-python-overview) - [API Reference](developer-guide/snowflake-python-api/reference/latest/index) %sf-rest% - [Developer Guide](/developer-guide/snowflake-rest-api/snowflake-rest-api) - [API Reference](developer-guide/snowflake-rest-api/reference) Snowflake SQL API - [Developer Guide](/developer-guide/sql-api/index) - [API Reference](/developer-guide/sql-api/reference) - SQL API Playground (https://api.developers.snowflake.com/)
**APIs for extending Snowflake:**
Extensibility Feature Resources User-Defined Functions (UDFs) - [Developer Guide](/developer-guide/udf/udf-overview) - Getting Started With User-Defined Functions (https://quickstarts.snowflake.com/guide/getting_started_with_user_defined_functions/index.html?index=..%2F..index) Snowpark for Scala - [Developer Guide](/developer-guide/snowpark/scala/index) - [API Reference](developer-guide/snowpark/reference/scala/com/snowflake/snowpark/index.html) - Getting Started With Snowpark in Scala (https://quickstarts.snowflake.com/guide/getting_started_with_snowpark_scala/index.html) Snowpark for Java - [Developer Guide](/developer-guide/snowpark/java/index) - [API Reference](developer-guide/snowpark/reference/java/index.html) Snowpark for Python - [Developer Guide](/developer-guide/snowpark/python/index) - [API Reference](/developer-guide/snowpark/reference/python/latest/index.html) Snowflake ML for Python - [Developer Guide](/developer-guide/snowflake-ml/overview) - [API Reference](/developer-guide/snowpark-ml/reference/latest/index.html) External Functions - [Developer Guide](/sql-reference/external-functions) Stored Procedures - [Developer Guide](/developer-guide/stored-procedure/stored-procedures-overview) - [API Reference](/developer-guide/stored-procedure/stored-procedures-api)
--- title: Appendices source: https://docs.snowflake.cn/en/appendices.md section: General --- # Appendices - [Notational conventions](/sql-reference/conventions) Notational conventions used in the Snowflake documentation. - [Reserved & limited keywords](/sql-reference/reserved-keywords) List of words reserved for Snowflake SQL. --- title: Applications and tools for connecting to Snowflake source: https://docs.snowflake.cn/en/guides-overview-connecting.md section: General --- # Applications and tools for connecting to Snowflake Snowflake provides several different applications and tools that you can use to access databases in Snowflake. For information about configuring clients, driver, libraries, and third-party applications to connect to Snowflake, see [Configuring a client, driver, library, or third-party application to connect to Snowflake](/user-guide/gen-conn-config). ## User interface
[Snowsight: The Snowflake web interface](/user-guide/ui-snowsight)
%sf-web-interface% distills Snowflake's powerful SQL support into a unified, easy-to-use experience. Use %sf-web-interface% to perform your critical Snowflake operations.
## Command-line clients
[Snowflake CLI](/developer-guide/snowflake-cli/index)
Use the command line to create, manage, update, and view apps running on Snowflake across workloads.
## Extensions for code editors
[Snowflake Extension for Visual Studio Code](/user-guide/vscode-ext)
Use the %sf-vscext% to connect to Snowflake within Visual Studio Code and perform SQL operations.
## Infrastructure as code The following content is not supported by Snowflake. All code is provided "AS IS" and without warranty.
[Snowflake Terraform provider](/user-guide/terraform)
Documentation and resources for the Snowflake Terraform provider.
## Drivers and libraries
[API Reference](/api-reference)
Lists the drivers and APIs provided by Snowflake for writing applications that connect to Snowflake.
## Integrating with third-party systems
[Snowflake Connectors](https://other-docs.snowflake.cn/connectors.html)
Snowflake Connectors allow you to integrate third-party applications and database systems with Snowflake.
## Third-party software
[Snowflake Ecosystem](/user-guide/ecosystem)
Overview of the third-party tools and technologies, as well as the Snowflake-provided clients, in the Snowflake ecosystem.
--- title: Cost & billing source: https://docs.snowflake.cn/en/guides-overview-cost.md section: General --- # Cost & billing Snowflake provides a robust framework to manage costs. You can also obtain monthly usage statements and reconcile those statements with usage data in views. ## Cost management
[Managing cost in Snowflake](/user-guide/cost-management-overview)
Snowflake's cost management framework helps you manage costs across the dimensions of visibility, control, and optimization. Learn about the framework and the features that support each part of it.
[Understanding overall cost](/user-guide/cost-understanding-overall)
The total cost of using Snowflake is the aggregate of the cost of using data transfer, storage, and compute resources. Learn about how overall cost is calculated.
[Exploring overall cost](/user-guide/cost-exploring-overall)
Snowsight allows you to quickly and easily obtain information about cost from a visual dashboard. Queries against the usage views allow you to drill down into cost data and can help generate custom reports and dashboards. Learn about exploring your spend using various queries to return cost information.
[Introduction to cost anomalies](/user-guide/cost-anomalies)
A cost anomaly occurs when daily consumption falls outside the expected range. Snowflake automatically detects these anomalies and provides tools to help you investigate the root cause. Learn how to identify and investigate cost anomalies at the account and organization level.
[Optimizing cost](/user-guide/cost-optimize)
Learn how to optimize Snowflake in order to reduce costs and maximize your spend.
[Attributing cost](/user-guide/cost-attributing)
Gain insight into Snowflake cost by attributing those costs to logical units within the organization such as departments, environments or other entities. Learn how to attribute cost to differing entities within your organization.
[Controlling cost](/user-guide/cost-controlling)
Cost controls allow you to limit how much is spent on various services such as virtual warehouses. [Budgets](/user-guide/budgets) allow you to monitor the credit usage of supported objects and serverless features in your account. [Resource monitors](/user-guide/resource-monitors) allow you to monitor credit usage by user-managed virtual warehouses and the cloud services layer of the Snowflake architecture.
[Access control for cost management](/user-guide/cost-access-control)
Snowflake provides system-defined roles that grant access to cost management features. Learn about the roles that control access to cost management features.
## Billing
[Access billing invoices](/user-guide/billing-invoices)
Learn how to use %sf-web-interface% to view and download billing invoices.
[Access payment history](/user-guide/billing-payment-history)
Learn how to use %sf-web-interface% to view payment activity, including charges, refunds, and authorization holds.
[Access a billing usage statement](/user-guide/billing-usage-statement)
Learn how to use %sf-web-interface% to view and download monthly usage statements.
[Reconcile a billing usage statement](/user-guide/billing-reconcile)
Learn how to execute queries to reconcile usage data shown on a usage statement with data in the billing views of the Organization Usage schema.
[Update billing contact information](/user-guide/billing-contacts)
Learn how to use %sf-web-interface% to update billing contact information.
--- title: Data Governance in Snowflake source: https://docs.snowflake.cn/en/guides-overview-govern.md section: General --- # Data Governance in Snowflake Snowflake provides industry-leading features that ensure the highest levels of governance for your account and users, as well as all the data you store and access in Snowflake.
[Data Quality Monitoring and data metric functions](/user-guide/data-quality-intro)
Allows the monitoring of the state and integrity of your data using system data metric functions and user-defined data metric functions.
[Column-level Security](/user-guide/security-column-intro)
Allows the application of a masking policy to a column within a table or view.
[Row-level Security](/user-guide/security-row-intro)
Allows the application of a row access policy to a table or view to determine which rows are visible in the query result.
[Introduction to object tagging](/user-guide/object-tagging/introduction)
Allows the tracking of sensitive data for compliance, discovery, protection, and resource usage.
[Tag-based masking policies](/user-guide/tag-based-masking-policies)
Allows protecting column data by assigning a masking policy to a tag and then setting the tag on a database object or the Snowflake account.
[Sensitive data classification](/user-guide/classify-intro)
Allows categorizing potentially personal and/or sensitive data to support compliance and privacy regulations.
[Access History](/user-guide/access-history)
Allows the auditing of the user access history through the Account Usage [ACCESS_HISTORY view](/sql-reference/account-usage/access_history).
[Object Dependencies](/user-guide/object-dependencies)
Allows the auditing of how one object references another object by its metadata (e.g. creating a view depends on a table name and column names) through the Account Usage [OBJECT_DEPENDENCIES](/sql-reference/account-usage/object_dependencies) view.
Data Governance area in %sf-web-interface%
Allows you to use **Governance & security** on %sf-web-interface% to access governance features. For details, see: - [](#label-data-protection-policies-get-started) - [](#label-object-tagging-create-tag-snowsight) - [](#label-object-tagging-snowsight) - [](#label-object-tagging-assign-ui) - [](#label-security-column-intro-snowsight) - [](#label-security-row-intro-snowsight)
--- title: Data sharing and collaboration in Snowflake source: https://docs.snowflake.cn/en/guides-overview-sharing.md section: General --- # Data sharing and collaboration in Snowflake - [Snowflake Marketplace and Listings](/user-guide/data-marketplace) - [About Secure Data Sharing](/user-guide/data-sharing-intro) - [Share data in non-secured views](/user-guide/data-sharing-views) - [About Data Exchange](/user-guide/data-exchange) - [Snowflake Data Clean Rooms](https://other-docs.snowflake.cn/en/cleanrooms/introduction) There are many ways to share data from your Snowflake account with users in other Snowflake accounts, including collaborating with other parties in a secure environment. ## Why share data with Snowflake When you use Snowflake to share data as a provider, you can manage who has access to your data, and avoid challenges keeping your data synchronized across different people and groups. As a data consumer, you can reduce the data transformations you need to perform because the data stays in Snowflake, making it easy to join datasets shared with you with your own data. If you share your data using listings, you can include metadata with your data share, such as a title and description, and usage examples to help consumers use the data quickly. In addition to the benefits for consumers, as a provider you get access to usage data, automatically replicate your data to other regions, and can even decide to charge for access to your data or offer some datasets publicly on the %sf-marketplace%. ## Options for sharing Listings let you share data with people in any Snowflake region, across clouds, without performing manual replication tasks. If you use listings, you can provide additional metadata for the data that you share, view customer data usage, and for listings offered publicly on the %sf-marketplace%, gauge consumer interest in your listings. If you don't want to share data using a listing, you can use a direct share instead, see [Secure data sharing](/user-guide/data-sharing-intro) and [Non-secure data sharing](/user-guide/data-sharing-views). No matter which option you choose, you can share with people who don't have Snowflake accounts by using [Reader Accounts](/user-guide/data-sharing-reader-create).
Data Sharing Mechanism Share With Whom? Auto-fulfill Across Clouds? Optionally Charge for Data? Optionally Offer Data Publicly? Get Consumer Usage Metrics? [](#label-about-listings) One or more accounts in any region Yes Yes Yes Yes [](#label-about-direct-share) One or more accounts in your region No No No No
If you want to manage a group of accounts, and control who can publish and consume listings in that group, consider using a [](#label-about-data-exchange). ## Listing You can offer a listing privately to specific accounts, or publicly on the %sf-marketplace%. For more about the %sf-marketplace%, see [About Snowflake Marketplace](/collaboration/collaboration-marketplace-about). After you accept the provider and consumer terms, you can start sharing and consuming data shared with you with a listing. For more information, see [About listings](https://other-docs.snowflake.cn/en/collaboration/collaboration-listings-about). To learn more about sharing listings to or from [](#label-snowflake-editions-vps), see [About collaboration in VPS environments](/collaboration/virtual-private-snowflake/about-vps-collaboration). ## Direct share Use a direct share to share data with one or more accounts in the same Snowflake region. You don't need to copy or move data shared with a direct share. If you want to convert a direct share with active consumers to a listing, see [Convert a direct share to a listing](https://other-docs.snowflake.cn/en/collaboration/provider-listings-creating-publishing#convert-a-direct-share-to-a-private-listing). For more information, see [Share secure database objects](/user-guide/data-sharing-gs). ## Open Data Sharing Open Data Sharing in Snowflake expands traditional data sharing beyond the Snowflake ecosystem. This capability allows you to securely share live, read-only data assets with consumers who do not use Snowflake, eliminating the need for complex ETL pipelines, data duplication, or manual file exports. For more information, see [Open Data Sharing](/user-guide/open-data-sharing). ## Data Exchange If creating listings that you offer privately to specific accounts isn't an option, you can use a data exchange to share data with a selected group of accounts that you invite. You must request that a data exchange be provisioned and configured for your account, then you can invite members to the exchange and specify whether they can consume data, provide data, or both. For more information, see [About Data Exchange](/user-guide/data-exchange). ## Collaborating with shared data in a secure environment When you use listings, direct shares, and Data Exchange to share data with another party, they can directly access the data. If you want to share data with other parties, but want to control how that data is accessed, you can use a %samooha-clean-room% to collaborate. The provider who is sharing their data in a clean room defines what analyses can be run against the shared data, which allows the consumer to gather insights from the data without having unrestricted access to it. For more information, see [Overview of Snowflake Data Clean Rooms](/user-guide/cleanrooms/overview). --- title: Databases, Tables and Views - Overview source: https://docs.snowflake.cn/en/guides-overview-db.md section: General --- # Databases, Tables and Views - Overview - [Data Definition Language (DDL) commands](/sql-reference/sql-ddl-summary) - [Managing Snowflake databases, schemas, tables, and views with Python](/developer-guide/snowflake-python-api/snowflake-python-managing-databases) All data in Snowflake is maintained in databases. Each database consists of one or more schemas, which are logical groupings of database objects, such as tables and views. Snowflake does not place any hard limits on the number of databases, schemas (within a database), or objects (within a schema) you can create. Use the following pages to learn about tables and table types, views, design considerations and other related content.
[Understanding Snowflake Table Structures](/user-guide/tables-micro-partitions)
Introduction to *micro-partitions* and *data clustering*, two of the principal concepts utilized in Snowflake physical table structures.
[Temporary and Transient Tables](/user-guide/tables-temp-transient)
Snowflake supports creating temporary tables for storing non-permanent, transitory data such as ETL data, session-specific or other short lived data.
[External Tables](/user-guide/tables-external-intro)
Snowflake supports the concept of an external table. External tables are read-only, and their files are stored in an external stage.
[Hybrid Tables](/user-guide/tables-hybrid)
Snowflake supports the concept of a hybrid table. Hybrid tables provide optimized performance for read and write operations in transactional and hybrid workloads.
[Apache Iceberg™ tables](/user-guide/tables-iceberg)
Snowflake supports the %iceberg-tm% open table format. Iceberg tables use data in external cloud storage and give you the option to use Snowflake as the Iceberg catalog, an external Iceberg catalog, or to create a table from files in object storage.
[Views](/user-guide/views-introduction)
A view allows the result of a query to be accessed as if it were a table. Views serve a variety of purposes, including combining, segregating, and protecting data.
[Secure Views](/user-guide/views-secure)
Snowflake supports the concept of a secure view. Secure views are specifically designed for data privacy. For example to limit access to sensitive data that should not be exposed to all users of the underlying table(s).
[Materialized Views](/user-guide/views-materialized)
Materialized views are views precomputed from data derived from a query specification and stored for later use. Querying a materialized view is faster than executing a query against the base table of the view because the data is pre-computed.
[Table Design Best Practices](/user-guide/table-considerations)
Best practices, general guidelines, and important considerations when designing and managing tables.
[Cloning Best Practices](/user-guide/object-clone)
Best practices, general guidelines, and important considerations when cloning objects in Snowflake, particularly databases, schemas, and permanent tables.
[Data storage considerations](/user-guide/tables-storage-considerations)
Best practices and guidelines for controlling data storage costs associated with Continuous Data Protection (CDP), particularly for tables.
--- title: Function and stored procedure reference source: https://docs.snowflake.cn/en/sql-reference-functions.md section: General --- # Function and stored procedure reference - [Writing external functions](/sql-reference/external-functions) - [User-defined functions overview](/developer-guide/udf/udf-overview) These topics provide reference information for the system-defined functions and system-defined stored procedures. - [Summary of functions](/sql-reference/intro-summary-operators-functions) — combined summary of all system-defined functions. Can be used as a quick-reference. - [All functions (alphabetical)](/sql-reference/functions-all) — alphabetical list of all system-defined functions (scalar, aggregate, table, etc.). - [Aggregate functions](/sql-reference/functions-aggregation) — functions that take multiple rows/values as input and return a single value. - [Scalar functions](/sql-reference/functions) — functions that take a single row/value as input and return a single value: - [Bitwise expression functions](/sql-reference/expressions-byte-bit) - [Conditional expression functions](/sql-reference/expressions-conditional) - [Context functions](/sql-reference/functions-context) - [Conversion functions](/sql-reference/functions-conversion) - [Data generation functions](/sql-reference/functions-data-generation) - [Date & time functions](/sql-reference/functions-date-time) - [Differential privacy functions](/sql-reference/functions-differential-privacy) - [Encryption functions](/sql-reference/functions-encryption) - [Geospatial functions](/sql-reference/functions-geospatial) - [Hash functions](/sql-reference/functions-hash-scalar) - [Metadata functions](/sql-reference/functions-metadata) - [Notification functions](/sql-reference/functions-notification) - [Numeric functions](/sql-reference/functions-numeric) - [Semi-structured and structured data functions](/sql-reference/functions-semistructured) - [String functions (regular expressions)](/sql-reference/functions-regexp) — regular expression (search) functions - [String & binary functions](/sql-reference/functions-string) - [Vector functions](/sql-reference/functions-vector) - [Model monitor functions](/sql-reference/functions-model-monitors) — functions that retrieve metrics from machine learning model monitors. - [System functions](/sql-reference/functions-system) — functions that perform control operations or return system-level information. - [Table functions](/sql-reference/functions-table) — functions that return results in tabular format. - [Window functions](/sql-reference/functions-window) — functions that run analytic calculations, such as moving aggregations and rankings. - [Data metric functions](/sql-reference/functions-data-metric) — functions that enable data quality measurements for tables and views. - [Stored procedures](/sql-reference-stored-procedures) — stored procedures to facilitate using certain Snowflake features. --- title: Get started with Snowflake for users source: https://docs.snowflake.cn/en/getting-started-for-users.md section: General --- # Get started with Snowflake for users These topics get you started with Snowflake:
[Before you begin](/user-guide/setup)
Overview of getting an account and methods for accessing Snowflake.
[Sign in to Snowflake](/user-guide/connecting)
Overview of the different ways to connect to Snowflake.
[Snowflake key concepts and architecture](/user-guide/intro-key-concepts)
Description of Snowflake architecture, key concepts, and features.
[Snowsight quick tour](/user-guide/ui-snowsight-quick-tour)
Overview of %sf-web-interface%, Snowflake's web-based interface.
[Overview of the data lifecycle](/user-guide/data-lifecycle)
Introduces the main operations and corresponding SQL commands for getting your data into Snowflake and then using it to perform queries and other SQL operations.
--- title: Key concepts for Snowflake administrators source: https://docs.snowflake.cn/en/concepts-for-administrators.md section: General --- # Key concepts for Snowflake administrators These topics cover key concepts related to administering Snowflake. ## Cloud platforms and regions These topics describe the cloud infrastructure on which Snowflake runs:
[Supported cloud platforms](/user-guide/intro-cloud-platforms)
Describes the cloud computing platforms on which Snowflake is offered, which include Amazon Web Services (AWS), Google Cloud, and Microsoft Azure.
[Supported cloud regions](/user-guide/intro-regions)
Describes the different cloud platform regions in which Snowflake is offered. This topic helps you choose where your data is geographically stored and your compute resources are provisioned.
## Editions, releases, and features
[Snowflake editions](/user-guide/intro-editions)
Describes the services and features that are included with each edition of Snowflake. This topic helps you choose the right edition for your organization.
[Snowflake releases](/user-guide/intro-releases)
Describes the Snowflake release process and provides instructions for requesting 12-hour early access for Enterprise Edition and Business Critical Edition accounts, or 24-hour early access for Virtual Private Snowflake (VPS) accounts.
[Overview of key features](/user-guide/intro-supported-features)
Lists the key features of Snowflake to help you decide which features you want to use.
## Security and compliance
[Continuous data protection](/user-guide/data-cdp)
Introduces the features that Snowflake provides for ensuring your data is protected, secure, and available.
[Regulatory compliance](/user-guide/intro-compliance)
Describes the major regulatory compliance standards Snowflake meets to ensure the highest levels of data assurance, security, and governance for data in Snowflake.
--- title: Load data into Snowflake source: https://docs.snowflake.cn/en/guides-overview-loading-data.md section: General --- # Load data into Snowflake Data can be loaded into Snowflake in a number of ways. The following topics provide an overview of data loading concepts, tasks, tools, and techniques to quick and easily load data into your Snowflake database. - [Trial SaaS applications from listings](/collaboration/consumer-saas-trials) - [Overview of data unloading](/user-guide/data-unload-overview) - [Data Manipulation Language (DML) commands](/sql-reference/sql-dml) - [Load data into Apache Iceberg™ tables](/user-guide/tables-iceberg-load)
[Overview of data loading](/user-guide/data-load-overview)
Options available to load data into Snowflake.
[Summary of data loading features](/user-guide/intro-summary-loading)
Reference of the supported features for using the [COPY INTO *<table>*](/sql-reference/sql/copy-into-table) command to load data from files.
[Tutorials: Load and query data](/user-guide/data-load-tutorials)
Learn how to load data by using step-by-step instructions in tutorials.
[Data loading considerations](/user-guide/data-load-considerations)
Best practices, general guidelines, and important considerations for bulk data loading.
[Work with Amazon S3-compatible storage](/user-guide/data-load-s3-compatible-storage)
Instructions for accessing data in other storage.
[Load data using Snowsight](/user-guide/data-load-web-ui)
Instructions for loading limited amounts of data using the web interface.
[Introduction to loading semi-structured data](/user-guide/semistructured-intro)
Considerations for loading semi-structured data.
[Introduction to unstructured data](/user-guide/unstructured-intro)
Considerations for loading unstructured data.
[Bulk loading from a local file system](/user-guide/data-load-local-file-system)
Instructions for loading data in bulk using the COPY command.
[Snowpipe](/user-guide/data-load-snowpipe-intro)
Instructions for loading data continuously using Snowpipe.
[Snowpipe Streaming](/user-guide/snowpipe-streaming/data-load-snowpipe-streaming-overview)
Instructions for loading data streams continuously using Snowpipe Streaming.
[Multi-Location Resilience for Data Pipelines](/user-guide/multi-location-resilience-data-pipelines)
Guidance for resilient Snowpipe and COPY INTO data pipelines across locations.
[Transform data during a load](/user-guide/data-load-transform)
Instructions for transforming data while loading it into a table using the COPY INTO command.
[Query data in staged files](/user-guide/querying-stage)
Instructions on using standard SQL to query internal and external named stages.
[Query metadata for staged files](/user-guide/querying-metadata)
Instructions on querying metadata in internal and external stages.
--- title: Managing Snowflake source: https://docs.snowflake.cn/en/user-guide-manage.md section: General --- # Managing Snowflake These topics describe the tasks associated with using Snowflake. - [Virtual warehouses](/user-guide/warehouses) — Key concepts and tasks for creating and using virtual warehouses to execute queries and perform DML operations, such as loading and unloading data: - [Overview of warehouses](/user-guide/warehouses-overview) - [Multi-cluster warehouses](/user-guide/warehouses-multicluster) - [Warehouse considerations](/user-guide/warehouses-considerations) - [Working with warehouses](/user-guide/warehouses-tasks) - [Using the Query Acceleration Service (QAS)](/user-guide/query-acceleration-service) - [Monitoring warehouse load](/user-guide/warehouses-load-monitoring) - [Databases, Tables & Views](/user-guide/databases) — Key concepts and tasks related to understanding and working with Snowflake databases and tables: - [Understanding Snowflake Table Structures](/user-guide/tables-micro-partitions) - [Working with Temporary and Transient Tables](/user-guide/tables-temp-transient) - [Introduction to external tables](/user-guide/tables-external-intro) - [Overview of Views](/user-guide/views-introduction) - [Working with Secure Views](/user-guide/views-secure) - [Working with Materialized Views](/user-guide/views-materialized) - [Table Design Considerations](/user-guide/table-considerations) - [Cloning considerations](/user-guide/object-clone) - [Data storage considerations](/user-guide/tables-storage-considerations) - [Query Data in Snowflake](/guides-overview-queries) — Key concepts and tasks for executing queries in Snowflake: - [Working with joins](/user-guide/querying-joins) - [Understanding How Snowflake Can Eliminate Redundant Joins](/user-guide/join-elimination) - [Working with Subqueries](/user-guide/querying-subqueries) - [Querying Hierarchical Data](/user-guide/queries-hierarchical) - [Working with CTEs (Common Table Expressions)](/user-guide/queries-cte) - [Querying Semi-structured Data](/user-guide/querying-semistructured) - [Analyzing data with window functions](/user-guide/functions-window-using) - [Identifying Sequences of Rows That Match a Pattern](/user-guide/match-recognize-introduction) - [Using Sequences](/user-guide/querying-sequences) - [Using Persisted Query Results](/user-guide/querying-persisted-results) - [Computing the Number of Distinct Values](/user-guide/querying-distinct-counts) - [Estimating Similarity of Two or More Sets](/user-guide/querying-approximate-similarity) - [Estimating Frequent Values](/user-guide/querying-approximate-frequent-values) - [Estimating Percentile Values](/user-guide/querying-approximate-percentile-values) - [Querying data using worksheets](/user-guide/ui-snowsight-query) - [Canceling Statements](/user-guide/querying-cancel-statements) - [Date & time data types](/sql-reference/data-types-datetime) — Reference information and examples for working with dates, times and timestamps, and time zones in Snowflake: - [Date and time input and output formats](/sql-reference/date-time-input-output) - [Working with date and time values](/sql-reference/date-time-examples) - [Introduction to loading semi-structured data](/user-guide/semistructured-intro) — Key concepts and tasks for working with JSON and other types of semi-structured data: - [Introduction to loading semi-structured data](/user-guide/semistructured-intro) - [Supported formats for semi-structured data](/user-guide/semistructured-data-formats) - [Considerations for semi-structured data stored in VARIANT](/user-guide/semistructured-considerations) - [Tutorial: JSON basics for Snowflake](/user-guide/tutorials/json-basics-tutorial) - [Introduction to unstructured data](/user-guide/unstructured-intro) — Key concepts and tasks for working with unstructured data: - [Directory tables](/user-guide/data-load-dirtables) - [REST API for unstructured data support](/user-guide/data-load-unstructured-rest-api) - [Share unstructured data with a secure view](/user-guide/unstructured-data-sharing) - [Troubleshooting processing of unstructured data](/user-guide/unstructured-ts) - [String & binary data types](/sql-reference/data-types-text) — Reference information and examples for working with binary data in Snowflake: - [Binary input and output](/sql-reference/binary-input-output) - [Using binary data](/sql-reference/binary-examples) - [Snowflake Time Travel & Fail-safe](/user-guide/data-availability) — Key concepts and tasks for understanding how Snowflake maintains access to deleted and modified data, and also how Snowflake enables data recovery in the event of loss: - [Understanding & using Time Travel](/user-guide/data-time-travel) - [Understanding and viewing Fail-safe](/user-guide/data-failsafe) - [Storage costs for Time Travel and Fail-safe](/user-guide/data-cdp-storage-costs) - [Introduction to streams and tasks](/user-guide/data-pipelines-intro) — Key concepts and tasks for transforming and optimizing loaded data for analysis: - [Introduction to streams](/user-guide/streams-intro) - [Introduction to tasks](/user-guide/tasks-intro) - [Introduction to dynamic tables](/user-guide/dynamic-tables/overview) - [Introduction to business continuity & disaster recovery](/user-guide/replication-intro) — Key concepts and tasks for replicating and failing over objects across multiple Snowflake accounts, as well as redirecting client connections, for business continuity and disaster recovery: - [Introduction to replication and failover across multiple accounts](/user-guide/account-replication-intro) - [Redirecting client connections](/user-guide/client-redirect) - [Sample data sets](/user-guide/sample-data) — Key concepts and tasks for using the sample data sets provided with Snowflake: - [Use the sample database](/user-guide/sample-data-using) - [Sample data: TPC-H](/user-guide/sample-data-tpch) - [Sample Data: OpenWeatherMap — *Deprecated*](/user-guide/sample-data-openweathermap) --- title: Managing Your Snowflake Account source: https://docs.snowflake.cn/en/user-guide-admin.md section: General --- # Managing Your Snowflake Account - [Securing Snowflake](/guides-overview-secure) These topics describe the administrative concepts and tasks associated with managing your account in Snowflake. These topics are intended primarily for administrators (i.e. users with the ACCOUNTADMIN, SYSADMIN, or SECURITYADMIN roles). - [Account identifiers](/user-guide/admin-account-identifier) Detailed descriptions of the two unique account identifiers supported for connecting to Snowflake and using features that span multiple accounts. - [Trial accounts](/user-guide/admin-trial-account) Instructions for signing up for a trial account, adding a credit card to the account, and canceling the account. - [Parameter management](/user-guide/admin-account-management) Instructions for setting account, session, and object parameters for your account. - [User management](/user-guide/admin-user-management) Instructions for creating and managing users in your account. - [Behavior change management](/release-notes/bcr-bundles/managing-behavior-change-releases) Instructions for enabling and disabling behavior change releases in your account. --- title: ML Functions source: https://docs.snowflake.cn/en/guides-overview-ml-functions.md section: General --- # ML Functions These powerful analysis functions give you automated predictions and insights into your data using machine learning. Snowflake provides an appropriate type of model for each feature, so you don't have to be a machine learning expert to take advantage of them. All you need is your data. ## Time-Series Functions Use time-series functions to train a machine learning model on your time-series data to determine how a specified metric (for example, sales) varies over time and relative to other features of your data. The model then provides insights or predictions based on the trends detected in the data. - [Forecasting](/user-guide/ml-functions/forecasting) predicts future metric values from past trends in time-series data. - [Anomaly Detection](/user-guide/ml-functions/anomaly-detection) flags metric values that differ from typical expectations. ## Other Analysis Functions These features don't require time series data. - [Classification](/user-guide/ml-functions/classification) sort rows into two or more classes based on their most predictive features. - [Top Insights](/user-guide/ml-functions/top-insights) helps you find dimensions and values that affect the metric in surprising ways. ## Cost Considerations When you use ML functions, you incur storage and compute costs. These costs vary depending on the feature used and the quantity of data used in training and prediction. The storage costs you incur reflect storage of the ML model instances created during the training step. To view the objects associated with your model instance, navigate to your [Account Usage views](#label-account-usage-views) (ACCOUNT_USAGE.TABLES and ACCOUNT_USAGE.STAGES). These objects appear with null database and schema columns. The `instance_id` column, however, will be populated, indicating that these objects are contained in a model instance. These objects are fully managed by the model instance, and you cannot access or delete them separately. To reduce storage costs associated with your models, delete unused or obsolete models. See [Understanding compute cost](/user-guide/cost-understanding-compute) for general information on Snowflake compute costs. ## Limitations Before you use ML functions, you must ensure [AUTOCOMMIT](#label-txn-autocommit) is enabled in your session. AUTOCOMMIT is enabled by default when you start a new Snowflake session. ## Using ML functions in Snowpark `session.call` is not yet compatible with models created by ML functions. To call such a model in Snowpark, use `session.sql` instead, as shown here. ```python session.sql('call my_model!FORECAST(...)').collect() ``` --- title: Optimizing performance in Snowflake source: https://docs.snowflake.cn/en/guides-overview-performance.md section: General --- # Optimizing performance in Snowflake - [Managing cost in Snowflake](/user-guide/cost-management-overview) The following topics help guide efforts to improve the performance of Snowflake.
[Exploring execution times](/user-guide/performance-query-exploring)
Gain insights into the historical performance of queries using the web interface or by writing queries against data in the ACCOUNT_USAGE schema.
[Optimizing query performance](/user-guide/performance-query-options)
Learn about options for optimizing Snowflake query performance.
[Optimizing warehouses for performance](/user-guide/performance-query-warehouse)
Learn about strategies to fine-tune computing power in order to improve the performance of a query or set of queries running on a warehouse, including enabling the Query Acceleration Service.
[Optimizing storage for performance](/user-guide/performance-query-storage)
Learn how storing similar data together, creating optimized data structures, and defining specialized data sets can improve the performance of queries. Helpful when choosing between Automatic Clustering, Search Optimization Service, and materialized views.
[Analyzing query workloads with Performance Explorer](/user-guide/performance-explorer)
Learn how to use Performance Explorer in %sf-web-interface% to monitor interactive metrics for SQL workloads.
[Analyze Workload Performance with CoCo](/user-guide/analyze-workload-performance-coco)
Use Cortex Code and the `workload-performance-analysis` bundled skill to analyze SQL query performance through ACCOUNT_USAGE views.
[Snowflake Optima](/user-guide/snowflake-optima)
Learn how Snowflake Optima continuously analyzes workload patterns and implements the most effective strategies automatically.
--- title: Privacy in Snowflake source: https://docs.snowflake.cn/en/guides-overview-privacy.md section: General --- # Privacy in Snowflake Snowflake provides industry-leading features that maintain the privacy of individuals and sensitive data.
[Differential privacy](/user-guide/diff-privacy/differential-privacy-overview)
Protect the identity and information of entities against targeted privacy attacks. Data providers assign privacy policies to tables and views to protect their data with differential privacy.
[Aggregation policies](/user-guide/aggregation-policies)
Require queries to aggregate data in order to return results.
[Join policies](/user-guide/join-policies)
Require queries to join tables in order to return results.
%logo-snowflake-black% [Preview Feature](/release-notes/preview-features) — Open
Available to all accounts that are Enterprise Edition (or higher). To inquire about upgrading, please contact [Snowflake Support](https://docs.snowflake.cn/user-guide/contacting-support).
[Projection policies](/user-guide/projection-policies)
Prevent queries from using a SELECT statement to project values from a column.
[Synthetic data](/user-guide/synthetic-data)
Programmatically create realistic datasets that closely mirror your original data. This allows you to safely represent sensitive, confidential, or restricted information across various workloads, such as testing and validation.
--- title: Query Data in Snowflake source: https://docs.snowflake.cn/en/guides-overview-queries.md section: General --- # Query Data in Snowflake Snowflake supports standard SQL, including a subset of ANSI SQL:1999 and the SQL:2003 analytic extensions. Snowflake also supports common variations for a number of commands where those variations do not conflict with each other. You can use the search optimization service to improve query performance. For details, see [Search optimization service](/user-guide/search-optimization-service).
[Working with joins](/user-guide/querying-joins)
A join combines rows from two tables to create a new combined row that can be used in the query. Learn join concepts, types of joins, and how to work with joins.
[Analyzing time-series data](/user-guide/querying-time-series-data)
Analyze time-series data, using SQL functionality designed for this purpose, such as the ASOF JOIN feature, date and time helper functions, aggregate functions for downsampling, and functions that support sliding window frames. Using ASOF JOIN, learn how to join tables on timestamp columns when their values closely follow each other, precede each other, or match exactly.
[Eliminate Redundant Joins](/user-guide/join-elimination)
A join on a key column can refer to tables that are not needed for the join. Such a join is referred to as a *redundant join*. Learn about redundant joins, and how to eliminate them to improve query performance.
[Working with Subqueries](/user-guide/querying-subqueries)
A subquery is a query within another query. Learn about subqueries and how to use them.
[Querying Hierarchical Data](/user-guide/queries-hierarchical)
Relational databases often store hierarchical data by using different tables. Learn about querying hierarchical data using joins, Common Table Expressions(CTEs) and CONNECT BY.
[Working with CTEs (Common Table Expressions)](/user-guide/queries-cte)
A CTE (common table expression) is a named subquery defined in a WITH clause, the result of which is effectively a table. Learn how to write and work with CTE expressions.
[Querying Semi-structured Data](/user-guide/querying-semistructured)
Semi-structured data represents arbitrary hierarchical data structures, which can be used to load and operate on data in semi-structured formats (e.g. JSON, Avro, ORC, Parquet, or XML). Learn how to use special operators and functions to query complex hierarchical data stored in a VARIANT.
[Using full-text search](/user-guide/querying-with-search-functions)
You can use full-text search to find character data (text) in specified columns from one or more tables, including fields in VARIANT, OBJECT, and ARRAY columns. Learn how to run queries that use full-text search.
[Constructing SQL at runtime](/user-guide/querying-construct-at-runtime)
You can create programs that construct SQL statements dynamically at runtime. Learn about different options for constructing SQL at runtime.
[Analyzing data with window functions](/user-guide/functions-window-using)
Window functions operate on windows, which are groups of rows that are related in some way. Learn about windows, window functions, and how to use window functions to examine data.
[Identifying Sequences of Rows That Match a Pattern](/user-guide/match-recognize-introduction)
In some cases, you might need to identify sequences of table rows that match a pattern. Learn about pattern matching, and how to use MATCH_RECOGNIZE to work with table rows matching patterns.
[Using Sequences](/user-guide/querying-sequences)
Sequences are used to generate unique numbers across sessions and statements, including concurrent statements. Learn what are sequences, and how to use them.
[Using Persisted Query Results](/user-guide/querying-persisted-results)
When a query is executed, the result is persisted for a period of time. Learn how query results are persisted, how long persisted results are available, and how to use persisted query results to improve performance.
[Computing the Number of Distinct Values](/user-guide/querying-distinct-counts)
Various methods exist to determine the count of distinct elements within a column. Learn methods to identify and report distinct elements in data.
[Estimating Similarity of Two or More Sets](/user-guide/querying-approximate-similarity)
Snowflake provides mechanisms to compare data sets for similarity. Learn how Snowflake determines similarity and how to compare multiple data sets for similarity.
[Estimating Frequent Values](/user-guide/querying-approximate-frequent-values)
Snowflake can examine data to determine how frequent values are within the data. Learn how frequency is determined and how to query data to determine data frequency using the through the APPROX_TOP_K family of functions.
[Estimating Percentile Values](/user-guide/querying-approximate-percentile-values)
Snowflake can estimate percentages of values using an improved version of the t-Digest algorithm. Learn how to estimate percentages using the APPROX_PERCENTILE family of functions
[Monitor query activity with Query History](/user-guide/ui-snowsight-activity)
Monitor the query activity in your account. Learn how examine queries, using query profiles, to understand and improve performance.
[Using query insights to improve performance](/user-guide/query-insights)
Review the insights produced for a query. Learn how to improve the performance of a query.
[Using the Query Hash to Identify Patterns and Trends in Queries](/user-guide/query-hash)
To identify patterns and trends in queries, you can use the hash of the query text, which is included in the `query_hash` and `query_parameterized_hash` columns in selected Account Usage view and in the output of selected Information Schema table functions. Learn how to use the query hash in these columns to identify repeated queries and detect patterns and trends in queries.
[Top-K pruning for improved query performance](/user-guide/querying-top-k-pruning-optimization)
Instead of scanning all eligible rows in SELECT statements that contain LIMIT and ORDER BY clauses, SELECT statements that use top-K pruning scan a subset of rows, which can improve performance. Learn how to use top-K pruning to improve the performance of SELECT statements that contain LIMIT and ORDER BY clauses.
[Canceling Statements](/user-guide/querying-cancel-statements)
Executing statements are typically cancelled using the interface used to start the query. Learn how to use system functions to cancel a specific query or all currently executing queries.
--- title: Reference source: https://docs.snowflake.cn/en/reference.md section: General --- # Reference Reference information on various areas of Snowflake.
[SQL data types reference](/sql-reference-data-types)
Reference for SQL data types.
[SQL command reference](/sql-reference-commands)
Reference for SQL commands.
[Function and stored procedure reference](/sql-reference-functions)
Reference for SQL functions.
[SQL class reference](/sql-reference-classes)
Reference for SQL classes.
[Snowflake Scripting reference](/sql-reference-snowflake-scripting)
Reference for [Snowflake Scripting](/developer-guide/snowflake-scripting/index) constructs.
[General reference](/sql-reference)
Reference material on other subjects.
--- title: Securing Snowflake source: https://docs.snowflake.cn/en/guides-overview-secure.md section: General --- # Securing Snowflake Snowflake provides industry-leading features that help ensure you can configure the highest levels of security for your account and users, as well as all the data you store in Snowflake. These topics are intended primarily for administrators (that is, users with the ACCOUNTADMIN, SYSADMIN, or SECURITYADMIN roles). ## Authentication
[Authentication policies](/user-guide/authentication-policies)
Using authentication policies to restrict account and user authentication by client, authentication methods, and more.
[Multi-factor authentication (MFA)](/user-guide/security-mfa)
Using multi-factor authentication with Snowflake.
[Federated Authentication and SSO](/user-guide/admin-security-fed-auth-overview)
Topics related to federated authentication to Snowflake.
[Key-pair authentication and key-pair rotation](/user-guide/key-pair-auth)
Using key-pair authentication to Snowflake.
[Using programmatic access tokens for authentication](/user-guide/programmatic-access-tokens)
Generating and managing programmatic access tokens for authentication.
[OAuth](/user-guide/oauth-intro)
Topics related to using Snowflake OAuth and External OAuth to connect to Snowflake.
[Workload identity federation](/user-guide/workload-identity-federation)
Preferred authentication method for service-to-service workloads accessing Snowflake data.
[Workload identity federation for Snowflake workloads that access external services](/user-guide/workload-identity-federation-outbound)
Using workload identity federation so that Snowflake workloads can authenticate to external services, with Snowflake acting as the OIDC provider.
[External API authentication and secrets](/user-guide/api-authentication)
Configuring Snowflake to authenticate to external services.
## Network security
[Malicious IP Protection](/user-guide/malicious-ip-protection)
Protecting your account from IP addresses that are known to be malicious.
[Controlling network traffic with network policies](/user-guide/network-policies)
Using network policies to restrict access to Snowflake.
[Network rules](/user-guide/network-rules)
Using network rules with other Snowflake features to restrict access to and from Snowflake.
## Private connectivity
[Private connectivity for inbound network traffic](/user-guide/private-connectivity-inbound)
Using private connectivity to access the Snowflake service, %sf-web-interface%, %sis%, internal stages, Snowflake managed storage volumes, and Snowpark Container Services.
[Private connectivity for outbound network traffic](/user-guide/private-connectivity-outbound)
Using private connectivity for external network locations, external functions, external stages, external tables, external volumes, and Snowpipe automation.
## Administration and authorization
[Trust Center](/user-guide/trust-center/overview)
Using the Trust Center to evaluate and monitor your account for security risks.
[Snowflake sessions and session policies](/user-guide/session-policies)
Using session policies to manage your Snowflake session.
[SCIM](/user-guide/scim-intro)
Topics related to using SCIM to provision users and groups to Snowflake.
[Access Control](/user-guide/security-access-control-overview)
Topics related to role-based access control (RBAC) in Snowflake.
## Defense in depth
[End-to-End Encryption](/user-guide/security-encryption-end-to-end)
Using end-to-end encryption in Snowflake.
[Data movement policies](/user-guide/data-movement-policies)
Using data movement policies to proactively prevent data exfiltration across various movement channels in Snowflake.
[Multi-party Approval](/user-guide/multi-party-approval)
Using Multi-party Approval for a second-person review of security-sensitive and operationally risky critical operations.
--- title: Snowflake AI and ML source: https://docs.snowflake.cn/en/guides-overview-ai-features.md section: General --- # Snowflake AI and ML Snowflake offers two broad categories of powerful, intelligent features based on Artificial Intelligence (AI) and Machine Learning (ML). These features can help you do more with your data in less time than ever before. - **Snowflake Cortex** is a suite of AI features that use large language models (LLMs) to understand unstructured data, answer freeform questions, and provide intelligent assistance. This suite of Snowflake AI Features comprises: - [Cortex Agents](/user-guide/snowflake-cortex/cortex-agents) - [Snowflake Cortex AI Functions (including LLM functions)](/user-guide/snowflake-cortex/aisql) - [Cortex Analyst](/user-guide/snowflake-cortex/cortex-analyst) - [Cortex Fine-tuning](/user-guide/snowflake-cortex/cortex-finetuning) - [Cortex Search](/user-guide/snowflake-cortex/cortex-search/cortex-search-overview) - [%sf-intelligence%](/user-guide/snowflake-cortex/snowflake-cowork) - [Cortex Code](/user-guide/cortex-code/cortex-code) - [Cortex Code in Snowsight](/user-guide/cortex-code/cortex-code-snowsight) - [Cortex Code CLI](/user-guide/cortex-code/cortex-code-cli) - [Cortex Code Agent SDK](/user-guide/cortex-code-agent-sdk/cortex-code-agent-sdk) - [Cortex Code CLI Model Context Protocol (MCP) support](/user-guide/cortex-code/cortex-code-mcp) - [Cortex Code CLI Agent Client Protocol (ACP) support](/user-guide/cortex-code/cortex-code-acp) - [Cortex Code CLI plugins](/user-guide/cortex-code/cortex-code-plugins) - [Cortex AI Guardrails](/user-guide/snowflake-cortex/cortex-ai-guardrails) - **Snowflake ML** provides functionality for you to build your own models. - [ML Functions](/guides-overview-ml-functions) simplify the process of creating and using traditional machine learning models to detect patterns in your structured data. These powerful out-of-the-box analysis tools help time-strapped analysts, data engineers, and data scientists understand, predict, and classify data, without any programming. - For data scientists and developers, [Snowflake ML](/developer-guide/snowflake-ml/overview) lets you develop and operationalize custom models to solve your unique data challenges, while keeping your data inside Snowflake. Snowflake ML incorporates model development classes based on popular ML frameworks, along with ML Ops capabilities such as a feature store, a model registry, framework connectors, and immutable data snapshots. ## Use of Snowflake AI features Snowflake AI Features and their underlying models are designed with the following principles in mind: - **Full security.** Except as you elect, all AI models run inside of Snowflake's security and governance perimeter. Your data is not available to other customers or model developers. - **Data privacy.** Snowflake never uses your Customer Data to train models made available to our customer base. - **Control.** You have control over your team's use of Snowflake AI Features through familiar [role-based access control](/user-guide/security-access-control-overview). ## AI/ML model update process Snowflake is continually working to improve the quality of its offerings, including the models powering the Snowflake AI Features. This section describes how updates to those models fit into [Snowflake's Behavior Change](/release-notes/intro-bcr-releases) process. ## Model Update and Behavior Change Policy ### Overview Snowflake continuously updates the models that power Cortex AI features to improve quality, performance, and availability. These updates may introduce changes to model behavior, availability, or lifecycle status. This document describes how model changes are defined, how they are communicated, and how model lifecycle and deprecation are managed. ### Model lifecycle Models in Cortex follow a defined lifecycle to communicate readiness and stability: - Private Preview - Public Preview - General Availability (GA) - Legacy - End of Life (EOL) Lifecycle status reflects the maturity and support level of a model. As models progress through these stages, their status will be reflected across customer-facing surfaces. Preview models are intended for evaluation and may change more frequently. GA models are considered stable and suitable for production use. ### Types of model changes A model update is considered a behavior change if it results in any of the following: - Changes to required syntax, including specifying a model or model version - Changes to the structure of model outputs - Deprecation of a model These changes may impact how customers interact with models and should be reviewed as part of normal governance processes. ### How changes are communicated Snowflake communicates model-related updates through the following mechanisms: - [Behavior Change Releases (BCRs)](/release-notes/intro-bcr-releases) — Used for changes that may require customer action or impact existing workflows - [What's New](/release-notes/new-features) — Used for improvements or additions that do not materially change how customers interact with models Model deprecations are communicated separately from bundled releases to provide clear and timely notification. ### Deprecation policy Snowflake periodically deprecates models to ensure customers have access to high-quality, well-supported options. For General Availability (GA) models: - Snowflake will make reasonable efforts to provide at least 60 days advance notice prior to deprecation For Preview models: - Deprecation timelines are not guaranteed and may occur with shorter notice During the deprecation period: - Customers are expected to migrate to alternative models before the deprecation date - After deprecation, models may no longer be available for use Lifecycle status will reflect deprecation through the transition to Legacy and ultimately End of Life. ### Legal notices - If you choose to use any of the Snowflake AI Features, your use is subject to our [Acceptable Use Policy](https://www.snowflake.cn/legal/acceptable-use-policy/). - The outputs of Snowflake AI Features may be inaccurate, inappropriate, inefficient, or biased. Decisions based on such outputs, including those built into automatic pipelines, should have human oversight and review processes to ensure they are safe, accurate, and suitable for your intended use. - Your use of any Snowflake AI Feature that is identified as being powered by a third-party, open-source model is subject to any applicable license agreement and/or acceptable use policy set forth under the Offering-Specific Terms page available at [https://www.snowflake.cn/legal/](https://www.snowflake.cn/legal/). - For further information, see the [Snowflake AI Trust and Safety FAQ](https://www.snowflake.cn/en/legal/snowflake-ai-trust-and-safety/). --- title: Snowflake data types source: https://docs.snowflake.cn/en/data-types.md section: General --- # Snowflake data types - [String & binary functions](/sql-reference/functions-string) - [Date & time functions](/sql-reference/functions-date-time) - [Semi-structured and structured data functions](/sql-reference/functions-semistructured) - [Geospatial functions](/sql-reference/functions-geospatial) - [Vector functions](/sql-reference/functions-vector) - [Conversion functions](/sql-reference/functions-conversion) - [Data type conversion](/sql-reference/data-type-conversion) Snowflake supports most basic SQL data types (with some restrictions) for use in columns, local variables, expressions, parameters, and any other appropriate locations. You can also load unstructured data into Snowflake. For more information, see [Introduction to unstructured data](/user-guide/unstructured-intro). In some cases, data of one type can be converted to another type. For example, INTEGER data can be converted to FLOAT data. Some conversions are lossless, but others might lose information. The amount of loss depends upon the data types and the specific values. For example, converting a FLOAT value to an INTEGER value removes the digits after the decimal place. (The value is rounded to the nearest integer.) In some cases, the user must specify the desired conversion, such as when passing a VARCHAR value to the [TIME_SLICE](/sql-reference/functions/time_slice) function, which expects a TIMESTAMP or DATE argument. We call this explicit casting. In other cases, data types are converted automatically, such as when adding a float and an integer. We call this implicit casting (or coercion). In Snowflake, data types are automatically coerced whenever necessary and possible. For more information about explicit and implicit casting, see [Data type conversion](/sql-reference/data-type-conversion). For more information about Snowflake data types, see the following topics: - [Summary of data types](/sql-reference/intro-summary-data-types) - [Numeric data types](/sql-reference/data-types-numeric) - [String & binary data types](/sql-reference/data-types-text) - [Logical data types](/sql-reference/data-types-logical) - [Date & time data types](/sql-reference/data-types-datetime) - [Semi-structured data types](/sql-reference/data-types-semistructured) - [Structured data types](/sql-reference/data-types-structured) - [Unstructured data types](/sql-reference/data-types-unstructured) - [Geospatial data types](/sql-reference/data-types-geospatial) - [UUID data type](/sql-reference/data-types-uuid) - [Vector data types](/sql-reference/data-types-vector) - [User-defined types](/sql-reference/data-types-user-defined) - [Unsupported data types](/sql-reference/data-types-unsupported) - [Data type conversion](/sql-reference/data-type-conversion) --- title: Snowflake Scripting reference source: https://docs.snowflake.cn/en/sql-reference-snowflake-scripting.md section: General --- # Snowflake Scripting reference - [Snowflake Scripting Developer Guide](/developer-guide/snowflake-scripting/index) - [Writing stored procedures in Snowflake Scripting](/developer-guide/stored-procedure/stored-procedures-snowflake-scripting) - [Snowflake Scripting UDFs](/developer-guide/udf/sql/udf-sql-procedural-functions) These topics provide reference information for the language elements supported in [Snowflake Scripting](/developer-guide/snowflake-scripting/index). ```sqlsyntax -- Variable declaration [ DECLARE ... ] ... BEGIN ... -- Branching [ IF ... ] [ CASE ... ] -- Looping [ FOR ... ] [ WHILE ... ] [ REPEAT ... ] [ LOOP ... ] -- Loop termination (within a looping construct) [ BREAK ] [ CONTINUE ] -- Variable assignment [ LET ... ] -- Cursor management [ OPEN ... ] [ FETCH ... ] [ CLOSE ... ] -- Asynchronous child job management [ AWAIT ... ] [ CANCEL ... ] -- "No-op" (no-operation) statement (usually within a branch or exception) [ NULL ] -- Raising exceptions [ RAISE ... ] -- Returning a value [ RETURN ... ] -- Exception handling [ EXCEPTION ... ] END; ``` **Next Topics:** - [AWAIT](/sql-reference/snowflake-scripting/await) - [BEGIN ... END](/sql-reference/snowflake-scripting/begin) - [BREAK](/sql-reference/snowflake-scripting/break) - [CANCEL](/sql-reference/snowflake-scripting/cancel) - [CASE](/sql-reference/snowflake-scripting/case) - [CLOSE](/sql-reference/snowflake-scripting/close) - [CONTINUE](/sql-reference/snowflake-scripting/continue) - [DECLARE](/sql-reference/snowflake-scripting/declare) - [EXCEPTION](/sql-reference/snowflake-scripting/exception) - [FETCH](/sql-reference/snowflake-scripting/fetch) - [FOR](/sql-reference/snowflake-scripting/for) - [IF](/sql-reference/snowflake-scripting/if) - [LET](/sql-reference/snowflake-scripting/let) - [LOOP](/sql-reference/snowflake-scripting/loop) - [NULL](/sql-reference/snowflake-scripting/null) - [OPEN](/sql-reference/snowflake-scripting/open) - [RAISE](/sql-reference/snowflake-scripting/raise) - [REPEAT](/sql-reference/snowflake-scripting/repeat) - [RETURN](/sql-reference/snowflake-scripting/return) - [WHILE](/sql-reference/snowflake-scripting/while) --- title: SQL class reference source: https://docs.snowflake.cn/en/sql-reference-classes.md section: General --- # SQL class reference These topics provide reference information for Snowflake [classes](/sql-reference/snowflake-db-classes). Each class supports one or more of the following SQL operations: - ALTER: Modifies the properties of an instance of a class. - CREATE: Creates an instance of a class. - DROP: Deletes an instance of a class. - SHOW: Lists instances of a class. An instance of a class can have one or more methods. A method is a stored procedure or function and can be called by using the instance name and method name, and arguments (if any) required by the method. For example, CALL instance_name!method_name(...). ## Updating your search path You can add the schema for classes you use frequently to your search path to save typing and make your SQL statements more concise. For more information about updating your search path, see [](#label-update-search-path). ## Available classes Snowflake provides the following system-defined (built-in) classes.
[ANOMALY_DETECTION (SNOWFLAKE.ML)](/sql-reference/classes/anomaly_detection)
Allows you to detect outliers in your time series data.
[ANOMALY_INSIGHTS (SNOWFLAKE.LOCAL)](/sql-reference/classes/anomaly_insights)
Allows you to detect outliers in your costs.
[BUDGET (SNOWFLAKE.CORE)](/sql-reference/classes/budget)
Allows you to monitor credit usage of supported objects.
[CLASSIFICATION (SNOWFLAKE.ML)](/sql-reference/classes/classification)
Automatically sorts data into categories based on features in the data.
[CLASSIFICATION_PROFILE (SNOWFLAKE.DATA_PRIVACY)](/sql-reference/classes/classification_profile)
Allows you to automatically classify sensitive data.
[CUSTOM_CLASSIFIER (SNOWFLAKE.DATA_PRIVACY)](/sql-reference/classes/custom_classifier)
Allows you to define custom classifiers to extend your data classification capabilities.
[FORECAST (SNOWFLAKE.ML)](/sql-reference/classes/forecast)
Represents a forecast model that produces a forecast for a single or multiple time series.
[TOP_INSIGHTS (SNOWFLAKE.ML)](/sql-reference/classes/top-insights)
Allows you to determine the segments driving changes in a metric.
--- title: SQL command reference source: https://docs.snowflake.cn/en/sql-reference-commands.md section: General --- # SQL command reference These topics provide reference information for all the Snowflake SQL commands (DDL, DML, and query syntax). - [Query syntax](/sql-reference/constructs) — structure of SQL queries in Snowflake. - [Query operators](/sql-reference/operators) — arithmetic, logical, and other types of operators. - [Data Definition Language (DDL) commands](/sql-reference/sql-ddl-summary) — overview of DDL commands. - [Data Manipulation Language (DML) commands](/sql-reference/sql-dml) — commands for performing DML operations, including: - Inserting, deleting, updating, and merging data in Snowflake tables. - Bulk copying data into and out of Snowflake tables. - Staging files for bulk copying. - [All commands (alphabetical)](/sql-reference/sql-all) — alphabetical list of all the commands. - Commands categorized by the type of objects and operations they control, including: - General account-level objects (accounts, users, roles, security policies, integrations, etc.) and operations (failover & recovery, etc.). - Session-based operations (session context, queries, variables, transactions, etc.). - Virtual warehouses (for loading data and performing queries) and resource monitors (for controlling credit usage). - Databases, schemas, tables, and other schema-level objects (views, sequences, etc.). - Snowflake extensions and application development (user-defined functions, stored procedures, scripting, etc.). - Objects for sharing data (shares, listings, etc.). - Objects for classifying, protecting, and governing data (masking policies, row-access policies, tags, etc.). --- title: SQL data types reference source: https://docs.snowflake.cn/en/sql-reference-data-types.md section: General --- # SQL data types reference - [Numeric data types](/sql-reference/data-types-numeric) - [String & binary data types](/sql-reference/data-types-text) - [Logical data types](/sql-reference/data-types-logical) - [Date & time data types](/sql-reference/data-types-datetime) - [Semi-structured data types](/sql-reference/data-types-semistructured) - [Structured data types](/sql-reference/data-types-structured) - [Unstructured data types](/sql-reference/data-types-unstructured) - [Geospatial data types](/sql-reference/data-types-geospatial) - [UUID data type](/sql-reference/data-types-uuid) - [Vector data types](/sql-reference/data-types-vector) - [User-defined types](/sql-reference/data-types-user-defined) - [Unsupported data types](/sql-reference/data-types-unsupported) - [Data type conversion](/sql-reference/data-type-conversion) - [Conversion functions](/sql-reference/functions-conversion) - [Unstructured Data](/user-guide/unstructured-intro) Snowflake supports most basic SQL data types (with some restrictions) for use in columns, local variables, expressions, parameters, and any other appropriate locations. You can also load unstructured data into Snowflake. For more information, see [Introduction to unstructured data](/user-guide/unstructured-intro). In some cases, data of one type can be converted to another type. For example, INTEGER data can be converted to FLOAT data. Some conversions are lossless, but others might lose information. The amount of loss depends upon the data types and the specific values. For example, converting a FLOAT value to an INTEGER value removes the digits after the decimal place. (The value is rounded to the nearest integer.) In some cases, the user must specify the desired conversion, such as when passing a VARCHAR value to the [TIME_SLICE](/sql-reference/functions/time_slice) function, which expects a TIMESTAMP or DATE argument. We call this explicit casting. In other cases, data types are converted automatically, such as when adding a float and an integer. We call this implicit casting (or coercion). In Snowflake, data types are automatically coerced whenever necessary and possible. For more information about explicit and implicit casting, see [Data type conversion](/sql-reference/data-type-conversion). For more information about Snowflake data types, see the following topics: - [Summary of data types](/sql-reference/intro-summary-data-types) - [Numeric data types](/sql-reference/data-types-numeric) - [String & binary data types](/sql-reference/data-types-text) - [Logical data types](/sql-reference/data-types-logical) - [Date & time data types](/sql-reference/data-types-datetime) - [Semi-structured data types](/sql-reference/data-types-semistructured) - [Structured data types](/sql-reference/data-types-structured) - [Unstructured data types](/sql-reference/data-types-unstructured) - [Geospatial data types](/sql-reference/data-types-geospatial) - [UUID data type](/sql-reference/data-types-uuid) - [Vector data types](/sql-reference/data-types-vector) - [User-defined types](/sql-reference/data-types-user-defined) - [Unsupported data types](/sql-reference/data-types-unsupported) - [Data type conversion](/sql-reference/data-type-conversion) --- title: Stored procedures source: https://docs.snowflake.cn/en/sql-reference-stored-procedures.md section: General --- # Stored procedures Snowflake provides stored procedures to facilitate using certain Snowflake features. To find the stored procedures that are associated with a particular Snowflake Class, see [SQL class reference](/sql-reference-classes). Use [CALL](/sql-reference/sql/call) to call a stored procedure. For example: ```sql CALL SYSTEM$CLASSIFY('hr.tables.empl_info', null); ``` Snowflake supports the following stored procedures, grouped by feature:
Feature Stored procedure [Cortex Powered Object Descriptions](/user-guide/sql-cortex-descriptions) - [AI_GENERATE_TABLE_DESC](/sql-reference/stored-procedures/ai_generate_table_desc) [Data classification](/user-guide/classify-intro) - [ASSOCIATE_SEMANTIC_CATEGORY_TAGS](/sql-reference/stored-procedures/associate_semantic_category_tags) - [SYSTEM$CLASSIFY](/sql-reference/stored-procedures/system_classify) - [SYSTEM$CLASSIFY_SCHEMA](/sql-reference/stored-procedures/system_classify_schema) - [SYSTEM$CANCEL_CLASSIFY_SCHEMA](/sql-reference/stored-procedures/system_cancel_classify_schema) [Data sharing and collaboration](/guides-overview-sharing) - [SYSTEM$REQUEST_LISTING_AND_WAIT](/sql-reference/stored-procedures/system_request_listing_and_wait) [Default event table](/developer-guide/logging-tracing/event-table-setting-up) - [ADD_ROW_ACCESS_POLICY_ON_EVENTS_VIEW](/sql-reference/stored-procedures/snowflake_telemetry_add_row_access_policy_on_events_view) - [DROP_ROW_ACCESS_POLICY_ON_EVENTS_VIEW](/sql-reference/stored-procedures/snowflake_telemetry_drop_row_access_policy_on_events_view) [Differential privacy](/user-guide/diff-privacy/differential-privacy-overview) - [RESET_PRIVACY_BUDGET](/sql-reference/stored-procedures/reset_privacy_budget) [Network security](/user-guide/network-policy-advisor) - [EVALUATE_CANDIDATE_NETWORK_POLICY](/sql-reference/stored-procedures/evaluate_candidate_network_policy) - [RECOMMEND_NETWORK_POLICY](/sql-reference/stored-procedures/recommend_network_policy) [Notifications](/user-guide/notifications/about-notifications) - [SYSTEM$SEND_SNOWFLAKE_NOTIFICATION](/sql-reference/stored-procedures/system_send_snowflake_notification) - [SYSTEM$SEND_EMAIL](/sql-reference/stored-procedures/system_send_email) [Semantic views](/user-guide/views-semantic/overview) - [SYSTEM$CREATE_SEMANTIC_VIEW_FROM_YAML](/sql-reference/stored-procedures/system_create_semantic_view_from_yaml) [Synthetic data](/user-guide/synthetic-data) - [GENERATE_SYNTHETIC_DATA](/sql-reference/stored-procedures/generate_synthetic_data) [Trust Center](/user-guide/trust-center/overview) - [REGISTER_EXTENSION](/sql-reference/stored-procedures/register_extension) - [DEREGISTER_EXTENSION](/sql-reference/stored-procedures/deregister_extension)
--- title: Tutorials and Other Resources source: https://docs.snowflake.cn/en/other-resources.md section: General --- # Tutorials and Other Resources This topic provides links to assorted "how to" tutorials/labs and "best practices" for using Snowflake. ## Tutorials Snowflake provides several tutorials for getting started. You will need a Snowflake account to explore these tutorials. If you sign up for a trial account, the trial account has a user with necessary roles (ACCOUNTADMIN and SYSADMIN) and a virtual warehouse (COMPUTE_WH) needed to explore this tutorial. If you use any other account to explore this tutorial, then make sure your user is granted these roles and the account has the virtual warehouse. For new users, we recommend you start with these tutorials: - [Snowflake in 20 minutes](/user-guide/tutorials/snowflake-in-20minutes) — A simple tutorial using SnowSQL, the Snowflake command-line client, to introduce key concepts and tasks. - Getting Started with Snowflake - Zero to Snowflake (https://quickstarts.snowflake.com/guide/getting_started_with_snowflake/index.html) — A comprehensive tutorial that uses both SnowSQL and %sf-web-interface-link% covers data loading, querying, working with semi-structured data, accessing historical data using Snowflake's Time Travel feature, sharing, and so on. - Getting Started with Python (https://quickstarts.snowflake.com/guide/getting_started_with_python/index.html) — A tutorial in which you set up the Python Connector and then explore the basic operations you can do with it. For tutorials on bulk loading, see: - [Bulk Loading from a Local File System](/user-guide/tutorials/data-load-internal-tutorial) - [Bulk Loading from Amazon S3](/user-guide/tutorials/data-load-external-tutorial) In addition, you might explore the following pages that introduce important concepts about semi-structured data: - [JSON Basics](/user-guide/tutorials/json-basics-tutorial) - [Loading JSON Data into a Relational Table](/user-guide/tutorials/script-data-load-transform-json) - [Loading and Unloading Parquet Data](/user-guide/tutorials/script-data-load-transform-parquet) ![](/static/images/video-play-bn.png) ![](/static/images/vid-thumb-d-generic.png) ![](/static/images/vid-thumb-gs-key-concepts.png) ![](/static/images/vid-thumb-gs-intro-snowflake.png) ![](/static/images/vid-thumb-gs-intro-virtual-warehouses.png) ![](/static/images/vid-thumb-gs-intro-db-query.png) ![](/static/images/vid-thumb-gs-intro-data-loading.png) ![](/static/images/vid-thumb-d-accel-bi-queries.png) ![](/static/images/vid-thumb-d-easily-load-analyze-semi-struct.png) ![](/static/images/vid-thumb-d-elim-conc-issues.png) ![](/static/images/vid-thumb-d-protect-data-time-travel.png) ![](/static/images/vid-thumb-d-quick-look-zero-copy-cloning.png) ![](/static/images/vid-thumb-d-easy-data-sharing.png) ![](/static/images/vid-thumb-d-query-mult-databases.png) ![](/static/images/vid-thumb-d-tackle-high-concurrency.png) ![](/static/images/vid-thumb-d-snowpipe.png) ## Best Practices Snowflake best practices are provided throughout the documentation. The following are links to important practices related to Snowflake features: - [Roles and Access Control](/user-guide/security-access-control-considerations) - [Virtual Warehouses](/user-guide/warehouses-considerations) - [Table Design](/user-guide/table-considerations) - [Data Storage](/user-guide/tables-storage-considerations) - [Data Loading](/user-guide/data-load-considerations) - [Data Unloading](/user-guide/data-unload-considerations) - [Semi-structured Data](/user-guide/semistructured-considerations) ## Sample Data Sets The following benchmarking datasets are available for all Snowflake accounts: - [TPC-DS](/user-guide/sample-data-tpcds) - [TPC-H](/user-guide/sample-data-tpch) In addition, [Snowflake Marketplace](https://app.snowflake.cn/marketplace?pricing=free) is where you can find additional data sets, provided by third-parties, for use with Snowflake. For related documentation, refer to [Introduction to the Snowflake Marketplace](https://other-docs.snowflake.cn/en/marketplace/intro.html). --- title: Tutorials to get started with Snowflake source: https://docs.snowflake.cn/en/learn-tutorials.md section: General --- # Tutorials to get started with Snowflake The tutorials in this topic provide hands-on examples that get you started with Snowflake. To explore these tutorials, you must have a Snowflake account and a user with the required roles and access to a virtual warehouse: - If you have signed up for a [trial account](/user-guide/admin-trial-account), the trial account user has the required roles and a virtual warehouse that you can use for several of these tutorials. - If you use another account to explore these tutorials, you must sign in as a user that has the required roles and that can use a virtual warehouse. Each tutorial describes the prerequisites that must be met before completing its tasks, including the roles required for the user who performs the tasks. Several tutorials require the ACCOUNTADMIN and SYSADMIN roles. Snowflake bills a minimal amount for the on-disk storage that you use for any sample data in these tutorials. Snowflake requires a [virtual warehouse](/user-guide/warehouses) to load the data and execute queries. A running virtual warehouse consumes Snowflake credits. After you finish a tutorial, you can drop objects that are created in the tutorial to minimize costs. If you are using a 30-day trial account (https://signup.snowflake.com/), which provides free credits, you won't incur any costs. The following sections contain links to tutorials that get you started with Snowflake tasks and features: - [Tutorial that introduces you to Snowflake](#tutorial-that-introduces-you-to-snowflake) - [Tutorials to get started with data engineering](#tutorials-to-get-started-with-data-engineering) - [Tutorial to get started with security](#tutorial-to-get-started-with-security) - [Other learning resources](#other-learning-resources) ## Tutorial that introduces you to Snowflake Snowflake provides the following tutorial to introduce you to key concepts and tasks:
[Snowflake in 20 minutes](/user-guide/tutorials/snowflake-in-20minutes)
Use SnowSQL, a Snowflake command-line client, to learn about key concepts and tasks.
## Tutorials to get started with data engineering Snowflake provides the following tutorials to get you started with data engineering: These tutorials show you how to load data into a table by using the [COPY INTO <table>](/sql-reference/sql/copy-into-table) command. For information about other options for loading data, see [Overview of data loading](/user-guide/data-load-overview). ### Load data
[Load and query sample data using SQL](/user-guide/tutorials/tasty-bytes-sql-load)
Uses a fictitious food truck brand named Tasty Bytes to show you how to [load](/user-guide/data-load-overview) and query data in Snowflake using SQL. You can access a pre-loaded [Snowsight template](/user-guide/ui-snowsight/snowsight-templates) worksheet to complete these tasks.
[Load data from cloud storage: Amazon S3](/user-guide/tutorials/load-from-cloud-tutorial)
Shows you how to load data from an Amazon S3 bucket into Snowflake using SQL. You can access a pre-loaded Snowsight template worksheet to complete these tasks.
[Load data from cloud storage: Microsoft Azure](/user-guide/tutorials/load-from-cloud-tutorial-azure)
Shows you how to load data from Microsoft Azure cloud storage into Snowflake using SQL. You can access a pre-loaded Snowsight template worksheet to complete these tasks.
[Load data from cloud storage: Google Cloud Storage](/user-guide/tutorials/load-from-cloud-tutorial-gcs)
Shows you how to load data from Google Cloud Storage into Snowflake using SQL. You can access a pre-loaded Snowsight template worksheet to complete these tasks.
### Bulk load data
[Bulk load from a local file system using COPY](/user-guide/tutorials/data-load-internal-tutorial)
Describes how to [bulk load data](/user-guide/data-load-local-file-system) from files in your local file system into a table.
[Bulk load from Amazon S3 using COPY](/user-guide/tutorials/data-load-external-tutorial)
Describes how to bulk load data from files in an existing Amazon Simple Storage Service (Amazon S3) bucket into a table.
### Work with semi-structured data
[Learn the basics of using JSON with Snowflake](/user-guide/tutorials/json-basics-tutorial)
Describes the basics of using [JSON](#label-what-is-json) with Snowflake.
[Load JSON data into a relational table](/user-guide/tutorials/script-data-load-transform-json)
Uses a [COPY INTO <table>](/sql-reference/sql/copy-into-table) command with a SELECT statement to load individual elements in a staged JSON file into a table.
[Load and unload Parquet data](/user-guide/tutorials/script-data-load-transform-parquet)
Describes how you can upload [Parquet](#label-what-is-parquet) data by transforming elements of a staged Parquet file directly into table columns using the [COPY INTO <table>](/sql-reference/sql/copy-into-table) command. The tutorial also describes how you can use the [COPY INTO <location>](/sql-reference/sql/copy-into-location) command to unload table data into a Parquet file.
## Tutorial to get started with security Snowflake provides the following tutorial to get you started with security:
[Create users and grant roles](/user-guide/tutorials/users-and-roles-tutorial)
Shows you how to create a [user](/user-guide/admin-user-management) and grant a role to it by using SQL commands. You can access a pre-loaded [Snowsight template](/user-guide/ui-snowsight/snowsight-templates) worksheet to complete these tasks.
## Other learning resources These other learning sources are available:
[Tutorials](https://docs.snowflake.cn/tutorials)
Explore a large repository of tutorials with hands-on examples that help you learn about Snowflake's features.
Snowflake Education Services (https://learn.snowflake.com/en/)
Discover instructor-led classes, on-demand courses, and self-directed learning to get you started with Snowflake.
[Snowflake for Developers](https://www.snowflake.cn/en/developers/guides/)
Discover product quickstarts, industry-specific use cases, administration best practices, and reference architectures from Snowflake experts and partners.
Snowflake Developers YouTube Channel
Discover Snowflake product tips, demos, and tutorials.
--- title: Unload data from Snowflake source: https://docs.snowflake.cn/en/guides-overview-unloading-data.md section: General --- # Unload data from Snowflake Snowflake supports bulk unloading of data from a database table into flat, delimited text files. The following topics detail the processes and procedures associated with unloading data.
[Overview of data unloading](/user-guide/data-unload-overview)
Introduction and overview of unloading data.
[Summary of Data Unloading Features](/user-guide/intro-summary-unloading)
Reference of the supported features for using the [COPY INTO *<location>*](/sql-reference/sql/copy-into-location) command to unload data from Snowflake tables into flat files.
[Data unloading considerations](/user-guide/data-unload-considerations)
Best practices, general guidelines, and important considerations for unloading data.
[File formats to unload data](/user-guide/data-unload-prepare)
Supported data file formats for unloading data.
[Unload into a Snowflake stage](/user-guide/data-unload-snowflake)
Instructions on using the COPY command to unload data from a table into an internal (i.e. Snowflake) stage.
[Unload into Amazon S3](/user-guide/data-unload-s3)
Instructions on using the COPY command to unload data from a table into an Amazon S3 bucket.
[Unload into Google Cloud Storage](/user-guide/data-unload-gcs)
Instructions on using the COPY command to unload data from a table into a Google Cloud Storage bucket.
[Unload into Microsoft Azure](/user-guide/data-unload-azure)
Instructions on using the COPY command to unload data from a table into an Azure container.
--- title: Welcome to Snowflake Documentation source: https://docs.snowflake.cn/en/index.md section: General --- # Welcome to Snowflake Documentation ![WELCOME TO SNOWFLAKE DOCUMENTATION](/static/images/sf-hero.jpg) WELCOME TO SNOWFLAKE DOCUMENTATION In these topics, you will find the information you need to access your Snowflake account and perform all the administrative and user tasks associated with using Snowflake. The documentation also provides conceptual overviews, tutorials, and a detailed reference for all supported SQL commands, functions, and operators. You can start by browsing the contents on the left or using the search box at the top to search across the documentation and other Snowflake resources. If you do not find the information you are looking for, please feel free to reach out to Snowflake Documentation or Snowflake Support using the buttons at the bottom of each page. ## [Get started with Snowflake for users](/getting-started-for-users)
[Before you begin](/user-guide/setup)
Overview of getting an account and methods for accessing Snowflake.
[Sign in to Snowflake](/user-guide/connecting)
Overview of the different ways to connect to Snowflake.
[Snowflake key concepts and architecture](/user-guide/intro-key-concepts)
Description of Snowflake architecture, key concepts, and features.
[Snowsight quick tour](/user-guide/ui-snowsight-quick-tour)
Overview of %sf-web-interface%, Snowflake's web-based interface.
[Overview of the data lifecycle](/user-guide/data-lifecycle)
Introduces the main operations and corresponding SQL commands for getting your data into Snowflake and then using it to perform queries and other SQL operations.
## [Tutorials and Other Resources](/other-resources) This topic provides links to assorted "how to" tutorials/labs and "best practices" for using Snowflake. ## [Using Snowflake](/user-guide) - [Snowsight: The Snowflake web interface](/user-guide/ui-snowsight) — Learn how to use %sf-web-interface% for your Snowflake operations: - [Snowsight quick tour](/user-guide/ui-snowsight-quick-tour) - [Getting started with Snowsight](/user-guide/ui-snowsight-gs) - [Work with worksheets in Snowsight](/user-guide/ui-snowsight-worksheets) - [Workspaces](/user-guide/ui-snowsight/workspaces) - [About Legacy Snowflake Notebooks](/user-guide/ui-snowsight/notebooks) - [Using Snowflake Copilot](/user-guide/snowflake-copilot) - [Visualizing data with dashboards](/user-guide/ui-snowsight-dashboards) - [Explore and manage database objects in Snowsight](/user-guide/ui-snowsight-data) - [Monitor query activity with Query History](/user-guide/ui-snowsight-activity) - [Evaluating and monitoring account security in the Trust Center](/user-guide/trust-center/overview) - [Manage Snowflake Support cases](/user-guide/ui-support) - [Set up and manage notification contacts for Snowflake](/user-guide/ui-snowsight-contacts) - [Virtual warehouses](/user-guide/warehouses) — Key concepts and tasks for creating and using virtual warehouses to execute queries and perform DML operations, such as loading and unloading data: - [Overview of warehouses](/user-guide/warehouses-overview) - [Multi-cluster warehouses](/user-guide/warehouses-multicluster) - [Warehouse considerations](/user-guide/warehouses-considerations) - [Working with warehouses](/user-guide/warehouses-tasks) - [Using the Query Acceleration Service (QAS)](/user-guide/query-acceleration-service) - [Monitoring warehouse load](/user-guide/warehouses-load-monitoring) - [Databases, Tables & Views](/user-guide/databases) — Key concepts and tasks related to understanding and working with Snowflake databases and tables: - [Understanding Snowflake Table Structures](/user-guide/tables-micro-partitions) - [Working with Temporary and Transient Tables](/user-guide/tables-temp-transient) - [Introduction to external tables](/user-guide/tables-external-intro) - [Overview of Views](/user-guide/views-introduction) - [Working with Secure Views](/user-guide/views-secure) - [Working with Materialized Views](/user-guide/views-materialized) - [Table Design Considerations](/user-guide/table-considerations) - [Cloning considerations](/user-guide/object-clone) - [Data storage considerations](/user-guide/tables-storage-considerations) - [Query Data in Snowflake](/guides-overview-queries) — Key concepts and tasks for executing queries in Snowflake: - [Working with joins](/user-guide/querying-joins) - [Understanding How Snowflake Can Eliminate Redundant Joins](/user-guide/join-elimination) - [Working with Subqueries](/user-guide/querying-subqueries) - [Querying Hierarchical Data](/user-guide/queries-hierarchical) - [Working with CTEs (Common Table Expressions)](/user-guide/queries-cte) - [Querying Semi-structured Data](/user-guide/querying-semistructured) - [Analyzing data with window functions](/user-guide/functions-window-using) - [Identifying Sequences of Rows That Match a Pattern](/user-guide/match-recognize-introduction) - [Using Sequences](/user-guide/querying-sequences) - [Using Persisted Query Results](/user-guide/querying-persisted-results) - [Computing the Number of Distinct Values](/user-guide/querying-distinct-counts) - [Estimating Similarity of Two or More Sets](/user-guide/querying-approximate-similarity) - [Estimating Frequent Values](/user-guide/querying-approximate-frequent-values) - [Estimating Percentile Values](/user-guide/querying-approximate-percentile-values) - [Querying data using worksheets](/user-guide/ui-snowsight-query) - [Canceling Statements](/user-guide/querying-cancel-statements) - [Introduction to loading semi-structured data](/user-guide/semistructured-intro) — Key concepts and tasks for working with JSON and other types of semi-structured data: - [Supported formats for semi-structured data](/user-guide/semistructured-data-formats) - [Considerations for semi-structured data stored in VARIANT](/user-guide/semistructured-considerations) - [Tutorial: JSON basics for Snowflake](/user-guide/tutorials/json-basics-tutorial) - [Introduction to unstructured data](/user-guide/unstructured-intro) — Key concepts and tasks for working with unstructured data: - [Directory tables](/user-guide/data-load-dirtables) - [REST API for unstructured data support](/user-guide/data-load-unstructured-rest-api) - [Share unstructured data with a secure view](/user-guide/unstructured-data-sharing) - [Troubleshooting processing of unstructured data](/user-guide/unstructured-ts) - [Snowflake Time Travel & Fail-safe](/user-guide/data-availability) — Key concepts and tasks for understanding how Snowflake maintains access to deleted and modified data, and also how Snowflake enables data recovery in the event of loss: - [Understanding & using Time Travel](/user-guide/data-time-travel) - [Understanding and viewing Fail-safe](/user-guide/data-failsafe) - [Storage costs for Time Travel and Fail-safe](/user-guide/data-cdp-storage-costs) - [Introduction to streams and tasks](/user-guide/data-pipelines-intro) — Key concepts and tasks for transforming and optimizing loaded data for analysis: - [Introduction to streams](/user-guide/streams-intro) - [Introduction to tasks](/user-guide/tasks-intro) - [Introduction to business continuity & disaster recovery](/user-guide/replication-intro) — Key concepts and tasks for replicating and failing over databases across multiple Snowflake accounts, as well as redirecting client connections, for business continuity and disaster recovery:
Supported regions for feature
This feature is not available in the People's Republic of China.
- [Introduction to replication and failover across multiple accounts](/user-guide/account-replication-intro) - [Redirecting client connections](/user-guide/client-redirect) - [Sample data sets](/user-guide/sample-data) — Key concepts and tasks for using the sample data sets provided with Snowflake: - [Use the sample database](/user-guide/sample-data-using) - [Sample data: TPC-H](/user-guide/sample-data-tpch) - [Sample Data: OpenWeatherMap — *Deprecated*](/user-guide/sample-data-openweathermap) - [Alerts and Notifications](/guides-overview-alerts) — Key concepts and tasks for sending email notifications in SQL (e.g. from a stored procedure, task, etc.) and setting up alerts to perform actions or send notifications when data in Snowflake meets certain conditions. - [Setting up alerts based on data in Snowflake](/user-guide/alerts) - [Notifications in Snowflake](/user-guide/notifications/about-notifications) - [Snowflake Postgres](/user-guide/snowflake-postgres/about) — Create, manage, and use Postgres instances directly from Snowflake: - [Creating a Snowflake Postgres Instance](/user-guide/snowflake-postgres/postgres-create-instance) - [Connecting to Snowflake Postgres](/user-guide/snowflake-postgres/connecting-to-snowflakepg) - [Snowflake Postgres Roles](/user-guide/snowflake-postgres/postgres-roles) - [Snowflake Postgres Connection Pooling](/user-guide/snowflake-postgres/postgres-connection-pooling) - [Snowflake Postgres Maintenance](/user-guide/snowflake-postgres/postgres-maintenance) - [Snowflake Postgres Read Replicas](/user-guide/snowflake-postgres/postgres-create-replica) - [Snowflake Postgres High Availability](/user-guide/snowflake-postgres/high-availability) - [Snowflake Postgres Cost Evaluation](/user-guide/snowflake-postgres/postgres-cost) - [Snowflake Postgres Insights](/user-guide/snowflake-postgres/insights) - [Snowflake Postgres logging](/user-guide/snowflake-postgres/postgres-logging) - [Using Cortex Code CLI with Snowflake Postgres](/user-guide/snowflake-postgres/postgres-cortex-code) - [Snowflake Postgres networking](/user-guide/snowflake-postgres/postgres-network) - [Snowflake Postgres Instance Sizes](/user-guide/snowflake-postgres/postgres-instance-sizes) - [Snowflake Postgres Extensions](/user-guide/snowflake-postgres/postgres-extensions) - [Snowflake Postgres Server Settings](/user-guide/snowflake-postgres/postgres-server-settings) ## [Managing Your Snowflake Account](/user-guide-admin) - [Account identifiers](/user-guide/admin-account-identifier) Detailed descriptions of the two unique account identifiers supported for connecting to Snowflake and using features that span multiple accounts. - [Trial accounts](/user-guide/admin-trial-account) Instructions for signing up for a trial account, adding a credit card to the account, and canceling the account. - [Parameter management](/user-guide/admin-account-management) Instructions for setting account, session, and object parameters for your account. - [User management](/user-guide/admin-user-management) Instructions for creating and managing users in your account. - [Behavior change management](/release-notes/bcr-bundles/managing-behavior-change-releases) Instructions for enabling and disabling behavior change releases in your account. ## [General reference](/sql-reference) - [Parameters](/sql-reference/parameters) — parameters that can be used to control system behavior at the account, user, session, and object level. - [References](/sql-reference/references) — use references to authorize access on objects for owner's rights stored procedures, applications, and classes. - [Ternary logic](/sql-reference/ternary-logic) — information about the behavior of NULL in Boolean expressions and with comparison operators. - [Collation support](/sql-reference/collation) — information about sorting and other character-set-dependent operations on text strings. - [SQL format models](/sql-reference/sql-format-models) — formats for specifying conversion of numeric and date/time values to and from text strings. - [Object identifiers](/sql-reference/identifiers) — rules for defining and using object identifiers, including resolving object names used in SQL statements: - [Identifier requirements](/sql-reference/identifiers-syntax) - [Literals and variables as identifiers with IDENTIFIER() syntax](/sql-reference/identifier-literal) - [Object name resolution](/sql-reference/name-resolution) - [Constraints](/sql-reference/constraints) — concepts and reference information for defining and maintaining unique, primary key, and foreign key constraints in tables: - [Overview of constraints](/sql-reference/constraints-overview) - [Creating constraints](/sql-reference/constraints-create) - [Modifying constraints](/sql-reference/constraints-alter) - [Dropping constraints](/sql-reference/constraints-drop) - [SQL variables](/sql-reference/session-variables) — concepts and reference for defining and using variables in sessions. - [Transactions](/sql-reference/transactions) — concepts and reference for using transactions with SQL statements. - [Table literals](/sql-reference/literals-table) — concepts and reference for using table literals instead of a single scalar value in queries. - [SNOWFLAKE database](/sql-reference/snowflake-db) — reference for the SNOWFLAKE shared database, which is provided by Snowflake for querying/reporting on your organization, account, data sharing, and other object usage. - [Snowflake Information Schema](/sql-reference/info-schema) — concepts and reference for the Snowflake Information Schema, which consists of a set of metadata views and historical table functions for querying/reporting on objects in Snowflake. - [Metadata fields in Snowflake](/sql-reference/metadata) — concepts and reference for metadata fields in Snowflake. ## [SQL command reference](/sql-reference-commands) - [Query syntax](/sql-reference/constructs) — structure of SQL queries in Snowflake. - [Query operators](/sql-reference/operators) — arithmetic, logical, and other types of operators. - [Data Definition Language (DDL) commands](/sql-reference/sql-ddl-summary) — overview of DDL commands. - [Data Manipulation Language (DML) commands](/sql-reference/sql-dml) — commands for performing DML operations, including: - Inserting, deleting, updating, and merging data in Snowflake tables. - Bulk copying data into and out of Snowflake tables. - Staging files for bulk copying. - [All commands (alphabetical)](/sql-reference/sql-all) — alphabetical list of all the commands. - Commands categorized by the type of objects and operations they control, including: - General account-level objects (accounts, users, roles, security policies, integrations, etc.) and operations (failover & recovery, etc.). - Session-based operations (session context, queries, variables, transactions, etc.). - Virtual warehouses (for loading data and performing queries) and resource monitors (for controlling credit usage). - Databases, schemas, tables, and other schema-level objects (views, sequences, etc.). - Snowflake extensions and application development (user-defined functions, stored procedures, scripting, etc.). - Objects for sharing data (shares, listings, etc.). - Objects for classifying, protecting, and governing data (masking policies, row-access policies, tags, etc.). ## [Function and stored procedure reference](/sql-reference-functions) - [Summary of functions](/sql-reference/intro-summary-operators-functions) — combined summary of all system-defined functions. Can be used as a quick-reference. - [All functions (alphabetical)](/sql-reference/functions-all) — alphabetical list of all system-defined functions (scalar, aggregate, table, etc.). - [Aggregate functions](/sql-reference/functions-aggregation) — functions that take multiple rows/values as input and return a single value. - [Scalar functions](/sql-reference/functions) — functions that take a single row/value as input and return a single value: - [Bitwise expression functions](/sql-reference/expressions-byte-bit) - [Conditional expression functions](/sql-reference/expressions-conditional) - [Context functions](/sql-reference/functions-context) - [Conversion functions](/sql-reference/functions-conversion) - [Data generation functions](/sql-reference/functions-data-generation) - [Date & time functions](/sql-reference/functions-date-time) - [Differential privacy functions](/sql-reference/functions-differential-privacy) - [Encryption functions](/sql-reference/functions-encryption) - [Geospatial functions](/sql-reference/functions-geospatial) - [Hash functions](/sql-reference/functions-hash-scalar) - [Metadata functions](/sql-reference/functions-metadata) - [Notification functions](/sql-reference/functions-notification) - [Numeric functions](/sql-reference/functions-numeric) - [Semi-structured and structured data functions](/sql-reference/functions-semistructured) - [String functions (regular expressions)](/sql-reference/functions-regexp) — regular expression (search) functions - [String & binary functions](/sql-reference/functions-string) - [Vector functions](/sql-reference/functions-vector) - [Model monitor functions](/sql-reference/functions-model-monitors) — functions that retrieve metrics from machine learning model monitors. - [System functions](/sql-reference/functions-system) — functions that perform control operations or return system-level information. - [Table functions](/sql-reference/functions-table) — functions that return results in tabular format. - [Window functions](/sql-reference/functions-window) — functions that run analytic calculations, such as moving aggregations and rankings. - [Data metric functions](/sql-reference/functions-data-metric) — functions that enable data quality measurements for tables and views. - [Stored procedures](/sql-reference-stored-procedures) — stored procedures to facilitate using certain Snowflake features. ## [Snowflake Scripting reference](/sql-reference-snowflake-scripting) - [AWAIT](/sql-reference/snowflake-scripting/await) - [BEGIN ... END](/sql-reference/snowflake-scripting/begin) - [BREAK](/sql-reference/snowflake-scripting/break) - [CANCEL](/sql-reference/snowflake-scripting/cancel) - [CASE](/sql-reference/snowflake-scripting/case) - [CLOSE](/sql-reference/snowflake-scripting/close) - [CONTINUE](/sql-reference/snowflake-scripting/continue) - [DECLARE](/sql-reference/snowflake-scripting/declare) - [EXCEPTION](/sql-reference/snowflake-scripting/exception) - [FETCH](/sql-reference/snowflake-scripting/fetch) - [FOR](/sql-reference/snowflake-scripting/for) - [IF](/sql-reference/snowflake-scripting/if) - [LET](/sql-reference/snowflake-scripting/let) - [LOOP](/sql-reference/snowflake-scripting/loop) - [NULL](/sql-reference/snowflake-scripting/null) - [OPEN](/sql-reference/snowflake-scripting/open) - [RAISE](/sql-reference/snowflake-scripting/raise) - [REPEAT](/sql-reference/snowflake-scripting/repeat) - [RETURN](/sql-reference/snowflake-scripting/return) - [WHILE](/sql-reference/snowflake-scripting/while) ## [Appendices](/appendices) - [Notational conventions](/sql-reference/conventions) Notational conventions used in the Snowflake documentation. - [Reserved & limited keywords](/sql-reference/reserved-keywords) List of words reserved for Snowflake SQL. ![](/static/images/sf-hero.jpg) --- title: Working with organizations and accounts source: https://docs.snowflake.cn/en/guides-overview-manage.md section: General --- # Working with organizations and accounts The following topics describe how to manage Snowflake organizations and accounts. ## Organizations
[Introduction to organizations](/user-guide/organizations)
Learn about organizations, which link the accounts owned by your business entity. You can find the name of your organization, list the accounts in your organization, and change the name of your organization.
[Organization administrators](/user-guide/organization-administrators)
Learn about the system roles that administrators use to perform organization-level tasks.
[Organization users](/user-guide/organization-users)
Learn about using organization users for users who need access to multiple accounts within the organization.
[Managing accounts in your organization](/user-guide/organizations-manage-accounts)
Manage the lifecycle of an account such as creating it and deleting it. Also, manage the general characteristics of an account like its Snowflake edition.
[Connecting to your accounts](/user-guide/organizations-connect)
Connect to accounts in your organization from SnowSQL, connectors, drivers, and through %sf-web-interface%.
## Organization accounts
[Organization accounts](/user-guide/organization-accounts)
Learn how organization administrators of multi-account organizations use an organization account. Also, use premium views in the ORGANIZATION_USAGE schema to track usage across the organization.
## Organization Hub
[Organization Hub](/user-guide/organization-hub)
Use Organization Hub to open **Insights** (cost, security, and query health) or **Command center** (organization-wide configuration).
[Organization Hub Insights](/user-guide/organization-hub-insights)
Monitor organization-level metrics on the Insights page, including billing and cost, security, and query health.
[Organization Command Center](/user-guide/organization-hub-command-center)
Use Command Center to configure organization-wide settings, including Organization Features and 3rd party access configuration.
## Accounts
[Account identifiers](/user-guide/admin-account-identifier)
Learn how to use account identifiers to specify the account that you are using (e.g. to connect to the account, use %sf-web-interface%, etc.).
[Trial accounts](/user-guide/admin-trial-account)
Sign up for a trial account, convert that account to a paid account, and cancel the trial account.
[Parameter management](/user-guide/admin-account-management)
View and alter parameters for your account.
[User management](/user-guide/admin-user-management)
Create, modify, view, and drop users in your account.
[Behavior change management](/release-notes/bcr-bundles/managing-behavior-change-releases)
Enable, disable, and check the status of behavior changes.
## Loading & Unloading Data Stages, COPY INTO, Snowpipe, file formats, and connectors for ingesting and exporting data. --- title: AbortQueryJob 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/abortqueryjob.md section: Loading & Unloading Data --- # AbortQueryJob 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-salesforce-processors-nar ## Description Aborts a Query Job in Salesforce using the Bulk API 2.0. ## Tags abort, bulk, job, preview, query, salesforce ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
Property Description Job ID The ID of the job for which the status is checked. Salesforce Client Salesforce Client to interact with the APIs
## Relationships
Name Description comms.failure A FlowFile is routed to this relationship if the Query Job could not be aborted but the operation might be retried failure A FlowFile is routed to this relationship if the Query Job could not be aborted success If the Query Job has been successfully aborted, the FlowFile is routed to this relationship
## See also - [com.snowflake.openflow.runtime.processors.salesforce.DeleteQueryJob](/user-guide/data-integration/openflow/processors/deletequeryjob) - [com.snowflake.openflow.runtime.processors.salesforce.GetQueryJobResult](/user-guide/data-integration/openflow/processors/getqueryjobresult) - [com.snowflake.openflow.runtime.processors.salesforce.GetQueryJobStatus](/user-guide/data-integration/openflow/processors/getqueryjobstatus) - [com.snowflake.openflow.runtime.processors.salesforce.SubmitQueryJob](/user-guide/data-integration/openflow/processors/submitqueryjob) --- title: About Openflow source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/about.md section: Loading & Unloading Data --- # About Openflow This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions). - [About Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/about-spcs) - [About Openflow: BYOC deployments](/user-guide/data-integration/openflow/about-byoc) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Monitor Openflow using telemetry data](/user-guide/data-integration/openflow/monitor) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index) - [Snowflake Openflow version history](/user-guide/data-integration/openflow/version-history) - [Use row timestamps to measure latency in your pipelines](/user-guide/data-engineering/row-timestamps) Snowflake Openflow is an integration service that connects any data source and any destination with hundreds of processors supporting structured and unstructured text, images, audio, video, and sensor data. Built on Apache NiFi (https://nifi.apache.org/), Openflow lets you run a fully managed service in your own cloud for complete control. The Openflow platform is currently available for deployment in customers' own VPCs in both AWS and %spcs%. Openflow isn't automatically available in trial accounts. To enable it, contact your Snowflake account team. For operational safeguards (backing up flows, avoiding data loss when you remove deployments or runtimes), see [Manage Openflow](/user-guide/data-integration/openflow/manage). This topic describes the key features of Openflow, its benefits, architecture, workflow, and use cases. ## Key features and benefits
Open and extensible
An extensible managed service that's powered by Apache NiFi, enabling you to build and extend processors from any data source to any destination.
Unified data integration platform
Openflow enables data engineers to handle complex, bi-directional data extraction and loading through a fully managed service that can be deployed inside your own VPC or within your Snowflake deployment.
Enterprise-ready
Openflow offers out-of-the-box security, compliance, and observability and maintainability hooks for data integration.
High speed ingestion of all types of data
One unified platform lets you handle structured and unstructured data, in both batch and streaming modes, from your data source to Snowflake at virtually any scale.
Continuous ingestion of multimodal data for AI processing
Near real-time unstructured data ingestion, so you can immediately chat with your data coming from sources such as SharePoint, Google Drive, and so on.
## Openflow deployment types Openflow is supported in both the Bring Your Own Cloud (BYOC) and Snowflake deployment types. Both deployment types are available in gen 1 and gen 2. Your account is enabled for one or the other: if your account is enabled for public preview features, any new deployment is gen 2; otherwise, it is gen 1. Gen 2 (public preview) provides SQL-first management of deployments, runtimes, and connectors. For a comparison of gen 1 and gen 2, see [Openflow gen 1 and gen 2](/user-guide/data-integration/openflow/gen2/openflow-generations).
%ofsfspcs%
%ofsfspcs%, using [Snowpark Container Services](/developer-guide/snowpark-container-services/overview) (SPCS), provides a streamlined and integrated solution for connectivity. Because SPCS is a self-contained service within Snowflake, it's easy to deploy and manage. SPCS offers a convenient and cost-effective environment for running your data flows. A key advantage of %ofsfspcs% is its native integration with Snowflake's security model, which allows for seamless authentication, authorization, network security, and simplified operations. When configuring %ofsfspcs-plural%, follow the process as outlined in [Setup Openflow - Snowflake Deployment](/user-guide/data-integration/openflow/setup-openflow-spcs). For gen 2, see the [gen 2 quickstart](/user-guide/data-integration/openflow/gen2/quickstart).
Openflow - Bring Your Own Cloud
Openflow - Bring Your Own Cloud (BYOC) provides a connectivity solution that you can use to connect public and private systems securely and handle sensitive data preprocessing locally, within the secure bounds of your organization's cloud environment. BYOC refers to a deployment option where the Openflow data processing engine, or data plane, runs within your own cloud environment while Snowflake manages the overall Openflow service and control plane. When configuring BYOC deployments, follow the process as outlined in [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc). For gen 2, see the [gen 2 quickstart](/user-guide/data-integration/openflow/gen2/quickstart).
## Use cases Use Openflow if you want to fetch data from any source and put it in any destination with minimal management, coupled with Snowflake's built-in data security and governance. Openflow use cases include: - Ingest data from unstructured data sources, such as Google Drive and Box, and make it ready for chat in your AI assistants with Snowflake Cortex or use the data for your own custom processing. - Replicate the change data capture (CDC) of database tables into Snowflake for comprehensive, centralized reporting. - Ingest real-time events from streaming services, such as Apache Kafka, into Snowflake for near real-time analytics. - Ingest data from SaaS platforms, such as LinkedIn Ads, to Snowflake for reporting, analytics, and insights. - Create an Openflow dataflow using Snowflake and NiFi [processors](/user-guide/data-integration/openflow/processors/index) and [controller services](/user-guide/data-integration/openflow/controllers/index). ## Security Openflow uses industry-leading security features that help ensure you have the highest levels of security for your account, and users, and all the data you store in Snowflake. Some key aspects include:
Authentication
- Runtimes use [Snowflake Managed Token](#label-openflow-snowflake-managed-token) as the default and recommended authentication method. - Snowflake Managed Token works consistently across SPCS and BYOC deployment types. - BYOC deployments can alternatively use key-pair authentication for explicit credential management.
Authorization
- Openflow supports fine-grained roles for RBAC. - ACCOUNTADMIN to grant privileges to be able to create deployments and runtimes.
Encryption in-transit
- Openflow connectors support TLS protocol, using standard Snowflake clients for data ingestion. - All the communications between the Openflow deployments and Openflow control plane are encrypted using TLS protocol.
Secrets management
- Integration with [Snowflake secrets](/sql-reference/sql/create-secret) across both BYOC and Snowflake deployments. - (BYOC) Integration with AWS Secrets Manager or Hashicorp Vault. For more information, see Encrypted Passwords in Configuration Files (https://nifi.apache.org/docs/nifi-docs/html/administration-guide.html#encrypt-config_tool).
Private connectivity support
- Openflow connectors are compatible with reading and writing data to Snowflake using [inbound AWS PrivateLink](/user-guide/admin-security-privatelink) (BYOC) or [outbound private connectivity](/user-guide/private-connectivity-outbound) (Snowflake deployments).
Tri-Secret Secure support
- Openflow connectors are compatible with [Tri-Secret Secure](/user-guide/security-encryption-tss) for writing data to Snowflake.
## Snowflake Managed Token authentication Snowflake Managed Token is the recommended and default authentication method for Openflow runtimes to connect to Snowflake. This authentication method works consistently across both [Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/about-spcs) and [BYOC deployments](/user-guide/data-integration/openflow/about-byoc). Snowflake Managed Token provides a unified and simplified experience for configuring Snowflake connectivity. ### Key benefits
Simplified configuration
Snowflake Managed Token eliminates the need to generate, store, and rotate long-lived credentials such as key pairs. The token is automatically managed by Snowflake, reducing operational overhead.
Unified across deployment types
Whether you deploy Openflow in %spcs% (SPCS) or Bring Your Own Cloud (BYOC), you configure authentication the same way using the `SNOWFLAKE_MANAGED` authentication strategy.
Enhanced security
Tokens are short-lived and automatically refreshed, minimizing the risk associated with credential exposure.
### How it works When you configure a connector or processor to connect to Snowflake, select `SNOWFLAKE_MANAGED` as the **Snowflake Authentication Strategy**. The runtime automatically obtains and manages the token used to authenticate to Snowflake on your behalf. The behavior of Snowflake Managed Token varies based on your deployment type:
%ofsfspcs-plural%
When running in a Snowflake-managed deployment, the runtime uses [SPCS session tokens](/developer-guide/snowpark-container-services/overview) provided natively by the SPCS environment. These tokens are available at runtime and require no additional configuration.
BYOC deployments
When running in a BYOC deployment, the runtime uses [workload identity federation](/user-guide/workload-identity-federation) to authenticate to Snowflake. The runtime automatically exchanges its cloud provider identity (for example, an AWS IAM role) for a Snowflake token. To use Snowflake Managed Token in BYOC deployments, you must first configure [execute-as roles](#label-deployment-byoc-setup-runtime-role) for your deployment.
### When to use Snowflake Managed Token Use Snowflake Managed Token for: - All new connector configurations in both SPCS and BYOC deployments. - Migrations from key-pair authentication to the simplified, managed authentication model. - Scenarios where you want to avoid managing key pairs or other long-lived credentials. ### Alternative authentication methods While Snowflake Managed Token is recommended, BYOC deployments also support key-pair authentication (`KEY_PAIR`) for cases where you require explicit credential management. For more information about key-pair authentication, see [Key-pair authentication and key-pair rotation](/user-guide/key-pair-auth). For information about the underlying authentication mechanisms, see the following: - [Workload identity federation](/user-guide/workload-identity-federation): Information about the authentication mechanism used in BYOC deployments. - [Snowpark Container Services: Working with services](/developer-guide/snowpark-container-services/working-with-services): Information about how SPCS services authenticate to Snowflake. ## Architecture The following diagram illustrates the architecture of Openflow: ![Openflow architecture](/static/images/connectivity/openflow-architecture.png) The deployment agent installs and bootstraps the Openflow deployment infrastructure in your VPC and regularly syncs container images from the Snowflake system image registry. Openflow components include:
Deployments
A deployment is where your data flows execute, within individual runtimes. You will often have multiple runtimes to isolate different projects, teams, or for SDLC reasons, all associated with a single deployment. Deployments come in two types, [Openflow - Snowflake](/user-guide/data-integration/openflow/about-spcs) and [Bring Your Own Cloud (BYOC)](/user-guide/data-integration/openflow/about-byoc).
Control plane
The control plane is a layer containing all components used to manage and observe Openflow runtimes. This includes the Openflow service and API, which users interact with via the Openflow canvas or through interaction with Openflow APIs. On %ofsfspcs-plural%, the control plane consists of Snowflake-owned public cloud infrastructure and services as well as the control plane application itself.
BYOC deployments
BYOC deployments are deployments acting as containers for runtimes that are deployed in *your* cloud environment. They incur charges based on their compute, infrastructure, and storage use. See [Openflow BYOC cost and scaling considerations](/user-guide/data-integration/openflow/cost-byoc) for more information.
%ofsfspcs-plural%
Openflow - Snowflake Deployments are containers for runtimes and are deployed using a [compute pool](/developer-guide/snowpark-container-services/working-with-compute-pool). They incur utilization charges based on their uptime and usage of compute. See [Openflow Snowflake Deployment cost and scaling considerations](/user-guide/data-integration/openflow/cost-spcs) for more information.
Runtime
Runtimes host data pipelines, with the framework providing security, simplicity, and scalability. You can deploy Openflow runtimes in your VPC using Openflow. You can deploy Openflow connectors to your runtimes, and also build completely new pipelines using Openflow processors and controller services.
%ofsfspcs% Runtime
Openflow - Snowflake Deployment Runtimes are deployed as a [Snowpark Container Services](/developer-guide/snowpark-container-services/overview) service to an %ofsfspcs% deployment, which is represented by an underlying compute pool. Customers request a Runtime through the deployment, which executes a request on behalf of the user. Once created, customers access it via a web browser at the URL generated for that underlying service.
--- title: About Openflow - Snowflake Deployments source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/about-spcs.md section: Loading & Unloading Data --- # About %ofsfspcs-plural% This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). - [Set up Openflow - Snowflake Deployment - Task overview](/user-guide/data-integration/openflow/setup-openflow-spcs) - [Openflow Snowflake Deployment cost and scaling considerations](/user-guide/data-integration/openflow/cost-spcs) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Monitor Openflow using telemetry data](/user-guide/data-integration/openflow/monitor) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index) %ofsfspcs% runs on [Snowpark Container Services (SPCS)](/developer-guide/snowpark-container-services/overview) and provides a streamlined and integrated solution for data integration and connectivity across interoperable storage like Iceberg and Snowflake native storage. As a fully self-contained service within Snowflake, it's easy to deploy and manage, offering a convenient and cost-effective environment for running your data flows. A key advantage is its native integration with Snowflake's security model, which allows seamless authentication, authorization, and network security, and simplified operations. Although customers can have both BYOC and Snowflake Deployments, the following are use cases that are well-suited to Snowflake Deployments: - Incorporating full-fidelity data in the bronze layer: Landing raw data from various sources directly into Snowflake and using Openflow Snowflake Deployments to extract and load. - Enriching data: Running pipelines to enrich tables that already exist inside Snowflake. - From ingest to insight in one place: Building applications where the entire data lifecycle (ingest, process and serve) happens within the Snowflake ecosystem. - Transforming raw data to insights with AI: Ingesting unstructured data and then, for instance, using %sf-intelligence% to search and understand it better, all in concert with users' other structured data. - Employing reverse ETL: Closing the loop on insight generation by sharing with external operational systems via APIs, messaging infrastructure, and more. ## Understanding execute-as roles and External Access Integrations %ofsfspcs-plural% must be able to interact with data sources and destinations that are typically outside Snowflake. In addition, these deployments must also be able to communicate with and access Snowflake itself. Execute-as roles and external access integrations provide this support. ### What is an execute-as role? An execute-as role is a Snowflake role bound to a specific Openflow runtime. Connectors that use `SNOWFLAKE_MANAGED` authentication run with this role's privileges (or those of a child role granted to it). The execute-as role is used for the following tasks: - Grant access to external access integrations (EAIs). These EAIs specify rules that allow the runtime to access the data sources and destinations from within Snowflake itself. - Grant access to Snowflake resources. - Grant access to resources that are connector-specific. Because execute-as roles are linked to Openflow session tokens, you don't need to create separate service users and key pairs for authentication to Snowflake. ### What is an External Access Integration (EAI) within Openflow? An [External access integration](/developer-guide/external-network-access/external-network-access-overview) (EAI) is a Snowflake object designed to provide secure access to external resources, like source systems from which Openflow connectors pull external data. Openflow Snowflake Deployments use EAIs and network rules together to define the endpoints an Openflow connector can read from or write to. Data engineers define and configure EAIs and execute-as roles specific to a given connector and its underlying runtime. ## Typical %ofsfspcs% workflow The following sections describe %ofsfspcs% concepts and workflows.
User persona Task Snowflake administrator - Configures core Snowflake and external access integrations. See [Set up Openflow - Snowflake Deployment - Task overview](/user-guide/data-integration/openflow/setup-openflow-spcs). - Creates a set of deployments in Snowflake. The Openflow UI is used to manage deployments and runtime creation and maintenance. The Openflow UI allows users to create, upgrade, and delete runtimes in all deployments. Data engineer (pipeline author, responsible for data ingestion)
- Works with a Snowflake administrator to configure required allow-listed domains so that %ofsfspcs% can access the external data sources. - Creates execute-as roles, external integrations, and other objects that can later be used by runtimes. - Uses the runtime canvas to build completely new flows or to configure deployed connectors. Creates a completely new flow or uses an existing connector as-is or as a starting point to customize.
Connectors are a simple way to solve for a specific integration use case, and less technical users can deploy them without assistance from a data engineer. Data engineer (pipeline operator) Configures flow parameters and runs the flow. Data engineer (responsible for transformation to silver and gold layers) Responsible for transforming data from the bronze layer that was populated by the pipeline to silver and gold layers for analytics. Business user Makes use of gold layer objects for analytics.
## Deployment and runtime hierarchy Openflow separates management from execution: - The **control plane** is the layer you use to create, upgrade, and observe deployments and runtimes through the Openflow UI or APIs. On %ofsfspcs-plural%, Snowflake operates the control plane. - A **deployment** is the data plane container for your runtimes. Each deployment is backed by a [compute pool](/developer-guide/snowpark-container-services/working-with-compute-pool). An account can have multiple %ofsfspcs-plural% to separate workloads by project, team, or environment. See [Create deployment](/user-guide/data-integration/openflow/setup-openflow-spcs-deployment). - A **runtime** hosts your data flows within a deployment. Each deployment can host multiple runtimes, and each runtime has its own execute-as role and network access configuration. See [Create runtime](/user-guide/data-integration/openflow/setup-openflow-spcs-create-runtime). For definitions of all Openflow components, see [Openflow components](/user-guide/data-integration/openflow/about#label-openflow-components). ## Limitations - Users with a default role of ACCOUNTADMIN can't login to %ofsfspcs% runtimes and will get an error message when attempting to do so. - Customers requiring private connectivity will need to configure [outbound PrivateLink](/user-guide/private-connectivity-outbound). PrivateLink is available to [](#label-snowflake-editions-business-critical) only. ### Next steps [Set up Openflow - Snowflake Deployment - Task overview](/user-guide/data-integration/openflow/setup-openflow-spcs) --- title: About Openflow Connector for Amazon Ads source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/amazon-ads/about.md section: Loading & Unloading Data --- # About %amazonads% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Set up the Openflow Connector for Amazon Ads](/user-guide/data-integration/openflow/connectors/amazon-ads/setup) This topic describes the basic concepts of %amazonads%, its workflow, and limitations. The %amazonads% automatically ingests Amazon Ads (https://advertising.amazon.com/) data into your Snowflake account by using Amazon Ads Reporting API V3 (https://advertising.amazon.com/API/docs/en-us/guides/reporting/v3/overview). Reporting API enables you to configure custom reports with selected report types (https://advertising.amazon.com/API/docs/en-us/guides/reporting/v3/report-types/overview), columns (https://advertising.amazon.com/API/docs/en-us/guides/reporting/v3/columns), filters and other groupings. Use this connector if you're looking to do the following: - Bring data from Amazon Ads for Ad performance statistics and insights ## Workflow 1. A **Amazon Ads administrator** gets access to Reporting API by following the onboarding instructions (https://advertising.amazon.com/API/docs/en-us/guides/onboarding/overview), generates a refresh token (https://advertising.amazon.com/API/docs/en-us/guides/get-started/retrieve-access-token) and retrieves the client ID and client secret (https://advertising.amazon.com/API/docs/en-us/guides/onboarding/create-lwa-app#retrieve-your-security-credentials). 2. 1. A **Snowflake account administrator** performs the following: 3. Installs the connector. 4. Configures the connector with the required parameters, for example refresh token, report configuration, and database and schema names. 5. Runs the connector flow. The connector does the following: 1. Fetches the specified report as specified in the connector configuration. 2. Creates a temporary table and puts the report chunks in it. 3. Creates a table in the provided destination schema. 4. Synchronises data from the temporary table to the destination table. 5. Removes the temporary table. 6. **Marketing users** with Snowflake access can view and perform operations on the data downloaded from Amazon Ads to destination tables. ## Limitations - The connector supports incremental ingestion only for the daily value of `Report Time Increment` parameter. - Modification of the report definition when the processors are running might lead to data inconsistencies. To ensure consistency, stop the processors and clear the queues before updating the configuration. - If the Amazon Ads API rate limit (https://advertising.amazon.com/API/docs/en-us/reference/concepts/rate-limiting) is reached, the data doesn't get ingested despite the connector attempting to pull data from the source system. ## Next steps [Set up the Openflow Connector for Amazon Ads](/user-guide/data-integration/openflow/connectors/amazon-ads/setup) --- title: About Openflow Connector for Box source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/box/about.md section: Loading & Unloading Data --- # About %box% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Set up the Openflow Connector for Box](/user-guide/data-integration/openflow/connectors/box/setup) This topic describes the basic concepts of %box%, its workflow, and limitations. The %box% connects a Box enterprise with Snowflake. Use this connector to do the following: - Ingest Box content for your own custom processing in Snowflake - Ingest Box content and make it ready for chat in your AI assistants with Snowflake Cortex - Use Box AI to extract metadata from Box content for enrichment in Snowflake - Add enriched metadata from Snowflake to content in Box ## Workflow 1. A **Box developer** creates a Box Platform app and submits it for authorization. 2. A **Box administrator** authorizes the app. 3. The **Box developer** then performs the following tasks: 1. Shares a Box folder with the app service account. 2. Shares a Platform app configuration JSON file and a folder ID with a Snowflake account administrator. 4. A **Snowflake account administrator** performs the following tasks: 1. Installs the connector. 2. Configures the connector with Snowflake connection details and the data provided by the Box developer. 3. Runs the connector flow. The connector does the following: 1. Creates the required tables, stages, and a Cortex Search service in the specified Snowflake schema. 2. Fetches Box file content and permissions from the folder specified in the connector configuration. 3. Runs parsing and chunking on the fetched documents, and saves them in Snowflake tables. The saved chunks are automatically indexed by the Cortex Search service. 5. A **Chatbot developer** uses the Cortex Search service to build a chatbot application. ## Limitations - [Cortex Parse Document limitations and requirements](#label-parse-document-requirements) - [Cortex Search limitations](#label-cortex-search-overview-limitations) - Changes caused by moving folders out of the specified root folder aren't captured during incremental ingestion. - The connector ingests only the supported file types and ignores others. These limitations apply to the predefined connector flow. If the flow is customized and doesn't use some or all of the predefined components, then these limitations may not apply. ## Next steps [Set up the Openflow Connector for Box](/user-guide/data-integration/openflow/connectors/box/setup) --- title: About Openflow Connector for Google Ads source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/google-ads/about.md section: Loading & Unloading Data --- # About %gadsof% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Set up the Openflow Connector for Google Ads](/user-guide/data-integration/openflow/connectors/google-ads/setup) This topic describes the basic concepts of Openflow Connector for Google Ads, steps to set it up, and limitations. Google Ads is an online advertising platform where advertisers can create and run ads to promote their products or services. Through Google Ads, you can create online ads to reach people exactly when they're interested in offered products and services. The Openflow Connector for Google Ads: - Automatically ingests Google Ads data into your Snowflake account. - Downloads data using the Google Ads API (https://cloud.google.com/endpoints/docs/openapi/enable-api). - Lets you configure custom reports with chosen attributes, metrics (https://developers.google.com/google-ads/api/fields/v17/metrics), and segments (https://support.google.com/google-ads/answer/2454072). Use this connector if you're looking to do the following: - Import metrics from Google Ads for performance tracking and optimization ## Use cases ### Run the connector in different ingestion modes There are two ways of ingesting data incrementally and as a snapshot. Snapshot mode is a default one and is on as long as **segments.date** segment is not selected. It creates a table in the provided destination schema and appends on each schedule the newest data from Google Ads. To configure incremental ingestion user has to fill Report Segments parameter with segment named **segments.date**, other segments can be still preset. Then data will be overlapped between the one we fetched previously and the date range of the current run. The overlap is caused by the conversion window as we need to ask for the historical data for the number of days that's equal to the conversion window, for example, if the conversion window is set to 14 days and the ingestion happens every day, there is 13 days of overlap. ### Reconfigure currently running connector The report configuration can be changed when the processor is running. To do so go to GetGoogleAdsReportContext and change your desired parameters. Upon changing only Report Attributes, Metrics or Segments parameters, the current destination table will be removed and a new one with updated schema will be created, so before updating them please be aware that already downloaded data will be deleted. When the Resource Name or Account Client ID will be changed a new table will be created. The old destination table will not be dropped. Modifying the Schedule and Conversion window will not affect in any way the data already fetched in the destination table. When the Start Date will be changed, the connector will perform a single ingestion from that date to the current date and then proceed as normally in incremental mode. If there is data downloaded from the period between new Start Date and current date it will be replaced after change. Data before the new Start Date will not be affected. #### Rate Limiting Restrictions Google Ads API limits (https://developers.google.com/google-ads/api/docs/access-levels) govern how many requests can be made within a given time frame. If your flow exceeds the allowed quota, syncs may slow down or fail with an error. This mostly occurs when your access token makes higher number of requests than the source typically allows. In such cases, we recommend applying for higher access quota (wherever appliable) or reducing the sync frequency. ## Limitations - Filtering is not supported. Instead, data can be filtered after ingestion. - Custom column ingestion is not supported. - When segmenting reports, if all selected metrics are zero, they are always excluded. - Attributed resource ingestion is not supported. Instead, multiple reports can be joined after ingestion. - There can be only one report for selected resource name and client id pair. - Modification of report definition when processors are running may lead to data inconsistencies. To ensure consistency, before updating configuration stop processors and clear queues. ## Next steps [Set up the Openflow Connector for Google Ads](/user-guide/data-integration/openflow/connectors/google-ads/setup) --- title: About Openflow Connector for Google Drive source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/google-drive/about.md section: Loading & Unloading Data --- # About %gdof% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Set up the Openflow Connector for Google Drive](/user-guide/data-integration/openflow/connectors/google-drive/setup) The %gdof% connects a Google Workspace Shared Drive and Snowflake to ingest files and user permissions and keeps them up to date. %gdof% also supports the Cortex Search service and can make ingested files ready for conversational analysis for use in AI Assistants using SQL, Python or REST APIs. Use this connector if you're looking to do the following: - Ingest Google Drive content for your own custom processing in Snowflake - Ingest Google Drive content and make it ready for chat in your AI assistants with Snowflake Cortex ## Limitations 1. [Cortex Parse Document limitations and requirements](#label-parse-document-requirements). 2. [Cortex Search limitations](#label-cortex-search-overview-limitations). 3. Changes caused by moving or renaming folders aren't captured during incremental ingestion. 4. The connector supports only explicit Google Permissions for Users and Groups. It does not currently support authentication models for links shared with Anyone. 5. The connector ingests only the supported file types and ignores others. Please note, the limitations are listed for the predefined versioned flow. If the flow was customized, and it doesn't use some of the predefined components, the limitations related to these components won't apply. ## Next steps [Set up the Openflow Connector for Google Drive](/user-guide/data-integration/openflow/connectors/google-drive/setup) --- title: About Openflow Connector for Google Sheets source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/google-sheets/about.md section: Loading & Unloading Data --- # About %sheets% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Set up the Openflow Connector for Google Sheets](/user-guide/data-integration/openflow/connectors/google-sheets/setup) This topic describes the basic concepts of %sheets%, its workflow, and limitations. The %sheets% enables the ingestion of Google Sheets data into Snowflake. It uses the Google Sheets API to fetch data and persist that data in a table dedicated to a given range from a sheet. The connector creates the destination table in the database and the schema provided in the configuration. Use this connector if you're looking to do the following: - Load data from Google sheets into Snowflake tables for reporting, analytics and insights ## Workflow 1. A **Google Cloud administrator** creates a service account and a key as described in Service account credentials (https://developers.google.com/workspace/guides/create-credentials#service-account). 2. A **Google Sheets user** creates a Google Sheets spreadsheet and shares it with the service account. The first row of data represents the column names in the destination table that the connector will create. It cannot contain actual data. If a column contains multiple data types, the connector selects the least restrictive type. 3. A **Snowflake account administrator** configures the connector as follows: 1. Installs the connector. 2. Creates Snowflake warehouse, destination database, destination schema, and key. 3. Specifies the required parameters for the connector, such as Snowflake Warehouse, Destination Database, Snowflake Key, and Spreadsheet ID. 4. Runs the connector flow. The connector performs the following tasks when run in Openflow: 1. Retrieves the data from a specified spreadsheet. 2. Creates and updates the destination table to reflect the schema of data from Google Sheets. If the destination table is not created, then it is truncated. 3. Inserts the data into the destination table. ## Limitations - The connector saves numeric values from a sheet only as INT or DOUBLE types. Because of this, small rounding errors may occur in the least significant digits if sheets contain floating point numbers. The connector currently doesn't support higher precision. - Incremental load is not supported. The connector uses the truncate and load ingestion strategy. ## Next steps [Set up the Openflow Connector for Google Sheets](/user-guide/data-integration/openflow/connectors/google-sheets/setup) --- title: About Openflow Connector for HubSpot source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/hubspot/about.md section: Loading & Unloading Data --- # About %hubspot% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Set up the Openflow Connector for HubSpot](/user-guide/data-integration/openflow/connectors/hubspot/setup) This topic describes the basic concepts of %hubspot%, its workflow, and limitations. The %hubspot% ingests HubSpot data into Snowflake. It uses the HubSpot API to retrieve data, which is then stored in a Snowflake table. Data ingestion happens in the following two phases: 1. Initial load, where all data is retrieved during the first API call. 2. Incremental load, which merges the updates and new data into the destination table and uses timestamps from previous calls to limit the result to the issues that were updated since the last data load. For more information about HubSpot private apps, see Private apps (https://developers.hubspot.com/docs/guides/apps/private-apps/overview). Use this connector if you're looking to do the following: - Get HubSpot CRM data into Snowflake for reporting, analytics, and insights ## Workflow 1. A HubSpot administrator performs the following tasks: 1. Generates an API token within the HubSpot instance with the necessary scopes required for the API requests intended to make. This token is used by the connector for authentication. 2. Defines the criteria to search objects like `Object Types` and `Updated After (optional)` fields. 2. A Snowflake account administrator performs the following tasks: 1. Installs the connector. 2. Configures the connector parameters: - Provides the HubSpot private app API token. - Defines the criteria for the objects being ingested by providing filters. - Sets the desired database and schema names within Snowflake. 3. Runs the connector flow. Upon execution, the connector does the following: 1. Creates an API call to fetch objects from the configured HubSpot instance. 2. Extracts the relevant data. 3. Creates the configured destination table in the Snowflake database if the API call returned at least one result. 4. Loads raw data into the specified Snowflake table and creates a processed view on top of the raw data. ## Limitations - When multiple object types are defined, filtering by 'Updated After' applies to all object types defined in the parameter context. - Currently, the connector supports basic authentication using a HubSpot private app and API token. This means that the connector is only able to ingest data that is accessible to the owner of the API token. - The processors are designed to work on the primary node only with one thread. - The number of calls your private app can make is based on your account subscription. To learn more about HubSpot private app limits, see Private app limits (https://developers.hubspot.com/docs/guides/apps/private-apps/overview#private-app-limits). ## Next steps [Set up the Openflow Connector for HubSpot](/user-guide/data-integration/openflow/connectors/hubspot/setup) --- title: About Openflow Connector for Jira Cloud source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/jira-cloud/about.md section: Loading & Unloading Data --- # About %jira% This feature is not available in the People's Republic of China. - **Generally available:** The %jiracore% flow. - **[Public Preview](https://www.snowflake.cn/en/legal/optional-offerings/offering-specific-terms/preview-terms-of-service/):** The %jiraagile% flow. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and Google Cloud Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Set up the Atlassian Jira Cloud (Core) flow](/user-guide/data-integration/openflow/connectors/jira-cloud/setup-core) - [Set up the Atlassian Jira Cloud (Agile) flow](/user-guide/data-integration/openflow/connectors/jira-cloud/setup-agile) - [Migrate from the legacy Openflow Connector for Jira Cloud](/user-guide/data-integration/openflow/connectors/jira-cloud/migrate-from-legacy) This topic describes the basic concepts of %jira%, its workflow, and limitations. The %jira% ingests data from multiple Atlassian Jira Cloud entities into Snowflake. It consists of two separate flows: - **Core flow** — uses the Jira Cloud REST API (https://developer.atlassian.com/cloud/jira/platform/rest/v3/intro/#about) to retrieve issues, projects, comments, changelogs, worklogs, users, deleted issues, votes, watchers, remote links, issue security schemes, and lookup tables for issue type, priority, resolution, and status. - **Agile flow** — uses the Jira Agile REST API (https://developer.atlassian.com/cloud/jira/software/rest/intro/#about) to retrieve boards, sprints, board-sprint mappings, board-project mappings, and board-issue mappings. Both flows store data in dedicated Snowflake tables with explicit column schemas. The two flows can write to the same Snowflake destination schema, since they create tables with different names. Use this connector if you're looking to do the following: - Centralize Jira data in Snowflake for cross-team visibility and deeper insights into engineering, support, and project workflows - Ingest a broad set of Jira entities into separate, query-ready Snowflake tables, with a selectable subset of optional tables - Extract Jira issues with per-project parallel ingestion for faster data loads - Track deleted issues via Jira audit log polling - Optionally ingest Jira Agile data using the separate agile flow If you previously deployed an earlier version of the Jira Cloud connector, see [Migrate from the legacy Openflow Connector for Jira Cloud](/user-guide/data-integration/openflow/connectors/jira-cloud/migrate-from-legacy) for a step-by-step migration guide. ## Destination tables The connector creates the following tables in the configured Snowflake destination schema. Most tables have a fixed column schema defined by the connector. The `ISSUE` table is the exception: its columns are driven by the `Issue Fields` configuration and may include custom fields from your Jira instance. See [](#label-jira-core-issue-fields) for details. ### Core flow tables The `ISSUE`, `PROJECT`, `USER`, and `FIELD` tables are always created. The remaining tables are created only when the corresponding table name is listed in the `Enabled Tables` parameter (or, for `DELETED_ISSUE`, when delete tracking is enabled). See [](#label-jira-core-ingestion-parameters) for details.
Table Enabled by Contents ISSUE Always One row per Jira issue. The set of columns is driven by the `Issue Fields` configuration and may include custom fields. Fields such as issue type, priority, resolution, and status are stored as Jira IDs. Join to the following lookup tables to resolve names. PROJECT Always One row per Jira project visible to the API token owner. USER Always Jira users encountered during ingestion. FIELD Always Metadata for Jira issue fields used to drive the dynamic `ISSUE` schema. CHANGELOG `CHANGELOG` Issue field change history, one row per changelog entry. COMMENT `COMMENT` Comments attached to issues, one row per comment. ISSUE_REMOTE_LINK `ISSUE_REMOTE_LINK` Remote links attached to issues. ISSUE_SECURITY_SCHEME `ISSUE_SECURITY_SCHEME` Issue-level security schemes and levels defined in the Jira instance. ISSUE_TYPE `ISSUE_TYPE` Issue type names and hierarchy. Join to `ISSUE` on `ISSUE.ISSUE_TYPE = ISSUE_TYPE.ID`. ISSUE_VOTE `ISSUE_VOTE` Per-issue vote records. ISSUE_WATCHER `ISSUE_WATCHER` Per-issue watcher records. PERMISSION `PERMISSION` Global and project permission definitions. PRIORITY `PRIORITY` Priority names. Join to `ISSUE` on `ISSUE.PRIORITY = PRIORITY.ID`. PROJECT_COMPONENT `PROJECT_COMPONENT` Components defined in each project. PROJECT_VERSION `PROJECT_VERSION` Release versions defined in each project. RESOLUTION `RESOLUTION` Resolution names. Join to `ISSUE` on `ISSUE.RESOLUTION = RESOLUTION.ID`. STATUS `STATUS` Status names and categories. Join to `ISSUE` on `ISSUE.STATUS = STATUS.ID`. USER_GROUP `USER_GROUP` Group memberships per user. WORKLOG `WORKLOG` Time tracking entries on issues. DELETED_ISSUE `Deletes Fetch Strategy = AUDIT` Issues deleted from Jira, tracked via audit log.
### Agile flow tables The following tables are created by the agile flow. To populate these tables, install and run the agile flow separately from the core flow. The `BOARD` table is always created. The remaining tables are gated by the agile flow's own `Enabled Tables` parameter.
Table Enabled by Contents BOARD Always Agile boards visible to the API token owner. SPRINT `SPRINT` Sprints across all ingested boards. BOARD_SPRINT `SPRINT` Board-to-sprint mappings. BOARD_PROJECT `BOARD_PROJECT` Board-to-project mappings. BOARD_ISSUE `BOARD_ISSUE` Board-to-issue mappings.
### Connector-managed columns In addition to the columns derived from the Jira API response, the connector adds the following metadata columns. `_SNOWFLAKE_INSERTED_AT` and `_SNOWFLAKE_UPDATED_AT` are added to every destination table. `_SNOWFLAKE_DELETED` is added only to tables that track soft deletes. To see which tables have it, inspect the destination tables in Snowflake.
Column Type Purpose `_SNOWFLAKE_INSERTED_AT` `TIMESTAMP_NTZ` When the row was first inserted by the connector. `_SNOWFLAKE_UPDATED_AT` `TIMESTAMP_NTZ` When the row was last updated by the connector. `_SNOWFLAKE_DELETED` `BOOLEAN` `TRUE` when the source record is no longer present in the corresponding Jira API response (for example, an issue deleted in Jira, or a comment removed from an issue). The row remains in the destination table. Filter on `_SNOWFLAKE_DELETED = FALSE` to exclude soft-deleted records.
## Workflow 1. A **Jira Cloud administrator** performs the following tasks: 1. Generates an API token within the Jira instance. This token is used by the connector for authentication. Both tokens with scopes and tokens without scopes are supported, although tokens with scopes are recommended for fine-grained access control. The required scopes depend on which features are enabled. See [](#label-jira-core-api-scopes) for details. 2. Optionally, if delete tracking is required, ensures the API token owner has the **Administer Jira** global permission for access to the audit log endpoint. 2. A **Snowflake account administrator** performs the following tasks: 1. Installs the core flow, the agile flow, or both, depending on which entities are needed. 2. Configures each flow: 1. Provides the Jira API token and email address. 2. Specifies the Jira instance URL. 3. For the core flow, optionally filters ingestion to specific projects using `Project Keys Filter` and configures the issue fields to ingest. 4. Sets the database and schema names in the Snowflake account. 3. Runs the flow in the Openflow canvas. Upon execution: - The **core flow** discovers projects and registers them in the ingestion state service, fetches issues in parallel across projects along with the per-issue tables listed in `Enabled Tables` (and optionally deleted issues), and fetches worklogs, users, user groups, permissions, project components, project versions, issue security schemes, and the `ISSUE_TYPE`, `PRIORITY`, `RESOLUTION`, and `STATUS` lookup tables on independent schedules. - The **agile flow** fetches boards, sprints, board-project mappings, board-sprint mappings, and board-issue mappings. 3. **Snowflake business users** can then query the destination tables directly with standard SQL, without needing to flatten JSON. ## Openflow requirements - The minimum runtime size is `Small`. When you have many tables listed in `Enabled Tables`, more processors run concurrently and the default Small runtime thread budget may become a bottleneck. In that case, move to a `Medium` runtime (or larger). - The connector supports multi-node Openflow runtimes. Each flow's state service is cluster-aware, and the flow connections use load balancing where appropriate so that work is distributed across available nodes. If you want to run on multiple nodes, configure a static cluster size by setting **Min nodes** to the target node count rather than relying on autoscaling. The connector doesn't generate enough sustained load on the runtime to trigger the runtime to scale up additional nodes on its own. - For Jira instances with many projects, a multi-node runtime is recommended. Per-project work is distributed across nodes, so adding nodes increases the number of projects the connector processes in parallel. Use the project count as a rough guide when sizing **Min nodes**. - The connector is primarily limited by Jira API rate limits rather than runtime compute capacity. Increasing the runtime size beyond `Medium`, or adding more nodes than the API rate budget can sustain, is unlikely to improve ingestion speed. - The core flow and agile flow can run on the same or separate Openflow runtimes. If you run both flows on the same runtime, `Small` isn't sufficient — use at least `Medium` (or larger, depending on the load). ## Limitations - Basic authentication using an email and API token is the only supported authorization method. The connector can only ingest data accessible to the owner of the API token. - Delete tracking via the `AUDIT` strategy requires the API token owner to have the **Administer Jira** global permission. The Jira audit log has limited retention (typically 6 months for Jira Premium, less for Free or Standard plans). If the connector is paused for longer than the retention period, delete events can be missed. - Schema evolution for the `ISSUE` table is additive only. New columns can be added, but column type changes or removals aren't supported. If a Jira custom field type changes, the connector may require redeployment. - The `ISSUE` table schema is dynamic and depends on the `Issue Fields` configuration. Fields not included in the resolved field set aren't loaded, and there is no raw JSON fallback. Issue type, priority, resolution, and status are stored as Jira IDs. Enable the `ISSUE_TYPE`, `PRIORITY`, `RESOLUTION`, and `STATUS` lookup tables (they're in the default `Enabled Tables` value) and join them to resolve names. - Narrowing `Project Keys Filter` to remove a project doesn't delete that project's rows from the destination tables. Rows that were previously ingested remain in place and are no longer updated. To remove orphaned rows after a filter change, manually delete them from the destination tables. - Agile data (boards, sprints, board mappings) is fully re-fetched on every scheduled run of the agile flow. For Jira instances with many boards, this may result in increased API usage. - Each connector instance can be associated with only one Jira Cloud site. ## Next steps - [Set up the Atlassian Jira Cloud (Core) flow](/user-guide/data-integration/openflow/connectors/jira-cloud/setup-core) to install the core flow. - [Set up the Atlassian Jira Cloud (Agile) flow](/user-guide/data-integration/openflow/connectors/jira-cloud/setup-agile) to install the agile flow. - [Migrate from the legacy Openflow Connector for Jira Cloud](/user-guide/data-integration/openflow/connectors/jira-cloud/migrate-from-legacy) if you're moving from a previous version of the Jira Cloud connector. --- title: About Openflow Connector for LinkedIn Ads source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/linkedin-ads/about.md section: Loading & Unloading Data --- # About %linkedinads% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Set up the Openflow Connector for LinkedIn Ads](/user-guide/data-integration/openflow/connectors/linkedin-ads/setup) This topic describes the basic concepts, workflow, and limitations of %linkedinads%. The %linkedinads% enables you to ingest LinkedIn Ads metrics into Snowflake. This connector uses the Reporting API (https://learn.microsoft.com/en-us/linkedin/marketing/integrations/ads-reporting/ads-reporting?view=li-lms-2025-02&tabs=http) to fetch data. The connector persists data in a table dedicated to a given report. Each report can be configured to contain metrics, pivots, and facets chosen by the user. The connector creates the destination table in the database and the schema provided in the configuration. Use this connector if you're looking to do the following: - Import campaign performance data from LinkedIn Ads to Snowflake for reporting, analytics and insights ## Workflow 1. A **LinkedIn Ads user** obtains credentials required to connect to LinkedIn Ads API. 2. A **Snowflake account administrator** performs the following tasks: 1. Installs the connector. 2. Configures the connector with the required parameters. 3. Runs the connector. The following happens when the connector is run in Openflow: 1.
Retrieves the data based on the specified configuration.
If the Time Granularity parameter is set to `DAILY`, then the connector downloads only the data for a calculated timeframe. In other cases, the connector downloads all the data from the start date to the current time.
2. Creates a temporary table and inserts the downloaded data into it. 3. Recreates or updates the destination table to reflect the schema of data from LinkedIn Ads. If you change the schema, the connector drops the destination table and recreates it with a new schema. If `DAILY` time granularity is chosen in the Time Granularity parameter, then outdated data is deleted from the destination table. 4. Inserts the data into the destination table with an additional insertion timestamp. 5. Drops the temporary table. ## Limitations - All metrics of type BigDecimal are saved as Strings. [Conversion functions](/sql-reference/functions-conversion) allow you to convert values manually to numeric types with chosen scale and precision. - Some metrics and pivots return values that are IDs. The connector does not use the URN resolution (https://learn.microsoft.com/en-us/linkedin/marketing/integrations/ads-reporting/ads-reporting?view=li-lms-2025-02&tabs=http#urn-resolution). - The connector uses the Authorization Code Flow (https://learn.microsoft.com/en-us/linkedin/shared/authentication/authorization-code-flow?context=linkedin%2Fcontext&tabs=HTTPS1) because the Client Credentials Flow (https://learn.microsoft.com/en-us/linkedin/shared/authentication/client-credentials-flow?context=linkedin%2Fcontext&tabs=HTTPS1) is not available for Marketing API. This means that the refresh token must be refreshed manually every year. --- title: About Openflow Connector for Meta Ads source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/meta-ads/about.md section: Loading & Unloading Data --- # About %metaads% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Set up the Openflow Connector for Meta Ads](/user-guide/data-integration/openflow/connectors/meta-ads/setup) This topic describes the basic concepts of %metaads%, its workflow, and limitations. Meta Ads is an online advertising platform, which you can use to create and run ads to promote your products or services on Meta products, such as Facebook and Instagram. The %metaads% automatically ingests Meta Ads data into your Snowflake account by using Meta Ads Insights API (https://developers.facebook.com/docs/marketing-api/insights). Insights API enables you to configure custom reports with selected fields, breakdowns (https://developers.facebook.com/docs/marketing-api/insights/breakdowns), and other aggregations. Use this connector if you're looking to do the following: - Bring Meta Ads data to unify and analyze your marketing performance ## Workflow 1. A **Meta Ads administrator** performs the following: 1. Creates a Meta Ads app (https://developers.facebook.com/docs/development/create-an-app/). 2. Enables Marketing API (https://developers.facebook.com/docs/marketing-api/get-started). 3. Acquires a long-lived token (https://developers.facebook.com/docs/facebook-login/guides/access-tokens/get-long-lived/). 2. A **Snowflake account administrator** performs the following: 1. Installs the connector. 2. Configures the connector with the required parameters, for example long-lived token, report configuration, and database and schema names. 3. Runs the connector flow. The connector does the following: 1. Fetches the specified report as specified in the connector configuration. 2. Creates a temporary table and puts the report chunks in it. 3. Creates a table in the provided destination schema. 4. Synchronises data from the temporary table to the destination table. 5. Removes the temporary table. 3. **Marketing users** with Snowflake access can view and perform operations on the data downloaded from Meta Ads to destination tables. ## Limitations - The connector supports incremental ingestion only for the daily value of `Report Time Increment` parameter. - Modification of the report definition when the processors are running might lead to data inconsistencies. To ensure consistency, stop the processors and clear the queues before updating the configuration. - If the Meta Ads API rate limit (https://developers.facebook.com/docs/graph-api/overview/rate-limiting/#ads-insights) is reached, the data doesn't get ingested even though the connector continues attempting to pull data from the source system. To increase the rate limit, change the app access type (https://developers.facebook.com/docs/marketing-api/overview/rate-limiting) from `Standard access` to `Advanced access` of the Ads Management Standard Access, and enable the `ads_read` and `ads_management` permissions (https://developers.facebook.com/docs/permissions/). - Data can be fetched only from the past 37 months, as defined by Meta Ads. ## Next steps [Set up the Openflow Connector for Meta Ads](/user-guide/data-integration/openflow/connectors/meta-ads/setup) --- title: About Openflow Connector for Microsoft Dataverse source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/dataverse/about.md section: Loading & Unloading Data --- # About %dataverse% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Set up the Openflow Connector for Microsoft Dataverse](/user-guide/data-integration/openflow/connectors/dataverse/setup) The Openflow Connector for Microsoft Dataverse connects a Microsoft Dataverse storage and Snowflake to ingest Microsoft Dataverse tables and keeps them up to date on Snowflake side. The outcome of the connector are selected tables replicated on Snowflake Account in a database and schema specified by the user. Use this connector if you're looking to do the following: - Integrate data from Microsoft Power Platform and Dynamics 365 applications with Snowflake for holistic business insights ## Connector-managed columns In addition to the columns replicated from the Dataverse table, every destination table has the following connector-managed columns:
Column Type Purpose `_SNOWFLAKE_ID` `VARCHAR` The identifier of the record in Dataverse, taken from the primary key of the source table. `_SNOWFLAKE_UPDATED_AT` `VARCHAR` The time at which the connector last replicated the row, in ISO 8601 format, for example `2026-08-11T15:04:05.123Z`. `_SNOWFLAKE_DELETED` `BOOLEAN` Whether the record was deleted at the source.
Deletes are replicated as soft deletes: when a record is deleted in Dataverse, the connector keeps the row in the destination table and sets `_SNOWFLAKE_DELETED` to `TRUE`. To query only the records that currently exist in Dataverse, filter on `_SNOWFLAKE_DELETED = FALSE`. If you enable the `Include Formatted Values` parameter, each destination table also has a `_DATAVERSE_FORMATTED_VALUES` column of type `OBJECT`. For more information, see [](/user-guide/data-integration/openflow/connectors/dataverse/setup#label-include-formatted-values). ## Rate limiting restrictions Microsoft Dataverse API limits (https://learn.microsoft.com/en-us/power-apps/developer/data-platform/api-limits?tabs=sdk#how-service-protection-api-limits-are-enforced) govern how many requests can be made within a given time frame. If your flow exceeds the allowed quota, syncs may slow down or fail with an error. This mostly occurs when your access token makes higher number of requests than the source typically allows. In such cases, we recommend applying for higher access quota (wherever applicable) or reducing the sync frequency. ### Limitations - Only tables with enabled change tracking can be replicated - Schema of destination tables is discovered from the database metadata through REST APIs. Whenever new columns are added to the table, they appear in the destination table. Changes and removals of columns are not reflected in the destination table. - All limitations of Microsoft Dataverse Web API (https://learn.microsoft.com/en-us/power-apps/maker/data-platform/api-limits-overview) apply. - Supported set of column types is limited by set of types supported by [Snowpipe Streaming](#label-snowpipe-streaming-supported-java-data-types). - Each instance of the connector supports a single schedule. If you need multiple schedules, then you need to install multiple instances of the connector. - Empty tables are not replicated. - Removal of a table is not replicated. If a table was replicated previously and is removed, it will remain in destination schema. - Delta tokens used for change tracking expire after 7 days of inactivity by default. If the connector is not run for more than 7 days, the delta token expires and the connector must perform a full resync of the affected tables. This duration is controlled by the `ExpireChangeTrackingInDays` setting in the Microsoft Dataverse organization configuration. ### Next steps [Set up the Openflow Connector for Microsoft Dataverse](/user-guide/data-integration/openflow/connectors/dataverse/setup) --- title: About Openflow Connector for MySQL source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/mysql/about.md section: Loading & Unloading Data --- # About %mysql% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Set up the Openflow Connector for MySQL](/user-guide/data-integration/openflow/connectors/mysql/setup) - [Openflow Connector for MySQL: Data mapping](/user-guide/data-integration/openflow/connectors/mysql/data-mapping) This topic describes the basic concepts of %mysql%, its workflow, and limitations. ## About the %mysql% The %mysql% connects a MySQL database instance to Snowflake and replicates data from selected tables in near real-time or on a specified schedule. The connector also creates a log of all data changes, which is available along with the current state of the replicated tables. The connector also supports MariaDB as a source database. ## Use cases Use this connector if you're looking to do the following: - CDC replication of MySQL or MariaDB tables into Snowflake for comprehensive, centralized reporting ## Supported MySQL versions The following table lists the tested and officially supported MySQL versions.
8.0 8.4 Standard MySQL (https://www.mysql.com/) Yes Yes AWS RDS (https://docs.aws.amazon.com/AmazonRDS/latest/UserGuide/CHAP_MySQL.html) Yes Yes Amazon Aurora (https://docs.aws.amazon.com/AmazonRDS/latest/AuroraMySQLReleaseNotes/Welcome.html) Yes, as Version 3 Not applicable. Aurora 8.4 isn't currently supported. GCP Cloud SQL (https://cloud.google.com/sql/mysql?hl=en) Yes Yes Azure Database (https://azure.microsoft.com/en-us/products/mysql/) Yes Yes Percona Server (https://www.percona.com/software/mysql-database/percona-server) Yes Yes
## Supported MariaDB versions The following table lists the tested and officially supported MariaDB versions.
11.4 or later Standard MariaDB (https://mariadb.org/) Yes AWS RDS (https://docs.aws.amazon.com/AmazonRDS/latest/UserGuide/CHAP_MariaDB.html) Not applicable. AWS RDS for MariaDB isn't currently supported.
## Openflow requirements - Choose the runtime size based on the sustained replication workload. For sizing guidance and how to run multiple connectors on one runtime, see [Runtime sizing](/user-guide/data-integration/openflow/connectors/cdc-runtime-sizing). - The connector doesn't support multi-node Openflow runtimes. Configure the runtime for this connector with **Min nodes** and **Max nodes** set to `1`. ## Limitations - The connector supports MySQL version 8 or later and MariaDB version 11.4 or later. - The connector supports only username and password authentication with MySQL or MariaDB. - Only database tables that have a primary key, a NOT NULL unique index, or a configured logical key can be replicated. When no primary key is defined, MySQL's InnoDB storage engine automatically promotes the first NOT NULL unique index to act as the primary key, and the connector uses it as the replication key. For tables with neither a primary key nor a qualifying unique index, you can configure a logical key as the replication key. For more information, see [](#label-mysql-logical-key). - The connector doesn't replicate tables with data that exceeds [Snowflake's type limitations](/sql-reference/intro-summary-data-types). - The connector doesn't replicate columns of types GEOMETRY, GEOMETRYCOLLECTION, LINESTRING, MULTILINESTRING, MULTIPOINT, MULTIPOLYGON, POINT, and POLYGON. - The connector is subject to the Group Replication limitations of MySQL (https://dev.mysql.com/doc/refman/8.4/en/group-replication-limitations.html#group-replication-limitations-transaction-size). This means that a single transaction must fit into a binary log message of size no more than 4 GB. - The connector doesn't support replicating tables from a reader instance in Amazon Aurora as Aurora reader instances don't maintain their own binary logs. - The connector supports common source table schema changes during replication, such as adding, dropping, and renaming columns. See [Schema changes](#label-database-schema-changes) for the full list and a few unsupported change types. - For `DATE` and `DATETIME` types in MySQL or MariaDB, any values that contain a zero month or day are mapped to the Unix epoch ('1970-01-01' or '1970-01-01T00:00'). Date zero ('0000-00-00') is also mapped to the Unix epoch. Values with a zero year are converted to year one, for example, '0000-05-30 7:59:59' becomes '0001-05-30T7:59:59'. The remaining date and time components are unchanged. - For `TIMESTAMP` types in MySQL or MariaDB, value '0000-00-00 00:00:00' is mapped to the Unix epoch ('1970-01-01T00:00Z'). - The connector doesn't capture cascade delete operations (ON DELETE CASCADE). Foreign key cascade deletions are executed internally by InnoDB (the storage engine used by MySQL and MariaDB) and aren't recorded in the binary log, resulting in incomplete replication of dependent table deletions to Snowflake. - The connector doesn't support the truncate table operation. `TRUNCATE` statements on the source are ignored, and the corresponding row deletions are not applied to the destination table. Limitations affecting certain table columns can be bypassed by excluding these specific columns from replication. ## Workflow 1. A **MySQL or MariaDB database administrator** performs the following tasks: - Configure MySQL or MariaDB replication settings - Create credentials for the connector - (Optionally) Provide the SSL certificate 2. An **Openflow administrator** creates a warehouse for the connector and a destination database for the replicated data. 3. An **Openflow administrator** or a **data engineer** performs the following tasks: 1. Installs the connector. 2. Specifies the required parameters for the flow template. 3. Runs the flow. The connector performs the following tasks when run in Openflow: 1. Creates a schema for journal tables. 2. Creates the schemas and destination tables matching the source tables configured for replication. 3. Starts replicating the tables. For details on the replication process, see [How tables are replicated](#how-tables-are-replicated). ## How the connector works The following sections describe how the connector works in various scenarios, including replication, changes in schema, and data retention. ### Data replication The name of the destination schema is determined by the `Destination Schema Pattern` parameter. For more information, see [](#label-of-mysql-destination-parameters). By default, the destination schema name matches the source database name, so the fully qualified name of a destination table is: `..` ### How tables are replicated The tables are replicated in the following stages: 1. Schema introspection: The connector discovers the columns in the source table, including the column names and types, then validates them against Snowflake's and the connector's [Limitations](#limitations). Validation failures cause this stage to fail, and the cycle completes. After successful completion of this stage, the connector creates an empty destination table. 2. Snapshot load: The connector copies all data available in the source table into the destination table. If this stage fails, then no more data is replicated. After successful completion, the data from the source table is available in the destination table. 3. Incremental load: The connector tracks changes in the source table and applies those changes to the destination table. This process continues until the table is removed from replication. Failure at this stage permanently stops replication of the source table, until the issue is resolved. This connector can be configured to immediately start replicating incremental changes for newly added tables, bypassing the snapshot load phase. This option is often useful when reinstalling the connector in an account where previously replicated data exists and you want to continue replication without having to re-snapshot tables. For details on bypassing the snapshot load and using the incremental load process, see [Incremental replication](/user-guide/data-integration/openflow/connectors/mysql/incremental-replication). Interim failures, such as connection errors, do not prevent tables from being replicated. Permanent failures, such as unsupported data types, do prevent tables from being replicated. If a permanent failure prevents a table from being replicated, remove the table from the list of replicated tables. After you address the problem that caused the failure, you can add the table back to the list of replicated tables. ### Schema changes During incremental replication, the connector detects many source table schema changes and updates the destination table automatically. Unsupported changes stop replication for the affected table until you restart it. #### Supported changes The connector supports the following schema changes: - **Add column.** The connector adds the column to the destination table and replicates values for new and updated rows. Existing rows aren't backfilled; the new column is NULL for rows that existed before the change. - **Drop column.** The connector renames the destination column with a `__SNOWFLAKE_DELETED` suffix to preserve historical values. For details, see [Dropped columns](#dropped-columns). - **Rename column.** The connector treats a rename as dropping the original column and adding a new one. The connector retains the original column under a suffixed name; for example, a column named `A` becomes `A__SNOWFLAKE_DELETED`. For query patterns, see [Renamed columns](#renamed-columns). - **Compatible type change.** The connector keeps replication running with the destination column type unchanged when you change a column to a source type that maps to the same Snowflake data type (for example, `INT` to `BIGINT`, both mapped to `NUMBER`). - **Re-add a previously dropped column.** The connector adds the column as a new destination column alongside the existing soft-deleted column (for example, `A` and `A__SNOWFLAKE_DELETED`). If you drop a column that was previously dropped and soft-deleted, replication for the affected table fails because the soft-deleted column name is already taken. #### Unsupported changes The connector doesn't support the following schema changes. When one occurs, replication stops for the affected table: - **Primary key definition change.** Adding or removing primary key columns, or changing which columns form the primary key. - **Incompatible type change.** When the new source type maps to a different Snowflake data type (for example, `INT` to `VARCHAR`, mapped to `NUMBER` and `TEXT` respectively). - **Numeric precision or scale change.** For example, changing `NUMERIC(7,2)` to `NUMERIC(6,3)`. - **Character column length change.** For example, changing `VARCHAR(50)` to `VARCHAR(100)`. To recover, restart replication for the affected table: see [Restart table replication](#label-of-mysql-restart-table-replication). The same soft-delete mechanism applies when you change a table's Column Filter JSON. For details, see [Replicate a subset of columns in a table](#label-mysql-connector-replication-subset-of-columns). ### Track data changes in tables The connector replicates not only the current state of data from the source tables, but also every state of every row from every changeset. This data is stored in journal tables created in the same schema as the destination table. The journal table names are formatted as `_JOURNAL__`, where `` is the value of epoch seconds when the source table was added to replication, and `` is an integer increasing with every schema change on the source table. As a result, source tables that undergo schema changes will have multiple journal tables. When a table is removed from replication, then added back, the `` value will change, and `` will start again from `1`. Snowflake recommends that you don't alter the structure of journal tables in any way. They are used by the connector to update the destination table as part of the replication process. ### How the connector chooses a replication key The connector uses one column or set of columns from each source table as the replication key. The replication key uniquely identifies a row and drives the MERGE operation that applies CDC changes to the destination. For each table, the connector resolves the replication key in this order: 1. **User-declared logical key.** If the connector is configured with a Table Key Configuration Service that lists the table, the connector uses those columns as the replication key, overriding any primary key. For more information, see [](#label-mysql-logical-key). 2. **Primary key.** The columns of the table's primary key constraint. When no explicit primary key is defined, MySQL's InnoDB storage engine automatically promotes the first NOT NULL unique index to act as the primary key, and the connector uses it as the replication key. 3. **None.** If no primary key or qualifying unique index exists, the connector can't replicate the table. To enable replication, add a primary key, add a NOT NULL unique index, or declare a logical key. For more information, see [](#label-mysql-logical-key). The following examples illustrate each replication key scenario: A table with an explicit primary key (no special setup required): ```sql CREATE TABLE orders ( order_id BIGINT PRIMARY KEY, customer_id INT, total DECIMAL(10, 2) ); ``` The connector uses `order_id` as the replication key. A table without an explicit primary key, where InnoDB promotes a NOT NULL unique index to act as the primary key: ```sql CREATE TABLE sessions ( session_token VARCHAR(64) NOT NULL, user_id INT, created_at DATETIME, UNIQUE KEY idx_session_token (session_token) ); ``` InnoDB promotes `session_token` to act as the primary key, and the connector uses it as the replication key. A table with no primary key or qualifying unique index, replicated using a logical key: ```sql CREATE TABLE audit_events ( event_id CHAR(36) NOT NULL, event_type VARCHAR(100), payload JSON ); ``` Configure a logical key on `event_id` in the Table Key Configuration JSON. For setup instructions, see [](#label-mysql-logical-key). ### Changes to a replication key value When a source update changes the replication key value of an existing row, the connector can't update the destination row in place because the row's identity changes. Instead, it splits the source update into two operations on the destination table: 1. The destination row keyed by the **old** value is soft-deleted: its `_SNOWFLAKE_DELETED` metadata column is set to `TRUE`. 2. A new destination row is inserted keyed by the **new** value, with the updated payload and `_SNOWFLAKE_DELETED` set to `FALSE`. The destination table therefore contains two rows after the change: the original row, soft-deleted, and a new row under the new key value. To query only current rows, filter on `_SNOWFLAKE_DELETED = FALSE`. This behavior applies when the replication key is a primary key or a user-declared logical key. ### Oversized values By default, the connector replicates individual values up to **16 MB**. When the connector encounters a larger value, it marks the associated table as permanently failed and stops replicating it. To change how the connector handles oversized values (for example, to replace them with `NULL` instead), modify the **Oversized Value Strategy** destination parameter. If your Snowflake account has the `ENABLE_OPENFLOW_CDC_MYSQL_SSV2` parameter set to `true`, the per-value limit can be raised from 16 MB to **128 MB**. For details and instructions on enabling the 128 MB per-value limit, see [](/user-guide/data-integration/openflow/connectors/mysql/maintenance#label-of-mysql-increase-oversized-value-limit). ### Error handling for invalid rows An *invalid row* is a row that Snowflake rejects during ingestion because it can't be written to the destination table, for example a value that can't be converted to the destination column's type, or a missing required column. The **Error Handling Strategy** parameter controls what the connector does when it encounters an invalid row: - **Fail Table** (default): On the first invalid row, the connector marks the table as permanently failed and stops replicating it, preserving strict, all-or-nothing replication. After you fix the source data, resume replication as described in [Restart table replication](/user-guide/data-integration/openflow/connectors/mysql/maintenance#label-of-mysql-restart-table-replication). - **Log Errors and Continue**: The connector keeps replicating the valid rows and records each rejected row, together with its original payload and error details, in the table's *error table*. The table isn't marked as failed. To change the strategy, set the **Error Handling Strategy** parameter. For more information, see [](/user-guide/data-integration/openflow/connectors/mysql/setup#label-of-mysql-destination-parameters). #### How rejected rows are captured The connector loads data with Snowpipe Streaming, so error logging behaves exactly as described in [Error logging in Snowpipe Streaming](/user-guide/snowpipe-streaming/snowpipe-streaming-error-tables). When you select **Log Errors and Continue**, the connector creates new destination and journal tables with the [`ERROR_LOGGING`](/user-guide/snowpipe-streaming/snowpipe-streaming-error-tables#turn-on-error-logging) property set to `TRUE`, so rejected rows are captured in a dedicated error table instead of aborting the load. The error table stores the original payload sent to Snowflake before any transformation, along with error details. Query a table's error table with the `ERROR_TABLE` table function: ```sql SELECT * FROM ERROR_TABLE(..) ORDER BY timestamp; ``` Where a rejected row lands depends on the replication stage: - **Snapshot load**: The rejected row is written to the destination table's error table. - **Incremental (CDC) load**: The rejected row is written to the journal table's error table, because CDC changes are first written to the journal table. For more information about journal tables, see [](#track-data-changes-in-tables). The connector enables error logging only on tables that it creates after you select **Log Errors and Continue**. To capture rejected rows for tables that were already being replicated, enable error logging on their existing destination and journal tables with the stored procedure in [Enable error logging on an existing schema](/user-guide/data-integration/openflow/connectors/mysql/maintenance#label-of-mysql-enable-error-logging-existing-schema). When the connector encounters invalid rows, it emits a `WARN` log entry that includes the number of rejected rows. Use these entries to monitor rejected-row activity. #### Consume rejected rows To process rejected rows programmatically, create a stream on the error table and consume it like any other Snowflake stream. For more information, see [Streams on error tables](/user-guide/data-load-overview#streams-on-error-tables). # Understanding data retention The connector follows a data retention philosophy where customer data is never automatically deleted. You maintain full ownership and control over your replicated data, and the connector preserves historical information rather than permanently removing it. This approach has the following implications: - Rows deleted from the source table are soft-deleted in the destination table rather than physically removed. - Columns dropped from the source table are renamed in the destination table rather than dropped. - Journal tables are retained indefinitely and are not automatically cleaned up. ## Destination table metadata columns Each destination table includes the following metadata columns that track replication information:
## Soft-deleted rows When a row is deleted from the source table, the connector does not physically remove it from the destination table. Instead, the row is marked as deleted by setting the `_SNOWFLAKE_DELETED` metadata column to `true`. This approach allows you to: - Retain historical data for auditing or compliance purposes. - Query deleted records when needed. - Decide when and how to permanently remove data based on your requirements. To query only active (non-deleted) rows, filter on the `_SNOWFLAKE_DELETED` column: ```sql SELECT * FROM my_table WHERE _SNOWFLAKE_DELETED = FALSE; ``` To query deleted rows: ```sql SELECT * FROM my_table WHERE _SNOWFLAKE_DELETED = TRUE; ``` ## Dropped columns When a column is dropped from the source table, the connector does not drop the corresponding column from the destination table. Instead, the column is renamed by appending the `__SNOWFLAKE_DELETED` suffix to preserve historical values. For example, if a column named `EMAIL` is dropped from the source table, it is renamed to `EMAIL__SNOWFLAKE_DELETED` in the destination table. Rows that existed before the column was dropped retain their original values, while rows added after the drop have `NULL` in this column. You can still query historical values from the renamed column: ```sql SELECT EMAIL__SNOWFLAKE_DELETED FROM my_table; ``` ## Renamed columns Due to limitations in CDC (Change Data Capture) mechanisms, the connector cannot distinguish between a column being renamed and a column being dropped followed by a new column being added. As a result, when you rename a column in the source table, the connector treats this as two separate operations: dropping the original column and adding a new column with the new name. For example, if you rename a column from `A` to `B` in the source table, the destination table will contain: - `A__SNOWFLAKE_DELETED`: Contains values from before the rename. Rows added after the rename have `NULL` in this column. - `B`: Contains values from after the rename. Rows that existed before the rename have `NULL` in this column. ### Querying renamed columns To retrieve data from both the original and renamed columns as a single unified column, use a `COALESCE` or `CASE` expression: ```sql SELECT COALESCE(B, A__SNOWFLAKE_DELETED) AS A_RENAMED_TO_B FROM my_table; ``` Alternatively, using a `CASE` expression: ```sql SELECT CASE WHEN B IS NOT NULL THEN B ELSE A__SNOWFLAKE_DELETED END AS A_RENAMED_TO_B FROM my_table; ``` ### Creating a view for renamed columns Rather than manually modifying the destination table, you can create a view that presents the renamed column as a single unified column. This approach is recommended because it preserves the original data and avoids potential issues with ongoing replication. ```sql CREATE VIEW my_table_unified AS SELECT *, COALESCE(B, A__SNOWFLAKE_DELETED) AS A_RENAMED_TO_B FROM my_table; ``` Manually modifying the destination table structure (such as dropping or renaming columns) is not recommended, as it may interfere with ongoing replication and cause data inconsistencies. ## Journal tables During incremental replication, changes from the source database are first written to journal tables before being merged into the destination tables. The connector does not automatically remove data from journal tables, as this data may be useful for auditing, debugging, or reprocessing purposes. Journal tables are created in the same schema as their corresponding destination tables and follow this naming convention: `_JOURNAL__` Where: - `` is the name of the destination table. - `` is the creation timestamp in Unix epoch format (seconds since January 1, 1970), ensuring uniqueness. - `` starts at 1 and increments whenever the destination table schema changes, either due to schema changes in the source table or modifications to column filters. For example, if your destination table is `SALES.ORDERS`, the journal table might be named `SALES.ORDERS_JOURNAL_1705320000_1`. Do not drop journal tables while replication is in progress. Removing an active journal table may cause data loss or replication failures. Only drop journal tables after the corresponding source table has been fully removed from replication. ### Managing journal table storage If you need to manage storage costs by removing old journal data, you can create a Snowflake task that periodically cleans up journal tables for tables that are no longer being replicated. Before implementing journal cleanup, verify that: - The corresponding source tables have been fully removed from replication. - You no longer need the journal data for auditing or processing purposes. For information on creating and managing tasks for automated cleanup, see [Introduction to tasks](/user-guide/tasks-intro). ## Next steps Review [Openflow Connector for MySQL: Data mapping](/user-guide/data-integration/openflow/connectors/mysql/data-mapping) to understand how the connector maps data types to Snowflake data types. Review [Set up the Openflow Connector for MySQL](/user-guide/data-integration/openflow/connectors/mysql/setup) to set up the connector. --- title: About Openflow Connector for Oracle source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/oracle/about.md section: Loading & Unloading Data --- # About %oracleofc% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). The %oracleofc% is also subject to additional terms of service beyond the standard connector terms of service. For more information, see the [Openflow Connector for Oracle Addendum](https://www.snowflake.cn/en/legal/optional-offerings/offering-specific-terms/openflow-oracle-terms/). - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Openflow Connector for Oracle: Enable and manage commercial terms](/user-guide/data-integration/openflow/connectors/oracle/manage-commercial-terms) - [Openflow Connector for Oracle: Data mapping](/user-guide/data-integration/openflow/connectors/oracle/data-mapping) - [Set up tasks for the Openflow Connector for Oracle](/user-guide/data-integration/openflow/connectors/oracle/setup-tasks) This topic describes the basic concepts of %oracleofc%, its workflow, and limitations. ## About the %oracleofc% The %oracleofc% connects an Oracle database instance to Snowflake and replicates data from selected tables in near real-time or on a specified schedule. The connector also creates a log of all data changes, which is available along with the current state of the replicated tables. ## Use cases The connector supports the following use case: - Replicate Oracle database tables into Snowflake for comprehensive, centralized reporting. ## Licensing models and critical constraints The %oracleofc% supports three distinct licensing models. You must select the correct model before installation. Failure to select the correct model might result in deployment failure or unintended financial commitments. For detailed licensing terms, comparison, and configuration instructions, see [Oracle XStream licensing](#label-oracle-xstream-licensing). The connector is technically compatible with Oracle Database Standard Edition (SE/SE2). However, Oracle documentation states that "a license to Oracle Database Enterprise Edition is a prerequisite to license and use Oracle XStream." Before deploying the connector against a Standard Edition database, verify your Oracle license agreement to ensure that your use of XStream is permitted. You're solely responsible for compliance with your Oracle license terms. ### 1. Embedded license for 36-month commitment (Snowflake-provided) In Openflow, this license option is displayed as **Oracle Embedded License**. Snowflake provides the Oracle XStream license to you directly for a fee. This model allows you to consume XStream replication without a direct contract with Oracle. For more information, see [Embedded license details for 36-month commitment](#label-oracle-embedded-license-details-36) and the [Openflow Connector for Oracle Addendum](https://www.snowflake.cn/en/legal/optional-offerings/offering-specific-terms/openflow-oracle-terms/).
### 2. Embedded license for 12-month commitment (Snowflake-provided) In Openflow, this license option is displayed as **Oracle Embedded License (Public Sector)**. Snowflake provides the Oracle XStream license to you directly for a fee. This model allows you to consume XStream replication without a direct contract with Oracle. For more information, see [Embedded license details for 12-month commitment](#label-oracle-embedded-license-details-12) and the [Openflow Connector for Oracle Addendum](https://www.snowflake.cn/en/legal/optional-offerings/offering-specific-terms/openflow-oracle-terms/).
### 3. Independent license (Bring Your Own License, BYOL) You provide your own Oracle license that includes XStream entitlements (for example, Oracle GoldenGate license). For more information, see [Independent license (BYOL) details](#label-oracle-byol-license-details).
## Choosing an Oracle XStream licensing model The %oracleofc% requires a paid license for Oracle XStream services. Three licensing models are available: - Oracle Embedded License (36-month commitment) - Oracle Embedded License (12-month commitment) - Independent Oracle License (Bring Your Own License, BYOL) Use the following table to determine the appropriate model for your organization.
## Embedded license details for 36-month commitment By choosing this option, you are procuring the right to use Oracle XStream technology with the connector through Snowflake. Be aware of the following key terms: ### Billing Oracle XStream services are billed monthly and drawn from your Snowflake capacity balance. The fee has two components: a license fee and a Support & Maintenance (S&M) fee. The license fee is calculated based on the number of processor cores in your source Oracle database, multiplied by the Oracle Processor Licensing Factor. ### Commitment The first 60 days are free for up to 16 licensed cores. However, activating the connector beyond the 60-day trial initiates a non-cancelable 36-month billing term. - **Automatic conversion**: Billing commences automatically on Day 61. To avoid charges, you must cancel the trial in the **Admin** %raa% **Terms** %raa% **Openflow for Oracle** dashboard before Day 60. - **Lock-in**: If your Snowflake agreement is terminated during this term, the entire remaining balance for the 36-month term becomes due immediately. ### Post-term renewal and penalties After the initial 36-month term, the license fee becomes $0 but the Support & Maintenance (S&M) fee continues. - **Opt-out consequence**: You can opt out of S&M renewal through the dashboard in **Admin** %raa% **Terms** %raa% **Openflow for Oracle**. However, if S&M coverage stops, the connector processors are locked. To resume operations, you must purchase a new Embedded License, which resets the 36-month full-price commitment. ### Requirements You are responsible for accurately reporting the number of processor cores and the correct licensing factor in the connector configuration. This information must be kept current if your source database hardware changes. ### Configuration To configure the Embedded License (36-month commitment): - Review and accept the [Openflow Connector for Oracle Addendum](https://www.snowflake.cn/en/legal/optional-offerings/offering-specific-terms/openflow-oracle-terms/) terms presented in the UI. - Select the **Oracle Embedded License** tile for the 36-month commitment. - Enter the CPU core count details for your source Oracle database: **Oracle Database Processor Cores** (the total number of physical cores on the source database server) and **Oracle Database Processor Multiplier** (the Oracle processor licensing factor, for example, 0.5 for Intel processors). Consult the Oracle Processor Core Factor Table for the correct value. ## Embedded license details for 12-month commitment By choosing this option, you are procuring the right to use Oracle XStream technology with the connector through Snowflake under a 12-month, upfront-billed commitment. Be aware of the following key terms: ### Billing Oracle XStream services are billed upfront and drawn from your Snowflake capacity balance. The fee has two components: a license fee and a Support & Maintenance (S&M) fee. The license fee is calculated based on the number of processor cores in your source Oracle database, multiplied by the Oracle Processor Licensing Factor. ### Commitment The first 60 days are free for up to 16 licensed cores. However, activating the connector beyond the 60-day trial initiates a non-cancelable 12-month billing term. - **Automatic conversion**: Billing commences automatically on Day 61. To avoid charges, you must cancel the trial in the **Admin** %raa% **Terms** %raa% **Openflow for Oracle** dashboard before Day 60. - **Lock-in**: If your Snowflake agreement is terminated during this term, the entire remaining balance for the 12-month term becomes due immediately. ### Post-term renewal and penalties After the initial 12-month term, the license fee becomes $0 but the Support & Maintenance (S&M) fee continues on an annual basis. - **Opt-out consequence**: You can opt out of S&M renewal through the dashboard in **Admin** %raa% **Terms** %raa% **Openflow for Oracle**. However, if S&M coverage stops, the connector processors are locked. To resume operations, you must purchase a new Embedded License, which resets the 12-month full-price commitment. ### Requirements You are responsible for accurately reporting the number of processor cores and the correct licensing factor in the connector configuration. This information must be kept current if your source database hardware changes. ### Configuration To configure the Embedded License (12-month commitment): - Review and accept the [Openflow Connector for Oracle Addendum](https://www.snowflake.cn/en/legal/optional-offerings/offering-specific-terms/openflow-oracle-terms/) terms presented in the UI. - Select the **Oracle Embedded License (Public Sector)** tile for the 12-month commitment. - Enter the CPU core count details for your source Oracle database: **Oracle Database Processor Cores** (the total number of physical cores on the source database server) and **Oracle Database Processor Multiplier** (the Oracle processor licensing factor, for example, 0.5 for Intel processors). Consult the Oracle Processor Core Factor Table for the correct value. ## Independent license (BYOL) details This option is for customers who have already licensed the necessary Oracle technology. ### Requirements You are solely responsible for ensuring that your use of the connector complies with the terms of your existing Oracle license agreement. Snowflake doesn't validate or audit your Oracle entitlements. ### Configuration To configure the Independent License (BYOL): - Review and accept the [Openflow Connector for Oracle Addendum](https://www.snowflake.cn/en/legal/optional-offerings/offering-specific-terms/openflow-oracle-terms/) terms presented in the UI. - Select the **Independent License** type. When configuring the connector, proceed without entering any core count or billing-related information. ## Openflow requirements The following Openflow runtime requirements apply to the %oracleofc%: - Choose the runtime size based on the sustained replication workload. For sizing guidance and how to run multiple connectors on one runtime, see [Runtime sizing](#label-oracle-runtime-sizing). - The connector doesn't support multi-node Openflow runtimes. Configure the runtime for this connector with **Min nodes** and **Max nodes** set to `1`. ## Supported Oracle versions and platforms The following Oracle database versions and platforms are supported: - Oracle database versions 11g and later - On-premises servers - Oracle Exadata - OCI VM/Bare Metal - AWS Custom RDS for Oracle - AWS Standard Single-tenant RDS for Oracle ## Data Guard and standby support You can keep replication load off the primary Oracle database by connecting to a Data Guard standby. Which topology you need depends on whether the standby is physical or logical. ### Active Data Guard (physical standby) Active Data Guard is a *physical* standby: a read-only copy of the primary. You can't create an XStream outbound server on it, because XStream needs a writable database for the metadata. The connector still works with Active Data Guard. Use the physical standby for snapshot load (`Oracle Connection URL`). For incremental (CDC) load, create the XStream outbound server on a writable database (`XStream Out Server URL`): the primary, or a separate downstream capture (https://docs.oracle.com/en/database/oracle/oracle-database/19/xstrm/xstream-out-concepts.html) database if you want to keep CDC off the primary as well. When you run the snapshot against Active Data Guard, set **Snapshot Fetching Strategy** to `SEQUENTIAL_BY_PRIMARY_KEY`. The default `CONCURRENT_BY_ROWID` strategy uses parallel tasks to split a table into ranges, which isn't allowed on a read-only standby. ### Logical standby A *logical* standby is open read-write and applies changes from the primary with SQL Apply. The connector can use a logical standby for both snapshot and CDC, so you don't need an additional database for XStream. Before you create the outbound server or start the connector, set Database Guard to `STANDBY`. Logical standbys default to `ALL`, which blocks the XStream client with `ORA-16224: Database Guard is enabled`. For setup steps, see [](/user-guide/data-integration/openflow/connectors/oracle/setup-oracledb#label-oracle-standby-setup). ## Limitations The following limitations apply to the %oracleofc%: - AWS Standard Multi-tenant RDS for Oracle isn't supported. - Oracle Autonomous Databases (ATP/ADW) aren't supported. - Oracle SaaS offerings such as Oracle Fusion Cloud Applications and NetSuite aren't supported. - Active Data Guard physical standbys are read-only, so create the XStream outbound server on the primary, a logical standby, or a separate downstream capture database. For details, see [](#label-oracle-standby-data-guard-support). - The connector requires Openflow deployment version 0.55.0 or later for BYOC. - The Openflow runtime must be created after the required Openflow deployment version is installed. - Each replicated table must have a primary key, a qualifying unique constraint, a qualifying unique index, or a user-declared logical key. For more information, see [](#label-oracle-replication-key-selection). - The connector supports common source table schema changes during replication, such as adding, dropping, and renaming columns. See [Schema changes](#label-database-schema-changes) for the full list and a few unsupported change types. - Schema changes (such as ALTER TABLE statements that add or drop columns) aren't supported while re-reading the redo logs from the earliest position. If any table's schema was altered between the earliest available SCN and the current position, that table should be removed from replication and re-added with a fresh snapshot instead. - The connector doesn't detect at runtime when you drop or modify the primary key, unique constraint, or unique index that it uses as the replication key. This limitation also applies to renaming a replication-key column. After any such change, restart replication for the affected table: see [](#label-of-oracle-restart-table-replication). - When a logical-key value changes on the source, the connector doesn't soft-delete the old row, which results in duplicate active rows in the destination. For more information, see [](#label-oracle-logical-key-value-change). - Updates that modify only a part of a large object (`LOB`) value by using the `DBMS_LOB` package, for example `DBMS_LOB.WRITEAPPEND`, `DBMS_LOB.WRITE`, `DBMS_LOB.ERASE`, or `DBMS_LOB.TRIM`, aren't supported. Oracle XStream reports only the part of the `LOB` value that changed, but the connector needs the entire value to reconcile the merge query, so affected `LOB` columns are replicated as `NULL` in Snowflake. A common pattern that triggers this is inserting a row with `EMPTY_CLOB()` (or `EMPTY_BLOB()`) and then populating the `LOB` by using `DBMS_LOB.WRITEAPPEND`. When a `LOB` is written inline in a single INSERT or UPDATE statement, it is replicated correctly. For small `LOB` values, `DBMS_LOB.WRITEAPPEND` may produce an UPDATE LCR with the entire value, in which case the row is replicated correctly. When the connector observes an unsupported partial `LOB` operation, it logs a WARN-level message identifying the source table and primary key of the affected row so the change can be reconciled manually. - The connector doesn't support the truncate table operation. `TRUNCATE` statements on the source are ignored, and the corresponding row deletions are not applied to the destination table. ## How the connector works The following sections describe how the connector works in different contexts, including replication, schema changes, and data retention. ### How tables are replicated The name of the destination schema is determined by the `Destination Schema Pattern` parameter. For more information, see [](#label-oracle-snowflake-destination-parameters). By default, the destination schema name is the source database name and source schema name joined by an underscore, so the fully qualified name of a destination table is: `._.` The tables are replicated in the following stages: 1. Schema introspection: The connector discovers the columns in the source table, including the column names and types, then validates them against Snowflake's and the connector's [Limitations](#limitations). Validation failures cause this stage to fail, and the cycle completes. After successful completion of this stage, the connector creates an empty destination table in Snowflake. 2. Snapshot load: The connector copies all data available in the source table into the destination table. If this stage fails, then no more data is replicated. After successful completion, the data from the source table is available in the destination table. 3. Incremental load: The connector tracks changes in the source table and applies those changes to the destination table. This process continues until the table is removed from replication. Failure at this stage permanently stops replication of the source table until the issue is resolved. ### Schema changes During incremental replication, the connector detects many source table schema changes and updates the destination table automatically. Unsupported changes stop replication for the affected table until you restart it. #### Supported changes The connector supports the following schema changes: - **Add column.** The connector adds the column to the destination table and replicates values for new and updated rows. Existing rows aren't backfilled; the new column is NULL for rows that existed before the change. - **Drop column.** The connector renames the destination column with a `__SNOWFLAKE_DELETED` suffix to preserve historical values. For details, see [Dropped columns](#dropped-columns). - **Rename column.** The connector treats a rename as dropping the original column and adding a new one. The connector retains the original column under a suffixed name; for example, a column named `A` becomes `A__SNOWFLAKE_DELETED`. For query patterns, see [Renamed columns](#renamed-columns). - **Compatible type change.** The connector keeps replication running with the destination column type unchanged when you change a column to a source type that maps to the same Snowflake data type (for example, `INT` to `BIGINT`, both mapped to `NUMBER`). - **Re-add a previously dropped column.** The connector adds the column as a new destination column alongside the existing soft-deleted column (for example, `A` and `A__SNOWFLAKE_DELETED`). If you drop a column that was previously dropped and soft-deleted, replication for the affected table fails because the soft-deleted column name is already taken. #### Unsupported changes The connector doesn't support the following schema changes. When one occurs, replication stops for the affected table: - **Primary key definition change.** Adding or removing primary key columns, or changing which columns form the primary key. - **Incompatible type change.** When the new source type maps to a different Snowflake data type (for example, `INT` to `VARCHAR`, mapped to `NUMBER` and `TEXT` respectively). - **Numeric precision or scale change.** For example, changing `NUMERIC(7,2)` to `NUMERIC(6,3)`. - **Character column length change.** For example, changing `VARCHAR(50)` to `VARCHAR(100)`. To recover, restart replication for the affected table: see [Restart table replication](#label-of-oracle-restart-table-replication). For incompatible type changes, the connector might report an Oracle parameter type conflict before the destination table is updated. The same soft-delete mechanism applies when you change a table's Column Filter JSON. For details, see [Replicate a subset of columns in a table](#label-oracle-connector-replication-subset-of-columns). ### How the connector chooses a replication key The connector uses one column or set of columns from each source table as the replication key. The replication key uniquely identifies a row, drives the MERGE operation that applies CDC changes to the destination, and orders rows during the snapshot load. For each table, the connector resolves the replication key in this order: 1. **User-declared logical key.** If the connector is configured with a Table Key Configuration Service that lists the table, the connector uses those columns as the replication key, overriding any primary key, unique constraint, or unique index on the table. For more information, see [](#label-oracle-logical-key). 2. **Primary key.** The columns of the table's enabled primary key constraint. 3. **Unique constraint or unique index.** If the table has no primary key, the connector looks for a qualifying unique constraint or unique index, as described in [](#label-oracle-replication-key-uk-criteria). 4. **None.** If no qualifying key is found, the connector can't replicate the table. To resolve this, either add a primary key to the table, modify an existing constraint or index so it qualifies (see the following criteria), or declare a logical key on columns that uniquely identify rows. For diagnostic steps, see [](#label-oracle-no-replication-key) in the troubleshooting topic. #### Qualifying unique constraints and unique indexes The connector evaluates a unique constraint as a candidate replication key only when: - The constraint type is `UNIQUE` and `STATUS = ENABLED` in `ALL_CONSTRAINTS`. - The constraint isn't initially deferred (`DEFERRED = IMMEDIATE`). Constraints declared `DEFERRABLE INITIALLY IMMEDIATE` qualify; `DEFERRABLE INITIALLY DEFERRED` doesn't. - All columns covered by the constraint are `NOT NULL`. The connector evaluates a unique index as a candidate replication key only when: - `UNIQUENESS = UNIQUE` and the index isn't `UNUSABLE` in `ALL_INDEXES`. - `INDEX_TYPE = NORMAL` (a standard B-tree index). Bitmap and function-based unique indexes are excluded. - The index isn't the implementation of a primary or unique constraint (constraint-backed indexes are evaluated through the constraint, not separately). - All columns covered by the index are `NOT NULL`. `LOB`, `CLOB`, `NCLOB`, `LONG`, and similar large-object columns can't appear in unique constraints or unique indexes in Oracle, so they never qualify as replication-key columns. #### Tiebreakers When more than one candidate qualifies, the connector picks one deterministically using the following preferences, in order: 1. Among all candidates, a unique constraint is preferred over a unique index. 2. Among candidates of the same type, the candidate with the fewest columns is preferred. 3. Among candidates with the same column count, the candidate with the most numeric columns is preferred. The connector counts the following Oracle types as numeric: `NUMBER`, `INTEGER`, `INT`, `SMALLINT`, `FLOAT`, `DOUBLE`, `BINARY_FLOAT`, `BINARY_DOUBLE`. 4. If a tie remains, the candidate with the lowest constraint or index name in alphabetical order is selected. If you want a specific column set used regardless of the tiebreaker outcome, declare it as a logical key. For more information, see [](#label-oracle-logical-key). #### Replication key examples The following table has no primary key but has a unique constraint on a `NOT NULL` column. The constraint qualifies, and the connector replicates the table using the constraint as the replication key: ```sql CREATE TABLE customers ( email VARCHAR2(255) NOT NULL, name VARCHAR2(100), created_at TIMESTAMP DEFAULT SYSTIMESTAMP, CONSTRAINT uk_customers_email UNIQUE (email) ); ``` The following table has no primary key and no unique constraint, but a unique B-tree index on a `NOT NULL` column. The index qualifies, and the connector replicates the table using the index as the replication key: ```sql CREATE TABLE sessions ( session_id VARCHAR2(64) NOT NULL, user_id NUMBER, created_at TIMESTAMP ); CREATE UNIQUE INDEX idx_sessions_id ON sessions (session_id); ``` The following table doesn't qualify for automatic replication-key selection: the unique-constraint column is nullable. To replicate this table, add a `NOT NULL` constraint, replace the column with one that's `NOT NULL`, or specify a logical key: ```sql CREATE TABLE products ( sku VARCHAR2(50), name VARCHAR2(100), CONSTRAINT uk_products_sku UNIQUE (sku) ); ``` ### Changes to a replication key value When a source update changes the replication key value of an existing row, the connector can't update the destination row in place because the row's identity changes. Instead, it splits the source update into two operations on the destination table: 1. The destination row keyed by the **old** value is soft-deleted: its `_SNOWFLAKE_DELETED` metadata column is set to `TRUE`. 2. A new destination row is inserted keyed by the **new** value, with the updated payload and `_SNOWFLAKE_DELETED` set to `FALSE`. The destination table therefore contains two rows after the change: the original row, soft-deleted, and a new row under the new key value. To query only current rows, filter on `_SNOWFLAKE_DELETED = FALSE`. This behavior applies when the replication key is a primary key or an auto-detected unique constraint or unique index. User-declared logical keys behave differently: see the limitation described in [](#label-oracle-logical-key-value-change). ### Oversized values By default, the connector replicates individual values up to **16 MB**. When the connector encounters a larger value, it marks the associated table as permanently failed and stops replicating it. To change how the connector handles oversized values (for example, to replace them with `NULL` instead), modify the **Oversized Value Strategy** destination parameter. If your Snowflake account has the `ENABLE_OPENFLOW_CDC_ORACLE_SSV2` parameter set to `true`, the per-value limit can be raised from 16 MB to **128 MB**. For details and instructions on enabling the 128 MB per-value limit, see [](/user-guide/data-integration/openflow/connectors/oracle/maintenance#label-of-oracle-increase-oversized-value-limit). ### Error handling for invalid rows An *invalid row* is a row that Snowflake rejects during ingestion because it can't be written to the destination table, for example, a value that can't be converted to the destination column's type, or a missing required column. The **Error Handling Strategy** parameter controls what the connector does when it encounters an invalid row: - **Fail Table** (default): On the first invalid row, the connector marks the table as permanently failed and stops replicating it, preserving strict, all-or-nothing replication. After you fix the source data, resume replication as described in [Restart table replication](/user-guide/data-integration/openflow/connectors/oracle/setup-connector#label-of-oracle-restart-table-replication). - **Log Errors and Continue**: The connector keeps replicating the valid rows and records each rejected row, together with its original payload and error details, in the table's *error table*. The table isn't marked as failed. To change the strategy, set the **Error Handling Strategy** parameter. For more information, see [](/user-guide/data-integration/openflow/connectors/oracle/setup-connector#label-oracle-snowflake-destination-parameters). #### How rejected rows are captured The connector loads data with Snowpipe Streaming, so error logging behaves exactly as described in [Error logging in Snowpipe Streaming](/user-guide/snowpipe-streaming/snowpipe-streaming-error-tables). When you select **Log Errors and Continue**, the connector creates new destination and journal tables with the [`ERROR_LOGGING`](/user-guide/snowpipe-streaming/snowpipe-streaming-error-tables#turn-on-error-logging) property set to `TRUE`, so rejected rows are captured in a dedicated error table instead of aborting the load. The error table stores the original payload sent to Snowflake before any transformation, along with error details. Query a table's error table with the `ERROR_TABLE` table function: ```sql SELECT * FROM ERROR_TABLE(..
Column name Type Description
`_SNOWFLAKE_INSERTED_AT` TIMESTAMP_NTZ The timestamp when the row was originally inserted into the destination table.
`_SNOWFLAKE_UPDATED_AT` TIMESTAMP_NTZ The timestamp when the row was last updated in the destination table.
`_SNOWFLAKE_DELETED` BOOLEAN Indicates whether the row was deleted from the source table. When `true`, the row has been soft-deleted and no longer exists in the source.
Term Details
Billing Monthly license fees and Support & Maintenance (S&M) fees are drawn from your Snowflake Capacity.
Commitment Activation initiates a non-cancelable 36-month term (after the 60-day trial).
Lifecycle - **Post-term (36+ months)**: After the initial 36-month term, the license fee drops to $0, but the S&M fee auto-renews in 12-month increments, billed monthly. - **Lock-out risk**: If you opt out of S&M renewal, the connector will be permanently locked when S&M coverage ends. Unlocking the connector requires purchasing a new Embedded License, which triggers a new 36-month commitment at full price.
Management UI All license actions (Start/Cancel Trial, Monitor Usage, Opt-out) are performed by the ORGADMIN in %sf-web-interface% under **Admin** %raa% **Terms** %raa% **Openflow for Oracle**. For step-by-step instructions, see [Openflow Connector for Oracle: Enable and manage commercial terms](/user-guide/data-integration/openflow/connectors/oracle/manage-commercial-terms).
Restrictions The following customers are ineligible: - Customers purchasing Snowflake through the GCP Marketplace. - Customers contracted with Snowflake through a third-party reseller.
Term Details
Billing One-time license fee and annual Support & Maintenance (S&M) fees are drawn from your Snowflake Capacity.
Commitment Activation initiates a non-cancelable 12-month term (after the 60-day trial), with license fees paid upfront in full and S&M fees billed annually.
Lifecycle - **Post-term (12+ months)**: After the initial 12-month term, the license fee drops to $0, but the S&M fee auto-renews in 12-month increments, billed annually. - **Lock-out risk**: If you opt out of S&M renewal, the connector will be permanently locked when S&M coverage ends. Unlocking the connector requires purchasing a new Embedded License, which triggers a new 12-month commitment at full price.
Management UI All license actions (Start/Cancel Trial, Monitor Usage, Opt-out) are performed by the ORGADMIN in %sf-web-interface% under **Admin** %raa% **Terms** %raa% **Openflow for Oracle**. For step-by-step instructions, see [Openflow Connector for Oracle: Enable and manage commercial terms](/user-guide/data-integration/openflow/connectors/oracle/manage-commercial-terms).
Restrictions The following customers are ineligible: - Customers purchasing Snowflake through the GCP Marketplace.
Term Details
Billing No additional licensing fees from Snowflake. Standard storage and compute costs (for example, Openflow Compute) will apply.
Compliance You are solely responsible for compliance with your Oracle license.
Usage Mandatory for GCP Marketplace customers.
Consideration Oracle Embedded License (36-month commitment) Oracle Embedded License (12-month commitment) Independent License (BYOL)
Who is it for? Customers who need to license Oracle XStream technology directly through their Snowflake agreement and prefer a monthly payment schedule over 36 months. Customers who need to license Oracle XStream technology through their Snowflake agreement but can't agree to a multi-year commitment or prefer an upfront payment option instead of monthly payments. Customers who already have an Oracle GoldenGate license or another Oracle agreement that provides entitlement for XStream.
Billing Billed monthly through Snowflake based on the number of processor cores on your source Oracle DB. Involves a non-cancelable 36-month commitment. Also billed monthly for support and maintenance services. Additionally, standard storage and compute costs (for example, Openflow Compute) will apply. Billed upfront through Snowflake based on the number of processor cores on your source Oracle DB. Involves a non-cancelable 12-month commitment where all license fees are paid upfront in full. Also billed upfront for support and maintenance services annually. Additionally, standard storage and compute costs (for example, Openflow Compute) will apply. No additional licensing or support and maintenance fees for Oracle XStream services from Snowflake. You are responsible for all licensing and compliance directly with Oracle. Standard storage and compute costs (for example, Openflow Compute) will apply.
Configuration Requires you to input your Oracle DB's CPU core count and Oracle's licensing factor for its processors in the connector parameters. Requires you to input your Oracle DB's CPU core count and Oracle's licensing factor for its processors in the connector parameters. Does not require you to provide CPU core information to Snowflake.
Trial period Includes a 60-day free trial for up to 16 licensed cores. Billing commences automatically on the 61st day. Includes a 60-day free trial for up to 16 licensed cores. Billing commences automatically on the 61st day. No trial period is offered through Snowflake. Your use is subject to your existing Oracle agreement.
) ORDER BY timestamp; ``` Where a rejected row lands depends on the replication stage: - **Snapshot load**: The rejected row is written to the destination table's error table. - **Incremental (CDC) load**: The rejected row is written to the journal table's error table, because CDC changes are first written to the journal table before they're merged into the destination table. The connector enables error logging only on tables that it creates after you select **Log Errors and Continue**. To capture rejected rows for tables that were already being replicated, enable error logging on their existing destination and journal tables with the stored procedure in [Enable error logging on an existing schema](/user-guide/data-integration/openflow/connectors/oracle/maintenance#label-of-oracle-enable-error-logging-existing-schema). When the connector encounters invalid rows, it emits a `WARN` log entry that includes the number of rejected rows. Use these entries to monitor rejected-row activity. #### Consume rejected rows To process rejected rows programmatically, create a stream on the error table and consume it like any other Snowflake stream. For more information, see [Streams on error tables](/user-guide/data-load-overview#streams-on-error-tables). # Understanding data retention The connector follows a data retention philosophy where customer data is never automatically deleted. You maintain full ownership and control over your replicated data, and the connector preserves historical information rather than permanently removing it. This approach has the following implications: - Rows deleted from the source table are soft-deleted in the destination table rather than physically removed. - Columns dropped from the source table are renamed in the destination table rather than dropped. - Journal tables are retained indefinitely and are not automatically cleaned up. ## Destination table metadata columns Each destination table includes the following metadata columns that track replication information:
## Soft-deleted rows When a row is deleted from the source table, the connector does not physically remove it from the destination table. Instead, the row is marked as deleted by setting the `_SNOWFLAKE_DELETED` metadata column to `true`. This approach allows you to: - Retain historical data for auditing or compliance purposes. - Query deleted records when needed. - Decide when and how to permanently remove data based on your requirements. To query only active (non-deleted) rows, filter on the `_SNOWFLAKE_DELETED` column: ```sql SELECT * FROM my_table WHERE _SNOWFLAKE_DELETED = FALSE; ``` To query deleted rows: ```sql SELECT * FROM my_table WHERE _SNOWFLAKE_DELETED = TRUE; ``` ## Dropped columns When a column is dropped from the source table, the connector does not drop the corresponding column from the destination table. Instead, the column is renamed by appending the `__SNOWFLAKE_DELETED` suffix to preserve historical values. For example, if a column named `EMAIL` is dropped from the source table, it is renamed to `EMAIL__SNOWFLAKE_DELETED` in the destination table. Rows that existed before the column was dropped retain their original values, while rows added after the drop have `NULL` in this column. You can still query historical values from the renamed column: ```sql SELECT EMAIL__SNOWFLAKE_DELETED FROM my_table; ``` ## Renamed columns Due to limitations in CDC (Change Data Capture) mechanisms, the connector cannot distinguish between a column being renamed and a column being dropped followed by a new column being added. As a result, when you rename a column in the source table, the connector treats this as two separate operations: dropping the original column and adding a new column with the new name. For example, if you rename a column from `A` to `B` in the source table, the destination table will contain: - `A__SNOWFLAKE_DELETED`: Contains values from before the rename. Rows added after the rename have `NULL` in this column. - `B`: Contains values from after the rename. Rows that existed before the rename have `NULL` in this column. ### Querying renamed columns To retrieve data from both the original and renamed columns as a single unified column, use a `COALESCE` or `CASE` expression: ```sql SELECT COALESCE(B, A__SNOWFLAKE_DELETED) AS A_RENAMED_TO_B FROM my_table; ``` Alternatively, using a `CASE` expression: ```sql SELECT CASE WHEN B IS NOT NULL THEN B ELSE A__SNOWFLAKE_DELETED END AS A_RENAMED_TO_B FROM my_table; ``` ### Creating a view for renamed columns Rather than manually modifying the destination table, you can create a view that presents the renamed column as a single unified column. This approach is recommended because it preserves the original data and avoids potential issues with ongoing replication. ```sql CREATE VIEW my_table_unified AS SELECT *, COALESCE(B, A__SNOWFLAKE_DELETED) AS A_RENAMED_TO_B FROM my_table; ``` Manually modifying the destination table structure (such as dropping or renaming columns) is not recommended, as it may interfere with ongoing replication and cause data inconsistencies. ## Journal tables During incremental replication, changes from the source database are first written to journal tables before being merged into the destination tables. The connector does not automatically remove data from journal tables, as this data may be useful for auditing, debugging, or reprocessing purposes. Journal tables are created in the same schema as their corresponding destination tables and follow this naming convention: `_JOURNAL__` Where: - `` is the name of the destination table. - `` is the creation timestamp in Unix epoch format (seconds since January 1, 1970), ensuring uniqueness. - `` starts at 1 and increments whenever the destination table schema changes, either due to schema changes in the source table or modifications to column filters. For example, if your destination table is `SALES.ORDERS`, the journal table might be named `SALES.ORDERS_JOURNAL_1705320000_1`. Do not drop journal tables while replication is in progress. Removing an active journal table may cause data loss or replication failures. Only drop journal tables after the corresponding source table has been fully removed from replication. ### Managing journal table storage If you need to manage storage costs by removing old journal data, you can create a Snowflake task that periodically cleans up journal tables for tables that are no longer being replicated. Before implementing journal cleanup, verify that: - The corresponding source tables have been fully removed from replication. - You no longer need the journal data for auditing or processing purposes. For information on creating and managing tasks for automated cleanup, see [Introduction to tasks](/user-guide/tasks-intro). ## Next steps After reviewing this topic, consider the following next steps: - Review [Openflow Connector for Oracle: Enable and manage commercial terms](/user-guide/data-integration/openflow/connectors/oracle/manage-commercial-terms) to enable the connector, accept the Oracle XStream terms, and configure your licensing model. - Review [Openflow Connector for Oracle: Data mapping](/user-guide/data-integration/openflow/connectors/oracle/data-mapping) to understand how the connector maps data types to Snowflake data types. - Review [Set up tasks for the Openflow Connector for Oracle](/user-guide/data-integration/openflow/connectors/oracle/setup-tasks) to set up the connector. --- title: About Openflow Connector for PostgreSQL source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/postgres/about.md section: Loading & Unloading Data --- # About %postgresql% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Set up the Openflow Connector for PostgreSQL](/user-guide/data-integration/openflow/connectors/postgres/setup) - [Openflow Connector for PostgreSQL: Data mapping](/user-guide/data-integration/openflow/connectors/postgres/data-mapping) This topic describes the basic concepts of %postgresql%, its workflow, and limitations. ## About %postgresql% The %postgresql% connects a PostgreSQL database instance to Snowflake and replicates data from selected tables in near real-time or on a schedule. The connector also creates a log of all data changes, available along with the current state of the replicated tables. ## Use cases Use this connector if you're looking to do the following: - CDC replication of PostgreSQL data to Snowflake for comprehensive, centralized reporting. ## Supported PostgreSQL versions The following are the supported PostgreSQL versions. **Supported PostgreSQL versions**
## Openflow requirements - Choose the runtime size based on the sustained replication workload. For sizing guidance and how to run multiple connectors on one runtime, see [Runtime sizing](/user-guide/data-integration/openflow/connectors/cdc-runtime-sizing). - The connector doesn't support multi-node Openflow runtimes. Configure the runtime for this connector with **Min nodes** and **Max nodes** set to `1`. ## Limitations - The connector supports PostgreSQL version 11 or later. - The connector supports only username and password authentication with PostgreSQL. - The connector doesn't replicate tables with data that exceeds [Snowflake's type limitations](/sql-reference/intro-summary-data-types). An exception to this rule is date and time data type columns that contain out-of-range values. For more information, see [](#label-supported-pg-date-time-data-type-value). - The connector requires every replicated table to have a supported identity key configuration: either a primary key with replica identity `DEFAULT`, a unique index with replica identity `USING INDEX` (see [](#label-postgres-configure-replica-identity-using-index)), or a user-declared logical key with `REPLICA IDENTITY FULL`. Tables with no supported identity key configuration can replicate INSERT operations only. UPDATE and DELETE require an identity key. For more information, see [](#label-postgres-logical-key). - The connector supports common source table schema changes during replication, such as adding, dropping, and renaming columns. See [Schema changes](#label-database-schema-changes) for the full list and a few unsupported change types. - When using incremental replication without snapshots, if a row was inserted before incremental replication started, any subsequent update to that row will produce a destination row with missing values in VARCHAR, VARIANT, BINARY, and ARRAY columns. - The connector doesn't support the truncate table operation. `TRUNCATE` statements on the source are ignored, and the corresponding row deletions are not applied to the destination table. Limitations affecting certain table columns can be bypassed by excluding these specific columns from replication. ## Workflow 1. A **Database administrator** configures PostgreSQL replication settings, creates a publication, and credentials for the connector. Optionally, they deliver the SSL certificate. 2. An **Openflow administrator** creates a warehouse for the connector and a destination database to replicate into. 3. An **Openflow administrator** or a **data engineer** performs the following tasks: 1. Installs the connector. 2. Specifies the required parameters for the flow template. 3. Runs the flow. The connector performs the following tasks when run in Openflow: 1. Creates a schema for journal tables. 2. Creates the schemas and destination tables matching the source tables configured for replication. 3. Starts replication following the table replication lifecycle. ## How the connector works The following sections describe how the connector works in various scenarios, including replication, changes in schema, and data retention. ### Data replication The name of the destination schema is determined by the `Destination Schema Pattern` parameter. For more information, see [](#label-of-postgres-destination-parameters). By default, the destination schema name matches the source schema name, so the fully qualified name of a destination table is: `..` ### How tables are replicated The tables are replicated in the following stages: 1. Schema introspection: The connector discovers the columns in the source table, their names, and types, and then validates them against Snowflake's and the connector's limitations. Validation failures cause this stage to fail, and the cycle completes. After successful completion of Schema Introspection, the connector creates an empty destination table. 2. Snapshot load: The connector copies all data available in the source table into the destination table. Failure of this stage finishes the cycle, and no more data is replicated. After successful completion, the whole set of data from the source table is available in the destination table. 3. Incremental load: The connector keeps tracking changes in the source table and copying them into the destination table. This continues until the table is removed from replication. Failure at this stage permanently stops replication of the source table until the issue is resolved. This connector can be configured to immediately start replicating incremental changes for newly added tables, bypassing the snapshot load phase. This option is often useful when reinstalling the connector in an account where previously replicated data exists and you want to continue replication without having to re-snapshot tables. For details on bypassing the snapshot load and using the incremental load process, see [Incremental replication](/user-guide/data-integration/openflow/connectors/postgres/incremental-replication). Interim failures, such as connection errors, do not prevent tables from being replicated. Permanent failures, such as unsupported data types, do prevent tables from being replicated. If a permanent failure prevents a table from being replicated, remove the table from the list of replicated tables. After you address the problem that caused the failure, you can add the table back to the list of replicated tables. ### Schema changes During incremental replication, the connector detects many source table schema changes and updates the destination table automatically. Unsupported changes stop replication for the affected table until you restart it. #### Supported changes The connector supports the following schema changes: - **Add column.** The connector adds the column to the destination table and replicates values for new and updated rows. Existing rows aren't backfilled; the new column is NULL for rows that existed before the change. - **Drop column.** The connector renames the destination column with a `__SNOWFLAKE_DELETED` suffix to preserve historical values. For details, see [Dropped columns](#dropped-columns). - **Rename column.** The connector treats a rename as dropping the original column and adding a new one. The connector retains the original column under a suffixed name; for example, a column named `A` becomes `A__SNOWFLAKE_DELETED`. For query patterns, see [Renamed columns](#renamed-columns). - **Compatible type change.** The connector keeps replication running with the destination column type unchanged when you change a column to a source type that maps to the same Snowflake data type (for example, `INT` to `BIGINT`, both mapped to `NUMBER`). - **Re-add a previously dropped column.** The connector adds the column as a new destination column alongside the existing soft-deleted column (for example, `A` and `A__SNOWFLAKE_DELETED`). If you drop a column that was previously dropped and soft-deleted, replication for the affected table fails because the soft-deleted column name is already taken. #### Unsupported changes The connector doesn't support the following schema changes. When one occurs, replication stops for the affected table: - **Primary key definition change.** Adding or removing primary key columns, or changing which columns form the primary key. - **Incompatible type change.** When the new source type maps to a different Snowflake data type (for example, `INT` to `VARCHAR`, mapped to `NUMBER` and `TEXT` respectively). - **Numeric precision or scale change.** For example, changing `NUMERIC(7,2)` to `NUMERIC(6,3)`. - **Character column length change.** For example, changing `VARCHAR(50)` to `VARCHAR(100)`. To recover, restart replication for the affected table: see [Restart table replication](#label-of-postgres-restart-table-replication). The same soft-delete mechanism applies when you change a table's Column Filter JSON. For details, see [Replicate a subset of columns in a table](#label-postgres-connector-replication-subset-of-columns). ### Replicate tables from a PostgreSQL replica server The connector can ingest data from a primary server, a hot standby replica (https://www.postgresql.org/docs/current/hot-standby.html), or subscriber server using logical replication (https://www.postgresql.org/docs/current/logical-replication.html). Before configuring the connector to connect to a PostgreSQL replica, ensure that replication between primary and replica nodes works correctly. When investigating issues with missing data in the connector, first ensure that missing rows are present in the replica server used by the connector. Additional considerations when connecting to a standby replica:
- PostgreSQL version of the server must be >= 16. Amazon Aurora is not supported because it doesn't offer logical decoding from read replicas (https://docs.aws.amazon.com/AmazonRDS/latest/AuroraUserGuide/AuroraPostgreSQL.Replication.Logical.html). - Only connecting to a hot standby replica is supported. Note that warm standby replicas can't accept connections from clients until they are promoted to a primary instance. - [The publication](#label-postgres-connector-create-a-publication) needed by the connector must be created on the primary server, not the standby server. The standby server is read-only and doesn't let you create a publication.
If you connect to a hot standby instance and see **Trying to create the replication slot '<replication slot>' timed out. If connecting to a standby instance, ensure there is some traffic on the primary PostgreSQL instance, otherwise the call to create a replication slot will never return.** error in the Openflow bulletin, or the **Read PostgreSQL CDC Stream** processor isn't starting, log in to the primary PostgreSQL instance and execute the following query: ```sqlsyntax SELECT pg_log_standby_snapshot(); ``` The error occurs when there are no data changes in the primary server. As such, the connector can stall while creating a replication slot on the replica server. This results from the replica server requiring information about running transactions from the primary server to be able to create a replication slot. Primary servers won't send the information while idle. The `pg_log_standby_snapshot()` function forces the primary server to send information about running transactions to the replica server. On PostgreSQL 17 and later, if you want the replication slot to survive a primary failover, the connector must connect to the primary rather than a standby. See [PostgreSQL 17+ failover slot support](/user-guide/data-integration/openflow/connectors/postgres/failover). ### Track data changes in tables The connector replicates not only the current state of data from the source tables, but also every state of every row from every changeset. This data is stored in journal tables created in the same schema as the destination table. The journal table names are formatted as `_JOURNAL__`, where `` is the value of epoch seconds when the source table was added to replication, and `` is an integer increasing with every schema change on the source table. As a result, source tables that undergo schema changes will have multiple journal tables. When a table is removed from replication, then added back, the `` value will change, and `` will start again from `1`. Snowflake recommends that you don't alter the structure of journal tables in any way. They are used by the connector to update the destination table as part of the replication process. ### How the connector chooses a replication key The connector uses one column or set of columns from each source table as the replication key. The replication key uniquely identifies a row and drives the MERGE operation that applies CDC changes to the destination. For each table, the connector resolves the replication key in this order: 1. **User-declared logical key.** If the connector is configured with a Table Key Configuration Service that lists the table, the connector uses those columns as the replication key, overriding any primary key or unique index on the table. For more information, see [](#label-postgres-logical-key). 2. **Primary key.** The columns of the table's primary key constraint when `REPLICA IDENTITY` is `DEFAULT` (the PostgreSQL default for tables with a primary key). 3. **Unique index.** If the table has no primary key, the connector uses the unique index designated with `REPLICA IDENTITY USING INDEX`. For setup instructions and index requirements, see [](#label-postgres-configure-replica-identity-using-index). 4. **None.** If no qualifying key is found, the connector can replicate INSERT operations only. UPDATE and DELETE require an identity key. To enable full CDC for the table, add a primary key, configure `REPLICA IDENTITY USING INDEX` on a qualifying unique index, or declare a logical key. The following examples illustrate each replication key scenario: A table with a primary key (no special setup required): ```sql CREATE TABLE orders ( order_id BIGINT PRIMARY KEY, customer_id INT, total NUMERIC(10, 2) ); ``` The connector uses `order_id` as the replication key. A table without a primary key, replicated using a unique index: ```sql CREATE TABLE sessions ( session_token VARCHAR(64) NOT NULL, user_id INT, created_at TIMESTAMPTZ ); CREATE UNIQUE INDEX idx_sessions_token ON sessions (session_token); ALTER TABLE sessions REPLICA IDENTITY USING INDEX idx_sessions_token; ``` The connector uses `session_token` as the replication key. A table without a primary key or qualifying index, replicated using a logical key: ```sql CREATE TABLE audit_events ( event_id UUID NOT NULL, event_type TEXT, payload JSONB ); ALTER TABLE audit_events REPLICA IDENTITY FULL; ``` Configure a logical key on `event_id` in the Table Key Configuration JSON. For setup instructions, see [](#label-postgres-logical-key). ### Changes to a replication key value When a source update changes the replication key value of an existing row, the connector can't update the destination row in place because the row's identity changes. Instead, it splits the source update into two operations on the destination table: 1. The destination row keyed by the **old** value is soft-deleted: its `_SNOWFLAKE_DELETED` metadata column is set to `TRUE`. 2. A new destination row is inserted keyed by the **new** value, with the updated payload and `_SNOWFLAKE_DELETED` set to `FALSE`. The destination table therefore contains two rows after the change: the original row, soft-deleted, and a new row under the new key value. To query only current rows, filter on `_SNOWFLAKE_DELETED = FALSE`. This behavior applies when the replication key is a primary key, an auto-detected unique index, or a user-declared logical key. ### Oversized values By default, the connector replicates individual values up to **16 MB**. When the connector encounters a larger value, it marks the associated table as permanently failed and stops replicating it. To change how the connector handles oversized values (for example, to replace them with `NULL` instead), modify the **Oversized Value Strategy** destination parameter. If your Snowflake account has the `ENABLE_OPENFLOW_CDC_POSTGRES_SSV2` parameter set to `true`, the per-value limit can be raised from 16 MB to **128 MB**. For details and instructions on enabling the 128 MB per-value limit, see [](/user-guide/data-integration/openflow/connectors/postgres/maintenance#label-of-postgres-increase-oversized-value-limit). ### Error handling for invalid rows An *invalid row* is a row that Snowflake rejects during ingestion because it can't be written to the destination table, for example a value that can't be converted to the destination column's type, or a missing required column. The **Error Handling Strategy** parameter controls what the connector does when it encounters an invalid row: - **Fail Table** (default): On the first invalid row, the connector marks the table as permanently failed and stops replicating it, preserving strict, all-or-nothing replication. After you fix the source data, resume replication as described in [Restart table replication](/user-guide/data-integration/openflow/connectors/postgres/maintenance#label-of-postgres-restart-table-replication). - **Log Errors and Continue**: The connector keeps replicating the valid rows and records each rejected row, together with its original payload and error details, in the table's *error table*. The table isn't marked as failed. To change the strategy, set the **Error Handling Strategy** parameter. For more information, see [](/user-guide/data-integration/openflow/connectors/postgres/setup#label-of-postgres-destination-parameters). #### How rejected rows are captured The connector loads data with Snowpipe Streaming, so error logging behaves exactly as described in [Error logging in Snowpipe Streaming](/user-guide/snowpipe-streaming/snowpipe-streaming-error-tables). When you select **Log Errors and Continue**, the connector creates new destination and journal tables with the [`ERROR_LOGGING`](/user-guide/snowpipe-streaming/snowpipe-streaming-error-tables#turn-on-error-logging) property set to `TRUE`, so rejected rows are captured in a dedicated error table instead of aborting the load. The error table stores the original payload sent to Snowflake before any transformation, along with error details. Query a table's error table with the `ERROR_TABLE` table function: ```sql SELECT * FROM ERROR_TABLE(..
Column name Type Description
`_SNOWFLAKE_INSERTED_AT` TIMESTAMP_NTZ The timestamp when the row was originally inserted into the destination table.
`_SNOWFLAKE_UPDATED_AT` TIMESTAMP_NTZ The timestamp when the row was last updated in the destination table.
`_SNOWFLAKE_DELETED` BOOLEAN Indicates whether the row was deleted from the source table. When `true`, the row has been soft-deleted and no longer exists in the source.
11 12 13 14 15 16 17 18
Standard (https://www.postgresql.org/) Yes Yes Yes Yes Yes Yes Yes Yes
AWS RDS (https://docs.aws.amazon.com/AmazonRDS/latest/PostgreSQLReleaseNotes/Welcome.html) Yes Yes Yes Yes Yes Yes Yes Yes
Amazon Aurora (https://docs.aws.amazon.com/AmazonRDS/latest/AuroraPostgreSQLReleaseNotes/Welcome.html) Yes Yes Yes Yes Yes Yes Yes Yes
GCP Cloud SQL (https://cloud.google.com/sql/docs/postgres/) Yes Yes Yes Yes Yes Yes Yes Yes
Azure Database (https://learn.microsoft.com/en-us/azure/postgresql/) Yes Yes Yes Yes Yes Yes Yes Yes
) ORDER BY timestamp; ``` Where a rejected row lands depends on the replication stage: - **Snapshot load**: The rejected row is written to the destination table's error table. - **Incremental (CDC) load**: The rejected row is written to the journal table's error table, because CDC changes are first written to the journal table. For more information about journal tables, see [](#track-data-changes-in-tables). The connector enables error logging only on tables that it creates after you select **Log Errors and Continue**. To capture rejected rows for tables that were already being replicated, enable error logging on their existing destination and journal tables with the stored procedure in [Enable error logging on an existing schema](/user-guide/data-integration/openflow/connectors/postgres/maintenance#label-of-postgres-enable-error-logging-existing-schema). When the connector encounters invalid rows, it emits a `WARN` log entry that includes the number of rejected rows. Use these entries to monitor rejected-row activity. #### Consume rejected rows To process rejected rows programmatically, create a stream on the error table and consume it like any other Snowflake stream. For more information, see [Streams on error tables](/user-guide/data-load-overview#streams-on-error-tables). ### TOASTed value support The connector supports replicating tables with TOAST values (https://www.postgresql.org/docs/current/storage-toast.html) for columns of types: `array`, `bytea`, `json`, `jsonb`, `text`, `varchar`, `xml`. Whenever the connector encounters a TOASTed value in the CDC stream, it substitutes a default placeholder of `__previous_value_unchanged`, formatted for the given column type, and stores it in the journal table. The `MERGE` query then accounts for placeholder values, so that the destination table always contains the last non-TOASTed value. ### Out of range value support The connector supports replicating tables with columns of types `date`, `timestamp`, and `timestamptz` that contain out-of-range values. If the connector encounters an out-of-range value in the CDC stream, it substitutes a default placeholder based on the type of the column. **Placeholder values for out-of-range values**
`-Infinity` and `Infinity` values are also replaced with the respective placeholders for all three types. # Understanding data retention The connector follows a data retention philosophy where customer data is never automatically deleted. You maintain full ownership and control over your replicated data, and the connector preserves historical information rather than permanently removing it. This approach has the following implications: - Rows deleted from the source table are soft-deleted in the destination table rather than physically removed. - Columns dropped from the source table are renamed in the destination table rather than dropped. - Journal tables are retained indefinitely and are not automatically cleaned up. ## Destination table metadata columns Each destination table includes the following metadata columns that track replication information:
## Soft-deleted rows When a row is deleted from the source table, the connector does not physically remove it from the destination table. Instead, the row is marked as deleted by setting the `_SNOWFLAKE_DELETED` metadata column to `true`. This approach allows you to: - Retain historical data for auditing or compliance purposes. - Query deleted records when needed. - Decide when and how to permanently remove data based on your requirements. To query only active (non-deleted) rows, filter on the `_SNOWFLAKE_DELETED` column: ```sql SELECT * FROM my_table WHERE _SNOWFLAKE_DELETED = FALSE; ``` To query deleted rows: ```sql SELECT * FROM my_table WHERE _SNOWFLAKE_DELETED = TRUE; ``` ## Dropped columns When a column is dropped from the source table, the connector does not drop the corresponding column from the destination table. Instead, the column is renamed by appending the `__SNOWFLAKE_DELETED` suffix to preserve historical values. For example, if a column named `EMAIL` is dropped from the source table, it is renamed to `EMAIL__SNOWFLAKE_DELETED` in the destination table. Rows that existed before the column was dropped retain their original values, while rows added after the drop have `NULL` in this column. You can still query historical values from the renamed column: ```sql SELECT EMAIL__SNOWFLAKE_DELETED FROM my_table; ``` ## Renamed columns Due to limitations in CDC (Change Data Capture) mechanisms, the connector cannot distinguish between a column being renamed and a column being dropped followed by a new column being added. As a result, when you rename a column in the source table, the connector treats this as two separate operations: dropping the original column and adding a new column with the new name. For example, if you rename a column from `A` to `B` in the source table, the destination table will contain: - `A__SNOWFLAKE_DELETED`: Contains values from before the rename. Rows added after the rename have `NULL` in this column. - `B`: Contains values from after the rename. Rows that existed before the rename have `NULL` in this column. ### Querying renamed columns To retrieve data from both the original and renamed columns as a single unified column, use a `COALESCE` or `CASE` expression: ```sql SELECT COALESCE(B, A__SNOWFLAKE_DELETED) AS A_RENAMED_TO_B FROM my_table; ``` Alternatively, using a `CASE` expression: ```sql SELECT CASE WHEN B IS NOT NULL THEN B ELSE A__SNOWFLAKE_DELETED END AS A_RENAMED_TO_B FROM my_table; ``` ### Creating a view for renamed columns Rather than manually modifying the destination table, you can create a view that presents the renamed column as a single unified column. This approach is recommended because it preserves the original data and avoids potential issues with ongoing replication. ```sql CREATE VIEW my_table_unified AS SELECT *, COALESCE(B, A__SNOWFLAKE_DELETED) AS A_RENAMED_TO_B FROM my_table; ``` Manually modifying the destination table structure (such as dropping or renaming columns) is not recommended, as it may interfere with ongoing replication and cause data inconsistencies. ## Journal tables During incremental replication, changes from the source database are first written to journal tables before being merged into the destination tables. The connector does not automatically remove data from journal tables, as this data may be useful for auditing, debugging, or reprocessing purposes. Journal tables are created in the same schema as their corresponding destination tables and follow this naming convention: `_JOURNAL__` Where: - `` is the name of the destination table. - `` is the creation timestamp in Unix epoch format (seconds since January 1, 1970), ensuring uniqueness. - `` starts at 1 and increments whenever the destination table schema changes, either due to schema changes in the source table or modifications to column filters. For example, if your destination table is `SALES.ORDERS`, the journal table might be named `SALES.ORDERS_JOURNAL_1705320000_1`. Do not drop journal tables while replication is in progress. Removing an active journal table may cause data loss or replication failures. Only drop journal tables after the corresponding source table has been fully removed from replication. ### Managing journal table storage If you need to manage storage costs by removing old journal data, you can create a Snowflake task that periodically cleans up journal tables for tables that are no longer being replicated. Before implementing journal cleanup, verify that: - The corresponding source tables have been fully removed from replication. - You no longer need the journal data for auditing or processing purposes. For information on creating and managing tasks for automated cleanup, see [Introduction to tasks](/user-guide/tasks-intro). ## Next steps Review [Openflow Connector for PostgreSQL: Data mapping](/user-guide/data-integration/openflow/connectors/postgres/data-mapping) to understand how the connector maps data types to Snowflake data types. Review [Set up the Openflow Connector for PostgreSQL](/user-guide/data-integration/openflow/connectors/postgres/setup) to set up the connector. --- title: About Openflow Connector for SharePoint source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/sharepoint/about.md section: Loading & Unloading Data --- # About %sharepointof% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Set up the Openflow Connector for SharePoint](/user-guide/data-integration/openflow/connectors/sharepoint/setup) This topic describes the basic concepts of Openflow Connector for SharePoint, its use cases and limitations. The Openflow Connector for SharePoint connects a Microsoft 365 SharePoint site and Snowflake to ingest files and user permissions and keeps them up to date. Openflow Connector for SharePoint also supports the Cortex Search service and can make ingested files ready for conversational analysis for use in AI Assistants using SQL, Python or REST APIs. ## Variants of the %sharepointof% The %sharepointof% contains four variants which allow you to, optionally, index data into Snowflake Cortex Search and include document metadata (ACLs).
These variants appear as separate connectors in Marketplace. When installing the connector, choose the variant that meets your requirements. ## Rate limiting restrictions SharePoint API limits (https://learn.microsoft.com/en-us/sharepoint/dev/embedded/development/limits-calling#api-rate-limits) govern how many requests can be made within a given time frame. If your flow exceeds the allowed quota, syncs may slow down or fail with an error. This mostly occurs when your access token makes higher number of requests than the source typically allows. In such cases, Snowflake recommends applying for higher access quota (wherever applicable) or reducing the sync frequency. ### Limitations - [](#label-parse-document-requirements). - [](#label-cortex-search-overview-limitations). - Changes caused by moving or renaming folders aren't captured during incremental ingestion. - The connector ingests only the supported file types and ignores others. ### Next steps [Set up the Openflow Connector for SharePoint](/user-guide/data-integration/openflow/connectors/sharepoint/setup) --- title: About Openflow Connector for Slack source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/slack/about.md section: Loading & Unloading Data --- # About %slackof% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Set up the Openflow Connector for Slack](/user-guide/data-integration/openflow/connectors/slack/setup) This topic describes the basic concepts of Openflow Connector for Slack, steps to set it up, and limitations. The Openflow Connector for Slack connects a Slack workspace to Snowflake in order to ingest Slack messages, reactions, file attachments, and channel memberships (ACLs). The connector also supports the Cortex Search service and can make ingested Slack content ready for conversational analysis for use in AI Assistants using SQL, Python or REST APIs. Use this connector if you're looking to do the following: - Pull Slack messages and metadata into Snowflake for searchable, organization-wide insights - Ingest Slack content and make it ready for chat in your AI assistants with Snowflake Cortex ## Limitations - The connector captures historical file attachments, reactions and messages, but only after the Slack App is added to a conversation or channel. - If a user edits an existing message or deletes a message, the changes are captured in Snowflake at the next refresh interval. ## Workflow 1. **Slack Admin** creates a Slack App as described later, then installs the App in the channels or conversations they wish to ingest messages from. The Bot token and App token from the Slack App need to be provided to the Snowflake Account Admin 2. **Snowflake account admin**: 1. Installs the connector. 2. Specifies the required parameters for the flow template, for example, Bot token, App token, and database and schema names. 3. Runs flow. The following happens when the flow is run in Openflow: 1. The flow automatically creates a database, schema and the necessary tables and external access integration in Snowflake on behalf of the admin. It also creates a Cortex Search and wires up chunks and ACLs and metadata. By default, these are only accessible to the Snowflake account admin role 2. Fetches specified conversations, metadata, ACLs from the Slack channel(s). An ACL is defined as the snapshot list of user IDs and emails that are members of each channel being ingested. 3. Chunks ingested conversation messages 4. Puts chunked conversation messages along with metadata and ACLs into Snowflake tables 3. **IT Developer** in customer's organization creates bespoke Chat App and passes user identity which is the user's email registered on Slack, as a filter when invoking Cortex Search REST API with the end user's question 4. **End users** of the Chat App in the customer's organization see responses from Cortex Search restricted to chunks from conversations they have access to in the Slack channel based on ACLs, along with a link to the source conversation. ### Considerations - By default, any user with the Snowflake account admin role will be able to “see” the raw ingested messages and conversations and tables created by the flow template - The user with the Snowflake account admin role decides who can access the internal stage and tables through Snowflake roles. - The user with the Snowflake account admin role decides who can query the Cortex Search service through Snowflake roles. ### Next steps [Set up the Openflow Connector for Slack](/user-guide/data-integration/openflow/connectors/slack/setup) --- title: About Openflow Connector for Snowflake to Kafka source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/snowflake-to-kafka/about.md section: Loading & Unloading Data --- # About %sf-kafka% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Set up the Openflow Connector for Snowflake to Kafka](/user-guide/data-integration/openflow/connectors/snowflake-to-kafka/setup) This topic describes the basic concepts of %sf-kafka% and limitations. The connector consumes a Snowflake stream and sends consumed CDC records to a Kafka topic. A Snowflake Stream object records data manipulation language (DML) changes made to tables, including inserts, updates, and deletes, as well as metadata about each change, so that actions can be taken using the changed data. This process is referred to as change data capture (CDC). Use this connector if you're looking to do the following: - Replicate Snowflake tables to Apache Kafka using CDC for real-time insights distribution and event-driven architectures ## Workflow Depending on the configuration of the Kafka broker, which is going to be receiving the CDC data, the workflow may differ slightly. 1. A Snowflake account administrator performs the following tasks: 1. Creates or identifies the Snowflake stream that is going to be the source of the CDC data. 2. Designates a warehouse to be used by the connector. 3. Configures or identifies the Snowflake user used by the connector and a role for this user. The user must have appropriate permissions to the source Snowflake stream. At a minimum, the user needs USAGE privilege on the database and schema containing the Snowflake stream, and SELECT privilege on the stream and the stream's underlying table or view object. 2. A Kafka administrator performs the following tasks. 1. Creates or identifies a Kafka broker and topic that is going to be the destination for the CDC captured from the Snowflake stream. 2. Sets up the authentication mechanism for the Kafka broker, which is going to be used by the connector. 3. A data engineer performs the following tasks: 1. Installs and configures the connector. 2. Provides Snowflake credentials and configuration. 3. Provides Kafka credentials and configuration. 4. Provides connector parameters. ## Stream metadata columns Stream metadata columns `METADATA$ROW_ID`, `METADATA$ISUPDATE`, and `METADATA$ACTION` are sent to the Kafka topic. The names of these columns are modified before they are sent to Kafka. In the JSON message payload that is sent, they become `METADATA_ROW_ID`, `METADATA_ISUPDATE`, and `METADATA_ACTION`. For more information, see [](#label-stream-metadata-columns). ## Limitations - A single connector can only capture CDCs from one Snowflake stream. - Messages are sent without a schema. - Schema evolution is not supported. ## Next steps [Set up the Openflow Connector for Snowflake to Kafka](/user-guide/data-integration/openflow/connectors/snowflake-to-kafka/setup) --- title: About Openflow Connector for SQL Server source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/sql-server/about.md section: Loading & Unloading Data --- # About %sqlserver% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Monitor Openflow using telemetry data](/user-guide/data-integration/openflow/monitor) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Set up the Openflow Connector for SQL Server](/user-guide/data-integration/openflow/connectors/sql-server/setup) - [Openflow connectors for SQL Server: Data mapping](/user-guide/data-integration/openflow/connectors/sql-server/data-mapping) - [Comparison of Openflow connectors for SQL Server](/user-guide/data-integration/openflow/connectors/sql-server-cdc/compare-change-tracking-cdc) This topic describes the basic concepts, workflow, and limitations of the %sqlserver%. ## About the %sqlserver% The %sqlserver% connects a SQL Server database instance to Snowflake and replicates data from selected tables in near real-time or on a schedule. The connector uses SQL Server Change Tracking (https://learn.microsoft.com/en-us/sql/relational-databases/track-changes/about-change-tracking-sql-server) to detect and apply changes to replicated tables. Change data is recorded in journal tables alongside the current state of the replicated tables. Snowflake also provides the %sqlservercdc%, which uses SQL Server Change Data Capture instead. To choose between the two connectors, see [Comparison of Openflow connectors for SQL Server](/user-guide/data-integration/openflow/connectors/sql-server-cdc/compare-change-tracking-cdc). ## Use cases Use this connector if you're looking to do the following: - Synchronize SQL Server data with Snowflake for comprehensive, centralized reporting. ## Supported SQL Server versions The following SQL Server database versions and platforms are supported: - Microsoft SQL Server 2022 (https://www.microsoft.com/sql-server) - Microsoft SQL Server 2019 - Microsoft SQL Server 2017 - Microsoft SQL Server 2016 - Azure SQL Database (https://learn.microsoft.com/azure/azure-sql/database/?view=azuresql) - Azure SQL Managed Instance (https://learn.microsoft.com/azure/azure-sql/managed-instance/?view=azuresql) - AWS RDS for SQL Server (https://docs.aws.amazon.com/AmazonRDS/latest/UserGuide/CHAP_SQLServer.html) - Google Cloud SQL for SQL Server The connector relies on SQL Server Change Tracking, which is available starting with SQL Server 2008. Earlier versions don't support this feature and are incompatible with the connector. ## Openflow requirements - Choose the runtime size based on the sustained replication workload. For sizing guidance and how to run multiple connectors on one runtime, see [Runtime sizing](#label-sql-server-runtime-sizing). - The connector doesn't support multi-node Openflow runtimes. Configure the runtime for this connector with **Min nodes** and **Max nodes** set to `1`. ## Limitations - You can't run multiple connectors of the same type in a single runtime instance. - The connector supports only username and password authentication with SQL Server. - The connector only replicates database tables that contain primary keys. - The connector doesn't update existing records in the Snowflake database when a new NOT NULL column with a default value is added to one of the source databases. - The connector doesn't update existing records in the Snowflake database when a new column is added to the included list in the Column Filter JSON. - The connector supports common source table schema changes during replication, such as adding, dropping, and renaming columns. See [Schema changes](#label-database-schema-changes) for the full list and a few unsupported change types. - The connector doesn't support the truncate table operation. `TRUNCATE` statements on the source are ignored, and the corresponding row deletions are not applied to the destination table. You can bypass limitations affecting certain table columns by excluding these specific columns from replication. ## Workflow The following workflow outlines the steps to set up and run the %sqlserver%: 1. A SQL Server database administrator performs the following tasks: 1. Configures SQL Server replication settings and enables change tracking on the databases and tables being replicated. 2. Creates credentials for the connector. 3. (Optional) Provides the SSL certificate to connect to the SQL Server instance over SSL. 2. A Snowflake account administrator performs the following tasks: 1. Creates a service user for the connector, a destination database to store replicated data, and a warehouse for the connector. 2. Installs the connector. 3. Specifies the required parameters for the connector flow definition. 4. Runs the flow. The connector does the following when run in Openflow: 1. Creates the schemas and destination tables matching the source tables configured for replication. 2. Begins replication according to the table replication lifecycle. For more information, see [](#label-of-sql-server-how-tables-are-replicated). ## How the connector works The following sections describe how the connector works in various scenarios, including replication, snapshots of partitioned tables, changes in schema, and data retention. ### Change tracking behavior The connector uses SQL Server Change Tracking (https://learn.microsoft.com/en-us/sql/relational-databases/track-changes/about-change-tracking-sql-server) (CT) to detect changes in the source tables. Change Tracking reports the net effect of changes between polling intervals. If a row is updated multiple times between two consecutive polls, the connector sees only the most recent version of that row. Intermediate states aren't preserved. This makes the connector suitable for **data synchronization** use cases, where the goal is to keep the destination table in sync with the source. It isn't suitable for **audit or history** use cases where every intermediate change to a row must be captured. ### Data replication The connector supports replicating tables from multiple SQL Server databases in a single SQL Server instance. The connector creates replicated tables from different databases in separate schemas in the destination Snowflake database. Reference replicated tables by combining the source database name, the source schema name, and the table name in the following format: `..` The name of the destination schema is determined by the `Destination Schema Pattern` parameter. For more information, see [](#label-of-sqlserver-destination-parameters). By default, the destination schema name is the source database name and source schema name joined by an underscore, so the fully qualified name of a destination table is: `._.` ### How tables are replicated The connector replicates tables in the following stages: 1. Schema introspection: The connector discovers the columns in the source table, including the column names and types, then validates them against Snowflake's and the connector's limitations. Validation failures cause this stage to fail, and the cycle completes. After successful completion of this stage, the connector creates an empty destination table. 2. Snapshot load: The connector copies all data available in the source table into the destination table. If this stage fails, the connector stops replicating data. After successful completion, the data from the source table is available in the destination table. For how large partitioned tables are handled, see [Snapshot of partitioned tables](#label-sql-server-partitioned-snapshot). 3. Incremental load: The connector tracks changes in the source table and applies those changes to the destination table. This process continues until the table is removed from replication. Failure at this stage permanently stops replication of the source table, until the issue is resolved. For information on bypassing snapshot load and using the incremental load process, see [Incremental replication](/user-guide/data-integration/openflow/connectors/sql-server/incremental-replication). ### Snapshot of partitioned tables During snapshot load, the connector pages through each source table in primary key order. For a large table that is physically partitioned (https://learn.microsoft.com/en-us/sql/relational-databases/partitions/partitioned-tables-and-indexes) on the source, this ordering can force SQL Server to sort the whole table on every batch when no index delivers rows in the required order, which makes the snapshot extremely slow or prevents it from completing. To avoid this, the connector snapshots a physically partitioned table one partition at a time. Reading a single partition lets SQL Server stream rows in index order without a sort, so each batch finishes quickly. This behavior is automatic: the connector detects partitioned tables and requires no configuration change. Non-partitioned tables are unaffected and continue to be read as a whole. ### Schema changes During incremental replication, the connector detects many source table schema changes and updates the destination table automatically. Unsupported changes stop replication for the affected table until you restart it. #### Supported changes The connector supports the following schema changes: - **Add column.** The connector adds the column to the destination table and replicates values for new and updated rows. Existing rows aren't backfilled; the new column is NULL for rows that existed before the change. - **Drop column.** The connector renames the destination column with a `__SNOWFLAKE_DELETED` suffix to preserve historical values. For details, see [Dropped columns](#dropped-columns). - **Rename column.** The connector treats a rename as dropping the original column and adding a new one. The connector retains the original column under a suffixed name; for example, a column named `A` becomes `A__SNOWFLAKE_DELETED`. For query patterns, see [Renamed columns](#renamed-columns). - **Compatible type change.** The connector keeps replication running with the destination column type unchanged when you change a column to a source type that maps to the same Snowflake data type (for example, `INT` to `BIGINT`, both mapped to `NUMBER`). - **Re-add a previously dropped column.** The connector adds the column as a new destination column alongside the existing soft-deleted column (for example, `A` and `A__SNOWFLAKE_DELETED`). If you drop a column that was previously dropped and soft-deleted, replication for the affected table fails because the soft-deleted column name is already taken. #### Unsupported changes The connector doesn't support the following schema changes. When one occurs, replication stops for the affected table: - **Primary key definition change.** Adding or removing primary key columns, or changing which columns form the primary key. - **Incompatible type change.** When the new source type maps to a different Snowflake data type (for example, `INT` to `VARCHAR`, mapped to `NUMBER` and `TEXT` respectively). - **Numeric precision or scale change.** For example, changing `NUMERIC(7,2)` to `NUMERIC(6,3)`. - **Character column length change.** For example, changing `VARCHAR(50)` to `VARCHAR(100)`. To recover, restart replication for the affected table: see [Restart table replication](/user-guide/data-integration/openflow/connectors/sql-server/maintenance#label-of-sql-server-restart-table-replication). The same soft-delete mechanism applies when you change a table's Column Filter JSON. For details, see [Replicate a subset of columns in a table](#label-sqlserver-connector-replication-subset-of-columns). ### Oversized values By default, the connector replicates individual values up to **16 MB**. When the connector encounters a larger value, it marks the associated table as permanently failed and stops replicating it. To change how the connector handles oversized values (for example, to replace them with `NULL` instead), modify the **Oversized Value Strategy** destination parameter. If your Snowflake account has the `ENABLE_OPENFLOW_CDC_SQLSERVER_SSV2` parameter set to `true`, the per-value limit can be raised from 16 MB to **128 MB**. For details and instructions on enabling the 128 MB per-value limit, see [](/user-guide/data-integration/openflow/connectors/sql-server/maintenance#label-of-sql-server-increase-oversized-value-limit). ### Always On Availability Groups and source failover The connector supports SQL Server Always On Availability Groups (https://learn.microsoft.com/sql/database-engine/availability-groups/windows/overview-of-always-on-availability-groups-sql-server). The connector tolerates planned and unplanned failover without requiring you to restart replication or remove tables from the connector configuration. During failover, source databases can be briefly offline while SQL Server moves the primary role to another replica. When a source database is temporarily unavailable, replicated tables keep their current status in the Table State Store. The connector retries on the next polling cycle and resumes incremental replication from the last recorded position once the database is online again. Transient connection errors and temporary source unavailability do not move tables to `FAILED`. This behavior is distinct from permanent failures such as unsupported schema changes or other source-side conditions that permanently stop change capture for a table. Those conditions still move affected tables to `FAILED` until you resolve the underlying problem and restart replication for the table. For connection settings, see [Always On Availability Groups](/user-guide/data-integration/openflow/connectors/sql-server/setup#label-sql-server-availability-groups). ### Error handling for invalid rows An *invalid row* is a row that Snowflake rejects during ingestion because it can't be written to the destination table, for example a value that can't be converted to the destination column's type, or a missing required column. The **Error Handling Strategy** parameter controls what the connector does when it encounters an invalid row: - **Fail Table** (default): On the first invalid row, the connector marks the table as permanently failed and stops replicating it, preserving strict, all-or-nothing replication. After you fix the source data, resume replication as described in [Restart table replication](/user-guide/data-integration/openflow/connectors/sql-server/maintenance#label-of-sql-server-restart-table-replication). - **Log Errors and Continue**: The connector keeps replicating the valid rows and records each rejected row, together with its original payload and error details, in the table's *error table*. The table isn't marked as failed. To change the strategy, set the **Error Handling Strategy** parameter. For more information, see [](/user-guide/data-integration/openflow/connectors/sql-server/setup#label-of-sqlserver-destination-parameters). #### How rejected rows are captured The connector loads data with Snowpipe Streaming, so error logging behaves exactly as described in [Error logging in Snowpipe Streaming](/user-guide/snowpipe-streaming/snowpipe-streaming-error-tables). When you select **Log Errors and Continue**, the connector creates new destination and journal tables with the [`ERROR_LOGGING`](/user-guide/snowpipe-streaming/snowpipe-streaming-error-tables#turn-on-error-logging) property set to `TRUE`, so rejected rows are captured in a dedicated error table instead of aborting the load. The error table stores the original payload sent to Snowflake before any transformation, along with error details. Query a table's error table with the `ERROR_TABLE` table function: ```sql SELECT * FROM ERROR_TABLE(..
Column type Placeholder value
`date` `-9999-01-01` through `9999-12-31`.
`timestamp` `0001-01-01 00:00:00` through `9999-12-31 23:59:59.999999999`.
`timestamptz` `0001-01-01 00:00:00+00` through `9999-12-31 23:59:59.999999999+00`.
Column name Type Description
`_SNOWFLAKE_INSERTED_AT` TIMESTAMP_NTZ The timestamp when the row was originally inserted into the destination table.
`_SNOWFLAKE_UPDATED_AT` TIMESTAMP_NTZ The timestamp when the row was last updated in the destination table.
`_SNOWFLAKE_DELETED` BOOLEAN Indicates whether the row was deleted from the source table. When `true`, the row has been soft-deleted and no longer exists in the source.
Variant Description
Microsoft SharePoint (Cortex Search, document ACLs) Indexes files and their permissions (ACLs) into Snowflake Cortex Search.
Microsoft SharePoint (Cortex Search, no document ACLs) Indexes files without their permissions (ACLs) into Snowflake Cortex Search.
Microsoft SharePoint (Simple Ingest, document ACLs) Ingests files and their permissions (ACLs) into a Snowflake stage.
Microsoft SharePoint (Simple Ingest, no document ACLs) Ingests files without their permissions (ACLs) into a Snowflake stage.
) ORDER BY timestamp; ``` Where a rejected row lands depends on the replication stage: - **Snapshot load**: The rejected row is written to the destination table's error table. - **Incremental (change tracking) load**: The rejected row is written to the journal table's error table, because changes are first written to the journal table. For more information about journal tables, see [](/user-guide/data-integration/openflow/connectors/sql-server/setup#track-data-changes-in-tables). The connector enables error logging only on tables that it creates after you select **Log Errors and Continue**. To capture rejected rows for tables that were already being replicated, enable error logging on their existing destination and journal tables with the stored procedure in [Enable error logging on an existing schema](/user-guide/data-integration/openflow/connectors/sql-server/maintenance#label-of-sql-server-enable-error-logging-existing-schema). When the connector encounters invalid rows, it emits a `WARN` log entry that includes the number of rejected rows. Use these entries to monitor rejected-row activity. #### Consume rejected rows To process rejected rows programmatically, create a stream on the error table and consume it like any other Snowflake stream. For more information, see [Streams on error tables](/user-guide/data-load-overview#streams-on-error-tables). ### Source database locking behavior During snapshot and incremental replication, the connector reads from the source database tables to retrieve row data and track changes. Under SQL Server's default READ COMMITTED isolation level, these read operations acquire shared locks on the source tables. If other database clients hold conflicting locks on the same tables at the same time, this can lead to deadlocks, where SQL Server terminates one of the conflicting sessions. To avoid these deadlocks without affecting the isolation level that other applications use, configure the connector to read under SNAPSHOT isolation (https://learn.microsoft.com/en-us/dotnet/framework/data/adonet/sql/snapshot-isolation-in-sql-server). SNAPSHOT isolation reads from row versions instead of acquiring shared locks, so the connector's queries no longer contend with concurrent writes on the source tables. Because this approach makes SNAPSHOT isolation available only to the connector's own sessions, it doesn't change the default READ COMMITTED isolation level that other applications rely on. Avoid using Read Committed Snapshot Isolation (RCSI) for this purpose, because RCSI redefines the default isolation level for every connection to the database. For the steps to enable SNAPSHOT isolation for the connector, see [Read the source under SNAPSHOT isolation](/user-guide/data-integration/openflow/connectors/sql-server/setup#label-sql-server-snapshot-isolation). # Understanding data retention The connector follows a data retention philosophy where customer data is never automatically deleted. You maintain full ownership and control over your replicated data, and the connector preserves historical information rather than permanently removing it. This approach has the following implications: - Rows deleted from the source table are soft-deleted in the destination table rather than physically removed. - Columns dropped from the source table are renamed in the destination table rather than dropped. - Journal tables are retained indefinitely and are not automatically cleaned up. ## Destination table metadata columns Each destination table includes the following metadata columns that track replication information:
## Soft-deleted rows When a row is deleted from the source table, the connector does not physically remove it from the destination table. Instead, the row is marked as deleted by setting the `_SNOWFLAKE_DELETED` metadata column to `true`. This approach allows you to: - Retain historical data for auditing or compliance purposes. - Query deleted records when needed. - Decide when and how to permanently remove data based on your requirements. To query only active (non-deleted) rows, filter on the `_SNOWFLAKE_DELETED` column: ```sql SELECT * FROM my_table WHERE _SNOWFLAKE_DELETED = FALSE; ``` To query deleted rows: ```sql SELECT * FROM my_table WHERE _SNOWFLAKE_DELETED = TRUE; ``` ## Dropped columns When a column is dropped from the source table, the connector does not drop the corresponding column from the destination table. Instead, the column is renamed by appending the `__SNOWFLAKE_DELETED` suffix to preserve historical values. For example, if a column named `EMAIL` is dropped from the source table, it is renamed to `EMAIL__SNOWFLAKE_DELETED` in the destination table. Rows that existed before the column was dropped retain their original values, while rows added after the drop have `NULL` in this column. You can still query historical values from the renamed column: ```sql SELECT EMAIL__SNOWFLAKE_DELETED FROM my_table; ``` ## Renamed columns Due to limitations in CDC (Change Data Capture) mechanisms, the connector cannot distinguish between a column being renamed and a column being dropped followed by a new column being added. As a result, when you rename a column in the source table, the connector treats this as two separate operations: dropping the original column and adding a new column with the new name. For example, if you rename a column from `A` to `B` in the source table, the destination table will contain: - `A__SNOWFLAKE_DELETED`: Contains values from before the rename. Rows added after the rename have `NULL` in this column. - `B`: Contains values from after the rename. Rows that existed before the rename have `NULL` in this column. ### Querying renamed columns To retrieve data from both the original and renamed columns as a single unified column, use a `COALESCE` or `CASE` expression: ```sql SELECT COALESCE(B, A__SNOWFLAKE_DELETED) AS A_RENAMED_TO_B FROM my_table; ``` Alternatively, using a `CASE` expression: ```sql SELECT CASE WHEN B IS NOT NULL THEN B ELSE A__SNOWFLAKE_DELETED END AS A_RENAMED_TO_B FROM my_table; ``` ### Creating a view for renamed columns Rather than manually modifying the destination table, you can create a view that presents the renamed column as a single unified column. This approach is recommended because it preserves the original data and avoids potential issues with ongoing replication. ```sql CREATE VIEW my_table_unified AS SELECT *, COALESCE(B, A__SNOWFLAKE_DELETED) AS A_RENAMED_TO_B FROM my_table; ``` Manually modifying the destination table structure (such as dropping or renaming columns) is not recommended, as it may interfere with ongoing replication and cause data inconsistencies. ## Journal tables During incremental replication, changes from the source database are first written to journal tables before being merged into the destination tables. The connector does not automatically remove data from journal tables, as this data may be useful for auditing, debugging, or reprocessing purposes. Journal tables are created in the same schema as their corresponding destination tables and follow this naming convention: `_JOURNAL__` Where: - `` is the name of the destination table. - `` is the creation timestamp in Unix epoch format (seconds since January 1, 1970), ensuring uniqueness. - `` starts at 1 and increments whenever the destination table schema changes, either due to schema changes in the source table or modifications to column filters. For example, if your destination table is `SALES.ORDERS`, the journal table might be named `SALES.ORDERS_JOURNAL_1705320000_1`. Do not drop journal tables while replication is in progress. Removing an active journal table may cause data loss or replication failures. Only drop journal tables after the corresponding source table has been fully removed from replication. ### Managing journal table storage If you need to manage storage costs by removing old journal data, you can create a Snowflake task that periodically cleans up journal tables for tables that are no longer being replicated. Before implementing journal cleanup, verify that: - The corresponding source tables have been fully removed from replication. - You no longer need the journal data for auditing or processing purposes. For information on creating and managing tasks for automated cleanup, see [Introduction to tasks](/user-guide/tasks-intro). ## Next steps Review [Openflow connectors for SQL Server: Data mapping](/user-guide/data-integration/openflow/connectors/sql-server/data-mapping) to understand how the connector maps data types to Snowflake data types. Review [Set up the Openflow Connector for SQL Server](/user-guide/data-integration/openflow/connectors/sql-server/setup) to set up the connector. --- title: About Openflow Connector for SQL Server (CDC) source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/sql-server-cdc/about.md section: Loading & Unloading Data --- # About %sqlservercdc% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Monitor Openflow using telemetry data](/user-guide/data-integration/openflow/monitor) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Set up the Openflow Connector for SQL Server (CDC)](/user-guide/data-integration/openflow/connectors/sql-server-cdc/setup) - [Openflow connectors for SQL Server: Data mapping](/user-guide/data-integration/openflow/connectors/sql-server/data-mapping) This topic describes the basic concepts, workflow, and limitations of the %sqlservercdc%. ## About the %sqlservercdc% The %sqlservercdc% connects a SQL Server database instance to Snowflake and replicates data from selected tables in near real-time or on a schedule. The connector uses SQL Server Change Data Capture (https://learn.microsoft.com/en-us/sql/relational-databases/track-changes/about-change-data-capture-sql-server) (CDC) to detect and apply changes to replicated tables. Change data is recorded in change tables alongside the current state of the replicated tables. ## Use cases Use this connector if you're looking to do the following: - Synchronize SQL Server data with Snowflake for comprehensive, centralized reporting. - Capture every individual row-level change from the source database, including intermediate states between polling intervals. ## Supported SQL Server versions The following SQL Server database versions and platforms are supported: - Microsoft SQL Server 2025 - Microsoft SQL Server 2022 (https://www.microsoft.com/sql-server) - Microsoft SQL Server 2019 - Microsoft SQL Server 2017 - Microsoft SQL Server 2016 (SP1 or later, Enterprise / Standard / Developer edition) - Azure SQL Database (https://learn.microsoft.com/azure/azure-sql/database/?view=azuresql) - Azure SQL Managed Instance (https://learn.microsoft.com/azure/azure-sql/managed-instance/?view=azuresql) - AWS RDS for SQL Server (https://docs.aws.amazon.com/AmazonRDS/latest/UserGuide/CHAP_SQLServer.html) - Google Cloud SQL for SQL Server The connector requires SQL Server Change Data Capture to be enabled on the source databases and tables. CDC isn't available on SQL Server Express or SQL Server Web editions (including the Web edition on AWS RDS). SQL Server 2017 and later support CDC on the Enterprise, Standard, and Developer editions. On SQL Server 2016, CDC on the Standard edition requires SP1 or later; builds before 2016 SP1 require the Enterprise or Developer edition. ## Openflow requirements - The runtime size must be at least Medium. For guidance on choosing a size and resizing the runtime later, see [Runtime sizing](#label-sql-server-cdc-runtime-sizing). - The connector doesn't support multi-node Openflow runtimes. Configure the runtime for this connector with **Min nodes** and **Max nodes** set to `1`. ## Limitations - You can't run multiple connectors of the same type in a single runtime instance. - The connector supports only username and password authentication with SQL Server. - Each replicated table must have a primary key, a qualifying unique constraint, a qualifying unique index, or a user-declared logical key. For more information, see [](#label-sqlserver-cdc-replication-key-selection). - The connector doesn't update existing records in the Snowflake database when a new NOT NULL column with a default value is added to one of the source databases. - The connector doesn't update existing records in the Snowflake database when a new column is added to the included list in the Column Filter JSON. - The connector supports common source table schema changes during replication, such as adding and dropping columns. See [Schema changes](#label-sql-server-cdc-schema-changes) for the full list and a few unsupported change types. - The connector doesn't detect at runtime when you drop or modify the primary key, unique constraint, or unique index that it uses as the replication key, or when you alter or drop a logical-key column after the CDC capture instance exists. After any such change, restart replication for the affected table: see [Restart table replication](/user-guide/data-integration/openflow/connectors/sql-server-cdc/maintenance#label-of-sql-server-cdc-restart-table-replication). - When a new column is added to a source table and an update changes only that newly added column, SQL Server Change Data Capture doesn't record those updates in the change table, so the connector can't replicate them as individual change events. This is a SQL Server CDC limitation: a change is captured only when an update modifies at least one column that the table's capture instance already tracks. The connector still reflects the latest value of the new column in the destination table after the connector switches to the new capture instance. - The connector doesn't support the truncate table operation. `TRUNCATE` statements on the source are ignored, and the corresponding row deletions are not applied to the destination table. You can bypass limitations affecting certain table columns by excluding these specific columns from replication. ## Workflow The following workflow outlines the steps to set up and run the %sqlservercdc%: 1. A SQL Server database administrator performs the following tasks: 1. Enables Change Data Capture on each database using `sys.sp_cdc_enable_db`, then creates a capture instance for each table to be replicated using `sys.sp_cdc_enable_table`. 2. Creates credentials for the connector. 3. Deploys the Openflow CDC wrapper procedures so the connector can rotate capture instances during supported schema changes. If permissions or internal policy blocks deployment, see [When the wrapper procedures aren't deployed](#label-sql-server-cdc-wrapper-procedures-missing). 4. (Optional) Provides the SSL certificate to connect to the SQL Server instance over SSL. 2. A Snowflake account administrator performs the following tasks: 1. Creates a service user for the connector, a destination database to store replicated data, and a warehouse for the connector. 2. Installs the connector. 3. Specifies the required parameters for the connector flow definition. 4. Runs the flow. The connector does the following when run in Openflow: 1. Creates the schemas and destination tables matching the source tables configured for replication. 2. Begins replication according to the table replication lifecycle. For more information, see [](#label-of-sql-server-cdc-how-tables-are-replicated). ## How the connector works The following sections describe how the connector works in various scenarios, including replication, snapshots of partitioned tables, changes in schema, and data retention. ### Change Data Capture behavior The connector uses SQL Server Change Data Capture (https://learn.microsoft.com/en-us/sql/relational-databases/track-changes/about-change-data-capture-sql-server) (CDC) to detect changes in the source tables. CDC captures row-level insert, update, and delete activity from the SQL Server transaction log into dedicated change tables. Because CDC preserves every individual change, the connector is suitable for both **data synchronization** use cases and **audit or history** use cases where every change to a row must be captured. For a comparison with the %sqlserver%, which uses Change Tracking instead, see [Comparison of Openflow connectors for SQL Server](/user-guide/data-integration/openflow/connectors/sql-server-cdc/compare-change-tracking-cdc). ### Data replication The connector supports replicating tables from multiple SQL Server databases in a single SQL Server instance. The connector creates replicated tables from different databases in separate schemas in the destination Snowflake database. Reference replicated tables by combining the source database name, the source schema name, and the table name in the following format: `..` For each schema in each source database being replicated, the connector creates a separate schema in the destination Snowflake database. The name of the destination schema is a combination of the source database name and the source schema name, separated by an underscore character (`_`) as shown in the following example: `_` The connector creates tables in the destination schema with the same name as the source table name as shown in the following example: `..` ### How tables are replicated The connector replicates tables in the following stages: 1. Schema introspection: The connector discovers the columns in the source table, including the column names and types, then validates them against Snowflake's and the connector's limitations. Validation failures cause this stage to fail, and the cycle completes. After successful completion of this stage, the connector creates an empty destination table. 2. Snapshot load: The connector copies all data available in the source table into the destination table. If this stage fails, the connector stops replicating data. After successful completion, the data from the source table is available in the destination table. For how large partitioned tables are handled, see [Snapshot of partitioned tables](#label-sql-server-cdc-partitioned-snapshot). 3. Incremental load: The connector reads new entries from the CDC change tables and applies those changes to the destination table. This process continues until the table is removed from replication. Failure at this stage stops replication of the source table until the issue is resolved. For information on bypassing snapshot load and using the incremental load process, see [Incremental replication](/user-guide/data-integration/openflow/connectors/sql-server-cdc/incremental-replication). ### Snapshot of partitioned tables During snapshot load, the connector pages through each source table in primary key order. For a large table that is physically partitioned (https://learn.microsoft.com/en-us/sql/relational-databases/partitions/partitioned-tables-and-indexes) on the source, this ordering can force SQL Server to sort the whole table on every batch when no index delivers rows in the required order, which makes the snapshot extremely slow or prevents it from completing. To avoid this, the connector snapshots a physically partitioned table one partition at a time. Reading a single partition lets SQL Server stream rows in index order without a sort, so each batch finishes quickly. This behavior is automatic: the connector detects partitioned tables and requires no configuration change. Non-partitioned tables are unaffected and continue to be read as a whole. This per-partition optimization applies only to the snapshot phase. Incremental load reads from the CDC change tables and isn't affected. ### How the connector chooses a replication key The connector uses one column or set of columns from each source table as the replication key. The replication key uniquely identifies a row, drives the MERGE operation that applies CDC changes to the destination, and orders rows during the snapshot load. For each table, the connector resolves the replication key in this order: 1. **User-declared logical key.** If the connector's **Table Key Configuration JSON** parameter lists the table, the connector uses those columns as the replication key, overriding any primary key, unique constraint, or unique index on the table. For more information, see [Specify a logical key for a table](/user-guide/data-integration/openflow/connectors/sql-server-cdc/setup#label-sqlserver-cdc-logical-key). 2. **Primary key.** The columns of the table's enabled primary key constraint. 3. **Unique constraint or unique index.** If the table has no primary key, the connector looks for a qualifying unique constraint or unique index, as described in [](#label-sqlserver-cdc-replication-key-uk-criteria). 4. **None.** If no qualifying key is found, the connector can't replicate the table. To resolve this, either add a primary key to the table, modify an existing constraint or index so it qualifies (see the following criteria), or declare a logical key on columns that uniquely identify rows. #### Qualifying unique constraints and unique indexes The connector evaluates a unique constraint or unique index as a candidate replication key only when: - It's unique and isn't the primary key. - It's enabled (not disabled). - It's a standard B-tree index. Filtered indexes (those with a `WHERE` clause) are excluded. - All columns covered by the constraint or index are `NOT NULL`. SQL Server `text`, `image`, and `varbinary(max)` columns can't appear in unique constraints or unique indexes, so they never qualify as replication-key columns. #### Tiebreakers When more than one candidate qualifies, the connector picks one deterministically using the following preferences, in order: 1. Among all candidates, a unique constraint is preferred over a unique index. 2. Among candidates of the same type, the candidate with the fewest columns is preferred. 3. Among candidates with the same column count, the candidate with the most numeric columns is preferred. The connector counts the following SQL Server types as numeric: `INT`, `BIGINT`, `SMALLINT`, `TINYINT`, `DECIMAL`, `NUMERIC`, `MONEY`, `SMALLMONEY`, `FLOAT`, `REAL`. 4. If a tie remains, the candidate with the lowest constraint or index name in alphabetical order is selected. If you want a specific column set used regardless of the tiebreaker outcome, declare it as a logical key. For more information, see [Specify a logical key for a table](/user-guide/data-integration/openflow/connectors/sql-server-cdc/setup#label-sqlserver-cdc-logical-key). #### Replication key example The following table has no primary key but has a unique constraint on a `NOT NULL` column. The constraint qualifies, and the connector replicates the table using the constraint as the replication key: ```sql CREATE TABLE customers ( email NVARCHAR(255) NOT NULL, name NVARCHAR(100), created_at DATETIME2 DEFAULT SYSUTCDATETIME(), CONSTRAINT uq_customers_email UNIQUE (email) ); ``` ### Schema changes During incremental replication, the connector detects many source table schema changes and applies them automatically through SQL Server capture instance rotation, without stopping replication or requiring a manual re-snapshot of the table. Unsupported changes stop replication for the affected table until you restart it. To manage capture instances, the connector uses the wrapper procedures deployed during setup. For more information, see [Deploy the Openflow CDC wrapper procedures](/user-guide/data-integration/openflow/connectors/sql-server-cdc/setup#label-sql-server-cdc-wrapper-procedures). #### Supported changes The connector supports the following schema changes: - **Add column.** The connector adds the column to the destination table and replicates values for new and updated rows. Existing rows aren't backfilled; the new column is NULL for rows that existed before the change. - **Drop column.** The connector renames the destination column with a `__SNOWFLAKE_DELETED` suffix to preserve historical values. For details, see [Dropped columns](#dropped-columns). - **Compatible type change.** The connector transitions to a new capture instance that reflects the updated column definition when you change a column to a source type that maps to the same Snowflake data type (for example, `INT` to `BIGINT`, both mapped to `NUMBER`). - **Re-add a previously dropped column.** The connector adds the column as a new destination column alongside the existing soft-deleted column (for example, `A` and `A__SNOWFLAKE_DELETED`). - **Numeric precision or scale change.** For example, widening `DECIMAL(7,2)` to `DECIMAL(12,4)`. The connector transitions to a new capture instance that reflects the updated column definition. - **Character column length change.** The connector transitions to a new capture instance that reflects the updated column definition; for example, widening `VARCHAR(50)` to `VARCHAR(200)`. If you drop a column that was previously dropped and soft-deleted, replication for the affected table fails because the soft-deleted column name is already taken. #### Unsupported changes The connector doesn't support the following schema changes. When one occurs, replication stops for the affected table: - **Primary key definition change.** Adding or removing primary key columns, or changing which columns form the primary key. - **Incompatible type change.** When the new source type maps to a different Snowflake data type (for example, `INT` to `VARCHAR`, mapped to `NUMBER` and `TEXT` respectively). - **Rename column.** SQL Server doesn't allow renaming a column that belongs to an active CDC capture instance. This is a source-side restriction that SQL Server enforces itself, not a limitation of the connector: the rename statement fails on the source database before any change reaches the connector. #### When the wrapper procedures aren't deployed The connector expects `dbo.sf_openflow_cdc_enable_table` and `dbo.sf_openflow_cdc_disable_table` from [Deploy the Openflow CDC wrapper procedures](/user-guide/data-integration/openflow/connectors/sql-server-cdc/setup#label-sql-server-cdc-wrapper-procedures). Only use replication without them when permissions or internal policy blocks deployment. Treat that as a last resort, not the normal path. Replication still works until a supported schema change occurs; then a DBA must run manual capture-instance SQL for that change. Look for a WARN bulletin on the **MultiDatabaseCaptureChangeCdcSqlServer** processor whose message starts with `Schema-change replication` (Openflow bulletins or runtime logs). The bulletin includes the SQL to run. Use that script to unblock the table, or deploy the procedures and grants from [Deploy the Openflow CDC wrapper procedures](/user-guide/data-integration/openflow/connectors/sql-server-cdc/setup#label-sql-server-cdc-wrapper-procedures) so later schema changes don't need manual steps. After the fix, the connector continues on the next run without restarting the flow or re-adding the table. #### How the schema transition works A SQL Server capture instance records changes against a fixed set of columns that's frozen when the capture instance is created. When the schema of a source table changes, the connector can't keep using the same capture instance, so it transitions to a new capture instance that reflects the updated schema. This transition happens in the following stages: 1. **Schema change detection.** The connector detects DDL changes through a polling mechanism: it periodically queries SQL Server's `cdc.ddl_history` (https://learn.microsoft.com/en-us/sql/relational-databases/system-tables/cdc-ddl-history-transact-sql) table for the tables it replicates. The polling interval is configurable and defaults to 30 seconds, so a schema change is picked up shortly after it occurs rather than in the same cycle. 2. **New capture instance creation.** When the connector detects a schema change, it creates a new capture instance that reflects the post-change column set. The new capture instance starts recording changes from the point at which it's created. 3. **Draining the old capture instance.** The connector keeps reading from the old capture instance up to the point where the schema changed, so that no change committed under the old schema is lost. These changes are emitted using the old column set. All changes committed under the old schema are delivered to the destination before any changes recorded under the new schema, so the destination always receives changes in schema-consistent commit order. 4. **Mini-snapshot.** A gap exists between the point where the schema changed and the point where the new capture instance started recording. To fill this gap, the connector replays the changes in that gap from the old capture instance, joining them against the live source table so that newly added columns carry their current values. This mini-snapshot brings the destination table up to date with the new schema without a full re-snapshot of the whole table. 5. **Switching to the new capture instance.** After the mini-snapshot completes, the connector retires (drops) the old capture instance and resumes normal replication from the new one. #### Replaying already-sent changes When the connector detects a schema change, it might need to rewind and replay change records that it already sent. For example, records sent before a new column was detected don't include a value for that column, so the connector replays the affected rows to populate the new column. Because the connector applies changes idempotently by replication key, replaying these records doesn't create duplicate rows in the destination table. #### A schema change during a schema transition A second schema change can occur while the connector is still transitioning to a new capture instance because of an earlier change. The connector detects the follow-up change, provisions a newer capture instance that reflects the latest schema, and continues the transition against that newer instance, rewinding as needed so the affected changes are replayed under the most recent schema. No data is lost, and the transition completes against the most recent schema. ### Oversized values By default, the connector replicates individual values up to **16 MB**. When the connector encounters a larger value, it marks the associated table as permanently failed and stops replicating it. To change how the connector handles oversized values (for example, to replace them with `NULL` instead), modify the **Oversized Value Strategy** destination parameter. If your Snowflake account has the `ENABLE_OPENFLOW_CDC_BASED_SQLSERVER_SSV2` parameter set to `true`, the per-value limit can be raised from 16 MB to **128 MB**. For details and instructions on enabling the 128 MB per-value limit, see [Increase the oversized value limit](/user-guide/data-integration/openflow/connectors/sql-server-cdc/maintenance#label-of-sql-server-cdc-increase-oversized-value-limit). ### Always On Availability Groups and source failover The connector supports SQL Server Always On Availability Groups (https://learn.microsoft.com/sql/database-engine/availability-groups/windows/overview-of-always-on-availability-groups-sql-server). The connector tolerates planned and unplanned failover without requiring you to restart replication or remove tables from the connector configuration. During failover, source databases can be briefly offline while SQL Server moves the primary role to another replica. When a source database is temporarily unavailable, replicated tables keep their current status in the Table State Store. The connector retries on the next polling cycle and resumes incremental replication from the last recorded position once the database is online again. Transient connection errors and temporary source unavailability do not move tables to `FAILED`. This behavior is distinct from permanent failures such as unsupported schema changes or other source-side conditions that permanently stop change capture for a table. Those conditions still move affected tables to `FAILED` until you resolve the underlying problem and restart replication for the table. For connection settings, see [Always On Availability Groups](/user-guide/data-integration/openflow/connectors/sql-server-cdc/setup#label-sql-server-availability-groups). ### Source database locking behavior During the snapshot phase, the connector reads directly from the source tables to perform the initial full copy. Under SQL Server's default READ COMMITTED isolation level, these read operations acquire shared locks on the source tables, which can lead to deadlocks if other database clients hold conflicting locks at the same time. During incremental replication, the connector reads changes from dedicated CDC change tables, not from the source tables, so it doesn't take shared locks on the source tables and isn't subject to the deadlocks described here. To avoid deadlocks during the snapshot phase without affecting the isolation level that other applications use, configure the connector to read under SNAPSHOT isolation (https://learn.microsoft.com/en-us/dotnet/framework/data/adonet/sql/snapshot-isolation-in-sql-server). SNAPSHOT isolation reads from row versions instead of acquiring shared locks, so the connector's snapshot queries no longer contend with concurrent writes on the source tables. Because this approach makes SNAPSHOT isolation available only to the connector's own sessions, it doesn't change the default READ COMMITTED isolation level that other applications rely on. Avoid using Read Committed Snapshot Isolation (RCSI) for this purpose, because RCSI redefines the default isolation level for every connection to the database. For the steps to enable SNAPSHOT isolation for the connector, see [Read the source under SNAPSHOT isolation](/user-guide/data-integration/openflow/connectors/sql-server-cdc/setup#label-sql-server-cdc-snapshot-isolation). # Understanding data retention The connector follows a data retention philosophy where customer data is never automatically deleted. You maintain full ownership and control over your replicated data, and the connector preserves historical information rather than permanently removing it. This approach has the following implications: - Rows deleted from the source table are soft-deleted in the destination table rather than physically removed. - Columns dropped from the source table are renamed in the destination table rather than dropped. - Journal tables are retained indefinitely and are not automatically cleaned up. ## Destination table metadata columns Each destination table includes the following metadata columns that track replication information:
## Soft-deleted rows When a row is deleted from the source table, the connector does not physically remove it from the destination table. Instead, the row is marked as deleted by setting the `_SNOWFLAKE_DELETED` metadata column to `true`. This approach allows you to: - Retain historical data for auditing or compliance purposes. - Query deleted records when needed. - Decide when and how to permanently remove data based on your requirements. To query only active (non-deleted) rows, filter on the `_SNOWFLAKE_DELETED` column: ```sql SELECT * FROM my_table WHERE _SNOWFLAKE_DELETED = FALSE; ``` To query deleted rows: ```sql SELECT * FROM my_table WHERE _SNOWFLAKE_DELETED = TRUE; ``` ## Dropped columns When a column is dropped from the source table, the connector does not drop the corresponding column from the destination table. Instead, the column is renamed by appending the `__SNOWFLAKE_DELETED` suffix to preserve historical values. For example, if a column named `EMAIL` is dropped from the source table, it is renamed to `EMAIL__SNOWFLAKE_DELETED` in the destination table. Rows that existed before the column was dropped retain their original values, while rows added after the drop have `NULL` in this column. You can still query historical values from the renamed column: ```sql SELECT EMAIL__SNOWFLAKE_DELETED FROM my_table; ``` ## Renamed columns Due to limitations in CDC (Change Data Capture) mechanisms, the connector cannot distinguish between a column being renamed and a column being dropped followed by a new column being added. As a result, when you rename a column in the source table, the connector treats this as two separate operations: dropping the original column and adding a new column with the new name. For example, if you rename a column from `A` to `B` in the source table, the destination table will contain: - `A__SNOWFLAKE_DELETED`: Contains values from before the rename. Rows added after the rename have `NULL` in this column. - `B`: Contains values from after the rename. Rows that existed before the rename have `NULL` in this column. ### Querying renamed columns To retrieve data from both the original and renamed columns as a single unified column, use a `COALESCE` or `CASE` expression: ```sql SELECT COALESCE(B, A__SNOWFLAKE_DELETED) AS A_RENAMED_TO_B FROM my_table; ``` Alternatively, using a `CASE` expression: ```sql SELECT CASE WHEN B IS NOT NULL THEN B ELSE A__SNOWFLAKE_DELETED END AS A_RENAMED_TO_B FROM my_table; ``` ### Creating a view for renamed columns Rather than manually modifying the destination table, you can create a view that presents the renamed column as a single unified column. This approach is recommended because it preserves the original data and avoids potential issues with ongoing replication. ```sql CREATE VIEW my_table_unified AS SELECT *, COALESCE(B, A__SNOWFLAKE_DELETED) AS A_RENAMED_TO_B FROM my_table; ``` Manually modifying the destination table structure (such as dropping or renaming columns) is not recommended, as it may interfere with ongoing replication and cause data inconsistencies. ## Journal tables During incremental replication, changes from the source database are first written to journal tables before being merged into the destination tables. The connector does not automatically remove data from journal tables, as this data may be useful for auditing, debugging, or reprocessing purposes. Journal tables are created in the same schema as their corresponding destination tables and follow this naming convention: `_JOURNAL__` Where: - `` is the name of the destination table. - `` is the creation timestamp in Unix epoch format (seconds since January 1, 1970), ensuring uniqueness. - `` starts at 1 and increments whenever the destination table schema changes, either due to schema changes in the source table or modifications to column filters. For example, if your destination table is `SALES.ORDERS`, the journal table might be named `SALES.ORDERS_JOURNAL_1705320000_1`. Do not drop journal tables while replication is in progress. Removing an active journal table may cause data loss or replication failures. Only drop journal tables after the corresponding source table has been fully removed from replication. ### Managing journal table storage If you need to manage storage costs by removing old journal data, you can create a Snowflake task that periodically cleans up journal tables for tables that are no longer being replicated. Before implementing journal cleanup, verify that: - The corresponding source tables have been fully removed from replication. - You no longer need the journal data for auditing or processing purposes. For information on creating and managing tasks for automated cleanup, see [Introduction to tasks](/user-guide/tasks-intro). ## Next steps Review [Openflow connectors for SQL Server: Data mapping](/user-guide/data-integration/openflow/connectors/sql-server/data-mapping) to understand how the connector maps data types to Snowflake data types. Review [Set up the Openflow Connector for SQL Server (CDC)](/user-guide/data-integration/openflow/connectors/sql-server-cdc/setup) to set up the connector. --- title: About Openflow Connector for Workday source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/workday/about.md section: Loading & Unloading Data --- # About %workdayof% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Set up the Openflow Connector for Workday](/user-guide/data-integration/openflow/connectors/workday/setup) The Openflow Connector for Workday lets you ingest Workday reports into Snowflake. It is built as the Apache NiFi flow and uses the RaaS (Report-as-a-Service) API to fetch data from Workday. The connector persists data in a dedicated table in the database and schema provided in the configuration. Use this connector if you're looking to do the following: - Get Workday data into Snowflake using Report-as-a-Service (RaaS) streams for enterprise-level analytics and planning ## Limitations - Only advanced Workday reports are supported. - Only reports in the JSON format are supported. - All limitations of the RaaS API apply. - The schema discovery is not supported - schema of a destination table is inferred based on data fetched from Workday. - The incremental load is not supported - the connector uses the truncate & load ingestion strategy. ## Next steps [Set up the Openflow Connector for Workday](/user-guide/data-integration/openflow/connectors/workday/setup) --- title: About Openflow: BYOC deployments source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/about-byoc.md section: Loading & Unloading Data --- # About Openflow: BYOC deployments This feature is not available in the People's Republic of China. Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions). - [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) - [Openflow BYOC cost and scaling considerations](/user-guide/data-integration/openflow/cost-byoc) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Monitor Openflow using telemetry data](/user-guide/data-integration/openflow/monitor) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index) Openflow BYOC *is* Openflow and contains all the benefits of Openflow, but within your existing cloud. ## Typical BYOC workflow
## Limitations - As described in the [Snowflake Openflow BYOC terms](https://www.snowflake.cn/en/legal/optional-offerings/offering-specific-terms/openflow-terms/), securing Openflow BYOC is a shared responsibility model. - Openflow authorization uses roles and their associated privileges that are directly granted to the user. Currently, Openflow does not support authorization when the role is attached to another role within the user's role hierarchy. - Openflow BYOC deployments obtain all container images from the Snowflake System Image Registry. Sourcing Openflow images from a customer-owned AWS ECR repository is not supported. - The EKS cluster name is derived from the generated Openflow deployment key and is not configurable. - AWS CloudFormation stack tags are applied to the AWS-level resources created for the deployment, but not to Kubernetes-level objects inside the EKS cluster. For details, see [BYOC deployment customization and tagging behavior](/user-guide/data-integration/openflow/setup-openflow-byoc#label-openflow-byoc-customization-tagging). ## Next steps [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) --- title: About Salesforce Data Cloud and Snowflake source: https://docs.snowflake.cn/en/user-guide/data-integration/zero-copy/about-salesforce-datacloud.md section: Loading & Unloading Data --- # About Salesforce Data Cloud and Snowflake - [Set up Salesforce Data Cloud for Zero-Copy](/user-guide/data-integration/zero-copy/salesforce/setup-salesforce) - [Set up the Salesforce Data Cloud Zerocopy Connector](/user-guide/data-integration/zero-copy/salesforce/setup) - [Salesforce Data Cloud Zerocopy Connector: Security and privileges](/user-guide/data-integration/zero-copy/salesforce/security) - [Explore data products from Salesforce Data Cloud](/user-guide/data-integration/zero-copy/salesforce/explore-data-products) Snowflake and Salesforce have partnered to offer customers a seamless zero-copy integration between Salesforce Data Cloud and Snowflake. The integration enables customers to access semantically rich Salesforce data products directly from their existing Snowflake accounts, without ETL pipelines, data replication, or moving data out of Salesforce. Leveraging zero-copy data access, data and AI teams can work with real-time Salesforce customer, engagement, and business data in Snowflake, building analytics, machine learning models, and AI applications grounded in the full context of their mission-critical Salesforce data. ## How it works Salesforce Data Cloud shares data products with your Snowflake account through a Zerocopy Connector. The connector establishes a secure, authenticated channel between Salesforce Data Cloud and your Snowflake account. Once connected, Salesforce data products appear in Snowflake as catalog-linked databases, which are native Snowflake database objects that expose the shared data for querying without copying it. Data stays in Salesforce. Snowflake queries it on demand. There is no ETL and no duplication. ## Integration for existing Snowflake customers The Salesforce Data Cloud Zero-Copy integration is designed for existing Snowflake customers who want to bring Salesforce data products into their Snowflake account. You use your existing Snowflake account to set up the integration. As a Snowflake account administrator, you create a Zerocopy Connector in your account and retrieve an Enrollment ID. You then provide that Enrollment ID to your Salesforce administrator, who creates a Data Share Target in Salesforce Data Cloud to authorize the connection. Once connected, Salesforce administrators can share data products from the Salesforce Data Cloud catalog with your connector, and you can immediately query them in Snowflake. ## Prerequisites Before starting, ensure: - You have an existing Snowflake account (Standard, Enterprise, or Business Critical edition). - Your Snowflake account is in a supported region. For details, see [Supported Cloud Regions](/user-guide/intro-regions). - Your Salesforce administrator has access to Salesforce Data Cloud and can provision a connector and share data products. ## Set up the integration Perform the following tasks in order to set up, configure, and run the Salesforce Data Cloud Zero-Copy integration.
--- title: About Snowflake and SAP® Zero-Copy Integration source: https://docs.snowflake.cn/en/user-guide/data-integration/zero-copy/about-sap-snowflake.md section: Loading & Unloading Data --- # About %snowsapzerocopyintegration% - [Setup tasks for SAP® Snowflake and SAP® BDC Connect for Snowflake](/user-guide/data-integration/zero-copy/sap-sql/setup-tasks) Snowflake and SAP® have partnered to offer customers a seamless zero-copy integration between the two platforms. The integration leverages SAP® Business Data Cloud that enables customers to harmonize SAP® and non-SAP® data at scale in Snowflake, while optimizing total cost of ownership across workloads. Leveraging zero copy data access, data and AI teams can work with semantically rich SAP® Data Products in real time without added cost and complexity of ETL pipelines, and allows them to build AI and machine learning applications fueled by trusted SAP Data Products and grounded in the context of all their mission-critical data, ensuring accurate, reliable, and trustworthy AI outcomes. ## Two Ways to Integrate Snowflake and SAP® The integration delivers two distinct offerings, providing customers choice. Both leverage SAP® Business Data Cloud to enable zero-copy data sharing between SAP® Business Data Cloud and Snowflake. ### SAP® Snowflake Designed for new Snowflake customers, SAP® Snowflake makes Snowflake available in SAP® Business Data Cloud as a certified SAP® Solution Extension. From advanced analytics and ML to data engineering, applications, and marketplace it puts the Snowflake platform directly in the hands of SAP® users. For more information, see SAP Snowflake (https://help.sap.com/docs/business-data-cloud/introducing-sap-snowflake/introducing-sap-snowflake) in the SAP® documentation. ![SAP® Snowflake architecture](/static/images/openflow/sap-snowflake.png) #### SAP® Business Data Cloud Connect for Snowflake Designed for existing Snowflake customers, SAP® Business Data Cloud (BDC) Connect for Snowflake enables customers to share Data Products from SAP® BDC with their existing Snowflake accounts. This gives Snowflake users real-time access to semantically rich SAP® Data Products without duplication of data. ![SAP® BDC Connect for Snowflake architecture](/static/images/openflow/sap-bdc.png) For more information and set up instructions for either of these offerings, see [Setup tasks for SAP® Snowflake and SAP® BDC Connect for Snowflake](/user-guide/data-integration/zero-copy/sap-sql/setup-tasks). --- title: About the Openflow Connector for Google BigQuery source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/google-big-query/about.md section: Loading & Unloading Data --- # About the %bigqueryof% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [Setting Up the Openflow Connector for Google BigQuery](/user-guide/data-integration/openflow/connectors/google-big-query/setup) - [Use the Openflow Connector for Google BigQuery](/user-guide/data-integration/openflow/connectors/google-big-query/use) The %bigqueryof% connects a Google BigQuery project to Snowflake and replicates data from selected datasets, tables, and views on a schedule. The connector performs an initial full load for each table, followed by incremental updates using BigQuery's native change-tracking functionality. Views are replicated using a truncate and load strategy. ## Use cases The connector supports the following use cases: - **Replication to Snowflake:** Continuously mirror datasets from BigQuery into Snowflake for downstream analytics and modeling. Incremental changes arrive on a schedule with a 10 minute delay window. - **Selective replication:** Define which regions, datasets, tables, and views to include using names or regex filters for broad coverage with control. - **Migration and change capture:** Perform a one-time snapshot load for migrations, then run incremental syncs using BigQuery's change history to keep tables in sync. - **View replication:** Replicate standard and materialized BigQuery views to Snowflake using a truncate and load strategy on a configurable schedule. ## The table replication lifecycle A table's replication cycle begins with schema discovery and an initial snapshot load of the data. The cycle transitions to incremental synchronization after data has been ingested into Snowflake. 1. **Schema Introspection:** The connector discovers the source table's schema, validates its data types, and creates a corresponding destination schema and table in Snowflake. 2. **Snapshot Load:** After creating schema and table, the connector performs a full copy of all existing data from the BigQuery table to Snowflake. This process runs sequentially for each table in the configuration. 3. **Incremental Sync:** Once the initial load is complete, the table enters a scheduled incremental synchronization mode. On each run, the connector uses BigQuery's CHANGES function to read the journal of row-level changes (inserts, updates, deletes) that occurred since the last synchronization. These changes are then fetched and merged into the destination table in Snowflake. ## Openflow requirements The minimum runtime size must be `Medium`. Use a larger runtime and multi-node Openflow setup if you are replicating large data volumes. ## Limitations - BigQuery guarantees that data streams used to fetch source data remain valid for at least 6 hours. As a result, the process of reading the source table must be completed in less than 6 hours to prevent the data streams from expiring. You must use a larger, multi-node runtime when ingesting tables with data volumes that are larger than 100GB. - BigQuery’s BIGNUMERIC type supports a higher precision (up to 76 digits) than Snowflake's NUMBER type (38 digits). The connector cannot ingest values from BIGNUMERIC columns that exceed the Snowflake limit. - The connector does not support replication of external tables. - View replication uses a truncate and load strategy only. Incremental synchronization (CDC) is not supported for views. - Incremental syncs require a primary key to correctly handle updates and deletes. For tables without a primary key, the connector does not support deletes and treats updates as new inserts. You must ensure that the primary key constraints are met. If the field marked as the primary key is not unique, data inconsistency can occur during incremental mode. - The connector uses the BigQuery's CHANGES (https://cloud.google.com/bigquery/docs/reference/standard-sql/time-series-functions#changes) function for incremental updates. Because this function cannot query the last ten minutes of table history, replicated data in incremental mode has a minimum 10-minute lag behind the source. - The incremental sync process is limited to a maximum 24-hour data window due to the BigQuery CHANGES function. If the replication lag for a table exceeds this period, the connector truncates the change window to 24 hours to proceed with the sync. This truncation can result in data loss. - The connector inherits all other limitations of the BigQuery CHANGES function. For more information, see the BigQuery CHANGES function documentation (https://cloud.google.com/bigquery/docs/reference/standard-sql/time-series-functions#changes). ## View replication The connector supports replication of standard views and materialized views from BigQuery to Snowflake. Unlike table replication, views do not support incremental synchronization (CDC). Instead, the connector uses a **truncate and load** strategy: on each synchronization cycle, the connector fully replaces the data in the Snowflake destination table with the current contents of the source view. The view synchronization frequency is configured separately from table incremental sync frequency using the **View Sync Frequency** parameter. Runs do not overlap. If a cycle takes longer than the configured interval, the next run waits for the previous run to finish. You can filter which views to replicate using the **Included View Names** and **Included View Names Regex** parameters. These filters apply across all datasets selected for replication. The connector creates temporary tables in BigQuery during view ingestion. Use the **Temporary Table Dataset** parameter to specify a dedicated dataset for these temporary tables. Snowflake recommends using a separate dataset for temporary tables and not using the ingested dataset for this purpose. ## Data type mapping The connector maps BigQuery data types to the corresponding Snowflake data types.
## Track data changes in Google BigQuery The connector's incremental sync functionality is built on BigQuery's native CHANGES function (https://cloud.google.com/bigquery/docs/reference/standard-sql/time-series-functions#changes). When you enable change history on a source table, BigQuery maintains an internal journal of all row-level modifications (inserts, updates, and deletes). The connector queries this journal on a configured incremental sync frequency schedule to retrieve a feed of changes. The connector materializes these changes into a journal table within the same BigQuery dataset. This journal table follows a consistent naming convention: `___journal` These journal tables are managed entirely by the connector during the replication process and are used to merge data into the final destination table in Snowflake. Do not modify the journal tables in any way. Modifying journal tables can disrupt the synchronization process and lead to data integrity issues. The merge operation handles changes differently for tables with a Primary Key (PK) and tables without one. ### Tables with a Primary Key For tables with a primary key, the connector handles data changes as follows:
Inserts and Updates:
Rows identified as `INSERT` or `UPDATE` are "upserted" into the corresponding Snowflake table.
Deletes:
To preserve data history, the connector uses a soft-delete strategy. Instead of physically removing a deleted row from Snowflake, the connector performs an `UPDATE` on the target row, setting the `_SNOWFLAKE_DELETED` column to `TRUE`.
### Tables without a Primary Key For tables without a primary key, the connector handles data changes as follows:
Inserts and Updates:
Rows identified as `INSERT` or `UPDATE` are treated the same way and are inserted into the corresponding Snowflake table.
Deletes:
Not supported.
The connector automatically adds the `_SNOWFLAKE_DELETED` (BOOLEAN) column to the destination table schema when it is created. ### Configured synchronization frequency schedule vs actual synchronization frequency The Incremental Sync Frequency schedule determines the table synchronization frequency. If the schedule you specified is more frequent than the actual time required to synchronize the table, the system does not follow the schedule you specified. This occurs because incremental cycles must execute sequentially and cannot overlap. ## Schema Evolution The connector supports several common schema changes in the source BigQuery table. The following schema changes are detected and propagated to the Snowflake destination table:
Column Addition:
New columns added in BigQuery are automatically added to the corresponding Snowflake table.
Column Deletion (Soft Delete):
When a column is dropped in BigQuery, the connector performs a "soft delete" in Snowflake. The column is not dropped from the destination table. Instead, it is renamed by adding the `_SNOWFLAKE_DELETED` suffix to the end of the column name. For example `my_column` becomes `my_column_SNOWFLAKE_DELETED`. This preserves historical data in Snowflake.
Column Rename:
A column rename operation is a two-step process: 1. The original column is "soft deleted" and renamed with the `_SNOWFLAKE_DELETED` suffix added. 2. A new column with the new name is added to the Snowflake table.
Primary Key Modification:
Adding, removing and changing primary keys is supported.
Data Type Changes:
Only changes that widen the existing type are tolerated. Any change that narrows a column’s type or converts it to an incompatible type is not supported and will cause replication for that table to fail.
## Next steps For information on how to set up the connector, see the following topic: - [Setting Up the Openflow Connector for Google BigQuery](/user-guide/data-integration/openflow/connectors/google-big-query/setup) --- title: About the Openflow Connector for MongoDB source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/mongodb/about.md section: Loading & Unloading Data --- # About the %mongodbof% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [Connect to MongoDB](/user-guide/data-integration/openflow/connectors/mongodb/connect) - [Set up the Openflow Connector for MongoDB](/user-guide/data-integration/openflow/connectors/mongodb/setup) - [Use the Openflow Connector for MongoDB](/user-guide/data-integration/openflow/connectors/mongodb/use) This topic describes the basic concepts of the %mongodbof%, its workflow, and limitations. The %mongodbof% connects a MongoDB database to Snowflake and replicates data from selected collections on a schedule. The connector performs an initial full load for each collection, followed by incremental updates using MongoDB change streams. ## Use cases The connector supports the following use cases:
Replication to Snowflake
Continuously mirror collections from MongoDB into Snowflake for downstream analytics and modeling. Incremental changes arrive on a schedule with a delay window of a few minutes.
Selective replication
Define which collections to include using names or regex filters for broad coverage with control.
Migration and change capture
Perform a one-time snapshot load for migrations, then run incremental syncs using MongoDB change streams to keep collections in sync.
## Limitations The connector has the following limitations: - Standalone MongoDB instances aren't supported. The connector relies on the MongoDB oplog (operations log) to track changes. The MongoDB oplog is only available in a Replica Set or Sharded Cluster environment. - The minimum supported version of MongoDB is version 4.4. - The connector supports only username and password authentication with MongoDB. ## Snowflake table structure The connector maps MongoDB documents to the corresponding Snowflake table. The entire payload of the document is stored in the `data` field.
## Collection replication lifecycle A collection's replication cycle begins with an initial snapshot and transitions to incremental sync. 1. **Snowflake table creation:** The connector creates a table in Snowflake. The structure of the table is the same for each collection. For more information, see [](#label-mongodb-table-structure). 2. **Snapshot load:** After creating a table in Snowflake, the connector performs a full copy of all existing data from the MongoDB collection to the Snowflake table. This process runs sequentially for each collection in the configuration. 3. **Incremental sync:** After the initial load is complete, the collection enters incremental sync mode. The connector listens to the MongoDB change stream to read the journal document-level changes (inserts, updates, deletes) that accrued in the collection. These changes are then merged into the destination table in Snowflake. ## Openflow requirements The runtime size must be at least Medium. Use Large for high-throughput workloads or for replicating large collections. - The connector doesn't support multi-node Openflow runtimes. Configure the runtime for this connector with **Min nodes** and **Max nodes** set to `1`. For information about creating a warehouse for the connector, see [Designate a warehouse](/user-guide/data-integration/openflow/connectors/mongodb/connect#label-designate-warehouse). ## Workflow The workflow for the %mongodbof% involves steps performed by the MongoDB administrator and the Snowflake administrator. ### MongoDB administrator The MongoDB administrator performs the following tasks: 1. Enable replication The MongoDB administrator configures a replica set or sharded cluster. 2. Ensure the oplog size is sufficient For high-volume data ingestion, the MongoDB administrator must ensure the `oplogSizeMB` is sufficiently large to retain the history of changes during the connector or connectivity downtime. If the connector is offline for longer than the Oplog's retention period, the full re-sync of data might be required. ```yaml replication: replSetName: "myReplicaSet" oplogSizeMB: 51200 ``` 3. Create a database user The MongoDB administrator creates a user with the necessary roles to monitor changes in the database. The user requires the `readAnyDatabase` role on the `admin` database. 4. Configure network access The MongoDB administrator configures network access from MongoDB to the Openflow Runtime. ### Snowflake administrator The Snowflake administrator performs the following tasks: 1. Create a service user, a warehouse, and a destination database The administrator creates the necessary Snowflake objects for the replicated data. 2. Import the connector definition file The administrator imports the file into the Snowflake Openflow canvas. 3. Configure the flow The administrator configures the flow with the necessary MongoDB and Snowflake parameters. 4. Run the flow The administrator runs the flow. ## Next steps For information about configuring the source MongoDB database and the target Snowflake account, see [Connect to MongoDB](/user-guide/data-integration/openflow/connectors/mongodb/connect). --- title: About the Openflow Connector for Salesforce Bulk API source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/about.md section: Loading & Unloading Data --- # About the %salesforcebulkapiof% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [Openflow Connector for Salesforce Bulk API: Set up Salesforce](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/setup-salesforce) - [Openflow Connector for Salesforce Bulk API: Configure the connector](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/configure-connector) - [Openflow Connector for Salesforce Bulk API: Salesforce formula fields](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/formula-fields) - [Troubleshooting the Openflow Connector for Salesforce Bulk API](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/troubleshoot) This topic describes the basic concepts of the %salesforcebulkapiof%, its workflow, and limitations. ## Zero-copy integration with Salesforce Data Cloud Snowflake offers zero-copy bidirectional sharing and integration with Salesforce. This integration is recommended if you use Salesforce Data Cloud and require near real-time bidirectional integration. For more information about zero-copy integration with Salesforce Data Cloud, see the following blog posts: - Share Your Data from Salesforce Data Cloud to Snowflake (https://developer.salesforce.com/blogs/2024/08/share-your-data-from-salesforce-data-cloud-to-snowflake) - Zero Copy Data Federation with Snowflake and Salesforce Data Cloud (https://developer.salesforce.com/blogs/2024/08/zero-copy-data-federation-with-snowflake-and-salesforce-data-cloud) ## About the %salesforcebulkapiof% The %salesforcebulkapiof% provides replication-based data integration. This connector is designed for users who do not use Salesforce Data Cloud and prefer a fully managed Snowflake Openflow connector. The connector uses public Salesforce REST APIs to replicate data from Salesforce to Snowflake at a user-defined frequency. The connector supports Change Data Capture (CDC) and keeps data in Snowflake in sync with Salesforce. You can use one or both types of data integrations depending on your specific use cases. This topic describes how to set up and use the %salesforcebulkapiof% to replicate data from Salesforce to Snowflake. ## Use cases Use the %salesforcebulkapiof% to replicate standard or custom objects from Salesforce to Snowflake at a user-specified frequency and keep them up to date in Snowflake. ## Workflow The following workflow describes the steps to set up and use the %salesforcebulkapiof%. 1. A Salesforce administrator creates and configures an external client app in Salesforce and approves it for a specific user. 2. The Openflow administrator performs the following tasks: 1. Create a service user for the connector, a warehouse for the connector, and a destination database and schema to replicate into. 2. Install the connector. 3. Specify the required parameters for the flow template. 3. The data engineer runs the flow to replicate objects from Salesforce to Snowflake. ## Limitations Consider the following limitations when using the connector: - Custom Salesforce domains are not supported. - Traversing object relationships and fetching related objects is not supported. - The connector does not support hard deletes in Snowflake. You can either run a query on the destination table to delete all rows where the `isDeleted` column is `true` or perform a full refresh of the destination table to reflect "hard deletes". - Fields of type `location` and `address` are not supported and are ignored. - Fields of type `base64` (binary fields such as `Attachment.Body` and `ContentVersion.VersionData`) require a dedicated ingestion path. See [Configure blob field ingestion](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/configure-connector#blob-fields) for details. - You cannot consolidate data from multiple Salesforce instances into a single database in Snowflake. Data from a single Salesforce instance or org is ingested into a single database in Snowflake. A table is created in this database for each Salesforce object replicated. - Files attached to Salesforce records are ignored. - Formula fields are not replicated as data from Salesforce. Instead, the connector can translate supported Salesforce formulas into Snowflake SQL views. See [](#salesforce-formula-fields) for details on supported formulas and limitations. ## Authentication The connector uses the OAuth 2.0 JWT Bearer Flow via an external client app to connect to Salesforce and to retrieve data. This is the only supported OAuth flow for the connector. Using a different OAuth flow type (such as Authorization Code Flow) or misconfiguring the external client app can result in `invalid_grant` errors. See [Openflow Connector for Salesforce Bulk API: Set up Salesforce](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/setup-salesforce) for documentation on how to configure the external client app in Salesforce, and [Troubleshooting the Openflow Connector for Salesforce Bulk API](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/troubleshoot) for help with common authentication errors. ## Replication lifecycle The connector replicates data in two stages: initial replication and incremental replication. ### Initial replication The connector calls the Salesforce Bulk API 2.0 to discover standard and custom objects specified in the connector configuration. The connector respects Bulk API 2.0 API limits. - The connector creates one table per custom or standard object with one column for each field. - The connector uses Snowpipe Streaming v2 for the initial load to insert rows in the table based on the values of the fields from the Salesforce object. ### Incremental replication Incremental updates use a Snowflake warehouse that can be configured in the connector parameters. Depending on your latency and data freshness requirements, you can configure the refresh frequency for updates from 1 minute to 24 hours, which determines how often the tables in Snowflake are refreshed. Using the refresh frequency you specify, the connector calls the Salesforce Bulk API to detect changes in previously ingested objects. The connector identifies changed records by checking specific timestamp fields in the Salesforce objects. For most objects, the connector uses the `SystemModstamp` field. If `SystemModstamp` is not available, the connector attempts to use the following fields, in order of preference: 1. `LastModifiedDate` 2. `CreatedDate` 3. `LoginTime` For history tables (objects where History Tracking is enabled), the connector always uses the `CreatedDate` field to detect changes. The connector then uses Snowpipe Streaming v2 to push the incremental data into a staging table and executes a merge query to load the data into the final destination table. ## Schema evolution The connector supports schema evolution when the source objects change in Salesforce.
When a new field is added to the source object:
The connector adds a new column to the destination table in Snowflake.
When an existing field is renamed in the source object:
The connector treats the rename as both a field deletion and a field addition. The field addition causes a new column to be added to the destination table. The field deletion is handled as described next.
When an existing field is deleted in the source object:
The connector supports three strategies: - Delete: Deletes the corresponding column in the destination table in Snowflake. This is the default behavior. - Ignore: Ignores the deleted field in the source and skips it in the future. - Rename: Renames the deleted field in the destination table.
For example, if the deletion strategy is set to `Ignore` and a field is renamed for a Salesforce object, the existing column in Snowflake will be unchanged and a new column with the new field name will be added. ## How objects are deleted When objects are deleted in Salesforce, the connector does not "hard delete" them from Snowflake. The connector performs "soft deletes" for objects deleted in Salesforce and indicates that the source objects were deleted by setting the `isDeleted` column to `true` in the corresponding Snowflake tables. The connector does not support "hard deletes". You can either run a query on the destination table to delete all rows where the `isDeleted` column is `true` or perform a full refresh of the destination table to reflect "hard deletes". The connector may miss delete operations in situations where objects are deleted in Salesforce and purged from Salesforce's recycling bin when the connector was not running, for example if the connector was paused or stopped. You must perform a full refresh of the destination table to recover in these situations. ## Automatic retry handling The connector automatically retries failed operations or API errors using an exponential backoff strategy. The connector waits one second before the first retry, then doubles the wait time for each subsequent retry (two seconds, four seconds, and so on). If the failures persist, the connector stops retrying until the next scheduled run. You can monitor this activity in the [event table](/user-guide/data-integration/openflow/monitor). ## Use multiple connector instances to handle different sync schedules If you need to sync different objects at different frequencies, for example some every 30 minutes and others every 24 hours, Snowflake recommends deploying two separate connector instances within the same runtime. You can then configure the sync parameters independently for each instance. Deploying multiple connector instances in the same runtime does not incur additional costs. Similarly, if you need to fully fetch some objects every time the connector runs, Snowflake recommends deploying two separate connector instances within the same runtime and configuring the parameters for each instance. ## Salesforce formula fields Salesforce formula fields are calculated fields whose values are derived from expressions defined in Salesforce. Because the Salesforce Bulk API does not support incremental retrieval of formula field values, the connector takes a different approach: it translates the Salesforce formula expressions into Snowflake SQL and creates a view for each object that contains formula fields. To enable this feature, set the **Enable Views Creation** parameter to `true` in the connector configuration. See [Openflow Connector for Salesforce Bulk API: Configure the connector](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/configure-connector) for details. For more information, see [Openflow Connector for Salesforce Bulk API: Salesforce formula fields](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/formula-fields). ## Next steps For information on how to set up the connector, see the following topic: - [Openflow Connector for Salesforce Bulk API: Set up Salesforce](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/setup-salesforce) --- title: About the Openflow Connector for Shopify source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/shopify/about.md section: Loading & Unloading Data --- # About the %shopifyof% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [Set up the Openflow Connector for Shopify](/user-guide/data-integration/openflow/connectors/shopify/setup) - [Object definition overrides for the Openflow Connector for Shopify](/user-guide/data-integration/openflow/connectors/shopify/object-definitions) - [Maintain the Openflow Connector for Shopify](/user-guide/data-integration/openflow/connectors/shopify/maintain) - [Troubleshoot the Openflow Connector for Shopify](/user-guide/data-integration/openflow/connectors/shopify/troubleshoot) This topic describes the basic concepts, workflow, and limitations of the %shopifyof%. The %shopifyof% replicates data from a Shopify store into Snowflake using the Shopify Admin GraphQL API (https://shopify.dev/docs/api/admin-graphql). The connector uses Bulk Operations (https://shopify.dev/docs/api/usage/bulk-operations/queries) to efficiently extract large volumes of data and uses Snowpipe Streaming to load it into Snowflake. It supports initial bulk loads, incremental updates, and delete detection. ## Use cases Use the %shopifyof% to replicate data from your Shopify store into Snowflake for the following: - **E-commerce analytics:** Centralize order, product, and customer data in Snowflake for cross-channel reporting and business intelligence. - **Inventory management:** Bring inventory items and locations into Snowflake for demand forecasting and supply chain optimization. - **Customer insights:** Replicate customer and segment data in Snowflake for personalization, cohort analysis, and lifetime value modeling. - **Operational reporting:** Track fulfillment orders, draft orders, and transactions in Snowflake for real-time operational dashboards. ## Supported objects The connector ships with a built-in catalog of commonly replicated Shopify object types, including: - **Orders:** order data including line items, shipping and billing addresses, financial status, and fulfillment details. - **Products** and **Product Variants:** product catalog data including pricing, inventory, and variant information. - **Customers:** customer profiles, contact details, and marketing preferences. - **Collections:** manual and automated product collections. - **Inventory Items:** stock quantities and inventory tracking data. - **Fulfillment Orders:** fulfillment assignments and shipping details. The connector isn't limited to these objects. You can replicate any object type supported by the Shopify Admin GraphQL API by providing a custom definition in the **Object Definitions Override** parameter. Custom definitions let you choose which fields to extract, use GraphQL aliases to label or rename fields, and promote values from nested objects into dedicated top-level Snowflake columns. For more information, see [Object definition overrides for the Openflow Connector for Shopify](/user-guide/data-integration/openflow/connectors/shopify/object-definitions). For objects not in the built-in catalog, the connector can also auto-discover the schema using GraphQL introspection. For more information, see [Auto-discovery](#label-auto-discovery). ## Replication lifecycle The connector replicates data in two stages: initial bulk load and incremental synchronization. ### Initial bulk load When the connector runs for the first time (or after a state reset), it performs a bulk query for each configured object type using the Shopify Bulk Operations API. The connector: 1. Submits a bulk query to Shopify for each object type. 2. Polls Shopify until the bulk operation completes and a JSONL result file is available. 3. Downloads the JSONL result, flattens child connections into separate tables (with a `__PARENT_ID` column linking them to the parent record), and derives the Snowflake table schema from the GraphQL response. 4. Loads data into Snowflake using Snowpipe Streaming and merges it into the destination tables. ### Incremental synchronization After the initial load, the connector transitions to incremental mode. It uses timestamp-based watermarks to retrieve only records that have changed since the last sync. The connector selects the incremental field by checking the object's available fields against a priority list (`updatedAt`, `createdAt`, `processedAt`) and using the first match. The incremental frequency is user-configurable. Each incremental run retrieves changed records and merges them into the destination tables. ## Authentication The connector authenticates with Shopify using the OAuth2 client credentials grant. You provide a **Shopify Client ID** and **Shopify Client Secret** from a Shopify dev app, and the connector fetches tokens from the Shopify OAuth2 token endpoint and refreshes them as needed. For more information, see [Set up the Openflow Connector for Shopify](/user-guide/data-integration/openflow/connectors/shopify/setup). ## Auto-discovery The connector ships with a built-in object catalog that defines the GraphQL query structure for a set of commonly used Shopify object types. For objects not included in the catalog, the connector can optionally query the Shopify Admin GraphQL introspection endpoint to discover the schema dynamically. Auto-discovered definitions are cached in NiFi distributed state for 24 hours to avoid repeated introspection calls. For more information, see the [Enable Introspection](/user-guide/data-integration/openflow/connectors/shopify/setup#label-shopify-parameters) parameter. ## How deletes are handled For objects that support delete detection, the connector periodically queries the Shopify Events API (https://shopify.dev/docs/api/admin-graphql/latest/queries/events) using `action: "destroy"` and applies soft deletes in Snowflake. Only object types that emit destroy events in the Shopify Events API support delete detection. The connector sets a `__SNOWFLAKE_IS_DELETED` column to TRUE and a `__SNOWFLAKE_DELETED_AT` column to the timestamp of the deletion event. Rows are never physically removed from the destination table. When a parent record is soft-deleted, the connector cascades the soft delete to all registered child tables (for example, variants associated with a deleted product). ## Automatic retry and rate limiting The connector respects Shopify's rate limiting model, which uses a leaky bucket algorithm with a 1,000-point capacity that refills at 50 points per second. The connector tracks available points and automatically waits when the bucket is low to avoid throttling errors. For throttling responses, the connector retries automatically. When Shopify returns an HTTP 429, the connector waits for the duration specified in the `Retry-After` header before retrying. When the API returns a `THROTTLED` GraphQL error, the connector retries with exponential backoff. The default configuration allows up to 3 retries with an initial backoff of 1 second. ## Child record flattening For objects with nested connections (such as order line items or returns), the connector automatically extracts child records into separate Snowflake tables. Each child table includes a `__PARENT_ID` column that references the parent record's Shopify GID, enabling joins between parent and child tables. ## Limitations Consider the following limitations when using the connector: - The connector requires a Shopify dev app with Admin API access. - The Shopify Bulk Operations API (https://shopify.dev/docs/api/usage/bulk-operations/queries) supports a maximum of 5 connections per query and 2 levels of nesting. - The connector currently supports data extraction (ingestion) only. Writing data back to Shopify isn't supported. - Schema evolution isn't supported in the current release. If source objects gain or lose fields in Shopify, you must [reset the connector state for the affected object](/user-guide/data-integration/openflow/connectors/shopify/maintain#label-reload-a-specific-object) to re-ingest it with the updated schema. - Rate limits depend on your Shopify plan. The connector respects Shopify's leaky bucket throttling, but very high-volume stores with many objects might require careful scheduling to avoid sustained throttling. - Delete detection is only available for the object types listed in the **Objects to Track for Deletes** parameter. If an object type doesn't emit destroy events in the Shopify Events API, delete polls for that type return zero results. - The connector fetches up to the [`pageSize` value of each child connection](/user-guide/data-integration/openflow/connectors/shopify/object-definitions#label-child-fields) during incremental runs (maximum 250, the Shopify hard limit for incremental queries). Child records beyond this limit aren't captured. The initial bulk load isn't subject to this limit: the Shopify Bulk Operations API ignores the `first:` argument and returns all child records. ## Next steps To set up the connector, see [Set up the Openflow Connector for Shopify](/user-guide/data-integration/openflow/connectors/shopify/setup). --- title: About the Openflow Connector for Veeva Vault source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/veeva-vault/about.md section: Loading & Unloading Data --- # About the %veevavaultof% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [Setting up the Openflow Connector for Veeva Vault](/user-guide/data-integration/openflow/connectors/veeva-vault/setup) - [Use the Openflow Connector for Veeva Vault](/user-guide/data-integration/openflow/connectors/veeva-vault/use) The %veevavaultof% replicates data from a Veeva Vault instance into Snowflake using Direct Data API (https://general.veevavault.dev/direct-data-api). The connector downloads Direct Data files, extracts the CSV data they contain, and loads that data into Snowflake tables using Snowpipe Streaming. It supports full snapshots, incremental updates, and optional audit log ingestion. ## Use cases The connector supports the following use cases: - **Full data replication:** Perform a one-time full snapshot of all Veeva Vault data into Snowflake for reporting, analytics, and compliance. - **Incremental synchronization:** After the initial snapshot, the connector polls for incremental Direct Data files on a configurable schedule (default: every 15 minutes) to keep Snowflake tables up to date with changes in Veeva Vault. - **Audit log ingestion:** Optionally ingest Veeva Vault audit log archives alongside data archives, providing a complete audit trail in Snowflake. - **Migration and analytics:** Centralize Veeva Vault data in Snowflake for cross-system analytics, data science, and regulatory reporting. ## The replication lifecycle A table's replication cycle begins with a full data snapshot and then transitions to incremental synchronization. 1. **Snapshot phase:** The connector downloads the latest full Direct Data file from Veeva Vault. This archive is a tar.gz file containing one CSV per Vault data object. The connector unpacks the archive, creates a destination table in Snowflake for each object (if it doesn't already exist), loads the data through Snowpipe Streaming into a staging table, and merges the staging data into the final destination table. 2. **Incremental phase:** After the snapshot completes, the connector polls Veeva Vault for incremental Direct Data files. Each incremental file contains only the records that changed since the previous incremental file. The connector applies updates through the same staging-and-merge pipeline and processes deletes separately based on the configured delete strategy. Data freshness in Snowflake depends on how frequently Veeva Vault publishes Direct Data files and the configured sync frequency of the connector. 3. **Audit log phase (optional):** When audit log ingestion is enabled, the connector also downloads `log_directdata` files and loads them into Snowflake following the same pipeline. The connector groups Direct Data files by their reported time window and processes one window at a time to ensure each batch is handled atomically before moving to the next. The connector tracks its progress using a persisted state that records the last processed timestamp. If the connector is stopped and restarted, it resumes from where it left off. ## Ingestion modes The connector supports three ingestion modes that control how Direct Data files are consumed:
SNAPSHOT_AND_INCREMENTAL (default):
The connector first processes the latest full Direct Data file (snapshot). Once the snapshot is complete, it transitions to polling for incremental archives. This is the recommended mode for most deployments.
SNAPSHOT:
The connector continuously polls for the latest full Direct Data file. Each time a new full file becomes available, it is processed. Use this mode when you want to periodically replace all data in Snowflake with a fresh full export.
INCREMENTAL:
The connector polls only for incremental Direct Data files. No full snapshot is performed. Use this mode when a snapshot has already been loaded by other means or when only recent changes are needed. You can optionally specify a start time to control how far back incremental polling begins.
## Authentication The connector authenticates with Veeva Vault using session-based authentication. You provide a service account username and password, and the connector obtains a session identifier from the Vault API auth endpoint. This session is reused across requests and is automatically refreshed when it expires. For Snowflake authentication, the connector supports two strategies:
SNOWFLAKE_MANAGED (default):
Uses the Snowflake-managed token associated with the Openflow runtime's execute-as role. This is the recommended strategy for both %ofsfspcs-plural% and %ofbyoc-plural%.
KEY_PAIR:
Uses a user-provided RSA key pair for authentication. This strategy is available only on %ofbyoc-plural% and is intended for cross-account scenarios where the connector needs to write to a Snowflake account different from the one hosting the Openflow runtime.
## How deletes are handled When the connector receives a delete extract from Veeva Vault, it applies the deletes in Snowflake according to the configured delete strategy:
Hard Delete (default):
Rows are permanently removed from the destination table using a `DELETE` statement.
Soft Delete:
Rows are not removed. Instead, the connector sets a `__SNOWFLAKE_DELETED` column to `TRUE` and a `__SNOWFLAKE_DELETED_AT` column to the current timestamp. If these columns don't exist in the destination table, the connector adds them automatically.
## Schema evolution The connector supports schema evolution when the structure of Veeva Vault data changes between files. When the connector detects new columns in an incoming file, it automatically adds those columns to the destination and staging tables in Snowflake. When a column is no longer present in the incoming file, the connector applies the configured column removal strategy:
Drop Column (default):
Drops the column from the Snowflake table.
Rename Column:
Renames the column by appending a configurable suffix (default: `__deleted`). This preserves historical data in the table.
Ignore Column:
Leaves the column as-is in the Snowflake table and stops populating it.
## Automatic retry handling The connector automatically retries failed API calls using an exponential backoff strategy. Retryable conditions include HTTP status codes 500, 502, 503, and 504, as well as transient network errors. If a session expires or becomes invalid, the connector automatically re-authenticates and retries the request. ## Limitations Consider the following limitations when using the connector: - Direct Data must be enabled on your Vault instance before using the connector. Contact your Veeva Vault administrator to enable this feature. - The connector authenticates using session-based username and password credentials. Other authentication methods (such as OAuth) aren't yet supported. - The connector replicates structured data from Direct Data files only. Document and attachment content (such as files stored in Veeva Vault) isn't replicated. - The connector currently only performs an initial load of objects of type legacy_workflow (https://platform.veevavault.help/en/gr/5205/) and doesn't replicate ongoing changes. ## Next steps For information on how to set up the connector, see [Setting up the Openflow Connector for Veeva Vault](/user-guide/data-integration/openflow/connectors/veeva-vault/setup). --- title: About Workday Live Data Query for Snowflake source: https://docs.snowflake.cn/en/user-guide/data-integration/zero-copy/about-workday-ldq.md section: Loading & Unloading Data --- # About Workday Live Data Query for Snowflake Available to all accounts. - [Set up Snowflake for Workday Live Data Query](/user-guide/data-integration/zero-copy/workday/snowflake-setup) - [Connect to Workday and query data from Snowflake](/user-guide/data-integration/zero-copy/workday/connect-and-query) - [Use Cortex Code with Workday data](/user-guide/data-integration/zero-copy/workday/cortex-code) - [Troubleshoot Workday Live Data Query](/user-guide/data-integration/zero-copy/workday/troubleshooting) Workday Live Data Query for Snowflake is in Early Adopter (EA) for Workday and in Preview for Snowflake. To request access, contact your Workday account representative. Workday Live Data Query (LDQ) gives you real-time SQL access to Workday business data from Snowflake, without any ETL pipelines or data replication. Data stays in Workday; Snowflake queries it on demand through a Python connector running in a Snowflake Notebook. This integration is ideal for organizations that need up-to-date workforce and talent data inside Snowflake for analytics, reporting, or AI workloads, without the overhead and latency of a traditional data pipeline. ## How it works Workday LDQ uses a Trino-over-HTTPS connection to query the Workday Unified Data Catalog directly from a Snowflake Notebook. Authentication uses JWT Bearer OAuth2, with credentials stored securely as Snowflake Secrets. ``` Snowflake Notebook └── Python (workday_ldq wheel) └── JWT Bearer OAuth2 → Workday Token Endpoint └── Trino-over-HTTPS → Workday Live Data Query service └── Returns rows from Workday Unified Data Catalog ``` Because the data isn't copied into Snowflake, queries always reflect the current state of your Workday tenant. ## Available data In EA, the integration supports Workforce and Talent objects, including: - `worker` - `worker_contact_data` - `job_profile` Support for Financials, Payroll, and Student objects is planned for general availability (GA). ## Prerequisites Before starting, ensure you have the following from your Workday administrator:
You also need: - `ACCOUNTADMIN` (or equivalent) role in Snowflake to complete the initial setup. - The `ldq_python_client-*.whl` wheel file, available from the Workday Community portal. The steps in this guide use `WORKDAY_LDQ_TEST` as the base name for all Snowflake objects (for example, `WORKDAY_LDQ_TEST` database, `WORKDAY_LDQ_TEST_ROLE` role, `WORKDAY_LDQ_TEST_USER` user, `WORKDAY_LDQ_TEST_EAI` integration). Replace these with names that match your organization's naming conventions, and substitute consistently throughout all steps. ## Setup checklist
If you run into errors, see [Troubleshoot Workday Live Data Query](/user-guide/data-integration/zero-copy/workday/troubleshooting). --- title: ADLSCredentialsControllerService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/adlscredentialscontrollerservice.md section: Loading & Unloading Data --- # ADLSCredentialsControllerService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Defines credentials for ADLS processors. ## Tags adls, azure, cloud, credentials, microsoft, storage ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: ADLSCredentialsControllerServiceLookup source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/adlscredentialscontrollerservicelookup.md section: Loading & Unloading Data --- # ADLSCredentialsControllerServiceLookup This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides an ADLSCredentialsService that can be used to dynamically select another ADLSCredentialsService. This service requires an attribute named 'adls.credentials.name' to be passed in, and will throw an exception if the attribute is missing. The value of 'adls.credentials.name' will be used to select the ADLSCredentialsService that has been registered with that name. This will allow multiple ADLSCredentialsServices to be defined and registered, and then selected dynamically at runtime by tagging flow files with the appropriate 'adls.credentials.name' attribute. ## Tags adls, azure, cloud, credentials, microsoft, storage ## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: All controller services (alphabetical) source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/index.md section: Loading & Unloading Data --- # All controller services (alphabetical) - [About Openflow](/user-guide/data-integration/openflow/about) This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions). This topic provides a list of all openflow controller services in alphabetical order. The list includes:
- Type of controller service (Snowflake or not) - The name of each controller service - A summary of each controller service
## A
## C
## D
## E
## F
## G
## H
## I
## J
## K
## L
## M
## P
## R
## S
## U
## V
## W
## X
## Y
--- title: All processors (alphabetical) source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/index.md section: Loading & Unloading Data --- # All processors (alphabetical) - [About Openflow](/user-guide/data-integration/openflow/about) This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions). This topic provides a list of all Snowflake openflow processors in alphabetical order. The list includes:
- The name of each processor - A summary of each processor
## A
## C
## D
## E
## F
## G
## H
## I
## J
## L
## M
## N
## O
## P
## Q
## R
## S
## T
## U
## V
## W
--- title: AmazonGlueEncodedSchemaReferenceReader source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/amazonglueencodedschemareferencereader.md section: Loading & Unloading Data --- # AmazonGlueEncodedSchemaReferenceReader This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Reads Schema Identifier according to AWS Glue Schema encoding as a header consisting of a two byte markers and a 16 byte UUID ## Tags avro, aws, glue, registry, schema ## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: AmazonGlueSchemaRegistry source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/amazonglueschemaregistry.md section: Loading & Unloading Data --- # AmazonGlueSchemaRegistry This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides a Schema Registry that interacts with the AWS Glue Schema Registry so that those Schemas that are stored in the Glue Schema Registry can be used in NiFi. When a Schema is looked up by name by this registry, it will find a Schema in the Glue Schema Registry with their names. ## Tags avro, aws, glue, registry, schema ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: AmazonMSKConnectionService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/amazonmskconnectionservice.md section: Loading & Unloading Data --- # AmazonMSKConnectionService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides and manages connections to AWS MSK Kafka Brokers for producer or consumer operations. ## Tags aws, kafka, managed, msk, openflow, streaming ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: Apache Kafka for JSON/AVRO data format source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/kafka/kafka-json-avro.md section: Loading & Unloading Data --- # Apache Kafka for JSON/AVRO data format This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow Connector for Kafka](about) - [Set up the Openflow Connector for Kafka](setup) - [Configure MSK IAM authentication for Openflow Connector for Kafka](aws-msk-iam-auth) - [Configure mTLS authentication for Openflow Connector for Kafka](mtls-auth) - [Apache Kafka with DLQ and metadata](kafka-dlq-metadata) This topic describes the Apache Kafka connectors for JSON and AVRO data formats. These are simplified connectors optimized for basic message ingestion with schema evolution and topic-to-table mapping capabilities. ## Connector variants ### JSON data format connector The Apache Kafka for JSON data format connector is designed for straightforward JSON message ingestion from Kafka topics to Snowflake tables. Key features: - JSON message format support - Schema evolution - Topic-to-table mapping - SASL authentication ### AVRO data format connector The Apache Kafka for AVRO data format connector is designed for AVRO message ingestion from Kafka topics to Snowflake tables with schema registry support. Key features: - AVRO message format support - Schema registry integration - Schema evolution - Topic-to-table mapping - SASL authentication ## Specific parameters In addition to the common parameters described in [Set up the Openflow Connector for Kafka](setup), these connectors have specific parameter contexts. ### Schema registry parameters (AVRO connector only) The AVRO connector includes additional parameters for schema registry integration:
## Limitations These simplified connectors have the following limitations compared to the full-featured DLQ and metadata connector: - **No RECORD_METADATA column** - Kafka metadata is not stored in the target tables - **No dead letter queue (DLQ)** - Failed messages are not routed to a DLQ topic - **No Iceberg table support** - Only regular Snowflake tables are supported - **Fixed schematization** - Schema detection is always enabled and cannot be disabled Schema detection is enabled by default in these connectors and cannot be disabled. This means message fields are automatically flattened into individual table columns with automatic schema evolution. ## Use cases These connectors are ideal for:
Simple data ingestion
When you only need the message content without Kafka metadata.
High-throughput scenarios
Where the simplified data structure improves performance.
Schema evolution use cases
Where automatic table schema updates are required
JSON or AVRO message formats
With consistent schemas
If you need Kafka metadata, DLQ support, or Iceberg table ingestion, use the [Apache Kafka with DLQ and metadata](kafka-dlq-metadata) connector instead. ## Schema detection and evolution These connectors support automatic schema detection and evolution. The structure of tables in Snowflake is defined and evolved automatically to support the structure of new data loaded by the connector. With schema detection enabled (which is always the case for these connectors), Snowflake can detect the schema of the streaming data and load data into tables that automatically match any user-defined schema. Snowflake also allows adding new columns or dropping the `NOT NULL` constraint from columns missing in new data files. Schema detection with the connector is supported with or without a provided schema registry. If using schema registry (Avro), the column will be created with the data types defined in the provided schema registry. If there is no schema registry (JSON), the data type will be inferred based on the data provided. JSON ARRAY is not supported for further schematization. ### Schema evolution behavior If the connector creates the target table, schema evolution is enabled by default. If you want to enable or disable schema evolution on an existing table, use the [ALTER TABLE](/sql-reference/sql/alter-table) command to set the `ENABLE_SCHEMA_EVOLUTION` parameter. You must also use a role that has the `OWNERSHIP` privilege on the table. For more information, see [Enable automatic table schema evolution](/user-guide/data-load-schema-evolution). --- title: Apache Kafka with DLQ and metadata source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/kafka/kafka-dlq-metadata.md section: Loading & Unloading Data --- # Apache Kafka with DLQ and metadata This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow Connector for Kafka](about) - [Set up the Openflow Connector for Kafka](setup) - [Configure MSK IAM authentication for Openflow Connector for Kafka](aws-msk-iam-auth) - [Configure mTLS authentication for Openflow Connector for Kafka](mtls-auth) - [Apache Kafka for JSON/AVRO data format](kafka-json-avro) This topic describes the Apache Kafka with DLQ and metadata connector. This is the full-featured connector that provides feature parity with the legacy Snowflake connector for Kafka and includes advanced capabilities for production use cases. ## Key features The Apache Kafka with DLQ and metadata connector provides comprehensive functionality: - **Dead Letter Queue (DLQ)** support for failed message handling - **RECORD_METADATA** column with Kafka message metadata - **Configurable schematization** - enable or disable schema detection - **Iceberg table support** with schema evolution - **Multiple message formats** - JSON and AVRO support - **Schema registry integration** for AVRO messages - **Topic-to-table mapping** with advanced patterns - **SASL authentication** support ## Specific parameters In addition to the common parameters described in [Set up the Openflow Connector for Kafka](setup), this connector includes additional parameter contexts for advanced features. ### Message format and schema parameters
### Schema registry parameters
### DLQ and advanced features parameters
## Schematization behavior The connector's behavior changes based on the **Schematization Enabled** parameter: ### Schematization enabled When schematization is enabled, the connector: - Creates individual columns for each field in the message - Includes a **RECORD_METADATA** column with Kafka metadata - Automatically evolves the table schema when new fields are detected - Flattens nested JSON/AVRO structures into separate columns **Example table structure:**
### Schematization disabled When schematization is disabled, the connector: - Creates only two columns: **RECORD_CONTENT** and **RECORD_METADATA** - Stores the entire message content as an OBJECT in **RECORD_CONTENT** - Does not perform automatic schema evolution - Provides maximum flexibility for downstream processing **Example table structure:**
Use the `Schematization Enabled` property in the connector configuration properties to enable or disable schema detection. ## Schema detection and evolution The connector supports schema detection and evolution. The structure of tables in Snowflake can be defined and evolved automatically to support the structure of new data loaded by the connector. Without schema detection and evolution, the Snowflake table loaded by the connector only consists of two `OBJECT` columns: `RECORD_CONTENT` and `RECORD_METADATA`. With schema detection and evolution enabled, Snowflake can detect the schema of the streaming data and load data into tables that automatically match any user-defined schema. Snowflake also allows adding new columns or dropping the `NOT NULL` constraint from columns missing in new data files. Schema detection with the connector is supported with or without a provided schema registry. If using schema registry (Avro), the column will be created with the data types defined in the provided schema registry. If there is no schema registry (JSON), the data type will be inferred based on the data provided. JSON ARRAY is not supported for further schematization. ### Enabling schema evolution If the connector creates the target table, schema evolution is enabled by default. If you want to enable or disable schema evolution on the existing table, use the [ALTER TABLE](/sql-reference/sql/alter-table) command to set the `ENABLE_SCHEMA_EVOLUTION` parameter. You must also use a role that has the `OWNERSHIP` privilege on the table. For more information, see [Enable automatic table schema evolution](/user-guide/data-load-schema-evolution). However, if schema evolution is disabled for an existing table, then the connector will try to send the rows with mismatched schemas to the configured dead-letter queues (DLQ). ### RECORD_METADATA structure The **RECORD_METADATA** column contains important Kafka message metadata:
## Dead Letter Queue (DLQ) The DLQ functionality handles messages that cannot be processed successfully: ### DLQ behavior - **Parse failures** - Messages with invalid JSON/AVRO format are sent to the DLQ - **Schema mismatches** - Messages that don't match the expected schema when schema evolution is disabled - **Processing errors** - Other processing failures during ingestion ## Iceberg table support Openflow Connector for Kafka can ingest data into a Snowflake-managed [Apache Iceberg™ table](/user-guide/tables-iceberg) when **Iceberg Enabled** is set to *true*. ### Requirements and limitations Before you configure the Openflow Kafka connector for Iceberg table ingestion, note the following requirements and limitations: - You must create an Iceberg table before running the connector. - Make sure that the user has access to inserting data into the created tables. ### Configuration and setup To configure the Openflow Connector for Kafka for Iceberg table ingestion, follow the steps in [Set up the Openflow Connector for Kafka](setup) with a few differences noted in the following sections. #### Enable ingestion into Iceberg table To enable ingestion into an Iceberg table, you must set the `Iceberg Enabled` parameter to `true`. #### Create an Iceberg table for ingestion Before you run the connector, you must create an Iceberg table. The initial table schema depends on your connector `Schematization Enabled` property settings. If you enable schematization, you must create a table with a column named `record_metadata`: ```sql CREATE OR REPLACE ICEBERG TABLE my_iceberg_table ( record_metadata OBJECT() ) EXTERNAL_VOLUME = 'my_volume' CATALOG = 'SNOWFLAKE' BASE_LOCATION = 'my_location/my_iceberg_table'; ``` The connector automatically creates the columns for message fields and alters the `record_metadata` column schema. If you don't enable schematization, you must create a table with a column named `record_content` of a type that matches the actual Kafka message content. The connector automatically creates the `record_metadata` column. When you create an Iceberg table, you can use Iceberg data types or [compatible Snowflake types](/user-guide/tables-iceberg-data-types). The semi-structured VARIANT type isn't supported. Instead, use a [structured OBJECT or MAP](/sql-reference/data-types-structured). For example, consider the following message: ```sqljson { "id": 1, "name": "Steve", "body_temperature": 36.6, "approved_coffee_types": ["Espresso", "Doppio", "Ristretto", "Lungo"], "animals_possessed": { "dogs": true, "cats": false }, "date_added": "2024-10-15" } ``` ### Iceberg table creation examples **With schematization enabled:** ```sql CREATE OR REPLACE ICEBERG TABLE my_iceberg_table ( RECORD_METADATA OBJECT( offset INTEGER, topic STRING, partition INTEGER, key STRING, timestamp TIMESTAMP, SnowflakeConnectorPushTime BIGINT, headers MAP(VARCHAR, VARCHAR) ), id INT, body_temperature FLOAT, name STRING, approved_coffee_types ARRAY(STRING), animals_possessed OBJECT(dogs BOOLEAN, cats BOOLEAN), date_added DATE ) EXTERNAL_VOLUME = 'my_volume' CATALOG = 'SNOWFLAKE' BASE_LOCATION = 'my_location/my_iceberg_table'; ``` **With schematization disabled:** ```sql CREATE OR REPLACE ICEBERG TABLE my_iceberg_table ( RECORD_METADATA OBJECT( offset INTEGER, topic STRING, partition INTEGER, key STRING, timestamp TIMESTAMP, SnowflakeConnectorPushTime BIGINT, headers MAP(VARCHAR, VARCHAR) ), RECORD_CONTENT OBJECT( id INT, body_temperature FLOAT, name STRING, approved_coffee_types ARRAY(STRING), animals_possessed OBJECT(dogs BOOLEAN, cats BOOLEAN), date_added DATE ) ) EXTERNAL_VOLUME = 'my_volume' CATALOG = 'SNOWFLAKE' BASE_LOCATION = 'my_location/my_iceberg_table'; ``` RECORD_METADATA must always be created. Field names inside nested structures such as `dogs` or `cats` are case sensitive. ## Use cases This connector is ideal for: - **Production environments** requiring DLQ - **Data lineage and auditing** where Kafka metadata is important - **Complex message processing** with schema evolution requirements - **Iceberg table integration** If you need simpler ingestion without metadata or DLQ features, consider the [Apache Kafka for JSON/AVRO data format](kafka-json-avro) connectors instead. --- title: ApicurioSchemaRegistry source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/apicurioschemaregistry.md section: Loading & Unloading Data --- # ApicurioSchemaRegistry This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides a Schema Registry that interacts with the Apicurio Schema Registry so that those Schemas that are stored in the Apicurio Schema Registry can be used in NiFi. When a Schema is looked up by name by this registry, it will find a Schema in the Apicurio Schema Registry with their artifact identifiers. ## Tags apicurio, avro, registry, schema ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: AttributesToCSV 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/attributestocsv.md section: Loading & Unloading Data --- # AttributesToCSV 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Generates a CSV representation of the input FlowFile Attributes. The resulting CSV can be written to either a newly generated attribute named 'CSVAttributes' or written to the FlowFile as content. If the attribute value contains a comma, newline or double quote, then the attribute value will be escaped with double quotes. Any double quote characters in the attribute value are escaped with another double quote. ## Tags attributes, csv, flowfile ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: AttributesToJSON 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/attributestojson.md section: Loading & Unloading Data --- # AttributesToJSON 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Generates a JSON representation of the input FlowFile Attributes. The resulting JSON can be written to either a new Attribute 'JSONAttributes' or written to the FlowFile as content. Attributes which contain nested JSON objects can either be handled as JSON or as escaped JSON depending on the strategy chosen. ## Tags attributes, flowfile, json ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: AvroReader source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/avroreader.md section: Loading & Unloading Data --- # AvroReader This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Parses Avro data and returns each Avro record as an separate Record object. The Avro data may contain the schema itself, or the schema can be externalized and accessed by one of the methods offered by the 'Schema Access Strategy' property. ## Tags avro, comma, delimited, parse, reader, record, row, separated, values ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: AvroRecordSetWriter source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/avrorecordsetwriter.md section: Loading & Unloading Data --- # AvroRecordSetWriter This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Writes the contents of a RecordSet in Binary Avro format. ## Tags avro, record, recordset, result, row, serializer, set, writer ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: AvroSchemaRegistry source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/avroschemaregistry.md section: Loading & Unloading Data --- # AvroSchemaRegistry This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides a service for registering and accessing schemas. You can register a schema as a dynamic property where 'name' represents the schema name and 'value' represents the textual representation of the actual schema following the syntax and semantics of Avro's Schema format. ## Tags avro, csv, json, registry, schema ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: AWSCredentialsProviderControllerService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/awscredentialsprovidercontrollerservice.md section: Loading & Unloading Data --- # AWSCredentialsProviderControllerService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Defines credentials for Amazon Web Services processors. Uses default credentials without configuration. Default credentials support EC2 instance profile/role, default user profile, environment variables, etc. Additional options include access key / secret key pairs, credentials file, named profile, and assume role credentials. ## Tags aws, credentials, provider ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted ## Restrictions
## System Resource Considerations This component does not specify system resource considerations. --- title: AzureBlobStorageFileResourceService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/azureblobstoragefileresourceservice.md section: Loading & Unloading Data --- # AzureBlobStorageFileResourceService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides an Azure Blob Storage file resource for other components. ## Tags azure, blob, cloud, file, microsoft, resource, storage ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: AzureCosmosDBClientService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/azurecosmosdbclientservice.md section: Loading & Unloading Data --- # AzureCosmosDBClientService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides a controller service that configures a connection to Cosmos DB (Core SQL API) and provides access to that connection to other Cosmos DB-related components. ## Tags azure, cosmos, document, service ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: AzureDataLakeStorageFileResourceService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/azuredatalakestoragefileresourceservice.md section: Loading & Unloading Data --- # AzureDataLakeStorageFileResourceService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides an Azure Data Lake Storage (ADLS) file resource for other components. ## Tags adlsgen2, azure, cloud, datalake, file, microsoft, resource, storage ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: AzureEventHubRecordSink source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/azureeventhubrecordsink.md section: Loading & Unloading Data --- # AzureEventHubRecordSink This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Format and send Records to Azure Event Hubs ## Tags azure, record, sink ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: AzureStorageCredentialsControllerService_v12 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/azurestoragecredentialscontrollerservice_v12.md section: Loading & Unloading Data --- # AzureStorageCredentialsControllerService_v12 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides credentials for Azure Storage processors using Azure Storage client library v12. ## Tags azure, blob, cloud, credentials, microsoft, queue, storage ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: AzureStorageCredentialsControllerServiceLookup_v12 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/azurestoragecredentialscontrollerservicelookup_v12.md section: Loading & Unloading Data --- # AzureStorageCredentialsControllerServiceLookup_v12 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides an AzureStorageCredentialsService_v12 that can be used to dynamically select another AzureStorageCredentialsService_v12. This service requires an attribute named 'azure.storage.credentials.name' to be passed in, and will throw an exception if the attribute is missing. The value of 'azure.storage.credentials.name' will be used to select the AzureStorageCredentialsService_v12 that has been registered with that name. This will allow multiple AzureStorageCredentialsServices_v12 to be defined and registered, and then selected dynamically at runtime by tagging flow files with the appropriate 'azure.storage.credentials.name' attribute. ## Tags azure, blob, cloud, credentials, microsoft, queue, storage ## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: CalculateRecordStats 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/calculaterecordstats.md section: Loading & Unloading Data --- # CalculateRecordStats 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Counts the number of Records in a record set, optionally counting the number of elements per category, where the categories are defined by user-defined properties. ## Tags metrics, record, stats ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: CaptureChangeMySQL 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/capturechangemysql.md section: Loading & Unloading Data --- # CaptureChangeMySQL 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-database-cdc-processors-nar ## Description Reads CDC events from a MySQL database. The processor continuously reads events from binary log files, filtering those related to the tables provided by the TableStateService, and discarding the rest. The processor outputs two types of FlowFiles: - DDLs containing the schema of a table (the initial schema and a new schema on every schema change). - DMLs with records representing changes to the data in the table. One FlowFile always represents data related to a single table. The DDL with the schema is written to the FlowFile content as a JSON object: \{ "columns": [ \{ "name": "<columnName>", "type": "<snowflakeType>", "nullable": <true|false>, "scale": <scale>, "precision": <precision> \}, ... ], "primaryKeys": ["<primaryKey1>", "<primaryKey2>", ...] \} Structure of the FlowFiles containing the DML records: \{ "primaryKeys": \{ "<column>": <value>, ... \}, "payload": \{ "<column>": <value>, ... \}, "metadata": \{ "<column>": <value>, ... \} ## Tags cdc, event, jdbc, mysql, sql ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
--- title: CaptureChangePostgreSQL 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/capturechangepostgresql.md section: Loading & Unloading Data --- # CaptureChangePostgreSQL 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-database-cdc-processors-nar ## Description Reads CDC events from a PostgreSQL database. The processor continuously reads events arriving in the stream, filtering for those related to tables provided by the TableStateService, and discarding the rest. After the current batch of events is processed, the processor confirms the replication slot position back to PostgreSQL, letting it trim the WAL. The processor outputs two types of FlowFiles: DDLs, containing the initial schema of a table, and then every time its schema changes, and DMLs, with records representing changes to data in the table. One FlowFile always represents data related to a single table. The DDL with the schema is written to the FlowFile content as a JSON object, in a form such as: \{ "columns": [ \{ "name": "<columnName>", "type": "<snowflakeType>", "nullable": <true|false>, "scale": <scale>, "precision": <precision> \}, ... ], "primaryKeys": ["<primaryKey1>", "<primaryKey2>", ...] \} The DML records are structured as: \{ "primaryKeys": \{ "<column>": <value>, ... \}, "payload": \{ "<column>": <value>, ... \}, "metadata": \{ "<column>": <value>, ... \} ## Tags cdc, event, jdbc, postgresql, sql ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
--- title: CaptureChangeSqlServer 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/capturechangesqlserver.md section: Loading & Unloading Data --- # CaptureChangeSqlServer 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-database-cdc-processors-nar ## Description Reads CDC events from a SQL Server database. The processor periodically queries Change Tracking tables in the database, but only for the tables provided by the TableStateService. The processor maintains a state of the last processed event for each table. The processor moves the position after each processed table. The processor supports multi-threading. The number of threads and connection limit configured in the pool collectively define the upper bound of open connections to the source database. The processor outputs two types of FlowFiles: DDLs, containing the initial schema of a table, and then every time its schema changes, and DMLs, with records representing changes to data in the table. One FlowFile always represents data related to a single table. The DDL with the schema is written to the FlowFile content as a JSON object, in a form such as: \{ "columns": [ \{ "name": "<columnName>", "type": "<snowflakeType>", "nullable": <true|false>, "scale": <scale>, "precision": <precision> \}, ... ], "primaryKeys": ["<primaryKey1>", "<primaryKey2>", ...] \} The DML records are structured as: \{ "primaryKeys": \{ "<column>": <value>, ... \}, "payload": \{ "<column>": <value>, ... \}, "metadata": \{ "<column>": <value>, ... \} ## Tags cdc, event, jdbc, sql, sql server ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
--- title: CaptureGoogleDriveChanges 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/capturegoogledrivechanges.md section: Loading & Unloading Data --- # CaptureGoogleDriveChanges 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-google-drive-nar ## Description Captures changes to a Shared Google Drive and emits a FlowFile for each change that occurs. This includes addition and deletion of files, as well as changes to file metadata and permissions. The processor is designed to be used in conjunction with the FetchGoogleDrive processor. ## Tags authorization, cdc, change data capture, cloud, drive, gcp, google, openflow, permissions, storage, unstructured ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
## See also - [com.snowflake.openflow.runtime.processors.sharepoint.CaptureSharepointChanges](/user-guide/data-integration/openflow/processors/capturesharepointchanges) - [org.apache.nifi.processors.gcp.drive.FetchGoogleDrive](/user-guide/data-integration/openflow/processors/fetchgoogledrive) --- title: CaptureMicrosoft365GroupsChanges 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/capturemicrosoft365groupschanges.md section: Loading & Unloading Data --- # CaptureMicrosoft365GroupsChanges 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-msgraph-nar ## Description Captures Microsoft365 groups changes and emits a FlowFile for each change that occurs. This includes membership changes. ## Tags cdc, document, graph, library, microsoft, sharepoint, unstructured ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
--- title: CaptureSharepointChanges 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/capturesharepointchanges.md section: Loading & Unloading Data --- # CaptureSharepointChanges 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-msgraph-nar ## Description Captures changes from a Sharepoint Document Library and emits a FlowFile for each change that occurs. This includes additions and deletions of files and folders, as well as changes to permissions, metadata, and file content. ## Tags cdc, document, graph, library, microsoft, openflow, sharepoint, unstructured ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
## Use Cases Involving Other Components | Perform Change Data Capture on a Sharepoint Document Library, retrieving all data in the Document Library, including permissions, in order to keep a destination system in sync with Sharepoint. | | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ | ## See also - [com.snowflake.openflow.runtime.processors.sharepoint.FetchSharepointFile](/user-guide/data-integration/openflow/processors/fetchsharepointfile) --- title: CEFReader source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/cefreader.md section: Loading & Unloading Data --- # CEFReader This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Parses CEF (Common Event Format) events, returning each row as a record. This reader allows for inferring a schema based on the first event in the FlowFile or providing an explicit schema for interpreting the values. ## Tags cef, parser, reader, record ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: CheckMetaAdsReportReadiness 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/checkmetaadsreportreadiness.md section: Loading & Unloading Data --- # CheckMetaAdsReportReadiness 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-meta-ads-processors-nar ## Description Processor checking if the Meta Ads report is ready for download. ## Tags Facebook, Meta, Meta Ads, report ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: ChunkRecordText 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/chunkrecordtext.md section: Loading & Unloading Data --- # ChunkRecordText 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-chunking-nar ## Description Chunks text with options for recursively splitting by delimiters and max character length. The input text is expected to be in a record-oriented FlowFile that matches the configured Record Reader format. ## Tags chunk, openflow, text ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: ChunkText 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/chunktext.md section: Loading & Unloading Data --- # ChunkText 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-chunking-nar ## Description Chunks text with options for recursively splitting by delimiters and max character length. Each chunk is given the following attributes: fragment.identifier, fragment.index, fragment.count, segment.original.filename; these attributes can then be used by the MergeContent processor in order to reconstitute the original FlowFile ## Tags chunk, openflow, text ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: Comparison of Openflow connectors for SQL Server source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/sql-server-cdc/compare-change-tracking-cdc.md section: Loading & Unloading Data --- # Comparison of Openflow connectors for SQL Server This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow Connector for SQL Server (CDC)](/user-guide/data-integration/openflow/connectors/sql-server-cdc/about) - [About Openflow Connector for SQL Server](/user-guide/data-integration/openflow/connectors/sql-server/about) Snowflake provides two Openflow connectors for SQL Server. They differ primarily in how they detect source changes: - The %sqlserver% uses SQL Server Change Tracking to identify rows that changed between polls. - The %sqlservercdc% uses SQL Server Change Data Capture to capture every row-level change from the transaction log. ## What the connectors have in common Aside from how they detect source changes, the two connectors share the same core behavior and requirements: - Both replicate selected tables from one or more databases in a single SQL Server instance into Snowflake, in near real-time or on a schedule. - Both require an Openflow runtime of at least Medium size, running on a single node (set **Min nodes** and **Max nodes** to `1`). - Both support only username and password authentication with SQL Server. - Both replicate only tables that have a primary key. - You can't run more than one connector of the same type in a single runtime instance. ## How change detection differs Change Tracking reports only the net effect of changes between consecutive polls. If a row is updated multiple times between two polls, the %sqlserver% sees only the final state; intermediate states aren't preserved. Change Data Capture preserves every individual DML operation. If a row is updated multiple times between two consecutive polls, the %sqlservercdc% sees each intermediate state, in commit order. In practice, this means the %sqlserver% is a good fit for data-synchronization use cases where only the current row state matters, and the %sqlservercdc% is a good fit for audit or history use cases where every change must be captured in addition to keeping the destination synchronized. ## Source database impact The two SQL Server features are built around different trade-offs, and the connectors inherit those trade-offs. The %sqlserver% adds **per-transaction overhead on every DML operation** on a tracked table: - Each insert, update, and delete writes a row to SQL Server's internal change-tracking side tables, within the same transaction. Microsoft designs this overhead to be low. - The cost is paid on every DML operation, whether or not the changes are ever read. - On high-DML workloads, especially with wide primary keys or column tracking enabled, the overhead can become measurable. - The connector's incremental query joins `CHANGETABLE(CHANGES ...)` against the source table at each poll, so polling frequency and table activity add to source load. The %sqlservercdc% adds **no cost to DML transactions**, but shifts the cost elsewhere on the source: - DML transactions pay no extra write cost, because SQL Server writes the transaction log in any case. - A SQL Server Agent capture job reads the transaction log in the background and populates dedicated change tables. The job consumes CPU and I/O on the source. - The connector reads changes from a dedicated change table without taking row locks, so replication neither slows down application traffic nor is slowed down by it. - The transaction log can't be truncated past the capture job's position. A lagging capture job or a long-running transaction can cause the log to grow. As a rough guide: - For databases with low-to-moderate DML volumes where simple setup matters, the %sqlserver% tends to be the lighter-weight choice. - For high-volume OLTP workloads, or when keeping replication reads off the live source tables matters, the %sqlservercdc% tends to scale better. The trade-off is more source-side setup and more attention to transaction log retention. ## Supported SQL Server editions and environments The two SQL Server features have different availability on the source: - Change Tracking is available on all editions of SQL Server, including Express and Web, as well as Azure SQL Database and Azure SQL Managed Instance. - Change Data Capture requires SQL Server Standard or Enterprise edition. It isn't available on SQL Server Express or Web. For the specific versions and platforms each connector supports, see [](/user-guide/data-integration/openflow/connectors/sql-server/about#label-sql-server-versions) and [](/user-guide/data-integration/openflow/connectors/sql-server-cdc/about#label-sql-server-cdc-versions). ## Setup complexity - The %sqlserver% needs one database-level setting (`CHANGE_TRACKING = ON`) plus one table-level setting per replicated table. No SQL Server Agent, no capture instances. - The %sqlservercdc% requires SQL Server Agent to be running on the source. Each replicated table needs a capture instance, created through `sys.sp_cdc_enable_table`. Ongoing replication depends on the capture job staying healthy. If replicated tables contain LOB columns with values larger than 64 KB, you must also raise the SQL Server `max text repl size` setting on the source instance. For configuration steps by platform, see [Raise max text repl size for large LOB columns](/user-guide/data-integration/openflow/connectors/sql-server-cdc/setup#label-sql-server-cdc-max-text-repl-size). ## Schema change handling Both connectors apply supported source-table schema changes during replication, without a full re-snapshot of the table. Neither connector supports changing a table's primary key, or changing the precision or scale of a numeric column. - The %sqlserver% picks up schema changes on the next poll. It adds new columns to the destination table (without backfilling existing rows) and soft-deletes dropped columns by renaming them with a `__SNOWFLAKE_DELETED` suffix to preserve existing data. - The %sqlservercdc% applies schema changes automatically by transitioning to a new SQL Server capture instance that reflects the updated schema. This relies on the Openflow CDC wrapper procedures deployed during setup, which let the connector create and drop capture instances without holding elevated privileges. For details, see [](/user-guide/data-integration/openflow/connectors/sql-server-cdc/about#label-sql-server-cdc-schema-changes) and the **Schema changes** section of [About Openflow Connector for SQL Server](/user-guide/data-integration/openflow/connectors/sql-server/about). ## When to choose each connector Choose the %sqlserver% if you: - Only need the current row state in the destination, for example for data synchronization or centralized reporting. - Want the simplest source-side setup. - Run on an edition or platform where Change Data Capture isn't available. - Have low-to-moderate DML volumes and want to minimize moving parts on the source. Choose the %sqlservercdc% if you: - Need every individual row-level change, including intermediate states between polls, for audit or history use cases. - Run a high-volume OLTP source and want replication reads to stay off the live tables. - Can run on SQL Server Standard or Enterprise and can operate the SQL Server Agent capture job. --- title: CompressContent 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/compresscontent.md section: Loading & Unloading Data --- # CompressContent 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Compresses or decompresses the contents of FlowFiles using a user-specified compression algorithm and updates the mime.type attribute as appropriate. A common idiom is to precede CompressContent with IdentifyMimeType and configure Mode='decompress' AND Compression Format='use mime.type attribute'. When used in this manner, the MIME type is automatically detected and the data is decompressed, if necessary. If decompression is unnecessary, the data is passed through to the 'success' relationship. This processor operates in a very memory efficient way so very large objects well beyond the heap size are generally fine to process. ## Tags brotli, bzip2, compress, content, decompress, deflate, gzip, lz4-framed, lzma, snappy, snappy framed, snappy-hadoop, xz-lzma2, zstd ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## Use cases | Compress the contents of a FlowFile | | ------------------------------------- | | Decompress the contents of a FlowFile | ## Use Cases Involving Other Components | Check whether or not a FlowFile is compressed and if so, decompress it. | | ----------------------------------------------------------------------- | --- title: Configure a connector with the setup wizard source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/gen2/setup-connector-wizard.md section: Loading & Unloading Data --- # Configure a connector with the setup wizard Available to all accounts. - [Second generation Openflow objects and interfaces](/user-guide/data-integration/openflow/gen2/index) - [Openflow gen 1 and gen 2](/user-guide/data-integration/openflow/gen2/openflow-generations) - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Monitor connectors using the Openflow Connectors Dashboard](/user-guide/data-integration/openflow/connectors-dashboard) - [Configure a gen 2 connector with SQL](/user-guide/data-integration/openflow/gen2/configure-connector-sql) - [Manage the gen 2 Openflow connector lifecycle](/user-guide/data-integration/openflow/gen2/manage-connector-lifecycle) The Openflow connector setup wizard provides a guided, step-by-step experience for configuring gen 2 connectors. The wizard validates your inputs at each step so you can identify and fix configuration issues before completing the setup. This topic applies to gen 2 connectors only. For gen 1 catalog connectors, see [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors). For an overview of gen 1 vs gen 2, see [Openflow gen 1 and gen 2](/user-guide/data-integration/openflow/gen2/openflow-generations). ## Supported connectors The following **gen 2** connectors are available in the catalog: - PostgreSQL CDC - MySQL and MariaDB CDC ## Prerequisites Before you start the setup wizard, make sure the following requirements are met: - You have a **gen 2** Openflow deployment (BYOC or %OFSFSPCS%) with at least one gen 2 runtime. The wizard configures gen 2 connectors, which run on gen 2 runtimes only. To create deployment and runtime resources, see [Quickstart: gen 2 Openflow](/user-guide/data-integration/openflow/gen2/quickstart). For BYOC cloud installation, Snowflake deployment networking, deployment setup, and runtime parameters, see [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc), [Set up Openflow - Snowflake Deployment - Task overview](/user-guide/data-integration/openflow/setup-openflow-spcs), or [Set up Openflow - Snowflake Deployment: Create runtime](/user-guide/data-integration/openflow/setup-openflow-spcs-create-runtime) as applicable. If you are unsure whether your resources are gen 1 or gen 2, see [Openflow gen 1 and gen 2](/user-guide/data-integration/openflow/gen2/openflow-generations). - For %OFSFSPCS-plural%, your PostgreSQL database must be reachable through an [external access integration](/developer-guide/external-network-access/external-network-access-overview) (EAI) that references a [network rule](/sql-reference/sql/create-network-rule) permitting egress to your PostgreSQL hostname and port (the connector uses a customer-specific endpoint; see [PostgreSQL](#label-openflow-domains-used-by-openflow-connectors-postgresql)). Grant `USAGE` on the EAI to the runtime's `EXECUTE_AS_ROLE` (see [Create an execute-as role](/user-guide/data-integration/openflow/gen2/quickstart#label-openflow-gen2-quickstart-execute-as-role)). For setup steps, see [Configure external access](/user-guide/data-integration/openflow/gen2/quickstart#label-openflow-gen2-quickstart-eai) in the gen 2 quickstart or [Set up Openflow - Snowflake Deployment: Configure allowed domains for Openflow connectors](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list). If you use Openflow BYOC, configure outbound connectivity in your cloud environment so the runtime can reach PostgreSQL; Snowflake EAIs are not used in that deployment model. - Any required secrets (for example, database passwords or API keys) are created as [Snowflake secrets](/sql-reference/sql/create-secret) and accessible to the runtime's `EXECUTE_AS_ROLE` (see [Create an execute-as role](/user-guide/data-integration/openflow/gen2/quickstart#label-openflow-gen2-quickstart-execute-as-role)). - You have `CREATE OPENFLOW CONNECTOR` on the schema that the runtime is in, `USAGE` on the runtime, and `USAGE` on the runtime's database and schema. - You have the required permissions for the connector you want to install, and have completed any connector-specific source database prerequisites: [PostgreSQL CDC](/user-guide/data-integration/openflow/connectors/postgres/setup#source-database-setup) | [MySQL and MariaDB CDC](/user-guide/data-integration/openflow/connectors/mysql/setup#source-database-setup). For Snowflake account setup (destination database, warehouse, and secrets), follow the [Snowflake account setup](/user-guide/data-integration/openflow/connectors/postgres/setup#snowflake-account-setup) on those pages. ## Create and configure a connector 1. In the navigation menu, select **Ingestion** %raa% **Openflow**. 2. Select **Launch Openflow**. 3. In the **Featured Connectors** section, select **View More Connectors**. 4. Find a **gen 2** connector in the catalog. 5. Select a runtime to install the connector to. The list is filtered based on the runtime size requirements needed to run the connector. 6. Select **Install**. 7. Complete the wizard steps. The specific steps vary depending on the connector you selected. Documentation for every step is present within the wizard. 8. Upon completion, select **Create Connector**. 9. You're redirected to the **Installed Connectors** page. Once the connector has finished installing, select **Start** from the menu for your connector to start moving data. At any point during the wizard, you can select **Save and Close** to preserve your configuration changes without applying them to the connector. To apply your saved changes later, select **Edit** from the menu for that connector on the **Installed Connectors** tab, step through the wizard to the end, and select **Apply**. To create and configure the same connector types with SQL instead of the wizard, see [Configure a gen 2 connector with SQL](/user-guide/data-integration/openflow/gen2/configure-connector-sql). ## Edit an existing connector To edit a connector that you've already created, go to the **Installed Connectors** tab and select **Edit** from the menu for that connector. This reopens the setup wizard with your existing configuration. ## Input validation The wizard provides a button that allows you to validate your input at each step. Validation checks include: - **Connection tests**: The wizard attempts to connect to your data source using the provided credentials and displays the result. - **Permission checks**: The wizard verifies that the specified Snowflake user has the required privileges on the target database, schema, and table. - **Format validation**: The wizard checks that values such as hostnames, ports, and database names are in the expected format. If a validation check fails, the wizard highlights the field and displays a message explaining the issue. You can move to the next step even when intermediate validation fails; only the final validation before **Create Connector** (or **Apply**) must pass. ## Troubleshooting When you select **Verify** and validation fails, the wizard displays troubleshooting information directly in the UI explaining what went wrong and how to fix it. The panel on the right side of the wizard also contains detailed information about what is required for each property. ## Verify ingestion (dashboard, destination database, read-only canvas) After you **Start** the connector, confirm that data is flowing: - Use the [Openflow Connectors Dashboard](/user-guide/data-integration/openflow/connectors-dashboard) (**Ingestion** %raa% **Openflow** %raa% **Connector Observability**) for health, throughput, and errors. - In **Snowflake**, query the **destination database** (the tables or schemas the connector writes to) to verify that new rows or changes are arriving as you expect. - Open the **runtime canvas** to inspect processors, queues, FlowFiles, and bulletins for your connector's process group—a **read-only** operational view. From the dashboard, select **Go to canvas** for that connector; or open the canvas from **Runtimes** in Openflow. You **cannot** configure the connector on the canvas for setup wizard connector types; use **Installed Connectors** %raa% **Edit** or the connector API for any configuration changes. For starting and stopping ingestion, removal actions, and how the canvas compares to catalog-installed connectors, see [Manage the gen 2 Openflow connector lifecycle](/user-guide/data-integration/openflow/gen2/manage-connector-lifecycle). ## Next steps After you configure a connector with the wizard, you can: - [Manage the gen 2 connector lifecycle (start, stop, removal)](/user-guide/data-integration/openflow/gen2/manage-connector-lifecycle) - [Monitor connector health and performance](/user-guide/data-integration/openflow/connectors-dashboard) - [Manage your Openflow deployment](/user-guide/data-integration/openflow/manage) - [Troubleshoot Openflow issues](/user-guide/data-integration/openflow/troubleshoot) --- title: Configure a gen 2 connector with SQL source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/gen2/configure-connector-sql.md section: Loading & Unloading Data --- # Configure a gen 2 connector with SQL Available to all accounts. - [Second generation Openflow objects and interfaces](/user-guide/data-integration/openflow/gen2/index) - [Configure a connector with the setup wizard](/user-guide/data-integration/openflow/gen2/setup-connector-wizard) - [gen 2 connector configuration and versioning](/user-guide/data-integration/openflow/gen2/connector-versioning) - [CREATE OPENFLOW CONNECTOR](/sql-reference/sql/create-openflow-connector) - [Manage the gen 2 Openflow connector lifecycle](/user-guide/data-integration/openflow/gen2/manage-connector-lifecycle) This topic describes how to **create and configure** a gen 2 connector using SQL and stage commands—the programmatic alternative to the [Configure a connector with the setup wizard](/user-guide/data-integration/openflow/gen2/setup-connector-wizard). Use this workflow when you want to automate connector setup, manage configuration as code, or integrate with CI/CD. The same connector objects can also be managed from the Openflow UI; changes made in one interface are visible in the other. ## Prerequisites Before you begin: - A gen 2 **deployment** and **runtime**. See [Quickstart: gen 2 Openflow](/user-guide/data-integration/openflow/gen2/quickstart) if you need to create them. - `CREATE OPENFLOW CONNECTOR` on the schema and `USAGE` on the runtime. - Complete any connector-specific source database prerequisites first: [PostgreSQL CDC](/user-guide/data-integration/openflow/connectors/postgres/setup#source-database-setup) | [MySQL and MariaDB CDC](/user-guide/data-integration/openflow/connectors/mysql/setup#source-database-setup). For Snowflake account setup (destination database, warehouse, and secrets), follow the [Snowflake account setup](/user-guide/data-integration/openflow/connectors/postgres/setup#snowflake-account-setup) on those pages. - A client that supports `GET` and `PUT` on stages. Snowsight does **not** support `GET`/`PUT` on connector stages; use %sf-cli% or another supported client. For your first connector configuration, use the [Configure a connector with the setup wizard](/user-guide/data-integration/openflow/gen2/setup-connector-wizard). When you need a template for SQL or automation, create a draft with the wizard and download `config.json` from the live version (see [Upload and commit configuration](#label-openflow-configure-connector-sql-configure)). ## Create the connector The SQL examples in this topic assume you created a database and schema (see [Quickstart: gen 2 Openflow](/user-guide/data-integration/openflow/gen2/quickstart)) and set the session context: ```sql USE DATABASE my_db; USE SCHEMA my_schema; ``` Connectors and runtimes are schema-level objects; the examples below use simple names. `snow://` URI paths use the connector's fully qualified name. Create a connector in a gen 2 runtime from a catalog **definition ID**. Each gen 2 catalog entry maps to a definition ID—the value you pass to `FROM DEFINITION`. To find definition IDs available in your account: - Run `SHOW OPENFLOW CONNECTOR DEFINITIONS` (optionally with `LIKE` to filter). The `name` column is the definition ID. See [SHOW OPENFLOW CONNECTOR DEFINITIONS](/sql-reference/sql/show-openflow-connector-definitions). - Browse **gen 2** entries in the Openflow connector catalog (see [Configure a connector with the setup wizard](/user-guide/data-integration/openflow/gen2/setup-connector-wizard)). Example for PostgreSQL CDC: ```sql CREATE OPENFLOW CONNECTOR my_connector IN RUNTIME my_runtime FROM DEFINITION OPENFLOW_POSTGRES_CDC DISPLAY_NAME = 'My Postgres CDC Connector'; ``` The connector is created in **STOPPED** state with a **Draft** status: a **live** configuration version exists, but no committed **default** version yet. You must configure and commit before starting. See [gen 2 connector configuration and versioning](/user-guide/data-integration/openflow/gen2/connector-versioning). ## Upload and commit configuration Gen 2 connectors store configuration in `config.json` on the connector's [internal versioned stage](#label-openflow-fbe-versioned-stage). The standard workflow is download → edit → upload → commit. 1. List files in the live version: ```sql LS 'snow://openflow_connector/my_db.my_schema.my_connector/versions/live'; ``` 2. Download `config.json` to your local machine: ```sql GET 'snow://openflow_connector/my_db.my_schema.my_connector/versions/live/config.json' file:///path/to/local/; ``` Or with %sf-cli%: ```bash snow stage copy 'snow://openflow_connector/my_db.my_schema.my_connector/versions/live/config.json' . ``` 3. Edit `config.json` locally. Reference passwords and other secrets with `valueType = SECRET_REFERENCE` (see [Secrets in configuration](#label-openflow-configure-connector-sql-secrets)). 4. Upload the updated file to the live version: ```sql PUT 'file:///path/to/config.json' 'snow://openflow_connector/my_db.my_schema.my_connector/versions/live/config.json' AUTO_COMPRESS = FALSE OVERWRITE = TRUE; ``` 5. Commit the live version to create the default: ```sql ALTER OPENFLOW CONNECTOR my_connector COMMIT; SELECT SYSTEM$WAIT_FOR_STABLE_OPENFLOW_CONNECTORS(600, 'my_connector'); ``` For full details on live, default, and `LAST` versions, see [gen 2 connector configuration and versioning](/user-guide/data-integration/openflow/gen2/connector-versioning). ## Start the connector After configuration is committed: ```sql ALTER OPENFLOW CONNECTOR my_connector START; SELECT SYSTEM$WAIT_FOR_STABLE_OPENFLOW_CONNECTORS(600, 'my_connector'); ``` To stop or remove the connector, see [Manage the gen 2 Openflow connector lifecycle](/user-guide/data-integration/openflow/gen2/manage-connector-lifecycle). To monitor connector health and ingestion status, see [Monitor connectors using the Openflow Connectors Dashboard](/user-guide/data-integration/openflow/connectors-dashboard). ## Edit an existing connector To change configuration after a commit: 1. Create a new live version from the current default: ```sql ALTER OPENFLOW CONNECTOR my_connector ADD LIVE VERSION FROM LAST; ``` 2. Download, edit, and upload `config.json` as in [](#label-openflow-configure-connector-sql-configure). 3. Commit or abort: ```sql ALTER OPENFLOW CONNECTOR my_connector COMMIT; -- Or discard changes: ALTER OPENFLOW CONNECTOR my_connector ABORT; ``` ## Secrets in configuration Do not store passwords as plain text in `config.json`. Create a [Snowflake secret](/sql-reference/sql/create-secret) and reference it with `valueType = SECRET_REFERENCE`. Most connectors require secrets with `TYPE = GENERIC_STRING`. Check the setup topic for your connector to confirm the required type. The setup wizard generates the correct `SECRET_REFERENCE` structure for you. For SQL workflows, create a connector draft with the wizard, download `config.json` from the live version, and reuse that structure when you edit secrets and connection settings for additional connectors. Example `SECRET_REFERENCE` (PostgreSQL CDC): ```json "Source Database Password": { "valueType": "SECRET_REFERENCE", "fullyQualifiedSecretName": "openflow_db.openflow_schema.MY_SECRET" } ``` Grant **READ** on each referenced secret to the runtime's `EXECUTE_AS_ROLE`. The role also needs **USAGE** on the secret's database and schema. Grant these privileges before you start the connector. ## Create from a known configuration (optional) For your first connector, use `FROM DEFINITION` (above) or the setup wizard. When you already have a validated `config.json` and want to stand up another connector with the same settings—for example in a different runtime or environment—see [Create from a known configuration](#label-openflow-fbe-git-create) in [gen 2 connector configuration and versioning](/user-guide/data-integration/openflow/gen2/connector-versioning). ## Wizard vs SQL
Both approaches create the same gen 2 connector object and `config.json` format. ## Next steps - [CREATE OPENFLOW CONNECTOR](/sql-reference/sql/create-openflow-connector), [ALTER OPENFLOW CONNECTOR](/sql-reference/sql/alter-openflow-connector) — Full `CREATE` and `ALTER` syntax for connectors. - [gen 2 connector configuration and versioning](/user-guide/data-integration/openflow/gen2/connector-versioning) — Version states, UI labels, and [create from a known configuration](#label-openflow-fbe-git-create). - [Manage the gen 2 Openflow connector lifecycle](/user-guide/data-integration/openflow/gen2/manage-connector-lifecycle) — Start, stop, and remove gen 2 connectors. --- title: Configuring Avro data type ingestion source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/streaming/configuring-avro-data-type-ingestion.md section: Loading & Unloading Data --- This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [Snowflake Openflow Connector for Kafka](/user-guide/data-integration/openflow/connectors/kafka/about) - [Openflow Connector for Kinesis Data Streams](/user-guide/data-integration/openflow/connectors/kinesis/about) - [Configuring Protobuf data type ingestion](configuring-protobuf-data-type-ingestion) - [Configuring custom transformations](configuring-custom-transformations) - [Configuring Dead Letter Queue (DLQ) handling](configuring-dead-letter-queue-handling) # Configuring Avro data type ingestion The streaming connectors (Kafka high-performance, Kinesis high-performance) use a `Consume*` processor (`ConsumeKafka` / `ConsumeKinesis`) with a `JsonTreeReader` controller service to parse incoming messages. This topic describes how to switch to Avro-encoded messages by replacing `JsonTreeReader` with an `AvroReader`. The steps are identical for both connectors --- on a Kinesis connector, use the `ConsumeKinesis` processor where `ConsumeKafka` is referenced. You don't have to apply this customization by hand. The **Openflow skill in Snowflake CoCo** can perform it for you --- describe the change you want and it edits the flow following the steps on this page. We recommend using the skill instead of configuring the components manually. The following schema access strategies are supported: - **Inline schema text** --- you provide the Avro schema directly in the service configuration. - **Embedded Avro schema** --- the schema is read from the Avro container file header, no external configuration needed. - **Confluent Schema Registry** --- the schema ID is read from the message using `ConfluentEncodedSchemaReferenceReader` and resolved against a `ConfluentSchemaRegistry`. - **AWS Glue Schema Registry** --- schemas are looked up by name in the AWS Glue Schema Registry (`AmazonGlueSchemaRegistry`), commonly used by **Amazon MSK** customers. ## Prerequisites - You have an existing **Kafka high-performance** or **Kinesis high-performance** connector deployed in Openflow. - Your Kafka topics / Kinesis stream produce **Avro-encoded messages**. - If using Confluent Schema Registry: you have the registry URL and network access to it from the Openflow runtime. For Snowflake-managed deployments (SPCS), a proper [External Access Integration](/developer-guide/external-network-access/external-network-access-overview) must be configured and assigned to the runtime to allow outbound connections to the registry. ## Configure Avro data type ingestion The steps below apply identically to the **Kafka high-performance** and **Kinesis high-performance** connectors (on a Kinesis connector, use the `ConsumeKinesis` processor where `ConsumeKafka` is referenced). ### Step 1: Create the AvroReader controller service 1. Open the connector's process group in the Openflow UI. 2. Go to **Configure** > **Controller Services** (gear icon). 3. Select **+** to add a new controller service. 4. Search for and select `AvroReader` (`org.apache.nifi.avro.AvroReader`). 5. Select **Add**. The following properties are present on `AvroReader` regardless of the schema access strategy chosen in Step 2:
### Step 2: Configure the schema access strategy in AvroReader In the `AvroReader` controller service created in Step 1, configure the schema access strategy. Choose the option that matches how your Avro schema is distributed. #### Option A --- Inline schema text (Use 'Schema Text' Property) Use this when you have the Avro schema as a text string and it does not change at runtime. 1. Select the **Edit** (gear) icon on the `AvroReader` service. 2. Set the following properties:
3. Select **Apply**. #### Option B --- Embedded Avro schema (Use Embedded Avro Schema) Use this when messages are serialized as Avro Object Container Files (OCF), which include the writer schema in the file header. No additional services are required. 1. Select the **Edit** (gear) icon on the `AvroReader` service. 2. Set the following property:
3. Select **Apply**. This strategy only works with self-contained Avro container files. If your Kafka messages are raw Avro-encoded records without a file header (which is the common case for Kafka producers), use Option A or Option C instead. #### Option C --- Confluent Schema Registry (Schema Reference Reader) Use this when messages are encoded with the Confluent wire format (magic byte `0x00` followed by a 4-byte schema ID). Two additional controller services are required: `ConfluentSchemaRegistry` resolves the schema ID to an actual schema, and `ConfluentEncodedSchemaReferenceReader` reads the schema ID from each message. **Create the ConfluentSchemaRegistry controller service:** 1. Go to **Configure** > **Controller Services**. 2. Select **+** and search for `ConfluentSchemaRegistry` (`org.apache.nifi.confluent.schemaregistry.ConfluentSchemaRegistry`). 3. Select **Add**. 4. Select the **Edit** (gear) icon and set the following properties:
5. Select **Apply**. 6. Select the **Enable** (lightning bolt) icon and wait until the status shows **Enabled**. **Create the ConfluentEncodedSchemaReferenceReader controller service:** 1. Go to **Configure** > **Controller Services**. 2. Select **+** and search for `ConfluentEncodedSchemaReferenceReader` (`org.apache.nifi.confluent.schemaregistry.ConfluentEncodedSchemaReferenceReader`). 3. Select **Add**. 4. Select the **Enable** icon and wait until the status shows **Enabled**. `ConfluentEncodedSchemaReferenceReader` has no configurable properties. It simply reads the Confluent-encoded schema ID (magic byte `0x00` + 4-byte integer) from the beginning of each message. **Configure AvroReader to use the schema reference reader:** 1. Select the **Edit** (gear) icon on the `AvroReader` service created in Step 1. 2. Set the following properties:
3. Select **Apply**. #### Option D --- AWS Glue Schema Registry (Schema Name) Use this when an **Amazon MSK** producer registers Avro schemas in the AWS Glue Schema Registry. One additional controller service is required: `AmazonGlueSchemaRegistry` resolves schemas **by name**. **Create the AmazonGlueSchemaRegistry controller service:** 1. Go to **Configure** > **Controller Services**. 2. Select **+** and search for `AmazonGlueSchemaRegistry`. 3. Select **Add**. 4. Select the **Edit** (gear) icon and set the following properties:
5. Select **Apply**, then **Enable** the service. **Create the AmazonGlueEncodedSchemaReferenceReader controller service:** 1. Go to **Configure** > **Controller Services**. 2. Select **+** and search for `AmazonGlueEncodedSchemaReferenceReader`. 3. Select **Add**. 4. Select the **Enable** icon and wait until the status shows **Enabled**. `AmazonGlueEncodedSchemaReferenceReader` reads the AWS Glue schema reference (UUID and version number) embedded in each message by the Glue Schema Registry serializer. It has no configurable properties. **Configure AvroReader to use the schema reference reader:** 1. Select the **Edit** (gear) icon on the `AvroReader` service created in Step 1. 2. Set the following properties:
3. Select **Apply**. ### Step 3: Enable the AvroReader controller service Select the **Enable** (lightning bolt) icon on `AvroReader` and wait until its status shows **Enabled**. ### Step 4: Update the source processor 1. Double-click the `ConsumeKafka` processor (or `ConsumeKinesis` on a Kinesis connector) to open its properties. 2. Update the following property:
3. Select **Apply**. ### Step 5: Disable the JsonTreeReader controller service The original `JsonTreeReader` is no longer needed. 1. Stop the process group if it is running. 2. Go to **Configure** > **Controller Services**. 3. Select the **Disable** icon on `JsonTreeReader`. 4. If the service is not referenced by any other processor, you can also delete it by selecting the **Delete** (trash) icon. 5. Start the process group. ## Troubleshooting
--- title: Configuring custom transformations source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/streaming/configuring-custom-transformations.md section: Loading & Unloading Data --- This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [Snowflake Openflow Connector for Kafka](/user-guide/data-integration/openflow/connectors/kafka/about) - [Openflow Connector for Kinesis Data Streams](/user-guide/data-integration/openflow/connectors/kinesis/about) - [Configuring Avro data type ingestion](configuring-avro-data-type-ingestion) - [Configuring Protobuf data type ingestion](configuring-protobuf-data-type-ingestion) - [Configuring Dead Letter Queue (DLQ) handling](configuring-dead-letter-queue-handling) # Configuring custom transformations The streaming connectors (Kafka high-performance, Kinesis high-performance) consume messages with a `Consume*` processor and deliver them to Snowflake with `PublishSnowpipeStreaming`. By default the source connects directly to `PublishSnowpipeStreaming`. This topic describes how to insert **custom processing** between the source and the destination --- filtering, field mapping (flatten / rename / remove), topic-to-table mapping, content-based routing to multiple tables, default values, and custom Groovy scripts --- by adding a **Custom Transformations** process group in the Openflow UI. You apply this to an already-deployed streaming connector. If you don't have one yet, first set up the [Kafka](/user-guide/data-integration/openflow/connectors/kafka/setup) or [Kinesis](/user-guide/data-integration/openflow/connectors/kinesis/setup) connector. Streaming connectors use at-least-once (ALO) delivery. Custom processing sits directly in that path, so a set of **restriction rules** must be followed or you risk duplication, out-of-order delivery, or data loss (if records are explicitly dropped). Read [Restriction rules](#label-openflow-streaming-custom-transformations-restriction-rules) before adding any processor. You don't have to apply this customization by hand. The **Openflow skill in Snowflake CoCo** can perform it for you --- describe the change you want and it edits the flow following the steps on this page. We recommend using the skill instead of configuring the components manually. To get started, install and connect the [Snowflake CoCo CLI](/user-guide/cortex-code/cortex-code-cli), then ask the bundled [`openflow` skill](/user-guide/cortex-code/bundled-skills#label-bundled-skill-openflow) to make the change. For switching the message data type (JSON to Avro / Protobuf), see: - [Configuring Avro data type ingestion](configuring-avro-data-type-ingestion) - [Configuring Protobuf data type ingestion](configuring-protobuf-data-type-ingestion) For routing failed records to a dedicated destination instead of dropping them, see: - [Configuring Dead Letter Queue (DLQ) handling](configuring-dead-letter-queue-handling) ## Scope This topic customizes an **already-installed** streaming connector **in place** by adding a process group and processors in the Openflow UI and rewiring the source-to-destination path. What this topic covers: - Optionally inserting a **Custom Transformations** process group for readability (processors can also be added directly to the connector canvas). - The **restriction rules** for safe in-flight processing. - Reusing the connector's existing `JsonTreeReader` / `JsonRecordSetWriter` and adding a schema cache. - Planning a pipeline that minimizes serialization/deserialization (ser/de) passes. - Common transformation patterns and the processors that implement them. Out of scope --- broker authentication, data-type switching, and Snowflake Private Key Auth. See the [See also](#label-openflow-streaming-custom-transformations-see-also) links. ## Prerequisites - You have an existing **Kafka high-performance** or **Kinesis high-performance** connector deployed in Openflow. - The connector currently connects its source processor (for example, `ConsumeKafka`) directly to `PublishSnowpipeStreaming`. - You know which transformation you need and to which table(s) records should be written. - The execute-as role can create any target tables used for routing (see the connector's destination grants). ## Architecture Insert the transformation processors between the source processor and `PublishSnowpipeStreaming` --- that is, remove the direct source to `PublishSnowpipeStreaming` connection and chain your processors in between. The Custom Transformations process group is optional. You can add the transformation processors directly onto the connector's canvas, between the source processor and `PublishSnowpipeStreaming`. Grouping them inside a dedicated process group named **Custom Transformations** (with an Input Port and an Output Port) is purely for **readability and maintainability** --- it visually separates your customizations from the connector's built-in components and makes them easy to find, label, and reason about. It changes nothing functionally: the same processors, restriction rules, FIFO connections, and reader/writer apply either way. The rest of this topic describes the grouped layout. If you skip the group, ignore the Input/Output Port steps and connect the source processor directly to your first transformation processor and your last one directly to `PublishSnowpipeStreaming`. The recommended (grouped) layout. An **Input Port** receives messages from the source, transformation processors run inside the group, and an **Output Port** feeds the result to `PublishSnowpipeStreaming`: ```text ConsumeKafka (or ConsumeKinesis) | (success) v [Custom Transformations Input] <- Input Port | ... transformation processors ... | [Custom Transformations Output] <- Output Port | v PublishSnowpipeStreaming ``` ### Step 1: Create the process group (optional) This step (and Step 2) is only needed if you want the grouped layout. To add processors directly onto the connector canvas instead, do Step 1.1--1.2 below, then skip to [Step 3](#label-openflow-streaming-custom-transformations-wire) and connect the source processor straight to your first transformation processor. 1. Open the connector's process group in the Openflow UI. 2. Remove the existing connection between the source processor and `PublishSnowpipeStreaming`. 3. Drag a new **Process Group** onto the canvas and name it `Custom Transformations`. ### Step 2: Add the input and output ports (optional) Only if you created the process group in Step 1. Inside the `Custom Transformations` group: 1. Add an **Input Port** named `Custom Transformations Input`. 2. Add an **Output Port** named `Custom Transformations Output`. ### Step 3: Wire the processing into the flow 1. Connect the source processor's `success` relationship to `Custom Transformations Input` (or directly to your first transformation processor if you skipped the group). 2. Connect `Custom Transformations Output` to `PublishSnowpipeStreaming` (or your last transformation processor to `PublishSnowpipeStreaming` if you skipped the group). 3. Configure **every** connection (both these external connections and all internal connections you add later) with the **FirstInFirstOut** prioritizer. See [Connection configuration](#label-openflow-streaming-custom-transformations-connection-config). ## Restriction rules These rules MUST be followed. Violating them might cause data loss, duplication, or performance degradation. 1. **Minimize ser/de operations.** Plan the full pipeline *before* creating processors. Combine filtering, renaming, and defaults into as few record-aware processors as possible. Extract useful values (for example, routing fields) as attributes early so downstream steps can use attribute-only processors (`RouteOnAttribute`, `UpdateAttribute`) instead of content-aware ones. 2. **Reuse the existing reader/writer where possible.** The connector already defines a `JsonTreeReader` (schema inference) and a `JsonRecordSetWriter` at the parent process-group level, and these are visible to your processors. When a processor reads or writes content of the same data type, prefer reusing these existing services rather than creating new ones --- it keeps the flow simple and consistent. See [Reader and writer setup](#label-openflow-streaming-custom-transformations-reader-writer). 3. **One table per FlowFile.** A single FlowFile can contain records for only ONE table. Prefer `RouteOnAttribute` over `PartitionRecord` when the routing value is already available as an attribute (it saves a ser/de pass). 4. **Use FIFO prioritizers on connections.** Apply the **FirstInFirstOut** prioritizer on ALL connections (internal and external). This keeps records in arrival order within each partition and avoids unexpected interleaving. It does not affect throughput. 5. **No array exploding to the same table.** Exploding an array into multiple records destined for the *same* table is NOT allowed (it can cause data loss or duplicates). Array exploding is valid only when the resulting records route to *different* tables. 6. **Let schema inference handle structure.** With the existing `JsonTreeReader` (plus a `VolatileSchemaCache`) and `JsonRecordSetWriter`, structural changes are handled automatically --- you do not need to define schemas manually. ## Reader and writer setup Transformation processors that access FlowFile content need a Record Reader and Record Writer. The connector already defines a `JsonTreeReader` and a `JsonRecordSetWriter` at the parent process-group level, and these are visible inside the `Custom Transformations` group. When a processor works with the same data type, prefer reusing these existing services rather than creating new ones. ### Add a schema cache to the reader (recommended) The existing `JsonTreeReader` uses schema inference. To avoid re-inferring the schema on every FlowFile, add a `VolatileSchemaCache` and point the reader at it. 1. At the **connector** process-group level, go to **Configure** > **Controller Services**. 2. Add a `VolatileSchemaCache` service.
3. **Enable** the `VolatileSchemaCache` service. 4. **Disable** the `JsonTreeReader` (required before editing it). 5. Edit `JsonTreeReader` and set:
6. **Enable** the `JsonTreeReader` again. This caches the inferred schema and reuses it for messages with the same structure, improving performance. ## Transformation planning **Plan the full pipeline before creating any processor** (rule 1). The goal is the fewest possible ser/de passes. Building processors one-by-one without a plan almost always produces a wasteful pipeline. ### Planning checklist 1. **List every required transformation** (filter, rename, defaults, routing, and so on). 2. **Identify which can run on attributes alone** (zero ser/de). Attribute-only processors work only when the FlowFile already carries the attribute (for example, `kafka.topic` set by `ConsumeKafka`, `aws.kinesis.stream.name` set by `ConsumeKinesis`, or an attribute set by an upstream `PartitionRecord`): - Routing by source (topic / stream) or by an existing attribute → `UpdateAttribute` to derive a target table name into an attribute (for example, `table.name`), which `PublishSnowpipeStreaming` then reads to pick the destination table. This is explained in detail under [Topic-to-table mapping](#label-openflow-streaming-custom-transformations-topic-to-table) and [Content-based routing to multiple tables](#label-openflow-streaming-custom-transformations-content-routing). - Attribute-based filtering → `RouteOnAttribute`. 3. **Combine content transformations** into the fewest content-aware processors: - Filter + rename + defaults → ONE `QueryRecord` (SQL `SELECT` aliases, `COALESCE`, `WHERE`) or ONE `JoltTransformRecord` (Chain spec). 4. **Use `PartitionRecord` for multi-table routing.** A FlowFile may contain many records with *different* values for a routing field. Partitioning splits the FlowFile so each output FlowFile holds records for one value only, and sets that value as a FlowFile attribute. 5. **Order operations:** content transforms first (one pass on the whole FlowFile) → partition (split into per-value FlowFiles) → `UpdateAttribute` to set a target table-name attribute from the partitioned value (zero ser/de --- `PublishSnowpipeStreaming` uses this attribute to choose the destination table) → `RouteOnAttribute` only if filtering is needed (zero ser/de). The table-name attribute is explained under [Content-based routing to multiple tables](#label-openflow-streaming-custom-transformations-content-routing). ### Choosing between readable and optimized pipelines After planning the standard-processor pipeline, count its ser/de passes: - **1 pass** --- nothing to optimize, so implement it. - **2 or more passes** --- a single `ExecuteGroovyScript` could consolidate all content operations into 1 pass. Weigh maintainability (standard processors are easier to read and modify) against performance (one Groovy script can be faster for performance-critical workloads — confirm assumptions with testing before optimizing — but is harder to change). Choose the readable option unless you specifically need maximum performance. **Example --- "filter by timestamp, rename fields, add defaults, route to tables by field value":** Readable (2 ser/de passes): ```text Input Port -> QueryRecord (ser/de #1: rename via SELECT aliases, defaults via COALESCE, filter via WHERE) -> PartitionRecord (ser/de #2: split by routing field -> sets attribute) -> UpdateAttribute (zero ser/de: table.name = ${routing-field}) -> RouteOnAttribute (zero ser/de: drop unwanted values, auto-terminate unmatched) -> Output Port ``` Optimized (1 ser/de pass): ```text Input Port -> ExecuteGroovyScript (ser/de #1: rename + defaults + filter + partition by routing field) -> UpdateAttribute (zero ser/de: table.name = ${routing-field}) -> RouteOnAttribute (zero ser/de: drop unwanted values) -> Output Port ``` `PublishSnowpipeStreaming` handles multi-table routing natively --- set its **Table** property to `${table.name}` (or the routing attribute directly). `RouteOnAttribute` is only for *filtering*, never required for routing alone. **Anti-pattern (avoid):** separate processors for each of filter / rename / partition (3 ser/de passes where 2 suffice), or a separate `UpdateAttribute` per route value. Combine where possible, and use a single `UpdateAttribute` driven by the partitioned attribute. ## Connection configuration **Every** connection --- both into/out of the `Custom Transformations` group and between processors inside it --- MUST be configured with: 1. **FirstInFirstOut prioritizer** --- keeps records in arrival order within each partition (rule 4). 2. **Back pressure** --- leave at defaults unless you have a specific reason to change it. To set the prioritizer: edit the connection, open the **Settings** tab, and add **FirstInFirstOutPrioritizer** under **Prioritizers**. This applies to: - Source processor to `Custom Transformations Input` - `Custom Transformations Output` to `PublishSnowpipeStreaming` - All connections between processors inside the group **Connection queue before `PublishSnowpipeStreaming`:** Set the connection queue size limit to **5 GB** (not the default 1 GB). `PublishSnowpipeStreaming` keeps FlowFiles queued until they are acknowledged by Snowflake; with the default 1 GB limit, backpressure activates too early under normal load. ## Transformation patterns Pick the pattern that matches your need. All patterns assume the reader/writer setup above and obey the restriction rules. ### Pattern: Filtering messages **By attribute / key (no ser/de --- preferred).** Use `RouteOnAttribute`. It reads only FlowFile attributes, so there is no content-parsing cost. 1. Add a `RouteOnAttribute` processor. 2. Add dynamic properties whose values are Expression Language conditions. Each becomes a relationship. 3. Connect the desired relationship to the next step. Connect `unmatched` to auto-terminate (to drop) or to the Output Port (to keep). **By content (requires ser/de).** Use `QueryRecord` with a SQL `WHERE` clause.
Route the `filtered` relationship to the next step, and auto-terminate `original`. ### Pattern: Mapping / field transformations Use `JoltTransformRecord` (record-aware) for flatten / rename / remove / default operations.
Combine operations in one Chain spec to keep it to a single ser/de pass: ```json [ {"operation": "default", "spec": {"fieldName": "defaultValue"}}, {"operation": "shift", "spec": {"oldName": "newName", "*": "&"}}, {"operation": "remove", "spec": {"unwantedField": ""}} ] ``` **Use `JoltTransformRecord`, not `JoltTransformJSON`.** `JoltTransformRecord` is record-aware and processes NDJSON correctly using the configured RecordReader/RecordWriter. **Do NOT use `JoltTransformJSON`** --- it treats the entire FlowFile as a single JSON document and fails with NDJSON input. For simpler operations (add/rename/remove fields, set defaults), `UpdateRecord` with RecordPath expressions is a straightforward alternative to Jolt spec syntax. For content-based filtering, `QueryRecord` (SQL `WHERE`) is the alternative. ### Pattern: Topic-to-table mapping Route messages to different Snowflake tables based on the Kafka topic (or, for Kinesis, the source stream). `ConsumeKafka` sets the `kafka.topic` attribute automatically, and `ConsumeKinesis` sets `aws.kinesis.stream.name`, so this is attribute-only (no ser/de). The steps below use `kafka.topic` --- for Kinesis, substitute `aws.kinesis.stream.name`. 1. Add an `UpdateAttribute` processor with a dynamic property:
2. Add a `Topic To Table Map` parameter to the connector's parameter context. Format: `topic:table` pairs separated by commas. Table names must be valid unquoted Snowflake identifiers. Regex patterns must map a topic to a single table. If empty or no match, the topic name is used as the table name. - Explicit: `topic1:low_range,topic2:low_range,topic5:high_range` - Regex: `topic[0-4]:low_range,topic[5-9]:high_range` 3. Update `PublishSnowpipeStreaming`:
### Pattern: Default values for null / empty fields Use `JoltTransformRecord` with a `default` operation (preferably combined into the Chain spec above), or `UpdateRecord` with RecordPath:
### Pattern: Content-based routing to multiple tables Route records to different tables based on a field value in the message content. **A single FlowFile can contain records with different routing-field values, so `PartitionRecord` is always required** --- there is no shortcut. **Step 1 --- `PartitionRecord`** splits by the routing field and sets the value as a FlowFile attribute:
**Step 2 (optional) --- `UpdateAttribute`** to map the attribute to a table name, only if they differ:
If the attribute value *is* the table name, skip this and point `PublishSnowpipeStreaming` directly at the attribute. **Step 3 (optional) --- `RouteOnAttribute`** only if you must drop unwanted values:
Records that satisfy the expression flow to the `matched` relationship; connect it to the Output Port. Everything else falls to the built-in `unmatched` relationship --- auto-terminate it to drop those records. **Step 4 --- `PublishSnowpipeStreaming`:** set **Table** = `${table.name}` (or the routing attribute directly). `PublishSnowpipeStreaming` writes each FlowFile to whatever table the attribute resolves to. **Dynamic database and schema too.** `PublishSnowpipeStreaming` supports Expression Language (FlowFile attributes) on its **Database**, **Schema**, **Table**, and **Pipe** properties --- not just **Table**. So you can route to a fully dynamic destination by setting, for example, **Database** = `${target.db}`, **Schema** = `${target.schema}`, and **Table** = `${table.name}`, where each attribute is set upstream by `UpdateAttribute` / `PartitionRecord`. Each evaluates per FlowFile, so a single processor can fan out across databases, schemas, and tables.
Set FIFO on all connections. ### Pattern: Custom Groovy script (catch-all) Use `ExecuteGroovyScript` for anything that does not fit the patterns above. All restriction rules still apply: FIFO on connections, one table per output FlowFile, and preserved ordering. **Preserve original attributes.** The script MUST NOT remove or overwrite incoming attributes. For Kafka these include `kafka.topic` and `kafka.partition`. For Kinesis these include `aws.kinesis.stream.name` and `aws.kinesis.shard.id`. These are used in `PublishSnowpipeStreaming` channel names and must be preserved — the connectors provide at-least-once delivery and do not track offsets. When emitting output FlowFiles, always inherit attributes from the incoming FlowFile. Validate the script against edge cases (nulls, missing fields, type mismatches) before enabling the flow. ## Combining transformations Chain multiple processors inside the group: ```text Input Port -> Processor A -> Processor B -> ... -> Output Port ``` - **Order:** place attribute-only processors (no ser/de) *before* content-aware ones, so unwanted data is dropped early and costly ser/de runs only on records that will actually be written. - **Minimize ser/de:** combine content operations into a single processor where possible (one `QueryRecord` or one chained `JoltTransformRecord`). Keep `PartitionRecord` separate --- it changes FlowFile boundaries. - **Connections:** FIFO on all. Route failures to auto-terminate or a dead-letter output. ## Parameterization After wiring the transformations, move suitable hardcoded values into the connector's parameter context so the flow can be reconfigured without editing processors. Good candidates: connection strings / URLs, topic-to-table mappings, credentials, thresholds and constants. Not suitable (keep inline): Groovy scripts, Jolt specs, filter/routing conditions, large schema definitions. ## Verification After creating all processors, wiring all connections, and updating `PublishSnowpipeStreaming`: 1. **Enable all controller services first.** Processors that reference a disabled service show as INVALID, so enable every service before validating. 2. Validate the process group and resolve any validation failures. 3. Confirm `PublishSnowpipeStreaming` references the correct **Table** value (for example, `${table.name}`). 4. Start the flow. ## Troubleshooting
## See also - [Configuring Avro data type ingestion](configuring-avro-data-type-ingestion) --- JSON to Avro switching - [Configuring Protobuf data type ingestion](configuring-protobuf-data-type-ingestion) --- JSON to Protobuf switching - [Configuring Dead Letter Queue (DLQ) handling](configuring-dead-letter-queue-handling) --- routing failed records to a destination --- title: Configuring Dead Letter Queue (DLQ) handling source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/streaming/configuring-dead-letter-queue-handling.md section: Loading & Unloading Data --- This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [Snowflake Openflow Connector for Kafka](/user-guide/data-integration/openflow/connectors/kafka/about) - [Openflow Connector for Kinesis Data Streams](/user-guide/data-integration/openflow/connectors/kinesis/about) - [Configuring DLQ handling for Kafka](/user-guide/data-integration/openflow/connectors/kafka/configuring-dead-letter-queue-handling) - [Configuring DLQ handling for Kinesis](/user-guide/data-integration/openflow/connectors/kinesis/configuring-dead-letter-queue-handling) - [Configuring custom transformations](configuring-custom-transformations) # Configuring Dead Letter Queue (DLQ) handling The streaming connectors (Kafka high-performance, Kinesis high-performance) consume messages with a `Consume*` processor and deliver them to Snowflake with `PublishSnowpipeStreaming`. Failures occur on two sides: - **Client-side (Openflow) failures** --- records that fail to parse or transform before they reach Snowflake. By default these are **dropped** (the parse-failure relationship is auto-terminated), so they are silently lost unless you add DLQ handling. This topic describes the **common** building blocks for routing those failed records to a dedicated destination instead. - **Server-side (Snowpipe Streaming) failures** --- records that reach Snowflake but can't be ingested, for example, due to a schema mismatch. These are persisted in a server-side error table when error tables are enabled --- see [Snowpipe Streaming error tables](/user-guide/snowpipe-streaming/snowpipe-streaming-error-tables). Note that error tables are **not enabled by default**, so without them these failures are silently discarded. The DLQ handling described here is for the client-side failures only. You don't have to apply this customization by hand. The **Openflow skill in Snowflake CoCo** can perform it for you --- describe the change you want and it edits the flow following the steps on this page. We recommend using the skill instead of configuring the components manually. This is the shared reference. For the connector-specific pieces --- the source processor and configuring a Kafka topic or Kinesis stream as the DLQ destination --- see: - [Kafka as destination for DLQ messages](/user-guide/data-integration/openflow/connectors/kafka/configuring-dead-letter-queue-handling) - [Kinesis as destination for DLQ messages](/user-guide/data-integration/openflow/connectors/kinesis/configuring-dead-letter-queue-handling) A DLQ can send failed records to one of two destinations: - **Kafka topic / Kinesis stream** --- republish the failed payload **as-is, with no envelope**, to a messaging destination. Connector-specific --- see [Route A for Kafka](/user-guide/data-integration/openflow/connectors/kafka/configuring-dead-letter-queue-handling#label-openflow-kafka-dlq-route-a) / [Route A for Kinesis](/user-guide/data-integration/openflow/connectors/kinesis/configuring-dead-letter-queue-handling#label-openflow-kinesis-dlq-route-a). - **Snowflake table** --- wrap failures in the JSON envelope and insert them into a dedicated DLQ table (common --- see [Route B](#label-openflow-streaming-dlq-route-b)). For the **Snowflake-table route**, each failed record is wrapped in a uniform JSON envelope so it can be queried as table columns. The **messaging-destination route does not wrap anything** --- it republishes the original failed payload as-is (a Kafka/Kinesis consumer wants the original bytes), so the envelope below applies to Route B only. The fields are a **suggested** structure --- you can add, remove, or rename fields to fit your own needs. If you change the envelope, keep the DLQ table schema (see [Route B](#label-openflow-streaming-dlq-route-b)) and the metadata fields in the raw/structured branches consistent with it.
## Scope This topic customizes an **already-installed** streaming connector **in place** by adding components in the Openflow UI and rewiring failure relationships. **DLQ complexity scales with what the connector contains:** - A **vanilla / unmodified** connector has only one failure source --- the `Consume*` **parse failure** relationship. For these, build a **raw-only DLQ**: capture the unparseable bytes as a `raw_payload` string. No structured handling is needed. - If the connector has **custom processors** or a **Custom Transformations** process group, those can emit *structured* (valid-JSON) failures. Only then should you add the optional `structured_payload` branch. **Out of scope --- the main `PublishSnowpipeStreaming` (PSS) delivery failures.** PSS retries delivery and Snowflake persists rows it can't ingest in a server-side error table (when enabled) --- see [Snowpipe Streaming error tables](/user-guide/snowpipe-streaming/snowpipe-streaming-error-tables). Do **not** wire the main PSS `failure` or `invalid` relationships into the DLQ. Leave them as the connector ships them. The `failure` relationship covers communication errors; the `invalid` relationship routes FlowFiles where at least one record turned out to be invalid. **Exception.** If you specifically want **all** errors --- including PSS delivery failures --- to land in the same DLQ table, you can wire the main PSS `failure` relationship into the DLQ as well. This is not recommended: it duplicates what the server-side error table already captures and adds load to the flow. Use it only when a single, unified error destination is a hard requirement. ## Prerequisites - You have an existing **Kafka high-performance** or **Kinesis high-performance** connector deployed in Openflow. - You know where failed records should go (a Kafka topic / Kinesis stream, or a Snowflake table). - For a **Snowflake table** destination: the execute-as role can insert data into the target table (see [Grants](#label-openflow-streaming-dlq-grants)). - For a **messaging destination** (Kafka topic / Kinesis stream): follow the connector-specific page. ## Error sources
**The raw-vs-structured choice only applies to the Snowflake-table route** --- `structured_payload` is a table column. The stream route publishes the envelope content regardless. The parse-failure relationship name is connector-specific: `parse failure` (Kafka, with a space) vs `parse.failure` (Kinesis, with a dot). See the connector page for the exact name. ## Common setup Set up the shared building blocks below first --- the DLQ table, grants, capture branches, funnels, and sink failure handling. Then pick a destination route: [Route A](#label-openflow-streaming-dlq-route-a) (Kafka topic / Kinesis stream) or [Route B](#label-openflow-streaming-dlq-route-b) (Snowflake table). The Snowflake-table route uses all of these components; the messaging route reuses only the failure wiring --- it publishes the original payload as-is, with no table or envelope. ### Table setup Decide where the DLQ table lives --- the **same** database and schema as the main destination (the default, reusing the existing `Snowflake Destination Database` / `Snowflake Destination Schema` parameters), or a **different** one. Create the table (adjust the database/schema to your choice): ```sql CREATE TABLE pipeline_dlq ( error_message VARCHAR, failure_timestamp TIMESTAMP_NTZ, raw_payload VARCHAR, structured_payload VARIANT ); ``` **Keep this full schema even for a raw-only DLQ** --- `structured_payload` simply stays null. That way, adding structured handling later requires no table change. ### Grants The execute-as role needs the following grants: ```sql GRANT USAGE ON DATABASE TO ROLE OPENFLOW__EXECUTE_AS_RL; GRANT USAGE ON SCHEMA . TO ROLE OPENFLOW__EXECUTE_AS_RL; GRANT INSERT ON TABLE ..
Column name Type Description
`_SNOWFLAKE_INSERTED_AT` TIMESTAMP_NTZ The timestamp when the row was originally inserted into the destination table.
`_SNOWFLAKE_UPDATED_AT` TIMESTAMP_NTZ The timestamp when the row was last updated in the destination table.
`_SNOWFLAKE_DELETED` BOOLEAN Indicates whether the row was deleted from the source table. When `true`, the row has been soft-deleted and no longer exists in the source.
Column name Type Description
`_SNOWFLAKE_INSERTED_AT` TIMESTAMP_NTZ The timestamp when the row was originally inserted into the destination table.
`_SNOWFLAKE_UPDATED_AT` TIMESTAMP_NTZ The timestamp when the row was last updated in the destination table.
`_SNOWFLAKE_DELETED` BOOLEAN Indicates whether the row was deleted from the source table. When `true`, the row has been soft-deleted and no longer exists in the source.
User persona Task
AWS cloud engineer/administrator Creates a set of deployments in their AWS cloud account. The Openflow UI is used to manage deployments and runtime creation and maintenance. The Openflow UI allows users to create, upgrade, and delete runtimes in all deployments. Snowflake sign-ins are used to authenticate to Openflow, and roles and privileges are used to control access to Openflow deployments and runtimes.
Data engineer (pipeline author, responsible for data ingestion) Uses the runtime canvas to build completely new flows or to configure deployed connectors. Creates a completely new flow or uses an existing connector as-is or as a starting point to customize. Populates data in the bronze layer within your Snowflake account (or other target system). Connectors are a simple way to solve for a specific integration use case, and less technical users can deploy them without necessarily needing a data engineer.
Data engineer (pipeline operator) Configures the flow parameters and runs the flow.
Data engineer (responsible for transformation to silver and gold layers) Responsible for transforming data from the bronze layer that was populated by the pipeline to silver and gold layers for analytics.
Business user Makes use of gold layer objects for analytics.
Order Task Description Persona
1 [Set up the Salesforce Data Cloud Zerocopy Connector](/user-guide/data-integration/zero-copy/salesforce/setup) Create the Zerocopy Connector in Snowflake and retrieve the Enrollment ID to provide to your Salesforce administrator. Snowflake account administrator
2 [Set up Salesforce Data Cloud for Zero-Copy](/user-guide/data-integration/zero-copy/salesforce/setup-salesforce) Create a Data Share Target in Salesforce Data Cloud using the Enrollment ID to authorize the connection, then link existing or new Data Shares to the Data Share Target. Salesforce administrator
3 [Salesforce Data Cloud Zerocopy Connector: Security and privileges](/user-guide/data-integration/zero-copy/salesforce/security) Review security requirements and privileges required for Snowflake management of the Zerocopy Connector. Snowflake account administrator
4 [Explore data products from Salesforce Data Cloud](/user-guide/data-integration/zero-copy/salesforce/explore-data-products) Explore data products shared from Salesforce Data Cloud to Snowflake, create catalog-linked databases, and query the data. Snowflake account administrator and data engineer
BigQuery Data Type Snowflake Data Type
BIGNUMERIC NUMBER
NUMERIC NUMBER
GEOGRAPHY VARCHAR
DATETIME TIMESTAMP_NTZ
JSON OBJECT
STRUCT OBJECT
RANGE OBJECT
INTERVAL OBJECT
TIMESTAMP TIMESTAMP_NTZ
DATE DATE
TIME TIME
INT64 / INTEGER NUMBER
FLOAT64 FLOAT
BOOL / BOOLEAN BOOLEAN
STRING VARCHAR
BYTES BINARY
ARRAY ARRAY
Snowflake column Description
id ID of the MongoDB document
data The payload of the document
Item Example
ISU username `snowflake_ldq_user`
Client ID `YTg4YjRk...` (base64 string)
Token endpoint `https:///ccx/oauth2//token`
Private key file `private-key.pem` (RSA 2048, PEM format)
Workday host `impl-services1..myworkday.com`
Order Task Description Persona
1 [Set up Snowflake for Workday Live Data Query](/user-guide/data-integration/zero-copy/workday/snowflake-setup) Create the Snowflake objects required for LDQ: role, user, database, schema, stage, network rule, secret, and external access integration. Snowflake account administrator
2 [Connect to Workday and query data from Snowflake](/user-guide/data-integration/zero-copy/workday/connect-and-query) Create a Snowflake Notebook, install the Workday connector, configure credentials, and run your first queries against Workday data. Snowflake account administrator or data engineer
3 [Use Cortex Code with Workday data](/user-guide/data-integration/zero-copy/workday/cortex-code) Use Cortex Code to write queries, analyze results, and build visualizations on top of Workday data. Data engineer or analyst
Display Name API Name Default Value Allowable Values Description
Account Key * Account Key The storage account key. This is an admin-like password providing access to every container in this account. It is recommended one uses Shared Access Signature (SAS) token, Managed Identity or Service Principal instead for fine-grained control with policies. There are certain risks in allowing the account key to be stored as a FlowFile attribute. While it does provide for a more flexible flow by allowing the account key to be fetched dynamically from a FlowFile attribute, care must be taken to restrict access to the event provenance data (e.g., by strictly controlling the policies governing provenance for this processor). In addition, the provenance repositories may be put on encrypted disk partitions.
Credentials Type * Credentials Type SAS_TOKEN - Account Key - SAS Token - Managed Identity - Service Principal Credentials type to be used for authenticating to Azure
Endpoint Suffix * Endpoint Suffix dfs.core.windows.net Storage accounts in public Azure always use a common FQDN suffix. Override this endpoint suffix with a different suffix in certain circumstances (like Azure Stack or non-public Azure regions).
Managed Identity Client ID Managed Identity Client ID Client ID of the managed identity. The property is required when User Assigned Managed Identity is used for authentication. It must be empty in case of System Assigned Managed Identity.
SAS Token * SAS Token Shared Access Signature token (the leading '?' may be included) There are certain risks in allowing the SAS token to be stored as a FlowFile attribute. While it does provide for a more flexible flow by allowing the SAS token to be fetched dynamically from a FlowFile attribute, care must be taken to restrict access to the event provenance data (e.g., by strictly controlling the policies governing provenance for this processor). In addition, the provenance repositories may be put on encrypted disk partitions.
Service Principal Client ID * Service Principal Client ID Client ID (or Application ID) of the Client/Application having the Service Principal.
Service Principal Client Secret * Service Principal Client Secret Password of the Client/Application.
Service Principal Tenant ID * Service Principal Tenant ID Tenant ID of the Azure Active Directory hosting the Service Principal.
Storage Account Name * Storage Account Name The storage account name. There are certain risks in allowing the account name to be stored as a FlowFile attribute. While it does provide for a more flexible flow by allowing the account name to be fetched dynamically from a FlowFile attribute, care must be taken to restrict access to the event provenance data (e.g., by strictly controlling the policies governing provenance for this processor). In addition, the provenance repositories may be put on encrypted disk partitions.
Proxy Configuration Service proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests. In case of SOCKS, it is not guaranteed that the selected SOCKS Version will be used by the processor.
Controller Description
[ADLSCredentialsControllerService](/user-guide/data-integration/openflow/controllers/adlscredentialscontrollerservice) Defines credentials for ADLS processors.
[ADLSCredentialsControllerServiceLookup](/user-guide/data-integration/openflow/controllers/adlscredentialscontrollerservicelookup) Provides an ADLSCredentialsService that can be used to dynamically select another ADLSCredentialsService.
[AmazonGlueEncodedSchemaReferenceReader](/user-guide/data-integration/openflow/controllers/amazonglueencodedschemareferencereader) Reads Schema Identifier according to AWS Glue Schema encoding as a header consisting of a two byte markers and a 16 byte UUID
[AmazonGlueSchemaRegistry](/user-guide/data-integration/openflow/controllers/amazonglueschemaregistry) Provides a Schema Registry that interacts with the AWS Glue Schema Registry so that those Schemas that are stored in the Glue Schema Registry can be used in NiFi.
[AmazonMSKConnectionService](/user-guide/data-integration/openflow/controllers/amazonmskconnectionservice) Provides and manages connections to AWS MSK Kafka Brokers for producer or consumer operations.
%logo-snowflake-blue% [AmazonMSKConnectionService](/user-guide/data-integration/openflow/controllers/amazonmskconnectionservice) Provides and manages connections to AWS MSK Kafka Brokers for producer or consumer operations.
[ApicurioSchemaRegistry](/user-guide/data-integration/openflow/controllers/apicurioschemaregistry) Provides a Schema Registry that interacts with the Apicurio Schema Registry so that those Schemas that are stored in the Apicurio Schema Registry can be used in NiFi.
[AvroReader](/user-guide/data-integration/openflow/controllers/avroreader) Parses Avro data and returns each Avro record as an separate Record object.
[AvroRecordSetWriter](/user-guide/data-integration/openflow/controllers/avrorecordsetwriter) Writes the contents of a RecordSet in Binary Avro format.
[AvroSchemaRegistry](/user-guide/data-integration/openflow/controllers/avroschemaregistry) Provides a service for registering and accessing schemas.
[AWSCredentialsProviderControllerService](/user-guide/data-integration/openflow/controllers/awscredentialsprovidercontrollerservice) Defines credentials for Amazon Web Services processors.
[AzureBlobStorageFileResourceService](/user-guide/data-integration/openflow/controllers/azureblobstoragefileresourceservice) Provides an Azure Blob Storage file resource for other components.
[AzureCosmosDBClientService](/user-guide/data-integration/openflow/controllers/azurecosmosdbclientservice) Provides a controller service that configures a connection to Cosmos DB (Core SQL API) and provides access to that connection to other Cosmos DB-related components.
[AzureDataLakeStorageFileResourceService](/user-guide/data-integration/openflow/controllers/azuredatalakestoragefileresourceservice) Provides an Azure Data Lake Storage (ADLS) file resource for other components.
[AzureEventHubRecordSink](/user-guide/data-integration/openflow/controllers/azureeventhubrecordsink) Format and send Records to Azure Event Hubs
[AzureStorageCredentialsControllerService_v12](/user-guide/data-integration/openflow/controllers/azurestoragecredentialscontrollerservice_v12) Provides credentials for Azure Storage processors using Azure Storage client library v12.
[AzureStorageCredentialsControllerServiceLookup_v12](/user-guide/data-integration/openflow/controllers/azurestoragecredentialscontrollerservicelookup_v12) Provides an AzureStorageCredentialsService_v12 that can be used to dynamically select another AzureStorageCredentialsService_v12.
Controller Description
[CEFReader](/user-guide/data-integration/openflow/controllers/cefreader) Parses CEF (Common Event Format) events, returning each row as a record.
[ConfluentEncodedSchemaReferenceReader](/user-guide/data-integration/openflow/controllers/confluentencodedschemareferencereader) Reads Schema Identifier according to Confluent encoding as a header consisting of a byte marker and an integer represented as four bytes
[ConfluentEncodedSchemaReferenceWriter](/user-guide/data-integration/openflow/controllers/confluentencodedschemareferencewriter) Writes Schema Identifier according to Confluent encoding as a header consisting of a byte marker and an integer represented as four bytes
[ConfluentProtobufMessageNameResolver](/user-guide/data-integration/openflow/controllers/confluentprotobufmessagenameresolver) Resolves Protobuf message names from Confluent Schema Registry wire format by decoding message indexes and looking up the fully qualified name in the schema definition For Confluent wire format reference see: https://docs (https://docs).
[ConfluentSchemaRegistry](/user-guide/data-integration/openflow/controllers/confluentschemaregistry) Provides a Schema Registry that interacts with the Confluent Schema Registry so that those Schemas that are stored in the Confluent Schema Registry can be used in NiFi.
[CSVReader](/user-guide/data-integration/openflow/controllers/csvreader) Parses CSV-formatted data, returning each row in the CSV file as a separate record.
[CSVRecordLookupService](/user-guide/data-integration/openflow/controllers/csvrecordlookupservice) A reloadable CSV file-based lookup service.
[CSVRecordSetWriter](/user-guide/data-integration/openflow/controllers/csvrecordsetwriter) Writes the contents of a RecordSet as CSV data.
Controller Description
%logo-snowflake-blue% [DatabaseLookup](/user-guide/data-integration/openflow/controllers/databaselookup) A Lookup Service that allows for enrichment with a database using a user-specified SQL statement.
[DatabaseRecordLookupService](/user-guide/data-integration/openflow/controllers/databaserecordlookupservice) A relational-database-based lookup service.
[DatabaseRecordSink](/user-guide/data-integration/openflow/controllers/databaserecordsink) Provides a service to write records using a configured database connection.
[DBCPConnectionPool](/user-guide/data-integration/openflow/controllers/dbcpconnectionpool) Provides Database Connection Pooling Service.
[DBCPConnectionPoolLookup](/user-guide/data-integration/openflow/controllers/dbcpconnectionpoollookup) Provides a DBCPService that can be used to dynamically select another DBCPService.
[DeveloperBoxClientService](/user-guide/data-integration/openflow/controllers/developerboxclientservice) Provides Box client objects through which Box API calls can be used.
[DistributedMapCacheLookupService](/user-guide/data-integration/openflow/controllers/distributedmapcachelookupservice) Lets you choose a distributed map cache client to retrieve the value associated to a key.
Controller Description
[ElasticSearchClientServiceImpl](/user-guide/data-integration/openflow/controllers/elasticsearchclientserviceimpl) A controller service for accessing an Elasticsearch client, using the Elasticsearch (low-level) REST Client.
[ElasticSearchLookupService](/user-guide/data-integration/openflow/controllers/elasticsearchlookupservice) Lookup a record from Elasticsearch Server associated with the specified document ID.
[ElasticSearchStringLookupService](/user-guide/data-integration/openflow/controllers/elasticsearchstringlookupservice) Lookup a string value from Elasticsearch Server associated with the specified document ID.
[EmailRecordSink](/user-guide/data-integration/openflow/controllers/emailrecordsink) Provides a RecordSinkService that can be used to send records in email using the specified writer for formatting.
[EmbeddedHazelcastCacheManager](/user-guide/data-integration/openflow/controllers/embeddedhazelcastcachemanager) A service that runs embedded Hazelcast and provides cache instances backed by that.
[ExcelReader](/user-guide/data-integration/openflow/controllers/excelreader) Parses a Microsoft Excel document returning each row in each sheet as a separate record.
[ExternalHazelcastCacheManager](/user-guide/data-integration/openflow/controllers/externalhazelcastcachemanager) A service that provides cache instances backed by Hazelcast running outside of NiFi.
Controller Description
[FreeFormTextRecordSetWriter](/user-guide/data-integration/openflow/controllers/freeformtextrecordsetwriter) Writes the contents of a RecordSet as free-form text.
Controller Description
[GCPCredentialsControllerService](/user-guide/data-integration/openflow/controllers/gcpcredentialscontrollerservice) Defines credentials for Google Cloud Platform processors.
[GCSFileResourceService](/user-guide/data-integration/openflow/controllers/gcsfileresourceservice) Provides a Google Compute Storage (GCS) file resource for other components.
[GrokReader](/user-guide/data-integration/openflow/controllers/grokreader) Provides a mechanism for reading unstructured text data, such as log files, and structuring the data so that it can be processed.
Controller Description
[HazelcastMapCacheClient](/user-guide/data-integration/openflow/controllers/hazelcastmapcacheclient) An implementation of DistributedMapCacheClient that uses Hazelcast as the backing cache.
[HikariCPConnectionPool](/user-guide/data-integration/openflow/controllers/hikaricpconnectionpool) Provides Database Connection Pooling Service based on HikariCP.
[HttpRecordSink](/user-guide/data-integration/openflow/controllers/httprecordsink) Format and send Records to a configured uri using HTTP post.
Controller Description
[IPLookupService](/user-guide/data-integration/openflow/controllers/iplookupservice) A lookup service that provides several types of enrichment information for IP addresses.
Controller Description
[JettyWebSocketClient](/user-guide/data-integration/openflow/controllers/jettywebsocketclient) Implementation of WebSocketClientService.
[JettyWebSocketServer](/user-guide/data-integration/openflow/controllers/jettywebsocketserver) Implementation of WebSocketServerService.
[JMSConnectionFactoryProvider](/user-guide/data-integration/openflow/controllers/jmsconnectionfactoryprovider) Provides a generic service to create vendor specific javax.
[JndiJmsConnectionFactoryProvider](/user-guide/data-integration/openflow/controllers/jndijmsconnectionfactoryprovider) Provides a service to lookup an existing JMS ConnectionFactory using the Java Naming and Directory Interface (JNDI).
[JsonConfigBasedBoxClientService](/user-guide/data-integration/openflow/controllers/jsonconfigbasedboxclientservice) Provides Box client objects through which Box API calls can be used.
[JsonPathReader](/user-guide/data-integration/openflow/controllers/jsonpathreader) Parses JSON records and evaluates user-defined JSON Path 's against each JSON object.
[JsonRecordSetWriter](/user-guide/data-integration/openflow/controllers/jsonrecordsetwriter) Writes the results of a RecordSet as either a JSON Array or one JSON object per line.
%logo-snowflake-blue% [JsonTableColumnFilter](/user-guide/data-integration/openflow/controllers/jsontablecolumnfilter) Provides a table column filter based on a JSON configuration.
[JsonTreeReader](/user-guide/data-integration/openflow/controllers/jsontreereader) Parses JSON into individual Record objects.
[JWTBearerOAuth2AccessTokenProvider](/user-guide/data-integration/openflow/controllers/jwtbeareroauth2accesstokenprovider) Provides OAuth 2.
Controller Description
[Kafka3ConnectionService](/user-guide/data-integration/openflow/controllers/kafka3connectionservice) Provides and manages connections to Kafka Brokers for producer or consumer operations.
%logo-snowflake-blue% [Kafka3ConnectionService](/user-guide/data-integration/openflow/controllers/kafka3connectionservice) Provides and manages connections to Kafka Brokers for producer or consumer operations.
Controller Description
[LoggingRecordSink](/user-guide/data-integration/openflow/controllers/loggingrecordsink) Provides a RecordSinkService that can be used to log records to the application log (nifi-app.
Controller Description
[MapCacheClientService](/user-guide/data-integration/openflow/controllers/mapcacheclientservice) Provides the ability to communicate with a MapCacheServer.
[MapCacheServer](/user-guide/data-integration/openflow/controllers/mapcacheserver) Provides a map (key/value) cache that can be accessed over a socket.
%logo-snowflake-blue% [MicrosoftClientCertificateOAuth2TokenProvider](/user-guide/data-integration/openflow/controllers/microsoftclientcertificateoauth2tokenprovider) Provides OAuth2 access tokens for the Microsoft Graph API using client_credentials with a client certificate.
%logo-snowflake-blue% [MicrosoftGraphAuthenticationProvider](/user-guide/data-integration/openflow/controllers/microsoftgraphauthenticationprovider) Provides authentication for the Microsoft Graph API, which can be used for interacting with Microsoft 365 services.
[MongoDBControllerService](/user-guide/data-integration/openflow/controllers/mongodbcontrollerservice) Provides a controller service that configures a connection to MongoDB and provides access to that connection to other Mongo-related components.
[MongoDBLookupService](/user-guide/data-integration/openflow/controllers/mongodblookupservice) Provides a lookup service based around MongoDB.
Controller Description
%logo-snowflake-blue% [ParquetIcebergWriter](/user-guide/data-integration/openflow/controllers/parqueticebergwriter) Provides record serialization for Apache Iceberg using Apache Parquet formatting
[PEMEncodedSSLContextProvider](/user-guide/data-integration/openflow/controllers/pemencodedsslcontextprovider) SSLContext Provider configurable using PEM Private Key and Certificate files.
%logo-snowflake-blue% [PolarisIcebergCatalog](/user-guide/data-integration/openflow/controllers/polarisicebergcatalog) Provides Apache Iceberg integration with Apache Polaris Catalog access over REST HTTP
[PropertiesFileLookupService](/user-guide/data-integration/openflow/controllers/propertiesfilelookupservice) A reloadable properties file-based lookup service
[ProtobufReader](/user-guide/data-integration/openflow/controllers/protobufreader) Parses a Protocol Buffers message from binary format.
Controller Description
[ReaderLookup](/user-guide/data-integration/openflow/controllers/readerlookup) Provides a RecordReaderFactory that can be used to dynamically select another RecordReaderFactory.
[RecordSetWriterLookup](/user-guide/data-integration/openflow/controllers/recordsetwriterlookup) Provides a RecordSetWriterFactory that can be used to dynamically select another RecordSetWriterFactory.
[RecordSinkServiceLookup](/user-guide/data-integration/openflow/controllers/recordsinkservicelookup) Provides a RecordSinkService that can be used to dynamically select another RecordSinkService.
[RedisConnectionPoolService](/user-guide/data-integration/openflow/controllers/redisconnectionpoolservice) A service that provides connections to Redis.
[RedisDistributedMapCacheClientService](/user-guide/data-integration/openflow/controllers/redisdistributedmapcacheclientservice) An implementation of DistributedMapCacheClient that uses Redis as the backing cache.
%logo-snowflake-blue% [RemoveFieldRecordReader](/user-guide/data-integration/openflow/controllers/removefieldrecordreader) A wrapper for a RecordReaderFactory that supports filtering out specified fields from NiFi Records.
[RestLookupService](/user-guide/data-integration/openflow/controllers/restlookupservice) Use a REST service to look up values.
Controller Description
[S3FileResourceService](/user-guide/data-integration/openflow/controllers/s3fileresourceservice) Provides an Amazon Web Services (AWS) S3 file resource for other components.
%logo-snowflake-blue% [SalesforceDataCloudOAuthTokenProvider](/user-guide/data-integration/openflow/controllers/salesforcedatacloudoauthtokenprovider) Retrieves an OAuth2 access token from Salesforce using the configured OAuth2 Access Token Provider and exchanges the token for a Data Cloud API token.
[ScriptedLookupService](/user-guide/data-integration/openflow/controllers/scriptedlookupservice) Allows the user to provide a scripted LookupService instance in order to enrich records from an incoming flow file.
[ScriptedReader](/user-guide/data-integration/openflow/controllers/scriptedreader) Allows the user to provide a scripted RecordReaderFactory instance in order to read/parse/generate records from an incoming flow file.
[ScriptedRecordSetWriter](/user-guide/data-integration/openflow/controllers/scriptedrecordsetwriter) Allows the user to provide a scripted RecordSetWriterFactory instance in order to write records to an outgoing flow file.
[ScriptedRecordSink](/user-guide/data-integration/openflow/controllers/scriptedrecordsink) Allows the user to provide a scripted RecordSinkService instance in order to transmit records to the desired target.
[SetCacheClientService](/user-guide/data-integration/openflow/controllers/setcacheclientservice) Provides the ability to communicate with a SetCacheServer.
[SetCacheServer](/user-guide/data-integration/openflow/controllers/setcacheserver) Provides a set (collection of unique values) cache that can be accessed over a socket.
[SimpleCsvFileLookupService](/user-guide/data-integration/openflow/controllers/simplecsvfilelookupservice) A reloadable CSV file-based lookup service.
[SimpleDatabaseLookupService](/user-guide/data-integration/openflow/controllers/simpledatabaselookupservice) A relational-database-based lookup service.
[SimpleKeyValueLookupService](/user-guide/data-integration/openflow/controllers/simplekeyvaluelookupservice) Allows users to add key/value pairs as User-defined Properties.
[SimpleRedisDistributedMapCacheClientService](/user-guide/data-integration/openflow/controllers/simpleredisdistributedmapcacheclientservice) An implementation of DistributedMapCacheClient that uses Redis as the backing cache.
[SimpleScriptedLookupService](/user-guide/data-integration/openflow/controllers/simplescriptedlookupservice) Allows the user to provide a scripted LookupService instance in order to enrich records from an incoming flow file.
[SlackRecordSink](/user-guide/data-integration/openflow/controllers/slackrecordsink) Format and send Records to a configured Channel using the Slack Post Message API.
[SmbjClientProviderService](/user-guide/data-integration/openflow/controllers/smbjclientproviderservice) Provides access to SMB Sessions with shared authentication credentials.
%logo-snowflake-blue% [SnowflakeConnectionService](/user-guide/data-integration/openflow/controllers/snowflakeconnectionservice) Provides pooled database connections to Snowflake services
%logo-snowflake-blue% [SnowflakeDatabaseDialectService](/user-guide/data-integration/openflow/controllers/snowflakedatabasedialectservice) Database Dialect Service supporting Snowflake.
%logo-snowflake-blue% [SnowflakeSignJWTService](/user-guide/data-integration/openflow/controllers/snowflakesignjwtservice) Provides OAuth2 access token using a JWT signed with a secret stored in Snowflake.
%logo-snowflake-blue% [SnowflakeTableSchemaRegistry](/user-guide/data-integration/openflow/controllers/snowflaketableschemaregistry) Uses Snowflake tables as the source of schema — utilises Snowpipe Streaming REST API.
%logo-snowflake-blue% [StandardAnthropicLLMService](/user-guide/data-integration/openflow/controllers/standardanthropicllmservice) A Controller Service that provides integration with Anthropic's Claude AI models through their Messages API.
%logo-snowflake-blue% [StandardAtlassianRequestRateManager](/user-guide/data-integration/openflow/controllers/standardatlassianrequestratemanager) Provides rate limiting coordination for Atlassian API calls across processors to prevent cascading rate limit issues.
[StandardAzureCredentialsControllerService](/user-guide/data-integration/openflow/controllers/standardazurecredentialscontrollerservice) Provide credentials to use with an Azure client.
%logo-snowflake-blue% [StandardConfluenceClientService](/user-guide/data-integration/openflow/controllers/standardconfluenceclientservice) Provides connection service to Confluence APIs
%logo-snowflake-blue% [StandardDatabricksWorkspaceClientService](/user-guide/data-integration/openflow/controllers/standarddatabricksworkspaceclientservice) Databricks client.
[StandardDropboxCredentialService](/user-guide/data-integration/openflow/controllers/standarddropboxcredentialservice) Defines credentials for Dropbox processors.
[StandardFileResourceService](/user-guide/data-integration/openflow/controllers/standardfileresourceservice) Provides a file resource for other components.
[StandardHashiCorpVaultClientService](/user-guide/data-integration/openflow/controllers/standardhashicorpvaultclientservice) A controller service for interacting with HashiCorp Vault.
[StandardHttpContextMap](/user-guide/data-integration/openflow/controllers/standardhttpcontextmap) Provides the ability to store and retrieve HTTP requests and responses external to a Processor, so that multiple Processors can interact with the same HTTP request.
%logo-snowflake-blue% [StandardHubSpotClientService](/user-guide/data-integration/openflow/controllers/standardhubspotclientservice) HubSpot Controller Service to integrate with HubSpot HTTP api.
[StandardJsonSchemaRegistry](/user-guide/data-integration/openflow/controllers/standardjsonschemaregistry) Provides a service for registering and accessing JSON schemas.
[StandardKustoIngestService](/user-guide/data-integration/openflow/controllers/standardkustoingestservice) Sends batches of flowfile content or stream flowfile content to an Azure ADX cluster.
[StandardKustoQueryService](/user-guide/data-integration/openflow/controllers/standardkustoqueryservice) Standard implementation of Kusto Query Service for Azure Data Explorer
%logo-snowflake-blue% [StandardMilvusConnectionService](/user-guide/data-integration/openflow/controllers/standardmilvusconnectionservice) Provides connection service to a Milvus instance
[StandardOauth2AccessTokenProvider](/user-guide/data-integration/openflow/controllers/standardoauth2accesstokenprovider) Provides OAuth 2.
%logo-snowflake-blue% [StandardOCRService](/user-guide/data-integration/openflow/controllers/standardocrservice) Provides integration to Openflow OCR Service
%logo-snowflake-blue% [StandardOpenAILLMService](/user-guide/data-integration/openflow/controllers/standardopenaillmservice) A Controller Service that provides integration with OpenAI's Chat Completion API.
[StandardPGPPrivateKeyService](/user-guide/data-integration/openflow/controllers/standardpgpprivatekeyservice) PGP Private Key Service provides Private Keys loaded from files or properties
[StandardPGPPublicKeyService](/user-guide/data-integration/openflow/controllers/standardpgppublickeyservice) PGP Public Key Service providing Public Keys loaded from files
[StandardPrivateKeyService](/user-guide/data-integration/openflow/controllers/standardprivatekeyservice) Private Key Service provides access to a Private Key loaded from configured sources
[StandardProtobufReader](/user-guide/data-integration/openflow/controllers/standardprotobufreader) Parses Protocol Buffers messages from binary format into NiFi Records.
[StandardProxyConfigurationService](/user-guide/data-integration/openflow/controllers/standardproxyconfigurationservice) Provides a set of configurations for different NiFi components to use a proxy server.
[StandardRestrictedSSLContextService](/user-guide/data-integration/openflow/controllers/standardrestrictedsslcontextservice) Restricted implementation of the SSLContextService.
[StandardS3EncryptionService](/user-guide/data-integration/openflow/controllers/standards3encryptionservice) Adds configurable encryption to S3 Put and S3 Fetch operations.
%logo-snowflake-blue% [StandardSalesforceBulkJobsStateService](/user-guide/data-integration/openflow/controllers/standardsalesforcebulkjobsstateservice) Stores Salesforce Bulk Jobs state per object type at cluster scope
%logo-snowflake-blue% [StandardSalesforceClientService](/user-guide/data-integration/openflow/controllers/standardsalesforceclientservice) Provides connection service to Salesforce APIs
%logo-snowflake-blue% [StandardSalesforceDataCloudClientService](/user-guide/data-integration/openflow/controllers/standardsalesforcedatacloudclientservice) Provides connection service to Salesforce Data Cloud APIs
%logo-snowflake-blue% [StandardSlackRateLimiterService](/user-guide/data-integration/openflow/controllers/standardslackratelimiterservice) Provides rate limiting coordination for Slack API calls across processors to prevent cascading rate limit issues
[StandardSSLContextService](/user-guide/data-integration/openflow/controllers/standardsslcontextservice) Standard implementation of the SSLContextService.
%logo-snowflake-blue% [StandardTableStateService](/user-guide/data-integration/openflow/controllers/standardtablestateservice) A controller Service that provides and manages table state.
%logo-snowflake-blue% [StandardVectaraClientService](/user-guide/data-integration/openflow/controllers/standardvectaraclientservice) Vectara Controller Service to integrate with Vectara HTTP Api.
[StandardWebClientServiceProvider](/user-guide/data-integration/openflow/controllers/standardwebclientserviceprovider) Web Client Service Provider with support for configuring standard HTTP connection properties
%logo-snowflake-blue% [StateManagedCdcSchemaRegistry](/user-guide/data-integration/openflow/controllers/statemanagedcdcschemaregistry) Uses the in-built NiFi State Management to store the hashes of table schemas.
[Syslog5424Reader](/user-guide/data-integration/openflow/controllers/syslog5424reader) Provides a mechanism for reading RFC 5424 compliant Syslog data, such as log files, and structuring the data so that it can be processed.
[SyslogReader](/user-guide/data-integration/openflow/controllers/syslogreader) Attempts to parses the contents of a Syslog message in accordance to RFC5424 and RFC3164.
Controller Description
[UDPEventRecordSink](/user-guide/data-integration/openflow/controllers/udpeventrecordsink) Format and send Records as UDP Datagram Packets to a configurable destination
Controller Description
[VolatileSchemaCache](/user-guide/data-integration/openflow/controllers/volatileschemacache) Provides a Schema Cache that evicts elements based on a Least-Recently-Used algorithm.
Controller Description
[WindowsEventLogReader](/user-guide/data-integration/openflow/controllers/windowseventlogreader) Reads Windows Event Log data as XML content having been generated by ConsumeWindowsEventLog, ParseEvtx, etc.
Controller Description
[XMLFileLookupService](/user-guide/data-integration/openflow/controllers/xmlfilelookupservice) A reloadable XML file-based lookup service.
[XMLReader](/user-guide/data-integration/openflow/controllers/xmlreader) Reads XML content and creates Record objects.
[XMLRecordSetWriter](/user-guide/data-integration/openflow/controllers/xmlrecordsetwriter) Writes a RecordSet to XML.
Controller Description
[YamlTreeReader](/user-guide/data-integration/openflow/controllers/yamltreereader) Parses YAML into individual Record objects.
Processor Description
%logo-snowflake-blue% [AbortQueryJob](/user-guide/data-integration/openflow/processors/abortqueryjob) Aborts a Query Job in Salesforce using the Bulk API 2.
[AttributesToCSV](/user-guide/data-integration/openflow/processors/attributestocsv) Generates a CSV representation of the input FlowFile Attributes.
[AttributesToJSON](/user-guide/data-integration/openflow/processors/attributestojson) Generates a JSON representation of the input FlowFile Attributes.
Processor Description
[CalculateRecordStats](/user-guide/data-integration/openflow/processors/calculaterecordstats) Counts the number of Records in a record set, optionally counting the number of elements per category, where the categories are defined by user-defined properties.
%logo-snowflake-blue% [CaptureChangeMySQL](/user-guide/data-integration/openflow/processors/capturechangemysql) Reads CDC events from a MySQL database.
%logo-snowflake-blue% [CaptureChangePostgreSQL](/user-guide/data-integration/openflow/processors/capturechangepostgresql) Reads CDC events from a PostgreSQL database.
%logo-snowflake-blue% [CaptureChangeSqlServer](/user-guide/data-integration/openflow/processors/capturechangesqlserver) Reads CDC events from a SQL Server database.
%logo-snowflake-blue% [CaptureGoogleDriveChanges](/user-guide/data-integration/openflow/processors/capturegoogledrivechanges) Captures changes to a Shared Google Drive and emits a FlowFile for each change that occurs.
%logo-snowflake-blue% [CaptureMicrosoft365GroupsChanges](/user-guide/data-integration/openflow/processors/capturemicrosoft365groupschanges) Captures Microsoft365 groups changes and emits a FlowFile for each change that occurs.
%logo-snowflake-blue% [CaptureSharepointChanges](/user-guide/data-integration/openflow/processors/capturesharepointchanges) Captures changes from a Sharepoint Document Library and emits a FlowFile for each change that occurs.
%logo-snowflake-blue% [CheckMetaAdsReportReadiness](/user-guide/data-integration/openflow/processors/checkmetaadsreportreadiness) Processor checking if the Meta Ads report is ready for download.
%logo-snowflake-blue% [ChunkRecordText](/user-guide/data-integration/openflow/processors/chunkrecordtext) Chunks text with options for recursively splitting by delimiters and max character length.
%logo-snowflake-blue% [ChunkText](/user-guide/data-integration/openflow/processors/chunktext) Chunks text with options for recursively splitting by delimiters and max character length.
[CompressContent](/user-guide/data-integration/openflow/processors/compresscontent) Compresses or decompresses the contents of FlowFiles using a user-specified compression algorithm and updates the mime.
[ConnectWebSocket](/user-guide/data-integration/openflow/processors/connectwebsocket) Acts as a WebSocket client endpoint to interact with a remote WebSocket server.
[ConsumeAMQP](/user-guide/data-integration/openflow/processors/consumeamqp) Consumes AMQP Messages from an AMQP Broker using the AMQP 0.
[ConsumeAzureEventHub](/user-guide/data-integration/openflow/processors/consumeazureeventhub) Receives messages from Microsoft Azure Event Hubs with checkpointing to ensure consistent event processing.
[ConsumeBoxEnterpriseEvents](/user-guide/data-integration/openflow/processors/consumeboxenterpriseevents) Consumes Enterprise Events from Box admin_logs_streaming Stream Type.
[ConsumeBoxEvents](/user-guide/data-integration/openflow/processors/consumeboxevents) Consumes all events from Box.
[ConsumeElasticsearch](/user-guide/data-integration/openflow/processors/consumeelasticsearch) A processor that repeatedly runs a paginated query against a field using a Range query to consume new Documents from an Elasticsearch index/query.
[ConsumeGCPubSub](/user-guide/data-integration/openflow/processors/consumegcpubsub) Consumes messages from the configured Google Cloud PubSub subscription.
[ConsumeIMAP](/user-guide/data-integration/openflow/processors/consumeimap) Consumes messages from Email Server using IMAP protocol.
[ConsumeJMS](/user-guide/data-integration/openflow/processors/consumejms) Consumes JMS Message of type BytesMessage, TextMessage, ObjectMessage, MapMessage or StreamMessage transforming its content to a FlowFile and transitioning it to 'success' relationship.
[ConsumeKafka](/user-guide/data-integration/openflow/processors/consumekafka) Consumes messages from Apache Kafka Consumer API.
%logo-snowflake-blue% [ConsumeKafka](/user-guide/data-integration/openflow/processors/consumekafka) Consumes messages from Apache Kafka Consumer API.
[ConsumeKinesisStream](/user-guide/data-integration/openflow/processors/consumekinesisstream) Reads data from the specified AWS Kinesis stream and outputs a FlowFile for every processed Record (raw) or a FlowFile for a batch of processed records if a Record Reader and Record Writer are configured.
[ConsumeMQTT](/user-guide/data-integration/openflow/processors/consumemqtt) Subscribes to a topic and receives messages from an MQTT broker
[ConsumePOP3](/user-guide/data-integration/openflow/processors/consumepop3) Consumes messages from Email Server using POP3 protocol.
[ConsumeSlack](/user-guide/data-integration/openflow/processors/consumeslack) Retrieves messages from one or more configured Slack channels.
%logo-snowflake-blue% [ConsumeSlackConversation](/user-guide/data-integration/openflow/processors/consumeslackconversation) Retrieves messages from Slack conversations available to the App.
%logo-snowflake-blue% [ConsumeSlackHistory](/user-guide/data-integration/openflow/processors/consumeslackhistory) Fetches historical messages from all Slack channels available to the App.
%logo-snowflake-blue% [ConsumeSnowflakeStream](/user-guide/data-integration/openflow/processors/consumesnowflakestream) Fetches data from a Snowflake stream and writes it to a FlowFile.
[ConsumeTwitter](/user-guide/data-integration/openflow/processors/consumetwitter) Streams tweets from Twitter's streaming API v2.
[ControlRate](/user-guide/data-integration/openflow/processors/controlrate) Controls the rate at which data is transferred to follow-on processors.
[ConvertCharacterSet](/user-guide/data-integration/openflow/processors/convertcharacterset) Converts a FlowFile's content from one character set to another
[ConvertRecord](/user-guide/data-integration/openflow/processors/convertrecord) Converts records from one data format to another using configured Record Reader and Record Write Controller Services.
%logo-snowflake-blue% [ConvertToJournalSchema](/user-guide/data-integration/openflow/processors/converttojournalschema) Converts the incoming database schema into the appropriate schema for a Snowflake CDC Journal table.
[CopyAzureBlobStorage_v12](/user-guide/data-integration/openflow/processors/copyazureblobstorage_v12) Copies a blob in Azure Blob Storage from one account/container to another.
[CopyS3Object](/user-guide/data-integration/openflow/processors/copys3object) Copies a file from one bucket and key to another in AWS S3
[CountText](/user-guide/data-integration/openflow/processors/counttext) Counts various metrics on incoming text.
%logo-snowflake-blue% [CreateAmazonAdsReport](/user-guide/data-integration/openflow/processors/createamazonadsreport) Processor which creates report configuration for Amazon Ads connector.
%logo-snowflake-blue% [CreateAzureOpenAiEmbeddings](/user-guide/data-integration/openflow/processors/createazureopenaiembeddings) Uses Azure OpenAI to create embeddings for text.
[CreateBoxFileMetadataInstance](/user-guide/data-integration/openflow/processors/createboxfilemetadatainstance) Creates a metadata instance for a Box file using a specified template with values from the flowFile content.
[CreateBoxMetadataTemplate](/user-guide/data-integration/openflow/processors/createboxmetadatatemplate) Creates a Box metadata template using field specifications from the flowFile content.
%logo-snowflake-blue% [CreateCohereEmbeddings](/user-guide/data-integration/openflow/processors/createcohereembeddings) Uses Cohere to create embeddings for text.
%logo-snowflake-blue% [CreateMetaAdsReport](/user-guide/data-integration/openflow/processors/createmetaadsreport) Processor which creates report configuration for Meta Ads connector.
%logo-snowflake-blue% [CreateOpenAiEmbeddings](/user-guide/data-integration/openflow/processors/createopenaiembeddings) Uses OpenAI to create embeddings for text.
%logo-snowflake-blue% [CreateSnowflakeEmbeddings](/user-guide/data-integration/openflow/processors/createsnowflakeembeddings) Create vector embeddings using Snowflake Cortex Large Language Model functions
%logo-snowflake-blue% [CreateVertexAIEmbeddings](/user-guide/data-integration/openflow/processors/createvertexaiembeddings) Uses VertexAI to create embeddings for text.
[CryptographicHashContent](/user-guide/data-integration/openflow/processors/cryptographichashcontent) Calculates a cryptographic hash value for the flowfile content using the given algorithm and writes it to an output attribute.
Processor Description
[DebugFlow](/user-guide/data-integration/openflow/processors/debugflow) The DebugFlow processor aids testing and debugging the FlowFile framework by allowing various responses to be explicitly triggered in response to the receipt of a FlowFile or a timer event without a FlowFile if using timer or cron based scheduling.
[DecryptContentAge](/user-guide/data-integration/openflow/processors/decryptcontentage) Decrypt content using the age-encryption.
[DecryptContentPGP](/user-guide/data-integration/openflow/processors/decryptcontentpgp) Decrypt contents of OpenPGP messages.
[DeduplicateRecord](/user-guide/data-integration/openflow/processors/deduplicaterecord) This processor de-duplicates individual records within a record set.
[DeleteAzureBlobStorage_v12](/user-guide/data-integration/openflow/processors/deleteazureblobstorage_v12) Deletes the specified blob from Azure Blob Storage.
[DeleteAzureDataLakeStorage](/user-guide/data-integration/openflow/processors/deleteazuredatalakestorage) Deletes the provided file from Azure Data Lake Storage
[DeleteBoxFileMetadataInstance](/user-guide/data-integration/openflow/processors/deleteboxfilemetadatainstance) Deletes a metadata instance from a Box file using the specified template key
[DeleteByQueryElasticsearch](/user-guide/data-integration/openflow/processors/deletebyqueryelasticsearch) Delete from an Elasticsearch index using a query.
%logo-snowflake-blue% [DeleteDBFSResource](/user-guide/data-integration/openflow/processors/deletedbfsresource) Delete a DBFS files and directories.
[DeleteDynamoDB](/user-guide/data-integration/openflow/processors/deletedynamodb) Deletes a document from DynamoDB based on hash and range key.
[DeleteFile](/user-guide/data-integration/openflow/processors/deletefile) Deletes a file from the filesystem.
[DeleteGCSObject](/user-guide/data-integration/openflow/processors/deletegcsobject) Deletes objects from a Google Cloud Bucket.
[DeleteGridFS](/user-guide/data-integration/openflow/processors/deletegridfs) Deletes a file from GridFS using a file name or a query.
%logo-snowflake-blue% [DeleteMilvus](/user-guide/data-integration/openflow/processors/deletemilvus) Deletes vectors from Milvus database from a collection by ID.
[DeleteMongo](/user-guide/data-integration/openflow/processors/deletemongo) Executes a delete query against a MongoDB collection.
%logo-snowflake-blue% [DeletePinecone](/user-guide/data-integration/openflow/processors/deletepinecone) Deletes vectors from a Pinecone index.
%logo-snowflake-blue% [DeleteQueryJob](/user-guide/data-integration/openflow/processors/deletequeryjob) Deletes a Query Job in Salesforce using the Bulk API 2.
[DeleteS3Object](/user-guide/data-integration/openflow/processors/deletes3object) Deletes a file from an Amazon S3 Bucket.
[DeleteSFTP](/user-guide/data-integration/openflow/processors/deletesftp) Deletes a file residing on an SFTP server.
[DeleteSQS](/user-guide/data-integration/openflow/processors/deletesqs) Deletes a message from an Amazon Simple Queuing Service Queue
%logo-snowflake-blue% [DeleteUnityCatalogResource](/user-guide/data-integration/openflow/processors/deleteunitycatalogresource) Delete a Unity Catalog file or directory.
%logo-snowflake-blue% [DescribeDataShare](/user-guide/data-integration/openflow/processors/describedatashare) Describe the specified data share metadata in Salesforce Data Cloud.
%logo-snowflake-blue% [DescribeSFDCObject](/user-guide/data-integration/openflow/processors/describesfdcobject) Describe the specified object metadata in Salesforce.
[DetectDuplicate](/user-guide/data-integration/openflow/processors/detectduplicate) Caches a value, computed from FlowFile attributes, for each incoming FlowFile and determines if the cached value has already been seen.
[DistributeLoad](/user-guide/data-integration/openflow/processors/distributeload) Distributes FlowFiles to downstream processors based on a Distribution Strategy.
[DuplicateFlowFile](/user-guide/data-integration/openflow/processors/duplicateflowfile) Intended for load testing, this processor will create the configured number of copies of each incoming FlowFile.
Processor Description
[EncodeContent](/user-guide/data-integration/openflow/processors/encodecontent) Encode or decode the contents of a FlowFile using Base64, Base32, or hex encoding schemes
[EncryptContentAge](/user-guide/data-integration/openflow/processors/encryptcontentage) Encrypt content using the age-encryption.
[EncryptContentPGP](/user-guide/data-integration/openflow/processors/encryptcontentpgp) Encrypt contents using OpenPGP.
[EnforceOrder](/user-guide/data-integration/openflow/processors/enforceorder) Enforces expected ordering of FlowFiles that belong to the same data group within a single node.
%logo-snowflake-blue% [EnrichAttributes](/user-guide/data-integration/openflow/processors/enrichattributes) Looks up a value using the configured Lookup Service and adds the results to the FlowFile as one or more attributes.
%logo-snowflake-blue% [EnrichCdcStream](/user-guide/data-integration/openflow/processors/enrichcdcstream) Enriches incoming FlowFiles that come from CaptureChangePostgreSQL, etc.
[EvaluateJsonPath](/user-guide/data-integration/openflow/processors/evaluatejsonpath) Evaluates one or more JsonPath expressions against the content of a FlowFile.
%logo-snowflake-blue% [EvaluateRagAnswerCorrectness](/user-guide/data-integration/openflow/processors/evaluateraganswercorrectness) Evaluates the correctness of generated answers in a Retrieval-Augmented Generation (RAG) context by computing metrics such as F1 score, cosine similarity, and answer correctness.
%logo-snowflake-blue% [EvaluateRagFaithfulness](/user-guide/data-integration/openflow/processors/evaluateragfaithfulness) Evaluates the faithfulness of generated answers in a Retrieval-Augmented Generation (RAG) system by analyzing responses using an LLM (e.
%logo-snowflake-blue% [EvaluateRagRetrieval](/user-guide/data-integration/openflow/processors/evaluateragretrieval) Calculates retrieval metrics (Precision@N, Recall@N, FScore@N, MAP@N, MRR) for a RAG system using an LLM as a judge.
[EvaluateXPath](/user-guide/data-integration/openflow/processors/evaluatexpath) Evaluates one or more XPaths against the content of a FlowFile.
[EvaluateXQuery](/user-guide/data-integration/openflow/processors/evaluatexquery) Evaluates one or more XQueries against the content of a FlowFile.
[ExecuteGroovyScript](/user-guide/data-integration/openflow/processors/executegroovyscript) Experimental Extended Groovy script processor.
[ExecuteProcess](/user-guide/data-integration/openflow/processors/executeprocess) Runs an operating system command specified by the user and writes the output of that command to a FlowFile.
[ExecuteScript](/user-guide/data-integration/openflow/processors/executescript) Experimental - Executes a script given the flow file and a process session.
[ExecuteSQL](/user-guide/data-integration/openflow/processors/executesql) Executes provided SQL select query.
[ExecuteSQLRecord](/user-guide/data-integration/openflow/processors/executesqlrecord) Executes provided SQL select query.
%logo-snowflake-blue% [ExecuteSQLStatement](/user-guide/data-integration/openflow/processors/executesqlstatement) Executes a SQL DDL or DML Statement against a database.
[ExecuteStreamCommand](/user-guide/data-integration/openflow/processors/executestreamcommand) The ExecuteStreamCommand processor provides a flexible way to integrate external commands and scripts into NiFi data flows.
[ExtractAvroMetadata](/user-guide/data-integration/openflow/processors/extractavrometadata) Extracts metadata from the header of an Avro datafile.
[ExtractEmailAttachments](/user-guide/data-integration/openflow/processors/extractemailattachments) Extract attachments from a mime formatted email file, splitting them into individual flowfiles.
[ExtractEmailHeaders](/user-guide/data-integration/openflow/processors/extractemailheaders) Using the flowfile content as source of data, extract header from an RFC compliant email file adding the relevant attributes to the flowfile.
[ExtractGrok](/user-guide/data-integration/openflow/processors/extractgrok) Evaluates one or more Grok Expressions against the content of a FlowFile, adding the results as attributes or replacing the content of the FlowFile with a JSON notation of the matched content
[ExtractRecordSchema](/user-guide/data-integration/openflow/processors/extractrecordschema) Extracts the record schema from the FlowFile using the supplied Record Reader and writes it to the 'avro.
%logo-snowflake-blue% [ExtractSchemaColumns](/user-guide/data-integration/openflow/processors/extractschemacolumns) Extracts the record schema columns from the FlowFile using the supplied Record Reader and writes it to the 'schema.
[ExtractStructuredBoxFileMetadata](/user-guide/data-integration/openflow/processors/extractstructuredboxfilemetadata) Extracts metadata from a Box file using Box AI.
[ExtractText](/user-guide/data-integration/openflow/processors/extracttext) Evaluates one or more Regular Expressions against the content of a FlowFile.
Processor Description
[FetchAzureBlobStorage_v12](/user-guide/data-integration/openflow/processors/fetchazureblobstorage_v12) Retrieves the specified blob from Azure Blob Storage and writes its content to the content of the FlowFile.
[FetchAzureDataLakeStorage](/user-guide/data-integration/openflow/processors/fetchazuredatalakestorage) Fetch the specified file from Azure Data Lake Storage
[FetchBoxFile](/user-guide/data-integration/openflow/processors/fetchboxfile) Fetches files from a Box Folder.
[FetchBoxFileInfo](/user-guide/data-integration/openflow/processors/fetchboxfileinfo) Fetches metadata for files from Box and adds it to the FlowFile's attributes.
[FetchBoxFileMetadataInstance](/user-guide/data-integration/openflow/processors/fetchboxfilemetadatainstance) Retrieves specific metadata instance associated with a Box file using template key and scope.
[FetchBoxFileRepresentation](/user-guide/data-integration/openflow/processors/fetchboxfilerepresentation) Fetches a Box file representation using a representation hint and writes it to the FlowFile content.
[FetchDistributedMapCache](/user-guide/data-integration/openflow/processors/fetchdistributedmapcache) Computes cache key(s) from FlowFile attributes, for each incoming FlowFile, and fetches the value(s) from the Distributed Map Cache associated with each key.
[FetchDropbox](/user-guide/data-integration/openflow/processors/fetchdropbox) Fetches files from Dropbox.
[FetchFile](/user-guide/data-integration/openflow/processors/fetchfile) Reads the contents of a file from disk and streams it into the contents of an incoming FlowFile.
[FetchFTP](/user-guide/data-integration/openflow/processors/fetchftp) Fetches the content of a file from a remote FTP server and overwrites the contents of an incoming FlowFile with the content of the remote file.
[FetchGCSObject](/user-guide/data-integration/openflow/processors/fetchgcsobject) Fetches a file from a Google Cloud Bucket.
[FetchGoogleDrive](/user-guide/data-integration/openflow/processors/fetchgoogledrive) Fetches files from a Google Drive Folder.
%logo-snowflake-blue% [FetchGoogleDriveFileComments](/user-guide/data-integration/openflow/processors/fetchgoogledrivefilecomments) Fetches comments and their replies for a Google Drive file.
%logo-snowflake-blue% [FetchGoogleDriveMetadata](/user-guide/data-integration/openflow/processors/fetchgoogledrivemetadata) Fetches Google Drive file metadata.
[FetchGridFS](/user-guide/data-integration/openflow/processors/fetchgridfs) Retrieves one or more files from a GridFS bucket by file name or by a user-defined query.
%logo-snowflake-blue% [FetchJiraFields](/user-guide/data-integration/openflow/processors/fetchjirafields) Retrieves comprehensive metadata for all fields available in the Jira Cloud instance using the REST API v3 /field endpoint.
%logo-snowflake-blue% [FetchJiraIssues](/user-guide/data-integration/openflow/processors/fetchjiraissues) Fetches issues from Jira Cloud using REST API v3 with configurable search options.
%logo-snowflake-blue% [FetchMicrosoftDataverseTable](/user-guide/data-integration/openflow/processors/fetchmicrosoftdataversetable) Fetch records from Microsoft Dataverse Tables
[FetchS3Object](/user-guide/data-integration/openflow/processors/fetchs3object) Retrieves the contents of an S3 Object and writes it to the content of a FlowFile
[FetchSFTP](/user-guide/data-integration/openflow/processors/fetchsftp) Fetches the content of a file from a remote SFTP server and overwrites the contents of an incoming FlowFile with the content of the remote file.
%logo-snowflake-blue% [FetchSharepointFile](/user-guide/data-integration/openflow/processors/fetchsharepointfile) Fetches the contents of a file from a Sharepoint Drive, optionally downloading a PDF or HTML version of the file when applicable.
%logo-snowflake-blue% [FetchSharepointMetadata](/user-guide/data-integration/openflow/processors/fetchsharepointmetadata) For each drive item retrieves its metadata and permissions and writes them as FlowFile attributes.
%logo-snowflake-blue% [FetchSlackConversationInfo](/user-guide/data-integration/openflow/processors/fetchslackconversationinfo) Fetches Slack conversation info and member emails
%logo-snowflake-blue% [FetchSlackFile](/user-guide/data-integration/openflow/processors/fetchslackfile) Downloads a file shared on Slack.
%logo-snowflake-blue% [FetchSlackMessage](/user-guide/data-integration/openflow/processors/fetchslackmessage) Fetches data about a single Slack message
[FetchSmb](/user-guide/data-integration/openflow/processors/fetchsmb) Fetches files from a SMB Share.
%logo-snowflake-blue% [FetchSnowflakeTableProperties](/user-guide/data-integration/openflow/processors/fetchsnowflaketableproperties) Reads properties from a table and stores them as flow file attributes.
%logo-snowflake-blue% [FetchSourceTableSchema](/user-guide/data-integration/openflow/processors/fetchsourcetableschema) Fetches the table schema (i.
%logo-snowflake-blue% [FetchTableSnapshot](/user-guide/data-integration/openflow/processors/fetchtablesnapshot) Fetches a snapshot of a table from a database.
[FilterAttribute](/user-guide/data-integration/openflow/processors/filterattribute) Filters the attributes of a FlowFile by retaining specified attributes and removing the rest or by removing specified attributes and retaining the rest.
%logo-snowflake-blue% [FindConfluencePages](/user-guide/data-integration/openflow/processors/findconfluencepages) Processor for finding Confluence pages using space name and page name.
%logo-snowflake-blue% [FindSharepointDriveItem](/user-guide/data-integration/openflow/processors/findsharepointdriveitem) Finds a Sharepoint Drive Item by its Drive ID and Item path.
[FlattenJson](/user-guide/data-integration/openflow/processors/flattenjson) Provides the user with the ability to take a nested JSON document and flatten it into a simple key/value pair document.
[ForkEnrichment](/user-guide/data-integration/openflow/processors/forkenrichment) Used in conjunction with the JoinEnrichment processor, this processor is responsible for adding the attributes that are necessary for the JoinEnrichment processor to perform its function.
[ForkRecord](/user-guide/data-integration/openflow/processors/forkrecord) This processor allows the user to fork a record into multiple records.
Processor Description
%logo-snowflake-blue% [GenerateAnswersFromContext](/user-guide/data-integration/openflow/processors/generateanswersfromcontext) Generates synthetic answers for each question present in the incoming records using a Large Language Model (LLM).
%logo-snowflake-blue% [GenerateAnswersFromGroundTruth](/user-guide/data-integration/openflow/processors/generateanswersfromgroundtruth) Generates synthetic answers for each question in the incoming records using an LLM.
[GenerateFlowFile](/user-guide/data-integration/openflow/processors/generateflowfile) This processor creates FlowFiles with random data or custom content.
%logo-snowflake-blue% [GenerateJSON](/user-guide/data-integration/openflow/processors/generatejson) Produces a batch of JSON Objects with random field values based on a configurable JSON Schema.
[GenerateRecord](/user-guide/data-integration/openflow/processors/generaterecord) This processor creates FlowFiles with records having random value for the specified fields.
[GenerateTableFetch](/user-guide/data-integration/openflow/processors/generatetablefetch) Generates SQL select queries that fetch "pages" of rows from a table.
[GeoEnrichIP](/user-guide/data-integration/openflow/processors/geoenrichip) Looks up geolocation information for an IP address and adds the geo information to FlowFile attributes.
[GeoEnrichIPRecord](/user-guide/data-integration/openflow/processors/geoenrichiprecord) Looks up geolocation information for an IP address and adds the geo information to FlowFile attributes.
%logo-snowflake-blue% [GetAmazonAdsReport](/user-guide/data-integration/openflow/processors/getamazonadsreport) Processor downloading report from Amazon Ads if ready.
[GetAwsPollyJobStatus](/user-guide/data-integration/openflow/processors/getawspollyjobstatus) Retrieves the current status of an AWS Polly job.
[GetAwsTextractJobStatus](/user-guide/data-integration/openflow/processors/getawstextractjobstatus) Retrieves the current status of an AWS Textract job.
[GetAwsTranscribeJobStatus](/user-guide/data-integration/openflow/processors/getawstranscribejobstatus) Retrieves the current status of an AWS Transcribe job.
[GetAwsTranslateJobStatus](/user-guide/data-integration/openflow/processors/getawstranslatejobstatus) Retrieves the current status of an AWS Translate job.
[GetAzureEventHub](/user-guide/data-integration/openflow/processors/getazureeventhub) Receives messages from Microsoft Azure Event Hubs without reliable checkpoint tracking.
[GetAzureQueueStorage_v12](/user-guide/data-integration/openflow/processors/getazurequeuestorage_v12) Retrieves the messages from an Azure Queue Storage.
[GetBoxFileCollaborators](/user-guide/data-integration/openflow/processors/getboxfilecollaborators) Retrieves all collaborators on a Box file and adds the collaboration information to the FlowFile's attributes.
[GetBoxGroupMembers](/user-guide/data-integration/openflow/processors/getboxgroupmembers) Retrieves members for a Box Group and writes their details in FlowFile attributes.
%logo-snowflake-blue% [GetConfluenceAuditRecords](/user-guide/data-integration/openflow/processors/getconfluenceauditrecords) Processor listing Confluence audit records.
%logo-snowflake-blue% [GetConfluenceGroupUsers](/user-guide/data-integration/openflow/processors/getconfluencegroupusers) Processor that downloads information about users belonging to a given Confluence group
%logo-snowflake-blue% [GetConfluencePageContent](/user-guide/data-integration/openflow/processors/getconfluencepagecontent) Processor downloading Confluence pages.
%logo-snowflake-blue% [GetConfluencePageIds](/user-guide/data-integration/openflow/processors/getconfluencepageids) Downloads changed Confluence pages since the last sync and emits each as a FlowFile with metadata.
%logo-snowflake-blue% [GetConfluencePagePermissions](/user-guide/data-integration/openflow/processors/getconfluencepagepermissions) Processor downloading Confluence page permissions.
%logo-snowflake-blue% [GetConfluenceSpaceIds](/user-guide/data-integration/openflow/processors/getconfluencespaceids) Processor for retrieving Confluence space ids.
%logo-snowflake-blue% [GetConfluenceSpacePermissions](/user-guide/data-integration/openflow/processors/getconfluencespacepermissions) Processor downloading Confluence space permissions.
%logo-snowflake-blue% [GetDataShareCredentials](/user-guide/data-integration/openflow/processors/getdatasharecredentials) Describe the specified data share metadata in Salesforce Data Cloud.
%logo-snowflake-blue% [GetDataShareTables](/user-guide/data-integration/openflow/processors/getdatasharetables) Describe the specified data share metadata in Salesforce Data Cloud.
%logo-snowflake-blue% [GetDBFSFile](/user-guide/data-integration/openflow/processors/getdbfsfile) Read a DBFS file.
[GetDynamoDB](/user-guide/data-integration/openflow/processors/getdynamodb) Retrieves a document from DynamoDB based on hash and range key.
[GetElasticsearch](/user-guide/data-integration/openflow/processors/getelasticsearch) Elasticsearch get processor that uses the official Elastic REST client libraries to fetch a single document from Elasticsearch by _id.
[GetFile](/user-guide/data-integration/openflow/processors/getfile) Creates FlowFiles from files in a directory.
[GetFileResource](/user-guide/data-integration/openflow/processors/getfileresource) This processor creates FlowFiles with the content of the configured File Resource.
[GetFTP](/user-guide/data-integration/openflow/processors/getftp) Fetches files from an FTP Server and creates FlowFiles from them
[GetGcpVisionAnnotateFilesOperationStatus](/user-guide/data-integration/openflow/processors/getgcpvisionannotatefilesoperationstatus) Retrieves the current status of an Google Vision operation.
[GetGcpVisionAnnotateImagesOperationStatus](/user-guide/data-integration/openflow/processors/getgcpvisionannotateimagesoperationstatus) Retrieves the current status of an Google Vision operation.
%logo-snowflake-blue% [GetGoogleAdsReport](/user-guide/data-integration/openflow/processors/getgoogleadsreport) A processor which can interact with Google Ads Reporting API.
%logo-snowflake-blue% [GetGoogleGroupMembers](/user-guide/data-integration/openflow/processors/getgooglegroupmembers) Retrieves the members of one or more Google Groups, specified as a comma-separated list of group IDs that is given as a FlowFile attribute.
%logo-snowflake-blue% [GetGoogleSheets](/user-guide/data-integration/openflow/processors/getgooglesheets) Processor responsible for fetching data from Google Sheets.
[GetHubSpot](/user-guide/data-integration/openflow/processors/gethubspot) Retrieves JSON data from a private HubSpot application.
%logo-snowflake-blue% [GetHubSpotObject](/user-guide/data-integration/openflow/processors/gethubspotobject) Get a HubSpot object and its associations by ID or unique value.
%logo-snowflake-blue% [GetHubSpotSchema](/user-guide/data-integration/openflow/processors/gethubspotschema) Retrieves schema information for HubSpot object types including field names, types, and labels.
%logo-snowflake-blue% [GetLinkedInAdsReport](/user-guide/data-integration/openflow/processors/getlinkedinadsreport) Processor downloading metrics from the LinkedIn Reporting APIs.
%logo-snowflake-blue% [GetMicrosoft365GroupMembers](/user-guide/data-integration/openflow/processors/getmicrosoft365groupmembers) Retrieves Microsoft365 group members and emits a FlowFile for each change that occurs.
[GetMongo](/user-guide/data-integration/openflow/processors/getmongo) Creates FlowFiles from documents in MongoDB loaded by a user-specified query.
[GetMongoRecord](/user-guide/data-integration/openflow/processors/getmongorecord) A record-based version of GetMongo that uses the Record writers to write the MongoDB result set.
%logo-snowflake-blue% [GetQueryJobResult](/user-guide/data-integration/openflow/processors/getqueryjobresult) Gets the results of a Query Job in Salesforce using the Bulk API 2.
%logo-snowflake-blue% [GetQueryJobStatus](/user-guide/data-integration/openflow/processors/getqueryjobstatus) Gets the status of a Query Job in Salesforce using the Bulk API 2.
[GetS3ObjectMetadata](/user-guide/data-integration/openflow/processors/gets3objectmetadata) Check for the existence of an Object in S3 and fetch its Metadata without attempting to download it.
[GetS3ObjectTags](/user-guide/data-integration/openflow/processors/gets3objecttags) Check for the existence of an Object in S3 and fetch its Tags without attempting to download it.
[GetSFTP](/user-guide/data-integration/openflow/processors/getsftp) Fetches files from an SFTP Server and creates FlowFiles from them
%logo-snowflake-blue% [GetSharepointSiteGroupMembers](/user-guide/data-integration/openflow/processors/getsharepointsitegroupmembers) Retrieves all members of a SharePoint site group.
[GetShopify](/user-guide/data-integration/openflow/processors/getshopify) Retrieves objects from a custom Shopify store.
[GetSmbFile](/user-guide/data-integration/openflow/processors/getsmbfile) Reads file from a samba network location to FlowFiles.
[GetSplunk](/user-guide/data-integration/openflow/processors/getsplunk) Retrieves data from Splunk Enterprise.
[GetSQS](/user-guide/data-integration/openflow/processors/getsqs) Fetches messages from an Amazon Simple Queuing Service Queue
%logo-snowflake-blue% [GetUnityCatalogFile](/user-guide/data-integration/openflow/processors/getunitycatalogfile) Read a Unity Catalog file up to 5 GiB.
%logo-snowflake-blue% [GetUnityCatalogFileMetadata](/user-guide/data-integration/openflow/processors/getunitycatalogfilemetadata) Checks for Unity Catalog file metadata.
[GetWorkdayReport](/user-guide/data-integration/openflow/processors/getworkdayreport) A processor which can interact with a configurable Workday Report.
[GetZendesk](/user-guide/data-integration/openflow/processors/getzendesk) Incrementally fetches data from Zendesk API.
Processor Description
[HandleHttpRequest](/user-guide/data-integration/openflow/processors/handlehttprequest) Starts an HTTP Server and listens for HTTP Requests.
[HandleHttpResponse](/user-guide/data-integration/openflow/processors/handlehttpresponse) Sends an HTTP Response to the Requestor that generated a FlowFile.
Processor Description
[IdentifyMimeType](/user-guide/data-integration/openflow/processors/identifymimetype) Attempts to identify the MIME Type used for a FlowFile.
[InvokeHTTP](/user-guide/data-integration/openflow/processors/invokehttp) An HTTP client processor which can interact with a configurable HTTP Endpoint.
[InvokeScriptedProcessor](/user-guide/data-integration/openflow/processors/invokescriptedprocessor) Experimental - Invokes a script engine for a Processor defined in the given script.
[ISPEnrichIP](/user-guide/data-integration/openflow/processors/ispenrichip) Looks up ISP information for an IP address and adds the information to FlowFile attributes.
Processor Description
[JoinEnrichment](/user-guide/data-integration/openflow/processors/joinenrichment) Joins together Records from two different FlowFiles where one FlowFile, the 'original' contains arbitrary records and the second FlowFile, the 'enrichment' contains additional data that should be used to enrich the first.
[JoltTransformJSON](/user-guide/data-integration/openflow/processors/jolttransformjson) Applies a list of Jolt specifications to either the FlowFile JSON content or a specified FlowFile JSON attribute.
[JoltTransformRecord](/user-guide/data-integration/openflow/processors/jolttransformrecord) Applies a JOLT specification to each record in the FlowFile payload.
[JSLTTransformJSON](/user-guide/data-integration/openflow/processors/jslttransformjson) Applies a JSLT transformation to the FlowFile JSON payload.
[JsonQueryElasticsearch](/user-guide/data-integration/openflow/processors/jsonqueryelasticsearch) A processor that allows the user to run a query (with aggregations) written with the Elasticsearch JSON DSL.
Processor Description
%logo-snowflake-blue% [ListArchivedHubSpotData](/user-guide/data-integration/openflow/processors/listarchivedhubspotdata) Lists archived data from HubSpot for the chosen object type and generates one FlowFile per listed object with the corresponding metadata as FlowFile attributes.
[ListAzureBlobStorage_v12](/user-guide/data-integration/openflow/processors/listazureblobstorage_v12) Lists blobs in an Azure Blob Storage container.
[ListAzureDataLakeStorage](/user-guide/data-integration/openflow/processors/listazuredatalakestorage) Lists directory in an Azure Data Lake Storage Gen 2 filesystem
[ListBoxFile](/user-guide/data-integration/openflow/processors/listboxfile) Lists files in a Box folder.
[ListBoxFileInfo](/user-guide/data-integration/openflow/processors/listboxfileinfo) Fetches file metadata for each file in a Box Folder.
[ListBoxFileMetadataInstances](/user-guide/data-integration/openflow/processors/listboxfilemetadatainstances) Retrieves all metadata instances associated with a Box file.
[ListBoxFileMetadataTemplates](/user-guide/data-integration/openflow/processors/listboxfilemetadatatemplates) Retrieves all metadata templates associated with a Box file.
%logo-snowflake-blue% [ListConfluenceGroups](/user-guide/data-integration/openflow/processors/listconfluencegroups) Processor listing Confluence groups.
[ListDatabaseTables](/user-guide/data-integration/openflow/processors/listdatabasetables) Generates a set of flow files, each containing attributes corresponding to metadata about a table from a database connection.
%logo-snowflake-blue% [ListDBFSDirectory](/user-guide/data-integration/openflow/processors/listdbfsdirectory) List file names in a DBFS directory and output a new FlowFile with the filename.
[ListDropbox](/user-guide/data-integration/openflow/processors/listdropbox) Retrieves a listing of files from Dropbox (shortcuts are ignored).
[ListenFTP](/user-guide/data-integration/openflow/processors/listenftp) Starts an FTP server that listens on the specified port and transforms incoming files into FlowFiles.
[ListenHTTP](/user-guide/data-integration/openflow/processors/listenhttp) Starts an HTTP Server and listens on a given base path to transform incoming requests into FlowFiles.
[ListenOTLP](/user-guide/data-integration/openflow/processors/listenotlp) Collect OpenTelemetry messages over HTTP or gRPC.
[ListenSlack](/user-guide/data-integration/openflow/processors/listenslack) Retrieves real-time messages or Slack commands from one or more Slack conversations.
[ListenSyslog](/user-guide/data-integration/openflow/processors/listensyslog) Listens for Syslog messages being sent to a given port over TCP or UDP.
[ListenTCP](/user-guide/data-integration/openflow/processors/listentcp) Listens for incoming TCP connections and reads data from each connection using a line separator as the message demarcator.
[ListenUDP](/user-guide/data-integration/openflow/processors/listenudp) Listens for Datagram Packets on a given port.
[ListenUDPRecord](/user-guide/data-integration/openflow/processors/listenudprecord) Listens for Datagram Packets on a given port and reads the content of each datagram using the configured Record Reader.
[ListenWebSocket](/user-guide/data-integration/openflow/processors/listenwebsocket) Acts as a WebSocket server endpoint to accept client connections.
[ListFile](/user-guide/data-integration/openflow/processors/listfile) Retrieves a listing of files from the input directory.
[ListFTP](/user-guide/data-integration/openflow/processors/listftp) Performs a listing of the files residing on an FTP server.
[ListGCSBucket](/user-guide/data-integration/openflow/processors/listgcsbucket) Retrieves a listing of objects from a GCS bucket.
[ListGoogleDrive](/user-guide/data-integration/openflow/processors/listgoogledrive) Performs a listing of concrete files (shortcuts are ignored) in a Google Drive folder.
%logo-snowflake-blue% [ListGoogleDriveFileInfo](/user-guide/data-integration/openflow/processors/listgoogledrivefileinfo) Lists all files and folders in a specified Google Drive.
%logo-snowflake-blue% [ListGoogleGroups](/user-guide/data-integration/openflow/processors/listgooglegroups) Lists all of the groups for a given domain in Google Workspace.
%logo-snowflake-blue% [ListHubSpotObjects](/user-guide/data-integration/openflow/processors/listhubspotobjects) Fetches data from HubSpot for specified object types, and generates one FlowFile per listed object with the corresponding metadata as FlowFile attributes.
%logo-snowflake-blue% [ListMicrosoftDataverseTables](/user-guide/data-integration/openflow/processors/listmicrosoftdataversetables) List Tables from Microsoft Dataverse environments
[ListS3](/user-guide/data-integration/openflow/processors/lists3) Retrieves a listing of objects from an S3 bucket.
%logo-snowflake-blue% [ListSFDCDataShares](/user-guide/data-integration/openflow/processors/listsfdcdatashares) List the available data shares in the organization that are available to the identified user.
%logo-snowflake-blue% [ListSFDCObjects](/user-guide/data-integration/openflow/processors/listsfdcobjects) List the available objects in the organization that are available to the identified user.
[ListSFTP](/user-guide/data-integration/openflow/processors/listsftp) Performs a listing of the files residing on an SFTP server.
%logo-snowflake-blue% [ListSharepointDrives](/user-guide/data-integration/openflow/processors/listsharepointdrives) Emits a FlowFile for each Drive present in the specified Sharepoint Site.
%logo-snowflake-blue% [ListSharepointSiteGroups](/user-guide/data-integration/openflow/processors/listsharepointsitegroups) Lists all SharePoint site groups available on a specified SharePoint site.
[ListSmb](/user-guide/data-integration/openflow/processors/listsmb) Lists concrete files shared via SMB protocol.
%logo-snowflake-blue% [ListTableNames](/user-guide/data-integration/openflow/processors/listtablenames) Fetches all source table names and matches them with one of the possible configurations: - regexp expression e.
%logo-snowflake-blue% [ListUnityCatalogDirectory](/user-guide/data-integration/openflow/processors/listunitycatalogdirectory) List file names in a Unity Catalog directory and output a new FlowFile with the filename.
[LogAttribute](/user-guide/data-integration/openflow/processors/logattribute) Emits attributes of the FlowFile at the specified log level
[LogMessage](/user-guide/data-integration/openflow/processors/logmessage) Emits a log message at the specified log level
[LookupAttribute](/user-guide/data-integration/openflow/processors/lookupattribute) Lookup attributes from a lookup service
[LookupRecord](/user-guide/data-integration/openflow/processors/lookuprecord) Extracts one or more fields from a Record and looks up a value for those fields in a LookupService.
Processor Description
[MergeContent](/user-guide/data-integration/openflow/processors/mergecontent) Merges a Group of FlowFiles together based on a user-defined strategy and packages them into a single FlowFile.
[MergeRecord](/user-guide/data-integration/openflow/processors/mergerecord) This Processor merges together multiple record-oriented FlowFiles into a single FlowFile that contains all of the Records of the input FlowFiles.
%logo-snowflake-blue% [MergeSnowflakeJournalTable](/user-guide/data-integration/openflow/processors/mergesnowflakejournaltable) Triggers a merge operation on changes from journal table to a destination table in Snowflake.
[ModifyBytes](/user-guide/data-integration/openflow/processors/modifybytes) Discard byte range at the start and end or all content of a binary file.
[ModifyCompression](/user-guide/data-integration/openflow/processors/modifycompression) Changes the compression algorithm used to compress the contents of a FlowFile by decompressing the contents of FlowFiles using a user-specified compression algorithm and recompressing the contents using the specified compression format properties.
[MonitorActivity](/user-guide/data-integration/openflow/processors/monitoractivity) Monitors the flow for activity and sends out an indicator when the flow has not had any data for some specified amount of time and again when the flow's activity is restored
[MoveAzureDataLakeStorage](/user-guide/data-integration/openflow/processors/moveazuredatalakestorage) Moves content within an Azure Data Lake Storage Gen 2.
Processor Description
[Notify](/user-guide/data-integration/openflow/processors/notify) Caches a release signal identifier in the distributed cache, optionally along with the FlowFile's attributes.
Processor Description
%logo-snowflake-blue% [OpenAiTranscribeAudio](/user-guide/data-integration/openflow/processors/openaitranscribeaudio) Transcribes audio into English text.
Processor Description
[PackageFlowFile](/user-guide/data-integration/openflow/processors/packageflowfile) This processor will package FlowFile attributes and content into an output FlowFile that can be exported from NiFi and imported back into NiFi, preserving the original attributes and content.
[PaginatedJsonQueryElasticsearch](/user-guide/data-integration/openflow/processors/paginatedjsonqueryelasticsearch) A processor that allows the user to run a paginated query (with aggregations) written with the Elasticsearch JSON DSL.
[ParseEvtx](/user-guide/data-integration/openflow/processors/parseevtx) Parses the contents of a Windows Event Log file (evtx) and writes the resulting XML to the FlowFile
%logo-snowflake-blue% [ParseExcelCellReference](/user-guide/data-integration/openflow/processors/parseexcelcellreference) Processor responsible for parsing Excel cell reference formula.
[ParseSyslog](/user-guide/data-integration/openflow/processors/parsesyslog) Attempts to parses the contents of a Syslog message in accordance to RFC5424 and RFC3164 formats and adds attributes to the FlowFile for each of the parts of the Syslog message.
[ParseSyslog5424](/user-guide/data-integration/openflow/processors/parsesyslog5424) Attempts to parse the contents of a well formed Syslog message in accordance to RFC5424 format and adds attributes to the FlowFile for each of the parts of the Syslog message, including Structured Data.
[PartitionRecord](/user-guide/data-integration/openflow/processors/partitionrecord) Splits, or partitions, record-oriented data based on the configured fields in the data.
%logo-snowflake-blue% [PerformSnowflakeCortexOCR](/user-guide/data-integration/openflow/processors/performsnowflakecortexocr) Performs Optical Character Recognition (OCR) on PDF documents using Snowflake Cortex ML functions.
%logo-snowflake-blue% [PickTablesForReplication](/user-guide/data-integration/openflow/processors/picktablesforreplication) Accepts a list of fully qualified table names and determines if a table: - is new (is not replicated, but was added in the source) - is existing (is replicated and exists in the source) - is stale (is replicated but no longer exists in the source) Configuration is passed as a FlowFile attribute.
%logo-snowflake-blue% [PromptAnthropicAI](/user-guide/data-integration/openflow/processors/promptanthropicai) Sends a prompt to Anthropic, writing the response either as a FlowFile attribute or to the contents of the incoming FlowFile.
%logo-snowflake-blue% [PromptAzureOpenAI](/user-guide/data-integration/openflow/processors/promptazureopenai) Sends a prompt to Azure's OpenAI service, writing the response either as a FlowFile attribute or to the contents of the incoming FlowFile.
%logo-snowflake-blue% [PromptLLM](/user-guide/data-integration/openflow/processors/promptllm) This processor sends a user defined prompt to a Large Language Model (LLM) to respond.
%logo-snowflake-blue% [PromptOpenAI](/user-guide/data-integration/openflow/processors/promptopenai) Sends a prompt to OpenAI, writing the response either as a FlowFile attribute or to the contents of the incoming FlowFile.
%logo-snowflake-blue% [PromptSnowflakeCortex](/user-guide/data-integration/openflow/processors/promptsnowflakecortex) Sends a prompt to Snowflake Cortex, writing the response either as a FlowFile attribute or to the contents of the incoming FlowFile.
%logo-snowflake-blue% [PromptVertexAI](/user-guide/data-integration/openflow/processors/promptvertexai) Sends a prompt to VertexAI, writing the response either as a FlowFile attribute or to the contents of the incoming FlowFile.
[PublishAMQP](/user-guide/data-integration/openflow/processors/publishamqp) Creates an AMQP Message from the contents of a FlowFile and sends the message to an AMQP Exchange.
%logo-snowflake-blue% [PublishChangeDataSnowpipeStreaming](/user-guide/data-integration/openflow/processors/publishchangedatasnowpipestreaming) Publishes change data as Newline Delimited JSON to Snowflake Database Pipes using Snowpipe Streaming High Availability with concurrency group serialization.
[PublishGCPubSub](/user-guide/data-integration/openflow/processors/publishgcpubsub) Publishes the content of the incoming flowfile to the configured Google Cloud PubSub topic.
[PublishJMS](/user-guide/data-integration/openflow/processors/publishjms) Creates a JMS Message from the contents of a FlowFile and sends it to a JMS Destination (queue or topic) as JMS BytesMessage or TextMessage.
[PublishKafka](/user-guide/data-integration/openflow/processors/publishkafka) Sends the contents of a FlowFile as either a message or as individual records to Apache Kafka using the Kafka Producer API.
%logo-snowflake-blue% [PublishKafka](/user-guide/data-integration/openflow/processors/publishkafka) Sends the contents of a FlowFile as either a message or as individual records to Apache Kafka using the Kafka Producer API.
[PublishMQTT](/user-guide/data-integration/openflow/processors/publishmqtt) Publishes a message to an MQTT topic
[PublishSlack](/user-guide/data-integration/openflow/processors/publishslack) Posts a message to the specified Slack channel.
%logo-snowflake-blue% [PublishSnowpipeStreaming](/user-guide/data-integration/openflow/processors/publishsnowpipestreaming) Publishes Newline Delimited JSON to Snowflake Database Pipes using Snowpipe Streaming High Availability.
[PutAzureBlobStorage_v12](/user-guide/data-integration/openflow/processors/putazureblobstorage_v12) Puts content into a blob on Azure Blob Storage.
[PutAzureCosmosDBRecord](/user-guide/data-integration/openflow/processors/putazurecosmosdbrecord) This processor is a record-aware processor for inserting data into Cosmos DB with Core SQL API.
[PutAzureDataExplorer](/user-guide/data-integration/openflow/processors/putazuredataexplorer) Acts as an Azure Data Explorer sink which sends FlowFiles to the provided endpoint.
[PutAzureDataLakeStorage](/user-guide/data-integration/openflow/processors/putazuredatalakestorage) Writes the contents of a FlowFile as a file on Azure Data Lake Storage Gen 2
[PutAzureEventHub](/user-guide/data-integration/openflow/processors/putazureeventhub) Send FlowFile contents to Azure Event Hubs
[PutAzureQueueStorage_v12](/user-guide/data-integration/openflow/processors/putazurequeuestorage_v12) Writes the content of the incoming FlowFiles to the configured Azure Queue Storage.
[PutBigQuery](/user-guide/data-integration/openflow/processors/putbigquery) Writes the contents of a FlowFile to a Google BigQuery table.
[PutBoxFile](/user-guide/data-integration/openflow/processors/putboxfile) Puts content to a Box folder.
[PutCloudWatchMetric](/user-guide/data-integration/openflow/processors/putcloudwatchmetric) Publishes metrics to Amazon CloudWatch.
[PutDatabaseRecord](/user-guide/data-integration/openflow/processors/putdatabaserecord) The PutDatabaseRecord processor uses a specified RecordReader to input (possibly multiple) records from an incoming flow file.
%logo-snowflake-blue% [PutDatabricksSQL](/user-guide/data-integration/openflow/processors/putdatabrickssql) Submit a SQL Execution using Databricks REST API then write the JSON response to FlowFile Content.
%logo-snowflake-blue% [PutDBFSFile](/user-guide/data-integration/openflow/processors/putdbfsfile) Write FlowFile content to DBFS.
[PutDistributedMapCache](/user-guide/data-integration/openflow/processors/putdistributedmapcache) Gets the content of a FlowFile and puts it to a distributed map cache, using a cache key computed from FlowFile attributes.
[PutDropbox](/user-guide/data-integration/openflow/processors/putdropbox) Puts content to a Dropbox folder.
[PutDynamoDB](/user-guide/data-integration/openflow/processors/putdynamodb) Puts a document from DynamoDB based on hash and range key.
[PutDynamoDBRecord](/user-guide/data-integration/openflow/processors/putdynamodbrecord) Inserts items into DynamoDB based on record-oriented data.
[PutElasticsearchJson](/user-guide/data-integration/openflow/processors/putelasticsearchjson) An Elasticsearch put processor that uses the official Elastic REST client libraries.
[PutElasticsearchRecord](/user-guide/data-integration/openflow/processors/putelasticsearchrecord) A record-aware Elasticsearch put processor that uses the official Elastic REST client libraries.
[PutEmail](/user-guide/data-integration/openflow/processors/putemail) Sends an e-mail to configured recipients for each incoming FlowFile
[PutFile](/user-guide/data-integration/openflow/processors/putfile) Writes the contents of a FlowFile to the local file system
[PutFTP](/user-guide/data-integration/openflow/processors/putftp) Sends FlowFiles to an FTP Server
[PutGCSObject](/user-guide/data-integration/openflow/processors/putgcsobject) Writes the contents of a FlowFile as an object in a Google Cloud Storage.
[PutGoogleDrive](/user-guide/data-integration/openflow/processors/putgoogledrive) Writes the contents of a FlowFile as a file in Google Drive.
[PutGridFS](/user-guide/data-integration/openflow/processors/putgridfs) Writes a file to a GridFS bucket.
%logo-snowflake-blue% [PutHubSpot](/user-guide/data-integration/openflow/processors/puthubspot) Upsert a HubSpot object.
%logo-snowflake-blue% [PutIcebergTable](/user-guide/data-integration/openflow/processors/puticebergtable) Store records in Iceberg using configurable Catalog for managing namespaces and tables.
[PutKinesisFirehose](/user-guide/data-integration/openflow/processors/putkinesisfirehose) Sends the contents to a specified Amazon Kinesis Firehose.
[PutKinesisStream](/user-guide/data-integration/openflow/processors/putkinesisstream) Sends the contents to a specified Amazon Kinesis.
[PutLambda](/user-guide/data-integration/openflow/processors/putlambda) Sends the contents to a specified Amazon Lambda Function.
[PutMongo](/user-guide/data-integration/openflow/processors/putmongo) Writes the contents of a FlowFile to MongoDB
[PutMongoBulkOperations](/user-guide/data-integration/openflow/processors/putmongobulkoperations) Writes the contents of a FlowFile to MongoDB as bulk-update
[PutMongoRecord](/user-guide/data-integration/openflow/processors/putmongorecord) This processor is a record-aware processor for inserting/upserting data into MongoDB.
[PutRecord](/user-guide/data-integration/openflow/processors/putrecord) The PutRecord processor uses a specified RecordReader to input (possibly multiple) records from an incoming flow file, and sends them to a destination specified by a Record Destination Service (i.
[PutRedisHashRecord](/user-guide/data-integration/openflow/processors/putredishashrecord) Puts record field data into Redis using a specified hash value, which is determined by a RecordPath to a field in each record containing the hash value.
[PutS3Object](/user-guide/data-integration/openflow/processors/puts3object) Writes the contents of a FlowFile as an S3 Object to an Amazon S3 Bucket.
[PutSalesforceObject](/user-guide/data-integration/openflow/processors/putsalesforceobject) Creates new records for the specified Salesforce sObject.
[PutSFTP](/user-guide/data-integration/openflow/processors/putsftp) Sends FlowFiles to an SFTP Server
[PutSmbFile](/user-guide/data-integration/openflow/processors/putsmbfile) Writes the contents of a FlowFile to a samba network location.
%logo-snowflake-blue% [PutSnowflakeInternalStageFile](/user-guide/data-integration/openflow/processors/putsnowflakeinternalstagefile) Puts files into a Snowflake internal stage.
%logo-snowflake-blue% [PutSnowpipeStreaming](/user-guide/data-integration/openflow/processors/putsnowpipestreaming) Streams records into a Snowflake table.
[PutSNS](/user-guide/data-integration/openflow/processors/putsns) Sends the content of a FlowFile as a notification to the Amazon Simple Notification Service
[PutSplunk](/user-guide/data-integration/openflow/processors/putsplunk) Sends logs to Splunk Enterprise over TCP, TCP + TLS/SSL, or UDP.
[PutSplunkHTTP](/user-guide/data-integration/openflow/processors/putsplunkhttp) Sends flow file content to the specified Splunk server over HTTP or HTTPS.
[PutSQL](/user-guide/data-integration/openflow/processors/putsql) Executes a SQL UPDATE or INSERT command.
[PutSQS](/user-guide/data-integration/openflow/processors/putsqs) Publishes a message to an Amazon Simple Queuing Service Queue
[PutSyslog](/user-guide/data-integration/openflow/processors/putsyslog) Sends Syslog messages to a given host and port over TCP or UDP.
[PutTCP](/user-guide/data-integration/openflow/processors/puttcp) Sends serialized FlowFiles or Records over TCP to a configurable destination with optional support for TLS
[PutUDP](/user-guide/data-integration/openflow/processors/putudp) The PutUDP processor receives a FlowFile and packages the FlowFile content into a single UDP datagram packet which is then transmitted to the configured UDP server.
%logo-snowflake-blue% [PutUnityCatalogFile](/user-guide/data-integration/openflow/processors/putunitycatalogfile) Write FlowFile content with max size of 5 GiB to Unity Catalog.
%logo-snowflake-blue% [PutVectaraDocument](/user-guide/data-integration/openflow/processors/putvectaradocument) Generate and upload a JSON document to Vectara's upload endpoint.
%logo-snowflake-blue% [PutVectaraFile](/user-guide/data-integration/openflow/processors/putvectarafile) Upload a FlowFile content to Vectara's index endpoint.
[PutWebSocket](/user-guide/data-integration/openflow/processors/putwebsocket) Sends messages to a WebSocket remote endpoint using a WebSocket session that is established by either ListenWebSocket or ConnectWebSocket.
[PutZendeskTicket](/user-guide/data-integration/openflow/processors/putzendeskticket) Create Zendesk tickets using the Zendesk API.
Processor Description
[QueryAzureDataExplorer](/user-guide/data-integration/openflow/processors/queryazuredataexplorer) Query Azure Data Explorer and stream JSON results to output FlowFiles
[QueryDatabaseTable](/user-guide/data-integration/openflow/processors/querydatabasetable) Generates a SQL select query, or uses a provided statement, and executes it to fetch all rows whose values in the specified Maximum Value column(s) are larger than the previously-seen maxima.
[QueryDatabaseTableRecord](/user-guide/data-integration/openflow/processors/querydatabasetablerecord) Generates a SQL select query, or uses a provided statement, and executes it to fetch all rows whose values in the specified Maximum Value column(s) are larger than the previously-seen maxima.
%logo-snowflake-blue% [QueryMilvus](/user-guide/data-integration/openflow/processors/querymilvus) Queries a given collection in a Milvus database using vectors.
%logo-snowflake-blue% [QueryPinecone](/user-guide/data-integration/openflow/processors/querypinecone) Queries Pinecone for vectors that are similar to the input vector, or retrieves a vector by ID.
[QueryRecord](/user-guide/data-integration/openflow/processors/queryrecord) Evaluates one or more SQL queries against the contents of a FlowFile.
[QuerySalesforceObject](/user-guide/data-integration/openflow/processors/querysalesforceobject) Retrieves records from a Salesforce sObject.
[QuerySplunkIndexingStatus](/user-guide/data-integration/openflow/processors/querysplunkindexingstatus) Queries Splunk server in order to acquire the status of indexing acknowledgement.
Processor Description
[RemoveRecordField](/user-guide/data-integration/openflow/processors/removerecordfield) Modifies the contents of a FlowFile that contains Record-oriented data (i.
[RenameRecordField](/user-guide/data-integration/openflow/processors/renamerecordfield) Renames one or more fields in each Record of a FlowFile.
[ReplaceText](/user-guide/data-integration/openflow/processors/replacetext) Updates the content of a FlowFile by searching for some textual value in the FlowFile content (via Regular Expression/regex, or literal value) and replacing the section of the content that matches with some alternate value.
[ReplaceTextWithMapping](/user-guide/data-integration/openflow/processors/replacetextwithmapping) Updates the content of a FlowFile by evaluating a Regular Expression against it and replacing the section of the content that matches the Regular Expression with some alternate value provided in a mapping file.
[RetryFlowFile](/user-guide/data-integration/openflow/processors/retryflowfile) FlowFiles passed to this Processor have a 'Retry Attribute' value checked against a configured 'Maximum Retries' value.
[RouteOnAttribute](/user-guide/data-integration/openflow/processors/routeonattribute) Routes FlowFiles based on their Attributes using the Attribute Expression Language
[RouteOnContent](/user-guide/data-integration/openflow/processors/routeoncontent) Applies Regular Expressions to the content of a FlowFile and routes a copy of the FlowFile to each destination whose Regular Expression matches.
[RouteText](/user-guide/data-integration/openflow/processors/routetext) Routes textual data based on a set of user-defined rules.
%logo-snowflake-blue% [RunDatabricksJob](/user-guide/data-integration/openflow/processors/rundatabricksjob) Triggers a pre-defined Databricks job to run with custom parameters.
[RunMongoAggregation](/user-guide/data-integration/openflow/processors/runmongoaggregation) A processor that runs an aggregation query whenever a flowfile is received.
Processor Description
[SampleRecord](/user-guide/data-integration/openflow/processors/samplerecord) Samples the records of a FlowFile based on a specified sampling strategy (such as Reservoir Sampling).
[ScanAttribute](/user-guide/data-integration/openflow/processors/scanattribute) Scans the specified attributes of FlowFiles, checking to see if any of their values are present within the specified dictionary of terms
[ScanContent](/user-guide/data-integration/openflow/processors/scancontent) Scans the content of FlowFiles for terms that are found in a user-supplied dictionary.
[ScriptedFilterRecord](/user-guide/data-integration/openflow/processors/scriptedfilterrecord) This processor provides the ability to filter records out from FlowFiles using the user-provided script.
[ScriptedPartitionRecord](/user-guide/data-integration/openflow/processors/scriptedpartitionrecord) Receives Record-oriented data (i.
[ScriptedTransformRecord](/user-guide/data-integration/openflow/processors/scriptedtransformrecord) Provides the ability to evaluate a simple script against each record in an incoming FlowFile.
[ScriptedValidateRecord](/user-guide/data-integration/openflow/processors/scriptedvalidaterecord) This processor provides the ability to validate records in FlowFiles using the user-provided script.
[SearchElasticsearch](/user-guide/data-integration/openflow/processors/searchelasticsearch) A processor that allows the user to repeatedly run a paginated query (with aggregations) written with the Elasticsearch JSON DSL.
[SegmentContent](/user-guide/data-integration/openflow/processors/segmentcontent) Segments a FlowFile into multiple smaller segments on byte boundaries.
[SignContentPGP](/user-guide/data-integration/openflow/processors/signcontentpgp) Sign content using OpenPGP Private Keys
%logo-snowflake-blue% [SnowflakeDetectDuplicate](/user-guide/data-integration/openflow/processors/snowflakedetectduplicate) Checks if a FlowFile 's hash (provided as a FlowFile attribute) is already in a Snowflake table, and routes the FlowFile to' duplicate 'if found,'distinct 'if not found, or' failure' on errors.
[SplitAvro](/user-guide/data-integration/openflow/processors/splitavro) Splits a binary encoded Avro datafile into smaller files based on the configured Output Size.
[SplitContent](/user-guide/data-integration/openflow/processors/splitcontent) Splits incoming FlowFiles by a specified byte sequence
[SplitExcel](/user-guide/data-integration/openflow/processors/splitexcel) This processor splits a multi sheet Microsoft Excel spreadsheet into multiple Microsoft Excel spreadsheets where each sheet from the original file is converted to an individual spreadsheet in its own flow file.
[SplitJson](/user-guide/data-integration/openflow/processors/splitjson) Splits a JSON File into multiple, separate FlowFiles for an array element specified by a JsonPath expression.
[SplitRecord](/user-guide/data-integration/openflow/processors/splitrecord) Splits up an input FlowFile that is in a record-oriented data format into multiple smaller FlowFiles
[SplitText](/user-guide/data-integration/openflow/processors/splittext) Splits a text file into multiple smaller text files on line boundaries limited by maximum number of lines or total size of fragment.
[SplitXml](/user-guide/data-integration/openflow/processors/splitxml) Splits an XML File into multiple separate FlowFiles, each comprising a child or descendant of the original root element
[StartAwsPollyJob](/user-guide/data-integration/openflow/processors/startawspollyjob) Trigger a AWS Polly job.
[StartAwsTextractJob](/user-guide/data-integration/openflow/processors/startawstextractjob) Trigger a AWS Textract job.
[StartAwsTranscribeJob](/user-guide/data-integration/openflow/processors/startawstranscribejob) Trigger a AWS Transcribe job.
[StartAwsTranslateJob](/user-guide/data-integration/openflow/processors/startawstranslatejob) Trigger a AWS Translate job.
[StartGcpVisionAnnotateFilesOperation](/user-guide/data-integration/openflow/processors/startgcpvisionannotatefilesoperation) Trigger a Vision operation on file input.
[StartGcpVisionAnnotateImagesOperation](/user-guide/data-integration/openflow/processors/startgcpvisionannotateimagesoperation) Trigger a Vision operation on image input.
%logo-snowflake-blue% [SubmitQueryJob](/user-guide/data-integration/openflow/processors/submitqueryjob) Submits a Query Job to Salesforce using the Bulk API 2.
%logo-snowflake-blue% [SummarizeText](/user-guide/data-integration/openflow/processors/summarizetext) This processor uses a Large Language Model (LLM) to summarize the content of a FlowFile.
Processor Description
[TagS3Object](/user-guide/data-integration/openflow/processors/tags3object) Adds or updates a tag on an Amazon S3 Object.
[TailFile](/user-guide/data-integration/openflow/processors/tailfile) "Tails" a file, or a list of files, ingesting data from the file as it is written to the file.
[TransformXml](/user-guide/data-integration/openflow/processors/transformxml) Applies the provided XSLT file to the FlowFile XML payload.
Processor Description
[UnpackContent](/user-guide/data-integration/openflow/processors/unpackcontent) Unpacks the content of FlowFiles that have been packaged with one of several different Packaging Formats, emitting one to many FlowFiles for each input FlowFile.
[UpdateAttribute](/user-guide/data-integration/openflow/processors/updateattribute) Updates the Attributes for a FlowFile by using the Attribute Expression Language and/or deletes the attributes based on a regular expression
[UpdateBoxFileMetadataInstance](/user-guide/data-integration/openflow/processors/updateboxfilemetadatainstance) Updates metadata template values for a Box file using the record in the given flowFile.
%logo-snowflake-blue% [UpdateBulkJobState](/user-guide/data-integration/openflow/processors/updatebulkjobstate) Updates the status of a Salesforce Bulk Job in the shared state service for a specific object type
[UpdateByQueryElasticsearch](/user-guide/data-integration/openflow/processors/updatebyqueryelasticsearch) Update documents in an Elasticsearch index using a query.
[UpdateCounter](/user-guide/data-integration/openflow/processors/updatecounter) This processor allows users to set specific counters and key points in their flow.
[UpdateDatabaseTable](/user-guide/data-integration/openflow/processors/updatedatabasetable) This processor uses a JDBC connection and incoming records to generate any database table changes needed to support the incoming records.
[UpdateRecord](/user-guide/data-integration/openflow/processors/updaterecord) Updates the contents of a FlowFile that contains Record-oriented data (i.
%logo-snowflake-blue% [UpdateSnowflakeDatabase](/user-guide/data-integration/openflow/processors/updatesnowflakedatabase) Updates the definition of a Snowflake table based on the schema provided in the incoming FlowFile.
%logo-snowflake-blue% [UpdateSnowflakeIcebergDatabase](/user-guide/data-integration/openflow/processors/updatesnowflakeicebergdatabase) Updates the definition of a Snowflake Iceberg table.
%logo-snowflake-blue% [UpdateSnowflakeSchema](/user-guide/data-integration/openflow/processors/updatesnowflakeschema) Creates Snowflake database schema if it does not exist.
%logo-snowflake-blue% [UpdateSnowflakeStream](/user-guide/data-integration/openflow/processors/updatesnowflakestream) Manages Snowflake streams by creating, dropping, or replacing them based on the configured operation.
%logo-snowflake-blue% [UpdateSnowflakeTable](/user-guide/data-integration/openflow/processors/updatesnowflaketable) Updates the definition of a Snowflake table based on the schema provided in the incoming FlowFile.
%logo-snowflake-blue% [UpdateSnowflakeView](/user-guide/data-integration/openflow/processors/updatesnowflakeview) Creates or replaces Snowflake views based on column mappings provided in the incoming FlowFile.
%logo-snowflake-blue% [UpdateTableState](/user-guide/data-integration/openflow/processors/updatetablestate) Updates the state of a table in the Table State Service
%logo-snowflake-blue% [UpsertMilvus](/user-guide/data-integration/openflow/processors/upsertmilvus) Upserts vectors into Milvus database for a given collection
%logo-snowflake-blue% [UpsertPinecone](/user-guide/data-integration/openflow/processors/upsertpinecone) Publishes vectors, including metadata, and optionally text, to a Pinecone index.
%logo-snowflake-blue% [UpsertSFDCObjects](/user-guide/data-integration/openflow/processors/upsertsfdcobjects) Upserts the records from the incoming FlowFile into Salesforce
Processor Description
[ValidateCsv](/user-guide/data-integration/openflow/processors/validatecsv) Validates the contents of FlowFiles or a FlowFile attribute value against a user-specified CSV schema.
[ValidateJson](/user-guide/data-integration/openflow/processors/validatejson) Validates the contents of FlowFiles against a configurable JSON Schema.
[ValidateRecord](/user-guide/data-integration/openflow/processors/validaterecord) Validates the Records of an incoming FlowFile against a given schema.
[ValidateXml](/user-guide/data-integration/openflow/processors/validatexml) Validates XML contained in a FlowFile.
[VerifyContentMAC](/user-guide/data-integration/openflow/processors/verifycontentmac) Calculates a Message Authentication Code using the provided Secret Key and compares it with the provided MAC property
[VerifyContentPGP](/user-guide/data-integration/openflow/processors/verifycontentpgp) Verify signatures using OpenPGP Public Keys
Processor Description
[Wait](/user-guide/data-integration/openflow/processors/wait) Routes incoming FlowFiles to the 'wait' relationship until a matching release signal is stored in the distributed cache from a corresponding Notify processor.
%logo-snowflake-blue% [WaitForTableState](/user-guide/data-integration/openflow/processors/waitfortablestate) Blocks incoming FlowFiles until the corresponding table state is not equal to accepted state.
Display Name API Name Default Value Allowable Values Description
AWS Credentials Provider Service AWS Credentials Provider Service The Controller Service that is used to obtain AWS credentials provider
Cache Expiration * Cache Expiration 1 hour Specifies how long a Schema that is cached should remain in the cache. Once this time period elapses, a cached version of a schema will no longer be used, and the service will have to communicate with the Schema Registry again in order to obtain the schema.
Cache Size * Cache Size 1000 Specifies how many Schemas should be cached from the Schema Registry
Communications Timeout * Communications Timeout 30 secs Specifies how long to wait to receive data from the Schema Registry before considering the communications a failure
Region * Region us-west-2 - AWS GovCloud (US-East) - AWS GovCloud (US-West) - Africa (Cape Town) - Asia Pacific (Hong Kong) - Asia Pacific (Hyderabad) - Asia Pacific (Jakarta) - Asia Pacific (Malaysia) - Asia Pacific (Melbourne) - Asia Pacific (Mumbai) - Asia Pacific (New Zealand) - Asia Pacific (Osaka) - Asia Pacific (Seoul) - Asia Pacific (Singapore) - Asia Pacific (Sydney) - Asia Pacific (Taipei) - Asia Pacific (Thailand) - Asia Pacific (Tokyo) - Canada (Central) - Canada West (Calgary) - China (Beijing) - China (Ningxia) - EU (Germany) - EU ISOE West - Europe (Frankfurt) - Europe (Ireland) - Europe (London) - Europe (Milan) - Europe (Paris) - Europe (Spain) - Europe (Stockholm) - Europe (Zurich) - Israel (Tel Aviv) - Mexico (Central) - Middle East (Bahrain) - Middle East (UAE) - South America (Sao Paulo) - US East (N. Virginia) - US East (Ohio) - US ISO East - US ISO WEST - US ISOB East (Ohio) - US ISOF EAST - US ISOF SOUTH - US West (N. California) - US West (Oregon) - aws global region - aws-cn global region - aws-iso global region - aws-iso-b global region - aws-iso-e global region - aws-iso-f global region - aws-us-gov global region The region of the cloud resources
SSL Context Service SSL Context Service Specifies an optional SSL Context Service that, if provided, will be used to create connections
Schema Registry Name * Schema Registry Name The name of the Schema Registry
Proxy Configuration Service proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Display Name API Name Default Value Allowable Values Description
SSL Context Service SSL Context Service Service supporting SSL communication with Kafka brokers
Acknowledgment Wait Time * ack.wait.time 5 sec After sending a message to Kafka, this indicates the amount of time that the service will wait for a response from Kafka.If Kafka does not acknowledge the message within this time period, the service will throw an exception.
AWS Profile Name aws.profile.name The Amazon Web Services Profile to select when multiple profiles are available.
Bootstrap Servers * bootstrap.servers Comma-separated list of Kafka Bootstrap Servers in the format host:port. Corresponds to Kafka bootstrap.servers property
Client Timeout * default.api.timeout.ms 60 sec Default timeout for Kafka client operations. Mapped to Kafka default.api.timeout.ms. The Kafka request.timeout.ms property is derived from half of the configured timeout
Transaction Isolation Level * isolation.level read_committed - Read Committed - Read Uncommitted Specifies how the service should handle transaction isolation levels when communicating with Kafka.The uncommitted option means that messages will be received as soon as they are written to Kafka but will be pulled, even if the producer cancels the transactions.The committed option configures the service to not receive any messages for which the producer's transaction was canceled, but this can result in some latency since theconsumer must wait for the producer to finish its entire transaction instead of pulling as the messages become available.Corresponds to Kafka isolation.level property.
Max Metadata Wait Time * max.block.ms 5 sec The amount of time publisher will wait to obtain metadata or wait for the buffer to flush during the 'send' call before failing theentire 'send' call. Corresponds to Kafka max.block.ms property
Max Poll Records * max.poll.records 10000 Maximum number of records Kafka should return in a single poll.
SASL Mechanism * sasl.mechanism AWS_MSK_IAM - AWS_MSK_IAM - SCRAM-SHA-512 SASL mechanism used for authentication. Corresponds to Kafka Client sasl.mechanism property
SASL Password * sasl.password Password provided with configured username when using PLAIN or SCRAM SASL Mechanisms
SASL Username * sasl.username Username provided with configured password when using PLAIN or SCRAM SASL Mechanisms
Security Protocol * security.protocol PLAINTEXT - PLAINTEXT - SSL - SASL_PLAINTEXT - SASL_SSL Security protocol used to communicate with brokers. Corresponds to Kafka Client security.protocol property
Parameter Description Required
Schema Registry Authentication Type The method of authenticating to schema registry if used. Otherwise, use *NONE*. One of: *NONE* / *BASIC*. Default: *NONE\* Yes
Schema Registry URL The URL of Schema Registry. Required for *AVRO* message format. No
Schema Registry Username The username for Schema Registry. Required for *AVRO* message format. No
Schema Registry Password The password for Schema Registry. Required for *AVRO* message format. No
AVRO Schema Access Strategy The method of accessing the AVRO schema of a message. Required for *AVRO*. One of: *embedded-avro-schema* / *schema-reference-reader* / *schema-text-property*. Default: *embedded-avro-schema\* No
AVRO Schema Avro schema in case schema-text-property is used in AVRO Schema Access Strategy with the AVRO message format. Note: this should only be used in case all messages consumed from the configured Kafka Topic(s) share the same schema. No
Parameter Description Required
Message Format The format of messages in Kafka. One of: *JSON* / *AVRO*. Default: *JSON\* Yes
AVRO Schema Avro schema in case *schema-text-property* is used in AVRO Schema Access Strategy with the AVRO message format. Note: this should only be used in case all messages consumed from the configured Kafka Topic(s) share the same schema. No
AVRO Schema Access Strategy The method of accessing the AVRO schema of a message. Required for *AVRO*. One of: *embedded-avro-schema* / *schema-reference-reader* / *schema-text-property*. Default: *embedded-avro-schema\* No
Parameter Description Required
Schema Registry Authentication Type The method of authenticating to schema registry if used. Otherwise, use *NONE*. One of: *NONE* / *BASIC*. Default: *NONE\* Yes
Schema Registry URL The URL of Schema Registry. Required for *AVRO* message format. No
Schema Registry Username The username for Schema Registry. Required for *AVRO* message format. No
Schema Registry Password The password for Schema Registry. Required for *AVRO* message format. No
Parameter Description Required
Kafka DLQ Topic DLQ topic to send messages with parsing errors to Yes
Schematization Enabled Determines whether data is inserted into individual columns or a single RECORD_CONTENT field. One of: *true* / *false*. Default: *true\* Yes
Iceberg Enabled Specifies whether the processor ingests data into an Iceberg table. The processor fails if this property doesn't match the actual table type. Default: *false\* Yes
Row RECORD_METADATA ACCOUNT SYMBOL SIDE QUANTITY
1 \{"timestamp":1669074170090, "headers": \{"current.iter... ABC123 ZTEST BUY 3572
2 \{"timestamp":1669074170400, "headers": \{"current.iter... XYZ789 ZABX SELL 3024
Row RECORD_METADATA RECORD_CONTENT
1 \{"timestamp":1669074170090, "headers": \{"current.iter... \{"account": "ABC123", "symbol": "ZTEST", "side":...
2 \{"timestamp":1669074170400, "headers": \{"current.iter... \{"account": "XYZ789", "symbol": "ZABX", "side":...
Field Description
offset The message offset within the Kafka partition
topic The Kafka topic name
partition The Kafka partition number
key The message key (if present)
timestamp The message timestamp
SnowflakeConnectorPushTime Timestamp when the connector fetched the message from Kafka
headers Map of message headers (if present)
Display Name API Name Default Value Allowable Values Description
Cache Expiration * Cache Expiration 1 hour Specifies how long a Schema that is cached should remain in the cache. Once this time period elapses, a cached version of a schema will no longer be used, and the service will have to communicate with the Schema Registry again in order to obtain the schema.
Cache Size * Cache Size 1000 Specifies how many Schemas should be cached from the Schema Registry. The cache size must be a non-negative integer. When it is set to 0, the cache is effectively disabled.
Schema Group ID * Schema Group ID default The artifact Group ID for the schemas
Schema Registry URL * Schema Registry URL The URL of the Schema Registry e.g. http://localhost:8080 (http://localhost:8080)
Web Client Service Provider * Web Client Service Provider Controller service for HTTP client operations
Property Description
attribute-list Comma separated list of attributes to be included in the resulting CSV. If this value is left empty then all existing Attributes will be included. This list of attributes is case sensitive and supports attribute names that contain commas. If an attribute specified in the list is not found it will be emitted to the resulting CSV with an empty string or null depending on the 'Null Value' property. If a core attribute is specified in this list and the 'Include Core Attributes' property is false, the core attribute will be included. The attribute list ALWAYS wins.
attributes-regex Regular expression that will be evaluated against the flow file attributes to select the matching attributes. This property can be used in combination with the attributes list property. The final output will contain a combination of matches found in the ATTRIBUTE_LIST and ATTRIBUTE_REGEX.
destination Control if CSV value is written as a new flowfile attribute 'CSVData' or written in the flowfile content.
include-core-attributes Determines if the FlowFile org.apache.nifi.flowfile.attributes. CoreAttributes, which are contained in every FlowFile, should be included in the final CSV value generated. Core attributes will be added to the end of the CSVData and CSVSchema strings. The Attribute List property overrides this setting.
include-schema If true the schema (attribute names) will also be converted to a CSV string which will either be applied to a new attribute named 'CSVSchema' or applied at the first row in the content depending on the DESTINATION property setting.
null-value If true a non existing or empty attribute will be 'null' in the resulting CSV. If false an empty string will be placed in the CSV
Name Description
failure Failed to convert attributes to CSV
success Successfully converted attributes to CSV
Name Description
CSVSchema CSV representation of the Schema
CSVData CSV representation of Attributes
Property Description
Attributes List Comma separated list of attributes to be included in the resulting JSON. If this value is left empty then all existing Attributes will be included. This list of attributes is case sensitive. If an attribute specified in the list is not found it will be emitted to the resulting JSON with an empty string or NULL value.
Destination Control if JSON value is written as a new flowfile attribute 'JSONAttributes' or written in the flowfile content. Writing to flowfile content will overwrite any existing flowfile content.
Include Core Attributes Determines if the FlowFile org.apache.nifi.flowfile.attributes. CoreAttributes which are contained in every FlowFile should be included in the final JSON value generated.
JSON Handling Strategy Strategy to use for handling attributes which contain nested JSON.
Null Value If true a non existing selected attribute will be NULL in the resulting JSON. If false an empty string will be placed in the JSON
Pretty Print Apply pretty print formatting to the output.
attributes-to-json-regex Regular expression that will be evaluated against the flow file attributes to select the matching attributes. This property can be used in combination with the attributes list property.
Name Description
failure Failed to convert attributes to JSON
success Successfully converted attributes to JSON
Name Description
JSONAttributes JSON representation of Attributes
Display Name API Name Default Value Allowable Values Description
Schema Access Strategy * Schema Access Strategy embedded-avro-schema - Use 'Schema Name' Property - Use 'Schema Text' Property - Schema Reference Reader - Use Embedded Avro Schema Specifies how to obtain the schema that is to be used for interpreting the data.
Schema Branch Schema Branch Specifies the name of the branch to use when looking up the schema in the Schema Registry property. If the chosen Schema Registry does not support branching, this value will be ignored.
Schema Name Schema Name $\{schema.name\} Specifies the name of the schema to lookup in the Schema Registry property
Schema Reference Reader * Schema Reference Reader Service implementation responsible for reading FlowFile attributes or content to determine the Schema Reference Identifier
Schema Registry Schema Registry Specifies the Controller Service to use for the Schema Registry
Schema Text Schema Text $\{avro.schema\} The text of an Avro-formatted Schema
Schema Version Schema Version Specifies the version of the schema to lookup in the Schema Registry. If not specified then the latest version of the schema will be retrieved.
Cache Size * cache-size 1000 Specifies how many Schemas should be cached
Display Name API Name Default Value Allowable Values Description
Schema Access Strategy * Schema Access Strategy inherit-record-schema - Inherit Record Schema - Use 'Schema Name' Property - Use 'Schema Text' Property Specifies how to obtain the schema that is to be used for interpreting the data.
Schema Branch Schema Branch Specifies the name of the branch to use when looking up the schema in the Schema Registry property. If the chosen Schema Registry does not support branching, this value will be ignored.
Schema Cache Schema Cache Specifies a Schema Cache to add the Record Schema to so that Record Readers can quickly lookup the schema.
Schema Name Schema Name $\{schema.name\} Specifies the name of the schema to lookup in the Schema Registry property
Schema Reference Reader * Schema Reference Reader Service implementation responsible for reading FlowFile attributes or content to determine the Schema Reference Identifier
Schema Reference Writer * Schema Reference Writer Service implementation responsible for writing FlowFile attributes or content header with Schema reference information
Schema Registry Schema Registry Specifies the Controller Service to use for the Schema Registry
Schema Text Schema Text $\{avro.schema\} The text of an Avro-formatted Schema
Schema Version Schema Version Specifies the version of the schema to lookup in the Schema Registry. If not specified then the latest version of the schema will be retrieved.
Schema Write Strategy * Schema Write Strategy avro-embedded - Embed Avro Schema - Do Not Write Schema - Set 'schema.name' Attribute - Set 'avro.schema' Attribute - Schema Reference Writer Specifies how the schema for a Record should be added to the data.
Cache Size * cache-size 1000 Specifies how many Schemas should be cached
Compression Format * compression-format NONE - BZIP2 - DEFLATE - NONE - SNAPPY - LZO Compression type to use when writing Avro files. Default is None.
Encoder Pool Size * encoder-pool-size 32 Avro Writers require the use of an Encoder. Creation of Encoders is expensive, but once created, they can be reused. This property controls the maximum number of Encoders that can be pooled and reused. Setting this value too small can result in degraded performance, but setting it higher can result in more heap being used. This property is ignored if the Avro Writer is configured with a Schema Write Strategy of 'Embed Avro Schema'.
Display Name API Name Default Value Allowable Values Description
Validate Field Names * avro-reg-validated-field-names true - true - false Whether or not to validate the field names in the Avro schema based on Avro naming rules. If set to true, all field names must be valid Avro names, which must begin with `[A-Za-z_]`, and subsequently contain only `[A-Za-z0-9_]`. If set to false, no validation will be performed on the field names.
Display Name API Name Default Value Allowable Values Description
Access Key ID Access Key ID
Assume Role ARN Assume Role ARN The AWS Role ARN for cross account access. This is used in conjunction with Assume Role Session Name and other Assume Role properties.
Assume Role External ID Assume Role External ID External ID for cross-account access. This is used in conjunction with Assume Role ARN.
Assume Role Proxy Configuration Service Assume Role Proxy Configuration Service Proxy configuration for cross-account access, if needed within your environment. This will configure a proxy to request for temporary access keys into another AWS account.
Assume Role SSL Context Service Assume Role SSL Context Service SSL Context Service used when connecting to the STS Endpoint.
Assume Role STS Endpoint Override Assume Role STS Endpoint Override The default AWS Security Token Service (STS) endpoint ("sts.amazonaws.com") works for all accounts that are not for China (Beijing) region or GovCloud. You only need to set this property to "sts.cn-north-1.amazonaws.com.cn" when you are requesting session credentials for services in China(Beijing) region or to "sts.us-gov-west-1.amazonaws.com" for GovCloud.
Assume Role STS Region Assume Role STS Region us-west-2 - Middle East (UAE) - US ISOF SOUTH - Asia Pacific (Taipei) - US West (N. California) - US West (Oregon) - Africa (Cape Town) - Asia Pacific (Osaka) - Asia Pacific (Seoul) - Asia Pacific (Tokyo) - Middle East (Bahrain) - South America (Sao Paulo) - China (Beijing) - Asia Pacific (Singapore) - Asia Pacific (Sydney) - Asia Pacific (Jakarta) - Asia Pacific (Melbourne) - Asia Pacific (Malaysia) - US East (N. Virginia) - Asia Pacific (New Zealand) - US East (Ohio) - Asia Pacific (Thailand) - China (Ningxia) - Asia Pacific (Hyderabad) - Asia Pacific (Mumbai) - Europe (Milan) - Europe (Spain) - AWS GovCloud (US-East) - Israel (Tel Aviv) - Canada (Central) - Mexico (Central) - Europe (Frankfurt) - EU (Germany) - US ISO WEST - Europe (Zurich) - EU ISOE West - Europe (Stockholm) - Europe (Paris) - Europe (London) - Europe (Ireland) - Asia Pacific (Hong Kong) - Canada West (Calgary) - AWS GovCloud (US-West) - US ISO East - US ISOB East (Ohio) - US ISOF EAST The AWS Security Token Service (STS) region
Assume Role STS Signer Override Assume Role STS Signer Override Default Signature - Default Signature - Signature Version 4 - Custom Signature The AWS STS library uses Signature Version 4 by default. This property allows you to plug in your own custom signer implementation.
Assume Role Session Name * Assume Role Session Name The AWS Role Session Name for cross account access. This is used in conjunction with Assume Role ARN.
Assume Role Session Time Assume Role Session Time 3600 Session time for role based session (between 900 and 3600 seconds). This is used in conjunction with Assume Role ARN.
Credentials File Credentials File Path to a file containing AWS access key and secret key in properties file format.
Custom Signer Class Name * Custom Signer Class Name Fully qualified class name of the custom signer class. The signer must implement com.amazonaws.auth.Signer interface.
Custom Signer Module Location Custom Signer Module Location Comma-separated list of paths to files and/or directories which contain the custom signer's JAR file and its dependencies (if any).
Profile Name Profile Name The AWS profile name for credentials from the profile configuration file.
Secret Access Key Secret Access Key
Use Anonymous Credentials Use Anonymous Credentials false - true - false If true, uses Anonymous credentials
Use Default Credentials Use Default Credentials false - true - false If true, uses the Default Credential chain, including EC2 instance profiles or roles, environment variables, default user credentials, etc.
Required Permission Explanation
access environment credentials The default configuration can read environment variables and system properties for credentials
Display Name API Name Default Value Allowable Values Description
Blob Name * Blob Name $\{azure.blobname\} The full name of the blob
Container Name * Container Name $\{azure.container\} Name of the Azure storage container. In case of PutAzureBlobStorage processor, container can be created if it does not exist.
Storage Credentials * Storage Credentials Controller Service used to obtain Azure Blob Storage Credentials.
Display Name API Name Default Value Allowable Values Description
Cosmos DB Access Key Cosmos DB Access Key Cosmos DB Access Key from Azure Portal (Settings->Keys). Choose a read-write key to enable database or container creation at run time
Cosmos DB Consistency Level Cosmos DB Consistency Level SESSION - STRONG - BOUNDED_STALENESS - SESSION - CONSISTENT_PREFIX - EVENTUAL Choose from five consistency levels on the consistency spectrum. Refer to Cosmos DB documentation for their differences
Cosmos DB URI Cosmos DB URI Cosmos DB URI, typically in the form of https://\{databaseaccount\}.documents.azure.com:443/ Note this host URL is for Cosmos DB with Core SQL API from Azure Portal (Overview->URI)
Display Name API Name Default Value Allowable Values Description
ADLS Credentials * ADLS Credentials Controller Service used to obtain Azure Credentials.
Directory Name * Directory Name $\{azure.directory\} Name of the Azure Storage Directory. The Directory Name cannot contain a leading '/'. The root directory can be designated by the empty string value. In case of the PutAzureDataLakeStorage processor, the directory will be created if not already existing.
File Name * File Name $\{azure.filename\} The filename
Filesystem Name * Filesystem Name $\{azure.filesystem\} Name of the Azure Storage File System (also called Container). It is assumed to be already existing.
Display Name API Name Default Value Allowable Values Description
Authentication Strategy * Authentication Strategy DEFAULT_AZURE_CREDENTIAL - Shared Access Key - Default Azure Credential Strategy for authenticating to Azure Event Hubs
Event Hub Name * Event Hub Name Provides the Event Hub Name for connections
Event Hub Namespace * Event Hub Namespace Provides provides the host for connecting to Azure Event Hubs
Partition Key Partition Key A hint for Azure Event Hub message broker how to distribute messages across one or more partitions
Service Bus Endpoint * Service Bus Endpoint .servicebus.windows.net - Azure - Azure China - Azure Germany - Azure US Government Provides the domain for connecting to Azure Event Hubs
Shared Access Policy Shared Access Policy The name of the shared access policy. This policy must have Send claims
Shared Access Policy Key Shared Access Policy Key The primary or secondary key of the shared access policy
Transport Type * Transport Type Amqp - AMQP - AMQP_WEB_SOCKETS Advanced Message Queuing Protocol Transport Type for communication with Azure Event Hubs
Record Writer * record-sink-record-writer Specifies the Controller Service to use for writing out the records.
Display Name API Name Default Value Allowable Values Description
Account Key * Account Key The storage account key. This is an admin-like password providing access to every container in this account. It is recommended one uses Shared Access Signature (SAS) token, Managed Identity or Service Principal instead for fine-grained control with policies.
Credentials Type * Credentials Type SAS_TOKEN - Account Key - SAS Token - Managed Identity - Service Principal Credentials type to be used for authenticating to Azure
Endpoint Suffix * Endpoint Suffix blob.core.windows.net Storage accounts in public Azure always use a common FQDN suffix. Override this endpoint suffix with a different suffix in certain circumstances (like Azure Stack or non-public Azure regions).
Managed Identity Client ID Managed Identity Client ID Client ID of the managed identity. The property is required when User Assigned Managed Identity is used for authentication. It must be empty in case of System Assigned Managed Identity.
SAS Token * SAS Token Shared Access Signature token (the leading '?' may be included)
Service Principal Client ID * Service Principal Client ID Client ID (or Application ID) of the Client/Application having the Service Principal.
Service Principal Client Secret * Service Principal Client Secret Password of the Client/Application.
Service Principal Tenant ID * Service Principal Tenant ID Tenant ID of the Azure Active Directory hosting the Service Principal.
Storage Account Name * Storage Account Name The storage account name.
Proxy Configuration Service proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests. In case of SOCKS, it is not guaranteed that the selected SOCKS Version will be used by the processor.
Property Description
record-stats-limit Limit the number of individual stats that are returned for each record path to the top N results.
record-stats-reader A record reader to use for reading the records.
Name Description
failure If a FlowFile cannot be processed for any reason, it is routed to this Relationship.
success All FlowFiles that are successfully processed, are routed to this Relationship.
Name Description
record.count A count of the records in the record set in the FlowFile.
recordStats.<User Defined Property Name>.count A count of the records that contain a value for the user defined property.
recordStats.<User Defined Property Name>.<value>.count Each value discovered for the user defined property will have its own count attribute. Total number of top N value counts to be added is defined by the limit configuration.
Property Description
Column Filter Store Service storing per-table column filtering settings.
Connection Timeout Connection to source database timeout
JDBC Driver Location Comma-separated list of files/folders and/or URLs containing the driver JAR and its dependencies (if any). For example '/var/tmp/mariadb-java-client-3.4.1.jar'
JDBC URL JDBC URL of the database connection, ie. [jdbc:mariadb://localhost:3306/mysql](jdbc:mariadb://localhost:3306/mysql)
Max Batch Size The maximum number of records to process in a single iteration. The number of records may exceed the maximum batch size when the last binlog event contains more than one row.
Max Batch Wait Time The maximum time to wait for data to appear in the binlog.
Max Queue Size The maximum number of elements read from binlog until reader thread will wait for onTrigger
Password Password to access the MySQL database
Record Writer The Record Writer is used for serializing DML events
SSL Context Service SSL Context Service supporting encrypted socket communication
SSL Mode SSL Mode used when SSL Context Service configured supporting certificate verification options
Server ID Server ID (in the range from 1 to 2^32 - 1). This value MUST be unique across whole replication group (that is, different from any other Server ID being used by any master or slave). Keep in mind that each binary log client should be treated as a simplified slave and thus MUST also use a different Server ID.
Server ID Strategy Determines how the server ID is selected
Table State Store The shared store holding the state of replicated tables.
Username Username to access the MySQL database
Scopes Description
CLUSTER Information such as a 'pointer' to the current CDC event in the database is stored by this processor, such that it can continue from the same location if restarted.
Name Description
success Successfully created FlowFile from CDC stream events
Name Description
source.schema.name Name of the schema of the table from which an event originated
source.table.name Name of the table from which an event originated
cdc.event.type Type of event carried by the FlowFile: ddl or dml
cdc.most.significant.position Ddl's most significant position in cdc stream
cdc.least.significant.position Ddl's least significant position in cdc stream
cdc.event.seen.at Timestamp from time when ddl event has been read by the processor
Property Description
Column Filter Store Service storing per-table column filtering settings.
JDBC Driver Location Comma-separated list of files/folders and/or URLs containing the driver JAR and its dependencies (if any). For example '/var/tmp/postgresql-java-client-42.7.5.jar'
JDBC URL JDBC URL of the database connection, ie. [jdbc:postgresql://localhost:5432/postgres](jdbc:postgresql://localhost:5432/postgres)
Max Batch Size The maximum number of records to process in a single iteration
Max Batch Wait Time The maximum time to wait for data to appear in the CDC stream.
Password Password to access the PostgreSQL database
Publication Name The name of the CDC publication to read from.
Record Writer The Record Writer is used for serializing DML events
Replication Slot Name The name of the replication slot to use. 63 characters maximum. If the slot doesn't exist, the processor will create it.
SSL Context Service SSL Context Service supporting encrypted socket communication
SSL Mode Whether to use and enforce SSL when connecting to PostgreSQL
TOASTed Value Placeholder The value to put into a TOASTed column
TOASTed Value Strategy Determines how to handle TOASTed values.
Table State Store The shared store holding the state of replicated tables.
Username Username to access the PostgreSQL database
Scopes Description
CLUSTER Information such as a 'pointer' to the current CDC event in the database is stored by this processor, such that it can continue from the same location if restarted, and the name of the replication slot created in PostgreSQL.
Name Description
success Successfully created FlowFile from CDC stream events
Name Description
source.schema.name Name of the schema of the table from which an event originated
source.table.name Name of the table from which an event originated
cdc.event.type Type of event carried by the FlowFile: ddl or dml
cdc.most.significant.position Ddl's most significant position in cdc stream
cdc.least.significant.position Ddl's least significant position in cdc stream
cdc.event.seen.at Timestamp from time when ddl event has been read by the processor
Property Description
Column Filter Store Service storing per-table column filtering settings.
Connection Pool The connection pool
Fetch Size The maximum number of rows loaded into memory at once
Max Batch Size The maximum number of rows to fetch in a single batch
Record Writer The Record Writer is used for serializing DML events
Table Changes Query Interval The minimum time interval that must elapse before scheduling the next query for table changes. This controls the frequency of database polling to prevent excessive querying.
Table State Store The shared store holding the state of replicated tables.
Scopes Description
CLUSTER Information such as a version of the last processed record for each table is stored by this processor, such that it can continue from the same location if restarted.
Name Description
success Successfully created FlowFile from CDC stream events
Property Description
Drive ID The ID of the Shared Google Drive to monitor.
GCP Credentials Service The Controller Service used to obtain Google Cloud Platform credentials.
Scopes Description
CLUSTER Stores a token/cursor to track which changes have already been processed.
Name Description
created This Relationship is used for any files that are created.
removed This Relationship is used for any files that are deleted.
updated This Relationship is used for any files that are updated.
Name Description
google.drive.drive.id The ID of the Shared Google Drive.
google.drive.file.id The ID of the file that was changed.
drive.id The ID of the file that was changed. This is repeated for compatibility with FetchGoogleDrive's default configuration.
google.drive.file.name The name of the file that was changed.
google.drive.change.type The type of change that occurred. Possible values are 'CREATED', 'UPDATED', or 'DELETED'.
google.drive.change.time The timestamp of the change, in milliseconds since the Unix epoch.
google.drive.created.time The timestamp when the file was created, in milliseconds since the Unix epoch.
google.drive.webUrl A link for opening the file in a relevant Google editor or viewer in a browser.
google.drive.size The size of the file in bytes.
google.drive.md5 The MD5 checksum of the file.
google.drive.version The version of the file. This changes based on user and system based updates to the file.
google.drive.mime.type The MIME type of the file.
google.drive.lastModifiedBy.displayName A display name of the user that modified the file.
google.drive.lastModifiedBy.email An email of the user that modified the file.
google.drive.permissions.<role>.users A comma-separated list of email addresses for users with the specified role. Valid roles are 'owner', 'organizer', 'fileOrganizer', 'writer', 'commenter', 'reader'. For example, if the owner is [john.doe@gmail.com](mailto:john.doe@gmail.com) and users [jane.doe@gmail.com](mailto:jane.doe@gmail.com) and [jake.doe@gmail.com](mailto:jake.doe@gmail.com) are readers, there would be an attribute named _google.drive.permissions.owner.users_ with the value _john.doe@gmail.com_, and an attribute named _google.drive.permissions.reader.users_ with the value _jane.doe@gmail.com, jake.doe@gmail.com_
google.drive.permissions.<role>.groups A comma-separated list of email addresses for groups with the specified role. Valid roles are 'owner', 'organizer', 'fileOrganizer', 'writer', 'commenter', 'reader'. For example, if the owner is _employees@openflow-all-dev.iam.gserviceaccount.com_ and the group _contractors@openflow-all-dev.iam.gserviceaccount.com_ is a reader, there would be an attribute named _google.drive.permissions.owner.groups_ with the value _employees@openflow-all-dev.iam.gserviceaccount.com_, and an attribute named _google.drive.permissions.reader.groups_ with the value _contractors@openflow-all-dev.iam.gserviceaccount.com_
google.drive.permissions.<role>.domains A comma-separated list of domain names for which all users have the given role. Valid roles are 'owner', 'organizer', 'fileOrganizer', 'writer', 'commenter', 'reader'. For example, if all users in the domain _snowflake.com_ have the role of reader, there would be an attribute named _google.drive.permissions.reader.domains_ with the value _snowflake.com_
google.drive.permissions.<role>.public If a file is shared publicly, this attribute will be added with a value of 'true' for any role that applies to the public.
google.drive.file.path The hierarchical path of the file in Google Drive, e.g. 'parent_folder/child_folder/file.txt'.
Property Description
Authentication Service The service that provides authentication for the SharePoint API
Fallback Retry Duration The time to wait before retrying the operation after a communication failure. This value is used when the response doesn't contain a Retry-After header.
Scopes Description
CLUSTER Stores a delta token for Microsoft365 groups
Name Description
deleted A FlowFile is routed to this relationship for each Microsoft365 group that has been deleted.
updated A FlowFile is routed to this relationship for each Microsoft365 group whose membership has changed.
Name Description
microsoft365.group.id An id of a changed group
microsoft365.group.email An email of the changed group
Property Description
Authentication Service The service that provides authentication for the SharePoint API
Change Capture Initial Action If the Processor is run without having any prior state, this property dictates how the Processor should treat existing Sharepoint items.
Document Library Name The name of the Document Library to list. If not specified, all Document Libraries associated with the Site will be listed.
Fallback Retry Duration The time to wait before retrying the operation after a communication failure. This value is used when the response doesn't contain a Retry-After header.
Fetch Item Permissions If true, the Processor will fetch user and group permission information for the captured Sharepoint item.
Folder Name The name of the Folder/Directory to list
Item Permissions To Fetch A comma-separated list of permission types to fetch for the captured Sharepoint item. Available permission types: USER, GROUP, SITE_USER, SITE_GROUP.
Site URL The URL of the Sharepoint Site that data will be retrieved from.
Scopes Description
CLUSTER Stores tokens for each Sharepoint folder to track state about which events have already been captured.
Name Description
created A FlowFile is routed to this relationship for each Sharepoint item that is created.
deleted A FlowFile is routed to this relationship for each Sharepoint item that is deleted.
updated A FlowFile is routed to this relationship for each Sharepoint item that is updated.
Name Description
sharepoint.change.type The type of change that occurred. Possible values are 'Created', 'Updated', 'PermissionsUpdated', 'Deleted'.
sharepoint.item.id The ID of the Sharepoint item that was changed.
sharepoint.item.type The type of the Sharepoint item that was changed. Possible values are 'File' and 'Folder'.
sharepoint.path The path of the Sharepoint item that was changed. This is the path relative to the root of the Document Library.
sharepoint.filename The name of the Sharepoint item that was changed. This attribute is not available for 'Deleted' changes.
sharepoint.size The size of the Sharepoint item that was changed.
sharepoint.createdAt The creation timestamp of the Sharepoint item that was changed.
sharepoint.lastModified The last modified timestamp of the Sharepoint item that was changed.
sharepoint.createdBy.<identity>.id An id of the identity that created the Sharepoint item that was changed. This attribute is not always available.
sharepoint.createdBy.<identity>.displayName A display name of the identity that created the Sharepoint item that was changed. This attribute is not always available.
sharepoint.createdBy.<identity>.email An email of the identity that created the Sharepoint item that was changed. This attribute is not always available.
sharepoint.lastModifiedBy.<identity>.id An id of the identity that modified the Sharepoint item that was changed. This attribute is not always available.
sharepoint.lastModifiedBy.<identity>.displayName A display name of the identity that modified the Sharepoint item that was changed. This attribute is not always available.
sharepoint.lastModifiedBy.<identity>.email An email of the identity that modified the Sharepoint item that was changed. This attribute is not always available.
sharepoint.drive.id The ID of the Sharepoint Drive that contains the item that was changed.
sharepoint.drive.name The name of the Sharepoint Drive that contains the item that was changed.
sharepoint.site.id The ID of the Sharepoint Site that contains the item that was changed.
sharepoint.site.url The URL of the Sharepoint Site that contains the item that was changed.
sharepoint.ctag The CTag of the Sharepoint item that was changed.
sharepoint.etag The ETag of the Sharepoint item that was changed.
sharepoint.webUrl The browser view url of the Sharepoint item that was changed.
sharepoint.permissions.read.groups A comma-separated list of groups that have read permissions on the Sharepoint item that was changed. For each group, if an e-mail address is available in Sharepoint, it will be included. Additionally, the group principal, such as _mygroup@mytenant.onmicrosoft.com_, is included.
sharepoint.permissions.read.groups.ids A comma-separated list of group IDs that have read permissions on the Sharepoint item.
sharepoint.permissions.read.users A comma-separated list of users that have read permissions on the Sharepoint item that was changed. For each user, if an e-mail address is available in Sharepoint, it will be included. Additionally, the user principal, such as _johndoe@mytenant.onmicrosoft.com_, is included.
sharepoint.permissions.read.users.ids A comma-separated list of Microsoft365 user IDs that have read permissions on the Sharepoint item.
sharepoint.permissions.read.siteusers A comma-separated list of Sharepoint site user emails that have read permissions on the Sharepoint item.
sharepoint.permissions.read.siteusers.ids A comma-separated list of Sharepoint site user IDs that have read permissions on the Sharepoint item.
sharepoint.permissions.read.sitegroups.ids A comma-separated list of Sharepoint site group IDs that have read permissions on the Sharepoint item.
filename The name of the Sharepoint item that was changed. This attribute is not available for 'Deleted' changes.
path The path of the Sharepoint item that was changed. This is the path relative to the root of the Document Library.
mime.type The MIME type of the Sharepoint item that was changed. This attribute is only available for 'File' items.
hash.quickxor The QuickXor hash of the Sharepoint item that was changed. This attribute is not always available.
hash.sha256 The SHA-256 hash of the Sharepoint item that was changed. This attribute is not always available.
hash.sha1 The SHA-1 hash of the Sharepoint item that was changed. This attribute is not always available.
hash.crc32 The CRC32 hash of the Sharepoint item that was changed. This attribute is not always available.
Display Name API Name Default Value Allowable Values Description
Schema Access Strategy * Schema Access Strategy infer-schema - Use 'Schema Name' Property - Use 'Schema Text' Property - Schema Reference Reader - Infer Schema Specifies how to obtain the schema that is to be used for interpreting the data.
Schema Branch Schema Branch Specifies the name of the branch to use when looking up the schema in the Schema Registry property. If the chosen Schema Registry does not support branching, this value will be ignored.
Schema Name Schema Name $\{schema.name\} Specifies the name of the schema to lookup in the Schema Registry property
Schema Reference Reader * Schema Reference Reader Service implementation responsible for reading FlowFile attributes or content to determine the Schema Reference Identifier
Schema Registry Schema Registry Specifies the Controller Service to use for the Schema Registry
Schema Text Schema Text $\{avro.schema\} The text of an Avro-formatted Schema
Schema Version Schema Version Specifies the version of the schema to lookup in the Schema Registry. If not specified then the latest version of the schema will be retrieved.
Accept empty extensions * accept-empty-extensions false - true - false If set to true, empty extensions will be accepted and will be associated to a null value.
DateTime Locale * datetime-representation en-US The IETF BCP 47 representation of the Locale to be used when parsing date fields with long or short month names (e.g. may <en-US> vs. mai. <fr-FR>. The defaultvalue is generally safe. Only change if having issues parsing CEF messages
Inference Strategy * inference-strategy custom-extensions-inferred - Headers only - Headers and extensions - With custom extensions as strings - With custom extensions inferred Defines the set of fields should be included in the schema and the way the fields are being interpreted.
Invalid Field invalid-message-field Used when a line in the FlowFile cannot be parsed by the CEF parser. If set, instead of failing to process the FlowFile, a record is being added with one field. This record contains one field with the name specified by the property and the raw message as value.
Raw Message Field raw-message-field If set the raw message will be added to the record using the property value as field name. This is not the same as the "rawEvent" extension field!
Schema Inference Cache schema-inference-cache Specifies a Schema Cache to use when inferring the schema. If not populated, the schema will be inferred each time. However, if a cache is specified, the cache will first be consulted and if the applicable schema can be found, it will be used instead of inferring the schema.
Property Description
Access Token Token required to request Meta Ads Marketing API. It must match pattern 'Bearer <Access Token Value>'.
Meta Ads API Version Version of Meta Ads API which is used for report generation.
Report ID ID of the generated report.
Web Client Service Provider Service providing client for REST request execution.
Name Description
failure Error FlowFiles transferred when receiving error response from Meta Ads Marketing API or when an error occurred during response processing.
ready Response FlowFiles transferred when receiving Job Completed response from Meta Ads Marketing API.
retry Response FlowFiles transferred when report prepared by Meta Ads Marketing API is not yet ready to be downloaded.
Name Description
meta.ads.report.status Current state of the processed report.
Property Description
Chunk Count Field Name The field name in the record to write the total number of chunks created from the original record.
Chunk Delimiters Specifies a comma-separated list of character sequences. Meta-characters n, r and t are automatically un-escaped. Delimiters are recursively applied in order to chunk the text.
Chunk Index Field Name The field name in the record to write the chunk index.
Chunk Overlap The max number of characters to include from preceding and subsequent chunks.
Chunking Strategy Strategy to chunk text. 'Recursive Delimiters' will chunk text according to the recursive split by character algorithm. In this algorithm input text is split by the first delimiter and merged back into chunks that do not exceed the 'Max Chunk Length'. Any splits that exceed 'Max Chunk Length' are then recursively split using the next delimiter. 'Max Chunk Length' will chunk text by creating chunks that are 'Max Chunk Length' in size.
Language Language to use for parsing sentences.
Max Chunk Length Maximum number of characters to include in output chunk. Setting this number too high can result in an out of memory error.
Record Reader The Record Reader to use for reading the FlowFile.
Record Writer The Record Writer to use for writing the results.
Sentence Similarity Threshold Threshold for determining if two sentences are similar enough to occupy the same chunk. A value of 1.0 indicates the sentences are identical. A value of 0.0 indicates the sentences are completely dissimilar.
Text Record Path The record path to a text field in the record.
Trim Whitespace Trim whitespace surrounding the output text chunk.
Name Description
original The input Flow File is routed to the original relationship.
success Text chunks are routed to the success relationship.
Name Description
chunk.strategy Strategy used to chunk text. One of 'Max Chunk Length', 'Recursive Delimiters', 'Sentence', 'Semantic'.
chunk.semantic.threshold Threshold for determining if two sentences are similar enough to occupy the same chunk. This attribute is added only when the 'Semantic' chunking strategy is used.
chunk.language Language used for parsing sentences. This attribute is added only when the 'Sentence' or 'Semantic' chunking strategy is used.
chunk.delimiters Comma-separated list of delimiters used to chunk text. This attribute is added only when the 'Recursive Delimiters' chunking strategy is used.
chunk.max.chars Maximum number of characters to include in each chunk.
Property Description
Chunk Delimiters Specifies a comma-separated list of character sequences. Meta-characters n, r and t are automatically un-escaped. Delimiters are recursively applied in order to chunk the text.
Chunk Overlap The max number of characters to include from preceding and subsequent chunks.
Chunking Strategy Strategy to chunk text. 'Recursive Delimiters' will chunk text according to the recursive split by character algorithm. In this algorithm input text is split by the first delimiter and merged back into chunks that do not exceed the 'Max Chunk Length'. Any splits that exceed 'Max Chunk Length' are then recursively split using the next delimiter. 'Max Chunk Length' will chunk text by creating chunks that are 'Max Chunk Length' in size.
Language Language to use for parsing sentences.
Max Chunk Length Maximum number of characters to include in output chunk. Setting this number too high can result in an out of memory error.
Sentence Similarity Threshold Threshold for determining if two sentences are similar enough to occupy the same chunk. A value of 1.0 indicates the sentences are identical. A value of 0.0 indicates the sentences are completely dissimilar.
Trim Whitespace Trim whitespace surrounding the output text chunk.
Name Description
failure If any error during parsing occurs, the input Flow File will be routed to the failure relationship.
original The input Flow File is routed to the original relationship.
success Text chunks are routed to the success relationship.
Name Description
segment.original.filename Original filename of the input Flow File.
fragment.identifier ID of the parent Flow File used to generate each chunk.
fragment.index Index of the current Flow File chunk, starting at 0.
fragment.count The total count of Flow File chunks produced.
chunk.start.offsets The chunk.start.offsets attribute is added only to the original incoming FlowFile. It is a comma-separated list of start offsets for each chunk that gets generated. For example, if the FlowFile is chunked into 3 child FlowFiles, it might have a value of _0,183,365_ indicating that the first chunk starts at offset 0, the second chunk starts at offset 183, and the third chunk starts at offset 365. Offsets are based on the number of characters.
chunk.end.offsets The chunk.end.offsets attribute is added only to the original incoming FlowFile. It is a comma-separated list of end offsets for each chunk that gets generated. For example, if the FlowFile is chunked into 3 child FlowFiles, it might have a value of _183,365,548_ indicating that the first chunk ends at offset 183, the second chunk ends at offset 365, and the third chunk ends at offset 548. Offsets are based on the number of characters.
chunk.strategy Strategy used to chunk text. One of 'Max Chunk Length', 'Recursive Delimiters', 'Sentence', 'Semantic'.
chunk.semantic.threshold Threshold for determining if two sentences are similar enough to occupy the same chunk. This attribute is added only when the 'Semantic' chunking strategy is used.
chunk.language Language used for parsing sentences. This attribute is added only when the 'Sentence' or 'Semantic' chunking strategy is used.
chunk.delimiters Comma-separated list of delimiters used to chunk text. This attribute is added only when the 'Recursive Delimiters' chunking strategy is used.
chunk.max.chars Maximum number of characters to include in each chunk.
Property Description
Compression Format The compression format to use. Valid values are: GZIP, Deflate, ZSTD, BZIP2, XZ-LZMA2, LZMA, Brotli, Snappy, Snappy Hadoop, Snappy Framed, and LZ4-Framed
Compression Level The compression level to use; this is valid only when using gzip, deflate or xz-lzma2 compression. A lower value results in faster processing but less compression; a value of 0 indicates no (that is, simple archiving) for gzip or minimal for xz-lzma2 compression. Higher levels can mean much larger memory usage such as the case with levels 7-9 for xz-lzma/2 so be careful relative to heap size.
Mode Indicates whether the processor should compress content or decompress content. Must be either 'compress' or 'decompress'
Update Filename If true, will remove the filename extension when decompressing data (only if the extension indicates the appropriate compression format) and add the appropriate extension when compressing data
Name Description
failure FlowFiles will be transferred to the failure relationship if they fail to compress/decompress
success FlowFiles will be transferred to the success relationship after successfully being compressed or decompressed
Name Description
mime.type If the Mode property is set to compress, the appropriate MIME Type is set. If the Mode property is set to decompress and the file is successfully decompressed, this attribute is removed, as the MIME Type is no longer known.
Approach When to use it
[Configure a connector with the setup wizard](/user-guide/data-integration/openflow/gen2/setup-connector-wizard) Interactive setup with step-by-step validation; best for first-time configuration of connector types that support the setup wizard.
SQL (this topic) Automation, repeat deployments, CI/CD, and bulk connector creation; required for clients that manage Openflow programmatically.
Property Description
Fast Reader Enabled When enabled, uses an optimized reader that improves performance but increases memory usage. Disable if `OutOfMemoryError` occurs during Avro processing.
Cache Size Number of schemas to cache in memory. The default is fine for a few schemas; if a single topic/stream carries **many different schemas** at high throughput, raise it so schemas are not evicted and re-fetched repeatedly --- at the cost of higher memory consumption.
Property Value
Schema Access Strategy `Use 'Schema Text' Property`
Schema Text The full Avro-formatted schema text. Supports Expression Language.
Property Value
Schema Access Strategy `Use Embedded Avro Schema`
Property Value
Schema Registry URLs *(required)* Comma-separated URL(s) of your Confluent Schema Registry, for example, `https://schema-registry.example.com:8081`.
SSL Context Service *(optional)* An `SSLContextService` if the registry requires TLS. Implementations: `StandardSSLContextService`, `StandardRestrictedSSLContextService`, `PEMEncodedSSLContextProvider`.
Communications Timeout *(required)* How long to wait for a response from the registry before failing.
Cache Size *(required)* Number of schemas to cache locally. Raise it when a single topic/stream carries many distinct schemas at high throughput (more memory); the default is fine for a few schemas.
Cache Expiration *(required)* How long cached schemas are valid before being re-fetched.
Authentication Type `NONE` or `BASIC` if the registry requires HTTP Basic authentication.
Username Username for Basic authentication. Only used when **Authentication Type** is `BASIC`.
Password Password for Basic authentication. Sensitive property. Only used when **Authentication Type** is `BASIC`.
Property Value
Schema Access Strategy `Schema Reference Reader`
Schema Reference Reader Select the `ConfluentEncodedSchemaReferenceReader` created above.
Schema Registry Select the `ConfluentSchemaRegistry` created above.
Property Value
Schema Registry Name *(required)* The name of your Glue Schema Registry.
Region *(required)* The AWS region of the registry, for example, `us-west-2`.
AWS Credentials Provider Service Reuse the connector's `AWSCredentialsProviderControllerService` (Kinesis), or create one for MSK.
Cache Size *(required)* Number of schemas to cache locally. Raise for many distinct schemas at high throughput (more memory); the default is fine otherwise.
Cache Expiration *(required)* How long cached schemas are valid before being re-fetched.
Property Value
Schema Access Strategy `Schema Reference Reader`
Schema Reference Reader Select the `AmazonGlueEncodedSchemaReferenceReader` created above.
Schema Registry Select the `AmazonGlueSchemaRegistry` created above.
Property Value
Record Reader Select the `AvroReader` created above.
Symptom Likely cause
`SchemaNotFoundException` at runtime The schema ID in the message is not present in the registry, or the registry URL is misconfigured. Verify **Schema Registry URLs** in `ConfluentSchemaRegistry`.
`InvalidAvroSchemaException` or parse failures The **Schema Text** does not match the actual message schema. Compare the schema in the service with the one used by the producer. Failed messages are routed to the parse-failure relationship (`parse failure` on Kafka, `parse.failure` on Kinesis).
`ConfluentSchemaRegistry` fails to enable Network connectivity issue between the Openflow runtime and the registry. Check the External Access Integration and that the registry URL is reachable from the cluster.
Authentication failure against registry Registry requires Basic auth --- set **Authentication Type** to `BASIC` and provide **Username** and **Password** in `ConfluentSchemaRegistry`.
Property Value
Maximum Cache Size `100` (default is usually sufficient)
Property Value
Schema Inference Cache The `VolatileSchemaCache` created above.
Property Value
Record Reader The existing `JsonTreeReader`.
Record Writer The existing `JsonRecordSetWriter`.
`filtered` *(dynamic)* `SELECT * FROM FLOWFILE WHERE `
Property Value
Record Reader The existing `JsonTreeReader`.
Record Writer The existing `JsonRecordSetWriter`.
Jolt Transform `jolt-transform-chain`
Jolt Specification A Chain spec (see below).
Property Value
`table.name` Kafka: `${kafka.topic:replaceByPattern(#{'Topic To Table Map'})}`
Kinesis: `${aws.kinesis.stream.name:replaceByPattern(#{'Topic To Table Map'})}`
Property Value
Table `${table.name}`
Property Value
Record Reader The existing `JsonTreeReader`.
Record Writer The existing `JsonRecordSetWriter`.
Replacement Value Strategy `record-path-value`
`/field_name` *(dynamic)* `replaceNull(/field_name, 'default_value')`
Property Value
Record Reader The existing `JsonTreeReader`.
Record Writer The existing `JsonRecordSetWriter`.
`` *(dynamic)* `/routing_field`
Property Value
`table.name` `${}`
Property Value
`matched` *(dynamic)* `${table.name:isEmpty():not()}`
Need Pipeline
Route to multiple tables (all values valid) `PartitionRecord` -> Output Port, with `PublishSnowpipeStreaming` **Table** = `${field}`
Route to multiple tables + rename attribute `PartitionRecord` -> `UpdateAttribute` -> Output Port
Route to multiple tables + drop some values `PartitionRecord` -> `UpdateAttribute` -> `RouteOnAttribute` -> Output Port
Symptom Likely cause
Data loss or duplicate data FIFO prioritizer missing on a connection.
Out-of-order delivery Missing FIFO prioritizer on a connection between processors.
Processor shows INVALID A referenced controller service is disabled, or a required property is missing --- enable services first, then re-validate.
Records written to the wrong table `PublishSnowpipeStreaming` **Table** not set to the routing attribute, or `PartitionRecord` / `UpdateAttribute` not setting the expected attribute.
Schema re-inferred on every message (slow) `VolatileSchemaCache` not configured on the `JsonTreeReader` (see [Reader and writer setup](#label-openflow-streaming-custom-transformations-reader-writer)).
Lost `kafka.*` attributes after a Groovy step The script created new FlowFiles without inheriting the incoming attributes.
Field Description
`raw_payload` The original, unparseable bytes captured as a string.
`structured_payload` The parsed JSON record, when available (only for transformation failures).
`error_message` A short description of why the record failed.
`failure_timestamp` UTC timestamp of the failure, stored as `TIMESTAMP_NTZ`.
# Source When Routed to
1 `Consume*` **parse failure** Always RAW branch (unparseable bytes)
2 Custom processor / Custom Transformations failure Only if such components exist **and** you opt into structured handling STRUCTURED branch (or RAW branch if you chose raw-only)
3 Main `PublishSnowpipeStreaming` `failure` / `invalid` Never (out of scope) Left as-is (`failure` = communication errors; `invalid` = at least 1 invalid record)
TO ROLE OPENFLOW__EXECUTE_AS_RL; ``` ### Raw branch (always) Captures any non-JSON / unparseable content into the `raw_payload` string field. This is the **only** branch for a vanilla connector, and the fallback for the structured branch. **Capture the whole payload, not one line at a time.** Reading the failed content line-by-line (for example, a `GrokReader` with **No Match Behavior** = `raw-line`) emits one record **per line**, so a multi-line payload (pretty-printed JSON, multi-line text) is split into many bogus DLQ rows. Capture the **entire FlowFile content** as a single `raw_payload` value instead, using `ExtractText` -> `UpdateAttribute` -> `AttributesToJSON`. This works for any non-JSON content regardless of line breaks. **Step 1 --- Add an `ExtractText` processor** ("Capture Whole Payload"). It copies the entire content into a `raw_payload` attribute, with DOTALL enabled so newlines are included:
For **binary** or very large payloads, use a small `ExecuteGroovyScript` that reads the whole content and writes `{"raw_payload": , ...}` directly instead. **Step 2 --- Add an `UpdateAttribute` processor** ("Add Raw DLQ Metadata"):
**Step 3 --- Add an `AttributesToJSON` processor** ("Build Raw DLQ Envelope"). It writes the envelope to FlowFile content (values are JSON-escaped automatically):
**Step 4 --- Add a `PublishSnowpipeStreaming` processor** ("Ingest Failed Records into DLQ Table"). Reuse the existing PSS auth / web-client service. Point it at the DLQ table:
Auto-terminate `success`, `empty`. Route `failure`, `invalid` to the [DLQ sink failure handling](#label-openflow-streaming-dlq-sink-failure). ### Structured branch (conditional) Build this **only** when custom components exist and you want to preserve the parsed JSON in the `structured_payload` VARIANT column. **Step 1 --- Add a `JoltTransformRecord` processor** ("Move Payload to structured_payload + Add Metadata"). A single processor both shifts the record under `structured_payload` **and** adds the envelope metadata --- the **Jolt Specification** property supports Expression Language:
```text [ {"operation": "shift", "spec": {"*": "structured_payload.&"}}, {"operation": "default", "spec": { "error_message": "pipeline failure", "failure_timestamp": "${now():format('yyyy-MM-dd HH:mm:ss.SSS','UTC')}" }} ] ``` (On Kinesis, set `error_message` to `${record.error.message}` --- see the [Kinesis page](/user-guide/data-integration/openflow/connectors/kinesis/configuring-dead-letter-queue-handling).) This yields the **same envelope fields** as the raw branch (`error_message`, `failure_timestamp`, plus `structured_payload`). Auto-terminate `original`. Route `failure` to the **raw funnel** (fallback: if structuring fails, still capture the bytes). Route `JoltTransformRecord` `success` to the same `PublishSnowpipeStreaming` processor ("Ingest Failed Records into DLQ Table") configured in the raw branch. No separate PSS is needed --- both branches produce the same envelope schema and share the same channel group (`${hostname(false)}.dlq`). ### Funnels and wiring Use **funnels** as merge points so multiple failure sources converge cleanly: - **RAW funnel** --- all unparseable / ser-de-failure sources (the `Consume*` parse-failure relationship, and the structured-branch failures) converge here, then flow into `ExtractText` -> `UpdateAttribute` -> `AttributesToJSON` -> the single `PublishSnowpipeStreaming` ("Ingest Failed Records into DLQ Table"). - **JSON funnel** (only if the structured branch exists) --- custom / transformation failures converge here, then flow into `JoltTransformRecord` -> the same single `PublishSnowpipeStreaming`. For a **raw-only** connector, omit the JSON funnel and structured branch entirely --- every source goes to the RAW funnel. ### DLQ sink failure handling If even the DLQ publish/insert fails, do not lose the record: 1. Route the DLQ sink's `failure`, `invalid` relationships (the `PublishSnowpipeStreaming`, `PublishKafka`, or `PublishKinesis`) to a `LogAttribute` processor ("Log DLQ Ingestion Error", **Log Level** = `error`, with a prefix such as "Failed to ingest data into the DLQ"). 2. Route `LogAttribute` `success` to a **parking-lot funnel** where un-deliverable records accumulate for inspection. ## Route A --- Kafka topic / Kinesis stream This route republishes the failed payload **as-is, with no envelope**, to a messaging destination --- it does not use the DLQ table or the raw/structured branches in [Common setup](#label-openflow-streaming-dlq-common-setup). The publisher and the connection/credentials it reuses are connector-specific, so the steps live on the connector pages: - [Kafka as destination for DLQ messages](/user-guide/data-integration/openflow/connectors/kafka/configuring-dead-letter-queue-handling#label-openflow-kafka-dlq-route-a) - [Kinesis as destination for DLQ messages](/user-guide/data-integration/openflow/connectors/kinesis/configuring-dead-letter-queue-handling#label-openflow-kinesis-dlq-route-a) ## Route B --- Snowflake table This route assembles the building blocks from [Common setup](#label-openflow-streaming-dlq-common-setup) --- the DLQ table, grants, raw/structured branches, and funnels --- with `PublishSnowpipeStreaming` as the terminal sink. It is identical for both connectors. ## Data types and JSONL handling Both sinks consume the same envelope: `PublishSnowpipeStreaming` expects **JSONL** (one JSON object per line), and the stream publishers send that same JSONL content as the message value. Failures arrive in different shapes, so route them through a reader that produces valid records: - **Unparseable / non-JSON** (parse failure): the raw branch's `ExtractText` (DOTALL) captures the **whole payload** --- any text, including multi-line content --- into a single `raw_payload` field. (A line-based reader such as `GrokReader` with **No Match Behavior** = `raw-line` only wraps a single text *line* per record, so it splits multi-line payloads; use the whole-content capture instead.) This is what makes the raw branch robust against malformed input. - **Valid JSON** (downstream / transformation failures): the structured branch's Jolt shift `{"*":"structured_payload.&"}` nests the parsed object under `structured_payload`. On any failure it **falls back to the raw funnel**, so nothing is lost. **Watch for data-type changes along the flow.** A message may be one type at the source (for example, CSV/TSV or a malformed line) and a different type after a downstream mapping. Match the capture to the content **at the point of failure** --- do not feed raw CSV/TSV into a JSON reader. The whole-content raw branch handles this safely for any non-JSON content. ## Verification After wiring, enable all controller services **first** (processors referencing a disabled service show as INVALID), then validate the process group. Fix any validation failures before starting the flow. ## Troubleshooting
For connector-specific symptoms (parse-failure relationship name, publishing to a topic/stream), see the [Kafka](/user-guide/data-integration/openflow/connectors/kafka/configuring-dead-letter-queue-handling) and [Kinesis](/user-guide/data-integration/openflow/connectors/kinesis/configuring-dead-letter-queue-handling) troubleshooting tables. --- title: Configuring Private Key Authentication for Snowflake source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/streaming/configuring-private-key-authentication.md section: Loading & Unloading Data --- This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [Snowflake Openflow Connector for Kafka](/user-guide/data-integration/openflow/connectors/kafka/about) - [Openflow Connector for Kinesis Data Streams](/user-guide/data-integration/openflow/connectors/kinesis/about) - [StandardPrivateKeyService](/user-guide/data-integration/openflow/controllers/standardprivatekeyservice) - [Key-pair authentication and key-pair rotation](/en/user-guide/key-pair-auth) # Configuring Private Key Authentication for Snowflake The Kafka and Kinesis high-performance connectors use `PublishSnowpipeStreaming` to write data to Snowflake. By default they authenticate using `SNOWFLAKE_MANAGED` (session token). This page describes how to switch to key-pair authentication using an RSA private key. `SNOWFLAKE_MANAGED` is the recommended authentication strategy for both SPCS and BYOC deployments. Use Private Key authentication only when managed authentication is not suitable for your environment. The steps below apply identically to the Kafka and Kinesis high-performance connectors. ## Prerequisites ### Generate an RSA key pair and assign it to a Snowflake user Follow the official Snowflake guide to generate a key pair and assign the public key to your user: [Key-pair authentication and key-pair rotation](/en/user-guide/key-pair-auth). Both encrypted and unencrypted private keys are supported. If you generate an encrypted key (with a passphrase), set the **Key Password** property on the `StandardPrivateKeyService` controller service. The resulting `rsa_key.p8` file must begin with the header `-----BEGIN PRIVATE KEY-----` (unencrypted) or `-----BEGIN ENCRYPTED PRIVATE KEY-----` (encrypted). ## Step 1: Add a StandardPrivateKeyService controller service 1. Open the connector's process group in the Openflow / NiFi UI. 2. Select **Configure** \> **Controller Services** (gear icon). 3. Select **+** to add a new controller service. 4. Search for and select [StandardPrivateKeyService](/user-guide/data-integration/openflow/controllers/standardprivatekeyservice). 5. Select **Add**. ## Step 2: Upload the private key file 1. In the controller services list, select the **Edit** (pencil) icon on `StandardPrivateKeyService`. 2. Locate the **Key File** property. 3. Enable the **Reference asset** checkbox next to the field. 4. Select **Upload** and select your `rsa_key.p8` file. Openflow stores the file as an asset on the cluster so the key is never exposed in plain text in the configuration. 5. Leave **Key Password** blank for an unencrypted key, or provide the passphrase for an encrypted key. 6. Select **Apply**. ## Step 3: Enable the controller service Select the **Enable** (lightning bolt) icon on `StandardPrivateKeyService` and wait until its status shows **Enabled**. ## Step 4: Configure PublishSnowpipeStreaming 1. Double-click the `PublishSnowpipeStreaming` processor to open its properties. 2. Set the following properties:
**Account identifier format:** Use the organization-and-account format `-`, not the full hostname. For example, if your Snowflake URL is `https://myorg-myaccount.snowflakecomputing.cn`, the account identifier is `myorg-myaccount`. 3. Select **Apply**. 4. Start the process group. ## Property reference The [StandardPrivateKeyService](/user-guide/data-integration/openflow/controllers/standardprivatekeyservice) controller service accepts the following properties:
## Troubleshooting
--- title: Configuring Protobuf data type ingestion source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/streaming/configuring-protobuf-data-type-ingestion.md section: Loading & Unloading Data --- This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [Snowflake Openflow Connector for Kafka](/user-guide/data-integration/openflow/connectors/kafka/about) - [Openflow Connector for Kinesis Data Streams](/user-guide/data-integration/openflow/connectors/kinesis/about) - [Configuring Avro data type ingestion](configuring-avro-data-type-ingestion) - [Configuring custom transformations](configuring-custom-transformations) - [Configuring Dead Letter Queue (DLQ) handling](configuring-dead-letter-queue-handling) # Configuring Protobuf data type ingestion The streaming connectors (Kafka high-performance, Kinesis high-performance) use a `Consume*` processor (`ConsumeKafka` / `ConsumeKinesis`) with a `JsonTreeReader` controller service to parse incoming messages. This topic describes how to switch to Protobuf-encoded messages by replacing `JsonTreeReader` with a `StandardProtobufReader`. The steps are identical for both connectors --- on a Kinesis connector, use the `ConsumeKinesis` processor where `ConsumeKafka` is referenced. You don't have to apply this customization by hand. The **Openflow skill in Snowflake CoCo** can perform it for you --- describe the change you want and it edits the flow following the steps on this page. We recommend using the skill instead of configuring the components manually. AWS Glue Schema Registry is **not** supported for Protobuf in these connectors. Use inline schema text or Confluent Schema Registry below. Three schema access strategies are supported: - **Inline schema text** --- you provide the Proto 3 schema directly in the service configuration. - **Schema name** --- the schema name is resolved against a configured `SchemaRegistry` service (for example, `ConfluentSchemaRegistry`). - **Schema reference reader** --- the schema ID is read from the message using `ConfluentEncodedSchemaReferenceReader` and resolved against a `ConfluentSchemaRegistry`. This is the standard strategy for Confluent wire-format encoded messages. In addition, because a single `.proto` file can define multiple message types, you must also configure how the correct message name is resolved: - **Message name property** --- you specify the fully qualified message name (including package) directly as a parameter, for example, `mypackage.MyMessage`. - **Message name resolver** --- the message name is resolved dynamically from the FlowFile content or attributes using a `MessageNameResolver` service. `ConfluentProtobufMessageNameResolver` resolves the name by decoding message indexes from the Confluent wire format and looking up the fully qualified name in the schema definition. ## Prerequisites - You have an existing **Kafka high-performance** or **Kinesis high-performance** connector deployed in Openflow. - Your Kafka topics / Kinesis stream produce **Protobuf-encoded messages**. - If using Confluent Schema Registry: you have the registry URL and network access to it from the Openflow runtime. For Snowflake-managed deployments (SPCS), a proper [External Access Integration](/developer-guide/external-network-access/external-network-access-overview) must be configured and assigned to the runtime to allow outbound connections to the registry. ## Configure Protobuf data type ingestion The steps below apply identically to the **Kafka high-performance** and **Kinesis high-performance** connectors (on a Kinesis connector, use the `ConsumeKinesis` processor where `ConsumeKafka` is referenced). ### Step 1: Create the StandardProtobufReader controller service 1. Open the connector's process group in the Openflow UI. 2. Go to **Configure** > **Controller Services** (gear icon). 3. Select **+** to add a new controller service. 4. Search for and select `StandardProtobufReader` (`org.apache.nifi.services.protobuf.StandardProtobufReader`). 5. Select **Add**. ### Step 2: Configure the schema access strategy in StandardProtobufReader In the `StandardProtobufReader` controller service created in Step 1, configure the schema access strategy and the message name resolution strategy. Choose the combination that matches how your Protobuf schema and message type are distributed. #### Option A --- Inline schema text with message name property Use this when you have the Proto 3 schema as a text string and the message name does not change at runtime. 1. Select the **Edit** (gear) icon on the `StandardProtobufReader` service. 2. Set the following properties:
3. Select **Apply**. #### Option B --- Confluent Schema Registry with Confluent message name resolver Use this when messages are encoded with the Confluent wire format (magic byte `0x00` followed by a 4-byte schema ID) and the message name should be resolved automatically. Three additional controller services are required: - `ConfluentSchemaRegistry` --- resolves the schema ID to the actual Proto 3 schema. - `ConfluentEncodedSchemaReferenceReader` --- reads the schema ID from each message. - `ConfluentProtobufMessageNameResolver` --- resolves the message name by decoding message indexes from the Confluent wire format and looking up the fully qualified name in the schema definition. **Create the ConfluentSchemaRegistry controller service:** 1. Go to **Configure** > **Controller Services**. 2. Select **+** and search for `ConfluentSchemaRegistry` (`org.apache.nifi.confluent.schemaregistry.ConfluentSchemaRegistry`). 3. Select **Add**. 4. Select the **Edit** (gear) icon and set the following properties:
5. Select **Apply**. 6. Select the **Enable** (lightning bolt) icon and wait until the status shows **Enabled**. **Create the ConfluentEncodedSchemaReferenceReader controller service:** 1. Go to **Configure** > **Controller Services**. 2. Select **+** and search for `ConfluentEncodedSchemaReferenceReader` (`org.apache.nifi.confluent.schemaregistry.ConfluentEncodedSchemaReferenceReader`). 3. Select **Add**. 4. Select the **Enable** icon and wait until the status shows **Enabled**. `ConfluentEncodedSchemaReferenceReader` has no configurable properties. It simply reads the Confluent-encoded schema ID (magic byte `0x00` + 4-byte integer) from the beginning of each message. **Create the ConfluentProtobufMessageNameResolver controller service:** 1. Go to **Configure** > **Controller Services**. 2. Select **+** and search for `ConfluentProtobufMessageNameResolver` (`org.apache.nifi.confluent.schemaregistry.ConfluentProtobufMessageNameResolver`). 3. Select **Add**. 4. Select the **Enable** icon and wait until the status shows **Enabled**. `ConfluentProtobufMessageNameResolver` has no configurable properties. It decodes the message index sequence embedded in the Confluent Protobuf wire format to determine the fully qualified message name. For details on the wire format, see the Confluent Schema Registry documentation (https://docs.confluent.io/platform/current/schema-registry/fundamentals/serdes-develop/index.html#wire-format). **Configure StandardProtobufReader to use the schema reference reader and message name resolver:** 1. Select the **Edit** (gear) icon on the `StandardProtobufReader` service created in Step 1. 2. Set the following properties:
3. Select **Apply**. ### Step 3: Enable the StandardProtobufReader controller service Select the **Enable** (lightning bolt) icon on `StandardProtobufReader` and wait until its status shows **Enabled**. ### Step 4: Update the source processor 1. Double-click the `ConsumeKafka` processor (or `ConsumeKinesis` on a Kinesis connector) to open its properties. 2. Update the following property:
3. Select **Apply**. ### Step 5: Disable the JsonTreeReader controller service The original `JsonTreeReader` is no longer needed. 1. Stop the process group if it is running. 2. Go to **Configure** > **Controller Services**. 3. Select the **Disable** icon on `JsonTreeReader`. 4. If the service is not referenced by any other processor, you can also delete it by selecting the **Delete** (trash) icon. 5. Start the process group. ## Troubleshooting
--- title: ConfluentEncodedSchemaReferenceReader source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/confluentencodedschemareferencereader.md section: Loading & Unloading Data --- # ConfluentEncodedSchemaReferenceReader This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Reads Schema Identifier according to Confluent encoding as a header consisting of a byte marker and an integer represented as four bytes ## Tags avro, confluent, kafka, registry, schema ## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: ConfluentEncodedSchemaReferenceWriter source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/confluentencodedschemareferencewriter.md section: Loading & Unloading Data --- # ConfluentEncodedSchemaReferenceWriter This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Writes Schema Identifier according to Confluent encoding as a header consisting of a byte marker and an integer represented as four bytes ## Tags avro, confluent, kafka, registry, schema ## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: ConfluentProtobufMessageNameResolver source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/confluentprotobufmessagenameresolver.md section: Loading & Unloading Data --- # ConfluentProtobufMessageNameResolver This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Resolves Protobuf message names from Confluent Schema Registry wire format by decoding message indexes and looking up the fully qualified name in the schema definition For Confluent wire format reference see: https://docs.confluent.io/platform/current/schema-registry/fundamentals/serdes-develop/index.html#wire-format (https://docs.confluent.io/platform/current/schema-registry/fundamentals/serdes-develop/index.html#wire-format) ## Tags confluent, message, name, protobuf, registry, resolver, schema ## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: ConfluentSchemaRegistry source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/confluentschemaregistry.md section: Loading & Unloading Data --- # ConfluentSchemaRegistry This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides a Schema Registry that interacts with the Confluent Schema Registry so that those Schemas that are stored in the Confluent Schema Registry can be used in NiFi. The Confluent Schema Registry has a notion of a "subject" for schemas, which is their terminology for a schema name. When a Schema is looked up by name by this registry, it will find a Schema in the Confluent Schema Registry with that subject. ## Tags avro, confluent, kafka, registry, schema ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: Connect to MongoDB source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/mongodb/connect.md section: Loading & Unloading Data --- # Connect to MongoDB This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About the Openflow Connector for MongoDB](/user-guide/data-integration/openflow/connectors/mongodb/about) - [Set up the Openflow Connector for MongoDB](/user-guide/data-integration/openflow/connectors/mongodb/setup) - [Use the Openflow Connector for MongoDB](/user-guide/data-integration/openflow/connectors/mongodb/use) This topic describes how to configure the source MongoDB database and the target Snowflake account for the %mongodbof%. ## Set up the source MongoDB database The connector requires a MongoDB deployment running as either a Replica Set or a Sharded Cluster. This architecture ensures high availability and enables the use of Change Streams, which the connector uses to track and sync data changes in real time. To configure the MongoDB environment, perform the following steps: 1. Configure a basic Replica Set. Ensure all nodes have the same `replSetName` in their `mongod.conf` as shown in the following example: ```yaml replication: replSetName: "myReplicaSet" ``` 2. Initialize the replica set. Run this command in the `mongosh` console. In this example, the replica set consists of two nodes: ```javascript rs.initiate({ _id: "myReplicaSet", members: [ { _id: 0, host: "10.11.98.246:27017", }, { _id: 1, host: "10.11.104.58:27017", }, ], }); ``` 3. Create a dedicated database user. The connector opens a cluster-level Change Stream, which requires the `readAnyDatabase` role on the `admin` database. Create the user with the following role by running the following command in the `mongosh` console: ```javascript use admin db.createUser( { user: "openflowUser", pwd: "yourSecurePassword", roles: [ { role: "readAnyDatabase", db: "admin" } ] } ); ``` The `readAnyDatabase` role is required because the connector currently monitors change events at the cluster level. Database-scoped Change Stream support, which would allow a narrower `read` role on a specific database, is not currently supported. When configuring the connector, set **MongoDB Authentication Source** to `admin`. For more information, see [MongoDB source parameters](setup#label-mongodb-source-parameters). ## Set up the target Snowflake account To set up the target Snowflake account, perform the following steps: 1. Create a Snowflake user. Create a Snowflake user with the type as SERVICE. ```sql USE ROLE USERADMIN; CREATE USER TYPE=SERVICE COMMENT='Service user for Openflow automation'; ``` Store the private key for that user in a file to supply to the connector's configuration. For more information, see [key-pair authentication](/user-guide/key-pair-auth). ```sql ALTER USER SET RSA_PUBLIC_KEY = ''; ``` 2. Create a database. Create a database that stores the replicated data, and set up permissions for the Snowflake user to create objects in that database by granting USAGE and CREATE SCHEMA privileges. ```sql USE ROLE ACCOUNTADMIN; CREATE DATABASE IF NOT EXISTS ; GRANT USAGE ON DATABASE TO USER ; GRANT CREATE SCHEMA ON DATABASE TO USER ; ``` 3. Create a new warehouse or use an existing warehouse for the connector. To create a new warehouse, perform the following steps:
```sql CREATE WAREHOUSE WITH WAREHOUSE_SIZE = 'MEDIUM' AUTO_SUSPEND = 300 AUTO_RESUME = TRUE; GRANT USAGE, OPERATE ON WAREHOUSE TO USER ; ```
- Start with the MEDIUM warehouse size, then experiment with size depending on the number of tables being replicated and the amount of data transferred. - To determine if you should increase, monitor the connector and database while data replication is in progress. If you observe significant delays during incremental replication, experiment with a larger warehouse size. However, large table numbers typically scale better using [multi-cluster warehouses](/user-guide/warehouses-multicluster) instead of increasing the warehouse size. ## Next steps After setting up the source MongoDB database and the target Snowflake account, [Set up the connector](/user-guide/data-integration/openflow/connectors/mongodb/setup). --- title: Connect to Workday and query data from Snowflake source: https://docs.snowflake.cn/en/user-guide/data-integration/zero-copy/workday/connect-and-query.md section: Loading & Unloading Data --- # Connect to Workday and query data from Snowflake Available to all accounts. - [About Workday Live Data Query for Snowflake](/user-guide/data-integration/zero-copy/about-workday-ldq) - [Set up Snowflake for Workday Live Data Query](/user-guide/data-integration/zero-copy/workday/snowflake-setup) - [Use Cortex Code with Workday data](/user-guide/data-integration/zero-copy/workday/cortex-code) - [Troubleshoot Workday Live Data Query](/user-guide/data-integration/zero-copy/workday/troubleshooting) Workday Live Data Query for Snowflake is in Early Adopter (EA) for Workday and in Preview for Snowflake. To request access, contact your Workday account representative. This topic describes how to create a Snowflake Notebook, install the Workday Python connector, configure credentials, and run queries against Workday data. Complete [Set up Snowflake for Workday Live Data Query](/user-guide/data-integration/zero-copy/workday/snowflake-setup) before starting this topic. ## Step 1: Create a notebook Create a new Python notebook in a Snowflake Workspace. All LDQ connection and query code runs here. 1. In Snowsight, navigate to **Workspaces**. 2. Open an existing workspace or click **+ Workspace** to create one. 3. Inside the workspace, click **+** > **Notebook**. ## Step 2: Attach the external access integration The notebook needs explicit permission to make outbound calls to Workday. Attach the `WORKDAY_LDQ_TEST_EAI` integration created in [Set up Snowflake for Workday Live Data Query](/user-guide/data-integration/zero-copy/workday/snowflake-setup). 1. Open your notebook. 2. Click the dropdown arrow next to **Connected** at the top of the notebook. 3. In the service details panel, check **Enabled External Access Integrations (EAIs)**. If `WORKDAY_LDQ_TEST_EAI` isn't listed, click **Manage service** to add it. If you don't see it there either, click **+ Create new service** to create a new service and attach the EAI. 4. Restart the notebook session if prompted. Without the EAI attached, all outbound HTTP calls to Workday will fail with a network error. ## Step 3: Install the Python connector Install the `workday_ldq` package from your stage into the notebook's runtime environment. This makes the `DataServiceConfig` and `create_connection` APIs available. The installation is per-session and must be re-run after each notebook restart. The connector's dependencies (for example, `trino`, `requests`, `lz4`) aren't bundled: `pip` downloads them from PyPI automatically, which is why the network rule includes `pypi.org` and `files.pythonhosted.org`. In the **first cell** of your notebook, run: ```python from snowflake.snowpark.context import get_active_session session = get_active_session() # Replace with the correct wheel filename session.file.get( "@WORKDAY_LDQ_TEST.LIVEDATA.LDQ_STAGE/ldq_python_client-1.0.3-py3-none-any.whl", "/tmp" ) subprocess.check_call([ sys.executable, "-m", "pip", "install", "/tmp/ldq_python_client-1.0.3-py3-none-any.whl", "--quiet" ]) print("Wheel installed successfully!") ``` The wheel doesn't persist across notebook restarts. Re-run this cell every time you restart or reconnect the notebook. Keep it as the very first cell so it always runs first. ## Step 4: Configure credentials The connector accepts credentials as an in-memory dictionary via `DataServiceConfig()`. The private key is retrieved at runtime from a Snowflake Secret using a temporary UDF. The key is never written to disk or persisted in the notebook. In a notebook cell, run: ```python from snowflake.snowpark.context import get_active_session from snowflake.snowpark.functions import udf from workday_ldq import DataServiceConfig session = get_active_session() session.sql("USE DATABASE WORKDAY_LDQ_TEST").collect() session.sql("USE SCHEMA LIVEDATA").collect() @udf( name="get_secret_temp", is_permanent=False, replace=True, external_access_integrations=["WORKDAY_LDQ_TEST_EAI"], secrets={"pk": "WORKDAY_LDQ_TEST.LIVEDATA.WORKDAY_PRIVATE_KEY"} ) def get_secret_temp() -> str: import _snowflake return _snowflake.get_generic_secret_string("pk") private_key_pem = session.sql("SELECT get_secret_temp()").collect()[0][0] config = DataServiceConfig({ "wd.authn.clientId": "", "wd.authn.isu": "", "wd.authn.accessTokenEndpoint": "https:///ccx/oauth2//token", "wd.authn.privateKey": private_key_pem, "wd.host": "", "wd.port": "443" }) del private_key_pem session.sql("DROP FUNCTION IF EXISTS get_secret_temp()").collect() print("Config created successfully!") ``` Replace the placeholder values with those provided by your Workday administrator.
Workspace notebooks can't directly access Snowflake Secrets via `_snowflake` or `st.secrets`. The temporary UDF runs inside the Snowflake execution environment (where `_snowflake` is available), retrieves the secret, and returns it to the notebook session. The UDF is dropped immediately after use, and the private key is cleared from memory with `del`. The key is never written to disk. If your Snowflake environment routes traffic through a proxy, set `wd.host` to `` and update `wd.authn.accessTokenEndpoint` to point to the proxy's token endpoint. ## Step 5: Connect and run queries ### Connect to the Workday LDQ service Open a connection using the `config` object. A successful connection confirms that authentication, networking, and configuration are all correct. ```python from workday_ldq import create_connection connection = create_connection(config) print("Connected successfully!") ``` ### Run a query Use a cursor to send SQL to the Workday data service. Queries run against Workday's Unified Data Catalog, not Snowflake tables. ```python cursor = connection.cursor() cursor.execute("SELECT COUNT(*) FROM workday_core.public.worker") results = cursor.fetchall() print(results) cursor.close() ``` ### Load results into a DataFrame ```python cursor = connection.cursor() cursor.execute("SELECT * FROM workday_core.public.worker LIMIT 100") columns = [desc[0] for desc in cursor.description] rows = cursor.fetchall() df = pd.DataFrame(rows, columns=columns) cursor.close() df.head() ``` ### Close the connection Always close the connection when you're finished to release resources on both the Snowflake and Workday sides. ```python connection.close() ``` ## Sample queries These queries target Workday data, not Snowflake tables, and must be run through the LDQ connector. Paste each query string into a `cursor.execute()` call as shown above, not directly in a Snowflake Worksheet. The examples below use `workday_core.public` as the catalog and schema. Your environment may use different names. Always run the discovery queries first to confirm what's available in your tenant. ### Discover available catalogs and schemas ```sql SHOW CATALOGS ``` ```sql SHOW SCHEMAS IN workday_core ``` ```sql SHOW TABLES IN workday_core.public ``` ### Count all workers ```sql SELECT COUNT(*) AS total_workers FROM workday_core.public.worker ``` ### List active workers with job titles ```sql SELECT w.worker_id, w.full_name, w.employee_type, jp.job_title FROM workday_core.public.worker w JOIN workday_core.public.job_profile jp ON w.job_profile_id = jp.job_profile_id WHERE w.active = TRUE LIMIT 50 ``` ### Headcount by management level ```sql SELECT management_level, COUNT(*) AS headcount FROM workday_core.public.worker WHERE active = TRUE GROUP BY management_level ORDER BY headcount DESC ``` ### Workers hired in the last 90 days ```sql SELECT worker_id, full_name, hire_date, business_title FROM workday_core.public.worker WHERE hire_date >= CURRENT_DATE - INTERVAL '90' DAY ORDER BY hire_date DESC ``` In EA, available objects are limited to Workforce and Talent. Row-level security controls are planned for GA. Table and column-level access is controlled by the ISU's security group in Workday. ## Next steps With data in a DataFrame, you can use [Cortex Code](/user-guide/data-integration/zero-copy/workday/cortex-code) to write queries, build visualizations, and get AI-assisted analysis of your Workday data. --- title: ConnectWebSocket 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/connectwebsocket.md section: Loading & Unloading Data --- # ConnectWebSocket 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-websocket-processors-nar ## Description Acts as a WebSocket client endpoint to interact with a remote WebSocket server. FlowFiles are transferred to downstream relationships according to received message types as WebSocket client configured with this processor receives messages from remote WebSocket server. If a new flowfile is passed to the processor, the previous sessions will be closed and any data being sent will be aborted. ## Tags WebSocket, consume, listen, subscribe ## Input Requirement ALLOWED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: ConsumeAMQP 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/consumeamqp.md section: Loading & Unloading Data --- # ConsumeAMQP 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-amqp-nar ## Description Consumes AMQP Messages from an AMQP Broker using the AMQP 0.9.1 protocol. Each message that is received from the AMQP Broker will be emitted as its own FlowFile to the 'success' relationship. ## Tags amqp, consume, get, message, rabbit, receive ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: ConsumeAzureEventHub 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/consumeazureeventhub.md section: Loading & Unloading Data --- # ConsumeAzureEventHub 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-azure-nar ## Description Receives messages from Microsoft Azure Event Hubs with checkpointing to ensure consistent event processing. Checkpoint tracking avoids consuming a message multiple times and enables reliable resumption of processing in the event of intermittent network failures. Checkpoint tracking requires external storage and provides the preferred approach to consuming messages from Azure Event Hubs. In clustered environment, ConsumeAzureEventHub processor instances form a consumer group and the messages are distributed among the cluster nodes (each message is processed on one cluster node only). ## Tags azure, cloud, eventhub, events, microsoft, streaming, streams ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
--- title: ConsumeBoxEnterpriseEvents 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/consumeboxenterpriseevents.md section: Loading & Unloading Data --- # ConsumeBoxEnterpriseEvents 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-box-nar ## Description Consumes Enterprise Events from Box admin_logs_streaming Stream Type. The content of the events is sent to the 'success' relationship as a JSON array. The last known position of the Box stream is stored in the processor state and is used to resume the stream from the last known position when the processor is restarted. ## Tags box, storage ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## See also - [org.apache.nifi.processors.box.ConsumeBoxEvents](/user-guide/data-integration/openflow/processors/consumeboxevents) - [org.apache.nifi.processors.box.FetchBoxFile](/user-guide/data-integration/openflow/processors/fetchboxfile) - [org.apache.nifi.processors.box.ListBoxFile](/user-guide/data-integration/openflow/processors/listboxfile) --- title: ConsumeBoxEvents 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/consumeboxevents.md section: Loading & Unloading Data --- # ConsumeBoxEvents 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-box-nar ## Description Consumes all events from Box. This processor can be used to capture events such as uploads, modifications, deletions, etc. The content of the events is sent to the 'success' relationship as a JSON array. Events can be dropped in case of NiFi restart or if the queue capacity is exceeded. The last known position of the Box stream is stored in the processor state and is used to resume the stream from the last known position when the processor is restarted. ## Tags box, storage ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## See also - [org.apache.nifi.processors.box.FetchBoxFile](/user-guide/data-integration/openflow/processors/fetchboxfile) - [org.apache.nifi.processors.box.ListBoxFile](/user-guide/data-integration/openflow/processors/listboxfile) - [org.apache.nifi.processors.box.PutBoxFile](/user-guide/data-integration/openflow/processors/putboxfile) --- title: ConsumeElasticsearch 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/consumeelasticsearch.md section: Loading & Unloading Data --- # ConsumeElasticsearch 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-elasticsearch-restapi-nar ## Description A processor that repeatedly runs a paginated query against a field using a Range query to consume new Documents from an Elasticsearch index/query. The processor will retrieve multiple pages of results until either no more results are available or the Pagination Keep Alive expiration is reached, after which the Range query will automatically update the field constraint based on the last retrieved Document value. ## Tags elasticsearch, elasticsearch7, elasticsearch8, elasticsearch9, json, page, query, scroll, search ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.elasticsearch.PaginatedJsonQueryElasticsearch](/user-guide/data-integration/openflow/processors/paginatedjsonqueryelasticsearch) - [org.apache.nifi.processors.elasticsearch.SearchElasticsearch](/user-guide/data-integration/openflow/processors/searchelasticsearch) --- title: ConsumeGCPubSub 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/consumegcpubsub.md section: Loading & Unloading Data --- # ConsumeGCPubSub 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-gcp-nar ## Description Consumes messages from the configured Google Cloud PubSub subscription. The 'Batch Size' property specified the maximum number of messages that will be pulled from the subscription in a single request. The 'Processing Strategy' property specifies if each message should be its own FlowFile or if messages should be grouped into a single FlowFile. Using the Demarcator strategy will provide best throughput when the format allows it. Using Record lets you convert data format as well as doing schema enforcement. Using the FlowFile strategy will generate one FlowFile per message and will have the message's attributes as FlowFile attributes. ## Tags consume, gcp, google, google-cloud, message, pubsub ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.gcp.pubsub.PublishGCPubSub](/user-guide/data-integration/openflow/processors/publishgcpubsub) --- title: ConsumeIMAP 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/consumeimap.md section: Loading & Unloading Data --- # ConsumeIMAP 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-email-nar ## Description Consumes messages from Email Server using IMAP protocol. The raw-bytes of each received email message are written as contents of the FlowFile ## Tags Consume, Email, Get, Imap, Ingest, Ingress, Message ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: ConsumeJMS 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/consumejms.md section: Loading & Unloading Data --- # ConsumeJMS 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-jms-processors-nar ## Description Consumes JMS Message of type BytesMessage, TextMessage, ObjectMessage, MapMessage or StreamMessage transforming its content to a FlowFile and transitioning it to 'success' relationship. JMS attributes such as headers and properties will be copied as FlowFile attributes. MapMessages will be transformed into JSONs and then into byte arrays. The other types will have their raw contents as byte array transferred into the flowfile. ## Tags consume, get, jms, message, receive ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Restrictions
## Relationships
## Writes attributes
## See also - [org.apache.nifi.jms.processors.PublishJMS](/user-guide/data-integration/openflow/processors/publishjms) --- title: ConsumeKafka 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/consumekafka.md section: Loading & Unloading Data --- # ConsumeKafka 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-kafka-nar ## Description Consumes messages from Apache Kafka Consumer API. The complementary NiFi processor for sending messages is PublishKafka. The Processor supports consumption of Kafka messages, optionally interpreted as NiFi records. Please note that, at this time (in read record mode), the Processor assumes that all records that are retrieved from a given partition have the same schema. For this mode, if any of the Kafka messages are pulled but cannot be parsed or written with the configured Record Reader or Record Writer, the contents of the message will be written to a separate FlowFile, and that FlowFile will be transferred to the 'parse.failure' relationship. Otherwise, each FlowFile is sent to the 'success' relationship and may contain many individual messages within the single FlowFile. A 'record.count' attribute is added to indicate how many messages are contained in the FlowFile. No two Kafka messages will be placed into the same FlowFile if they have different schemas, or if they have different values for a message header that is included by the <Headers to Add as Attributes> property. ## Tags avro, consume, csv, get, ingest, ingress, json, kafka, openflow, pubsub, record, topic ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [com.snowflake.openflow.runtime.processors.kafka.PublishKafka](/user-guide/data-integration/openflow/processors/publishkafka) --- title: ConsumeKinesisStream 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/consumekinesisstream.md section: Loading & Unloading Data --- # ConsumeKinesisStream 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-aws-nar ## Description Reads data from the specified AWS Kinesis stream and outputs a FlowFile for every processed Record (raw) or a FlowFile for a batch of processed records if a Record Reader and Record Writer are configured. At-least-once delivery of all Kinesis Records within the Stream while the processor is running. AWS Kinesis Client Library can take several seconds to initialise before starting to fetch data. Uses DynamoDB for check pointing and CloudWatch (optional) for metrics. Ensure that the credentials provided have access to DynamoDB and CloudWatch (optional) along with Kinesis. ## Tags amazon, aws, consume, kinesis, stream ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.aws.kinesis.stream.PutKinesisStream](/user-guide/data-integration/openflow/processors/putkinesisstream) --- title: ConsumeMQTT 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/consumemqtt.md section: Loading & Unloading Data --- # ConsumeMQTT 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-mqtt-nar ## Description Subscribes to a topic and receives messages from an MQTT broker ## Tags IOT, MQTT, consume, listen, subscribe ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.mqtt.PublishMQTT](/user-guide/data-integration/openflow/processors/publishmqtt) --- title: ConsumePOP3 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/consumepop3.md section: Loading & Unloading Data --- # ConsumePOP3 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-email-nar ## Description Consumes messages from Email Server using POP3 protocol. The raw-bytes of each received email message are written as contents of the FlowFile ## Tags Consume, Email, Get, Ingest, Ingress, Message, POP3 ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: ConsumeSlack 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/consumeslack.md section: Loading & Unloading Data --- # ConsumeSlack 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-slack-nar ## Description Retrieves messages from one or more configured Slack channels. The messages are written out in JSON format. See Usage / Additional Details for more information about how to configure this Processor and enable it to retrieve messages from Slack. ## Tags conversation, conversation.history, slack, social media, team, text, unstructured ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.slack.ListenSlack](/user-guide/data-integration/openflow/processors/listenslack) --- title: ConsumeSlackConversation 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/consumeslackconversation.md section: Loading & Unloading Data --- # ConsumeSlackConversation 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-slack-processors-nar ## Description Retrieves messages from Slack conversations available to the App. New conversations are fetched based on the 'Reply Monitor Frequency'. Ingested messages are written out in JSON format. See Usage / Additional Details for more information about how to configure this Processor and enable it to retrieve messages from Slack. ## Tags conversation, conversation.history, slack, social media, team, text, unstructured ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
--- title: ConsumeSlackHistory 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/consumeslackhistory.md section: Loading & Unloading Data --- # ConsumeSlackHistory 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-slack-processors-nar ## Description Fetches historical messages from all Slack channels available to the App. This processor queries Slack's conversations.history and conversations.replies to retrieve older messages and outputs the result as records. The processor tracks the earliest retrieved message timestamp in the cluster state to allow it to continue the historical load on subsequent executions. Channels are discovered automatically, no channel ID or name needs to be configured. ## Tags consume, conversation, history, slack ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
--- title: ConsumeSnowflakeStream 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/consumesnowflakestream.md section: Loading & Unloading Data --- # ConsumeSnowflakeStream 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-snowflake-processors-nar ## Description Fetches data from a Snowflake stream and writes it to a FlowFile. The stream must be created in the database before using this processor. The processor will consume the stream and write the records to the FlowFile using the specified Record Writer. The processor will also add an attribute to the FlowFile with the name of the stream. The processor will not work if the stream is stale. Instead it will log an error message and stop processing. Stale stream has to be recreated in the database. After the stream is recreated in the database the processor will continue to read and process CDC records. For more information on Snowflake streams, see the <a href="[https://docs.snowflake.cn/en/user-guide/streams-intro](https://docs.snowflake.cn/en/user-guide/streams-intro)">snowflake documentation</a>. ## Tags connection, database, jdbc, openflow, snowflake, stream, table, view ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: ConsumeTwitter 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/consumetwitter.md section: Loading & Unloading Data --- # ConsumeTwitter 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-social-media-nar ## Description Streams tweets from Twitter's streaming API v2. The stream provides a sample stream or a search stream based on previously uploaded rules. This processor also provides a pass through for certain fields of the tweet to be returned as part of the response. See https://developer.twitter.com/en/docs/twitter-api/data-dictionary/introduction for more information regarding the Tweet object model. ## Tags json, social media, status, tweets, twitter ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: ControlRate 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/controlrate.md section: Loading & Unloading Data --- # ControlRate 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Controls the rate at which data is transferred to follow-on processors. If you configure a very small Time Duration, then the accuracy of the throttle gets worse. You can improve this accuracy by decreasing the Yield Duration, at the expense of more Tasks given to the processor. ## Tags rate, rate control, throttle, throughput ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Use cases | Limit the rate at which data is sent to a downstream system with little to no bursts | | ------------------------------------------------------------------------------------------ | | Limit the rate at which FlowFiles are sent to a downstream system with little to no bursts | | Reject requests that exceed a specific rate with little to no bursts | | Reject requests that exceed a specific rate, allowing for bursts | --- title: ConvertCharacterSet 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/convertcharacterset.md section: Loading & Unloading Data --- # ConvertCharacterSet 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Converts a FlowFile's content from one character set to another ## Tags character set, characterset, convert, text ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: ConvertRecord 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/convertrecord.md section: Loading & Unloading Data --- # ConvertRecord 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Converts records from one data format to another using configured Record Reader and Record Write Controller Services. The Reader and Writer must be configured with "matching" schemas. By this, we mean the schemas must have the same field names. The types of the fields do not have to be the same if a field value can be coerced from one type to another. For instance, if the input schema has a field named "balance" of type double, the output schema can have a field named "balance" with a type of string, double, or float. If any field is present in the input that is not present in the output, the field will be left out of the output. If any field is specified in the output schema but is not present in the input data/schema, then the field will not be present in the output or will have a null value, depending on the writer. ## Tags avro, convert, csv, freeform, generic, json, log, logs, record, schema, text ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## Use cases | Convert data from one record-oriented format to another | | ------------------------------------------------------- | --- title: ConvertToJournalSchema 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/converttojournalschema.md section: Loading & Unloading Data --- # ConvertToJournalSchema 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-database-cdc-processors-nar ## Description Converts the incoming database schema into the appropriate schema for a Snowflake CDC Journal table. ## Tags Snowflake, cdc, journal ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Relationships
--- title: CopyAzureBlobStorage_v12 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/copyazureblobstorage_v12.md section: Loading & Unloading Data --- # CopyAzureBlobStorage_v12 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-azure-nar ## Description Copies a blob in Azure Blob Storage from one account/container to another. The processor uses Azure Blob Storage client library v12. ## Tags azure, blob, cloud, microsoft, storage ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.azure.storage.DeleteAzureBlobStorage_v12](/user-guide/data-integration/openflow/processors/deleteazureblobstorage_v12) - [org.apache.nifi.processors.azure.storage.FetchAzureBlobStorage_v12](/user-guide/data-integration/openflow/processors/fetchazureblobstorage_v12) - [org.apache.nifi.processors.azure.storage.ListAzureBlobStorage_v12](/user-guide/data-integration/openflow/processors/listazureblobstorage_v12) - [org.apache.nifi.processors.azure.storage.PutAzureBlobStorage_v12](/user-guide/data-integration/openflow/processors/putazureblobstorage_v12) --- title: CopyS3Object 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/copys3object.md section: Loading & Unloading Data --- # CopyS3Object 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-aws-nar ## Description Copies a file from one bucket and key to another in AWS S3 ## Tags AWS, Amazon, Archive, Copy, S3 ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [org.apache.nifi.processors.aws.s3.DeleteS3Object](/user-guide/data-integration/openflow/processors/deletes3object) - [org.apache.nifi.processors.aws.s3.FetchS3Object](/user-guide/data-integration/openflow/processors/fetchs3object) - [org.apache.nifi.processors.aws.s3.GetS3ObjectMetadata](/user-guide/data-integration/openflow/processors/gets3objectmetadata) - [org.apache.nifi.processors.aws.s3.GetS3ObjectTags](/user-guide/data-integration/openflow/processors/gets3objecttags) - [org.apache.nifi.processors.aws.s3.ListS3](/user-guide/data-integration/openflow/processors/lists3) - [org.apache.nifi.processors.aws.s3.PutS3Object](/user-guide/data-integration/openflow/processors/puts3object) - [org.apache.nifi.processors.aws.s3.TagS3Object](/user-guide/data-integration/openflow/processors/tags3object) --- title: CountText 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/counttext.md section: Loading & Unloading Data --- # CountText 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Counts various metrics on incoming text. The requested results will be recorded as attributes. The resulting flowfile will not have its content modified. ## Tags character, count, line, text, word ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.standard.SplitText](/user-guide/data-integration/openflow/processors/splittext) --- title: CreateAmazonAdsReport 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/createamazonadsreport.md section: Loading & Unloading Data --- # CreateAmazonAdsReport 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-amazon-ads-processors-nar ## Description Processor which creates report configuration for Amazon Ads connector. By default it runs once a day. ## Tags Amazon, Amazon Ads, report ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
--- title: CreateAzureOpenAiEmbeddings 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/createazureopenaiembeddings.md section: Loading & Unloading Data --- # CreateAzureOpenAiEmbeddings 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-openai-nar ## Description Uses Azure OpenAI to create embeddings for text. The input text can be provided as a single FlowFile or as a record-oriented FlowFile. ## Tags azure, chatbot, embeddings, gen ai, generative ai, llm, nlp, openai, openflow, text ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## Use cases | Create embeddings for text using Azure OpenAI's Embeddings | | ---------------------------------------------------------- | ## See also - [com.snowflake.openflow.runtime.processors.openai.CreateOpenAiEmbeddings](/user-guide/data-integration/openflow/processors/createopenaiembeddings) - [com.snowflake.openflow.runtime.processors.openai.PromptAzureOpenAI](/user-guide/data-integration/openflow/processors/promptazureopenai) --- title: CreateBoxFileMetadataInstance 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/createboxfilemetadatainstance.md section: Loading & Unloading Data --- # CreateBoxFileMetadataInstance 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-box-nar ## Description Creates a metadata instance for a Box file using a specified template with values from the flowFile content. The Box API requires newly created templates to be created with the scope set as enterprise so no scope is required. The input record should be a flat key-value object where each field name is used as the metadata key. ## Tags box, create, metadata, storage, templates ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.box.FetchBoxFile](/user-guide/data-integration/openflow/processors/fetchboxfile) - [org.apache.nifi.processors.box.ListBoxFile](/user-guide/data-integration/openflow/processors/listboxfile) - [org.apache.nifi.processors.box.ListBoxFileMetadataTemplates](/user-guide/data-integration/openflow/processors/listboxfilemetadatatemplates) - [org.apache.nifi.processors.box.UpdateBoxFileMetadataInstance](/user-guide/data-integration/openflow/processors/updateboxfilemetadatainstance) --- title: CreateBoxMetadataTemplate 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/createboxmetadatatemplate.md section: Loading & Unloading Data --- # CreateBoxMetadataTemplate 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-box-nar ## Description Creates a Box metadata template using field specifications from the flowFile content. Expects a schema with fields: " 'type' (required), 'key' (required), 'displayName' (optional), 'description' (optional), 'hidden' (optional, boolean). ## Tags box, create, metadata, storage, templates ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.box.ListBoxFileMetadataTemplates](/user-guide/data-integration/openflow/processors/listboxfilemetadatatemplates) - [org.apache.nifi.processors.box.UpdateBoxFileMetadataInstance](/user-guide/data-integration/openflow/processors/updateboxfilemetadatainstance) --- title: CreateCohereEmbeddings 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/createcohereembeddings.md section: Loading & Unloading Data --- # CreateCohereEmbeddings 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-cohere-nar ## Description Uses Cohere to create embeddings for text. The input text can be provided as a single FlowFile or as a record-oriented FlowFile. ## Tags chatbot, cohere, embeddings, gen ai, generative ai, llm, nlp, openflow, text ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## Use cases | Create embeddings for text using Cohere's Embedding model | | --------------------------------------------------------- | --- title: CreateMetaAdsReport 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/createmetaadsreport.md section: Loading & Unloading Data --- # CreateMetaAdsReport 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-meta-ads-processors-nar ## Description Processor which creates report configuration for Meta Ads connector. By default it runs once a day. ## Tags Facebook, Meta, Meta Ads, report ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
--- title: CreateOpenAiEmbeddings 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/createopenaiembeddings.md section: Loading & Unloading Data --- # CreateOpenAiEmbeddings 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-openai-nar ## Description Uses OpenAI to create embeddings for text. The input text can be provided as a single FlowFile or as a record-oriented FlowFile. ## Tags chatbot, embeddings, gen ai, generative ai, llm, nlp, openai, openflow, text ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## Use cases | Create embeddings for text using OpenAI's Embeddings | | ---------------------------------------------------- | ## See also - [com.snowflake.openflow.runtime.processors.openai.CreateAzureOpenAiEmbeddings](/user-guide/data-integration/openflow/processors/createazureopenaiembeddings) - [com.snowflake.openflow.runtime.processors.openai.PromptOpenAI](/user-guide/data-integration/openflow/processors/promptopenai) --- title: CreateSnowflakeEmbeddings 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/createsnowflakeembeddings.md section: Loading & Unloading Data --- # CreateSnowflakeEmbeddings 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-snowflake-processors-nar ## Description Create vector embeddings using Snowflake Cortex Large Language Model functions ## Tags chatbot, embeddings, gen ai, generative ai, llm, nlp, openflow, snowflake, text ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: CreateVertexAIEmbeddings 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/createvertexaiembeddings.md section: Loading & Unloading Data --- # CreateVertexAIEmbeddings 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-vertexai-nar ## Description Uses VertexAI to create embeddings for text. The input text can be provided as a single FlowFile or as a record-oriented FlowFile. ## Tags chatbot, cloud, embeddings, gcp, gen ai, generative ai, google, llm, nlp, openflow, text, vertex ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## Use cases | Create embeddings for text using VertexAI's Embedding model | | ----------------------------------------------------------- | --- title: CryptographicHashContent 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/cryptographichashcontent.md section: Loading & Unloading Data --- # CryptographicHashContent 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Calculates a cryptographic hash value for the flowfile content using the given algorithm and writes it to an output attribute. Please refer to https://csrc.nist.gov/Projects/Hash-Functions/NIST-Policy-on-Hash-Functions (https://csrc.nist.gov/Projects/Hash-Functions/NIST-Policy-on-Hash-Functions) for help to decide which algorithm to use. ## Tags blake2, content, cryptography, hash, md5, sha ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: CSVReader source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/csvreader.md section: Loading & Unloading Data --- # CSVReader This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Parses CSV-formatted data, returning each row in the CSV file as a separate record. This reader allows for inferring a schema based on the first line of the CSV, if a 'header line' is present, or providing an explicit schema for interpreting the values. See Controller Service's Usage for further documentation. ## Tags comma, csv, delimited, parse, reader, record, row, separated, values ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: CSVRecordLookupService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/csvrecordlookupservice.md section: Loading & Unloading Data --- # CSVRecordLookupService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description A reloadable CSV file-based lookup service. When the lookup key is found in the CSV file, the columns are returned as a Record. All returned fields will be strings. The first line of the csv file is considered as header. ## Tags cache, csv, enrich, join, key, lookup, record, reloadable, value ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted ## Restrictions
## System Resource Considerations This component does not specify system resource considerations. --- title: CSVRecordSetWriter source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/csvrecordsetwriter.md section: Loading & Unloading Data --- # CSVRecordSetWriter This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Writes the contents of a RecordSet as CSV data. The first line written will be the column names (unless the 'Include Header Line' property is false). All subsequent lines will be the values corresponding to the record fields. ## Tags csv, delimited, record, recordset, result, row, separated, serializer, set, tab, tsv, writer ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: DatabaseLookup source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/databaselookup.md section: Loading & Unloading Data --- # DatabaseLookup This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description A Lookup Service that allows for enrichment with a database using a user-specified SQL statement. The SQL statement may reference any value from the FlowFile's Record that is provided by the calling Processor. ## Tags database, enrich, join, lookup, openflow, rdbms, record, sql ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: DatabaseRecordLookupService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/databaserecordlookupservice.md section: Loading & Unloading Data --- # DatabaseRecordLookupService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description A relational-database-based lookup service. When the lookup key is found in the database, the specified columns (or all if Lookup Value Columns are not specified) are returned as a Record. Only one row will be returned for each lookup, duplicate database entries are ignored. ## Tags cache, database, enrich, join, key, lookup, rdbms, record, reloadable, value ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: DatabaseRecordSink source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/databaserecordsink.md section: Loading & Unloading Data --- # DatabaseRecordSink This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides a service to write records using a configured database connection. ## Tags connection, database, db, jdbc, record ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: DBCPConnectionPool source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/dbcpconnectionpool.md section: Loading & Unloading Data --- # DBCPConnectionPool This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides Database Connection Pooling Service. Connections can be asked from pool and returned after usage. ## Tags connection, database, dbcp, jdbc, pooling, store ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted ## Restrictions
## System Resource Considerations This component does not specify system resource considerations. --- title: DBCPConnectionPoolLookup source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/dbcpconnectionpoollookup.md section: Loading & Unloading Data --- # DBCPConnectionPoolLookup This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides a DBCPService that can be used to dynamically select another DBCPService. This service requires an attribute named 'database.name' to be passed in when asking for a connection, and will throw an exception if the attribute is missing. The value of 'database.name' will be used to select the DBCPService that has been registered with that name. This will allow multiple DBCPServices to be defined and registered, and then selected dynamically at runtime by tagging flow files with the appropriate 'database.name' attribute. ## Tags connection, database, dbcp, jdbc, pooling, store ## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: DebugFlow 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/debugflow.md section: Loading & Unloading Data --- # DebugFlow 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description The DebugFlow processor aids testing and debugging the FlowFile framework by allowing various responses to be explicitly triggered in response to the receipt of a FlowFile or a timer event without a FlowFile if using timer or cron based scheduling. It can force responses needed to exercise or test various failure modes that can occur when a processor runs. ## Tags FlowFile, debug, flow, processor, test, utility ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: DecryptContentAge 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/decryptcontentage.md section: Loading & Unloading Data --- # DecryptContentAge 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-cipher-nar ## Description Decrypt content using the age-encryption.org/v1 specification. Detects binary or ASCII armored content encoding using the initial file header bytes. The age standard uses ChaCha20-Poly1305 for authenticated encryption of the payload. The age-keygen command supports generating X25519 key pairs for encryption and decryption operations. ## Tags ChaCha20-Poly1305, X25519, age, age-encryption.org, encryption ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [org.apache.nifi.processors.cipher.EncryptContentAge](/user-guide/data-integration/openflow/processors/encryptcontentage) --- title: DecryptContentPGP 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/decryptcontentpgp.md section: Loading & Unloading Data --- # DecryptContentPGP 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-pgp-nar ## Description Decrypt contents of OpenPGP messages. Using the Packaged Decryption Strategy preserves OpenPGP encoding to support subsequent signature verification. ## Tags Encryption, GPG, OpenPGP, PGP, RFC 4880 ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.pgp.EncryptContentPGP](/user-guide/data-integration/openflow/processors/encryptcontentpgp) - [org.apache.nifi.processors.pgp.SignContentPGP](/user-guide/data-integration/openflow/processors/signcontentpgp) - [org.apache.nifi.processors.pgp.VerifyContentPGP](/user-guide/data-integration/openflow/processors/verifycontentpgp) --- title: DeduplicateRecord 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/deduplicaterecord.md section: Loading & Unloading Data --- # DeduplicateRecord 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description This processor de-duplicates individual records within a record set. It can operate on a per-file basis using an in-memory hashset or bloom filter. When configured with a distributed map cache, it de-duplicates records across multiple files. ## Tags change, dedupe, distinct, dupe, duplicate, filter, hash, modify, record, replace, text, unique, update ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.standard.DetectDuplicate](/user-guide/data-integration/openflow/processors/detectduplicate) --- title: DeleteAzureBlobStorage_v12 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/deleteazureblobstorage_v12.md section: Loading & Unloading Data --- # DeleteAzureBlobStorage_v12 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-azure-nar ## Description Deletes the specified blob from Azure Blob Storage. The processor uses Azure Blob Storage client library v12. ## Tags azure, blob, cloud, microsoft, storage ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [org.apache.nifi.processors.azure.storage.CopyAzureBlobStorage_v12](/user-guide/data-integration/openflow/processors/copyazureblobstorage_v12) - [org.apache.nifi.processors.azure.storage.FetchAzureBlobStorage_v12](/user-guide/data-integration/openflow/processors/fetchazureblobstorage_v12) - [org.apache.nifi.processors.azure.storage.ListAzureBlobStorage_v12](/user-guide/data-integration/openflow/processors/listazureblobstorage_v12) - [org.apache.nifi.processors.azure.storage.PutAzureBlobStorage_v12](/user-guide/data-integration/openflow/processors/putazureblobstorage_v12) --- title: DeleteAzureDataLakeStorage 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/deleteazuredatalakestorage.md section: Loading & Unloading Data --- # DeleteAzureDataLakeStorage 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-azure-nar ## Description Deletes the provided file from Azure Data Lake Storage ## Tags adlsgen2, azure, cloud, datalake, microsoft, storage ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [org.apache.nifi.processors.azure.storage.FetchAzureDataLakeStorage](/user-guide/data-integration/openflow/processors/fetchazuredatalakestorage) - [org.apache.nifi.processors.azure.storage.ListAzureDataLakeStorage](/user-guide/data-integration/openflow/processors/listazuredatalakestorage) - [org.apache.nifi.processors.azure.storage.PutAzureDataLakeStorage](/user-guide/data-integration/openflow/processors/putazuredatalakestorage) --- title: DeleteBoxFileMetadataInstance 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/deleteboxfilemetadatainstance.md section: Loading & Unloading Data --- # DeleteBoxFileMetadataInstance 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-box-nar ## Description Deletes a metadata instance from a Box file using the specified template key ## Tags box, delete, metadata, storage, templates ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.box.CreateBoxFileMetadataInstance](/user-guide/data-integration/openflow/processors/createboxfilemetadatainstance) - [org.apache.nifi.processors.box.FetchBoxFileMetadataInstance](/user-guide/data-integration/openflow/processors/fetchboxfilemetadatainstance) - [org.apache.nifi.processors.box.UpdateBoxFileMetadataInstance](/user-guide/data-integration/openflow/processors/updateboxfilemetadatainstance) --- title: DeleteByQueryElasticsearch 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/deletebyqueryelasticsearch.md section: Loading & Unloading Data --- # DeleteByQueryElasticsearch 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-elasticsearch-restapi-nar ## Description Delete from an Elasticsearch index using a query. The query can be loaded from a flowfile body or from the Query parameter. ## Tags delete, elastic, elasticsearch, elasticsearch7, elasticsearch8, elasticsearch9, query ## Input Requirement ALLOWED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: DeleteDBFSResource 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/deletedbfsresource.md section: Loading & Unloading Data --- # DeleteDBFSResource 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-databricks-processors-nar ## Description Delete a DBFS files and directories. ## Tags databricks, dbfs, openflow ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: DeleteDynamoDB 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/deletedynamodb.md section: Loading & Unloading Data --- # DeleteDynamoDB 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-aws-nar ## Description Deletes a document from DynamoDB based on hash and range key. The key can be string or number. The request requires all the primary keys for the operation (hash or hash and range key) ## Tags AWS, Amazon, Delete, DynamoDB, Remove ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.aws.dynamodb.GetDynamoDB](/user-guide/data-integration/openflow/processors/getdynamodb) - [org.apache.nifi.processors.aws.dynamodb.PutDynamoDB](/user-guide/data-integration/openflow/processors/putdynamodb) - [org.apache.nifi.processors.aws.dynamodb.PutDynamoDBRecord](/user-guide/data-integration/openflow/processors/putdynamodbrecord) --- title: DeleteFile 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/deletefile.md section: Loading & Unloading Data --- # DeleteFile 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Deletes a file from the filesystem. ## Tags delete, file, files, filesystem, local, remove ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Restrictions
## Relationships
## Use cases | Delete source file only after its processing completed | | ------------------------------------------------------ | --- title: DeleteGCSObject 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/deletegcsobject.md section: Loading & Unloading Data --- # DeleteGCSObject 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-gcp-nar ## Description Deletes objects from a Google Cloud Bucket. If attempting to delete a file that does not exist, FlowFile is routed to success. ## Tags delete, gcs, google, google cloud, storage ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [org.apache.nifi.processors.gcp.storage.FetchGCSObject](/user-guide/data-integration/openflow/processors/fetchgcsobject) - [org.apache.nifi.processors.gcp.storage.ListGCSBucket](/user-guide/data-integration/openflow/processors/listgcsbucket) - [org.apache.nifi.processors.gcp.storage.PutGCSObject](/user-guide/data-integration/openflow/processors/putgcsobject) --- title: DeleteGridFS 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/deletegridfs.md section: Loading & Unloading Data --- # DeleteGridFS 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-mongodb-nar ## Description Deletes a file from GridFS using a file name or a query. ## Tags delete, gridfs, mongodb ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: DeleteMilvus 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/deletemilvus.md section: Loading & Unloading Data --- # DeleteMilvus 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-milvus-processors-nar ## Description Deletes vectors from Milvus database from a collection by ID. Unmatched IDs are ignored by Milvus and not deleted. ## Tags chatbot, delete, embeddings, gen ai, genai, generative ai, llm, metadata, milvus, openflow, text, vector ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [com.snowflake.openflow.runtime.processors.milvus.UpsertMilvus](/user-guide/data-integration/openflow/processors/upsertmilvus) --- title: DeleteMongo 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/deletemongo.md section: Loading & Unloading Data --- # DeleteMongo 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-mongodb-nar ## Description Executes a delete query against a MongoDB collection. The query is provided in the body of the flowfile and the user can select whether it will delete one or many documents that match it. ## Tags delete, mongo, mongodb ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: DeletePinecone 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/deletepinecone.md section: Loading & Unloading Data --- # DeletePinecone 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-pinecone-nar ## Description Deletes vectors from a Pinecone index. ## Tags delete, embeddings, genai, generative ai, openflow, pinecone, rag, retrieval augmented generation, vector store ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Use cases | Delete all vectors from a Pinecone index. | | ------------------------------------------------------------------------- | | Delete a namespace, along with all of its vectors, from a Pinecone index. | | Delete all vectors for a particular document from a Pinecone index. | --- title: DeleteQueryJob 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/deletequeryjob.md section: Loading & Unloading Data --- # DeleteQueryJob 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-salesforce-processors-nar ## Description Deletes a Query Job in Salesforce using the Bulk API 2.0. ## Tags bulk, delete, job, preview, query, salesforce ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [com.snowflake.openflow.runtime.processors.salesforce.AbortQueryJob](/user-guide/data-integration/openflow/processors/abortqueryjob) - [com.snowflake.openflow.runtime.processors.salesforce.GetQueryJobResult](/user-guide/data-integration/openflow/processors/getqueryjobresult) - [com.snowflake.openflow.runtime.processors.salesforce.GetQueryJobStatus](/user-guide/data-integration/openflow/processors/getqueryjobstatus) - [com.snowflake.openflow.runtime.processors.salesforce.SubmitQueryJob](/user-guide/data-integration/openflow/processors/submitqueryjob) --- title: DeleteS3Object 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/deletes3object.md section: Loading & Unloading Data --- # DeleteS3Object 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-aws-nar ## Description Deletes a file from an Amazon S3 Bucket. If attempting to delete a file that does not exist, FlowFile is routed to success. ## Tags AWS, Amazon, Archive, Delete, S3 ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.aws.s3.CopyS3Object](/user-guide/data-integration/openflow/processors/copys3object) - [org.apache.nifi.processors.aws.s3.FetchS3Object](/user-guide/data-integration/openflow/processors/fetchs3object) - [org.apache.nifi.processors.aws.s3.GetS3ObjectMetadata](/user-guide/data-integration/openflow/processors/gets3objectmetadata) - [org.apache.nifi.processors.aws.s3.GetS3ObjectTags](/user-guide/data-integration/openflow/processors/gets3objecttags) - [org.apache.nifi.processors.aws.s3.ListS3](/user-guide/data-integration/openflow/processors/lists3) - [org.apache.nifi.processors.aws.s3.PutS3Object](/user-guide/data-integration/openflow/processors/puts3object) - [org.apache.nifi.processors.aws.s3.TagS3Object](/user-guide/data-integration/openflow/processors/tags3object) --- title: DeleteSFTP 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/deletesftp.md section: Loading & Unloading Data --- # DeleteSFTP 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Deletes a file residing on an SFTP server. ## Tags delete, remote, remove, sftp ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Use cases | Delete source file only after its processing completed | | ------------------------------------------------------ | --- title: DeleteSQS 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/deletesqs.md section: Loading & Unloading Data --- # DeleteSQS 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-aws-nar ## Description Deletes a message from an Amazon Simple Queuing Service Queue ## Tags AWS, Amazon, Delete, Queue, SQS ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [org.apache.nifi.processors.aws.sqs.GetSQS](/user-guide/data-integration/openflow/processors/getsqs) - [org.apache.nifi.processors.aws.sqs.PutSQS](/user-guide/data-integration/openflow/processors/putsqs) --- title: DeleteUnityCatalogResource 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/deleteunitycatalogresource.md section: Loading & Unloading Data --- # DeleteUnityCatalogResource 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-databricks-processors-nar ## Description Delete a Unity Catalog file or directory. ## Tags databricks, openflow, unity catalog ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: DescribeDataShare 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/describedatashare.md section: Loading & Unloading Data --- # DescribeDataShare 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-salesforce-processors-nar ## Description Describe the specified data share metadata in Salesforce Data Cloud. ## Tags daas, data cloud, describe, object, preview, salesforce, sfdc ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [com.snowflake.openflow.runtime.processors.salesforce.ListSFDCDataShares](/user-guide/data-integration/openflow/processors/listsfdcdatashares) --- title: DescribeSFDCObject 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/describesfdcobject.md section: Loading & Unloading Data --- # DescribeSFDCObject 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-salesforce-processors-nar ## Description Describe the specified object metadata in Salesforce. ## Tags describe, object, preview, salesforce, sfdc ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [com.snowflake.openflow.runtime.processors.salesforce.AbortQueryJob](/user-guide/data-integration/openflow/processors/abortqueryjob) - [com.snowflake.openflow.runtime.processors.salesforce.DeleteQueryJob](/user-guide/data-integration/openflow/processors/deletequeryjob) - [com.snowflake.openflow.runtime.processors.salesforce.GetQueryJobResult](/user-guide/data-integration/openflow/processors/getqueryjobresult) - [com.snowflake.openflow.runtime.processors.salesforce.ListSFDCObjects](/user-guide/data-integration/openflow/processors/listsfdcobjects) --- title: DetectDuplicate 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/detectduplicate.md section: Loading & Unloading Data --- # DetectDuplicate 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Caches a value, computed from FlowFile attributes, for each incoming FlowFile and determines if the cached value has already been seen. If so, routes the FlowFile to 'duplicate' with an attribute named 'original.identifier' that specifies the original FlowFile 's "description", which is specified in the <FlowFile Description> property. If the FlowFile is not determined to be a duplicate, the Processor routes the FlowFile to' non-duplicate' ## Tags dedupe, dupe, duplicate, hash ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also --- title: DeveloperBoxClientService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/developerboxclientservice.md section: Loading & Unloading Data --- # DeveloperBoxClientService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides Box client objects through which Box API calls can be used. This using a developer token and is for testing only. ## Tags box, client, provider ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: DistributedMapCacheLookupService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/distributedmapcachelookupservice.md section: Loading & Unloading Data --- # DistributedMapCacheLookupService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Lets you choose a distributed map cache client to retrieve the value associated to a key. The coordinates that are passed to the lookup must contain the key 'key'. ## Tags cache, distributed, enrich, key, lookup, map, value ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: DistributeLoad 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/distributeload.md section: Loading & Unloading Data --- # DistributeLoad 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Distributes FlowFiles to downstream processors based on a Distribution Strategy. If using the Round Robin strategy, the default is to assign each destination a weighting of 1 (evenly distributed). However, optional properties can be added to the change this; adding a property with the name '5' and value '10' means that the relationship with name '5' will be receive 10 FlowFiles in each iteration instead of 1. ## Tags distribute, load balance, round robin, route, weighted ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: DuplicateFlowFile 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/duplicateflowfile.md section: Loading & Unloading Data --- # DuplicateFlowFile 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Intended for load testing, this processor will create the configured number of copies of each incoming FlowFile. The original FlowFile as well as all generated copies are sent to the 'success' relationship. In addition, each FlowFile gets an attribute 'copy.index'set to the copy number, where the original FlowFile gets a value of zero, and all copies receive incremented integer values. ## Tags duplicate, load, test ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: ElasticSearchClientServiceImpl source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/elasticsearchclientserviceimpl.md section: Loading & Unloading Data --- # ElasticSearchClientServiceImpl This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description A controller service for accessing an Elasticsearch client, using the Elasticsearch (low-level) REST Client. ## Tags client, elasticsearch, elasticsearch6, elasticsearch7, elasticsearch8 ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: ElasticSearchLookupService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/elasticsearchlookupservice.md section: Loading & Unloading Data --- # ElasticSearchLookupService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Lookup a record from Elasticsearch Server associated with the specified document ID. The coordinates that are passed to the lookup must contain the key 'id'. ## Tags elasticsearch, enrich, lookup, record ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: ElasticSearchStringLookupService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/elasticsearchstringlookupservice.md section: Loading & Unloading Data --- # ElasticSearchStringLookupService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Lookup a string value from Elasticsearch Server associated with the specified document ID. The coordinates that are passed to the lookup must contain the key 'id'. ## Tags elasticsearch, enrich, key, lookup, value ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: EmailRecordSink source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/emailrecordsink.md section: Loading & Unloading Data --- # EmailRecordSink This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides a RecordSinkService that can be used to send records in email using the specified writer for formatting. ## Tags email, record, send, sink, smtp, write ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: EmbeddedHazelcastCacheManager source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/embeddedhazelcastcachemanager.md section: Loading & Unloading Data --- # EmbeddedHazelcastCacheManager This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description A service that runs embedded Hazelcast and provides cache instances backed by that. The server does not ask for authentication, it is recommended to run it within secured network. ## Tags cache, hazelcast ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: EncodeContent 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/encodecontent.md section: Loading & Unloading Data --- # EncodeContent 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Encode or decode the contents of a FlowFile using Base64, Base32, or hex encoding schemes ## Tags base32, base64, decode, encode, hex ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: EncryptContentAge 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/encryptcontentage.md section: Loading & Unloading Data --- # EncryptContentAge 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-cipher-nar ## Description Encrypt content using the age-encryption.org/v1 specification. Supports binary or ASCII armored content encoding using configurable properties. The age standard uses ChaCha20-Poly1305 for authenticated encryption of the payload. The age-keygen command supports generating X25519 key pairs for encryption and decryption operations. ## Tags ChaCha20-Poly1305, X25519, age, age-encryption.org, encryption ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [org.apache.nifi.processors.cipher.DecryptContentAge](/user-guide/data-integration/openflow/processors/decryptcontentage) --- title: EncryptContentPGP 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/encryptcontentpgp.md section: Loading & Unloading Data --- # EncryptContentPGP 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-pgp-nar ## Description Encrypt contents using OpenPGP. The processor reads input and detects OpenPGP messages to avoid unnecessary additional wrapping in Literal Data packets. ## Tags Encryption, GPG, OpenPGP, PGP, RFC 4880 ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.pgp.DecryptContentPGP](/user-guide/data-integration/openflow/processors/decryptcontentpgp) - [org.apache.nifi.processors.pgp.SignContentPGP](/user-guide/data-integration/openflow/processors/signcontentpgp) - [org.apache.nifi.processors.pgp.VerifyContentPGP](/user-guide/data-integration/openflow/processors/verifycontentpgp) --- title: EnforceOrder 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/enforceorder.md section: Loading & Unloading Data --- # EnforceOrder 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Enforces expected ordering of FlowFiles that belong to the same data group within a single node. Although PriorityAttributePrioritizer can be used on a connection to ensure that flow files going through that connection are in priority order, depending on error-handling, branching, and other flow designs, it is possible for FlowFiles to get out-of-order. EnforceOrder can be used to enforce original ordering for those FlowFiles. [IMPORTANT] In order to take effect of EnforceOrder, FirstInFirstOutPrioritizer should be used at EVERY downstream relationship UNTIL the order of FlowFiles physically get FIXED by operation such as MergeContent or being stored to the final destination. ## Tags order, sort ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
--- title: EnrichAttributes 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/enrichattributes.md section: Loading & Unloading Data --- # EnrichAttributes 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-enrichment-nar ## Description Looks up a value using the configured Lookup Service and adds the results to the FlowFile as one or more attributes. Frequently, this is used in conjunction with the DatabaseLookup Service in order to enrich a FlowFile by querying a database and adding the results as attributes. ## Tags attributes, database, enrichment, json, lookup, openflow ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Use cases | Query a database to retrieve information based on the attributes of a FlowFile | | ------------------------------------------------------------------------------ | ## See also --- title: EnrichCdcStream 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/enrichcdcstream.md section: Loading & Unloading Data --- # EnrichCdcStream 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-database-cdc-processors-nar ## Description Enriches incoming FlowFiles that come from CaptureChangePostgreSQL, etc. with information pertaining to which Journal Table to write to and relevant schema information. This Processor manages the schema versions for each table being processed in order to ensure that the correct Journal Table is used for each FlowFile. ## Tags ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
## See also - [com.snowflake.openflow.runtime.processors.database.CaptureChangePostgreSQL](/user-guide/data-integration/openflow/processors/capturechangepostgresql) --- title: EvaluateJsonPath 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/evaluatejsonpath.md section: Loading & Unloading Data --- # EvaluateJsonPath 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Evaluates one or more JsonPath expressions against the content of a FlowFile. The results of those expressions are assigned to FlowFile Attributes or are written to the content of the FlowFile itself, depending on configuration of the Processor. JsonPaths are entered by adding user-defined properties; the name of the property maps to the Attribute Name into which the result will be placed (if the Destination is flowfile-attribute; otherwise, the property name is ignored). The value of the property must be a valid JsonPath expression. A Return Type of 'auto-detect' will make a determination based off the configured destination. When 'Destination' is set to 'flowfile-attribute,' a return type of 'scalar' will be used. When 'Destination' is set to 'flowfile-content,' a return type of 'JSON' will be used. If the JsonPath evaluates to a JSON array or JSON object and the Return Type is set to 'scalar' the FlowFile will be unmodified and will be routed to failure. A Return Type of JSON can return scalar values if the provided JsonPath evaluates to the specified value and will be routed as a match. If Destination is 'flowfile-content' and the JsonPath does not evaluate to a defined path, the FlowFile will be routed to 'unmatched' without having its contents modified. If Destination is 'flowfile-attribute' and the expression matches nothing, attributes will be created with empty strings as the value unless 'Path Not Found Behaviour' is set to 'skip', and the FlowFile will always be routed to 'matched.' ## Tags JSON, JsonPath, evaluate ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: EvaluateRagAnswerCorrectness 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/evaluateraganswercorrectness.md section: Loading & Unloading Data --- # EvaluateRagAnswerCorrectness 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-rag-evaluation-processors-nar ## Description Evaluates the correctness of generated answers in a Retrieval-Augmented Generation (RAG) context by computing metrics such as F1 score, cosine similarity, and answer correctness. The processor uses an LLM (e.g., OpenAI's GPT) to assess the generated answer against the ground truth. ## Tags ai, answer correctness, evaluation, llm, nlp, openai, openflow, rag ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## Use cases | Use this processor to assess the quality of answers generated by an LLM in comparison to ground truth answers, providing metrics that can be used for monitoring and improving the performance of RAG systems. | | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | --- title: EvaluateRagFaithfulness 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/evaluateragfaithfulness.md section: Loading & Unloading Data --- # EvaluateRagFaithfulness 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-rag-evaluation-processors-nar ## Description Evaluates the faithfulness of generated answers in a Retrieval-Augmented Generation (RAG) system by analyzing responses using an LLM (e.g., OpenAI's GPT). The processor enriches each FlowFile record with faithfulness metrics and detailed analysis. ## Tags ai, evaluation, faithfulness, llm, nlp, openai, openflow, rag ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## Use cases | Use this processor to assess the faithfulness of answers generated by an LLM compared to the provided context. It provides metrics that can be used for monitoring and improving the performance of RAG systems. | | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | --- title: EvaluateRagRetrieval 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/evaluateragretrieval.md section: Loading & Unloading Data --- # EvaluateRagRetrieval 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-rag-evaluation-processors-nar ## Description Calculates retrieval metrics (Precision@N, Recall@N, FScore@N, MAP@N, MRR) for a RAG system using an LLM as a judge. For each record, it uses both Precision and Recall prompts to evaluate the response, and adds the metrics as attributes to the FlowFile. ## Tags evaluation, fscore, llm, metrics, mrr, openai, openflow, precision, rag, recall, retrieval ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: EvaluateXPath 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/evaluatexpath.md section: Loading & Unloading Data --- # EvaluateXPath 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Evaluates one or more XPaths against the content of a FlowFile. The results of those XPaths are assigned to FlowFile Attributes or are written to the content of the FlowFile itself, depending on configuration of the Processor. XPaths are entered by adding user-defined properties; the name of the property maps to the Attribute Name into which the result will be placed (if the Destination is flowfile-attribute; otherwise, the property name is ignored). The value of the property must be a valid XPath expression. If the XPath evaluates to more than one node and the Return Type is set to 'nodeset' (either directly, or via 'auto-detect' with a Destination of 'flowfile-content'), the FlowFile will be unmodified and will be routed to failure. If the XPath does not evaluate to a Node, the FlowFile will be routed to 'unmatched' without having its contents modified. If Destination is flowfile-attribute and the expression matches nothing, attributes will be created with empty strings as the value, and the FlowFile will always be routed to 'matched' ## Tags XML, XPath, evaluate ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: EvaluateXQuery 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/evaluatexquery.md section: Loading & Unloading Data --- # EvaluateXQuery 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Evaluates one or more XQueries against the content of a FlowFile. The results of those XQueries are assigned to FlowFile Attributes or are written to the content of the FlowFile itself, depending on configuration of the Processor. XQueries are entered by adding user-defined properties; the name of the property maps to the Attribute Name into which the result will be placed (if the Destination is 'flowfile-attribute'; otherwise, the property name is ignored). The value of the property must be a valid XQuery. If the XQuery returns more than one result, new attributes or FlowFiles (for Destinations of 'flowfile-attribute' or 'flowfile-content' respectively) will be created for each result (attributes will have a '.n' one-up number appended to the specified attribute name). If any provided XQuery returns a result, the FlowFile(s) will be routed to 'matched'. If no provided XQuery returns a result, the FlowFile will be routed to 'unmatched'. If the Destination is 'flowfile-attribute' and the XQueries matche nothing, no attributes will be applied to the FlowFile. ## Tags XML, XPath, XQuery, evaluate ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: ExcelReader source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/excelreader.md section: Loading & Unloading Data --- # ExcelReader This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Parses a Microsoft Excel document returning each row in each sheet as a separate record. This reader allows for inferring a schema from all the required sheets or providing an explicit schema for interpreting the values. See Controller Service 's Usage for further documentation. This reader is capable of processing both password and non password protected .xlsx (XSSF 2007 OOXML file format) and older .xls (HSSF'97(-2007) file format) Excel documents. ## Tags cell, excel, parse, reader, record, row, spreadsheet, values, xls, xlsx ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: ExecuteGroovyScript 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/executegroovyscript.md section: Loading & Unloading Data --- # ExecuteGroovyScript 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-groovyx-nar ## Description Experimental Extended Groovy script processor. The script is responsible for handling the incoming flow file (transfer to SUCCESS or remove, e.g.) as well as any flow files created by the script. If the handling is incomplete or incorrect, the session will be rolled back. ## Tags groovy, groovyx, script ## Input Requirement ALLOWED ## Supports Sensitive Dynamic Properties true ## Properties
## State management
## Restrictions
## Relationships
## See also - [org.apache.nifi.processors.script.ExecuteScript](/user-guide/data-integration/openflow/processors/executescript) --- title: ExecuteProcess 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/executeprocess.md section: Loading & Unloading Data --- # ExecuteProcess 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Runs an operating system command specified by the user and writes the output of that command to a FlowFile. If the command is expected to be long-running, the Processor can output the partial data on a specified interval. When this option is used, the output is expected to be in textual format, as it typically does not make sense to split binary data on arbitrary time-based intervals. ## Tags command, external, invoke, process, script, source ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Restrictions
## Relationships
## Writes attributes
--- title: ExecuteScript 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/executescript.md section: Loading & Unloading Data --- # ExecuteScript 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-scripting-nar ## Description Experimental - Executes a script given the flow file and a process session. The script is responsible for handling the incoming flow file (transfer to SUCCESS or remove, e.g.) as well as any flow files created by the script. If the handling is incomplete or incorrect, the session will be rolled back. Experimental: Impact of sustained usage not yet verified. ## Tags clojure, execute, groovy, script ## Input Requirement ALLOWED ## Supports Sensitive Dynamic Properties true ## Properties
## State management
## Restrictions
## Relationships
## See also - [org.apache.nifi.processors.script.InvokeScriptedProcessor](/user-guide/data-integration/openflow/processors/invokescriptedprocessor) --- title: ExecuteSQL 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/executesql.md section: Loading & Unloading Data --- # ExecuteSQL 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Executes provided SQL select query. Query result will be converted to Avro format. Streaming is used so arbitrarily large result sets are supported. This processor can be scheduled to run on a timer, or cron expression, using the standard scheduling methods, or it can be triggered by an incoming FlowFile. If it is triggered by an incoming FlowFile, then attributes of that FlowFile will be available when evaluating the select query, and the query may use the ? to escape parameters. In this case, the parameters to use must exist as FlowFile attributes with the naming convention sql.args. N.type and sql.args. N.value, where N is a positive integer. The sql.args. N.type is expected to be a number indicating the JDBC Type. The content of the FlowFile is expected to be in UTF-8 format. FlowFile attribute 'executesql.row.count' indicates how many rows were selected. ## Tags database, jdbc, query, select, sql ## Input Requirement ALLOWED ## Supports Sensitive Dynamic Properties true ## Properties
## Relationships
## Writes attributes
--- title: ExecuteSQLRecord 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/executesqlrecord.md section: Loading & Unloading Data --- # ExecuteSQLRecord 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Executes provided SQL select query. Query result will be converted to the format specified by a Record Writer. Streaming is used so arbitrarily large result sets are supported. This processor can be scheduled to run on a timer, or cron expression, using the standard scheduling methods, or it can be triggered by an incoming FlowFile. If it is triggered by an incoming FlowFile, then attributes of that FlowFile will be available when evaluating the select query, and the query may use the ? to escape parameters. In this case, the parameters to use must exist as FlowFile attributes with the naming convention sql.args. N.type and sql.args. N.value, where N is a positive integer. The sql.args. N.type is expected to be a number indicating the JDBC Type. The content of the FlowFile is expected to be in UTF-8 format. FlowFile attribute 'executesql.row.count' indicates how many rows were selected. ## Tags database, jdbc, query, record, select, sql ## Input Requirement ALLOWED ## Supports Sensitive Dynamic Properties true ## Properties
## Relationships
## Writes attributes
--- title: ExecuteSQLStatement 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/executesqlstatement.md section: Loading & Unloading Data --- # ExecuteSQLStatement 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-database-processors-nar ## Description Executes a SQL DDL or DML Statement against a database. This Processor allows Expression Language to be evaluated against FlowFile attributes in order to parameterize the SQL for each FlowFile. ## Tags database, delete, insert, jdbc, openflow, sql, update ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: ExecuteStreamCommand 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/executestreamcommand.md section: Loading & Unloading Data --- # ExecuteStreamCommand 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description The ExecuteStreamCommand processor provides a flexible way to integrate external commands and scripts into NiFi data flows. ExecuteStreamCommand can pass the incoming FlowFile's content to the command that it executes similarly how piping works. ## Tags command, command execution, execute, stream ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties true ## Properties
## Restrictions
## Relationships
## Writes attributes
--- title: Explore data products from Salesforce Data Cloud source: https://docs.snowflake.cn/en/user-guide/data-integration/zero-copy/salesforce/explore-data-products.md section: Loading & Unloading Data --- # Explore data products from Salesforce Data Cloud - [About Salesforce Data Cloud and Snowflake](/user-guide/data-integration/zero-copy/about-salesforce-datacloud) - [Set up the Salesforce Data Cloud Zerocopy Connector](/user-guide/data-integration/zero-copy/salesforce/setup) - [Set up Salesforce Data Cloud for Zero-Copy](/user-guide/data-integration/zero-copy/salesforce/setup-salesforce) - [Salesforce Data Cloud Zerocopy Connector: Security and privileges](/user-guide/data-integration/zero-copy/salesforce/security) This topic describes how to list available Salesforce data products, mount them as catalog-linked databases, and query the shared data in Snowflake. Before performing the steps in this topic: - The Zerocopy Connector must be in `CONNECTED` state. See [Set up the Salesforce Data Cloud Zerocopy Connector](/user-guide/data-integration/zero-copy/salesforce/setup). - Your Salesforce administrator must have created and linked at least one Data Share to the connector. See [Set up Salesforce Data Cloud for Zero-Copy](/user-guide/data-integration/zero-copy/salesforce/setup-salesforce). ## List shared data products After your Salesforce administrator links a Data Share to the Snowflake V2 Data Share Target, call `SYSTEM$ZEROCOPY_CONNECTOR_LIST_SHARES` to see what's available: ```sql SELECT SYSTEM$ZEROCOPY_CONNECTOR_LIST_SHARES('my_db.my_schema.my_sfdc_connector'); ``` The function returns a JSON array. Each element represents one shared data product. The `name` field is the value you pass as `SHARE_NAME` or `SHARE_NAME_FILTER` when creating a catalog-linked database. ```text [ { "name": "contact_v1", "status": "UNMOUNTED", "catalog_linked_databases": [] }, { "name": "opportunity_v1", "status": "MOUNTED", "catalog_linked_databases": [ { "name": "MARKETINGSHARE" } ] } ] ``` The `status` field indicates whether the data share is available to mount or already mounted:
To parse the output into a tabular format: ```sql WITH raw AS ( SELECT PARSE_JSON( SYSTEM$ZEROCOPY_CONNECTOR_LIST_SHARES('my_db.my_schema.my_sfdc_connector') ) AS json_data ) SELECT f.value:name::STRING AS share_name, f.value:status::STRING AS status, CASE WHEN ARRAY_SIZE(f.value:catalog_linked_databases) > 0 THEN f.value:catalog_linked_databases[0]:name::STRING ELSE NULL END AS mounted_database FROM raw, LATERAL FLATTEN(INPUT => json_data) f; ``` ## Create a catalog-linked database Mounting a share creates a catalog-linked database that contains the shared data as queryable schemas. Snowflake automatically creates views on top of them. You can mount using the Snowsight UI or SQL. ### Using Snowsight 1. In Snowsight, navigate to **Ingestion** %raa% **Zero-Copy**. 2. Select the **Available connectors** tab and click your Salesforce connector. 3. On the **Catalog linked databases** tab, click **Mount all data shares**. The catalog-linked database is created immediately. ### Using SQL ```sql -- (Recommended) Mount all shares — each share becomes a schema CREATE DATABASE my_sfdc_db LINKED_ZEROCOPY_CONNECTOR = ( CONNECTOR_NAME = 'my_db.my_schema.my_sfdc_connector', ALL_SHARES = TRUE, SYNC_INTERVAL_SECONDS = 30 -- optional; controls how often new shares are detected ); -- Mount a filtered set of shares CREATE DATABASE my_sfdc_db LINKED_ZEROCOPY_CONNECTOR = ( CONNECTOR_NAME = 'my_db.my_schema.my_sfdc_connector', SHARE_NAME_FILTER = ('share1', 'share2') ); -- Mount a single share CREATE DATABASE my_sfdc_db LINKED_ZEROCOPY_CONNECTOR = ( CONNECTOR_NAME = 'my_db.my_schema.my_sfdc_connector', SHARE_NAME = 'my_share' ); ``` To confirm the database was created: ```sql SHOW DATABASES LIKE 'MY_SFDC_DB%'; ``` ## Explore the data ### Data model overview When you mount a share, each data share appears as a **schema** within the catalog-linked database. Within each schema, Salesforce data objects are exposed as **views**. ### Discover schemas and views ```sql -- Data shares are mounted as schemas in the catalog-linked database SHOW SCHEMAS IN DATABASE my_sfdc_db; -- Views are the queryable layer — use these for all queries SHOW VIEWS IN SCHEMA my_sfdc_db.my_share_schema; -- Inspect columns before querying SHOW COLUMNS IN VIEW my_sfdc_db.my_share_schema.ssot__Account__dlm; ``` Views are created shortly after the catalog-linked database is mounted. If `SHOW VIEWS` returns no results immediately, wait for 1 minute and try again. ### Query the data Query Salesforce data via the views in each schema. The view names are determined by what your Salesforce administrator included in the Data Share. ```sql -- Query a Data Lake Object (DLO) SELECT * FROM my_sfdc_db.my_share_schema.Case_Home__dll LIMIT 10; -- Query a Data Model Object (DMO) SELECT * FROM my_sfdc_db.my_share_schema.ssot__PriceBook__dlm LIMIT 10; -- Query a Calculated Insights Object (CIO) SELECT * FROM my_sfdc_db.my_share_schema.Product_Sku_Aggregation__cio LIMIT 10; ``` Replace `my_sfdc_db`, `my_share_schema`, and the view names with the actual values returned by `SHOW SCHEMAS` and `SHOW VIEWS` in your environment. ## Create table as select (CTAS) To persist query results as a native Snowflake table for use in dashboards, ML models, or data sharing: ```sql CREATE DATABASE IF NOT EXISTS my_ctas_db; USE DATABASE my_ctas_db; -- Snapshot a Salesforce data model object into a native Snowflake table CREATE OR REPLACE TABLE account_snapshot AS SELECT * FROM my_sfdc_db.my_share_schema.ssot__Account__dlm; SELECT * FROM account_snapshot LIMIT 10; ``` ## Drop a catalog-linked database All catalog-linked databases must be dropped before you can disconnect or drop the connector. Catalog-linked databases do not support `UNDROP`. ```sql DROP DATABASE my_sfdc_db; ``` --- title: Explore Data Products from SAP® BDC Connect for Snowflake source: https://docs.snowflake.cn/en/user-guide/data-integration/zero-copy/sap-sql/explore-data-products.md section: Loading & Unloading Data --- # Explore Data Products from %sapbdc% - [About Snowflake and SAP® Zero-Copy Integration](/user-guide/data-integration/zero-copy/about-sap-snowflake) - [Set Up SAP® BDC Connect for Snowflake Zerocopy Connector](/user-guide/data-integration/zero-copy/sap-sql/setup) - [SAP® BDC Connect for Snowflake Zerocopy Connector — Security and Privileges](/user-guide/data-integration/zero-copy/sap-sql/security) This topic describes how to use a Zerocopy Connector to list available SAP® data products, create catalog-linked databases, and query the shared data in Snowflake. The connector must be in `CONNECTED` state before performing any of the steps in this topic. ## In SAP® BDC, choose data products to share with Snowflake To search for and share data products with Snowflake, users must use the central SAP Business Data Cloud catalog and have a global role that grants them the following privileges: - BDC Data Packages (read) - To access SAP Business Data Cloud. - Catalog Asset (read) - To access the catalog and view objects in the Assets and Data Products collections. - Cloud Data Product (share) - To share data products to target systems. Users with these privileges can share data products from the SAP Business Data Cloud catalog with the desired SAP Snowflake account to make them available for consumption to specific roles in that account. To share data products with Snowflake: 1. In the central SAP Business Data Cloud catalog, select data products to share with an SAP Snowflake account 2. From **Catalog & Marketplace**, search for (or use filters) to find the data products to be shared 3. From the search results, select **Share** in the data product to be shared (for example, customer) to open the **Manage Share Access** dialog 4. In the **Overview** section, learn more about the data product by reviewing its details and available objects. 5. Under **Target System**: 1. Choose the Snowflake account with the enrolled Zerocopy Connector to share with (if there is more than one). 2. Select **Update**. A message confirms the share process has started. After it finishes, a notification shows the result. ## In Snowflake, list shared data products To list the data products that SAP® BDC has shared with your Snowflake account, call the `SYSTEM$ZEROCOPY_CONNECTOR_LIST_SHARES` function: ```sql SELECT SYSTEM$ZEROCOPY_CONNECTOR_LIST_SHARES('my_db.my_schema.my_sap_connector'); ``` The function returns a JSON array. Each element represents one shared data product: ```text [ { "name": "usid:b077d21c-b7a2-479a-a20e-bba1dbe91034:ns:sap.s4pce:r:SalesOrder:v:1", "id": "25c0de58-6e61-4bcc-ba68-c2c15b7a2d4b", "display_name": "Sales Order (BDF730, sap.s4pce:apiResource:SalesOrder:v1)", "comment": "An agreement between a vendor and a customer to provide products on a specific date.", "status": "MOUNTED", "catalog_linked_databases": [ { "name": "SALES_ORDER_CLD" } ], "properties": { "sap.ord.apiResource.ordId": "sap.s4pce:apiResource:SalesOrder:v1", "sap.ord.systemInstance.name": "BDF730", "sap.ord.systemInstance.id": "30f962e7-791c-41d7-9e72-1534823e8b21" } } ] ``` To filter and search more easily, parse the JSON output into a tabular format using `PARSE_JSON` and `LATERAL FLATTEN`: ```sql WITH raw AS ( SELECT PARSE_JSON( SYSTEM$ZEROCOPY_CONNECTOR_LIST_SHARES('my_db.my_schema.my_sap_connector') ) AS json_data ) SELECT f.value:name::STRING AS name, f.value:id::STRING AS id, f.value:display_name::STRING AS display_name, f.value:comment::STRING AS comment, f.value:properties['sap.ord.apiResource.ordId']::STRING AS api_resource_ord_id, f.value:properties['sap.ord.systemInstance.name']::STRING AS system_instance_name, f.value:properties['sap.ord.systemInstance.id']::STRING AS system_instance_id FROM raw, LATERAL FLATTEN(INPUT => json_data) f; ``` ## Create a Catalog-Linked Database To mount a shared SAP® data product in Snowflake, create a catalog-linked database using the `LINKED_ZEROCOPY_CONNECTOR` clause. The role requires `CREATE DATABASE` on the account and `USAGE` on the connector. The owner of the catalog-linked database can be different from the owner of the connector. ```sql CREATE DATABASE my_sales_order LINKED_ZEROCOPY_CONNECTOR = ( CONNECTOR_NAME = 'my_db.my_schema.my_sap_connector', SHARE_NAME = 'usid:b077d21c-b7a2-479a-a20e-bba1dbe91034:ns:sap.s4pce:r:SalesOrder:v:1', SYNC_INTERVAL_SECONDS = 86400 ); ``` When a catalog-linked database is created, a read-only schema named `snowflake$` is automatically created within it. This schema contains [Semantic Views](/user-guide/views-semantic/overview) generated from the SAP® Core Schema Notation (CSN). Semantic Views add business meaning to the incoming shared data by defining metrics, entities, and relationships — enabling consistent business definitions and powering AI capabilities such as [Cortex Analyst](/user-guide/snowflake-cortex/cortex-analyst) directly on top of the SAP® data in Snowflake. Use `SYNC_INTERVAL_SECONDS` to control how frequently Snowflake automatically discovers schema and table changes from the shared data product. The value can range from 30 to 86400 seconds (1 day). The default value for SAP® BDC is 86400 seconds. You can create multiple catalog-linked databases from the same connector, one per data product shared from SAP® BDC. To confirm the database was created, use [SHOW DATABASES](/sql-reference/sql/show-databases): ```sql SHOW DATABASES LIKE 'MY_SALES_ORDER%'; ``` ## Explore the Data List the schemas and tables available in the catalog-linked database: ```sql SHOW SCHEMAS IN DATABASE my_sales_order; SHOW TABLES IN DATABASE my_sales_order; ``` Query the data: ```sql SELECT * FROM my_sales_order.salesorder.salesorder LIMIT 100; ``` You can join tables across multiple catalog-linked databases. For example, to find the top customers by revenue using data from two shared data products: ```sql SELECT s.salesorder, s.soldtoparty, c.customername, c.country, s.totalnetamount FROM my_sales_order.salesorder.salesorder s JOIN my_customers.customer.customer c ON s.soldtoparty = c.customer WHERE s.overallsdprocessingstatus != 'C' ORDER BY s.totalnetamount DESC LIMIT 10; ``` ## Create Table As Select (CTAS) To persist query results as a native Snowflake table, use CREATE TABLE AS SELECT (CTAS). Create a new database to hold the results: ```sql CREATE DATABASE IF NOT EXISTS my_ctas_db; USE DATABASE my_ctas_db; CREATE OR REPLACE TABLE top_customers_by_revenue AS SELECT c.customer, c.customername, c.country, c.region, c.businesstype, COUNT(DISTINCT s.salesorder) AS num_orders, SUM(s.totalnetamount) AS total_revenue, AVG(s.totalnetamount) AS avg_order_amount FROM my_customers.customer.customer c JOIN my_sales_order.salesorder.salesorder s ON c.customer = s.soldtoparty WHERE c.deletionindicator = FALSE GROUP BY 1, 2, 3, 4, 5; -- Query the result table SELECT * FROM top_customers_by_revenue LIMIT 10; ``` ## Drop a Catalog-Linked Database All catalog-linked databases must be dropped before you can disconnect or drop the connector. Catalog-linked databases do not support `UNDROP`. ```sql DROP DATABASE my_sales_order; ``` --- title: ExternalHazelcastCacheManager source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/externalhazelcastcachemanager.md section: Loading & Unloading Data --- # ExternalHazelcastCacheManager This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description A service that provides cache instances backed by Hazelcast running outside of NiFi. ## Tags cache, hazelcast ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: ExtractAvroMetadata 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/extractavrometadata.md section: Loading & Unloading Data --- # ExtractAvroMetadata 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-avro-nar ## Description Extracts metadata from the header of an Avro datafile. ## Tags avro, metadata, schema ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: ExtractEmailAttachments 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/extractemailattachments.md section: Loading & Unloading Data --- # ExtractEmailAttachments 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-email-nar ## Description Extract attachments from a mime formatted email file, splitting them into individual flowfiles. ## Tags email, split ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Relationships
## Writes attributes
--- title: ExtractEmailHeaders 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/extractemailheaders.md section: Loading & Unloading Data --- # ExtractEmailHeaders 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-email-nar ## Description Using the flowfile content as source of data, extract header from an RFC compliant email file adding the relevant attributes to the flowfile. This processor does not perform extensive RFC validation but still requires a bare minimum compliance with RFC 2822 ## Tags email, split ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: ExtractGrok 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/extractgrok.md section: Loading & Unloading Data --- # ExtractGrok 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Evaluates one or more Grok Expressions against the content of a FlowFile, adding the results as attributes or replacing the content of the FlowFile with a JSON notation of the matched content ## Tags delimit, extract, grok, log, parse, text ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Restrictions
## Relationships
## Writes attributes
--- title: ExtractRecordSchema 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/extractrecordschema.md section: Loading & Unloading Data --- # ExtractRecordSchema 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Extracts the record schema from the FlowFile using the supplied Record Reader and writes it to the *avro.schema* attribute. ## Tags avro, csv, freeform, generic, json, record, schema, text, xml ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: ExtractSchemaColumns 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/extractschemacolumns.md section: Loading & Unloading Data --- # ExtractSchemaColumns 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-record-schema-nar ## Description Extracts the record schema columns from the FlowFile using the supplied Record Reader and writes it to the *schema.columns* attribute. ## Tags avro, csv, freeform, generic, json, record, schema, text, xml ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: ExtractStructuredBoxFileMetadata 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/extractstructuredboxfilemetadata.md section: Loading & Unloading Data --- # ExtractStructuredBoxFileMetadata 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-box-nar ## Description Extracts metadata from a Box file using Box AI. The extraction can use either a template or a list of fields. The extracted metadata is written to the FlowFile content as JSON. ## Tags ai, box, extract, metadata, storage ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.box.FetchBoxFile](/user-guide/data-integration/openflow/processors/fetchboxfile) - [org.apache.nifi.processors.box.ListBoxFile](/user-guide/data-integration/openflow/processors/listboxfile) - [org.apache.nifi.processors.box.ListBoxFileMetadataTemplates](/user-guide/data-integration/openflow/processors/listboxfilemetadatatemplates) - [org.apache.nifi.processors.box.UpdateBoxFileMetadataInstance](/user-guide/data-integration/openflow/processors/updateboxfilemetadatainstance) --- title: ExtractText 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/extracttext.md section: Loading & Unloading Data --- # ExtractText 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Evaluates one or more Regular Expressions against the content of a FlowFile. The results of those Regular Expressions are assigned to FlowFile Attributes. Regular Expressions are entered by adding user-defined properties; the name of the property maps to the Attribute Name into which the result will be placed. The attributes are generated differently based on the enabling of named capture groups. If named capture groups are not enabled: The first capture group, if any found, will be placed into that attribute name. But all capture groups, including the matching string sequence itself will also be provided at that attribute name with an index value provided, with the exception of a capturing group that is optional and does not match - for example, given the attribute name "regex" and expression "abc(def)?(g)" we would add an attribute "regex.1" with a value of "def" if the "def" matched. If the "def" did not match, no attribute named "regex.1" would be added but an attribute named "regex.2" with a value of "g" will be added regardless. If named capture groups are enabled: Each named capture group, if found will be placed into the attributes name with the name provided. If enabled the matching string sequence itself will be placed into the attribute name. If multiple matches are enabled, and index will be applied after the first set of matches. The exception is a capturing group that is optional and does not match For example, given the attribute name "regex" and expression "abc(?<NAMED>def)?(?<NAMED-TWO>g)" we would add an attribute "regex. NAMED" with the value of "def" if the "def" matched. We would add an attribute "regex. NAMED-TWO" with the value of "g" if the "g" matched regardless. The value of the property must be a valid Regular Expressions with one or more capturing groups. If named capture groups are enabled, all capture groups must be named. If they are not, then the processor configuration will fail validation. If the Regular Expression matches more than once, only the first match will be used unless the property enabling repeating capture group is set to true. If any provided Regular Expression matches, the FlowFile(s) will be routed to 'matched'. If no provided Regular Expression matches, the FlowFile will be routed to 'unmatched' and no attributes will be applied to the FlowFile. ## Tags Regular Expression, Text, evaluate, extract, regex ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: FetchAzureBlobStorage_v12 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/fetchazureblobstorage_v12.md section: Loading & Unloading Data --- # FetchAzureBlobStorage_v12 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-azure-nar ## Description Retrieves the specified blob from Azure Blob Storage and writes its content to the content of the FlowFile. The processor uses Azure Blob Storage client library v12. ## Tags azure, blob, cloud, microsoft, storage ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## Use Cases Involving Other Components | Retrieve all files in an Azure Blob Storage container | | ----------------------------------------------------- | ## See also - [org.apache.nifi.processors.azure.storage.DeleteAzureBlobStorage_v12](/user-guide/data-integration/openflow/processors/deleteazureblobstorage_v12) - [org.apache.nifi.processors.azure.storage.ListAzureBlobStorage_v12](/user-guide/data-integration/openflow/processors/listazureblobstorage_v12) - [org.apache.nifi.processors.azure.storage.PutAzureBlobStorage_v12](/user-guide/data-integration/openflow/processors/putazureblobstorage_v12) --- title: FetchAzureDataLakeStorage 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/fetchazuredatalakestorage.md section: Loading & Unloading Data --- # FetchAzureDataLakeStorage 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-azure-nar ## Description Fetch the specified file from Azure Data Lake Storage ## Tags adlsgen2, azure, cloud, datalake, microsoft, storage ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## Use Cases Involving Other Components | Retrieve all files in an Azure DataLake Storage directory | | --------------------------------------------------------- | ## See also - [org.apache.nifi.processors.azure.storage.DeleteAzureDataLakeStorage](/user-guide/data-integration/openflow/processors/deleteazuredatalakestorage) - [org.apache.nifi.processors.azure.storage.ListAzureDataLakeStorage](/user-guide/data-integration/openflow/processors/listazuredatalakestorage) - [org.apache.nifi.processors.azure.storage.PutAzureDataLakeStorage](/user-guide/data-integration/openflow/processors/putazuredatalakestorage) --- title: FetchBoxFile 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/fetchboxfile.md section: Loading & Unloading Data --- # FetchBoxFile 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-box-nar ## Description Fetches files from a Box Folder. Designed to be used in tandem with ListBoxFile. ## Tags box, fetch, storage ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.box.ListBoxFile](/user-guide/data-integration/openflow/processors/listboxfile) - [org.apache.nifi.processors.box.PutBoxFile](/user-guide/data-integration/openflow/processors/putboxfile) --- title: FetchBoxFileInfo 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/fetchboxfileinfo.md section: Loading & Unloading Data --- # FetchBoxFileInfo 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-box-nar ## Description Fetches metadata for files from Box and adds it to the FlowFile's attributes. ## Tags box, fetch, metadata, storage ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.box.FetchBoxFile](/user-guide/data-integration/openflow/processors/fetchboxfile) - [org.apache.nifi.processors.box.ListBoxFile](/user-guide/data-integration/openflow/processors/listboxfile) - [org.apache.nifi.processors.box.PutBoxFile](/user-guide/data-integration/openflow/processors/putboxfile) --- title: FetchBoxFileMetadataInstance 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/fetchboxfilemetadatainstance.md section: Loading & Unloading Data --- # FetchBoxFileMetadataInstance 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-box-nar ## Description Retrieves specific metadata instance associated with a Box file using template key and scope. ## Tags box, instance, metadata, storage, template ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.box.FetchBoxFile](/user-guide/data-integration/openflow/processors/fetchboxfile) - [org.apache.nifi.processors.box.FetchBoxFileInfo](/user-guide/data-integration/openflow/processors/fetchboxfileinfo) - [org.apache.nifi.processors.box.ListBoxFile](/user-guide/data-integration/openflow/processors/listboxfile) - [org.apache.nifi.processors.box.ListBoxFileMetadataInstances](/user-guide/data-integration/openflow/processors/listboxfilemetadatainstances) --- title: FetchBoxFileRepresentation 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/fetchboxfilerepresentation.md section: Loading & Unloading Data --- # FetchBoxFileRepresentation 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-box-nar ## Description Fetches a Box file representation using a representation hint and writes it to the FlowFile content. ## Tags box, cloud, content, download, file, representation, storage ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.box.FetchBoxFile](/user-guide/data-integration/openflow/processors/fetchboxfile) - [org.apache.nifi.processors.box.ListBoxFile](/user-guide/data-integration/openflow/processors/listboxfile) --- title: FetchDistributedMapCache 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/fetchdistributedmapcache.md section: Loading & Unloading Data --- # FetchDistributedMapCache 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Computes cache key(s) from FlowFile attributes, for each incoming FlowFile, and fetches the value(s) from the Distributed Map Cache associated with each key. If configured without a destination attribute, the incoming FlowFile 's content is replaced with the binary data received by the Distributed Map Cache. If there is no value stored under that key then the flow file will be routed to' not-found '. Note that the processor will always attempt to read the entire cached value into memory before placing it in it's destination. This could be potentially problematic if the cached value is very large. ## Tags cache, distributed, fetch, map ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.standard.PutDistributedMapCache](/user-guide/data-integration/openflow/processors/putdistributedmapcache) --- title: FetchDropbox 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/fetchdropbox.md section: Loading & Unloading Data --- # FetchDropbox 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-dropbox-processors-nar ## Description Fetches files from Dropbox. Designed to be used in tandem with ListDropbox. ## Tags dropbox, fetch, storage ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.dropbox.ListDropbox](/user-guide/data-integration/openflow/processors/listdropbox) - [org.apache.nifi.processors.dropbox.PutDropbox](/user-guide/data-integration/openflow/processors/putdropbox) --- title: FetchFile 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/fetchfile.md section: Loading & Unloading Data --- # FetchFile 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Reads the contents of a file from disk and streams it into the contents of an incoming FlowFile. Once this is done, the file is optionally moved elsewhere or deleted to help keep the file system organized. ## Tags fetch, files, filesystem, get, ingest, ingress, input, local, source ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Restrictions
## Relationships
## Use Cases Involving Other Components | Ingest all files from a directory into NiFi | | ----------------------------------------------------------------------- | | Ingest specific files from a directory into NiFi, filtering on filename | ## See also - [org.apache.nifi.processors.standard.GetFile](/user-guide/data-integration/openflow/processors/getfile) - [org.apache.nifi.processors.standard.ListFile](/user-guide/data-integration/openflow/processors/listfile) - [org.apache.nifi.processors.standard.PutFile](/user-guide/data-integration/openflow/processors/putfile) --- title: FetchFTP 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/fetchftp.md section: Loading & Unloading Data --- # FetchFTP 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Fetches the content of a file from a remote FTP server and overwrites the contents of an incoming FlowFile with the content of the remote file. ## Tags fetch, files, ftp, get, ingest, input, remote, retrieve, source ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## Use Cases Involving Other Components | Retrieve all files in a directory of an FTP Server | | -------------------------------------------------- | ## See also - [org.apache.nifi.processors.standard.GetFTP](/user-guide/data-integration/openflow/processors/getftp) - [org.apache.nifi.processors.standard.GetSFTP](/user-guide/data-integration/openflow/processors/getsftp) - [org.apache.nifi.processors.standard.PutFTP](/user-guide/data-integration/openflow/processors/putftp) - [org.apache.nifi.processors.standard.PutSFTP](/user-guide/data-integration/openflow/processors/putsftp) --- title: FetchGCSObject 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/fetchgcsobject.md section: Loading & Unloading Data --- # FetchGCSObject 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-gcp-nar ## Description Fetches a file from a Google Cloud Bucket. Designed to be used in tandem with ListGCSBucket. ## Tags fetch, gcs, google, google cloud, storage ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## Use Cases Involving Other Components | Retrieve all files in a Google Compute Storage (GCS) bucket | | ----------------------------------------------------------- | ## See also - [org.apache.nifi.processors.gcp.storage.DeleteGCSObject](/user-guide/data-integration/openflow/processors/deletegcsobject) - [org.apache.nifi.processors.gcp.storage.ListGCSBucket](/user-guide/data-integration/openflow/processors/listgcsbucket) - [org.apache.nifi.processors.gcp.storage.PutGCSObject](/user-guide/data-integration/openflow/processors/putgcsobject) --- title: FetchGoogleDrive 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/fetchgoogledrive.md section: Loading & Unloading Data --- # FetchGoogleDrive 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-gcp-nar ## Description Fetches files from a Google Drive Folder. Designed to be used in tandem with ListGoogleDrive. Please see Additional Details to set up access to Google Drive. ## Tags drive, fetch, google, storage ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## Use Cases Involving Other Components | Retrieve all files in a Google Drive folder | | ------------------------------------------- | ## See also - [org.apache.nifi.processors.gcp.drive.ListGoogleDrive](/user-guide/data-integration/openflow/processors/listgoogledrive) - [org.apache.nifi.processors.gcp.drive.PutGoogleDrive](/user-guide/data-integration/openflow/processors/putgoogledrive) --- title: FetchGoogleDriveFileComments 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/fetchgoogledrivefilecomments.md section: Loading & Unloading Data --- # FetchGoogleDriveFileComments 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-google-drive-nar ## Description Fetches comments and their replies for a Google Drive file. The file ID can be set by a FlowFile attribute. Records include comment metadata such as deleted status, resolved status, anchors, and a nested array of replies. ## Tags comments, drive, gcp, google, openflow, replies ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: FetchGoogleDriveMetadata 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/fetchgoogledrivemetadata.md section: Loading & Unloading Data --- # FetchGoogleDriveMetadata 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-google-drive-nar ## Description Fetches Google Drive file metadata. This includes the file's name, size, MIME type, and permissions. The file ID must be provided as a FlowFile attribute. ## Tags authorization, cloud, drive, gcp, google, openflow, permissions, storage, unstructured ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [com.snowflake.openflow.runtime.processors.google.CaptureGoogleDriveChanges](/user-guide/data-integration/openflow/processors/capturegoogledrivechanges) --- title: FetchGridFS 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/fetchgridfs.md section: Loading & Unloading Data --- # FetchGridFS 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-mongodb-nar ## Description Retrieves one or more files from a GridFS bucket by file name or by a user-defined query. ## Tags fetch, gridfs, mongo ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: FetchJiraFields 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/fetchjirafields.md section: Loading & Unloading Data --- # FetchJiraFields 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-atlassian-processors-nar ## Description Retrieves comprehensive metadata for all fields available in the Jira Cloud instance using the REST API v3 /field endpoint. For each field, returns detailed information including field ID/key, display name, field properties, JQL clause names for queries, and schema details with data types. ## Tags api, atlassian, fetch, jira, rest ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [com.snowflake.openflow.runtime.atlassian.jira.processors.FetchJiraIssues](/user-guide/data-integration/openflow/processors/fetchjiraissues) --- title: FetchJiraIssues 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/fetchjiraissues.md section: Loading & Unloading Data --- # FetchJiraIssues 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-atlassian-processors-nar ## Description Fetches issues from Jira Cloud using REST API v3 with configurable search options. Provides two search modes: 1. Simple Search - Filter by project name, status category, created/updated dates 2. Advanced Search - Use custom JQL (Jira Query Language) expressions Key features: - Smart pagination handling with automatic state management - Incremental sync capability using timestamps between processor runs - Timezone-aware date handling using Jira user's timezone - Configurable issue fields retrieval - Adds metadata to FlowFiles: source URL (jira.source.url), query (jira.query.jql), statement type (statement.type) - Adds insert,upsert attributes for downstream processing The processor maintains cluster state to resume operations after restarts Authentication is handled via basic auth using Jira email/API token credentials. Currently that is the only supported method. LIMITATIONS: - Jira issue deletes are not detected. ## Tags api, atlassian, fetch, jira, rest ## Input Requirement ALLOWED ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
## See also - [com.snowflake.openflow.runtime.atlassian.jira.processors.FetchJiraFields](/user-guide/data-integration/openflow/processors/fetchjirafields) --- title: FetchMicrosoftDataverseTable 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/fetchmicrosoftdataversetable.md section: Loading & Unloading Data --- # FetchMicrosoftDataverseTable 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-dataverse-processors-nar ## Description Fetch records from Microsoft Dataverse Tables ## Tags dataverse ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
--- title: FetchS3Object 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/fetchs3object.md section: Loading & Unloading Data --- # FetchS3Object 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-aws-nar ## Description Retrieves the contents of an S3 Object and writes it to the content of a FlowFile ## Tags AWS, Amazon, Fetch, Get, S3 ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## Use cases | Fetch a specific file from S3 | | ----------------------------- | ## Use Cases Involving Other Components | Retrieve all files in an S3 bucket | | ------------------------------------------------------------- | | Retrieve only files from S3 that meet some specified criteria | | Retrieve new files as they arrive in an S3 bucket | ## See also - [org.apache.nifi.processors.aws.s3.CopyS3Object](/user-guide/data-integration/openflow/processors/copys3object) - [org.apache.nifi.processors.aws.s3.DeleteS3Object](/user-guide/data-integration/openflow/processors/deletes3object) - [org.apache.nifi.processors.aws.s3.GetS3ObjectMetadata](/user-guide/data-integration/openflow/processors/gets3objectmetadata) - [org.apache.nifi.processors.aws.s3.GetS3ObjectTags](/user-guide/data-integration/openflow/processors/gets3objecttags) - [org.apache.nifi.processors.aws.s3.ListS3](/user-guide/data-integration/openflow/processors/lists3) - [org.apache.nifi.processors.aws.s3.PutS3Object](/user-guide/data-integration/openflow/processors/puts3object) - [org.apache.nifi.processors.aws.s3.TagS3Object](/user-guide/data-integration/openflow/processors/tags3object) --- title: FetchSFTP 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/fetchsftp.md section: Loading & Unloading Data --- # FetchSFTP 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Fetches the content of a file from a remote SFTP server and overwrites the contents of an incoming FlowFile with the content of the remote file. ## Tags fetch, files, get, ingest, input, remote, retrieve, sftp, source ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## Use Cases Involving Other Components | Retrieve all files in a directory of an SFTP Server | | --------------------------------------------------- | ## See also - [org.apache.nifi.processors.standard.GetFTP](/user-guide/data-integration/openflow/processors/getftp) - [org.apache.nifi.processors.standard.GetSFTP](/user-guide/data-integration/openflow/processors/getsftp) - [org.apache.nifi.processors.standard.PutFTP](/user-guide/data-integration/openflow/processors/putftp) - [org.apache.nifi.processors.standard.PutSFTP](/user-guide/data-integration/openflow/processors/putsftp) --- title: FetchSharepointFile 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/fetchsharepointfile.md section: Loading & Unloading Data --- # FetchSharepointFile 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-msgraph-nar ## Description Fetches the contents of a file from a Sharepoint Drive, optionally downloading a PDF or HTML version of the file when applicable. Any FlowFile that represents a Sharepoint folder will be routed to success without fetching contents. ## Tags cdc, document, graph, microsoft, openflow, sharepoint, unstructured ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Use Cases Involving Other Components | Fetch a file from Sharepoint by the Site URL, Drive Name and file path. | | ----------------------------------------------------------------------- | ## See also - [com.snowflake.openflow.runtime.processors.sharepoint.CaptureSharepointChanges](/user-guide/data-integration/openflow/processors/capturesharepointchanges) --- title: FetchSharepointMetadata 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/fetchsharepointmetadata.md section: Loading & Unloading Data --- # FetchSharepointMetadata 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-msgraph-nar ## Description For each drive item retrieves its metadata and permissions and writes them as FlowFile attributes. ## Tags cdc, document, graph, library, microsoft, openflow, sharepoint, unstructured ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: FetchSlackConversationInfo 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/fetchslackconversationinfo.md section: Loading & Unloading Data --- # FetchSlackConversationInfo 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-slack-processors-nar ## Description Fetches Slack conversation info and member emails ## Tags conversation, conversation.members, slack, social media, team ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: FetchSlackFile 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/fetchslackfile.md section: Loading & Unloading Data --- # FetchSlackFile 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-slack-processors-nar ## Description Downloads a file shared on Slack. Writes the file content to the FlowFile content and FlowFile attributes from the file. ## Tags download, file, slack ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [com.snowflake.openflow.runtime.processors.slack.FetchSlackConversationInfo](/user-guide/data-integration/openflow/processors/fetchslackconversationinfo) - [com.snowflake.openflow.runtime.processors.slack.FetchSlackMessage](/user-guide/data-integration/openflow/processors/fetchslackmessage) --- title: FetchSlackMessage 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/fetchslackmessage.md section: Loading & Unloading Data --- # FetchSlackMessage 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-slack-processors-nar ## Description Fetches data about a single Slack message ## Tags conversation, conversation.history, slack, social media, team, text, unstructured ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: FetchSmb 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/fetchsmb.md section: Loading & Unloading Data --- # FetchSmb 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-smb-nar ## Description Fetches files from a SMB Share. Designed to be used in tandem with ListSmb. ## Tags cifs, fetch, files, samba, smb ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.smb.GetSmbFile](/user-guide/data-integration/openflow/processors/getsmbfile) - [org.apache.nifi.processors.smb.ListSmb](/user-guide/data-integration/openflow/processors/listsmb) - [org.apache.nifi.processors.smb.PutSmbFile](/user-guide/data-integration/openflow/processors/putsmbfile) --- title: FetchSnowflakeTableProperties 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/fetchsnowflaketableproperties.md section: Loading & Unloading Data --- # FetchSnowflakeTableProperties 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-snowflake-processors-nar ## Description Reads properties from a table and stores them as flow file attributes. ## Tags database, jdbc, openflow, snowflake ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: FetchSourceTableSchema 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/fetchsourcetableschema.md section: Loading & Unloading Data --- # FetchSourceTableSchema 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-database-cdc-processors-nar ## Description Fetches the table schema (i.e., column names, data types, etc.) for a given table in a database, converting the data types to Snowflake-compatible types. The schema is written to the FlowFile content as a JSON object, in a form such as: \{ "columns": [ \{ "name": "<columnName>", "type": "<snowflakeType>", "nullable": <true|false>, "scale": <scale>, "precision": <precision> \}, ... ], "primaryKeys": ["<primaryKey1>", "<primaryKey2>", ...] \} ## Tags ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: FetchTableSnapshot 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/fetchtablesnapshot.md section: Loading & Unloading Data --- # FetchTableSnapshot 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-database-cdc-processors-nar ## Description Fetches a snapshot of a table from a database. The snapshot is fetched incrementally, using the primary key columns of the table to fetch rows in batches. Replicating a table without primary key is not supported. The snapshot is written to a FlowFile in the specified Record Writer format. The input FlowFile is expected to consist of a JSON representation of the table schema in the following format: \{ "columns": [\{ "name": "<column name>", "type": "<column type>" \}, \{ "name": "<column name>", "type": "<column type>" \}, ... ], "primaryKeys": ["<name of first primary key column>", "<name of second primary key column>", ...] \} Only those columns that are specified in the schema will be fetched from the table. ## Tags database, fetch, rdbms, snapshot, snowflake, table ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: FilterAttribute 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/filterattribute.md section: Loading & Unloading Data --- # FilterAttribute 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Filters the attributes of a FlowFile by retaining specified attributes and removing the rest or by removing specified attributes and retaining the rest. ## Tags Attribute Expression Language, attributes, delete, filter, modification, regex, regular expression, remove, retain ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Use cases | Retain all FlowFile attributes matching a regular expression | | ------------------------------------------------------------ | | Remove only a specified set of FlowFile attributes | --- title: FindConfluencePages 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/findconfluencepages.md section: Loading & Unloading Data --- # FindConfluencePages 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-atlassian-processors-nar ## Description Processor for finding Confluence pages using space name and page name. ## Tags Preview, atlassian, confluence, fetch, pages ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: FindSharepointDriveItem 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/findsharepointdriveitem.md section: Loading & Unloading Data --- # FindSharepointDriveItem 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-msgraph-nar ## Description Finds a Sharepoint Drive Item by its Drive ID and Item path. ## Tags document, graph, microsoft, openflow, sharepoint, unstructured ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [com.snowflake.openflow.runtime.processors.sharepoint.FetchSharepointFile](/user-guide/data-integration/openflow/processors/fetchsharepointfile) - [com.snowflake.openflow.runtime.processors.sharepoint.ListSharepointDrives](/user-guide/data-integration/openflow/processors/listsharepointdrives) --- title: FlattenJson 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/flattenjson.md section: Loading & Unloading Data --- # FlattenJson 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Provides the user with the ability to take a nested JSON document and flatten it into a simple key/value pair document. The keys are combined at each level with a user-defined separator that defaults to '.'. This Processor also lets you unflatten the flattened JSON. It supports four kinds of flatten mode such as normal, keep-arrays, dot notation for MongoDB query and keep-primitive-arrays. Default flatten mode is 'keep-arrays'. ## Tags flatten, json, unflatten ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: ForkEnrichment 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/forkenrichment.md section: Loading & Unloading Data --- # ForkEnrichment 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Used in conjunction with the JoinEnrichment processor, this processor is responsible for adding the attributes that are necessary for the JoinEnrichment processor to perform its function. Each incoming FlowFile will be cloned. The original FlowFile will have appropriate attributes added and then be transferred to the 'original' relationship. The clone will have appropriate attributes added and then be routed to the 'enrichment' relationship. See the documentation for the JoinEnrichment processor (and especially its Additional Details) for more information on how these Processors work together and how to perform enrichment tasks in NiFi by using these Processors. ## Tags enrich, fork, join, record ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.standard.JoinEnrichment](/user-guide/data-integration/openflow/processors/joinenrichment) --- title: ForkRecord 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/forkrecord.md section: Loading & Unloading Data --- # ForkRecord 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description This processor allows the user to fork a record into multiple records. The user must specify at least one Record Path, as a dynamic property, pointing to a field of type ARRAY containing RECORD objects. The processor accepts two modes: 'split' and 'extract'. In both modes, there is one record generated per element contained in the designated array. In the 'split' mode, each generated record will preserve the same schema as given in the input but the array will contain only one element. In the 'extract' mode, the element of the array must be of record type and will be the generated record. Additionally, in the 'extract' mode, it is possible to specify if each generated record should contain all the fields of the parent records from the root level to the extracted record. This assumes that the fields to add in the record are defined in the schema of the Record Writer controller service. See examples in the additional details documentation of this processor. ## Tags array, content, event, fork, record, stream ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: FreeFormTextRecordSetWriter source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/freeformtextrecordsetwriter.md section: Loading & Unloading Data --- # FreeFormTextRecordSetWriter This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Writes the contents of a RecordSet as free-form text. The configured text is able to make use of the Expression Language to reference each of the fields that are available in a Record, as well as the attributes in the FlowFile and variables. If there is a name collision, the field name/value is used before attributes or variables. Each record in the RecordSet will be separated by a single newline character. ## Tags el, expression, freeform, language, record, recordset, resultset, serialize, text, writer ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: GCPCredentialsControllerService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/gcpcredentialscontrollerservice.md section: Loading & Unloading Data --- # GCPCredentialsControllerService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Defines credentials for Google Cloud Platform processors. Uses Application Default credentials without configuration. Application Default credentials support environmental variable (GOOGLE_APPLICATION_CREDENTIALS) pointing to a credential file, the config generated by *gcloud auth application-default login*, AppEngine/Compute Engine service accounts, etc. ## Tags credentials, gcp, provider ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted ## Restrictions
## System Resource Considerations This component does not specify system resource considerations. --- title: GCSFileResourceService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/gcsfileresourceservice.md section: Loading & Unloading Data --- # GCSFileResourceService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides a Google Compute Storage (GCS) file resource for other components. ## Tags file, gcs, resource ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: gen 2 connector configuration and versioning source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/gen2/connector-versioning.md section: Loading & Unloading Data --- # Gen 2 connector configuration and versioning Available to all accounts. - [Second generation Openflow objects and interfaces](/user-guide/data-integration/openflow/gen2/index) - [Configure a connector with the setup wizard](/user-guide/data-integration/openflow/gen2/setup-connector-wizard) - [Configure a gen 2 connector with SQL](/user-guide/data-integration/openflow/gen2/configure-connector-sql) - [Manage the gen 2 Openflow connector lifecycle](/user-guide/data-integration/openflow/gen2/manage-connector-lifecycle) - [Using a Git repository in Snowflake](/developer-guide/git/git-overview) **Using the setup wizard or** **Installed Connectors** **only?** You do not need this topic for day-to-day work. The Openflow UI creates and manages configuration versions automatically as you install, edit, and save connector settings. Labels such as **Draft** and **Edits not applied** reflect the same version states described below—you can follow the wizard and UI prompts without reading about stages or `COMMIT`. Read this topic if you configure connectors with SQL, `GET`/`PUT` on stages, Git, or other automation—or if you want to understand what the UI is doing under the hood. Gen 2 Openflow connectors are **File Based Entities (FBEs)**: Snowflake objects whose configuration is stored as files on an internal **versioned stage** that Snowflake creates and manages on the connector object. You do not create this stage with `CREATE STAGE`—it is attached automatically when the connector is created. Configuration files (for example, `config.json`) and assets (for example, JDBC driver JARs) live under versioned paths on that stage. This topic explains the version states, UI labels, SQL workflow for editing connector configuration, and how to list, download, and upload files on the connector stage. Other Snowflake object types (for example, dbt projects and Cortex agents) use a similar versioned-stage model with their own `snow://` URI schemes; here we cover Openflow connectors only. ## Access the connector's versioned stage Each connector version is an immutable snapshot in the connector's version history. Versions behave similarly to Git commits: if a new version does not change a file, both versions can reference the same underlying file. Use the `snow://openflow_connector/` URI scheme to reference files: ``` snow://openflow_connector/../versions//[] ``` version is one of: - `live` — writable working copy (see [](#label-openflow-fbe-version-states) below) - `LAST` — alias for the most recently committed (default) version - `VERSION$N` — a specific committed version (for example, `VERSION$1`) - A user-assigned name — set when you commit; preserved for later reference (for example, `production-config`) You can use a user-assigned name or `VERSION$N` in `snow://` paths and SQL when referencing a committed version. List, download, and upload files with the standard stage commands documented in [File staging commands](/sql-reference/commands-file) (`LIST`, `GET`, and `PUT`). Pass the URI as a quoted string (for example, `GET 'snow://openflow_connector/...'`). Snowsight does not support `GET` or `PUT` on connector stages. Use %sf-cli% or another client that supports stage file operations. You can also inspect version metadata with `SHOW VERSIONS IN OPENFLOW CONNECTOR` and connector properties (including the active version) with `DESCRIBE OPENFLOW CONNECTOR`. See [SHOW VERSIONS IN OPENFLOW CONNECTOR](/sql-reference/sql/show-versions-in-openflow-connector) and [DESCRIBE OPENFLOW CONNECTOR](/sql-reference/sql/desc-openflow-connector). ## Version states
The **live** version is your working copy. The **default** version is what runs when the connector starts in the target runtime. In stage paths, `versions/LAST` points to the **default** (committed) version. Committing the live version creates a new immutable default and removes the live version. While a connector is **RUNNING**, you can still edit the live version. Changes are not applied to the running connector until you **COMMIT** (UI **Apply** or SQL `COMMIT`). ## UI labels
## Configuration workflow New connectors created with `CREATE OPENFLOW CONNECTOR ... FROM DEFINITION` or the setup wizard start with a live version and no default (**Draft**). 1. Upload or edit files in the live version (skip `ADD LIVE VERSION` on a new connector—it already has a live version). 2. Commit to promote live to default: ```sql ALTER OPENFLOW CONNECTOR my_db.my_schema.my_connector COMMIT; ``` 3. To discard uncommitted changes: ```sql ALTER OPENFLOW CONNECTOR my_db.my_schema.my_connector ABORT; ``` 4. To edit a committed connector, create a new live version seeded from the current default: ```sql ALTER OPENFLOW CONNECTOR my_db.my_schema.my_connector ADD LIVE VERSION FROM LAST; ``` ## Stage file operations The following examples use the [snow://openflow_connector/ URI](#label-openflow-fbe-versioned-stage). Replace `my_db.my_schema.my_connector` with your connector's fully qualified name. List files in the live version: ```sql LS 'snow://openflow_connector/my_db.my_schema.my_connector/versions/live'; ``` Download the last committed `config.json` (use `snow sql` or another client that supports `GET` on stages; Snowsight does not support `GET`/`PUT` on stages): ```sql GET 'snow://openflow_connector/my_db.my_schema.my_connector/versions/LAST/config.json' file:///path/to/local/; ``` Upload to the live version: ```sql PUT 'file:///path/to/config.json' 'snow://openflow_connector/my_db.my_schema.my_connector/versions/live/config.json' AUTO_COMPRESS = FALSE OVERWRITE = TRUE; ``` After uploading, commit: ```sql ALTER OPENFLOW CONNECTOR my_db.my_schema.my_connector COMMIT; SELECT SYSTEM$WAIT_FOR_STABLE_OPENFLOW_CONNECTORS(600, 'my_db.my_schema.my_connector'); ``` ## Create from a known configuration Use this workflow when you already have a **validated** connector configuration and want to create another connector with the same settings—for example, standing up a matching connector in a second runtime, or automating repeat deployments with CI/CD. This is **not** the path for your first connector. Create and configure a connector once with the setup wizard or `CREATE OPENFLOW CONNECTOR ... FROM DEFINITION`, then export the configuration. ### Definition vs configuration A catalog **definition** (for example, `OPENFLOW_POSTGRES_CDC`) and instance **configuration** (`config.json`) are separate: - `FROM DEFINITION` in `CREATE OPENFLOW CONNECTOR` selects the catalog connector type. You then edit `config.json` on the connector's versioned stage and **COMMIT**. - `FROM` a stage path supplies a complete configuration bundle from any stage reference—a Git repository stage (`@my_git_repo/...`), another connector's stage in the same account (`snow://openflow_connector/...`), or another internal stage. The catalog definition is named inside `config.json` as `connectorDefinitionId`—there is no `FROM DEFINITION` clause in the `CREATE` command. When you use `FROM` with a stage path, Openflow reads `connectorDefinitionId` from `config.json` to determine the connector type—you do not use `FROM DEFINITION` in `CREATE`. The stage holds only instance configuration: `config.json`, asset files (such as JDBC drivers), and metadata. Snowflake supplies the catalog connector package at create time; you do not copy it onto the stage. Before you run `CREATE`, update connection URLs, secret references, and destination settings for the target runtime. ### Initial state difference
### Workflow 1. Create and configure a connector with the wizard or `FROM DEFINITION`. Commit the configuration when it works in your source environment. 2. Register a Git repository in Snowflake if you do not already have one. See [Using a Git repository in Snowflake](/developer-guide/git/git-overview). 3. Export the connector configuration: ```sql ALTER OPENFLOW CONNECTOR my_db.my_schema.my_connector PUSH TO '@my_git_repo/branches/main/connectors/my_connector' USERNAME = 'my-git-username' PASSWORD = 'my-git-token' NAME = 'My Name' EMAIL = 'my.email@example.com' COMMENT = 'Export connector config'; ``` 4. Review and update `config.json` in the repository for the target environment (secrets, URLs, destination settings). 5. Create the new connector from the stage path: ```sql CREATE OPENFLOW CONNECTOR my_db.my_schema.my_connector_prod IN RUNTIME my_db.my_schema.my_prod_runtime FROM '@my_git_repo/branches/main/connectors/my_connector/' COMMENT = 'Created from validated stage config'; ``` You can also use a `snow://openflow_connector/.../versions/LAST/` URI to clone a connector in the same account without Git—for example, `'snow://openflow_connector/my_db.my_schema.my_connector/versions/LAST/'`. For `CREATE`, `ADD VERSION FROM`, `PUSH`, and `PULL` syntax, see [CREATE OPENFLOW CONNECTOR](/sql-reference/sql/create-openflow-connector) and [ALTER OPENFLOW CONNECTOR](/sql-reference/sql/alter-openflow-connector). ## Secrets in configuration Sensitive values (for example, database passwords) should reference [Snowflake secrets](/sql-reference/sql/create-secret) rather than plain text in `config.json`. See [Secrets in configuration](#label-openflow-configure-connector-sql-secrets) in [Configure a gen 2 connector with SQL](/user-guide/data-integration/openflow/gen2/configure-connector-sql). --- title: GenerateAnswersFromContext 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/generateanswersfromcontext.md section: Loading & Unloading Data --- # GenerateAnswersFromContext 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-rag-evaluation-processors-nar ## Description Generates synthetic answers for each question present in the incoming records using a Large Language Model (LLM). For every record, the processor extracts the question and its associated context based on the specified RecordPaths, constructs a prompt, and sends it to an LLM provider to obtain a synthetic answer. The generated answer is then inserted into the record at the designated RecordPath. ## Tags ai, answers, contextual, generation, llm, nlp, openai, openflow, rag, synthetic ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: GenerateAnswersFromGroundTruth 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/generateanswersfromgroundtruth.md section: Loading & Unloading Data --- # GenerateAnswersFromGroundTruth 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-rag-evaluation-processors-nar ## Description Generates synthetic answers for each question in the incoming records using an LLM. The synthetic answers are added to the specified RecordPath within each record. Additionally, the processor tracks the number of answers generated and updates the FlowFile attributes accordingly. ## Tags ai, answers, generation, llm, nlp, openai, openflow, rag, synthetic ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: GenerateFlowFile 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/generateflowfile.md section: Loading & Unloading Data --- # GenerateFlowFile 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description This processor creates FlowFiles with random data or custom content. GenerateFlowFile is useful for load testing, configuration, and simulation. Also see DuplicateFlowFile for additional load testing. ## Tags generate, load, random, test ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: GenerateJSON 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/generatejson.md section: Loading & Unloading Data --- # GenerateJSON 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-record-generation-nar ## Description Produces a batch of JSON Objects with random field values based on a configurable JSON Schema. ## Tags JSON, JSON Schema, generate, random ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: GenerateRecord 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/generaterecord.md section: Loading & Unloading Data --- # GenerateRecord 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description This processor creates FlowFiles with records having random value for the specified fields. GenerateRecord is useful for testing, configuration, and simulation. It uses either user-defined properties to define a record schema or a provided schema and generates the specified number of records using random data for the fields in the schema. ## Tags fake, generate, random, test ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: GenerateTableFetch 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/generatetablefetch.md section: Loading & Unloading Data --- # GenerateTableFetch 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Generates SQL select queries that fetch "pages" of rows from a table. The partition size property, along with the table 's row count, determine the size and number of pages and generated FlowFiles. In addition, incremental fetching can be achieved by setting Maximum-Value Columns, which causes the processor to track the columns' maximum values, thus only fetching rows whose columns 'values exceed the observed maximums. This processor is intended to be run on the Primary Node only. This processor can accept incoming connections; the behavior of the processor is different whether incoming connections are provided: - If no incoming connection(s) are specified, the processor will generate SQL queries on the specified processor schedule. Expression Language is supported for many fields, but no FlowFile attributes are available. However the properties will be evaluated using the Environment/System properties. - If incoming connection(s) are specified and no FlowFile is available to a processor task, no work will be performed. - If incoming connection(s) are specified and a FlowFile is available to a processor task, the FlowFile's attributes may be used in Expression Language for such fields as Table Name and others. However, the Max-Value Columns and Columns to Return fields must be empty or refer to columns that are available in each specified table. ## Tags database, fetch, generate, jdbc, query, select, sql ## Input Requirement ALLOWED ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.standard.ExecuteSQL](/user-guide/data-integration/openflow/processors/executesql) - [org.apache.nifi.processors.standard.ListDatabaseTables](/user-guide/data-integration/openflow/processors/listdatabasetables) - [org.apache.nifi.processors.standard.QueryDatabaseTable](/user-guide/data-integration/openflow/processors/querydatabasetable) --- title: GeoEnrichIP 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/geoenrichip.md section: Loading & Unloading Data --- # GeoEnrichIP 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-enrich-nar ## Description Looks up geolocation information for an IP address and adds the geo information to FlowFile attributes. The geo data is provided as a MaxMind database. The attribute that contains the IP address to lookup is provided by the 'IP Address Attribute' property. If the name of the attribute provided is 'X', then the attributes added by enrichment will take the form X.geo.<fieldName> ## Tags enrich, geo, ip, maxmind ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: GeoEnrichIPRecord 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/geoenrichiprecord.md section: Loading & Unloading Data --- # GeoEnrichIPRecord 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-enrich-nar ## Description Looks up geolocation information for an IP address and adds the geo information to FlowFile attributes. The geo data is provided as a MaxMind database. This version uses the NiFi Record API to allow large scale enrichment of record-oriented data sets. Each field provided by the MaxMind database can be directed to a field of the user's choosing by providing a record path for that field configuration. ## Tags enrich, geo, ip, maxmind, record ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: GetAmazonAdsReport 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getamazonadsreport.md section: Loading & Unloading Data --- # GetAmazonAdsReport 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-amazon-ads-processors-nar ## Description Processor downloading report from Amazon Ads if ready. ## Tags Amazon, Amazon Ads, report ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: GetAwsPollyJobStatus 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getawspollyjobstatus.md section: Loading & Unloading Data --- # GetAwsPollyJobStatus 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-aws-nar ## Description Retrieves the current status of an AWS Polly job. ## Tags AWS, Amazon, ML, Machine Learning, Polly ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.aws.ml.polly.StartAwsPollyJob](/user-guide/data-integration/openflow/processors/startawspollyjob) --- title: GetAwsTextractJobStatus 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getawstextractjobstatus.md section: Loading & Unloading Data --- # GetAwsTextractJobStatus 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-aws-nar ## Description Retrieves the current status of an AWS Textract job. ## Tags AWS, Amazon, ML, Machine Learning, Textract ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [org.apache.nifi.processors.aws.ml.textract.StartAwsTextractJob](/user-guide/data-integration/openflow/processors/startawstextractjob) --- title: GetAwsTranscribeJobStatus 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getawstranscribejobstatus.md section: Loading & Unloading Data --- # GetAwsTranscribeJobStatus 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-aws-nar ## Description Retrieves the current status of an AWS Transcribe job. ## Tags AWS, Amazon, ML, Machine Learning, Transcribe ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.aws.ml.transcribe.StartAwsTranscribeJob](/user-guide/data-integration/openflow/processors/startawstranscribejob) --- title: GetAwsTranslateJobStatus 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getawstranslatejobstatus.md section: Loading & Unloading Data --- # GetAwsTranslateJobStatus 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-aws-nar ## Description Retrieves the current status of an AWS Translate job. ## Tags AWS, Amazon, ML, Machine Learning, Translate ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.aws.ml.translate.StartAwsTranslateJob](/user-guide/data-integration/openflow/processors/startawstranslatejob) --- title: GetAzureEventHub 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getazureeventhub.md section: Loading & Unloading Data --- # GetAzureEventHub 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-azure-nar ## Description Receives messages from Microsoft Azure Event Hubs without reliable checkpoint tracking. In clustered environment, GetAzureEventHub processor instances work independently and all cluster nodes process all messages (unless running the processor in Primary Only mode). ConsumeAzureEventHub offers the recommended approach to receiving messages from Azure Event Hubs. This processor creates a thread pool for connections to Azure Event Hubs. ## Tags azure, cloud, eventhub, events, microsoft, streaming, streams ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.azure.eventhub.ConsumeAzureEventHub](/user-guide/data-integration/openflow/processors/consumeazureeventhub) --- title: GetAzureQueueStorage_v12 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getazurequeuestorage_v12.md section: Loading & Unloading Data --- # GetAzureQueueStorage_v12 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-azure-nar ## Description Retrieves the messages from an Azure Queue Storage. The retrieved messages will be deleted from the queue by default. If the requirement is to consume messages without deleting them, set 'Auto Delete Messages' to 'false'. Note: There might be chances of receiving duplicates in situations like when a message is received but was unable to be deleted from the queue due to some unexpected situations. ## Tags azure, cloud, dequeue, microsoft, queue, storage ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.azure.storage.queue.PutAzureQueueStorage_v12](/user-guide/data-integration/openflow/processors/putazurequeuestorage_v12) --- title: GetBoxFileCollaborators 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getboxfilecollaborators.md section: Loading & Unloading Data --- # GetBoxFileCollaborators 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-box-nar ## Description Retrieves all collaborators on a Box file and adds the collaboration information to the FlowFile's attributes. ## Tags box, collaboration, permissions, sharing, storage ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.box.FetchBoxFile](/user-guide/data-integration/openflow/processors/fetchboxfile) - [org.apache.nifi.processors.box.ListBoxFile](/user-guide/data-integration/openflow/processors/listboxfile) --- title: GetBoxGroupMembers 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getboxgroupmembers.md section: Loading & Unloading Data --- # GetBoxGroupMembers 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-box-nar ## Description Retrieves members for a Box Group and writes their details in FlowFile attributes. ## Tags box, metadata, storage ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: GetConfluenceAuditRecords 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getconfluenceauditrecords.md section: Loading & Unloading Data --- # GetConfluenceAuditRecords 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-atlassian-processors-nar ## Description Processor listing Confluence audit records. ## Tags Preview, atlassian, audit log, confluence ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
--- title: GetConfluenceGroupUsers 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getconfluencegroupusers.md section: Loading & Unloading Data --- # GetConfluenceGroupUsers 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-atlassian-processors-nar ## Description Processor that downloads information about users belonging to a given Confluence group ## Tags Preview, atlassian, confluence, groups, users ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: GetConfluencePageContent 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getconfluencepagecontent.md section: Loading & Unloading Data --- # GetConfluencePageContent 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-atlassian-processors-nar ## Description Processor downloading Confluence pages. ## Tags Preview, atlassian, confluence, content, fetch, page ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: GetConfluencePageIds 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getconfluencepageids.md section: Loading & Unloading Data --- # GetConfluencePageIds 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-atlassian-processors-nar ## Description Downloads changed Confluence pages since the last sync and emits each as a FlowFile with metadata. ## Tags Preview, atlassian, changes, confluence, fetch, pages ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
--- title: GetConfluencePagePermissions 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getconfluencepagepermissions.md section: Loading & Unloading Data --- # GetConfluencePagePermissions 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-atlassian-processors-nar ## Description Processor downloading Confluence page permissions. ## Tags Preview, atlassian, confluence, page, permissions ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: GetConfluenceSpaceIds 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getconfluencespaceids.md section: Loading & Unloading Data --- # GetConfluenceSpaceIds 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-atlassian-processors-nar ## Description Processor for retrieving Confluence space ids. ## Tags atlassian, confluence, preview, spaces ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: GetConfluenceSpacePermissions 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getconfluencespacepermissions.md section: Loading & Unloading Data --- # GetConfluenceSpacePermissions 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-atlassian-processors-nar ## Description Processor downloading Confluence space permissions. ## Tags Preview, atlassian, confluence, permissions, space ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: GetDataShareCredentials 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getdatasharecredentials.md section: Loading & Unloading Data --- # GetDataShareCredentials 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-salesforce-processors-nar ## Description Describe the specified data share metadata in Salesforce Data Cloud. ## Tags daas, data cloud, describe, object, preview, salesforce, sfdc ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## See also - [com.snowflake.openflow.runtime.processors.salesforce.ListSFDCDataShares](/user-guide/data-integration/openflow/processors/listsfdcdatashares) --- title: GetDataShareTables 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getdatasharetables.md section: Loading & Unloading Data --- # GetDataShareTables 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-salesforce-processors-nar ## Description Describe the specified data share metadata in Salesforce Data Cloud. ## Tags daas, data cloud, describe, object, preview, salesforce, sfdc ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [com.snowflake.openflow.runtime.processors.salesforce.ListSFDCDataShares](/user-guide/data-integration/openflow/processors/listsfdcdatashares) --- title: GetDBFSFile 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getdbfsfile.md section: Loading & Unloading Data --- # GetDBFSFile 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-databricks-processors-nar ## Description Read a DBFS file. ## Tags databricks, dbfs, openflow ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: GetDynamoDB 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getdynamodb.md section: Loading & Unloading Data --- # GetDynamoDB 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-aws-nar ## Description Retrieves a document from DynamoDB based on hash and range key. The key can be string or number. For any get request all the primary keys are required (hash or hash and range based on the table keys).A Json Document ( 'Map') attribute of the DynamoDB item is read into the content of the FlowFile. ## Tags AWS, Amazon, DynamoDB, Fetch, Get ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.aws.dynamodb.DeleteDynamoDB](/user-guide/data-integration/openflow/processors/deletedynamodb) - [org.apache.nifi.processors.aws.dynamodb.PutDynamoDB](/user-guide/data-integration/openflow/processors/putdynamodb) - [org.apache.nifi.processors.aws.dynamodb.PutDynamoDBRecord](/user-guide/data-integration/openflow/processors/putdynamodbrecord) --- title: GetElasticsearch 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getelasticsearch.md section: Loading & Unloading Data --- # GetElasticsearch 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-elasticsearch-restapi-nar ## Description Elasticsearch get processor that uses the official Elastic REST client libraries to fetch a single document from Elasticsearch by _id. Note that the full body of the document will be read into memory before being written to a FlowFile for transfer. ## Tags elasticsearch, elasticsearch7, elasticsearch8, elasticsearch9, index, json, put, record ## Input Requirement ALLOWED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.elasticsearch.JsonQueryElasticsearch](/user-guide/data-integration/openflow/processors/jsonqueryelasticsearch) --- title: GetFile 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getfile.md section: Loading & Unloading Data --- # GetFile 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Creates FlowFiles from files in a directory. NiFi will ignore files it doesn't have at least read permissions for. ## Tags files, filesystem, get, ingest, ingress, input, local, source ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Restrictions
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.standard.FetchFile](/user-guide/data-integration/openflow/processors/fetchfile) - [org.apache.nifi.processors.standard.PutFile](/user-guide/data-integration/openflow/processors/putfile) --- title: GetFileResource 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getfileresource.md section: Loading & Unloading Data --- # GetFileResource 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description This processor creates FlowFiles with the content of the configured File Resource. GetFileResource is useful for load testing, configuration, and simulation. ## Tags file, generate, load, test ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Restrictions
## Relationships
## Writes attributes
--- title: GetFTP 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getftp.md section: Loading & Unloading Data --- # GetFTP 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Fetches files from an FTP Server and creates FlowFiles from them ## Tags FTP, fetch, files, get, ingest, input, remote, retrieve, source ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.standard.PutFTP](/user-guide/data-integration/openflow/processors/putftp) --- title: GetGcpVisionAnnotateFilesOperationStatus 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getgcpvisionannotatefilesoperationstatus.md section: Loading & Unloading Data --- # GetGcpVisionAnnotateFilesOperationStatus 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-gcp-nar ## Description Retrieves the current status of an Google Vision operation. ## Tags Cloud, Google, Machine Learning, Vision ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [org.apache.nifi.processors.gcp.vision.StartGcpVisionAnnotateFilesOperation](/user-guide/data-integration/openflow/processors/startgcpvisionannotatefilesoperation) --- title: GetGcpVisionAnnotateImagesOperationStatus 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getgcpvisionannotateimagesoperationstatus.md section: Loading & Unloading Data --- # GetGcpVisionAnnotateImagesOperationStatus 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-gcp-nar ## Description Retrieves the current status of an Google Vision operation. ## Tags Cloud, Google, Machine Learning, Vision ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [org.apache.nifi.processors.gcp.vision.StartGcpVisionAnnotateImagesOperation](/user-guide/data-integration/openflow/processors/startgcpvisionannotateimagesoperation) --- title: GetGoogleAdsReport 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getgoogleadsreport.md section: Loading & Unloading Data --- # GetGoogleAdsReport 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-google-ads-nar ## Description A processor which can interact with Google Ads Reporting API. By default it fetches data once a day ## Tags Google, Google Ads, report ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
--- title: GetGoogleGroupMembers 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getgooglegroupmembers.md section: Loading & Unloading Data --- # GetGoogleGroupMembers 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-google-drive-nar ## Description Retrieves the members of one or more Google Groups, specified as a comma-separated list of group IDs that is given as a FlowFile attribute. Supports both immediate (top-level) and nested group member retrieval. Outputs four FlowFile attributes: 'google.group.member.user.ids', 'google.group.member.user.emails', 'google.group.member.group.ids', and 'google.group.member.group.emails'. When nested fetching is enabled, it recursively expands sub-groups up to the specified depth. If an attribute already exists on the FlowFile, the new values are concatenated to the existing value (separated by a comma). ## Tags cloud, directory, gcp, google, groups, membership ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [com.snowflake.openflow.runtime.processors.google.CaptureGoogleDriveChanges](/user-guide/data-integration/openflow/processors/capturegoogledrivechanges) --- title: GetGoogleSheets 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getgooglesheets.md section: Loading & Unloading Data --- # GetGoogleSheets 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-google-sheets-processors-nar ## Description Processor responsible for fetching data from Google Sheets. By default it fetches data once a day. ## Tags Google, Google Sheets, spreadsheet ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: GetHubSpot 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/gethubspot.md section: Loading & Unloading Data --- # GetHubSpot 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-hubspot-nar ## Description Retrieves JSON data from a private HubSpot application. This processor is intended to be run on the Primary Node only. ## Tags hubspot ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
--- title: GetHubSpotObject 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/gethubspotobject.md section: Loading & Unloading Data --- # GetHubSpotObject 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-hubspot-processors-nar ## Description Get a HubSpot object and its associations by ID or unique value. ## Tags Preview, hubspot ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [com.snowflake.openflow.runtime.processors.hubspot.GetHubSpotSchema](/user-guide/data-integration/openflow/processors/gethubspotschema) - [com.snowflake.openflow.runtime.processors.hubspot.ListArchivedHubSpotData](/user-guide/data-integration/openflow/processors/listarchivedhubspotdata) - [com.snowflake.openflow.runtime.processors.hubspot.ListHubSpotObjects](/user-guide/data-integration/openflow/processors/listhubspotobjects) - [com.snowflake.openflow.runtime.processors.hubspot.PutHubSpot](/user-guide/data-integration/openflow/processors/puthubspot) --- title: GetHubSpotSchema 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/gethubspotschema.md section: Loading & Unloading Data --- # GetHubSpotSchema 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-hubspot-processors-nar ## Description Retrieves schema information for HubSpot object types including field names, types, and labels. Outputs detailed field metadata as JSON for schema discovery and mapping purposes. ## Tags Preview, crm, hubspot, metadata, schema ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [com.snowflake.openflow.runtime.processors.hubspot.GetHubSpotObject](/user-guide/data-integration/openflow/processors/gethubspotobject) - [com.snowflake.openflow.runtime.processors.hubspot.ListArchivedHubSpotData](/user-guide/data-integration/openflow/processors/listarchivedhubspotdata) - [com.snowflake.openflow.runtime.processors.hubspot.ListHubSpotObjects](/user-guide/data-integration/openflow/processors/listhubspotobjects) - [com.snowflake.openflow.runtime.processors.hubspot.PutHubSpot](/user-guide/data-integration/openflow/processors/puthubspot) --- title: GetLinkedInAdsReport 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getlinkedinadsreport.md section: Loading & Unloading Data --- # GetLinkedInAdsReport 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-linkedin-ads-processors-nar ## Description Processor downloading metrics from the LinkedIn Reporting APIs. ## Tags LinkedIn, LinkedIn Ads, ads, report ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
--- title: GetMicrosoft365GroupMembers 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getmicrosoft365groupmembers.md section: Loading & Unloading Data --- # GetMicrosoft365GroupMembers 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-msgraph-nar ## Description Retrieves Microsoft365 group members and emits a FlowFile for each change that occurs. This includes membership changes. ## Tags cdc, document, graph, library, microsoft, sharepoint, unstructured ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: GetMongo 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getmongo.md section: Loading & Unloading Data --- # GetMongo 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-mongodb-nar ## Description Creates FlowFiles from documents in MongoDB loaded by a user-specified query. ## Tags get, mongodb, read ## Input Requirement ALLOWED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: GetMongoRecord 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getmongorecord.md section: Loading & Unloading Data --- # GetMongoRecord 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-mongodb-nar ## Description A record-based version of GetMongo that uses the Record writers to write the MongoDB result set. ## Tags fetch, get, json, mongo, mongodb, record ## Input Requirement ALLOWED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: GetQueryJobResult 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getqueryjobresult.md section: Loading & Unloading Data --- # GetQueryJobResult 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-salesforce-processors-nar ## Description Gets the results of a Query Job in Salesforce using the Bulk API 2.0. The output is CSV and GZIP compression is used. ## Tags bulk, job, preview, query, salesforce ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [com.snowflake.openflow.runtime.processors.salesforce.AbortQueryJob](/user-guide/data-integration/openflow/processors/abortqueryjob) - [com.snowflake.openflow.runtime.processors.salesforce.DeleteQueryJob](/user-guide/data-integration/openflow/processors/deletequeryjob) - [com.snowflake.openflow.runtime.processors.salesforce.GetQueryJobStatus](/user-guide/data-integration/openflow/processors/getqueryjobstatus) - [com.snowflake.openflow.runtime.processors.salesforce.SubmitQueryJob](/user-guide/data-integration/openflow/processors/submitqueryjob) --- title: GetQueryJobStatus 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getqueryjobstatus.md section: Loading & Unloading Data --- # GetQueryJobStatus 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-salesforce-processors-nar ## Description Gets the status of a Query Job in Salesforce using the Bulk API 2.0. ## Tags bulk, job, preview, query, salesforce, status ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [com.snowflake.openflow.runtime.processors.salesforce.AbortQueryJob](/user-guide/data-integration/openflow/processors/abortqueryjob) - [com.snowflake.openflow.runtime.processors.salesforce.DeleteQueryJob](/user-guide/data-integration/openflow/processors/deletequeryjob) - [com.snowflake.openflow.runtime.processors.salesforce.GetQueryJobResult](/user-guide/data-integration/openflow/processors/getqueryjobresult) - [com.snowflake.openflow.runtime.processors.salesforce.SubmitQueryJob](/user-guide/data-integration/openflow/processors/submitqueryjob) --- title: GetS3ObjectMetadata 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/gets3objectmetadata.md section: Loading & Unloading Data --- # GetS3ObjectMetadata 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-aws-nar ## Description Check for the existence of an Object in S3 and fetch its Metadata without attempting to download it. This processor can be used as a router for workflows that need to check on an Object in S3 before proceeding with data processing ## Tags AWS, Amazon, Archive, Exists, S3 ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [org.apache.nifi.processors.aws.s3.DeleteS3Object](/user-guide/data-integration/openflow/processors/deletes3object) - [org.apache.nifi.processors.aws.s3.FetchS3Object](/user-guide/data-integration/openflow/processors/fetchs3object) - [org.apache.nifi.processors.aws.s3.GetS3ObjectTags](/user-guide/data-integration/openflow/processors/gets3objecttags) - [org.apache.nifi.processors.aws.s3.ListS3](/user-guide/data-integration/openflow/processors/lists3) - [org.apache.nifi.processors.aws.s3.PutS3Object](/user-guide/data-integration/openflow/processors/puts3object) - [org.apache.nifi.processors.aws.s3.TagS3Object](/user-guide/data-integration/openflow/processors/tags3object) --- title: GetS3ObjectTags 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/gets3objecttags.md section: Loading & Unloading Data --- # GetS3ObjectTags 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-aws-nar ## Description Check for the existence of an Object in S3 and fetch its Tags without attempting to download it. This processor can be used as a router for workflows that need to check on an Object in S3 before proceeding with data processing ## Tags AWS, Amazon, Archive, Exists, S3 ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [org.apache.nifi.processors.aws.s3.DeleteS3Object](/user-guide/data-integration/openflow/processors/deletes3object) - [org.apache.nifi.processors.aws.s3.FetchS3Object](/user-guide/data-integration/openflow/processors/fetchs3object) - [org.apache.nifi.processors.aws.s3.GetS3ObjectMetadata](/user-guide/data-integration/openflow/processors/gets3objectmetadata) - [org.apache.nifi.processors.aws.s3.ListS3](/user-guide/data-integration/openflow/processors/lists3) - [org.apache.nifi.processors.aws.s3.PutS3Object](/user-guide/data-integration/openflow/processors/puts3object) - [org.apache.nifi.processors.aws.s3.TagS3Object](/user-guide/data-integration/openflow/processors/tags3object) --- title: GetSFTP 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getsftp.md section: Loading & Unloading Data --- # GetSFTP 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Fetches files from an SFTP Server and creates FlowFiles from them ## Tags fetch, files, get, ingest, input, remote, retrieve, sftp, source ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.standard.PutSFTP](/user-guide/data-integration/openflow/processors/putsftp) --- title: GetSharepointSiteGroupMembers 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getsharepointsitegroupmembers.md section: Loading & Unloading Data --- # GetSharepointSiteGroupMembers 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-sharepoint-rest-nar ## Description Retrieves all members of a SharePoint site group. ## Tags groups, membership, microsoft, openflow, sharepoint ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [com.snowflake.openflow.runtime.processors.sharepoint.rest.ListSharepointSiteGroups](/user-guide/data-integration/openflow/processors/listsharepointsitegroups) --- title: GetShopify 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getshopify.md section: Loading & Unloading Data --- # GetShopify 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-shopify-nar ## Description Retrieves objects from a custom Shopify store. The processor yield time must be set to the account's rate limit accordingly. ## Tags shopify ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
--- title: GetSmbFile 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getsmbfile.md section: Loading & Unloading Data --- # GetSmbFile 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-smb-nar ## Description Reads file from a samba network location to FlowFiles. Use this processor instead of a cifs mounts if share access control is important. Configure the Hostname, Share and Directory accordingly: \[Hostname][Share][pathtoDirectory] ## Tags samba, smb, cifs, files, get ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.smb.FetchSmb](/user-guide/data-integration/openflow/processors/fetchsmb) - [org.apache.nifi.processors.smb.ListSmb](/user-guide/data-integration/openflow/processors/listsmb) - [org.apache.nifi.processors.smb.PutSmbFile](/user-guide/data-integration/openflow/processors/putsmbfile) --- title: GetSplunk 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getsplunk.md section: Loading & Unloading Data --- # GetSplunk 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-splunk-nar ## Description Retrieves data from Splunk Enterprise. ## Tags get, logs, splunk ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
--- title: GetSQS 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getsqs.md section: Loading & Unloading Data --- # GetSQS 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-aws-nar ## Description Fetches messages from an Amazon Simple Queuing Service Queue ## Tags AWS, Amazon, Fetch, Get, Poll, Queue, SQS ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.aws.sqs.DeleteSQS](/user-guide/data-integration/openflow/processors/deletesqs) - [org.apache.nifi.processors.aws.sqs.PutSQS](/user-guide/data-integration/openflow/processors/putsqs) --- title: GetUnityCatalogFile 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getunitycatalogfile.md section: Loading & Unloading Data --- # GetUnityCatalogFile 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-databricks-processors-nar ## Description Read a Unity Catalog file up to 5 GiB. ## Tags databricks, openflow, unity catalog ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: GetUnityCatalogFileMetadata 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getunitycatalogfilemetadata.md section: Loading & Unloading Data --- # GetUnityCatalogFileMetadata 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-databricks-processors-nar ## Description Checks for Unity Catalog file metadata. ## Tags databricks, openflow, unity catalog ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: GetWorkdayReport 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getworkdayreport.md section: Loading & Unloading Data --- # GetWorkdayReport 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-workday-processors-nar ## Description A processor which can interact with a configurable Workday Report. The processor can forward the content without modification, or you can transform it by providing the specific Record Reader and Record Writer services based on your needs. You can also remove fields by defining schema in the Record Writer. Supported Workday report formats are: csv, simplexml, json ## Tags Workday, report ## Input Requirement ALLOWED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: GetZendesk 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/getzendesk.md section: Loading & Unloading Data --- # GetZendesk 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-zendesk-nar ## Description Incrementally fetches data from Zendesk API. ## Tags zendesk ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
--- title: GrokReader source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/grokreader.md section: Loading & Unloading Data --- # GrokReader This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides a mechanism for reading unstructured text data, such as log files, and structuring the data so that it can be processed. The service is configured using Grok patterns. The service reads from a stream of data and splits each message that it finds into a separate Record, each containing the fields that are configured. If a line in the input does not match the expected message pattern, the line of text is either considered to be part of the previous message or is skipped, depending on the configuration, with the exception of stack traces. A stack trace that is found at the end of a log message is considered to be part of the previous message but is added to the 'stackTrace' field of the Record. If a record has no stack trace, it will have a NULL value for the stackTrace field (assuming that the schema does in fact include a stackTrace field of type String). Assuming that the schema includes a '_raw' field of type String, the raw message will be included in the Record. ## Tags grok, logfiles, logs, logstash, parse, pattern, reader, record, regex, text, unstructured ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted ## Restrictions
## System Resource Considerations This component does not specify system resource considerations. --- title: Guidelines for using Python extensions in Openflow source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors-python-ext-guide.md section: Loading & Unloading Data --- # Guidelines for using Python extensions in Openflow This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions). - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index) This topic describes the limitations, supported configurations, and best practices when using Python extensions in Openflow. Python processors in Openflow use NiFi's Py4J bridge architecture, which has fundamentally different resource characteristics than native Java processors. Because Python processors run as external OS processes outside the JVM, they consume additional system memory, are not governed by NiFi's internal resource management, and have limited observability. These differences affect runtime sizing, capacity planning, and monitoring. ## Architecture differences Python processors run as external OS processes rather than within the JVM. This architecture affects how resources are allocated, monitored, and managed:
## Runtime size constraints Python extensions are only available on Medium and Large runtimes. Small runtimes do not support Python processors due to CPU and memory constraints. Snowflake Openflow blocks Python extensions on Small runtimes:
## Best practices Follow these guidelines for working with Python processors in Openflow: - Use Java for CPU-heavy operations. Java provides more efficient thread management within the JVM. Groovy scripting is a Java-based alternative. - Use Medium or Large runtimes. Python is not available on Small runtimes. - Limit the number of Python processors. Stay within the documented limits per runtime size. - Monitor resource usage. Watch for memory pressure and CPU contention. - Plan for upgrades. Custom Python processors might require a virtual environment (venv) reset after runtime upgrades. For more information, see [Restore Python processors following runtime upgrades](#label-openflow-python-ext-restore). - Use single-threaded Python processors. Openflow does not support Python processors spawning subprocesses or using multithreading. ## Limitations on using Python processors The following limitations apply when using Python processors in Openflow.
Runtime constraints
Python extensions can only be used with Medium or Large runtimes. Python extensions cannot be used with Small runtimes. This is disabled by the platform.
Memory overhead
Each Python processor spawns an external OS process with its own memory footprint. Python processes can collectively compete with the JVM for resources.
No NiFi resource management
Python processors are not observed or limited by NiFi's internal resource management. CPU-heavy Python operations can consume approximately 50% of total server CPU time.
Monitoring gaps
The platform lacks visibility into external Python process health and resource consumption.
Upgrade handling
After runtime upgrades, custom Python processors might fail to load or exhibit unexpected behavior until virtual environments are recreated.
## Restore Python processors following runtime upgrades If Python processors fail after upgrading the runtime, do the following: 1. Increment the processor version in the `ProcessorDetails.version` field. 2. Rebuild and re-upload the NiFi Archive (NAR) binary. This triggers the Python virtual environment cache to reset. 3. Remove and re-add the processor on the canvas. This triggers reinitialization of the Py4J bridge. --- title: HandleHttpRequest 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/handlehttprequest.md section: Loading & Unloading Data --- # HandleHttpRequest 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Starts an HTTP Server and listens for HTTP Requests. For each request, creates a FlowFile and transfers to 'success'. This Processor is designed to be used in conjunction with the HandleHttpResponse Processor in order to create a Web Service. In case of a multipart request, one FlowFile is generated for each part. ## Tags http, https, ingress, listen, request, web service ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.standard.HandleHttpResponse](/user-guide/data-integration/openflow/processors/handlehttpresponse) --- title: HandleHttpResponse 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/handlehttpresponse.md section: Loading & Unloading Data --- # HandleHttpResponse 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Sends an HTTP Response to the Requestor that generated a FlowFile. This Processor is designed to be used in conjunction with the HandleHttpRequest in order to create a web service. ## Tags egress, http, https, response, web service ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [org.apache.nifi.processors.standard.HandleHttpRequest](/user-guide/data-integration/openflow/processors/handlehttprequest) --- title: HazelcastMapCacheClient source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/hazelcastmapcacheclient.md section: Loading & Unloading Data --- # HazelcastMapCacheClient This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description An implementation of DistributedMapCacheClient that uses Hazelcast as the backing cache. This service relies on another controller service that manages the actual Hazelcast calls, set in the Hazelcast Cache Manager property. ## Tags cache, hazelcast, map ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: HikariCPConnectionPool source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/hikaricpconnectionpool.md section: Loading & Unloading Data --- # HikariCPConnectionPool This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides Database Connection Pooling Service based on HikariCP. Connections can be asked from pool and returned after usage. ## Tags connection, database, dbcp, hikari, jdbc, pooling, store ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted ## Restrictions
## System Resource Considerations This component does not specify system resource considerations. --- title: HttpRecordSink source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/httprecordsink.md section: Loading & Unloading Data --- # HttpRecordSink This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Format and send Records to a configured uri using HTTP post. The Record Writer formats the records which are sent as the body of the HTTP post request. JsonRecordSetWriter is often used with this processor because many HTTP posts require a JSON body. ## Tags http, post, record, sink ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: IdentifyMimeType 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/identifymimetype.md section: Loading & Unloading Data --- # IdentifyMimeType 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Attempts to identify the MIME Type used for a FlowFile. If the MIME Type can be identified, an attribute with the name 'mime.type' is added with the value being the MIME Type. If the MIME Type cannot be determined, the value will be set to 'application/octet-stream'. In addition, the attribute 'mime.extension' will be set if a common file extension for the MIME Type is known. If the MIME Type detected is of type text/*, attempts to identify the charset used and an attribute with the name 'mime.charset' is added with the value being the charset. ## Tags MIME, bzip2, compression, file, gzip, identify, mime.type, zip ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: Install and configure the Openflow Connector for Oracle source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/oracle/setup-connector.md section: Loading & Unloading Data --- # Install and configure the %oracleofc% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). The %oracleofc% is also subject to additional terms of service beyond the standard connector terms of service. For more information, see the [Openflow Connector for Oracle Addendum](https://www.snowflake.cn/en/legal/optional-offerings/offering-specific-terms/openflow-oracle-terms/). - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [About Openflow Connector for Oracle](/user-guide/data-integration/openflow/connectors/oracle/about) - [Openflow Connector for Oracle: Enable and manage commercial terms](/user-guide/data-integration/openflow/connectors/oracle/manage-commercial-terms) - [Openflow Connector for Oracle: Set up Snowflake](/user-guide/data-integration/openflow/connectors/oracle/setup-snowflake) - [Openflow Connector for Oracle: Set up incremental replication without snapshots](/user-guide/data-integration/openflow/connectors/oracle/incremental-replication) This topic describes the steps to install and configure the %oracleofc% connector. As a data engineer, perform the following tasks to install and configure the connector: ## Install the connector To install the connector, do the following as a data engineer: 1. Navigate to the Openflow overview page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find the connector and select **Install**. 3. In the **Select runtime** dialog, select your runtime from the **Available runtimes** drop-down list and click **Install**. Before you install the connector, ensure that you have created a database and schema in Snowflake for the connector to store ingested data. 4. Authenticate to the deployment with your Snowflake account credentials and select **Allow** when prompted to allow the runtime application to access your Snowflake account. The connector installation process takes a few minutes to complete. 5. Authenticate to the runtime with your Snowflake account credentials. The Openflow canvas appears with the connector process group added to it. ## Runtime sizing The runtime size determines the CPU, memory, and disk available to the connector. The available sizes are Small, Medium, and Large. Choose the size when you create the runtime: you can't change the size of an existing runtime in place. Size the runtime based on the sustained workload it needs to handle across all connectors running on it. Sustained means typical steady-state throughput, not peak. Peak load can temporarily increase connector queues and end-to-end replication latency; the workload catches up when the load drops back to the steady-state level. The following ranges are starting points based on internal benchmarks and production customer data. They aren't service guarantees. Your fit depends on row size, event distribution, schema width, and source burstiness. Start at the lower bound, measure runtime CPU, memory, queue depth, and end-to-end replication latency in production, then increase from there. - Light workload (aggregate sustained throughput below approximately 1,000 events per second, fewer than approximately 100 actively changing tables): a Small runtime can host a single low-volume connector. Pack additional connectors on Small only when each source is genuinely light. - Moderate workload (approximately 1,000 to 5,000 events per second, hundreds of actively changing tables): a Medium runtime can typically host 5 to 8 connectors. - Heavy workload (approximately 5,000 to 15,000 events per second, hundreds to low thousands of actively changing tables): a Large runtime can typically host 15 or more connectors. If you want a smaller blast radius, split across two Medium runtimes instead. ## Running multiple connectors on one runtime You can run multiple CDC connector instances on a single runtime. This is useful for replicating many small databases, for example a multi-tenant SaaS with one database per tenant, or a fleet of operational databases per business unit or region. When you run multiple CDC connector instances of the same type on one runtime, keep their shared Source and Destination parameter contexts intact and override only the per-connector values in each Ingestion context. For the recommended process, see [](#run-multiple-connectors-on-one-runtime). Run a connector on a dedicated runtime, not packed with others, when any of the following applies: - A single source sustains more than approximately 15,000 events per second. - You need sub-1-minute end-to-end replication latency under load. - You can't tolerate noisy-neighbor effects from other sources sharing the runtime. Each replicated table can consume two Snowpipe Streaming pipes: one for snapshot replication and one for incremental replication. As you pack more tables onto a runtime, check your account's [Snowpipe Streaming pipe limit](/user-guide/snowpipe-streaming/snowpipe-streaming-high-performance-limitations#pipe-limits) and raise it before you approach the cap. ## Resize a runtime Runtime size is fixed at creation, so to change size you run the connector on a different runtime. You have two options depending on whether you want to preserve the current replication progress. If you don't need to keep the progress of the current connector, the simplest path is to create a new runtime at the size you need and install a new connector instance on it. The new connector starts from scratch: it snapshots all configured tables and then captures ongoing changes from that point. The replication progress of the existing connector is discarded. To keep the progress of the current connector, for example to avoid re-snapshotting tables that took a long time to snapshot initially, migrate the connector to the new runtime. This reuses the existing destination tables and resumes incremental replication from where it left off. For migration instructions, see [Reinstall the connector](#label-oracle-reinstall-connector). ## Configure the connector To configure the connector, do the following as a data engineer: 1. Right-click on the added runtime and select **Parameters**. 2. Populate the required parameter values. For more information on the required parameter values, see the following sections: - [](#label-oracle-snowflake-destination-parameters): Used to establish connection with Snowflake. - [](#label-oracle-ingestion-parameters): Used to specify the tables to replicate. - [](#label-oracle-source-parameters): Used to define the configuration of data downloaded from Oracle. To run multiple CDC connector instances on one runtime, see [](/user-guide/data-integration/openflow/connectors/cdc-runtime-sizing#run-multiple-connectors-on-one-runtime). ### Snowflake Destination Parameters
### Oracle Ingestion Parameters
### Oracle Source Parameters
## Restart table replication A table in FAILED state — for example, due to a missing primary key or unsupported schema change — does not restart automatically. If a table enters a FAILED state or you need to restart replication from scratch, use the following procedure to remove and re-add the table to replication. If the failure was caused by an issue in the source table such as a missing primary key, resolve that issue in the source database before continuing. 1. Remove the table from replication, using one of the following methods: - Add the table to the **Re-snapshot Table Exclusions** parameter to temporarily exclude it from replication. This is convenient when the table is matched by an **Included Table Regex** that you don't want to change. - In the Ingestion Parameters context, either remove the table from **Included Table Names** or modify the **Included Table Regex** so the table is no longer matched. 2. Verify the table has been removed: 1. In the Openflow runtime canvas, right-click a processor group and choose **Controller Services**. 2. In the table listing controller services, locate the **Table State Store** row, click the three vertical dots on the right side of the row, then choose **View State**. You must wait until the table's state is fully removed from this list before proceeding. Do not continue until this configuration change has completed. 3. Clean up the destination: Once the table's state shows as fully removed, manually [DROP](/sql-reference/sql/drop-table) the destination table in Snowflake. Note that the connector will not overwrite an existing destination table during the snapshot phase; if the table still exists, replication will fail again. Optionally, the journal table and stream can also be removed if they are no longer needed. 4. Re-add the table by reversing the change you made in the first step: either remove the table from **Re-snapshot Table Exclusions**, or add it back to **Included Table Names** or **Included Table Regex**. The connector then re-snapshots the table. 5. Verify the restart: Check the **Table State Store** using the instructions given previously. The state of the table should appear with the status NEW, then transition to SNAPSHOT_REPLICATION, and finally INCREMENTAL_REPLICATION. ## Replicate a subset of columns in a table The connector can filter the data replicated per table to a subset of configured columns. Primary key columns are always included regardless of exclusions. To apply column filters, set the **Column Filter JSON** parameter in the Ingestion Parameters context to a JSON array of filter objects, one per table you want to filter. Columns can be included or excluded by name or by regular expression pattern. You can apply a single condition per table, or combine multiple conditions, with exclusions always taking precedence over inclusions. ## Syntax Each object in the array identifies a table and specifies which columns to include or exclude. Because this connector uses three-part fully qualified names (database, schema, and table), each object can include a `database` or `databasePattern` field in addition to the schema and table fields. ```javascript [ { "database": "" | "databasePattern": "", "schema": "" | "schemaPattern": "", "table": "
Property Value
Enable DOTALL Mode `true`
Maximum Buffer Size `1 MB`
Maximum Capture Group Length `1048576`
`raw_payload` *(dynamic property)* `(?s)(.*)`
Property Value
`error_message` `raw payload (non-JSON)` --- on Kinesis you can use `${record.error.message}` instead (see the [Kinesis page](/user-guide/data-integration/openflow/connectors/kinesis/configuring-dead-letter-queue-handling))
`failure_timestamp` `${now():format('yyyy-MM-dd HH:mm:ss.SSS', 'UTC')}`
Property Value
Attributes List `raw_payload,error_message,failure_timestamp`
Destination `flowfile-content`
Include Core Attributes `false`
Property Value
Destination Type `TABLE`
Database The DLQ table's database.
Schema The DLQ table's schema.
Table The DLQ table name (for example, `pipeline_dlq`).
Channel Group `${hostname(false)}.dlq`
Authentication Strategy `SNOWFLAKE_MANAGED`
Connection Strategy `STANDARD`
Web Client Service Provider The existing web-client service.
Property Value
Record Reader The existing `JsonTreeReader`.
Record Writer The existing `JsonRecordSetWriter`.
Jolt Transform `jolt-transform-chain`
Jolt Specification The chain spec below.
Symptom Likely cause
`CREATE TABLE` / insert denied Missing grants on the DLQ schema (see [Grants](#label-openflow-streaming-dlq-grants)).
Records pile up in the parking-lot funnel DLQ table/schema mismatch or wrong database/schema/table parameters --- inspect the `LogAttribute` error output.
Property Value
**Authentication Strategy** `KEY_PAIR`
**Account** Your Snowflake account identifier, for example `myorg-myaccount`
**User** Your Snowflake username
**Role** Your Snowflake role
**Private Key Service** Select the `StandardPrivateKeyService` created in [](#label-openflow-streaming-private-key-auth-step1)
Property Description
`Key File` Path to the PKCS8 PEM private key file. Use **Reference asset** to upload the file directly to the cluster.
`Key` Inline PEM key content (alternative to `Key File`).
`Key Password` Passphrase for an encrypted private key. Leave blank for unencrypted keys.
Symptom Likely cause
`PublishSnowpipeStreaming` shows validation errors after applying `StandardPrivateKeyService` is not yet enabled --- enable it before starting the processor.
Authentication failure at runtime Verify the public key is correctly assigned to the Snowflake user (`DESC USER ` should show `RSA_PUBLIC_KEY` set).
`BEGIN ENCRYPTED PRIVATE KEY` in key file but auth fails Encrypted key in use --- ensure `Key Password` is set on `StandardPrivateKeyService`.
Wrong account identifier format Use `-` without `.snowflakecomputing.cn`.
Property Value
Schema Access Strategy `Use 'Schema Text' Property`
Schema Text The full Proto 3 formatted schema text. Supports Expression Language.
Message Name Resolution Strategy `Message Name Property`
Message Name The fully qualified name of the Protocol Buffers message including its package, for example, `mypackage.MyMessage`. Supports Expression Language.
Property Value
Schema Registry URLs *(required)* Comma-separated URL(s) of your Confluent Schema Registry, for example, `https://schema-registry.example.com:8081`.
SSL Context Service *(optional)* An `SSLContextService` if the registry requires TLS. Implementations: `StandardSSLContextService`, `StandardRestrictedSSLContextService`, `PEMEncodedSSLContextProvider`.
Communications Timeout *(required)* How long to wait for a response from the registry before failing.
Cache Size *(required)* Number of schemas to cache locally. Raise it when a single topic/stream carries many distinct Protobuf message types at high throughput (more memory); the default is fine for a few schemas.
Cache Expiration *(required)* How long cached schemas are valid before being re-fetched.
Authentication Type `NONE` or `BASIC` if the registry requires HTTP Basic authentication.
Username Username for Basic authentication. Only used when **Authentication Type** is `BASIC`.
Password Password for Basic authentication. Sensitive property. Only used when **Authentication Type** is `BASIC`.
Property Value
Schema Access Strategy `Schema Reference Reader`
Schema Reference Reader Select the `ConfluentEncodedSchemaReferenceReader` created above.
Schema Registry Select the `ConfluentSchemaRegistry` created above.
Message Name Resolution Strategy `Message Name Resolver`
Message Name Resolver Select the `ConfluentProtobufMessageNameResolver` created above.
Property Value
Record Reader Select the `StandardProtobufReader` created above.
Symptom Likely cause
`SchemaNotFoundException` at runtime The schema ID in the message is not present in the registry, or the registry URL is misconfigured. Verify **Schema Registry URLs** in `ConfluentSchemaRegistry`.
Parse failures or malformed records The **Schema Text** does not match the actual message schema, or the wrong **Message Name** is specified. Compare the schema and message name with those used by the producer. Failed messages are routed to the parse-failure relationship (`parse failure` on Kafka, `parse.failure` on Kinesis).
`ConfluentSchemaRegistry` fails to enable Network connectivity issue between the Openflow runtime and the registry. Check the External Access Integration and that the registry URL is reachable from the cluster.
Authentication failure against registry Registry requires Basic auth --- set **Authentication Type** to `BASIC` and provide **Username** and **Password** in `ConfluentSchemaRegistry`.
Display Name API Name Default Value Allowable Values Description
Authentication Type Authentication Type NONE - BASIC - NONE HTTP Client Authentication Type for Confluent Schema Registry
Cache Expiration * Cache Expiration 1 hour Specifies how long a Schema that is cached should remain in the cache. Once this time period elapses, a cached version of a schema will no longer be used, and the service will have to communicate with the Schema Registry again in order to obtain the schema.
Cache Size * Cache Size 1000 Specifies how many Schemas should be cached from the Schema Registry
Communications Timeout * Communications Timeout 30 secs Specifies how long to wait to receive data from the Schema Registry before considering the communications a failure
Password Password Password for authentication to Confluent Schema Registry
SSL Context Service SSL Context Service Specifies the SSL Context Service to use for interacting with the Confluent Schema Registry
Schema Registry URLs * Schema Registry URLs http://localhost:8081 (http://localhost:8081) A comma-separated list of URLs of the Schema Registry to interact with
Username Username Username for authentication to Confluent Schema Registry
Property Description
`wd.authn.clientId` Client ID from the Workday Register API Client task.
`wd.authn.isu` ISU username (for example, `snowflake_ldq_user`).
`wd.authn.accessTokenEndpoint` Full OAuth2 token URL in the format `https:///ccx/oauth2//token`.
`wd.authn.privateKey` PEM private key content, retrieved securely from a Snowflake Secret at runtime.
`wd.host` Workday service host.
`wd.port` Always `443`.
Property Description
websocket-client-controller-service A WebSocket CLIENT Controller Service which can connect to a WebSocket server.
websocket-client-id The client ID to identify WebSocket session. It should be unique within the WebSocket Client Controller Service. Otherwise, it throws WebSocketConfigurationException when it gets started.
Name Description
binary message The WebSocket binary message output
connected The WebSocket session is established
disconnected The WebSocket session is disconnected
failure FlowFile holding connection configuration attributes (like URL or HTTP headers) in case of connection failure
success FlowFile holding connection configuration attributes (like URL or HTTP headers) in case of successful connection
text message The WebSocket text message output
Name Description
websocket.controller.service.id WebSocket Controller Service id.
websocket.session.id Established WebSocket session id.
websocket.endpoint.id WebSocket endpoint id.
websocket.local.address WebSocket client address.
websocket.remote.address WebSocket server address.
websocket.message.type TEXT or BINARY.
Property Description
AMQP Version AMQP Version. Currently only supports AMQP v0.9.1.
Auto-Acknowledge Messages If false (Non-Auto-Acknowledge), the messages will be acknowledged by the processor after transferring the FlowFiles to success and committing the NiFi session. Non-Auto-Acknowledge mode provides 'at-least-once' delivery semantics. If true (Auto-Acknowledge), messages that are delivered to the AMQP Client will be auto-acknowledged by the AMQP Broker just after sending them out. This generally will provide better throughput but will also result in messages being lost upon restart/crash of the AMQP Broker, NiFi or the processor. Auto-Acknowledge mode provides 'at-most-once' delivery semantics and it is recommended only if losing messages is acceptable.
Batch Size The maximum number of messages that should be processed in a single session. Once this many messages have been received (or once no more messages are readily available), the messages received will be transferred to the 'success' relationship and the messages will be acknowledged to the AMQP Broker. Setting this value to a larger number could result in better performance, particularly for very small messages, but can also result in more messages being duplicated upon sudden restart of NiFi.
Brokers A comma-separated list of known AMQP Brokers in the format <host>:<port> (e.g., localhost:5672). If this is set, Host Name and Port are ignored. Only include hosts from the same AMQP cluster.
Client Certificate Authentication Enabled Authenticate using the SSL certificate rather than user name/password.
Header Key Prefix Text to be prefixed to header keys as the are added to the FlowFile attributes. Processor will append '.' to the value of this property
Header Output Format Defines how to output headers from the received message
Header Separator The character that is used to separate key-value for header in String. The value must be only one character.
Host Name Network address of AMQP broker (e.g., localhost). If Brokers is set, then this property is ignored.
Max Inbound Message Body Size Maximum body size of inbound (received) messages.
Password Password used for authentication and authorization.
Port Numeric value identifying Port of AMQP broker (e.g., 5671). If Brokers is set, then this property is ignored.
Prefetch Count The maximum number of unacknowledged messages for the consumer. If consumer has this number of unacknowledged messages, AMQP broker will no longer send new messages until consumer acknowledges some of the messages already delivered to it. Allowed values: from 0 to 65535.0 means no limit
Queue The name of the existing AMQP Queue from which messages will be consumed. Usually pre-defined by AMQP administrator.
Remove Curly Braces If true Remove Curly Braces, Curly Braces in the header will be automatically remove.
SSL Context Service The SSL Context Service used to provide client certificate information for TLS/SSL connections.
Username Username used for authentication and authorization.
Virtual Host Virtual Host name which segregates AMQP system for enhanced security.
Name Description
success All FlowFiles that are received from the AMQP queue are routed to this relationship
Name Description
amqp$appId The App ID field from the AMQP Message
amqp$contentEncoding The Content Encoding reported by the AMQP Message
amqp$contentType The Content Type reported by the AMQP Message
amqp$headers The headers present on the AMQP Message. Added only if processor is configured to output this attribute.
<Header Key Prefix>.<attribute> Each message header will be inserted with this attribute name, if processor is configured to output headers as attribute
amqp$deliveryMode The numeric indicator for the Message's Delivery Mode
amqp$priority The Message priority
amqp$correlationId The Message's Correlation ID
amqp$replyTo The value of the Message's Reply-To field
amqp$expiration The Message Expiration
amqp$messageId The unique ID of the Message
amqp$timestamp The timestamp of the Message, as the number of milliseconds since epoch
amqp$type The type of message
amqp$userId The ID of the user
amqp$clusterId The ID of the AMQP Cluster
amqp$routingKey The routingKey of the AMQP Message
amqp$exchange The exchange from which AMQP Message was received
Property Description
Batch Size The number of messages to process within a NiFi session. This parameter affects throughput and consistency. NiFi commits its session and Event Hubs checkpoints after processing this number of messages. If NiFi session is committed, but fails to create an Event Hubs checkpoint, then it is possible that the same messages will be received again. The higher number, the higher throughput, but possibly less consistent.
Checkpoint Strategy Specifies which strategy to use for storing and retrieving partition ownership and checkpoint information for each partition.
Consumer Group The name of the consumer group to use.
Event Hub Name The name of the event hub to pull messages from.
Event Hub Namespace The namespace that the Azure Event Hubs is assigned to. This is generally equal to <Event Hub Names>-ns.
Initial Offset Specify where to start receiving messages if offset is not yet stored in the checkpoint store.
Message Receive Timeout The amount of time this consumer should wait to receive the Batch Size before returning.
Prefetch Count
Record Reader The Record Reader to use for reading received messages. The event hub name can be referred by Expression Language '$\{eventhub.name\}' to access a schema.
Record Writer The Record Writer to use for serializing Records to an output FlowFile. The event hub name can be referred by Expression Language '$\{eventhub.name\}' to access a schema. If not specified, each message will create a FlowFile.
Service Bus Endpoint To support namespaces not in the default windows.net domain.
Shared Access Policy Key The key of the shared access policy. Either the primary or the secondary key can be used.
Shared Access Policy Name The name of the shared access policy. This policy must have Listen claims.
Storage Account Key The Azure Storage account key to store event hub consumer group state.
Storage Account Name Name of the Azure Storage account to store event hub consumer group state.
Storage Container Name Name of the Azure Storage container to store the event hub consumer group state. If not specified, event hub name is used.
Storage SAS Token The Azure Storage SAS token to store Event Hub consumer group state. Always starts with a ? character.
Transport Type Advanced Message Queuing Protocol Transport Type for communication with Azure Event Hubs
Use Azure Managed Identity Choose whether or not to use the managed identity of Azure VM/VMSS
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Scopes Description
LOCAL Local state is used to store the client id. Cluster state is used to store partition ownership and checkpoint information when component state is configured as the checkpointing strategy.
CLUSTER Local state is used to store the client id. Cluster state is used to store partition ownership and checkpoint information when component state is configured as the checkpointing strategy.
Name Description
success FlowFiles received from Event Hub.
Name Description
eventhub.enqueued.timestamp The time (in milliseconds since epoch, UTC) at which the message was enqueued in the event hub
eventhub.offset The offset into the partition at which the message was stored
eventhub.sequence The sequence number associated with the message
eventhub.name The name of the event hub from which the message was pulled
eventhub.partition The name of the partition from which the message was pulled
eventhub.property.* The application properties of this message. IE: 'application' would be 'eventhub.property.application'
Property Description
Box Client Service Controller Service used to obtain a Box API connection.
Event Types A comma separated list of Enterprise Events to consume. If not set, all Events are consumed. See Additional Details for more information.
Start Event Position What position to consume the Events from.
Start Offset The offset to start consuming the Events from.
Scopes Description
CLUSTER The last known position of the Box Event stream is stored in the processor state and is used to resume the stream from the last known position when the processor is restarted.
Name Description
success Events received successfully will be sent out this relationship.
Property Description
Box Client Service Controller Service used to obtain a Box API connection.
Queue Capacity The maximum size of the internal queue used to buffer events being transferred from the underlying stream to the processor. Setting this value higher allows more messages to be buffered in memory during surges of incoming messages, but increases the total memory used by the processor during these surges.
Scopes Description
CLUSTER The last known position of the Box stream is stored in the processor state and is used to resume the stream from the last known position when the processor is restarted.
Name Description
success Events received successfully will be sent out this relationship.
Property Description
Additional Filters One or more query filters in JSON syntax, not Lucene syntax. Ex: [\{"match":\{"somefield":"somevalue"\}\}, \{"match":\{"anotherfield":"anothervalue"\}\}]. These filters wil be used as part of a Bool query's filter.
Aggregation Results Format Format of Aggregation output.
Aggregation Results Split Output a flowfile containing all aggregations or one flowfile for each individual aggregation.
Aggregations One or more query aggregations (or "aggs"), in JSON syntax. Ex: \{"items": \{"terms": \{"field": "product", "size": 10\}\}\}
Client Service An Elasticsearch client service to use for running queries.
Fields Fields of indexed documents to be retrieved, in JSON syntax. Ex: ["user.id", "http.response.*", \{"field": "@timestamp", "format": "epoch_millis"\}]
Index The name of the index to use.
Initial Value The initial value to use for the query if the processor has not run previously. If the processor has run previously and stored a value in its state, this property will be ignored. If no value is provided, and the processor has not previously run, no Range query bounds will be used, i.e. all documents will be retrieved in the specified "Sort Order".
Initial Value Date Format If the "Range Query Field" is a Date field, convert the "Initial Value" to a date with this format. If not specified, Elasticsearch will use the date format provided by the "Range Query Field"'s mapping. For valid syntax, see https://www.elastic.co/guide/en/elasticsearch/reference/current/mapping-date-format.html (https://www.elastic.co/guide/en/elasticsearch/reference/current/mapping-date-format.html)
Initial Value Date Time Zone If the "Range Query Field" is a Date field, convert the "Initial Value" to UTC with this time zone. Valid values are ISO 8601 UTC offsets, such as "+01:00" or "-08:00", and IANA time zone IDs, such as "Europe/London".
Max JSON Field String Length The maximum allowed length of a string value when parsing a JSON document or attribute.
Output No Hits Output a "hits" flowfile even if no hits found for query. If true, an empty "hits" flowfile will be output even if "aggregations" are output.
Pagination Keep Alive Pagination "keep_alive" period. Period Elasticsearch will keep the scroll/pit cursor alive in between requests (this is not the time expected for all pages to be returned, but the maximum allowed time for requests between page retrievals).
Pagination Type Pagination method to use. Not all types are available for all Elasticsearch versions, check the Elasticsearch docs to confirm which are applicable and recommended for your service.
Query Attribute If set, the executed query will be set on each result flowfile in the specified attribute.
Range Query Field Field to be tracked as part of an Elasticsearch Range query using a "gt" bound match. This field must exist within the Elasticsearch document for it to be retrieved.
Script Fields Fields to created using script evaluation at query runtime, in JSON syntax. Ex: \{"test1": \{"script": \{"lang": "painless", "source": "doc[ 'price'].value * 2"\}\}, "test2": \{"script": \{"lang": "painless", "source": "doc[ 'price'].value * params.factor", "params": \{"factor": 2.0\}\}\}\}
Search Results Format Format of Hits output.
Search Results Split Output a flowfile containing all hits or one flowfile for each individual hit or one flowfile containing all hits from all paged responses.
Size The maximum number of documents to retrieve in the query. If the query is paginated, this "size" applies to each page of the query, not the "size" of the entire result set.
Sort Sort results by one or more fields, in JSON syntax. Ex: [\{"price" : \{"order" : "asc", "mode" : "avg"\}\}, \{"post_date" : \{"format": "strict_date_optional_time_nanos"\}\}]
Sort Order The order in which to sort the "Range Query Field". A "sort" clause for the "Range Query Field" field will be prepended to any provided "Sort" clauses. If a "sort" clause already exists for the "Range Query Field" field, it will not be updated.
Type The type of this document (used by Elasticsearch for indexing and searching).
Scopes Description
CLUSTER The pagination state (scrollId, searchAfter, pitId, hitCount, pageCount, pageExpirationTimestamp, trackingRangeValue) is retained in between invocations of this processor until the Scroll/PiT has expired (when the current time is later than the last query execution plus the Pagination Keep Alive interval).
Name Description
aggregations Aggregations are routed to this relationship.
failure All flowfiles that fail for reasons unrelated to server availability go to this relationship.
hits Search hits are routed to this relationship.
retry All flowfiles that fail due to server/cluster availability go to this relationship.
Name Description
mime.type application/json
page.number The number of the page (request), starting from 1, in which the results were returned that are in the output flowfile
hit.count The number of hits that are in the output flowfile
elasticsearch.query.error The error message provided by Elasticsearch if there is an error querying the index.
Property Description
GCP Credentials Provider Service The Controller Service used to obtain Google Cloud Platform credentials.
Message Demarcator Since the PubSub client receives messages in batches, this Processor has an option to output FlowFiles which contains all the messages in a single batch. This property allows you to provide a string (interpreted as UTF-8) to use for demarcating apart multiple messages. To enter special character such as 'new line' use CTRL+Enter or Shift+Enter depending on the OS.
Output Strategy The format used to output the Kafka Record into a FlowFile Record.
Processing Strategy Strategy for processing PubSub Records and writing serialized output to FlowFiles
Record Reader The Record Reader to use for incoming messages
Record Writer The Record Writer to use in order to serialize the outgoing FlowFiles
api-endpoint Override the gRPC endpoint in the form of [host:port]
gcp-project-id Google Cloud Project ID
gcp-pubsub-publish-batch-size Indicates the number of messages the cloud service should bundle together in a batch. If not set and left empty, only one message will be used in a batch
gcp-pubsub-subscription Name of the Google Cloud Pub/Sub Subscription
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
success FlowFiles are routed to this relationship after a successful Google Cloud Pub/Sub operation.
Name Description
gcp.pubsub.ackId Acknowledgement Id of the consumed Google Cloud PubSub message
gcp.pubsub.messageSize Serialized size of the consumed Google Cloud PubSub message
gcp.pubsub.attributesCount Number of attributes the consumed PubSub message has, if any
gcp.pubsub.publishTime Timestamp value when the message was published
gcp.pubsub.subscription Name of the PubSub subscription
Dynamic Attributes Other than the listed attributes, this processor may write zero or more attributes, if the original Google Cloud Publisher client added any attributes to the message while sending
Property Description
Authorization Mode How to authorize sending email on the user's behalf.
Connection Timeout The amount of time to wait to connect to Email server
Delete Messages Specify whether mail messages should be deleted after retrieval.
Fetch Size Specify the maximum number of Messages to fetch per call to Email Server.
Folder Email folder to retrieve messages from (e.g., INBOX)
Host Name Network address of Email server (e.g., pop.gmail.com, imap.gmail.com . .)
Mark Messages as Read Specify if messages should be marked as read after retrieval.
OAuth2 Access Token Provider OAuth2 service that can provide access tokens.
Password Password used for authentication and authorization with Email server.
Port Numeric value identifying Port of Email server (e.g., 993)
Use SSL Specifies if IMAP connection must be obtained via SSL encrypted connection (i.e., IMAPS)
User Name User Name used for authentication and authorization with Email server.
Name Description
success All messages that are the are successfully received from Email server and converted to FlowFiles are routed to this relationship
Property Description
Acknowledgement Mode The JMS Acknowledgement Mode. Using Auto Acknowledge can cause messages to be lost on restart of NiFi but may provide better performance than Client Acknowledge.
Connection Client ID The client id to be set on the connection, if set. For durable non shared consumer this is mandatory, for all others it is optional, typically with shared consumers it is undesirable to be set. Please see JMS spec for further details
Connection Factory Service The Controller Service that is used to obtain Connection Factory. Alternatively, the 'JNDI *' or the 'JMS *' properties can also be used to configure the Connection Factory.
Destination Name The name of the JMS Destination. Usually provided by the administrator (e.g., 'topic://myTopic' or 'myTopic').
Destination Type The type of the JMS Destination. Could be one of 'QUEUE' or 'TOPIC'. Usually provided by the administrator. Defaults to 'QUEUE'
Durable subscription If destination is Topic if present then make it the consumer durable. @see https://jakarta.ee/specifications/platform/9/apidocs/jakarta/jms/session#createDurableConsumer-jakarta.jms (https://jakarta.ee/specifications/platform/9/apidocs/jakarta/jms/session#createDurableConsumer-jakarta.jms). Topic-java.lang. String-
Error Queue Name The name of a JMS Queue where - if set - unprocessed messages will be routed. Usually provided by the administrator (e.g., 'queue://myErrorQueue' or 'myErrorQueue').Only applicable if 'Destination Type' is set to 'QUEUE'
Maximum Batch Size The maximum number of messages to publish or consume in each invocation of the processor.
Message Selector The JMS Message Selector to filter the messages that the processor will receive
Password Password used for authentication and authorization.
SSL Context Service The SSL Context Service used to provide client certificate information for TLS/SSL connections.
Shared subscription If destination is Topic if present then make it the consumer shared. @see https://jakarta.ee/specifications/platform/9/apidocs/jakarta/jms/session#createSharedConsumer-jakarta.jms (https://jakarta.ee/specifications/platform/9/apidocs/jakarta/jms/session#createSharedConsumer-jakarta.jms). Topic-java.lang. String-
Subscription Name The name of the subscription to use if destination is Topic and is shared or durable.
Timeout How long to wait to consume a message from the remote broker before giving up.
User Name User Name used for authentication and authorization.
broker URI pointing to the network location of the JMS Message broker. Example for ActiveMQ: '[tcp://myhost:61616](tcp://myhost:61616)'. Examples for IBM MQ: 'myhost(1414)' and 'myhost01(1414),myhost02(1414)'.
cf The fully qualified name of the JMS ConnectionFactory implementation class (eg. org.apache.activemq. ActiveMQConnectionFactory).
cflib Path to the directory with additional resources (eg. JARs, configuration files etc.) to be added to the classpath (defined as a comma separated list of values). Such resources typically represent target JMS client libraries for the ConnectionFactory implementation.
character-set The name of the character set to use to construct or interpret TextMessages
connection.factory.name The name of the JNDI Object to lookup for the Connection Factory.
java.naming.factory.initial The fully qualified class name of the JNDI Initial Context Factory Class (java.naming.factory.initial).
java.naming.provider.url The URL of the JNDI Provider to use as the value for java.naming.provider.url. See additional details documentation for allowed URL schemes.
java.naming.security.credentials The Credentials to use when authenticating with JNDI (java.naming.security.credentials).
java.naming.security.principal The Principal to use when authenticating with JNDI (java.naming.security.principal).
naming.factory.libraries Specifies jar files and/or directories to add to the ClassPath in order to load the JNDI / JMS client libraries. This should be a comma-separated list of files, directories, and/or URLs. If a directory is given, any files in that directory will be included, but subdirectories will not be included (i.e., it is not recursive).
output-strategy The format used to output the JMS message into a FlowFile record.
record-reader The Record Reader to use for parsing received JMS Messages into Records.
record-writer The Record Writer to use for serializing Records before writing them to a FlowFile.
Required Permission Explanation
reference remote resources Client Library Location can reference resources over HTTP
Name Description
parse.failure If a message cannot be parsed using the configured Record Reader, the contents of the message will be routed to this Relationship as its own individual FlowFile.
success All FlowFiles that are received from the JMS Destination are routed to this relationship
Name Description
jms_deliveryMode The JMSDeliveryMode from the message header.
jms_expiration The JMSExpiration from the message header.
jms_priority The JMSPriority from the message header.
jms_redelivered The JMSRedelivered from the message header.
jms_timestamp The JMSTimestamp from the message header.
jms_correlationId The JMSCorrelationID from the message header.
jms_messageId The JMSMessageID from the message header.
jms_type The JMSType from the message header.
jms_replyTo The JMSReplyTo from the message header.
jms_destination The JMSDestination from the message header.
jms.messagetype The JMS message type, can be TextMessage, BytesMessage, ObjectMessage, MapMessage or StreamMessage).
other attributes Each message property is written to an attribute.
Property Description
Commit Offsets Specifies whether this Processor should commit the offsets to Kafka after receiving messages. Typically, this value should be set to true so that messages that are received are not duplicated. However, in certain scenarios, we may want to avoid committing the offsets, that the data can be processed and later acknowledged by PublishKafka in order to provide Exactly Once semantics.
Content Field Specifies under what field of the record the content will be added. If not set, the content will be at the root of the record
Group ID Kafka Consumer Group Identifier corresponding to Kafka group.id property
Header Encoding Character encoding applied when reading Kafka Record Header values and writing FlowFile attributes
Header Name Pattern Regular Expression Pattern applied to Kafka Record Header Names for selecting Header Values to be written as FlowFile attributes
Headers Field Parent Specifies under what field of the record the headers field will be added. If not set, the headers field will be at the root of the record
Kafka Connection Service Provides connections to Kafka Broker for publishing Kafka Records
Key Attribute Encoding Encoding for value of configured FlowFile attribute containing Kafka Record Key.
Key Field Parent Specifies under what field of the record the key field will be added. If not set, the key field will be at the root of the record
Key Format Specifies how to represent the Kafka Record Key in the output FlowFile
Key Record Reader The Record Reader to use for parsing the Kafka Record Key into a Record
Max Uncommitted Time Specifies the maximum amount of time that the Processor can consume from Kafka before it must transfer FlowFiles on through the flow and commit the offsets to Kafka (if appropriate). A larger time period can result in longer latency
Message Demarcator Since KafkaConsumer receives messages in batches, this Processor has an option to output FlowFiles which contains all Kafka messages in a single batch for a given topic and partition and this property allows you to provide a string (interpreted as UTF-8) to use for demarcating apart multiple Kafka messages. This is an optional property and if not provided each Kafka message received will result in a single FlowFile which time it is triggered. To enter special character such as 'new line' use CTRL+Enter or Shift+Enter depending on the OS
Metadata Field Specifies under what field of the record the metadata will be added. If not set, the metadata will be at the root of the record
Metadata Received Timestamp Field If specified a timestamp will be placed under the specified field in the metadata of record in the output FlowFile
Output Strategy The format used to output the Kafka Record into a FlowFile Record.
Processing Strategy Strategy for processing Kafka Records and writing serialized output to FlowFiles
Record Reader The Record Reader to use for incoming Kafka messages
Record Writer The Record Writer to use in order to serialize the outgoing FlowFiles
Separate By Key When this property is enabled, two messages will only be added to the same FlowFile if both of the Kafka Messages have identical keys.
Topic Format Specifies whether the Topics provided are a comma separated list of names or a single regular expression
Topics The name or pattern of the Kafka Topics from which the Processor consumes Kafka Records. More than one can be supplied if comma separated.
auto.offset.reset Automatic offset configuration applied when no previous consumer offset found corresponding to Kafka auto.offset.reset property
Name Description
success FlowFiles containing one or more serialized Kafka Records
Name Description
record.count The number of records received
mime.type The MIME Type that is provided by the configured Record Writer
kafka.count The number of messages written if more than one
kafka.key The key of message if present and if single message. How the key is encoded depends on the value of the 'Key Attribute Encoding' property.
kafka.offset The offset of the message in the partition of the topic.
kafka.timestamp The timestamp of the message in the partition of the topic.
kafka.partition The partition of the topic the message or message bundle is from
kafka.topic The topic the message or message bundle is from
kafka.tombstone Set to true if the consumed message is a tombstone message
Property Description
AWS Credentials Provider service The Controller Service that is used to obtain AWS credentials provider
Amazon Kinesis Stream Name The name of Kinesis Stream
Application Name The Kinesis stream reader application name.
Checkpoint Interval Interval between Kinesis checkpoints
Communications Timeout
DynamoDB Override DynamoDB override to use non-AWS deployments
Endpoint Override URL Endpoint URL to use instead of the AWS default including scheme, host, port, and path. The AWS libraries select an endpoint URL based on the AWS region, but this property overrides the selected endpoint URL, allowing use with other S3-compatible endpoints.
Failover Timeout Kinesis Client Library failover timeout
FlowFile Handling On Schema Difference The strategy used when records in a Kinesis Stream change their schema in a single batch.
Graceful Shutdown Timeout Kinesis Client Library graceful shutdown timeout
Initial Stream Position Initial position to read Kinesis streams.
Output Strategy The format used to output the Kinesis Record into a FlowFile Record.
Record Reader The Record Reader to use for reading received messages. The Kinesis Stream name can be referred to by Expression Language '$\{kinesis.name\}' to access a schema. If Record Reader/Writer are not specified, each Kinesis Record will create a FlowFile.
Record Writer The Record Writer to use for serializing Records to an output FlowFile. The Kinesis Stream name can be referred to by Expression Language '$\{kinesis.name\}' to access a schema. If Record Reader/Writer are not specified, each Kinesis Record will create a FlowFile.
Region
Report Metrics to CloudWatch Whether to report Kinesis usage metrics to CloudWatch.
Retry Count Number of times to retry a Kinesis operation (process record, checkpoint, shutdown)
Retry Wait Interval between Kinesis operation retries (process record, checkpoint, shutdown)
Stream Position Timestamp Timestamp position in stream from which to start reading Kinesis Records. Required if Initial position to read Kinesis streams. is AT_TIMESTAMP. Uses the Timestamp Format to parse value into a Date.
Timestamp Format Format to use for parsing the Stream Position Timestamp into a Date and converting the Kinesis Record's Approximate Arrival Timestamp into a FlowFile attribute.
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
success FlowFiles are routed to success relationship
Name Description
aws.kinesis.partition.key Partition key of the (last) Kinesis Record read from the Shard
aws.kinesis.shard.id Shard ID from which the Kinesis Record was read
aws.kinesis.sequence.number The unique identifier of the (last) Kinesis Record within its Shard
aws.kinesis.approximate.arrival.timestamp Approximate arrival timestamp of the (last) Kinesis Record read from the stream
mime.type Sets the mime.type attribute to the MIME Type specified by the Record Writer (if configured)
record.count Number of records written to the FlowFiles by the Record Writer (if configured)
record.error.message This attribute provides on failure the error message encountered by the Record Reader or Record Writer (if configured)
Property Description
Broker URI The URI(s) to use to connect to the MQTT broker (e.g., [tcp://localhost:1883](tcp://localhost:1883)). The 'tcp', 'ssl', 'ws' and 'wss'schemes are supported. In order to use 'ssl', the SSL Context Service property must be set. When a comma-separated URI list is set (e.g., [tcp://localhost:1883,tcp://localhost:1884](tcp://localhost:1883,tcp://localhost:1884)), the processor will use a round-robin algorithm to connect to the brokers on connection failure.
Client ID MQTT client ID to use. If not set, a UUID will be generated.
Connection Timeout (seconds) Maximum time interval the client will wait for the network connection to the MQTT server to be established. The default timeout is 30 seconds. A value of 0 disables timeout processing meaning the client will wait until the network connection is made successfully or fails.
Group ID MQTT consumer group ID to use. If group ID not set, client will connect as individual consumer.
Keep Alive Interval (seconds) Defines the maximum time interval between messages sent or received. It enables the client to detect if the server is no longer available, without having to wait for the TCP/IP timeout. The client will ensure that at least one message travels across the network within each keep alive period. In the absence of a data-related message during the time period, the client sends a very small "ping" message, which the server will acknowledge. A value of 0 disables keepalive processing in the client.
Last Will Message The message to send as the client's Last Will.
Last Will QoS Level QoS level to be used when publishing the Last Will Message.
Last Will Retain Whether to retain the client's Last Will.
Last Will Topic The topic to send the client's Last Will to.
MQTT Specification Version The MQTT specification version when connecting with the broker. See the allowable value descriptions for more details.
Max Queue Size The MQTT messages are always being sent to subscribers on a topic regardless of how frequently the processor is scheduled to run. If the 'Run Schedule' is significantly behind the rate at which the messages are arriving to this processor, then a back up can occur in the internal queue of this processor. This property specifies the maximum number of messages this processor will hold in memory at one time in the internal queue. This data would be lost in case of a NiFi restart.
Password Password to use when connecting to the broker
Quality of Service(QoS) The Quality of Service (QoS) to receive the message with. Accepts values '0', '1' or '2'; '0' for 'at most once', '1' for 'at least once', '2' for 'exactly once'.
SSL Context Service The SSL Context Service used to provide client certificate information for TLS/SSL connections.
Session Expiry Interval After this interval the broker will expire the client and clear the session state.
Session state Whether to start a fresh or resume previous flows. See the allowable value descriptions for more details.
Topic Filter The MQTT topic filter to designate the topics to subscribe to.
Username Username to use when connecting to the broker
add-attributes-as-fields If setting this property to true, default fields are going to be added in each record: _topic, _qos, _isDuplicate, _isRetained.
message-demarcator With this property, you have an option to output FlowFiles which contains multiple messages. This property allows you to provide a string (interpreted as UTF-8) to use for demarcating apart multiple messages. This is an optional property ; if not provided, and if not defining a Record Reader/Writer, each message received will result in a single FlowFile. To enter special character such as 'new line' use CTRL+Enter or Shift+Enter depending on the OS.
record-reader The Record Reader to use for parsing received MQTT Messages into Records.
record-writer The Record Writer to use for serializing Records before writing them to a FlowFile.
Name Description
Message The MQTT message output
parse.failure If a message cannot be parsed using the configured Record Reader, the contents of the message will be routed to this Relationship as its own individual FlowFile.
Name Description
record.count The number of records received
mqtt.broker MQTT broker that was the message source
mqtt.topic MQTT topic on which message was received
mqtt.qos The quality of service for this message.
mqtt.isDuplicate Whether or not this message might be a duplicate of one which has already been received.
mqtt.isRetained Whether or not this message was from a current publisher, or was "retained" by the server as the last message published on the topic.
Property Description
Authorization Mode How to authorize sending email on the user's behalf.
Connection Timeout The amount of time to wait to connect to Email server
Delete Messages Specify whether mail messages should be deleted after retrieval.
Fetch Size Specify the maximum number of Messages to fetch per call to Email Server.
Folder Email folder to retrieve messages from (e.g., INBOX)
Host Name Network address of Email server (e.g., pop.gmail.com, imap.gmail.com . .)
OAuth2 Access Token Provider OAuth2 service that can provide access tokens.
Password Password used for authentication and authorization with Email server.
Port Numeric value identifying Port of Email server (e.g., 993)
User Name User Name used for authentication and authorization with Email server.
Name Description
success All messages that are the are successfully received from Email server and converted to FlowFiles are routed to this relationship
Property Description
Access Token OAuth Access Token used for authenticating/authorizing the Slack request sent by NiFi. This may be either a User Token or a Bot Token. It must be granted the channels:history, groups:history, im:history, or mpim:history scope, depending on the type of conversation being used.
Batch Size The maximum number of messages to retrieve in a single request to Slack. The entire response will be parsed into memory, so it is important that this be kept in mind when setting this value.
Channels A comma-separated list of Slack Channels to Retrieve Messages From. Each element in the list may be either a Channel ID, such as C0L9VCD47, or (for public channels only) the name of a channel, prefixed with a # sign, such as #general. If any channel name is provided instead,instead of an ID, the Access Token provided must be granted the channels:read scope in order to resolve the Channel ID. See the Processor's Additional Details for information on how to find a Channel ID.
Include Message Blocks Specifies whether or not the output JSON should include the value of the 'blocks' field for each Slack Message. This field includes information such as individual parts of a message that are formatted using rich text. This may be useful, for instance, for parsing. However, it often accounts for a significant portion of the data and as such may be set to null when it is not useful to you.
Include Null Fields Specifies whether or not fields that have null values should be included in the output JSON. If true, any field in a Slack Message that has a null value will be included in the JSON with a value of null. If false, the key omitted from the output JSON entirely. Omitting null values results in smaller messages that are generally more efficient to process, but including the values may provide a better understanding of the format, especially for schema inference.
Reply Monitor Frequency After consuming all messages in a given channel, this Processor will periodically poll all "threaded messages", aka Replies, whose timestamp falls between now and the amount of time specified by the <Reply Monitor Window> property. This property determines how frequently those messages are polled. Setting the value to a shorter duration may result in replies to messages being captured more quickly, providing a lower latency. However, it will also result in additional resource use and could trigger Rate Limiting to occur.
Reply Monitor Window After consuming all messages in a given channel, this Processor will periodically poll all "threaded messages", aka Replies, whose timestamp is between now and this amount of time in the past in order to check for any new replies. Setting this value to a larger value may result in additional resource use and may result in Rate Limiting. However, if a user replies to an old thread that was started outside of this window, the reply may not be captured.
Resolve Usernames Specifies whether or not User IDs should be resolved to usernames. By default, Slack Messages provide the ID of the user that sends a message, such as U0123456789, but not the username, such as NiFiUser. The username may be resolved, but it may require additional calls to the Slack API and requires that the Token used be granted the users:read scope. If set to true, usernames will be resolved with a best-effort policy: if a username cannot be obtained, it will be skipped over. Also, note that when a username is obtained, the Message's <username> field is populated, and the <text> field is updated such that any mention will be output such as "Hi @user" instead of "Hi <@U1234567>".
Scopes Description
CLUSTER Maintains a mapping of Slack Channel IDs to the timestamp of the last message that was retrieved for that channel. This allows the processor to only retrieve messages that have been posted since the last time the processor was run. This state is stored in the cluster so that if the Primary Node changes, the new node will pick up where the previous node left off.
Name Description
success Slack messages that are successfully received will be routed to this relationship
Name Description
slack.channel.id The ID of the Slack Channel from which the messages were retrieved
slack.message.count The number of slack messages that are included in the FlowFile
mime.type Set to application/json, as the output will always be in JSON format
Property Description
Access Token OAuth Access Token used for authenticating/authorizing the Slack request sent by NiFi. This may be either a User Token or a Bot Token. It must be granted the channels:history, groups:history, im:history, or mpim:history scope, depending on the type of conversation being used.
Batch Size The maximum number of messages to retrieve in a single request to Slack. The entire response will be parsed into memory, so it is important that this be kept in mind when setting this value.
Rate Limiter Service Slack Rate Limiter Service to coordinate rate limiting across processors
Reply Monitor Frequency After consuming all messages in a given channel, this Processor will periodically poll all "threaded messages", aka Replies, whose timestamp falls between now and the amount of time specified by the <Reply Monitor Window> property. This property determines how frequently those messages are polled. Setting the value to a shorter duration may result in replies to messages being captured more quickly, providing a lower latency. However, it will also result in additional resource use and could trigger Rate Limiting to occur. This also determines how frequently newly added channels are checked.
Reply Monitor Window After consuming all messages in a given channel, this Processor will periodically poll all "threaded messages", aka Replies, whose timestamp is between now and this amount of time in the past in order to check for any new replies. Setting this value to a larger value may result in additional resource use and may result in Rate Limiting. However, if a user replies to an old thread that was started outside of this window, the reply may not be captured.
Resolve Usernames Specifies whether or not User IDs should be resolved to usernames. By default, Slack Messages provide the ID of the user that sends a message, such as U0123456789, but not the username, such as NiFiUser. The username may be resolved, but it may require additional calls to the Slack API and requires that the Token used be granted the users:read scope. If set to true, usernames will be resolved with a best-effort policy: if a username cannot be obtained, it will be skipped over. Also, note that when a username is obtained, the Message's <username> field is populated, and the <text> field is updated such that any mention will be output such as "Hi @user" instead of "Hi <@U1234567>".
Scopes Description
CLUSTER Maintains a mapping of Slack Channel IDs to the timestamp of the last message that was retrieved for that channel. This allows the processor to only retrieve messages that have been posted since the last time the processor was run. This state is stored in the cluster so that if the Primary Node changes, the new node will pick up where the previous node left off.
Name Description
success Slack messages that are successfully received will be routed to this relationship
Name Description
slack.channel.id The ID of the Slack Channel from which the messages were retrieved
slack.message.count The number of slack messages that are included in the FlowFile
mime.type Set to application/json, as the output will always be in JSON format
Property Description
Access Token OAuth Access Token used for authenticating the Slack request. It must be granted the channels:history (and, if resolving usernames, users:read) scope.
Batch Size The maximum number of messages to retrieve in a single request to Slack.
Channel Refresh Frequency The frequency at which the processor refreshes the list of Slack channels accessible to the App. This helps detect newly available channels or remove channels that are no longer available.
Include Message Blocks Specifies whether the output JSON should include the value of the 'blocks' field for each Slack Message.
Include Null Fields Specifies whether fields that have null values should be included in the output JSON. If true, any field with a null value will be output as null; if false, it will be omitted.
Rate Limiter Service Slack Rate Limiter Service to coordinate rate limiting across processors
Resolve Usernames Specifies whether User IDs should be resolved to usernames. If true, usernames will be resolved with a best-effort policy; if a username cannot be obtained, it will be skipped.
Scopes Description
CLUSTER Maintains a mapping of Slack Channel IDs to the earliest message timestamp that has been retrieved. When no more messages are available, a flag is set indicating that the historical load is complete for that channel. This state is stored in the cluster so that if the Primary Node changes, the new node will pick up where the previous node left off.
Name Description
success FlowFiles containing the JSON-encoded Slack conversation history are routed to this relationship
Name Description
slack.channel.id The ID of the Slack Channel from which the messages were retrieved
slack.channel.name The name of the Slack Channel from which the messages were retrieved
slack.message.count The number of Slack messages that are included in the FlowFile
mime.type Set to application/json, the output will always be in JSON format
Property Description
Max Chunk Size Number of records to write into a single FlowFile. This value might be slightly exceeded.
Record Writer The Record Writer to use for CDC record serialization
Snowflake Connection Service Database Connection Service for accessing Snowflake
Stream Name The name of the stream in the database
Name Description
success For FlowFiles with stream CDC records
Name Description
snowflake.stream.name Name of the Snowflake Stream
Property Description
backfill-minutes The number of minutes (up to 5 minutes) of streaming data to be requested after a disconnect. Only available for project with academic research access. See https://developer.twitter.com/en/docs/twitter-api/tweets/filtered-stream/integrate/recovery-and-redundancy-features
backoff-attempts The number of reconnection tries the processor will attempt in the event of a disconnection of the stream for any reason, before throwing an exception. To start a stream after this exception occur and the connection is fixed, please stop and restart the processor. If the valueof this property is 0, then backoff will never occur and the processor will always need to be restartedif the stream fails.
backoff-time The duration to backoff before requesting a new stream ifthe current one fails for any reason. Will increase by factor of 2 every time a restart fails
base-path The base path that the processor will use for making HTTP requests. The default value should be sufficient for most use cases.
batch-size The maximum size of the number of Tweets to be written to a single FlowFile. Will write fewer Tweets based on the number available in the queue at the time of processor invocation.
bearer-token The Bearer Token provided by Twitter.
connect-timeout The maximum time in which client should establish a connection with the Twitter API before a time out. Setting the value to 0 disables connection timeouts.
expansions A comma-separated list of expansions for objects in the returned tweet. See https://developer.twitter.com/en/docs/twitter-api/expansions for proper usage. Possible field values include: author_id, referenced_tweets.id, referenced_tweets.id.author_id, entities.mentions.username, attachments.poll_ids, attachments.media_keys ,in_reply_to_user_id, geo.place_id
maximum-backoff-time The maximum duration to backoff to start attempting a new stream. It is recommended that this number be much higher than the 'Backoff Time' property
media-fields A comma-separated list of media fields to be returned as part of the tweet. Refer to https://developer.twitter.com/en/docs/twitter-api/data-dictionary/object-model/media for proper usage. Possible field values include: alt_text, duration_ms, height, media_key, non_public_metrics, organic_metrics, preview_image_url, promoted_metrics, public_metrics, type, url, width
place-fields A comma-separated list of place fields to be returned as part of the tweet. Refer to https://developer.twitter.com/en/docs/twitter-api/data-dictionary/object-model/place for proper usage. Possible field values include: contained_within, country, country_code, full_name, geo, id, name, place_type
poll-fields A comma-separated list of poll fields to be returned as part of the tweet. Refer to https://developer.twitter.com/en/docs/twitter-api/data-dictionary/object-model/poll for proper usage. Possible field values include: duration_minutes, end_datetime, id, options, voting_status
queue-size Maximum size of internal queue for streamed messages
read-timeout The maximum time of inactivity between receiving tweets from Twitter through the API before a timeout. Setting the value to 0 disables read timeouts.
stream-endpoint The source from which the processor will consume Tweets.
tweet-fields A comma-separated list of tweet fields to be returned as part of the tweet. Refer to https://developer.twitter.com/en/docs/twitter-api/data-dictionary/object-model/tweet for proper usage. Possible field values include: attachments, author_id, context_annotations, conversation_id, created_at, entities, geo, id, in_reply_to_user_id, lang, non_public_metrics, organic_metrics, possibly_sensitive, promoted_metrics, public_metrics, referenced_tweets, reply_settings, source, text, withheld
user-fields A comma-separated list of user fields to be returned as part of the tweet. Refer to https://developer.twitter.com/en/docs/twitter-api/data-dictionary/object-model/user for proper usage. Possible field values include: created_at, description, entities, id, location, name, pinned_tweet_id, profile_image_url, protected, public_metrics, url, username, verified, withheld
Name Description
success FlowFiles containing an array of one or more Tweets
Name Description
mime.type The MIME Type set to application/json
tweets The number of Tweets in the FlowFile
Property Description
Grouping Attribute By default, a single "throttle" is used for all FlowFiles. If this value is specified, a separate throttle is used for each value specified by the attribute with this name. Changing this value resets the rate counters.
Maximum Data Rate The maximum rate at which data should pass through this processor. The format of this property is expected to be a Data Size (such as '1 MB') representing bytes per Time Duration.
Maximum FlowFile Rate The maximum rate at which FlowFiles should pass through this processor. The format of this property is expected to be a positive integer representing FlowFiles count per Time Duration
Maximum Rate The maximum rate at which data should pass through this processor. The format of this property is expected to be a positive integer, or a Data Size (such as '1 MB') if Rate Control Criteria is set to 'data rate'.
Rate Control Criteria Indicates the criteria that is used to control the throughput rate. Changing this value resets the rate counters.
Rate Controlled Attribute The name of an attribute whose values build toward the rate limit if Rate Control Criteria is set to 'attribute value'. The value of the attribute referenced by this property must be a positive long, or the FlowFile will be routed to failure. This value is ignored if Rate Control Criteria is not set to 'attribute value'. Changing this value resets the rate counters.
Rate Exceeded Strategy Specifies how to handle an incoming FlowFile when the maximum data rate has been exceeded.
Time Duration The amount of time to which the Maximum Rate pertains. Changing this value resets the rate counters.
Name Description
failure FlowFiles will be routed to this relationship if they are missing a necessary Rate Controlled Attribute or the attribute is not in the expected format
success FlowFiles are transferred to this relationship under normal conditions
Property Description
Input Character Set The name of the CharacterSet to expect for Input
Output Character Set The name of the CharacterSet to convert to
Name Description
success
Property Description
Include Zero Record FlowFiles When converting an incoming FlowFile, if the conversion results in no data, this property specifies whether or not a FlowFile will be sent to the corresponding relationship
Record Reader Specifies the Controller Service to use for reading incoming data
Record Writer Specifies the Controller Service to use for writing out the records
Name Description
failure If a FlowFile cannot be transformed from the configured input format to the configured output format, the unchanged FlowFile will be routed to this relationship
success FlowFiles that are successfully transformed will be routed to this relationship
Name Description
mime.type Sets the mime.type attribute to the MIME Type specified by the Record Writer
record.count The number of records in the FlowFile
record.error.message This attribute provides on failure the error message encountered by the Reader or Writer.
Name Description
failure FlowFiles are routed to this relationship if the schema cannot be translated.
original The original FlowFile is routed to this relationship when the schema is successfully converted.
success FlowFiles are routed to this relationship after the schema has been converted.
Property Description
Conflict Resolution Strategy Specifies whether an existing blob will have its contents replaced upon conflict.
Create Container Specifies whether to check if the container exists and to automatically create it if it does not. Permission to list containers is required. If false, this check is not made, but the Put operation will fail if the container does not exist.
Destination Blob Name The full name of the destination blob defaults to the Source Blob Name when not specified
Destination Container Name Name of the Azure storage container destination defaults to the Source Container Name when not specified
Destination Storage Credentials Controller Service used to obtain Azure Blob Storage Credentials.
Source Blob Name The full name of the source blob
Source Container Name Name of the Azure storage container that will be copied
Source Storage Credentials Credentials Service used to obtain Azure Blob Storage Credentials to read Source Blob information
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests. In case of SOCKS, it is not guaranteed that the selected SOCKS Version will be used by the processor.
Name Description
failure Unsuccessful operations will be transferred to the failure relationship.
success All successfully processed FlowFiles are routed to this relationship
Name Description
azure.container The name of the Azure Blob Storage container
azure.blobname The name of the blob on Azure Blob Storage
azure.primaryUri Primary location of the blob
azure.etag ETag of the blob
azure.blobtype Type of the blob (either BlockBlob, PageBlob or AppendBlob)
mime.type MIME Type of the content
lang Language code for the content
azure.timestamp Timestamp of the blob
azure.length Length of the blob
azure.error.code Error code reported during blob operation
azure.ignored When Conflict Resolution Strategy is 'ignore', this property will be true/false depending on whether the blob was ignored.
Property Description
AWS Credentials Provider service The Controller Service that is used to obtain AWS credentials provider
Canned ACL Amazon Canned ACL for an object, one of: BucketOwnerFullControl, BucketOwnerRead, LogDeliveryWrite, AuthenticatedRead, PublicReadWrite, PublicRead, Private; will be ignored if any other ACL/permission/owner property is specified
Communications Timeout The amount of time to wait in order to establish a connection to AWS or receive data from AWS before timing out.
Custom Signer Class Name Fully qualified class name of the custom signer class. The signer must implement com.amazonaws.auth. Signer interface.
Custom Signer Module Location Comma-separated list of paths to files and/or directories which contain the custom signer's JAR file and its dependencies (if any).
Destination Bucket The bucket that will receive the copy.
Destination Key The target key in the target bucket
Endpoint Override URL Endpoint URL to use instead of the AWS default including scheme, host, port, and path. The AWS libraries select an endpoint URL based on the AWS region, but this property overrides the selected endpoint URL, allowing use with other S3-compatible endpoints.
FullControl User List A comma-separated list of Amazon User ID's or E-mail addresses that specifies who should have Full Control for an object
Owner The Amazon ID to use for the object's owner
Read ACL User List A comma-separated list of Amazon User ID's or E-mail addresses that specifies who should have permissions to read the Access Control List for an object
Read Permission User List A comma-separated list of Amazon User ID's or E-mail addresses that specifies who should have Read Access for an object
Region The AWS Region to connect to.
SSL Context Service Specifies an optional SSL Context Service that, if provided, will be used to create connections
Signer Override The AWS S3 library uses Signature Version 4 by default but this property allows you to specify the Version 2 signer to support older S3-compatible services or even to plug in your own custom signer implementation.
Source Bucket The bucket that contains the file to be copied.
Source Key The source key in the source bucket
Write ACL User List A comma-separated list of Amazon User ID's or E-mail addresses that specifies who should have permissions to change the Access Control List for an object
Write Permission User List A comma-separated list of Amazon User ID's or E-mail addresses that specifies who should have Write Access for an object
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
failure If the Processor is unable to process a given FlowFile, it will be routed to this Relationship.
success FlowFiles are routed to this Relationship after they have been successfully processed.
Property Description
ajust-immediately If true, the counter will be updated immediately, without regard to whether the ProcessSession is commit or rolled back;otherwise, the counter will be incremented only if and when the ProcessSession is committed.
character-encoding Specifies a character encoding to use.
split-words-on-symbols If enabled, the word count will identify strings separated by common logical delimiters [ _ - . ] as independent words (ex. split-words-on-symbols = 4 words).
text-character-count If enabled, will count the number of characters (including whitespace and symbols, but not including newlines and carriage returns) present in the incoming text.
text-line-count If enabled, will count the number of lines present in the incoming text.
text-line-nonempty-count If enabled, will count the number of lines that contain a non-whitespace character present in the incoming text.
text-word-count If enabled, will count the number of words (alphanumeric character groups bounded by whitespace) present in the incoming text. Common logical delimiters [_-.] do not bound a word unless 'Split Words on Symbols' is true.
Name Description
failure If the flowfile text cannot be counted for some reason, the original file will be routed to this destination and nothing will be routed elsewhere
success The flowfile contains the original content with one or more attributes added containing the respective counts
Name Description
text.line.count The number of lines of text present in the FlowFile content
text.line.nonempty.count The number of lines of text (with at least one non-whitespace character) present in the original FlowFile
text.word.count The number of words present in the original FlowFile
text.character.count The number of characters (given the specified character encoding) present in the original FlowFile
Property Description
Access Token Provider Service providing OAuth access token.
Amazon Advertising Client ID Client ID of the Amazon Advertising user.
Region Environment from which advertising data will be downloaded.
Report Ad Product Type of advertising product being reported.
Report Columns List of columns fetched from Reporting API.
Report Filters Set of filters used to trim returned data.
Report Group By Level of granularity of the report.
Report Ingestion Strategy Configuration of the report ingestion.
Report Ingestion Window How many days from the past should be downloaded during incremental ingestion.
Report Name Unique name of the report.
Report Profile ID The profile ID associated with an advertising account in a specific marketplace.
Report Start Date Start date from which the ingestion should happen.
Report Time Unit Date aggregation.
Report Type Data type contained in the report.
Web Client Service Provider Service providing client for REST request execution.
Scopes Description
CLUSTER Stores information about last report definition in form of hash to detect schema changes. Incrementally loaded reports persist last ingestion date to define ingestion date ranges after initial load. Additionally start date is saved.
Name Description
success Response FlowFiles transferred when receiving success response from Amazon Ads Reporting API.
Name Description
amazon.ads.report.id Unique identifier of the currently prepared job.
amazon.ads.report.name Unique name of the report.
amazon.ads.ingestion.strategy Strategy which defines if the report will be downloaded as a SNAPSHOT or INCREMENTALLY.
amazon.ads.run.id Unique identifier of the current ingestion process.
amazon.ads.ingestion.start.date Date from which data is downloaded from Amazon Ads (including given date).
amazon.ads.ingestion.end.date Date to which data is downloaded from Amazon Ads (including given date).
amazon.ads.report.schema.changed Flag meaning if the report schema has changed between processor executions.
avro.schema Avro schema containing set of all configured fields.
fragment.identifier A unique ID of each ingestion run. Lets you identify all flow files generated during a single run.
fragment.index Number representing unique identifier in batch of flowfiles generated during one ingestion run.
fragment.count Amount of flowfiles generated during processor execution.
Property Description
API Key The API Key for authenticating to Azure OpenAI
Deployment Name The name of the OpenAI model deployment to use for creating embeddings
Dimensions The number of dimensions to request the resulting output embeddings have. This is only supported in text-embedding-3 and later models.
Embeddings Record Path The path to the field in the record where the embeddings are to be written.
Max Batch Size The maximum number of records to include in each batch sent to OpenAI
OpenAI Service Name The name of the OpenAI service to use
Record Reader The record reader to use for reading record-oriented data. If the incoming data is to be treated as plaintext, this property should be left unset.
Record Writer The Record Writer to use for writing the output
Text Record Path The path to the field in the record that contains the text to be embedded. If the incoming data is to be treated as plaintext, this property should be left unset.
User An identifier for the remote user on whose behalf the request is being made; OpenAI uses this to detect and prevent abuse.
Web Client Service The Web Client Service to use for communicating with OpenAI
Name Description
failure The original FlowFile will be routed to this relationship if the embeddings could not be created
success The embeddings will be routed to this relationship
Name Description
record.count The number of records written to the output
mime.type The MIME type of the output data, based on the chosen Record Writer
Property Description
Box Client Service Controller Service used to obtain a Box API connection.
File ID The ID of the file for which to create metadata.
Record Reader The Record Reader to use for parsing the incoming data
Template Key The key of the metadata template to use for creation.
Name Description
failure A FlowFile is routed to this relationship if an error occurs during metadata creation.
file not found FlowFiles for which the specified Box file was not found will be routed to this relationship.
success A FlowFile is routed to this relationship after metadata has been successfully created.
template not found FlowFiles for which the specified metadata template was not found will be routed to this relationship.
Name Description
box.id The ID of the file for which metadata was created
box.template.key The template key used for metadata creation
error.code The error code returned by Box
error.message The error message returned by Box
Property Description
Box Client Service Controller Service used to obtain a Box API connection.
Hidden Whether the template should be hidden in the Box UI.
Record Reader The Record Reader to use for parsing the incoming data
Template Key The key of the metadata template to create (used for API calls).
Template Name The display name of the metadata template to create.
Name Description
failure A FlowFile is routed to this relationship if an error occurs during template creation.
success A FlowFile is routed to this relationship after a template has been successfully created.
Name Description
box.template.name The template name that was created
box.template.key The template key that was created
box.template.scope The template scope.
box.template.fields.count Number of fields created for the template
error.code The error code returned by Box
error.message The error message returned by Box
Property Description
Cohere API Key The API Key for authenticating to Cohere
Embedding Type Specifies the types of embeddings you want to get back.
Embeddings Model The model to use for embeddings, available models are listed at https://docs.cohere.com/reference/embed (https://docs.cohere.com/reference/embed)
Embeddings Record Path The path to the field in the record where the embeddings are to be written.
Input Type Specifies the type of input passed to the model. Required for embedding models v3 and higher.
Max Batch Size The maximum number of records to include in each batch sent to Cohere
Record Reader The record reader to use for reading record-oriented data. If the incoming data is to be treated as plaintext, this property should be left unset.
Record Writer The Record Writer to use for writing the output
Text Record Path The path to the field in the record that contains the text to be embedded. If the incoming data is to be treated as plaintext, this property should be left unset.
Truncate Policy One of NONE%start%END to specify how the API will handle inputs longer than the maximum token length.
User An identifier for the remote user on whose behalf the request is being made.
Name Description
failure The original FlowFile will be routed to this relationship if the embeddings could not be created
success The embeddings will be routed to this relationship
Name Description
record.count The number of records written to the output
mime.type The MIME type of the output data, based on the chosen Record Writer
Property Description
Access Token Token required to request Meta Ads Marketing API. It must match pattern 'Bearer <Access Token Value>'.
Action Report Time Determine the report time of action stats.
Click Attribution Window Attribution window for the click action.
Meta Ads API Version Version of Meta Ads API which is used for report generation.
Report Breakdowns List of values which determine how to break down the result. Multiple breakdowns can be picked, but only some combinations work.
Report Fields List of fields fetched from Marketing API. If non are selected most used fields will be downloaded.
Report Ingestion Strategy Configuration of the report ingestion.
Report Level Granularity of the report.
Report Name Unique name of the report.
Report Object ID ID of the object from which data will be fetched. It can be Account, Campaign, Ad or Ad Set ID.
Report Start Date Start date from which the ingestion should happen.
Report Time Increment Value of aggregation in days.
View Attribution Window Attribution window for the view action.
Web Client Service Provider Service providing client for REST request execution.
Scopes Description
CLUSTER Stores information about last report definition in form of hash to detect schema changes. Incrementally loaded reports persist last ingestion date to define ingestion date ranges after initial load. Additionally start date is saved.
Name Description
success Response FlowFiles transferred when receiving success response from Meta Ads Marketing API.
Name Description
meta.ads.report.id Unique identifier of the currently prepared job.
meta.ads.report.name Unique name of the report.
meta.ads.report.ingestion.strategy Strategy which defines if the report will be downloaded as a SNAPSHOT or INCREMENTALLY.
meta.ads.run.id Unique identifier of the current ingestion process.
meta.ads.ingestion.start.date Date from which data is downloaded from Meta Ads (including given date).
meta.ads.ingestion.end.date Date to which data is downloaded from Meta Ads (including given date).
meta.ads.report.schema.changed Flag meaning if the report schema has changed between processor executions.
avro.schema Avro schema containing set of all configured fields.
Property Description
Dimensions The number of dimensions to request the resulting output embeddings have. This is only supported in text-embedding-3 and later models.
Embeddings Model The model to use for embeddings
Embeddings Record Path The path to the field in the record where the embeddings are to be written.
Max Batch Size The maximum number of records to include in each batch sent to OpenAI
OpenAI API Key The API Key for authenticating to OpenAI
OpenAI Organization The organization to use for OpenAI
Record Reader The record reader to use for reading record-oriented data. If the incoming data is to be treated as plaintext, this property should be left unset.
Record Writer The Record Writer to use for writing the output
Text Record Path The path to the field in the record that contains the text to be embedded. If the incoming data is to be treated as plaintext, this property should be left unset.
User An identifier for the remote user on whose behalf the request is being made; OpenAI uses this to detect and prevent abuse.
Web Client Service The Web Client Service to use for communicating with OpenAI
Name Description
failure The original FlowFile will be routed to this relationship if the embeddings could not be created
success The embeddings will be routed to this relationship
Name Description
record.count The number of records written to the output
mime.type The MIME type of the output data, based on the chosen Record Writer
Property Description
Dimensions The number of dimensions to request the resulting output embeddings have.
Embeddings Model The model to use for embeddings
Record Writer The Record Writer to use for writing the output
Snowflake Connection Service Database Connection Service for accessing Snowflake
Name Description
failure The original FlowFile will be routed to this relationship if the embeddings could not be created
success The embeddings will be routed to this relationship
Name Description
record.count The number of records written to the output
mime.type The MIME type of the output data, based on the chosen Record Writer
Property Description
Auto Truncate If set to false, text that exceeds the token limit causes the request to fail.
Embeddings Model The model to use for embeddings, available models are listed at https://cloud.google.com/vertex-ai/generative-ai/docs/learn/models#models (https://cloud.google.com/vertex-ai/generative-ai/docs/learn/models#models)
Embeddings Record Path The path to the field in the record where the embeddings are to be written.
GCP Credentials Service The Controller Service used to obtain Google Cloud Platform credentials.
GCP Location The location to configure the Vertex client with
GCP Project ID The project ID to configure the Vertex client with
Max Batch Size The maximum number of records to include in each batch sent to VertexAI
Model Publisher The publisher of the model
Output Dimensionality Used to specify output embedding size. If set, output embeddings will be truncated to the size specified.
Record Reader The record reader to use for reading record-oriented data. If the incoming data is to be treated as plaintext, this property should be left unset.
Record Writer The Record Writer to use for writing the output
Task Type Used to convey intended downstream application of embeddings to help the model tune embeddings for a specific purpose.
Text Record Path The path to the field in the record that contains the text to be embedded. If the incoming data is to be treated as plaintext, this property should be left unset.
User An identifier for the remote user on whose behalf the request is being made.
Name Description
failure The original FlowFile will be routed to this relationship if the embeddings could not be created
success The embeddings will be routed to this relationship
Name Description
record.count The number of records written to the output
mime.type The MIME type of the output data, based on the chosen Record Writer
Property Description
fail_when_empty Route to failure if the content is empty. While hashing an empty value is valid, some flows may want to detect empty input.
hash_algorithm The hash algorithm to use. Note that not all of the algorithms available are recommended for use (some are provided for legacy compatibility). There are many things to consider when picking an algorithm; it is recommended to use the most secure algorithm possible.
Name Description
failure Used for flowfiles that have no content if the 'fail on empty' setting is enabled
success Used for flowfiles that have a hash value added
Name Description
content_<algorithm> This processor adds an attribute whose value is the result of hashing the flowfile content. The name of this attribute is specified by the value of the algorithm, e.g. 'content_SHA-256'.
Display Name API Name Default Value Allowable Values Description
Allow Duplicate Header Names Allow Duplicate Header Names true - true - false Whether duplicate header names are allowed. Header names are case-sensitive, for example "name" and "Name" are treated as separate fields.Handling of duplicate header names is CSV Parser specific (where applicable):* Apache Commons CSV - duplicate headers will result in column data "shifting" right with new fields created for "unknown_field_index_X" where "X" is the CSV column index number* Jackson CSV - duplicate headers will be de-duplicated with the field value being that of the right-most duplicate CSV column* FastCSV - duplicate headers will be de-duplicated with the field value being that of the left-most duplicate CSV column
CSV Format * CSV Format custom - Custom Format - RFC 4180 - Microsoft Excel - Tab-Delimited - MySQL Format - Informix Unload - Informix Unload Escape Disabled Specifies which "format" the CSV data is in, or specifies if custom formatting should be used.
Character Set * Character Set UTF-8 The Character Encoding that is used to encode/decode the CSV file
Comment Marker Comment Marker The character that is used to denote the start of a comment. Any line that begins with this comment will be ignored.
Date Format Date Format Specifies the format to use when reading/writing Date fields. If not specified, Date fields will be assumed to be number of milliseconds since epoch (Midnight, Jan 1, 1970 GMT). If specified, the value must match the Java java.time.format.DateTimeFormatter format (for example, MM/dd/yyyy for a two-digit month, followed by a two-digit day, followed by a four-digit year, all separated by '/' characters, as in 01/01/2017).
Escape Character * Escape Character The character that is used to escape characters that would otherwise have a specific meaning to the CSV Parser. If the property has been specified via Expression Language but the expression gets evaluated to an invalid Escape Character at runtime, then it will be skipped and the default Escape Character will be used. Setting it to an empty string means no escape character should be used.
Ignore CSV Header Column Names Ignore CSV Header Column Names false - true - false If the first line of a CSV is a header, and the configured schema does not match the fields named in the header line, this controls how the Reader will interpret the fields. If this property is true, then the field names mapped to each column are driven only by the configured schema and any fields not in the schema will be ignored. If this property is false, then the field names found in the CSV Header will be used as the names of the fields.
Null String Null String Specifies a String that, if present as a value in the CSV, should be considered a null field instead of using the literal value.
Quote Character * Quote Character " The character that is used to quote values so that escape characters do not have to be used. If the property has been specified via Expression Language but the expression gets evaluated to an invalid Quote Character at runtime, then it will be skipped and the default Quote Character will be used.
Record Separator * Record Separator n Specifies the characters to use in order to separate CSV Records
Schema Access Strategy * Schema Access Strategy infer-schema - Use 'Schema Name' Property - Use 'Schema Text' Property - Schema Reference Reader - Use String Fields From Header - Infer Schema Specifies how to obtain the schema that is to be used for interpreting the data.
Schema Branch Schema Branch Specifies the name of the branch to use when looking up the schema in the Schema Registry property. If the chosen Schema Registry does not support branching, this value will be ignored.
Schema Name Schema Name $\{schema.name\} Specifies the name of the schema to lookup in the Schema Registry property
Schema Reference Reader * Schema Reference Reader Service implementation responsible for reading FlowFile attributes or content to determine the Schema Reference Identifier
Schema Registry Schema Registry Specifies the Controller Service to use for the Schema Registry
Schema Text Schema Text $\{avro.schema\} The text of an Avro-formatted Schema
Schema Version Schema Version Specifies the version of the schema to lookup in the Schema Registry. If not specified then the latest version of the schema will be retrieved.
Time Format Time Format Specifies the format to use when reading/writing Time fields. If not specified, Time fields will be assumed to be number of milliseconds since epoch (Midnight, Jan 1, 1970 GMT). If specified, the value must match the Java java.time.format.DateTimeFormatter format (for example, HH:mm:ss for a two-digit hour in 24-hour format, followed by a two-digit minute, followed by a two-digit second, all separated by ':' characters, as in 18:04:15).
Timestamp Format Timestamp Format Specifies the format to use when reading/writing Timestamp fields. If not specified, Timestamp fields will be assumed to be number of milliseconds since epoch (Midnight, Jan 1, 1970 GMT). If specified, the value must match the Java java.time.format.DateTimeFormatter format (for example, MM/dd/yyyy HH:mm:ss for a two-digit month, followed by a two-digit day, followed by a four-digit year, all separated by '/' characters; and then followed by a two-digit hour in 24-hour format, followed by a two-digit minute, followed by a two-digit second, all separated by ':' characters, as in 01/01/2017 18:04:15).
Treat First Line as Header * Treat First Line as Header false - true - false Specifies whether or not the first line of CSV should be considered a Header or should be considered a record. If the Schema Access Strategy indicates that the columns must be defined in the header, then this property will be ignored, since the header must always be present and won't be processed as a Record. Otherwise, if 'true', then the first line of CSV data will not be processed as a record and if 'false',then the first line will be interpreted as a record.
Trim Fields * Trim Fields true - true - false Whether or not white space should be removed from the beginning and end of fields
Trim double quote * Trim double quote true - true - false Whether or not to trim starting and ending double quotes. For example: with trim string '"test"' would be parsed to 'test', without trim would be parsed to '"test"'.If set to 'false' it means full compliance with RFC-4180. Default value is true, with trim.
Value Separator * Value Separator , The character that is used to separate values/fields in a CSV Record. If the property has been specified via Expression Language but the expression gets evaluated to an invalid Value Separator at runtime, then it will be skipped and the default Value Separator will be used.
CSV Parser * csv-reader-csv-parser commons-csv - Apache Commons CSV - Jackson CSV - FastCSV Specifies which parser to use to read CSV records. NOTE: Different parsers may support different subsets of functionality and may also exhibit different levels of performance.
Display Name API Name Default Value Allowable Values Description
CSV Format * CSV Format default - Custom Format - RFC 4180 - Microsoft Excel - Tab-Delimited - MySQL Format - Informix Unload - Informix Unload Escape Disabled - Default Format - RFC4180 Specifies which "format" the CSV data is in, or specifies if custom formatting should be used.
Character Set * Character Set UTF-8 The Character Encoding that is used to decode the CSV file.
Comment Marker Comment Marker The character that is used to denote the start of a comment. Any line that begins with this comment will be ignored.
Escape Character * Escape Character The character that is used to escape characters that would otherwise have a specific meaning to the CSV Parser. If the property has been specified via Expression Language but the expression gets evaluated to an invalid Escape Character at runtime, then it will be skipped and the default Escape Character will be used. Setting it to an empty string means no escape character should be used.
Quote Character * Quote Character " The character that is used to quote values so that escape characters do not have to be used. If the property has been specified via Expression Language but the expression gets evaluated to an invalid Quote Character at runtime, then it will be skipped and the default Quote Character will be used.
Quote Mode * Quote Mode MINIMAL - Quote All Values - Quote Minimal - Quote Non-Numeric Values - Do Not Quote Values Specifies how fields should be quoted when they are written
Trim Fields * Trim Fields true - true - false Whether or not white space should be removed from the beginning and end of fields
Value Separator * Value Separator , The character that is used to separate values/fields in a CSV Record. If the property has been specified via Expression Language but the expression gets evaluated to an invalid Value Separator at runtime, then it will be skipped and the default Value Separator will be used.
CSV File * csv-file Path to a CSV File in which the key value pairs can be looked up.
Ignore Duplicates * ignore-duplicates true - true - false Ignore duplicate keys for records in the CSV file.
Lookup Key Column * lookup-key-column The field in the CSV file that will serve as the lookup key. This is the field that will be matched against the property specified in the lookup processor.
Required Permission Explanation
read filesystem Provides operator the ability to read from any file that NiFi has access to.
Display Name API Name Default Value Allowable Values Description
CSV Format * CSV Format custom - Custom Format - RFC 4180 - Microsoft Excel - Tab-Delimited - MySQL Format - Informix Unload - Informix Unload Escape Disabled Specifies which "format" the CSV data is in, or specifies if custom formatting should be used.
Character Set * Character Set UTF-8 The Character Encoding that is used to encode/decode the CSV file
Comment Marker Comment Marker The character that is used to denote the start of a comment. Any line that begins with this comment will be ignored.
Date Format Date Format Specifies the format to use when reading/writing Date fields. If not specified, Date fields will be assumed to be number of milliseconds since epoch (Midnight, Jan 1, 1970 GMT). If specified, the value must match the Java java.time.format.DateTimeFormatter format (for example, MM/dd/yyyy for a two-digit month, followed by a two-digit day, followed by a four-digit year, all separated by '/' characters, as in 01/01/2017).
Escape Character * Escape Character The character that is used to escape characters that would otherwise have a specific meaning to the CSV Parser. If the property has been specified via Expression Language but the expression gets evaluated to an invalid Escape Character at runtime, then it will be skipped and the default Escape Character will be used. Setting it to an empty string means no escape character should be used.
Include Header Line * Include Header Line true - true - false Specifies whether or not the CSV column names should be written out as the first line.
Include Trailing Delimiter * Include Trailing Delimiter false - true - false If true, a trailing delimiter will be added to each CSV Record that is written. If false, the trailing delimiter will be omitted.
Null String Null String Specifies a String that, if present as a value in the CSV, should be considered a null field instead of using the literal value.
Quote Character * Quote Character " The character that is used to quote values so that escape characters do not have to be used. If the property has been specified via Expression Language but the expression gets evaluated to an invalid Quote Character at runtime, then it will be skipped and the default Quote Character will be used.
Quote Mode * Quote Mode MINIMAL - Quote All Values - Quote Minimal - Quote Non-Numeric Values - Do Not Quote Values Specifies how fields should be quoted when they are written
Record Separator * Record Separator n Specifies the characters to use in order to separate CSV Records
Schema Access Strategy * Schema Access Strategy inherit-record-schema - Inherit Record Schema - Use 'Schema Name' Property - Use 'Schema Text' Property Specifies how to obtain the schema that is to be used for interpreting the data.
Schema Branch Schema Branch Specifies the name of the branch to use when looking up the schema in the Schema Registry property. If the chosen Schema Registry does not support branching, this value will be ignored.
Schema Cache Schema Cache Specifies a Schema Cache to add the Record Schema to so that Record Readers can quickly lookup the schema.
Schema Name Schema Name $\{schema.name\} Specifies the name of the schema to lookup in the Schema Registry property
Schema Reference Reader * Schema Reference Reader Service implementation responsible for reading FlowFile attributes or content to determine the Schema Reference Identifier
Schema Reference Writer * Schema Reference Writer Service implementation responsible for writing FlowFile attributes or content header with Schema reference information
Schema Registry Schema Registry Specifies the Controller Service to use for the Schema Registry
Schema Text Schema Text $\{avro.schema\} The text of an Avro-formatted Schema
Schema Version Schema Version Specifies the version of the schema to lookup in the Schema Registry. If not specified then the latest version of the schema will be retrieved.
Schema Write Strategy * Schema Write Strategy no-schema - Do Not Write Schema - Set 'schema.name' Attribute - Set 'avro.schema' Attribute - Schema Reference Writer Specifies how the schema for a Record should be added to the data.
Time Format Time Format Specifies the format to use when reading/writing Time fields. If not specified, Time fields will be assumed to be number of milliseconds since epoch (Midnight, Jan 1, 1970 GMT). If specified, the value must match the Java java.time.format.DateTimeFormatter format (for example, HH:mm:ss for a two-digit hour in 24-hour format, followed by a two-digit minute, followed by a two-digit second, all separated by ':' characters, as in 18:04:15).
Timestamp Format Timestamp Format Specifies the format to use when reading/writing Timestamp fields. If not specified, Timestamp fields will be assumed to be number of milliseconds since epoch (Midnight, Jan 1, 1970 GMT). If specified, the value must match the Java java.time.format.DateTimeFormatter format (for example, MM/dd/yyyy HH:mm:ss for a two-digit month, followed by a two-digit day, followed by a four-digit year, all separated by '/' characters; and then followed by a two-digit hour in 24-hour format, followed by a two-digit minute, followed by a two-digit second, all separated by ':' characters, as in 01/01/2017 18:04:15).
Trim Fields * Trim Fields true - true - false Whether or not white space should be removed from the beginning and end of fields
Value Separator * Value Separator , The character that is used to separate values/fields in a CSV Record. If the property has been specified via Expression Language but the expression gets evaluated to an invalid Value Separator at runtime, then it will be skipped and the default Value Separator will be used.
CSV Writer * csv-writer commons-csv - Apache Commons CSV - FastCSV Specifies which writer implementation to use to write CSV records. NOTE: Different writers may support different subsets of functionality and may also exhibit different levels of performance.
Display Name API Name Default Value Allowable Values Description
Connection Pooling Service * Connection Pooling Service The Connection Pooling Service that is used to obtain a connection to the database
Max Array Size * Max Array Size 1000 The maximum number of records to include in the array. This is a mechanism to ensure that the returned results due not cause memory issues. If the result set contains more records than this value, the lookup will fail. If the desire is instead to limit the number of rows returned, a LIMIT clause should be added to the SQL.
Multiple Result Field Name * Multiple Result Field Name results If multiple results are returned, they will be combined into an array. This property dictates the name of the field in the returned record.
Multiple Result Strategy * Multiple Result Strategy Fail - Use Array - Use First Only - Fail Specifies how to handle the situation where the lookup results in multiple records.
SQL * SQL The SQL statement to execute against the database in order to lookup the value. The statement may reference any attributes or values from the incoming Record that are provided by the calling Processor via Expression Language. The processor is will extract any Expression Language expressions and replace them with parameterized values so that the SQL can be safely executed, avoiding SQL Injection attacks.
Display Name API Name Default Value Allowable Values Description
Cache Expiration Cache Expiration Time interval to clear all cache entries. If the Cache Size is zero then this property is ignored.
Default Decimal Precision * Default Decimal Precision 10 When a DECIMAL/NUMBER value is written as a 'decimal' Avro logical type, a specific 'precision' denoting number of available digits is required. Generally, precision is defined by column data type definition or database engines default. However undefined precision (0) can be returned from some database engines. 'Default Decimal Precision' is used when writing those undefined precision numbers.
Default Decimal Scale * Default Decimal Scale 0 When a DECIMAL/NUMBER value is written as a 'decimal' Avro logical type, a specific 'scale' denoting number of available decimal digits is required. Generally, scale is defined by column data type definition or database engines default. However when undefined precision (0) is returned, scale can also be uncertain with some database engines. 'Default Decimal Scale' is used when writing those undefined numbers. If a value has more decimals than specified scale, then the value will be rounded-up, e.g. 1.53 becomes 2 with scale 0, and 1.5 with scale 1.
Cache Size * dbrecord-lookup-cache-size 0 Specifies how many lookup values/records should be cached. The cache is shared for all tables and keeps a map of lookup values to records. Setting this property to zero means no caching will be done and the table will be queried for each lookup value in each record. If the lookup table changes often or the most recent data must be retrieved, do not use the cache.
Clear Cache on Enabled * dbrecord-lookup-clear-cache-on-enabled true - true - false Whether to clear the cache when this service is enabled. If the Cache Size is zero then this property is ignored. Clearing the cache when the service is enabled ensures that the service will first go to the database to get the most recent data.
Database Connection Pooling Service * dbrecord-lookup-dbcp-service The Controller Service that is used to obtain connection to database
Lookup Key Column * dbrecord-lookup-key-column The column in the table that will serve as the lookup key. This is the column that will be matched against the property specified in the lookup processor. Note that this may be case-sensitive depending on the database.
Table Name * dbrecord-lookup-table-name The name of the database table to be queried. Note that this may be case-sensitive depending on the database.
Lookup Value Columns dbrecord-lookup-value-columns A comma-delimited list of columns in the table that will be returned when the lookup key matches. Note that this may be case-sensitive depending on the database.
Display Name API Name Default Value Allowable Values Description
Catalog Name db-record-sink-catalog-name The name of the catalog that the statement should update. This may not apply for the database that you are updating. In this case, leave the field empty
Database Connection Pooling Service * db-record-sink-dcbp-service The Controller Service that is used to obtain a connection to the database for sending records.
Max Wait Time * db-record-sink-query-timeout 0 seconds The maximum amount of time allowed for a running SQL statement , zero means there is no limit. Max time less than 1 second will be equal to zero.
Quote Column Identifiers db-record-sink-quoted-identifiers false - true - false Enabling this option will cause all column names to be quoted, allowing you to use reserved words as column names in your tables.
Quote Table Identifiers db-record-sink-quoted-table-identifiers false - true - false Enabling this option will cause the table name to be quoted to support the use of special characters in the table name.
Schema Name db-record-sink-schema-name The name of the schema that the table belongs to. This may not apply for the database that you are updating. In this case, leave the field empty
Table Name * db-record-sink-table-name The name of the table that the statement should affect.
Translate Field Names db-record-sink-translate-field-names true - true - false If true, the Processor will attempt to translate field names into the appropriate column names for the table specified. If false, the field names must match the column names exactly, or the column will not be updated
Unmatched Column Behavior db-record-sink-unmatched-column-behavior Fail on Unmatched Columns - Ignore Unmatched Columns - Warn on Unmatched Columns - Fail on Unmatched Columns If an incoming record does not have a field mapping for all of the database table's columns, this property specifies how to handle the situation
Unmatched Field Behavior db-record-sink-unmatched-field-behavior Ignore Unmatched Fields - Ignore Unmatched Fields - Fail on Unmatched Fields If an incoming record has a field that does not map to any of the database table's columns, this property specifies how to handle the situation
Display Name API Name Default Value Allowable Values Description
Database Connection URL * Database Connection URL A database connection URL used to connect to a database. May contain database system name, host, port, database name and some parameters. The exact syntax of a database connection URL is specified by your DBMS.
Database Driver Class Name * Database Driver Class Name Database driver class name
Database Driver Location(s) Database Driver Location(s) Comma-separated list of files/folders and/or URLs containing the driver JAR and its dependencies (if any). For example '/var/tmp/mariadb-java-client-1.1.7.jar'
Database User Database User Database user name
Kerberos User Service Kerberos User Service Specifies the Kerberos User Controller Service that should be used for authenticating with Kerberos
Max Total Connections * Max Total Connections 8 The maximum number of active connections that can be allocated from this pool at the same time, or negative for no limit.
Max Wait Time * Max Wait Time 500 millis The maximum amount of time that the pool will wait (when there are no available connections) for a connection to be returned before failing, or -1 to wait indefinitely.
Maximum Connection Lifetime Maximum Connection Lifetime -1 The maximum lifetime of a connection. After this time is exceeded the connection will fail the next activation, passivation or validation test. A value of zero or less means the connection has an infinite lifetime.
Maximum Idle Connections Maximum Idle Connections 8 The maximum number of connections that can remain idle in the pool without extra ones being released. Set to any negative value to allow unlimited idle connections.
Minimum Evictable Idle Time Minimum Evictable Idle Time 30 mins The minimum amount of time a connection may sit idle in the pool before it is eligible for eviction.
Minimum Idle Connections Minimum Idle Connections 0 The minimum number of connections that can remain idle in the pool without extra ones being created. Set to or zero to allow no idle connections.
Password Password The password for the database user
Soft Minimum Evictable Idle Time Soft Minimum Evictable Idle Time -1 The minimum amount of time a connection may sit idle in the pool before it is eligible for eviction by the idle connection evictor, with the extra condition that at least a minimum number of idle connections remain in the pool. When the not-soft version of this option is set to a positive value, it is examined first by the idle connection evictor: when idle connections are visited by the evictor, idle time is first compared against it (without considering the number of idle connections in the pool) and then against this soft option, including the minimum idle connections constraint.
Time Between Eviction Runs Time Between Eviction Runs -1 The time period to sleep between runs of the idle connection evictor thread. When non-positive, no idle connection evictor thread will be run.
Validation Query Validation Query Validation query used to validate connections before returning them. When connection is invalid, it gets dropped and new valid connection will be returned. Note!! Using validation might have some performance penalty.
Required Permission Explanation
reference remote resources Database Driver Location can reference resources over HTTP
Property Description
@OnScheduled Pause Time Specifies how long the processor should sleep in the @OnScheduled method, so that the processor can be forced to take a long time to start up
@OnStopped Pause Time Specifies how long the processor should sleep in the @OnStopped method, so that the processor can be forced to take a long time to shutdown
@OnUnscheduled Pause Time Specifies how long the processor should sleep in the @OnUnscheduled method, so that the processor can be forced to take a long time to respond when user clicks stop
Content Size The number of bytes to write each time that the FlowFile is written to
CustomValidate Pause Time Specifies how long the processor should sleep in the customValidate() method
Fail When @OnScheduled called Specifies whether or not the Processor should throw an Exception when the methods annotated with @OnScheduled are called
Fail When @OnStopped called Specifies whether or not the Processor should throw an Exception when the methods annotated with @OnStopped are called
Fail When @OnUnscheduled called Specifies whether or not the Processor should throw an Exception when the methods annotated with @OnUnscheduled are called
FlowFile Exception Class Exception class to be thrown (must extend java.lang. RuntimeException).
FlowFile Exception Iterations Number of FlowFiles to throw exception.
FlowFile Failure Iterations Number of FlowFiles to forward to failure relationship.
FlowFile Rollback Iterations Number of FlowFiles to roll back (without penalty).
FlowFile Rollback Penalty Iterations Number of FlowFiles to roll back with penalty.
FlowFile Rollback Yield Iterations Number of FlowFiles to roll back and yield.
FlowFile Success Iterations Number of FlowFiles to forward to success relationship.
Ignore Interrupts When Paused If the Processor's thread(s) are sleeping (due to one of the "Pause Time" properties above), and the thread is interrupted, this indicates whether the Processor should ignore the interrupt and continue sleeping or if it should allow itself to be interrupted.
No FlowFile Exception Class Exception class to be thrown if no FlowFile (must extend java.lang. RuntimeException).
No FlowFile Exception Iterations Number of times to throw NPE exception if no FlowFile.
No FlowFile Skip Iterations Number of times to skip onTrigger if no FlowFile.
No FlowFile Yield Iterations Number of times to yield if no FlowFile.
OnTrigger Pause Time Specifies how long the processor should sleep in the onTrigger() method, so that the processor can be forced to take a long time to perform its task
Write Iterations Number of times to write to the FlowFile
Name Description
failure FlowFiles that failed to process.
success FlowFiles processed successfully.
Property Description
Private Key Identities One or more X25519 Private Key Identities, separated with newlines, encoded according to the age specification, starting with AGE-SECRET-KEY-1
Private Key Identity Resources One or more files or URLs containing X25519 Private Key Identities, separated with newlines, encoded according to the age specification, starting with AGE-SECRET-KEY-1
Private Key Source Source of information determines the loading strategy for X25519 Private Key Identities
Name Description
failure Decryption Failed
success Decryption Completed
Property Description
decryption-strategy Strategy for writing files to success after decryption
passphrase Passphrase used for decrypting data encrypted with Password-Based Encryption
private-key-service PGP Private Key Service for decrypting data encrypted with Public Key Encryption
Name Description
failure Decryption Failed
success Decryption Succeeded
Name Description
pgp.literal.data.filename Filename from decrypted Literal Data
pgp.literal.data.modified Modified Date from decrypted Literal Data
pgp.symmetric.key.algorithm.block.cipher Symmetric-Key Algorithm Block Cipher
pgp.symmetric.key.algorithm.id Symmetric-Key Algorithm Identifier
Property Description
bloom-filter-certainty The desired false positive probability when using the BloomFilter type. Using a value of .05 for example, guarantees a five-percent probability that the result is a false positive. The closer to 1 this value is set, the more precise the result at the expense of more storage space utilization.
cache-identifier An optional expression language field that overrides the record's computed cache key. This field has an additional attribute available: $\{record.hash.value\}, which contains the cache key derived from dynamic properties (if set) or record fields.
deduplication-strategy The strategy to use for detecting and routing duplicate records. The option for detecting duplicates across a single FlowFile operates in-memory, whereas detection spanning multiple FlowFiles utilises a distributed map cache.
distributed-map-cache This property is required when the deduplication strategy is set to 'multiple files.' The map cache will for each record, atomically check whether the cache key exists and if not, set it.
filter-capacity-hint An estimation of the total number of unique records to be processed. The more accurate this number is will lead to fewer false negatives on a BloomFilter.
filter-type The filter used to determine whether a record has been seen before based on the matching RecordPath criteria. If hash set is selected, a Java HashSet object will be used to deduplicate all encountered records. If the bloom filter option is selected, a bloom filter will be used. The bloom filter option is less memory intensive, but has a chance of having false positives.
include-zero-record-flowfiles If a FlowFile sent to either the duplicate or non-duplicate relationships contains no records, a value of _false_ in this property causes the FlowFile to be dropped. Otherwise, the empty FlowFile is emitted.
put-cache-identifier For each record, check whether the cache identifier exists in the distributed map cache. If it doesn't exist and this property is true, put the identifier to the cache.
record-hashing-algorithm The algorithm used to hash the cache key.
record-reader Specifies the Controller Service to use for reading incoming data
record-writer Specifies the Controller Service to use for writing out the records
Name Description
duplicate Records detected as duplicates are routed to this relationship.
failure If unable to communicate with the cache, the FlowFile will be penalized and routed to this relationship
non-duplicate Records not found in the cache are routed to this relationship.
original The original input FlowFile is sent to this relationship unless a fatal error occurs.
Name Description
record.count Number of records written to the destination FlowFile.
Property Description
Blob Name The full name of the blob
Container Name Name of the Azure storage container. In case of PutAzureBlobStorage processor, container can be created if it does not exist.
Delete Snapshots Option Specifies the snapshot deletion options to be used when deleting a blob.
Storage Credentials Controller Service used to obtain Azure Blob Storage Credentials.
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests. In case of SOCKS, it is not guaranteed that the selected SOCKS Version will be used by the processor.
Name Description
failure Unsuccessful operations will be transferred to the failure relationship.
success All successfully processed FlowFiles are routed to this relationship
Property Description
ADLS Credentials Controller Service used to obtain Azure Credentials.
Directory Name Name of the Azure Storage Directory. The Directory Name cannot contain a leading '/'. The root directory can be designated by the empty string value. In case of the PutAzureDataLakeStorage processor, the directory will be created if not already existing.
File Name The filename
Filesystem Name Name of the Azure Storage File System (also called Container). It is assumed to be already existing.
Filesystem Object Type They type of the file system object to be deleted. It can be either folder or file.
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests. In case of SOCKS, it is not guaranteed that the selected SOCKS Version will be used by the processor.
Name Description
failure Files that could not be written to Azure storage for some reason are transferred to this relationship
success Files that have been successfully written to Azure storage are transferred to this relationship
Property Description
Box Client Service Controller Service used to obtain a Box API connection.
File ID The ID of the file from which to delete metadata.
Template Key The key of the metadata template instance to delete.
Name Description
failure A FlowFile is routed to this relationship if an error occurs during metadata deletion.
file not found FlowFiles for which the specified Box file was not found will be routed to this relationship.
success A FlowFile is routed to this relationship after metadata has been successfully deleted.
template not found FlowFiles for which the specified metadata template was not found will be routed to this relationship.
Name Description
box.id The ID of the file from which metadata was deleted
box.template.key The template key used for metadata deletion
error.code The error code returned by Box
error.message The error message returned by Box
Property Description
Client Service An Elasticsearch client service to use for running queries.
Index The name of the index to use.
Max JSON Field String Length The maximum allowed length of a string value when parsing a JSON document or attribute.
Query A query in JSON syntax, not Lucene syntax. Ex: \{"query":\{"match":\{"somefield":"somevalue"\}\}\}. If this parameter is not set, the query will be read from the flowfile content. If the query (property and flowfile content) is empty, a default empty JSON Object will be used, which will result in a "match_all" query in Elasticsearch.
Query Attribute If set, the executed query will be set on each result flowfile in the specified attribute.
Query Clause A "query" clause in JSON syntax, not Lucene syntax. Ex: \{"match":\{"somefield":"somevalue"\}\}. If the query is empty, a default JSON Object will be used, which will result in a "match_all" query in Elasticsearch.
Query Definition Style How the JSON Query will be defined for use by the processor.
Type The type of this document (used by Elasticsearch for indexing and searching).
Name Description
failure If the "by query" operation fails, and a flowfile was read, it will be sent to this relationship.
retry All flowfiles that fail due to server/cluster availability go to this relationship.
success If the "by query" operation succeeds, and a flowfile was read, it will be sent to this relationship.
Name Description
elasticsearch.delete.took The amount of time that it took to complete the delete operation in ms.
elasticsearch.delete.error The error message provided by Elasticsearch if there is an error running the delete.
Property Description
DBFS File Path DBFS file path e.g. /directory/file.txt
Databricks Client Databricks Client Service.
Name Description
failure Databricks failure relationship
success Databricks success relationship
Name Description
error.code The error code for the SQL statement if an error occurred.
error.message The error message for the SQL statement if an error occurred.
Property Description
AWS Credentials Provider service The Controller Service that is used to obtain AWS credentials provider
Batch items for each request (between 1 and 50) The items to be retrieved in one batch
Communications Timeout
Endpoint Override URL Endpoint URL to use instead of the AWS default including scheme, host, port, and path. The AWS libraries select an endpoint URL based on the AWS region, but this property overrides the selected endpoint URL, allowing use with other S3-compatible endpoints.
Hash Key Name The hash key name of the item
Hash Key Value The hash key value of the item
Hash Key Value Type The hash key value type of the item
Range Key Name The range key name of the item
Range Key Value
Range Key Value Type The range key value type of the item
Region
SSL Context Service Specifies an optional SSL Context Service that, if provided, will be used to create connections
Table Name The DynamoDB table name
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
failure FlowFiles are routed to failure relationship
success FlowFiles are routed to success relationship
unprocessed FlowFiles are routed to unprocessed relationship when DynamoDB is not able to process all the items in the request. Typical reasons are insufficient table throughput capacity and exceeding the maximum bytes per request. Unprocessed FlowFiles can be retried with a new request.
Name Description
dynamodb.key.error.unprocessed DynamoDB unprocessed keys
dynmodb.range.key.value.error DynamoDB range key error
dynamodb.key.error.not.found DynamoDB key not found
dynamodb.error.exception.message DynamoDB exception message
dynamodb.error.code DynamoDB error code
dynamodb.error.message DynamoDB error message
dynamodb.error.service DynamoDB error service
dynamodb.error.retryable DynamoDB error is retryable
dynamodb.error.request.id DynamoDB error request id
dynamodb.error.status.code DynamoDB status code
Property Description
Directory Path The path to the directory the file to delete is located in.
Filename The name of the file to delete.
Required Permission Explanation
read filesystem Provides operator the ability to read from any file that NiFi has access to.
write filesystem Provides operator the ability to delete any file that NiFi has access to.
Name Description
failure All FlowFiles, for which an existing file could not be deleted, are routed to this relationship
not found All FlowFiles, for which the file to delete did not exist, are routed to this relationship
success All FlowFiles, for which an existing file has been deleted, are routed to this relationship
Property Description
GCP Credentials Provider Service The Controller Service used to obtain Google Cloud Platform credentials.
gcp-project-id Google Cloud Project ID
gcp-retry-count How many retry attempts should be made before routing to the failure relationship.
gcs-bucket Bucket of the object.
gcs-generation The generation of the object to be deleted. If null, will use latest version of the object.
gcs-key Name of the object.
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
storage-api-url Overrides the default storage URL. Configuring an alternative Storage API URL also overrides the HTTP Host header on requests as described in the Google documentation for Private Service Connections.
Name Description
failure FlowFiles are routed to this relationship if the Google Cloud Storage operation fails.
success FlowFiles are routed to this relationship after a successful Google Cloud Storage operation.
Property Description
delete-gridfs-query A valid MongoDB query to use to find and delete one or more files from GridFS.
gridfs-bucket-name The GridFS bucket where the files will be stored. If left blank, it will use the default value 'fs' that the MongoDB client driver uses.
gridfs-client-service The MongoDB client service to use for database connections.
gridfs-database-name The name of the database to use
gridfs-file-name The name of the file in the bucket that is the target of this processor. GridFS file names do not include path information because GridFS does not sort files into folders within a bucket.
mongo-query-attribute If set, the query will be written to a specified attribute on the output flowfiles.
Name Description
failure When there is a failure processing the flowfile, it goes to this relationship.
success When the operation succeeds, the flowfile is sent to this relationship.
Property Description
Collection Name The name of the Milvus collection name to use
Delete Filter The filter to use in the delete request. Example: id like "prefix%"
Delete Strategy The strategy to use for deleting vectors in Milvus
ID Record Path The path to the ID field in the record
Milvus Connection Service Connection Service for accessing Milvus Database
Partition Partition of the vector database that you want to perform operations in. If the database has only one partition leave empty.
Record Reader The Record Reader to use for reading the FlowFile
Name Description
failure FlowFiles that cannot be sent to Milvus, and for which a retry is not expected to be successful, are routed to this relationship
retry FlowFiles that fail to be sent to Milvus, but for which a retry may help, are routed to this relationship
success FlowFiles that are successfully sent to Milvus are routed to this relationship
Property Description
Mongo Collection Name The name of the collection to use
Mongo Database Name The name of the database to use
delete-mongo-delete-mode Choose between deleting one document by query or many documents by query.
delete-mongo-fail-on-no-delete Determines whether to send the flowfile to the success or failure relationship if nothing is successfully deleted.
mongo-client-service If configured, this property will use the assigned client service for connection pooling.
Name Description
failure All FlowFiles that cannot be written to MongoDB are routed to this relationship
success All FlowFiles that are written to MongoDB are routed to this relationship
Property Description
ID Prefix The Pinecone vector ID prefix. If specified, only the vectors whose IDs start with the given value will be deleted.
Pinecone API Key The API key for the Pinecone service
Pinecone Index The name of the Pinecone index to use
Pinecone Namespace The name of the Pinecone namespace to use
Web Client Service The Web Client Service to use for communicating with Pinecone
Name Description
failure FlowFiles that cannot be sent to Pinecone, and for which a retry is not expected to be successful, are routed to this relationship
retry FlowFiles that fail to be sent to Pinecone, but for which a retry may help, are routed to this relationship
success FlowFiles that are successfully sent to Pinecone are routed to this relationship
Property Description
Job ID The ID of the job for which the status is checked.
Salesforce Client Salesforce Client to interact with the APIs
Name Description
comms.failure A FlowFile is routed to this relationship if the Query Job status could not be retrieved but the operation might be retried
failure A FlowFile is routed to this relationship if the Query Job status could not be retrieved
success If the Query Job has been successfully deleted, the FlowFile is routed to this relationship
Property Description
AWS Credentials Provider service The Controller Service that is used to obtain AWS credentials provider
Bucket The S3 Bucket to interact with
Communications Timeout The amount of time to wait in order to establish a connection to AWS or receive data from AWS before timing out.
Custom Signer Class Name Fully qualified class name of the custom signer class. The signer must implement com.amazonaws.auth. Signer interface.
Custom Signer Module Location Comma-separated list of paths to files and/or directories which contain the custom signer's JAR file and its dependencies (if any).
Endpoint Override URL Endpoint URL to use instead of the AWS default including scheme, host, port, and path. The AWS libraries select an endpoint URL based on the AWS region, but this property overrides the selected endpoint URL, allowing use with other S3-compatible endpoints.
FullControl User List A comma-separated list of Amazon User ID's or E-mail addresses that specifies who should have Full Control for an object
Object Key The S3 Object Key to use. This is analogous to a filename for traditional file systems.
Owner The Amazon ID to use for the object's owner
Read ACL User List A comma-separated list of Amazon User ID's or E-mail addresses that specifies who should have permissions to read the Access Control List for an object
Read Permission User List A comma-separated list of Amazon User ID's or E-mail addresses that specifies who should have Read Access for an object
Region The AWS Region to connect to.
SSL Context Service Specifies an optional SSL Context Service that, if provided, will be used to create connections
Signer Override The AWS S3 library uses Signature Version 4 by default but this property allows you to specify the Version 2 signer to support older S3-compatible services or even to plug in your own custom signer implementation.
Version The Version of the Object to delete
Write ACL User List A comma-separated list of Amazon User ID's or E-mail addresses that specifies who should have permissions to change the Access Control List for an object
Write Permission User List A comma-separated list of Amazon User ID's or E-mail addresses that specifies who should have Write Access for an object
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
failure If the Processor is unable to process a given FlowFile, it will be routed to this Relationship.
success FlowFiles are routed to this Relationship after they have been successfully processed.
Name Description
s3.exception The class name of the exception thrown during processor execution
s3.additionalDetails The S3 supplied detail from the failed operation
s3.statusCode The HTTP error code (if available) from the failed operation
s3.errorCode The S3 moniker of the failed operation
s3.errorMessage The S3 exception message from the failed operation
Property Description
Algorithm Negotiation Configuration strategy for SSH algorithm negotiation
Batch Size The maximum number of FlowFiles to send in a single connection
Ciphers Allowed A comma-separated list of Ciphers allowed for SFTP connections. Leave unset to allow all. Available options are: 3des-cbc, aes128-cbc, aes128-ctr, [aes128-gcm@openssh.com](mailto:aes128-gcm@openssh.com), aes192-cbc, aes192-ctr, aes256-cbc, aes256-ctr, [aes256-gcm@openssh.com](mailto:aes256-gcm@openssh.com), arcfour128, arcfour256, blowfish-cbc, [chacha20-poly1305@openssh.com](mailto:chacha20-poly1305@openssh.com), none
Connection Timeout Amount of time to wait before timing out while creating a connection
Data Timeout When transferring a file between the local and remote system, this value specifies how long is allowed to elapse without any data being transferred between systems
Directory Path The path to the directory the file to delete is located in.
Filename The name of the file to delete.
Host Key File If supplied, the given file will be used as the Host Key; otherwise, if 'Strict Host Key Checking' property is applied (set to true) then uses the 'known_hosts' and 'known_hosts2' files from ~/.ssh directory else no host key file will be used
Hostname The fully qualified hostname or IP address of the remote system
Key Algorithms Allowed A comma-separated list of Key Algorithms allowed for SFTP connections. Leave unset to allow all. Available options are: ecdsa-sha2-nistp256, [ecdsa-sha2-nistp256-cert-v01@openssh.com](mailto:ecdsa-sha2-nistp256-cert-v01@openssh.com), ecdsa-sha2-nistp384, [ecdsa-sha2-nistp384-cert-v01@openssh.com](mailto:ecdsa-sha2-nistp384-cert-v01@openssh.com), ecdsa-sha2-nistp521, [ecdsa-sha2-nistp521-cert-v01@openssh.com](mailto:ecdsa-sha2-nistp521-cert-v01@openssh.com), rsa-sha2-256, [rsa-sha2-256-cert-v01@openssh.com](mailto:rsa-sha2-256-cert-v01@openssh.com), rsa-sha2-512, [rsa-sha2-512-cert-v01@openssh.com](mailto:rsa-sha2-512-cert-v01@openssh.com), [sk-ecdsa-sha2-nistp256@openssh.com](mailto:sk-ecdsa-sha2-nistp256@openssh.com), [sk-ssh-ed25519@openssh.com](mailto:sk-ssh-ed25519@openssh.com), ssh-dss, [ssh-dss-cert-v01@openssh.com](mailto:ssh-dss-cert-v01@openssh.com), ssh-ed25519, [ssh-ed25519-cert-v01@openssh.com](mailto:ssh-ed25519-cert-v01@openssh.com), ssh-rsa, [ssh-rsa-cert-v01@openssh.com](mailto:ssh-rsa-cert-v01@openssh.com)
Key Exchange Algorithms Allowed A comma-separated list of Key Exchange Algorithms allowed for SFTP connections. Leave unset to allow all. Available options are: curve25519-sha256, [curve25519-sha256@libssh.org](mailto:curve25519-sha256@libssh.org), curve448-sha512, diffie-hellman-group-exchange-sha1, diffie-hellman-group-exchange-sha256, diffie-hellman-group1-sha1, diffie-hellman-group14-sha1, diffie-hellman-group14-sha256, diffie-hellman-group15-sha512, diffie-hellman-group16-sha512, diffie-hellman-group17-sha512, diffie-hellman-group18-sha512, ecdh-sha2-nistp256, ecdh-sha2-nistp384, ecdh-sha2-nistp521, mlkem1024nistp384-sha384, mlkem768nistp256-sha256, mlkem768x25519-sha256, sntrup761x25519-sha512, [sntrup761x25519-sha512@openssh.com](mailto:sntrup761x25519-sha512@openssh.com)
Message Authentication Codes Allowed A comma-separated list of Message Authentication Codes allowed for SFTP connections. Leave unset to allow all. Available options are: hmac-md5, hmac-md5-96, hmac-sha1, hmac-sha1-96, [hmac-sha1-etm@openssh.com](mailto:hmac-sha1-etm@openssh.com), hmac-sha2-256, [hmac-sha2-256-etm@openssh.com](mailto:hmac-sha2-256-etm@openssh.com), hmac-sha2-512, [hmac-sha2-512-etm@openssh.com](mailto:hmac-sha2-512-etm@openssh.com)
Password Password for the user account
Port The port that the remote system is listening on for file transfers
Private Key Passphrase Password for the private key
Private Key Path The fully qualified path to the Private Key file
Send Keep Alive On Timeout Send a Keep Alive message every 5 seconds up to 5 times for an overall timeout of 25 seconds.
Strict Host Key Checking Indicates whether or not strict enforcement of hosts keys should be applied
Use Compression Indicates whether or not ZLIB compression should be used when transferring files
Username Username
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
failure All FlowFiles, for which an existing file could not be deleted, are routed to this relationship
not found All FlowFiles, for which the file to delete did not exist, are routed to this relationship
success All FlowFiles, for which an existing file has been deleted, are routed to this relationship
Property Description
AWS Credentials Provider service The Controller Service that is used to obtain AWS credentials provider
Communications Timeout
Endpoint Override URL Endpoint URL to use instead of the AWS default including scheme, host, port, and path. The AWS libraries select an endpoint URL based on the AWS region, but this property overrides the selected endpoint URL, allowing use with other S3-compatible endpoints.
Queue URL The URL of the queue delete from
Receipt Handle The identifier that specifies the receipt of the message
Region
SSL Context Service Specifies an optional SSL Context Service that, if provided, will be used to create connections
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
failure FlowFiles are routed to failure relationship
success FlowFiles are routed to success relationship
Property Description
Databricks Client Databricks Client Service.
Missing Resource Policy What to action to take if the resource is not found.
Unity Catalog Resource Path Unity Catalog resource path e.g. /Volumes/catalog/schema/volume_name/path
Name Description
failure Databricks failure relationship
success Databricks success relationship
Name Description
error.code The error code for the SQL statement if an error occurred.
error.message The error message for the SQL statement if an error occurred.
Property Description
Data Share Name The name of the Data Share to describe.
Salesforce Data Cloud Client Salesforce Data Cloud Client to interact with the APIs
Name Description
comms.failure A FlowFile is routed to this relationship if the data share metadata could not be retrieved but the operation might be retried
failure A FlowFile is routed to this relationship if the data share metadata could not be retrieved
success FlowFile containing the data share metadata will be routed to this relationship
Name Description
explicitDataLakeObjects Comma-separated list of the names of the explicit data lake objects.
implicitDataLakeObjects Comma-separated list of the names of the implicit data lake objects.
dataModelObjects Comma-separated list of the names of the data model objects.
calculatedInsightObjects Comma-separated list of the names of the calculated insights objects.
Property Description
Object Fields Filter JSON JSON representation describing which fields to include or exclude for Salesforce objects.
Object Name The name of the object to describe.
Salesforce Client Salesforce Client to interact with the APIs
Name Description
comms.failure A FlowFile is routed to this relationship if the object metadata could not be retrieved but the operation might be retried
failure A FlowFile is routed to this relationship if the object metadata could not be retrieved
success FlowFile containing the object metadata will be routed to this relationship
Name Description
sObjectFields Comma-separated list of the fields of the object (without non-queryable fields).
sObjectExcludedFields Comma-separated list of the non-queryable fields of the object.
sObjectSchema The schema associated to the object based on its fields (without non-queryable fields).
Property Description
Age Off Duration Time interval to age off cached FlowFiles
Cache Entry Identifier A FlowFile attribute, or the results of an Attribute Expression Language statement, which will be evaluated against a FlowFile in order to determine the value used to identify duplicates; it is this value that is cached
Cache The Entry Identifier When true this cause the processor to check for duplicates and cache the Entry Identifier. When false, the processor would only check for duplicates and not cache the Entry Identifier, requiring another processor to add identifiers to the distributed cache.
Distributed Cache Service The Controller Service that is used to cache unique identifiers, used to determine duplicates
FlowFile Description When a FlowFile is added to the cache, this value is stored along with it so that if a duplicate is found, this description of the original FlowFile will be added to the duplicate's "original.flowfile.description" attribute
Name Description
duplicate If a FlowFile has been detected to be a duplicate, it will be routed to this relationship
failure If unable to communicate with the cache, the FlowFile will be penalized and routed to this relationship
non-duplicate If a FlowFile's Cache Entry Identifier was not found in the cache, it will be routed to this relationship
Name Description
original.flowfile.description All FlowFiles routed to the duplicate relationship will have an attribute added named original.flowfile.description. The value of this attribute is determined by the attributes of the original copy of the data and by the FlowFile Description property.
Display Name API Name Default Value Allowable Values Description
Developer Token * Developer Token The Developer Token to use to interact with the Box API. This is for testing only and should not be used in production.
Display Name API Name Default Value Allowable Values Description
Character Encoding * character-encoding UTF-8 - ISO-8859-1 - UTF-8 - UTF-16 - UTF-16LE - UTF-16BE - US-ASCII Specifies a character encoding to use.
Distributed Cache Service * distributed-map-cache-service The Controller Service that is used to get the cached values.
Property Description
Distribution Strategy Determines how the load will be distributed. Relationship weight is in numeric order where '1' has the greatest weight.
Number of Relationships Determines the number of Relationships to which the load should be distributed
Name Description
1 Where to route flowfiles for this relationship index
Name Description
distribute.load.relationship The name of the specific relationship the FlowFile has been routed through
Property Description
Number of Copies Specifies how many copies of each incoming FlowFile will be made
Name Description
success The original FlowFile and all copies will be sent to this relationship
Name Description
copy.index A zero-based incrementing integer value based on which copy the FlowFile is.
Display Name API Name Default Value Allowable Values Description
API Key * API Key Encoded API key.
API Key ID * API Key ID Unique identifier of the API key.
Authorization Scheme * Authorization Scheme BASIC - None - PKI - Basic - API Key - JWT Authorization Scheme used for optional authentication to Elasticsearch.
Character Set * Character Set UTF-8 The charset to use for interpreting the response from Elasticsearch.
Connect timeout * Connect timeout 5000 Controls the amount of time, in milliseconds, before a timeout occurs when trying to connect.
Enable Compression * Enable Compression false - true - false Whether the REST client should compress requests using gzip content encoding and add the "Accept-Encoding: gzip" header to receive compressed responses
HTTP Hosts * HTTP Hosts A comma-separated list of HTTP hosts that host Elasticsearch query nodes.The HTTP Hosts should be valid URIs including protocol, domain and port for each entry.For example "https://elasticsearch1:9200 (https://elasticsearch1:9200), https://elasticsearch2:9200 (https://elasticsearch2:9200)".Note that the Host is included in requests as a header (typically including domain and port, e.g. elasticsearch:9200).
JWT Shared Secret * JWT Shared Secret JWT realm Shared Secret.
Node Selector * Node Selector ANY - Any - Skip Dedicated Masters Selects Elasticsearch nodes that can receive requests. Used to keep requests away from dedicated Elasticsearch master nodes
OAuth2 Access Token Provider * OAuth2 Access Token Provider The OAuth2 Access Token Provider used to provide JWTs for Bearer Token Authorization with Elasticsearch.
Password * Password The password to use with XPack security.
Path Prefix Path Prefix Sets the path's prefix for every request used by the http client. For example, if this is set to "/my/path", then any client request will become "/my/path/" + endpoint. In essence, every request's endpoint is prefixed by this pathPrefix. The path prefix is useful for when Elasticsearch is behind a proxy that provides a base path or a proxy that requires all paths to start with '/'; it is not intended for other purposes and it should not be supplied in other scenarios
Read Timeout * Read Timeout 60000 Controls the amount of time, in milliseconds, before a timeout occurs when waiting for a response.
Run As User Run As User The username to impersonate within Elasticsearch.
SSL Context Service SSL Context Service The SSL Context Service used to provide client certificate information for TLS/SSL connections. This service only applies if the Elasticsearch endpoint(s) have been secured with TLS/SSL.
Send Meta Header * Send Meta Header true - true - false Whether to send a "X-Elastic-Client-Meta" header that describes the runtime environment. It contains information that is similar to what could be found in User-Agent. Using a separate header allows applications to use User-Agent for their own needs, e.g. to identify application version or other environment information
Sniff Cluster Nodes * Sniff Cluster Nodes false - true - false Periodically sniff for nodes within the Elasticsearch cluster via the Elasticsearch Node Info API. If Elasticsearch security features are enabled (default to "true" for 8.x+), the Elasticsearch user must have the "monitor" or "manage" cluster privilege to use this API.Note that all HTTP Hosts (and those that may be discovered within the cluster using the Sniffer) must use the same protocol, e.g. http or https, and be contactable using the same client settings. Finally the Elasticsearch "network.publish_host" must match one of the "network.bind_host" list entries see https://www.elastic.co/guide/en/elasticsearch/reference/current/modules-network.html (https://www.elastic.co/guide/en/elasticsearch/reference/current/modules-network.html) for more information
Sniff on Failure * Sniff on Failure false - true - false Enable sniffing on failure, meaning that after each failure the Elasticsearch nodes list gets updated straight away rather than at the following ordinary sniffing round
Sniffer Failure Delay * Sniffer Failure Delay 1 min Delay between an Elasticsearch request failure and updating available Cluster nodes using the Sniffer
Sniffer Interval * Sniffer Interval 5 mins Interval between Cluster sniffer operations
Sniffer Request Timeout * Sniffer Request Timeout 1 sec Cluster sniffer timeout for node info requests
Strict Deprecation * Strict Deprecation false - true - false Whether the REST client should return any response containing at least one warning header as a failure
Suppress Null and Empty Values * Suppress Null and Empty Values always-suppress - Never Suppress - Always Suppress Specifies how the writer should handle null and empty fields (including objects and arrays)
Username * Username The username to use with XPack security.
Proxy Configuration Service proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Display Name API Name Default Value Allowable Values Description
Client Service * Client Service An ElasticSearch client service to use for running queries.
Index * Index The name of the index to read from
Schema Access Strategy * Schema Access Strategy infer - Use 'Schema Name' Property - Use 'Schema Text' Property - Infer from Result Specifies how to obtain the schema that is to be used for interpreting the data.
Schema Branch Schema Branch Specifies the name of the branch to use when looking up the schema in the Schema Registry property. If the chosen Schema Registry does not support branching, this value will be ignored.
Schema Name Schema Name $\{schema.name\} Specifies the name of the schema to lookup in the Schema Registry property
Schema Registry Schema Registry Specifies the Controller Service to use for the Schema Registry
Schema Text Schema Text $\{avro.schema\} The text of an Avro-formatted Schema
Schema Version Schema Version Specifies the version of the schema to lookup in the Schema Registry. If not specified then the latest version of the schema will be retrieved.
Type Type The type of this document (used by Elasticsearch for indexing and searching)
Display Name API Name Default Value Allowable Values Description
Client Service * Client Service An ElasticSearch client service to use for running queries.
Index * Index The name of the index to read from
Type Type The type of this document (used by Elasticsearch for indexing and searching)
Display Name API Name Default Value Allowable Values Description
BCC bcc The recipients to include in the BCC-Line of the email. Comma separated sequence of addresses following RFC822 syntax.
CC cc The recipients to include in the CC-Line of the email. Comma separated sequence of addresses following RFC822 syntax.
From * from Specifies the Email address to use as the sender. Comma separated sequence of addresses following RFC822 syntax.
Record Writer * record-sink-record-writer Specifies the Controller Service to use for writing out the records.
SMTP Auth * smtp-auth true Flag indicating whether authentication should be used
SMTP Hostname * smtp-hostname The hostname of the SMTP Server that is used to send Email Notifications
SMTP Password smtp-password Password for the SMTP account
SMTP Port * smtp-port 25 The Port used for SMTP communications
SMTP SSL * smtp-ssl false Flag indicating whether SSL should be enabled
SMTP STARTTLS * smtp-starttls false Flag indicating whether STARTTLS should be enabled. If the server does not support STARTTLS, the connection continues without the use of TLS
SMTP Username smtp-username Username for the SMTP account
SMTP X-Mailer Header * smtp-xmailer-header NiFi X-Mailer used in the header of the outgoing email
Subject * subject Message from NiFi The email subject
To to The recipients to include in the To-Line of the email. Comma separated sequence of addresses following RFC822 syntax.
Display Name API Name Default Value Allowable Values Description
Hazelcast Cluster Name * hazelcast-cluster-name nifi Name of the Hazelcast cluster.
Hazelcast Clustering Strategy * hazelcast-clustering-strategy none - None - All Nodes - Explicit Specifies with what strategy the Hazelcast cluster should be created.
Hazelcast Instances hazelcast-instances Only used with "Explicit" Clustering Strategy! List of NiFi instance host names which should be part of the Hazelcast cluster. Host names are separated by comma. The port specified in the "Hazelcast Port" property will be used as server port. The list must contain every instance that will be part of the cluster. Other instances will join the Hazelcast cluster as clients.
Hazelcast Port * hazelcast-port 5701 Port for the Hazelcast instance to use.
Property Description
Encoded Line Length Each line of encoded data will contain up to the configured number of characters, rounded down to the nearest multiple of 4.
Encoding Specifies the type of encoding used.
Line Output Mode Controls the line formatting for encoded content based on selected property values.
Mode Specifies whether the content should be encoded or decoded.
Name Description
failure Any FlowFile that cannot be encoded or decoded will be routed to failure
success Any FlowFile that is successfully encoded or decoded will be routed to success
Property Description
File Encoding Output encoding for encrypted files. Binary encoding provides optimal processing performance.
Public Key Recipient Resources One or more files or URLs containing X25519 Public Key Recipients, separated with newlines, encoded according to the age specification, starting with age1
Public Key Recipients One or more X25519 Public Key Recipients, separated with newlines, encoded according to the age specification, starting with age1
Public Key Source Source of information determines the loading strategy for X25519 Public Key Recipients
Name Description
failure Encryption Failed
success Encryption Completed
Property Description
file-encoding File Encoding for encryption
passphrase Passphrase used for encrypting data with Password-Based Encryption
public-key-search PGP Public Key Search will be used to match against the User ID or Key ID when formatted as uppercase hexadecimal string of 16 characters
public-key-service PGP Public Key Service for encrypting data with Public Key Encryption
symmetric-key-algorithm Symmetric-Key Algorithm for encryption
Name Description
failure Encryption Failed
success Encryption Succeeded
Name Description
pgp.symmetric.key.algorithm Symmetric-Key Algorithm
pgp.symmetric.key.algorithm.block.cipher Symmetric-Key Algorithm Block Cipher
pgp.symmetric.key.algorithm.key.size Symmetric-Key Algorithm Key Size
pgp.symmetric.key.algorithm.id Symmetric-Key Algorithm Identifier
pgp.file.encoding File Encoding
pgp.compression.algorithm Compression Algorithm
pgp.compression.algorithm.id Compression Algorithm Identifier
Property Description
batch-count The maximum number of FlowFiles that EnforceOrder can process at an execution.
group-id EnforceOrder is capable of multiple ordering groups. 'Group Identifier' is used to determine which group a FlowFile belongs to. This property will be evaluated with each incoming FlowFile. If evaluated result is empty, the FlowFile will be routed to failure.
inactive-timeout Indicates the duration after which state for an inactive group will be cleared from managed state. Group is determined as inactive if any new incoming FlowFile has not seen for a group for specified duration. Inactive Timeout must be longer than Wait Timeout. If a FlowFile arrives late after its group is already cleared, it will be treated as a brand new group, but will never match the order since expected preceding FlowFiles are already gone. The FlowFile will eventually timeout for waiting and routed to 'overtook'. To avoid this, group states should be kept long enough, however, shorter duration would be helpful for reusing the same group identifier again.
initial-order When the first FlowFile of a group arrives, initial target order will be computed and stored in the managed state. After that, target order will start being tracked by EnforceOrder and stored in the state management store. If Expression Language is used but evaluated result was not an integer, then the FlowFile will be routed to failure, and initial order will be left unknown until consecutive FlowFiles provide a valid initial order.
maximum-order If specified, any FlowFiles that have larger order will be routed to failure. This property is computed only once for a given group. After a maximum order is computed, it will be persisted in the state management store and used for other FlowFiles belonging to the same group. If Expression Language is used but evaluated result was not an integer, then the FlowFile will be routed to failure, and maximum order will be left unknown until consecutive FlowFiles provide a valid maximum order.
order-attribute A name of FlowFile attribute whose value will be used to enforce order of FlowFiles within a group. If a FlowFile does not have this attribute, or its value is not an integer, the FlowFile will be routed to failure.
wait-timeout Indicates the duration after which waiting FlowFiles will be routed to the 'overtook' relationship.
Scopes Description
LOCAL EnforceOrder uses following states per ordering group: '<groupId>.target' is a order number which is being waited to arrive next. When a FlowFile with a matching order arrives, or a FlowFile overtakes the FlowFile being waited for because of wait timeout, target order will be updated to (FlowFile.order + 1). '<groupId>.max is the maximum order number for a group. '<groupId>.updatedAt' is a timestamp when the order of a group was updated last time. These managed states will be removed automatically once a group is determined as inactive, see 'Inactive Timeout' for detail.
Name Description
failure A FlowFiles which does not have required attributes, or fails to compute those will be routed to this relationship
overtook A FlowFile that waited for preceding FlowFiles longer than Wait Timeout and overtook those FlowFiles, will be routed to this relationship.
skipped A FlowFile that has an order younger than current, which means arrived too late and skipped, will be routed to this relationship.
success A FlowFile with a matching order number will be routed to this relationship.
wait A FlowFile with non matching order will be routed to this relationship
Name Description
EnforceOrder.startedAt All FlowFiles going through this processor will have this attribute. This value is used to determine wait timeout.
EnforceOrder.result All FlowFiles going through this processor will have this attribute denoting which relationship it was routed to.
EnforceOrder.detail FlowFiles routed to 'failure' or 'skipped' relationship will have this attribute describing details.
EnforceOrder.expectedOrder FlowFiles routed to 'wait' or 'skipped' relationship will have this attribute denoting expected order when the FlowFile was processed.
Property Description
Attribute Name The name of the attribute to add, whose contents will be the JSON representation of the Record returned from the Lookup Service.
Attribute Prefix A prefix to apply to all attribute names that are added.
Flattening Strategy When a Record is returned from the Lookup Service, this property specifies how the Record should be flattened into the FlowFile's attributes
Lookup Service The Lookup Service to use for enrichment
Name Description
failure If unable to enrich a given FlowFile for any reason, the FlowFile will be routed to this relationship.
matched FlowFiles that are successfully enriched with the Record from the Lookup Service are routed to this relationship.
unmatched FlowFiles for which the Lookup Service did not find a match are routed to this relationship.
Property Description
CDC Schema Registry Specifies the CDC Schema Registry to use for managing the schemas of the CDC data
Record Reader Specifies the Record Reader to use for reading the incoming data
Record Writer Specifies the Record Writer to use for writing the outgoing data
Table State Service Holds the state of replicated tables
Scopes Description
CLUSTER Tracks the current journal table version for each table being processed.
Name Description
failure If any FlowFile is unable to be read, it will be routed to this Relationship.
schema update If any schema update is required in order to handle incoming Records, a FlowFile is routed to this relationship. The FlowFile will include the schema information to indicate what changes are required.
skipped ddl event This Relationship will be used for any DDL / Schema Change events that do not result in a change to the destination table's schema.
success Rows to be inserted into the Snowflake table will be routed to this Relationship.
table not in state Used when a FlowFile references a table that does not exist in the state of replicated tables, probably after it was removed from replication.
Name Description
table.schema.generation The index of the journal table for incremental processing.
table.schema.initial Marks the initial generation of a journal table.
destination.table.schema The updated schema for the destination table. This attribute is only written for DDL events.
Property Description
Destination Indicates whether the results of the JsonPath evaluation are written to the FlowFile content or a FlowFile attribute; if using attribute, must specify the Attribute Name property. If set to flowfile-content, only one JsonPath may be specified, and the property name is ignored.
Max String Length The maximum allowed length of a string value when parsing the JSON document
Null Value Representation Indicates the desired representation of JSON Path expressions resulting in a null value.
Path Not Found Behavior Indicates how to handle missing JSON path expressions when destination is set to 'flowfile-attribute'. Selecting 'warn' will generate a warning when a JSON path expression is not found. Selecting 'skip' will omit attributes for any unmatched JSON path expressions.
Return Type Indicates the desired return type of the JSON Path expressions. Selecting 'auto-detect' will set the return type to 'json' for a Destination of 'flowfile-content', and 'scalar' for a Destination of 'flowfile-attribute'.
Name Description
failure FlowFiles are routed to this relationship when the JsonPath cannot be evaluated against the content of the FlowFile; for instance, if the FlowFile is not valid JSON
matched FlowFiles are routed to this relationship when the JsonPath is successfully evaluated and the FlowFile is modified as a result
unmatched FlowFiles are routed to this relationship when the JsonPath does not match the content of the FlowFile and the Destination is set to flowfile-content
Property Description
Cosine Similarity Weight The weight to apply to the cosine similarity when calculating answer correctness (between 0.0 and 1.0)
Evaluation Results Record Path The RecordPath to write the results of the evaluation to.
F1 Score Weight The weight to apply to the F1 score when calculating answer correctness (between 0.0 and 1.0)
Generated Answer Record Path The path to the answer field in the record
Generated Answer Vector Record Path The path to the answer vector field in the record.
Ground Truth Record Path The RecordPath to the ground truth field in the record.
Ground Truth Vector Record Path The path to the ground truth vector field in the record.
LLM Provider Service The provider service for sending evaluation prompts to LLM
Question Record Path The RecordPath to the question field in the record.
Record Reader The Record Reader to use for reading the FlowFile.
Record Writer The Record Writer to use for writing the results.
Name Description
failure FlowFiles that cannot be processed are routed to this relationship
success FlowFiles that are successfully processed are routed to this relationship
Name Description
average.f1Score The average F1 score computed over all records.
average.cosineSim The average cosine similarity between the ground truth and answer embeddings.
average.answerCorrectness The average answer correctness score computed over all records.
json.parse.failures Number of JSON parse failures encountered.
Property Description
Context Identifier Record Path The RecordPath to the array of contexts IDs in the record.
Context Record Path The RecordPath to the array of contexts in the record.
Evaluation Results Record Path The RecordPath to write the results of the evaluation to.
Generated Answer Record Path The path to the answer field in the record
LLM Provider Service The provider service for sending evaluation prompts to LLM
Question Record Path The RecordPath to the question field in the record.
Record Reader The Record Reader to use for reading the FlowFile.
Record Writer The Record Writer to use for writing the results.
Name Description
failure FlowFiles that cannot be processed are routed to this relationship
success FlowFiles that are successfully processed are routed to this relationship
Name Description
average.answer.faithfulness The average faithfulness score computed over all records.
json.parse.failures Number of JSON parse failures encountered.
Property Description
Context Identifier Record Path The RecordPath to the array of contexts IDs in the record.
Context Record Path The RecordPath to the array of contexts in the record.
Evaluation Results Record Path The RecordPath to write the results of the evaluation to.
Ground Truth Record Path The RecordPath to the ground truth field in the record.
LLM Provider Service The provider service for sending evaluation prompts to LLM
Question Record Path The RecordPath to the question field in the record.
Record Reader The Record Reader to use for reading the FlowFile.
Record Writer The Record Writer to use for writing the results.
Name Description
failure FlowFiles that cannot be processed are routed to this relationship
success FlowFiles that are successfully processed are routed to this relationship
Name Description
n The average number of retrieved documents per query.
precision.at.n The average precision at N over all queries.
recall.at.n The average recall at N over all queries.
fscore.at.n The average F-Score at N over all queries.
mrr The Mean Reciprocal Rank.
retrieval.eval.failures Number of records where the eval could not be calculated.
json.parse.failures Number of JSON parse failures encountered.
Property Description
Destination Indicates whether the results of the XPath evaluation are written to the FlowFile content or a FlowFile attribute; if using attribute, must specify the Attribute Name property. If set to flowfile-content, only one XPath may be specified, and the property name is ignored.
Return Type Indicates the desired return type of the Xpath expressions. Selecting 'auto-detect' will set the return type to 'nodeset' for a Destination of 'flowfile-content', and 'string' for a Destination of 'flowfile-attribute'.
Validate DTD Allow embedded Document Type Declaration in XML. This feature should be disabled to avoid XML entity expansion vulnerabilities.
Name Description
failure FlowFiles are routed to this relationship when the XPath cannot be evaluated against the content of the FlowFile; for instance, if the FlowFile is not valid XML, or if the Return Type is 'nodeset' and the XPath evaluates to multiple nodes
matched FlowFiles are routed to this relationship when the XPath is successfully evaluated and the FlowFile is modified as a result
unmatched FlowFiles are routed to this relationship when the XPath does not match the content of the FlowFile and the Destination is set to flowfile-content
Name Description
user-defined This processor adds user-defined attributes if the <Destination> property is set to flowfile-attribute.
Property Description
Destination Indicates whether the results of the XQuery evaluation are written to the FlowFile content or a FlowFile attribute. If set to <flowfile-content>, only one XQuery may be specified and the property name is ignored. If set to <flowfile-attribute> and the XQuery returns more than one result, multiple attributes will be added to theFlowFile, each named with a '.n' one-up number appended to the specified attribute name
Output: Indent Specifies whether the processor may add additional whitespace when outputting a result tree.
Output: Method Identifies the overall method that should be used for outputting a result tree.
Output: Omit XML Declaration Specifies whether the processor should output an XML declaration when transforming a result tree.
Validate DTD Allow embedded Document Type Declaration in XML. This feature should be disabled to avoid XML entity expansion vulnerabilities.
Name Description
failure FlowFiles are routed to this relationship when the XQuery cannot be evaluated against the content of the FlowFile.
matched FlowFiles are routed to this relationship when the XQuery is successfully evaluated and the FlowFile is modified as a result
unmatched FlowFiles are routed to this relationship when the XQuery does not match the content of the FlowFile and the Destination is set to flowfile-content
Name Description
user-defined This processor adds user-defined attributes if the <Destination> property is set to flowfile-attribute .
Display Name API Name Default Value Allowable Values Description
Date Format Date Format Specifies the format to use when reading/writing Date fields. If not specified, Date fields will be assumed to be number of milliseconds since epoch (Midnight, Jan 1, 1970 GMT). If specified, the value must match the Java java.time.format.DateTimeFormatter format (for example, MM/dd/yyyy for a two-digit month, followed by a two-digit day, followed by a four-digit year, all separated by '/' characters, as in 01/01/2017).
Input File Type * Input File Type XLSX - XLS - XLSX Specifies type of Excel input file.
Password * Password The password for a password protected Excel spreadsheet
Protection Type * Protection Type UNPROTECTED - Unprotected - Password Protected Specifies whether an Excel spreadsheet is protected by a password or not.
Required Sheets Required Sheets Comma-separated list of Excel document sheet names whose rows should be extracted from the excel document. If this property is left blank then all the rows from all the sheets will be extracted from the Excel document. The list of names is case sensitive. Any sheets not specified in this value will be ignored. An exception will be thrown if a specified sheet(s) are not found.
Row Evaluation Strategy * Row Evaluation Strategy STANDARD - Standard - All Rows A strategy to select how many rows after the starting row to use for determining the schema.
Schema Access Strategy * Schema Access Strategy Use Starting Row - Use 'Schema Name' Property - Use 'Schema Text' Property - Schema Reference Reader - Use Starting Row - Infer Schema Specifies how to obtain the schema that is to be used for interpreting the data.
Schema Branch Schema Branch Specifies the name of the branch to use when looking up the schema in the Schema Registry property. If the chosen Schema Registry does not support branching, this value will be ignored.
Schema Name Schema Name $\{schema.name\} Specifies the name of the schema to lookup in the Schema Registry property
Schema Reference Reader * Schema Reference Reader Service implementation responsible for reading FlowFile attributes or content to determine the Schema Reference Identifier
Schema Registry Schema Registry Specifies the Controller Service to use for the Schema Registry
Schema Text Schema Text $\{avro.schema\} The text of an Avro-formatted Schema
Schema Version Schema Version Specifies the version of the schema to lookup in the Schema Registry. If not specified then the latest version of the schema will be retrieved.
Starting Row * Starting Row 1 The row number of the first row to start processing (One based). Use this to skip over rows of data at the top of a worksheet that are not part of the dataset. When using the 'Use Starting Row' strategy this should be the column header row.
Time Format Time Format Specifies the format to use when reading/writing Time fields. If not specified, Time fields will be assumed to be number of milliseconds since epoch (Midnight, Jan 1, 1970 GMT). If specified, the value must match the Java java.time.format.DateTimeFormatter format (for example, HH:mm:ss for a two-digit hour in 24-hour format, followed by a two-digit minute, followed by a two-digit second, all separated by ':' characters, as in 18:04:15).
Timestamp Format Timestamp Format Specifies the format to use when reading/writing Timestamp fields. If not specified, Timestamp fields will be assumed to be number of milliseconds since epoch (Midnight, Jan 1, 1970 GMT). If specified, the value must match the Java java.time.format.DateTimeFormatter format (for example, MM/dd/yyyy HH:mm:ss for a two-digit month, followed by a two-digit day, followed by a four-digit year, all separated by '/' characters; and then followed by a two-digit hour in 24-hour format, followed by a two-digit minute, followed by a two-digit second, all separated by ':' characters, as in 01/01/2017 18:04:15).
Property Description
groovyx-additional-classpath Classpath list separated by semicolon or comma. You can use masks like _*_, _*.jar_ in file name.
groovyx-failure-strategy What to do with unhandled exceptions. If you want to manage exception by code then keep the default value _rollback_. If _transfer to failure_ selected and unhandled exception occurred then all flowFiles received from incoming queues in this session will be transferred to _failure_ relationship with additional attributes set: ERROR_MESSAGE and ERROR_STACKTRACE. If _rollback_ selected and unhandled exception occurred then all flowFiles received from incoming queues will be penalized and returned. If the processor has no incoming connections then this parameter has no effect.
groovyx-script-body Body of script to execute. Only one of Script File or Script Body may be used
groovyx-script-file Path to script file to execute. Only one of Script File or Script Body may be used
Scopes Description
LOCAL Scripts can store and retrieve state using the State Management APIs. Consult the State Manager section of the Developer's Guide for more details.
CLUSTER Scripts can store and retrieve state using the State Management APIs. Consult the State Manager section of the Developer's Guide for more details.
Required Permission Explanation
execute code Provides operator the ability to execute arbitrary code assuming all permissions that NiFi has.
Name Description
failure FlowFiles that failed to be processed
success FlowFiles that were successfully processed
Property Description
Argument Delimiter Delimiter to use to separate arguments for a command [default: space]. Must be a single character.
Batch Duration If the process is expected to be long-running and produce textual output, a batch duration can be specified so that the output will be captured for this amount of time and a FlowFile will then be sent out with the results and a new FlowFile will be started, rather than waiting for the process to finish before sending out the results
Command Specifies the command to be executed; if just the name of an executable is provided, it must be in the user's environment PATH.
Command Arguments The arguments to supply to the executable delimited by white space. White space can be escaped by enclosing it in double-quotes.
Output MIME type Specifies the value to set for the "mime.type" attribute. This property is ignored if 'Batch Duration' is set.
Redirect Error Stream If true will redirect any error stream output of the process to the output stream. This is particularly helpful for processes which write extensively to the error stream or for troubleshooting.
Working Directory The directory to use as the current working directory when executing the command
Required Permission Explanation
execute code Provides operator the ability to execute arbitrary code assuming all permissions that NiFi has.
Name Description
success All created FlowFiles are routed to this relationship
Name Description
command Executed command
command.arguments Arguments of the command
mime.type Sets the MIME type of the output if the 'Output MIME Type' property is set and 'Batch Duration' is not set
Property Description
Module Directory Comma-separated list of paths to files and/or directories which contain modules required by the script.
Script Body Body of script to execute. Only one of Script File or Script Body may be used
Script Engine Language Engine for executing scripts
Script File Path to script file to execute. Only one of Script File or Script Body may be used
Scopes Description
LOCAL Scripts can store and retrieve state using the State Management APIs. Consult the State Manager section of the Developer's Guide for more details.
CLUSTER Scripts can store and retrieve state using the State Management APIs. Consult the State Manager section of the Developer's Guide for more details.
Required Permission Explanation
execute code Provides operator the ability to execute arbitrary code assuming all permissions that NiFi has.
Name Description
failure FlowFiles that failed to be processed
success FlowFiles that were successfully processed
Property Description
Content Output Strategy Specifies the strategy for writing FlowFile content when processing input FlowFiles. The strategy applies when handling queries that do not produce results.
Database Connection Pooling Service The Controller Service that is used to obtain connection to database
Default Decimal Precision When a DECIMAL/NUMBER value is written as a 'decimal' Avro logical type, a specific 'precision' denoting number of available digits is required. Generally, precision is defined by column data type definition or database engines default. However undefined precision (0) can be returned from some database engines. 'Default Decimal Precision' is used when writing those undefined precision numbers.
Default Decimal Scale When a DECIMAL/NUMBER value is written as a 'decimal' Avro logical type, a specific 'scale' denoting number of available decimal digits is required. Generally, scale is defined by column data type definition or database engines default. However when undefined precision (0) is returned, scale can also be uncertain with some database engines. 'Default Decimal Scale' is used when writing those undefined numbers. If a value has more decimals than specified scale, then the value will be rounded-up, e.g. 1.53 becomes 2 with scale 0, and 1.5 with scale 1.
Max Wait Time The maximum amount of time allowed for a running SQL select query , zero means there is no limit. Max time less than 1 second will be equal to zero.
Normalize Table and Column Names Whether to change non-Avro-compatible characters in column names to Avro-compatible characters. For example, colons and periods will be changed to underscores in order to build a valid Avro record.
SQL Query The SQL query to execute. The query can be empty, a constant value, or built from attributes using Expression Language. If this property is specified, it will be used regardless of the content of incoming flowfiles. If this property is empty, the content of the incoming flow file is expected to contain a valid SQL select query, to be issued by the processor to the database. Note that Expression Language is not evaluated for flow file contents.
Use Avro Logical Types Whether to use Avro Logical Types for DECIMAL/NUMBER, DATE, TIME and TIMESTAMP columns. If disabled, written as string. If enabled, Logical types are used and written as its underlying type, specifically, DECIMAL/NUMBER as logical 'decimal': written as bytes with additional precision and scale meta data, DATE as logical 'date-millis': written as int denoting days since Unix epoch (1970-01-01), TIME as logical 'time-millis': written as int denoting milliseconds since Unix epoch, and TIMESTAMP as logical 'timestamp-millis': written as long denoting milliseconds since Unix epoch. If a reader of written Avro records also knows these logical types, then these values can be deserialized with more context depending on reader implementation.
compression-format Compression type to use when writing Avro files. Default is None.
esql-auto-commit Enables or disables the auto commit functionality of the DB connection. Default value is 'true'. The default value can be used with most of the JDBC drivers and this functionality doesn't have any impact in most of the cases since this processor is used to read data. However, for some JDBC drivers such as PostgreSQL driver, it is required to disable the auto committing functionality to limit the number of result rows fetching at a time. When auto commit is enabled, postgreSQL driver loads whole result set to memory at once. This could lead for a large amount of memory usage when executing queries which fetch large data sets. More Details of this behaviour in PostgreSQL driver can be found in https://jdbc.postgresql.org//documentation/head/query.html (https://jdbc.postgresql.org//documentation/head/query.html).
esql-fetch-size The number of result rows to be fetched from the result set at a time. This is a hint to the database driver and may not be honored and/or exact. If the value specified is zero, then the hint is ignored.
esql-max-rows The maximum number of result rows that will be included in a single FlowFile. This will allow you to break up very large result sets into multiple FlowFiles. If the value specified is zero, then all rows are returned in a single FlowFile.
esql-output-batch-size The number of output FlowFiles to queue before committing the process session. When set to zero, the session will be committed when all result set rows have been processed and the output FlowFiles are ready for transfer to the downstream relationship. For large result sets, this can cause a large burst of FlowFiles to be transferred at the end of processor execution. If this property is set, then when the specified number of FlowFiles are ready for transfer, then the session will be committed, thus releasing the FlowFiles to the downstream relationship. NOTE: The fragment.count attribute will not be set on FlowFiles when this property is set.
sql-post-query A semicolon-delimited list of queries executed after the main SQL query is executed. Example like setting session properties after main query. It 's possible to include semicolons in the statements themselves by escaping them with a backslash (';'). Results/outputs from these queries will be suppressed if there are no errors.
sql-pre-query A semicolon-delimited list of queries executed before the main SQL query is executed. For example, set session properties before main query. It 's possible to include semicolons in the statements themselves by escaping them with a backslash (';'). Results/outputs from these queries will be suppressed if there are no errors.
Name Description
failure SQL query execution failed. Incoming FlowFile will be penalized and routed to this relationship
success Successfully created FlowFile from SQL query result set.
Name Description
executesql.row.count Contains the number of rows returned by the query. If 'Max Rows Per Flow File' is set, then this number will reflect the number of rows in the Flow File instead of the entire result set.
executesql.query.duration Combined duration of the query execution time and fetch time in milliseconds. If 'Max Rows Per Flow File' is set, then this number will reflect only the fetch time for the rows in the Flow File instead of the entire result set.
executesql.query.executiontime Duration of the query execution time in milliseconds. This number will reflect the query execution time regardless of the 'Max Rows Per Flow File' setting.
executesql.query.fetchtime Duration of the result set fetch time in milliseconds. If 'Max Rows Per Flow File' is set, then this number will reflect only the fetch time for the rows in the Flow File instead of the entire result set.
executesql.resultset.index Assuming multiple result sets are returned, the zero based index of this result set.
executesql.error.message If processing an incoming flow file causes an Exception, the Flow File is routed to failure and this attribute is set to the exception message.
fragment.identifier If 'Max Rows Per Flow File' is set then all FlowFiles from the same query result set will have the same value for the fragment.identifier attribute. This can then be used to correlate the results.
fragment.count If 'Max Rows Per Flow File' is set then this is the total number of FlowFiles produced by a single ResultSet. This can be used in conjunction with the fragment.identifier attribute in order to know how many FlowFiles belonged to the same incoming ResultSet. If Output Batch Size is set, then this attribute will not be populated.
fragment.index If 'Max Rows Per Flow File' is set then the position of this FlowFile in the list of outgoing FlowFiles that were all derived from the same result set FlowFile. This can be used in conjunction with the fragment.identifier attribute to know which FlowFiles originated from the same query result set and in what order FlowFiles were produced
input.flowfile.uuid If the processor has an incoming connection, outgoing FlowFiles will have this attribute set to the value of the input FlowFile's UUID. If there is no incoming connection, the attribute will not be added.
Property Description
Database Connection Pooling Service The Controller Service that is used to obtain connection to database
Default Decimal Precision When a DECIMAL/NUMBER value is written as a 'decimal' Avro logical type, a specific 'precision' denoting number of available digits is required. Generally, precision is defined by column data type definition or database engines default. However undefined precision (0) can be returned from some database engines. 'Default Decimal Precision' is used when writing those undefined precision numbers.
Default Decimal Scale When a DECIMAL/NUMBER value is written as a 'decimal' Avro logical type, a specific 'scale' denoting number of available decimal digits is required. Generally, scale is defined by column data type definition or database engines default. However when undefined precision (0) is returned, scale can also be uncertain with some database engines. 'Default Decimal Scale' is used when writing those undefined numbers. If a value has more decimals than specified scale, then the value will be rounded-up, e.g. 1.53 becomes 2 with scale 0, and 1.5 with scale 1.
Max Wait Time The maximum amount of time allowed for a running SQL select query , zero means there is no limit. Max time less than 1 second will be equal to zero.
SQL Query The SQL query to execute. The query can be empty, a constant value, or built from attributes using Expression Language. If this property is specified, it will be used regardless of the content of incoming flowfiles. If this property is empty, the content of the incoming flow file is expected to contain a valid SQL select query, to be issued by the processor to the database. Note that Expression Language is not evaluated for flow file contents.
Use Avro Logical Types Whether to use Avro Logical Types for DECIMAL/NUMBER, DATE, TIME and TIMESTAMP columns. If disabled, written as string. If enabled, Logical types are used and written as its underlying type, specifically, DECIMAL/NUMBER as logical 'decimal': written as bytes with additional precision and scale meta data, DATE as logical 'date-millis': written as int denoting days since Unix epoch (1970-01-01), TIME as logical 'time-millis': written as int denoting milliseconds since Unix epoch, and TIMESTAMP as logical 'timestamp-millis': written as long denoting milliseconds since Unix epoch. If a reader of written Avro records also knows these logical types, then these values can be deserialized with more context depending on reader implementation.
esql-auto-commit Enables or disables the auto commit functionality of the DB connection. Default value is 'true'. The default value can be used with most of the JDBC drivers and this functionality doesn't have any impact in most of the cases since this processor is used to read data. However, for some JDBC drivers such as PostgreSQL driver, it is required to disable the auto committing functionality to limit the number of result rows fetching at a time. When auto commit is enabled, postgreSQL driver loads whole result set to memory at once. This could lead for a large amount of memory usage when executing queries which fetch large data sets. More Details of this behaviour in PostgreSQL driver can be found in https://jdbc.postgresql.org//documentation/head/query.html (https://jdbc.postgresql.org//documentation/head/query.html).
esql-fetch-size The number of result rows to be fetched from the result set at a time. This is a hint to the database driver and may not be honored and/or exact. If the value specified is zero, then the hint is ignored.
esql-max-rows The maximum number of result rows that will be included in a single FlowFile. This will allow you to break up very large result sets into multiple FlowFiles. If the value specified is zero, then all rows are returned in a single FlowFile.
esql-output-batch-size The number of output FlowFiles to queue before committing the process session. When set to zero, the session will be committed when all result set rows have been processed and the output FlowFiles are ready for transfer to the downstream relationship. For large result sets, this can cause a large burst of FlowFiles to be transferred at the end of processor execution. If this property is set, then when the specified number of FlowFiles are ready for transfer, then the session will be committed, thus releasing the FlowFiles to the downstream relationship. NOTE: The fragment.count attribute will not be set on FlowFiles when this property is set.
esqlrecord-normalize Whether to change characters in column names. For example, colons and periods will be changed to underscores.
esqlrecord-record-writer Specifies the Controller Service to use for writing results to a FlowFile. The Record Writer may use Inherit Schema to emulate the inferred schema behavior, i.e. an explicit schema need not be defined in the writer, and will be supplied by the same logic used to infer the schema from the column types.
sql-post-query A semicolon-delimited list of queries executed after the main SQL query is executed. Example like setting session properties after main query. It 's possible to include semicolons in the statements themselves by escaping them with a backslash (';'). Results/outputs from these queries will be suppressed if there are no errors.
sql-pre-query A semicolon-delimited list of queries executed before the main SQL query is executed. For example, set session properties before main query. It 's possible to include semicolons in the statements themselves by escaping them with a backslash (';'). Results/outputs from these queries will be suppressed if there are no errors.
Name Description
failure SQL query execution failed. Incoming FlowFile will be penalized and routed to this relationship
success Successfully created FlowFile from SQL query result set.
Name Description
executesql.row.count Contains the number of rows returned in the select query
executesql.query.duration Combined duration of the query execution time and fetch time in milliseconds
executesql.query.executiontime Duration of the query execution time in milliseconds
executesql.query.fetchtime Duration of the result set fetch time in milliseconds
executesql.resultset.index Assuming multiple result sets are returned, the zero based index of this result set.
executesql.error.message If processing an incoming flow file causes an Exception, the Flow File is routed to failure and this attribute is set to the exception message.
fragment.identifier If 'Max Rows Per Flow File' is set then all FlowFiles from the same query result set will have the same value for the fragment.identifier attribute. This can then be used to correlate the results.
fragment.count If 'Max Rows Per Flow File' is set then this is the total number of FlowFiles produced by a single ResultSet. This can be used in conjunction with the fragment.identifier attribute in order to know how many FlowFiles belonged to the same incoming ResultSet. If Output Batch Size is set, then this attribute will not be populated.
fragment.index If 'Max Rows Per Flow File' is set then the position of this FlowFile in the list of outgoing FlowFiles that were all derived from the same result set FlowFile. This can be used in conjunction with the fragment.identifier attribute to know which FlowFiles originated from the same query result set and in what order FlowFiles were produced
input.flowfile.uuid If the processor has an incoming connection, outgoing FlowFiles will have this attribute set to the value of the input FlowFile's UUID. If there is no incoming connection, the attribute will not be added.
mime.type Sets the mime.type attribute to the MIME Type specified by the Record Writer.
record.count The number of records output by the Record Writer.
Property Description
Connection Pooling Service The Connection Pooling Service that is used to obtain a connection to the database
Max Batch Size The maximum number of FlowFiles to process in a single batch
Max Content Reference Size If the SQL property references $\{flowfile_content\}, this property specifies the maximum size of the FlowFile that is allowed to be read into memory. If the FlowFile is larger than this value, the FlowFile will be routed to failure. If the SQL property does not reference $\{flowfile_content\}, this value has no effect.
SQL The SQL statement to execute. The SQL may make use of Expression Language to reference attributes. In this case, the Processor will rewrite the query using parameters in order to avoid SQL Injection attacks. When referencing Expression Language, the entire value must be a single Expression. For example, _INSERT INTO TABLE X (name) VALUES ( '$\{name\}')_ is valid, but _INSERT INTO TABLE X (name) VALUES ( 'Mr. $\{name\}')_ is not because Expression Language is used within a String value. The SQL may also reference _$\{flowfile_content\}_ in order to reference the content of the FlowFile as UTF-8 encoded text.
Name Description
failure The SQL statement could not be executed
success The SQL statement was successfully executed
Property Description
Argument Delimiter Delimiter to use to separate arguments for a command [default: ;]. Must be a single character
Command Arguments The arguments to supply to the executable delimited by the ';' character.
Command Path Specifies the command to be executed; if just the name of an executable is provided, it must be in the user's environment PATH.
Ignore STDIN If true, the contents of the incoming flowfile will not be passed to the executing command
Max Attribute Length If routing the output of the stream command to an attribute, the number of characters put to the attribute value will be at most this amount. This is important because attributes are held in memory and large attributes will quickly cause out of memory issues. If the output goes longer than this value, it will truncated to fit. Consider making this smaller if able.
Output Destination Attribute If set, the output of the stream command will be put into an attribute of the original FlowFile instead of a separate FlowFile. There will no longer be a relationship for 'output stream' or 'nonzero status'. The value of this property will be the key for the output attribute.
Output MIME Type Specifies the value to set for the "mime.type" attribute. This property is ignored if 'Output Destination Attribute' is set.
Working Directory The directory to use as the current working directory when executing the command
argumentsStrategy Strategy for configuring arguments to be supplied to the command.
Required Permission Explanation
execute code Provides operator the ability to execute arbitrary code assuming all permissions that NiFi has.
Name Description
nonzero status The destination path for the flow file created from the command's output, if the returned status code is non-zero. All flow files routed to this relationship will be penalized.
original The original FlowFile will be routed. It will have new attributes detailing the result of the script execution.
output stream The destination path for the flow file created from the command's output, if the returned status code is zero.
Name Description
execution.command The name of the command executed
execution.command.args The semi-colon delimited list of arguments. Sensitive properties will be masked
execution.status The exit status code returned from executing the command
execution.error Any error messages returned from executing the command
mime.type Sets the MIME type of the output if the 'Output MIME Type' property is set and 'Output Destination Attribute' is not set
Status Description
`UNMOUNTED` Shared by Salesforce Data Cloud. No catalog-linked database has been created yet.
`MOUNTED` A catalog-linked database exists for this share.
Display Name API Name Default Value Allowable Values Description
Hazelcast Cluster Name * hazelcast-cluster-name nifi Name of the Hazelcast cluster.
Hazelcast Connection Timeout * hazelcast-connection-timeout 20 secs The maximum amount of time the client tries to connect or reconnect before giving up.
Hazelcast Initial Backoff * hazelcast-retry-backoff-initial 1 secs The amount of time the client waits before it tries to reestablish connection for the first time.
Hazelcast Maximum Backoff * hazelcast-retry-backoff-maximum 5 secs The maximum amount of time the client waits before it tries to reestablish connection.
Hazelcast Backoff Multiplier * hazelcast-retry-backoff-multiplier 1.5 A multiplier by which the wait time is increased before each attempt to reestablish connection.
Hazelcast Server Address * hazelcast-server-address Addresses of one or more the Hazelcast instances, using \{host:port\} format, separated by comma.
Property Description
Count Items If true the number of items in the datafile will be counted and stored in a FlowFile attribute 'item.count'. The counting is done by reading blocks and getting the number of items for each block, thus avoiding de-serializing. The items being counted will be the top-level items in the datafile. For example, with a schema of type record the items will be the records, and for a schema of type Array the items will be the arrays (not the number of entries in each array).
Fingerprint Algorithm The algorithm used to generate the schema fingerprint. Available choices are based on the Avro recommended practices for fingerprint generation.
Metadata Keys A comma-separated list of keys indicating key/value pairs to extract from the Avro file header. The key 'avro.schema' can be used to extract the full schema in JSON format, and 'avro.codec' can be used to extract the codec name if one exists.
Name Description
failure A FlowFile is routed to this relationship if it cannot be parsed as Avro or metadata cannot be extracted for any reason
success A FlowFile is routed to this relationship after metadata has been extracted.
Name Description
schema.type The type of the schema (i.e. record, enum, etc.).
schema.name Contains the name when the type is a record, enum or fixed, otherwise contains the name of the primitive type.
schema.fingerprint The result of the Fingerprint Algorithm as a Hex string.
item.count The total number of items in the datafile, only written if Count Items is set to true.
Name Description
attachments Each individual attachment will be routed to the attachments relationship
failure FlowFiles that could not be parsed
original The original file
Name Description
filename The filename of the attachment
email.attachment.parent.filename The filename of the parent FlowFile
email.attachment.parent.uuid The UUID of the original FlowFile.
mime.type The mime type of the attachment.
Property Description
Additional Header List COLON separated list of additional headers to be extracted from the flowfile content. NOTE the header key is case insensitive and will be matched as lower-case. Values will respect email contents.
Email Address Parsing If "strict", strict address format parsing rules are applied to mailbox and mailbox list fields, such as "to" and "from" headers, and FlowFiles with poorly formed addresses will be routed to the failure relationship, similar to messages that fail RFC compliant format validation. If "non-strict", the processor will extract the contents of mailbox list headers as comma-separated values without attempting to parse each value as well-formed Internet mailbox addresses. This is optional and defaults to Strict Address Parsing
Name Description
failure Flowfiles that could not be parsed as a RFC-2822 compliant message
success Extraction was successful
Name Description
email.headers.bcc.* Each individual BCC recipient (if available)
email.headers.cc.* Each individual CC recipient (if available)
email.headers.from.* Each individual mailbox contained in the From of the Email (array as per RFC-2822)
email.headers.message-id The value of the Message-ID header (if available)
email.headers.received_date The Received-Date of the message (if available)
email.headers.sent_date Date the message was sent
email.headers.subject Subject of the message (if available)
email.headers.to.* Each individual TO recipient (if available)
email.attachment_count Number of attachments of the message
Property Description
Character Set The Character Set in which the file is encoded
Destination Control if Grok output value is written as a new flowfile attributes, in this case each of the Grok identifier that is matched in the flowfile will be added as an attribute, prefixed with "grok." or written in the flowfile content. Writing to flowfile content will overwrite any existing flowfile content.
Grok Expression Grok expression. If other Grok expressions are referenced in this expression, they must be provided in the Grok Pattern File if set or exist in the default Grok patterns
Grok Pattern file Custom Grok pattern definitions. These definitions will be loaded after the default Grok patterns. The Grok Parser will use the default Grok patterns when this property is not configured.
Keep Empty Captures If true, then empty capture values will be included in the returned capture map.
Maximum Buffer Size Specifies the maximum amount of data to buffer (per file) in order to apply the Grok expressions. Files larger than the specified maximum will not be fully evaluated.
Named captures only Only store named captures from grok
Required Permission Explanation
reference remote resources Patterns can reference resources over HTTP
Name Description
matched FlowFiles are routed to this relationship when the Grok Expression is successfully evaluated and the FlowFile is modified as a result
unmatched FlowFiles are routed to this relationship when no provided Grok Expression matches the content of the FlowFile
Name Description
grok.XXX When operating in flowfile-attribute mode, each of the Grok identifier that is matched in the flowfile will be added as an attribute, prefixed with "grok." For example,if the grok identifier "timestamp" is matched, then the value will be added to an attribute named "grok.timestamp"
Property Description
cache-size Specifies the number of schemas to cache. This value should reflect the expected number of different schemas that may be in the incoming FlowFiles. This ensures more efficient retrieval of the schemas and thus the processor performance.
record-reader Specifies the Controller Service to use for reading incoming data
Name Description
failure If a FlowFile's record schema cannot be extracted from the configured input format, the FlowFile will be routed to this relationship
success FlowFiles whose record schemas are successfully extracted will be routed to this relationship
Name Description
record.error.message This attribute provides on failure the error message encountered by the Reader.
avro.schema This attribute provides the schema extracted from the input FlowFile using the provided RecordReader.
Property Description
End Column Index Specifies index of the column in schema to which columns should be taken.
Record Reader Specifies the Controller Service to use for reading incoming data
Start Column Index Specifies index of the column (numbered from 1) in schema from which columns should be taken.
Name Description
failure If a FlowFile's record schema cannot be extracted from the configured input format, the FlowFile will be routed to this relationship
success FlowFiles whose record schemas are successfully extracted will be routed to this relationship
Name Description
record.error.message This attribute provides on failure the error message encountered by the Reader.
schema.columns This attribute provides columns extracted from the input FlowFile using the provided RecordReader.
Property Description
Box Client Service Controller Service used to obtain a Box API connection.
Extraction Method The method to use for extracting metadata. TEMPLATE uses a Box metadata template for extraction. FIELDS uses a JSON schema of fields (read from FlowFile content) for extraction.
File ID The ID of the file from which to extract metadata.
Record Reader The Record Reader to use for parsing the incoming data. Required when Extraction Method is FIELDS.
Template Key The key of the metadata template to use for extraction. Required when Extraction Method is TEMPLATE.
Name Description
failure A FlowFile is routed to this relationship if an error occurs during metadata extraction.
file not found FlowFiles for which the specified Box file was not found will be routed to this relationship.
success A FlowFile is routed to this relationship after metadata has been successfully extracted.
template not found FlowFiles for which the specified metadata template was not found will be routed to this relationship.
Name Description
box.id The ID of the file from which metadata was extracted
box.ai.template.key The template key used for extraction (when using TEMPLATE extraction method)
box.ai.extraction.method The extraction method used (TEMPLATE or FIELDS)
box.ai.completion.reason The completion reason from the AI extraction
mime.type Set to 'application/json' for the JSON content
error.code The error code returned by Box
error.message The error message returned by Box
Property Description
Character Set The Character Set in which the file is encoded
Enable Canonical Equivalence Indicates that two characters match only when their full canonical decompositions match.
Enable Case-insensitive Matching Indicates that two characters match even if they are in a different case. Can also be specified via the embedded flag (?i).
Enable DOTALL Mode Indicates that the expression '.' should match any character, including a line terminator. Can also be specified via the embedded flag (?s).
Enable Literal Parsing of the Pattern Indicates that Metacharacters and escape characters should be given no special meaning.
Enable Multiline Mode Indicates that '^' and '$' should match just after and just before a line terminator or end of sequence, instead of only the beginning or end of the entire input. Can also be specified via the embedded flag (?m).
Enable Unicode Predefined Character Classes Specifies conformance with the Unicode Technical Standard #18: Unicode Regular Expression Annex C: Compatibility Properties. Can also be specified via the embedded flag (?U).
Enable Unicode-aware Case Folding When used with 'Enable Case-insensitive Matching', matches in a manner consistent with the Unicode Standard. Can also be specified via the embedded flag (?u).
Enable Unix Lines Mode Indicates that only the 'line terminator is recognized in the behavior of'. ','^ ', and'$'. Can also be specified via the embedded flag (?d).
Enable named group support If set to true, when named groups are present in the regular expression, the name of the group will be used in the attribute name as opposed to the group index. All capturing groups must be named, if the number of groups (not including capture group 0) does not equal the number of named groups validation will fail.
Enable repeating capture group If set to true, every string matching the capture groups will be extracted. Otherwise, if the Regular Expression matches more than once, only the first match will be extracted.
Include Capture Group 0 Indicates that Capture Group 0 should be included as an attribute. Capture Group 0 represents the entirety of the regular expression match, is typically not used, and could have considerable length.
Maximum Buffer Size Specifies the maximum amount of data to buffer (per FlowFile) in order to apply the regular expressions. FlowFiles larger than the specified maximum will not be fully evaluated.
Maximum Capture Group Length Specifies the maximum number of characters a given capture group value can have. Any characters beyond the max will be truncated.
Permit Whitespace and Comments in Pattern In this mode, whitespace is ignored, and embedded comments starting with # are ignored until the end of a line. Can also be specified via the embedded flag (?x).
Name Description
matched FlowFiles are routed to this relationship when the Regular Expression is successfully evaluated and the FlowFile is modified as a result
unmatched FlowFiles are routed to this relationship when no provided Regular Expression matches the content of the FlowFile
Property Description
Blob Name The full name of the blob
Client-Side Encryption Key ID Specifies the ID of the key to use for client-side encryption.
Client-Side Encryption Key Type Specifies the key type to use for client-side encryption.
Client-Side Encryption Local Key When using local client-side encryption, this is the raw key, encoded in hexadecimal
Container Name Name of the Azure storage container. In case of PutAzureBlobStorage processor, container can be created if it does not exist.
Range Length The number of bytes to download from the blob, starting from the Range Start. An empty value or a value that extends beyond the end of the blob will read to the end of the blob.
Range Start The byte position at which to start reading from the blob. An empty value or a value of zero will start reading at the beginning of the blob.
Storage Credentials Controller Service used to obtain Azure Blob Storage Credentials.
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests. In case of SOCKS, it is not guaranteed that the selected SOCKS Version will be used by the processor.
Name Description
failure Unsuccessful operations will be transferred to the failure relationship.
success All successfully processed FlowFiles are routed to this relationship
Name Description
azure.container The name of the Azure Blob Storage container
azure.blobname The name of the blob on Azure Blob Storage
azure.primaryUri Primary location of the blob
azure.etag ETag of the blob
azure.blobtype Type of the blob (either BlockBlob, PageBlob or AppendBlob)
mime.type MIME Type of the content
lang Language code for the content
azure.timestamp Timestamp of the blob
azure.length Length of the blob
Property Description
ADLS Credentials Controller Service used to obtain Azure Credentials.
Directory Name Name of the Azure Storage Directory. The Directory Name cannot contain a leading '/'. The root directory can be designated by the empty string value. In case of the PutAzureDataLakeStorage processor, the directory will be created if not already existing.
File Name The filename
Filesystem Name Name of the Azure Storage File System (also called Container). It is assumed to be already existing.
Number of Retries The number of automatic retries to perform if the download fails.
Range Length The number of bytes to download from the object, starting from the Range Start. An empty value or a value that extends beyond the end of the object will read to the end of the object.
Range Start The byte position at which to start reading from the object. An empty value or a value of zero will start reading at the beginning of the object.
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests. In case of SOCKS, it is not guaranteed that the selected SOCKS Version will be used by the processor.
Name Description
failure Files that could not be written to Azure storage for some reason are transferred to this relationship
success Files that have been successfully written to Azure storage are transferred to this relationship
Name Description
azure.datalake.storage.statusCode The HTTP error code (if available) from the failed operation
azure.datalake.storage.errorCode The Azure Data Lake Storage moniker of the failed operation
azure.datalake.storage.errorMessage The Azure Data Lake Storage error message from the failed operation
Property Description
Box Client Service Controller Service used to obtain a Box API connection.
File ID The ID of the File to fetch
Name Description
failure A FlowFile will be routed here for each File for which fetch was attempted but failed.
success A FlowFile will be routed here for each successfully fetched File.
Name Description
box.id The id of the file
filename The name of the file
path The folder path where the file is located
box.size The size of the file
box.timestamp The last modified time of the file
error.code The error code returned by Box
error.message The error message returned by Box
Property Description
Box Client Service Controller Service used to obtain a Box API connection.
File ID The ID of the File to fetch metadata for
Name Description
failure A FlowFile will be routed here if fetching the file metadata fails.
not.found FlowFiles for which the specified Box file was not found.
success A FlowFile will be routed here after successfully fetching the file metadata.
Name Description
box.id The id of the file
filename The name of the file
path The folder path where the file is located
box.path.folder.ids A comma separated list of file path_collection IDs
box.size The size of the file
box.timestamp The last modified time of the file
box.created.at The creation date of the file
box.owner The name of the file owner
box.owner.id The ID of the file owner
box.owner.login The login of the file owner
box.description The description of the file
box.etag The etag of the file
box.sha1 The SHA-1 hash of the file
box.content.created.at The date the content was created
box.content.modified.at The date the content was modified
box.item.status The status of the file (active, trashed, etc.)
box.sequence_id The sequence ID of the file
box.parent.folder.id The ID of the parent folder
box.trashed.at The date the file was trashed, if applicable
box.purged.at The date the file was purged, if applicable
box.shared.link The shared link of the file, if any
error.code The error code returned by Box
error.message The error message returned by Box
Property Description
Box Client Service Controller Service used to obtain a Box API connection.
File ID The ID of the file for which to fetch metadata.
Template Key The metadata template key to retrieve.
Template Scope The metadata template scope (e.g., 'enterprise', 'global').
Name Description
failure A FlowFile will be routed here if there is an error fetching metadata instance from the file.
file not found FlowFiles for which the specified Box file was not found will be routed to this relationship.
success A FlowFile containing the metadata instance will be routed to this relationship upon successful processing.
template not found FlowFiles for which the specified metadata template was not found will be routed to this relationship.
Name Description
box.id The ID of the file from which metadata was fetched
box.metadata.template.key The metadata template key
box.metadata.template.scope The metadata template scope
mime.type The MIME Type of the FlowFile content
error.code The error code returned by Box
error.message The error message returned by Box
Property Description
Box Client Service Controller Service used to obtain a Box API connection.
File ID The ID of the Box file to retrieve.
Representation Type The type of representation to fetch. Common values include 'pdf', 'text', 'jpg', 'png', etc.
Name Description
failure FlowFiles that encounter errors during processing will be routed to this relationship.
file.not.found FlowFiles for which the specified Box file was not found.
representation.not.found FlowFiles for which the specified Box file's requested representation was not found.
success FlowFiles that are successfully processed will be routed to this relationship.
Name Description
box.id The ID of the Box file.
box.file.name The name of the Box file.
box.file.size The size of the Box file in bytes.
box.file.created.time The timestamp when the file was created.
box.file.modified.time The timestamp when the file was last modified.
box.file.mime.type The MIME type of the file.
box.file.representation.type The representation type that was fetched.
box.error.message The error message returned by Box if the operation fails.
box.error.code The error code returned by Box if the operation fails.
Property Description
Cache Entry Identifier A comma-delimited list of FlowFile attributes, or the results of Attribute Expression Language statements, which will be evaluated against a FlowFile in order to determine the value(s) used to identify duplicates; it is these values that are cached. NOTE: Only a single Cache Entry Identifier is allowed unless Put Cache Value In Attribute is specified. Multiple cache lookups are only supported when the destination is a set of attributes (see the documentation for 'Put Cache Value In Attribute' for more details including naming convention.
Character Set The Character Set in which the cached value is encoded. This will only be used when routing to an attribute.
Distributed Cache Service The Controller Service that is used to get the cached values.
Max Length To Put In Attribute If routing the cache value to an attribute of the FlowFile (by setting the "Put Cache Value in attribute" property), the number of characters put to the attribute value will be at most this amount. This is important because attributes are held in memory and large attributes will quickly cause out of memory issues. If the output goes longer than this value, it will be truncated to fit. Consider making this smaller if able.
Put Cache Value In Attribute If set, the cache value received will be put into an attribute of the FlowFile instead of a the content of theFlowFile. The attribute key to put to is determined by evaluating value of this property. If multiple Cache Entry Identifiers are selected, multiple attributes will be written, using the evaluated value of this property, appended by a period (.) and the name of the cache entry identifier.
Name Description
failure If unable to communicate with the cache or if the cache entry is evaluated to be blank, the FlowFile will be penalized and routed to this relationship
not-found If a FlowFile's Cache Entry Identifier was not found in the cache, it will be routed to this relationship
success If the cache was successfully communicated with it will be routed to this relationship
Name Description
user-defined If the 'Put Cache Value In Attribute' property is set then whatever it is set to will become the attribute key and the value would be whatever the response was from the Distributed Map Cache. If multiple cache entry identifiers are selected, multiple attributes will be written, using the evaluated value of this property, appended by a period (.) and the name of the cache entry identifier. For example, if the Cache Entry Identifier property is set to 'id,name', and the user-defined property is named 'fetched', then two attributes will be written, fetched.id and fetched.name, containing their respective values.
Property Description
Dropbox Credential Service Controller Service used to obtain Dropbox credentials (App Key, App Secret, Access Token, Refresh Token). See controller service's Additional Details for more information.
File The Dropbox identifier or path of the Dropbox file to fetch. The 'File'should match the following regular expression pattern: /.*|id:.* . When ListDropbox is used for input, either '$\{dropbox.id\}' (identifying files by Dropbox id) or '$\{path\}/$\{filename\}' (identifying files by path) can be used as 'File' value.
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
failure A FlowFile will be routed here for each File for which fetch was attempted but failed.
success A FlowFile will be routed here for each successfully fetched File.
Name Description
error.message The error message returned by Dropbox
dropbox.id The Dropbox identifier of the file
path The folder path where the file is located
filename The name of the file
dropbox.size The size of the file
dropbox.timestamp The server modified time of the file
dropbox.revision Revision of the file
Property Description
Completion Strategy Specifies what to do with the original file on the file system once it has been pulled into NiFi
File to Fetch The fully-qualified filename of the file to fetch from the file system
Log level when file not found Log level to use in case the file does not exist when the processor is triggered
Log level when permission denied Log level to use if the current application user does not have sufficient permissions to read the file
Move Conflict Strategy If Completion Strategy is set to Move File and a file already exists in the destination directory with the same name, this property specifies how that naming conflict should be resolved
Move Destination Directory The directory to the move the original file to once it has been fetched from the file system. This property is ignored unless the Completion Strategy is set to "Move File". If the directory does not exist, it will be created.
Required Permission Explanation
read filesystem Provides operator the ability to read from any file that NiFi has access to.
write filesystem Provides operator the ability to delete any file that NiFi has access to.
Name Description
failure Any FlowFile that could not be fetched from the file system for any reason other than insufficient permissions or the file not existing will be transferred to this Relationship.
not.found Any FlowFile that could not be fetched from the file system because the file could not be found will be transferred to this Relationship.
permission.denied Any FlowFile that could not be fetched from the file system due to the user running NiFi not having sufficient permissions will be transferred to this Relationship.
success Any FlowFile that is successfully fetched from the file system will be transferred to this Relationship.
Property Description
Completion Strategy Specifies what to do with the original file on the server once it has been pulled into NiFi. If the Completion Strategy fails, a warning will be logged but the data will still be transferred.
Connection Mode The FTP Connection Mode
Connection Timeout Amount of time to wait before timing out while creating a connection
Create Directory Used when 'Completion Strategy' is 'Move File'. Specifies whether or not the remote directory should be created if it does not exist.
Data Timeout When transferring a file between the local and remote system, this value specifies how long is allowed to elapse without any data being transferred between systems
Hostname The fully-qualified hostname or IP address of the host to fetch the data from
Internal Buffer Size Set the internal buffer size for buffered data streams
Log Level When File Not Found Log level to use in case the file does not exist when the processor is triggered
Move Destination Directory The directory on the remote server to move the original file to once it has been ingested into NiFi. This property is ignored unless the Completion Strategy is set to 'Move File'. The specified directory must already exist on the remote system if 'Create Directory' is disabled, or the rename will fail.
Password Password for the user account
Port The port to connect to on the remote host to fetch the data from
Remote File The fully qualified filename on the remote system
Transfer Mode The FTP Transfer Mode
Use Compression Indicates whether or not ZLIB compression should be used when transferring files
Username Username
ftp-use-utf8 Tells the client to use UTF-8 encoding when processing files and filenames. If set to true, the server must also support UTF-8 encoding.
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
comms.failure Any FlowFile that could not be fetched from the remote server due to a communications failure will be transferred to this Relationship.
not.found Any FlowFile for which we receive a 'Not Found' message from the remote server will be transferred to this Relationship.
permission.denied Any FlowFile that could not be fetched from the remote server due to insufficient permissions will be transferred to this Relationship.
success All FlowFiles that are received are routed to success
Name Description
ftp.remote.host The hostname or IP address from which the file was pulled
ftp.remote.port The port that was used to communicate with the remote FTP server
ftp.remote.filename The name of the remote file that was pulled
filename The filename is updated to point to the filename fo the remote file
path If the Remote File contains a directory name, that directory name will be added to the FlowFile using the 'path' attribute
fetch.failure.reason The name of the failure relationship applied when routing to any failure relationship
Property Description
GCP Credentials Provider Service The Controller Service used to obtain Google Cloud Platform credentials.
gcp-project-id Google Cloud Project ID
gcp-retry-count How many retry attempts should be made before routing to the failure relationship.
gcs-bucket Bucket of the object.
gcs-generation The generation of the Object to download. If not set, the latest generation will be downloaded.
gcs-key Name of the object.
gcs-object-range-length The number of bytes to download from the object, starting from the Range Start. An empty value or a value that extends beyond the end of the object will read to the end of the object.
gcs-object-range-start The byte position at which to start reading from the object. An empty value or a value of zero will start reading at the beginning of the object.
gcs-server-side-encryption-key An AES256 Key (encoded in base64) which the object has been encrypted in.
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
storage-api-url Overrides the default storage URL. Configuring an alternative Storage API URL also overrides the HTTP Host header on requests as described in the Google documentation for Private Service Connections.
Name Description
failure FlowFiles are routed to this relationship if the Google Cloud Storage operation fails.
success FlowFiles are routed to this relationship after a successful Google Cloud Storage operation.
Name Description
filename The name of the file, parsed if possible from the Content-Disposition response header
gcs.bucket Bucket of the object.
gcs.key Name of the object.
gcs.size Size of the object.
gcs.cache.control Data cache control of the object.
gcs.component.count The number of components which make up the object.
gcs.content.disposition The data content disposition of the object.
gcs.content.encoding The content encoding of the object.
gcs.content.language The content language of the object.
mime.type The MIME/Content-Type of the object
gcs.crc32c The CRC32C checksum of object's data, encoded in base64 in big-endian order.
gcs.create.time The creation time of the object (milliseconds)
gcs.update.time The last modification time of the object (milliseconds)
gcs.encryption.algorithm The algorithm used to encrypt the object.
gcs.encryption.sha256 The SHA256 hash of the key used to encrypt the object
gcs.etag The HTTP 1.1 Entity tag for the object.
gcs.generated.id The service-generated for the object
gcs.generation The data generation of the object.
gcs.md5 The MD5 hash of the object's data encoded in base64.
gcs.media.link The media download link to the object.
gcs.metageneration The metageneration of the object.
gcs.owner The owner (uploader) of the object.
gcs.owner.type The ACL entity type of the uploader of the object.
gcs.acl.owner A comma-delimited list of ACL entities that have owner access to the object. Entities will be either email addresses, domains, or project IDs.
gcs.acl.writer A comma-delimited list of ACL entities that have write access to the object. Entities will be either email addresses, domains, or project IDs.
gcs.acl.reader A comma-delimited list of ACL entities that have read access to the object. Entities will be either email addresses, domains, or project IDs.
gcs.uri The URI of the object as a string.
Property Description
Google Doc Export Type Google Documents cannot be downloaded directly from Google Drive but instead must be exported to a specified MIME Type. In the event that the incoming FlowFile's MIME Type indicates that the file is a Google Document, this property specifies the MIME Type to export the document to.
Google Drawing Export Type Google Drawings cannot be downloaded directly from Google Drive but instead must be exported to a specified MIME Type. In the event that the incoming FlowFile's MIME Type indicates that the file is a Google Drawing, this property specifies the MIME Type to export the drawing to.
Google Presentation Export Type Google Presentations cannot be downloaded directly from Google Drive but instead must be exported to a specified MIME Type. In the event that the incoming FlowFile's MIME Type indicates that the file is a Google Presentation, this property specifies the MIME Type to export the presentation to.
Google Spreadsheet Export Type Google Spreadsheets cannot be downloaded directly from Google Drive but instead must be exported to a specified MIME Type. In the event that the incoming FlowFile's MIME Type indicates that the file is a Google Spreadsheet, this property specifies the MIME Type to export the spreadsheet to.
connect-timeout Maximum wait time for connection to Google Drive service.
drive-file-id The Drive ID of the File to fetch. Please see Additional Details for information on how to obtain the Drive ID.
gcp-credentials-provider-service The Controller Service used to obtain Google Cloud Platform credentials.
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
read-timeout Maximum wait time for response from Google Drive service.
Name Description
failure A FlowFile will be routed here for each File for which fetch was attempted but failed.
success A FlowFile will be routed here for each successfully fetched File.
Name Description
drive.id The id of the file
filename The name of the file
mime.type The MIME type of the file
drive.size The size of the file. Set to 0 when the file size is not available (e.g. externally stored files).
drive.size.available Indicates if the file size is known / available
drive.timestamp The last modified time or created time (whichever is greater) of the file. The reason for this is that the original modified date of a file is preserved when uploaded to Google Drive. 'Created time' takes the time when the upload occurs. However uploaded files can still be modified later.
drive.created.time The file's creation time
drive.modified.time The file's last modification time
drive.owner The owner of the file
drive.last.modifying.user The last modifying user of the file
drive.web.view.link Web view link to the file
drive.web.content.link Web content link to the file
drive.parent.folder.id The id of the file's parent folder
drive.parent.folder.name The name of the file's parent folder
drive.shared.drive.id The id of the shared drive (if the file is located on a shared drive)
drive.shared.drive.name The name of the shared drive (if the file is located on a shared drive)
error.code The error code returned by Google Drive
error.message The error message returned by Google Drive
Property Description
File ID Google Drive file ID.
GCP Credentials Service Controller Service used to obtain Google Cloud Platform credentials.
Record Writer Specifies the Record Writer to use when writing the comments.
Name Description
failure FlowFiles are routed here if the processor fails to retrieve comments.
not.found A FlowFile is routed here if the file was not found.
retry FlowFiles are routed here if a connection or rate-limit issue occurs.
success All FlowFiles that are successfully processed are routed here.
Name Description
record.count Number of comment records returned (not including replies).
google.drive.file.id The file ID from which comments were fetched.
Property Description
File ID An id of an file to retrieve the metadata for
GCP Credentials Service The Controller Service used to obtain Google Cloud Platform credentials.
Name Description
failure A FlowFile is routed here if the processor fails to retrieve Google Drive file metadata.
not.found A FlowFile is routed here if the file metadata was not found
retry A FlowFile is routed here if the processor should retry the request (e.g., after rate limiting).
success A FlowFile is routed here after successfully retrieving Google Drive file metadata.
Name Description
google.drive.drive.id The ID of the Shared Google Drive.
google.drive.file.name The name of the file.
google.drive.created.time The timestamp when the file was created, in milliseconds since the Unix epoch.
google.drive.modified.time The timestamp when the file was modified, in milliseconds since the Unix epoch.
google.drive.size The size of the file in bytes.
google.drive.md5 The MD5 checksum of the file.
google.drive.mime.type The MIME type of the file.
google.drive.version The version of the file. This changes based on user and system based updates to the file.
google.drive.webUrl A link for opening the file in a relevant Google editor or viewer in a browser.
google.drive.lastModifiedBy.displayName A display name of the user that modified the file.
google.drive.lastModifiedBy.email An email of the user that modified the file.
google.drive.permissions.<role>.users A comma-separated list of email addresses for users with the specified role. Valid roles are 'owner', 'organizer', 'fileOrganizer', 'writer', 'commenter', 'reader'. For example, if the owner is [john.doe@gmail.com](mailto:john.doe@gmail.com) and users [jane.doe@gmail.com](mailto:jane.doe@gmail.com) and [jake.doe@gmail.com](mailto:jake.doe@gmail.com) are readers, there would be an attribute named _google.drive.permissions.owner.users_ with the value _john.doe@gmail.com_, and an attribute named _google.drive.permissions.reader.users_ with the value _jane.doe@gmail.com, jake.doe@gmail.com_
google.drive.permissions.<role>.groups A comma-separated list of email addresses for groups with the specified role. Valid roles are 'owner', 'organizer', 'fileOrganizer', 'writer', 'commenter', 'reader'. For example, if the owner is _employees@openflow-all-dev.iam.gserviceaccount.com_ and the group _contractors@openflow-all-dev.iam.gserviceaccount.com_ is a reader, there would be an attribute named _google.drive.permissions.owner.groups_ with the value _employees@openflow-all-dev.iam.gserviceaccount.com_, and an attribute named _google.drive.permissions.reader.groups_ with the value _contractors@openflow-all-dev.iam.gserviceaccount.com_
google.drive.permissions.<role>.domains A comma-separated list of domain names for which all users have the given role. Valid roles are 'owner', 'organizer', 'fileOrganizer', 'writer', 'commenter', 'reader'. For example, if all users in the domain _snowflake.com_ have the role of reader, there would be an attribute named _google.drive.permissions.reader.domains_ with the value _snowflake.com_
google.drive.permissions.<role>.public If a file is shared publicly, this attribute will be added with a value of 'true' for any role that applies to the public.
google.drive.file.path The hierarchical path of the file in Google Drive, e.g. 'parent_folder/child_folder/file.txt'.
Property Description
gridfs-bucket-name The GridFS bucket where the files will be stored. If left blank, it will use the default value 'fs' that the MongoDB client driver uses.
gridfs-client-service The MongoDB client service to use for database connections.
gridfs-database-name The name of the database to use
gridfs-file-name The name of the file in the bucket that is the target of this processor.
gridfs-query A valid MongoDB query to use to fetch one or more files from GridFS.
mongo-operation-mode This option controls when results are made available to downstream processors. If Stream Query Results is enabled, provenance will not be tracked relative to the input flowfile if an input flowfile is received and starts the query. In Stream Query Results mode errors will be handled by sending a new flowfile with the original content and attributes of the input flowfile to the failure relationship. Streaming should only be used if there is reliable connectivity between MongoDB and NiFi.
mongo-query-attribute If set, the query will be written to a specified attribute on the output flowfiles.
Name Description
failure When there is a failure processing the flowfile, it goes to this relationship.
original The original input flowfile goes to this relationship if the query does not cause an error
success When the operation succeeds, the flowfile is sent to this relationship.
Name Description
gridfs.file.metadata The custom metadata stored with a file is attached to this property if it exists.
Property Description
API Token Jira API token for authorization
Authorization Method Authorization method for Jira Cloud API
Environment URL URL to the Atlassian Jira Environment
Issue Fields A list of fields to return for each issue. This property accepts a comma-separated list.
Jira Email Email address associated with Jira account
Request Rate Manager Controller service for keeping track of rate limits for Atlassian APIs
Web Client Service Controller service for managing HTTP connections to Jira
Name Description
failure Failed to fetch Jira fields, e.g., due to connection issues or invalid credentials
retry Retryable failure occurred, e.g. rate limiting
success Successfully fetched Jira fields
Name Description
mime.type The MIME type of the returned response, always set to 'application/json'
Property Description
API Token Jira API token for authorization
Authorization Method Authorization method for Jira Cloud API
Created After Filter issues created after specified date/time (optional, format: yyyy-MM-dd)
Environment URL URL to the Atlassian Jira Environment
Issue Fields A list of fields to return for each issue. This property accepts a comma-separated list.
JQL Query JQL query string (required when using JQL query type)
Jira Email Email address associated with Jira account
Maximum Page Size The Maximum Page Size value must be between 50 and 1000
Project Names Comma-separated list of project names for simple search
Request Rate Manager Controller service for keeping track of rate limits for Atlassian APIs
Search Type Type of search to perform
Status Category Status category filter for simple search (optional)
Updated After Filter issues updated after specified date/time (optional, format: yyyy-MM-dd)
Web Client Service Controller service for managing HTTP connections to Jira
Scopes Description
CLUSTER Stores pagination state to maintain position between restarts. Resets when ingestion configuration changes.
Name Description
retry Retryable failure occurred, e.g. rate limiting
success Successfully fetched Jira issues
Name Description
mime.type application/json
jira.query.jql The JQL query used for this fetch
jira.source.url URL of the Jira source
statement.type Statement type INSERT, UPSERT
Property Description
Delete Schema
Environment URL URL to Microsoft Dataverse Environment
Logical Name Logical Name of Dataverse Table
Max Page Size Defines how many records will be fetched from Dataverse at once
OAuth2 Access Token Provider Enables managed retrieval of OAuth2 Bearer Token.
Record Writer Specifies the Controller Service to use for writing out the records
Rows Number Limit Defines maximum number of rows returned in a single flow file. Multiple request will be made to API to reach the limit. When not set, a page size value will be used effectively.
Table Name Dataverse Table Name
Upsert Schema
Web Client Service Provider Creates instance of web client.
Scopes Description
CLUSTER status
Name Description
failure FlowFile with errors occurred while fetching from Dataverse.
retry FlowFile with maintainable errors occurred while fetching from Dataverse.
success FlowFile with fetched data stored as records.
Property Description
AWS Credentials Provider service The Controller Service that is used to obtain AWS credentials provider
Bucket The S3 Bucket to interact with
Communications Timeout The amount of time to wait in order to establish a connection to AWS or receive data from AWS before timing out.
Custom Signer Class Name Fully qualified class name of the custom signer class. The signer must implement com.amazonaws.auth. Signer interface.
Custom Signer Module Location Comma-separated list of paths to files and/or directories which contain the custom signer's JAR file and its dependencies (if any).
Encryption Service Specifies the Encryption Service Controller used to configure requests. PutS3Object: For backward compatibility, this value is ignored when 'Server Side Encryption' is set. FetchS3Object: Only needs to be configured in case of Server-side Customer Key, Client-side KMS and Client-side Customer Key encryptions.
Endpoint Override URL Endpoint URL to use instead of the AWS default including scheme, host, port, and path. The AWS libraries select an endpoint URL based on the AWS region, but this property overrides the selected endpoint URL, allowing use with other S3-compatible endpoints.
Object Key The S3 Object Key to use. This is analogous to a filename for traditional file systems.
Range Length The number of bytes to download from the object, starting from the Range Start. An empty value or a value that extends beyond the end of the object will read to the end of the object.
Range Start The byte position at which to start reading from the object. An empty value or a value of zero will start reading at the beginning of the object.
Region The AWS Region to connect to.
Requester Pays If true, indicates that the requester consents to pay any charges associated with retrieving objects from the S3 bucket. This sets the 'x-amz-request-payer' header to 'requester'.
SSL Context Service Specifies an optional SSL Context Service that, if provided, will be used to create connections
Signer Override The AWS S3 library uses Signature Version 4 by default but this property allows you to specify the Version 2 signer to support older S3-compatible services or even to plug in your own custom signer implementation.
Version The Version of the Object to download
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
failure If the Processor is unable to process a given FlowFile, it will be routed to this Relationship.
success FlowFiles are routed to this Relationship after they have been successfully processed.
Name Description
s3.url The URL that can be used to access the S3 object
s3.bucket The name of the S3 bucket
path The path of the file
absolute.path The path of the file
filename The name of the file
hash.value The MD5 sum of the file
hash.algorithm MD5
mime.type If S3 provides the content type/MIME type, this attribute will hold that file
s3.etag The ETag that can be used to see if the file has changed
s3.exception The class name of the exception thrown during processor execution
s3.additionalDetails The S3 supplied detail from the failed operation
s3.statusCode The HTTP error code (if available) from the failed operation
s3.errorCode The S3 moniker of the failed operation
s3.errorMessage The S3 exception message from the failed operation
s3.expirationTime If the file has an expiration date, this attribute will be set, containing the milliseconds since epoch in UTC time
s3.expirationTimeRuleId The ID of the rule that dictates this object's expiration time
s3.sseAlgorithm The server side encryption algorithm of the object
s3.version The version of the S3 object
s3.encryptionStrategy The name of the encryption strategy that was used to store the S3 object (if it is encrypted)
Property Description
Algorithm Negotiation Configuration strategy for SSH algorithm negotiation
Ciphers Allowed A comma-separated list of Ciphers allowed for SFTP connections. Leave unset to allow all. Available options are: 3des-cbc, aes128-cbc, aes128-ctr, [aes128-gcm@openssh.com](mailto:aes128-gcm@openssh.com), aes192-cbc, aes192-ctr, aes256-cbc, aes256-ctr, [aes256-gcm@openssh.com](mailto:aes256-gcm@openssh.com), arcfour128, arcfour256, blowfish-cbc, [chacha20-poly1305@openssh.com](mailto:chacha20-poly1305@openssh.com), none
Completion Strategy Specifies what to do with the original file on the server once it has been pulled into NiFi. If the Completion Strategy fails, a warning will be logged but the data will still be transferred.
Connection Timeout Amount of time to wait before timing out while creating a connection
Create Directory Used when 'Completion Strategy' is 'Move File'. Specifies whether or not the remote directory should be created if it does not exist.
Data Timeout When transferring a file between the local and remote system, this value specifies how long is allowed to elapse without any data being transferred between systems
Disable Directory Listing Control how 'Move Destination Directory' is created when 'Completion Strategy' is 'Move File' and 'Create Directory' is enabled. If set to 'true', directory listing is not performed prior to create missing directories. By default, this processor executes a directory listing command to see target directory existence before creating missing directories. However, there are situations that you might need to disable the directory listing such as the following. Directory listing might fail with some permission setups (e.g. chmod 100) on a directory. Also, if any other SFTP client created the directory after this processor performed a listing and before a directory creation request by this processor is finished, then an error is returned because the directory already exists.
Host Key File If supplied, the given file will be used as the Host Key; otherwise, if 'Strict Host Key Checking' property is applied (set to true) then uses the 'known_hosts' and 'known_hosts2' files from ~/.ssh directory else no host key file will be used
Hostname The fully-qualified hostname or IP address of the host to fetch the data from
Key Algorithms Allowed A comma-separated list of Key Algorithms allowed for SFTP connections. Leave unset to allow all. Available options are: ecdsa-sha2-nistp256, [ecdsa-sha2-nistp256-cert-v01@openssh.com](mailto:ecdsa-sha2-nistp256-cert-v01@openssh.com), ecdsa-sha2-nistp384, [ecdsa-sha2-nistp384-cert-v01@openssh.com](mailto:ecdsa-sha2-nistp384-cert-v01@openssh.com), ecdsa-sha2-nistp521, [ecdsa-sha2-nistp521-cert-v01@openssh.com](mailto:ecdsa-sha2-nistp521-cert-v01@openssh.com), rsa-sha2-256, [rsa-sha2-256-cert-v01@openssh.com](mailto:rsa-sha2-256-cert-v01@openssh.com), rsa-sha2-512, [rsa-sha2-512-cert-v01@openssh.com](mailto:rsa-sha2-512-cert-v01@openssh.com), [sk-ecdsa-sha2-nistp256@openssh.com](mailto:sk-ecdsa-sha2-nistp256@openssh.com), [sk-ssh-ed25519@openssh.com](mailto:sk-ssh-ed25519@openssh.com), ssh-dss, [ssh-dss-cert-v01@openssh.com](mailto:ssh-dss-cert-v01@openssh.com), ssh-ed25519, [ssh-ed25519-cert-v01@openssh.com](mailto:ssh-ed25519-cert-v01@openssh.com), ssh-rsa, [ssh-rsa-cert-v01@openssh.com](mailto:ssh-rsa-cert-v01@openssh.com)
Key Exchange Algorithms Allowed A comma-separated list of Key Exchange Algorithms allowed for SFTP connections. Leave unset to allow all. Available options are: curve25519-sha256, [curve25519-sha256@libssh.org](mailto:curve25519-sha256@libssh.org), curve448-sha512, diffie-hellman-group-exchange-sha1, diffie-hellman-group-exchange-sha256, diffie-hellman-group1-sha1, diffie-hellman-group14-sha1, diffie-hellman-group14-sha256, diffie-hellman-group15-sha512, diffie-hellman-group16-sha512, diffie-hellman-group17-sha512, diffie-hellman-group18-sha512, ecdh-sha2-nistp256, ecdh-sha2-nistp384, ecdh-sha2-nistp521, mlkem1024nistp384-sha384, mlkem768nistp256-sha256, mlkem768x25519-sha256, sntrup761x25519-sha512, [sntrup761x25519-sha512@openssh.com](mailto:sntrup761x25519-sha512@openssh.com)
Log Level When File Not Found Log level to use in case the file does not exist when the processor is triggered
Message Authentication Codes Allowed A comma-separated list of Message Authentication Codes allowed for SFTP connections. Leave unset to allow all. Available options are: hmac-md5, hmac-md5-96, hmac-sha1, hmac-sha1-96, [hmac-sha1-etm@openssh.com](mailto:hmac-sha1-etm@openssh.com), hmac-sha2-256, [hmac-sha2-256-etm@openssh.com](mailto:hmac-sha2-256-etm@openssh.com), hmac-sha2-512, [hmac-sha2-512-etm@openssh.com](mailto:hmac-sha2-512-etm@openssh.com)
Move Destination Directory The directory on the remote server to move the original file to once it has been ingested into NiFi. This property is ignored unless the Completion Strategy is set to 'Move File'. The specified directory must already exist on the remote system if 'Create Directory' is disabled, or the rename will fail.
Password Password for the user account
Port The port to connect to on the remote host to fetch the data from
Private Key Passphrase Password for the private key
Private Key Path The fully qualified path to the Private Key file
Remote File The fully qualified filename on the remote system
Send Keep Alive On Timeout Send a Keep Alive message every 5 seconds up to 5 times for an overall timeout of 25 seconds.
Strict Host Key Checking Indicates whether or not strict enforcement of hosts keys should be applied
Use Compression Indicates whether or not ZLIB compression should be used when transferring files
Username Username
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
comms.failure Any FlowFile that could not be fetched from the remote server due to a communications failure will be transferred to this Relationship.
not.found Any FlowFile for which we receive a 'Not Found' message from the remote server will be transferred to this Relationship.
permission.denied Any FlowFile that could not be fetched from the remote server due to insufficient permissions will be transferred to this Relationship.
success All FlowFiles that are received are routed to success
Name Description
sftp.remote.host The hostname or IP address from which the file was pulled
sftp.remote.port The port that was used to communicate with the remote SFTP server
sftp.remote.filename The name of the remote file that was pulled
filename The filename is updated to point to the filename fo the remote file
path If the Remote File contains a directory name, that directory name will be added to the FlowFile using the 'path' attribute
fetch.failure.reason The name of the failure relationship applied when routing to any failure relationship
Property Description
Authentication Service The service that provides authentication for the SharePoint API
Download PDF/HTML Version Sharepoint supports automatically converting certain file formats to PDF or HTML. If this property is set to _true_, the Processor will inspect the FlowFile's filename extension to determine if the file can be converted to PDF or HTML. If the file can be converted, the Processor will download the converted version. If the file cannot be converted, the Processor will download the original file. If this property is set to _false_, the Processor will always download the original file.
Drive ID The ID of the drive that contains the file to fetch
Fallback Retry Duration The time to wait before retrying the operation after a communication failure. This value is used when the response doesn't contain a Retry-After header.
Item ID The ID of the item to fetch
Update Extension If true, the Processor will update the filename extension to match the format of the downloaded file
Name Description
comms.failure A FlowFile is routed here if the processor failed to communicate with the Graph API. Can be retried
failure An incoming FlowFile is routed to this relationship if the contents of the item could not be fetched
not.found A FlowFile is routed here if the item was not found
success An incoming FlowFile is routed to this relationship after the contents of the item have been fetched and written to the FlowFile
Property Description
Authentication Service The service that provides authentication for the SharePoint API
Drive ID A drive id where the Sharepoint file resides
Fallback Retry Duration The time to wait before retrying the operation after a communication failure. This value is used when the response doesn't contain a Retry-After header.
Fetch Item Permissions If true, the Processor will fetch user and group permission information for the captured Sharepoint item.
Item ID An id of an item to retrieve the metadata for
Item Permissions To Fetch A comma-separated list of permission types to fetch for the captured Sharepoint item. Available permission types: USER, GROUP, SITE_USER, SITE_GROUP.
Site ID A site id where the Sharepoint file resides
Name Description
comms.failure A FlowFile is routed here if the processor failed to communicate with the Graph API. Can be retried
failure An incoming FlowFile is routed to this relationship if the metadata and permissions of the item could not be fetched
not.found A FlowFile is routed here if the item was not found
success An incoming FlowFile is routed to this relationship after the metadata and permissions of the item have been fetched and written to the FlowFile attributes
Name Description
sharepoint.item.id The ID of the Sharepoint item.
sharepoint.item.type The type of the Sharepoint item. Possible values are 'File' and 'Folder'.
sharepoint.path The path of the Sharepoint item. This is the path relative to the root of the Document Library.
sharepoint.filename The name of the Sharepoint item. This attribute is not available for 'Deleted' changes.
sharepoint.size The size of the Sharepoint item.
sharepoint.createdAt The creation timestamp of the Sharepoint item.
sharepoint.lastModified The last modified timestamp of the Sharepoint item.
sharepoint.createdBy.<identity>.id An id of the identity that created the Sharepoint item. This attribute is not always available.
sharepoint.createdBy.<identity>.displayName A display name of the identity that created the Sharepoint item. This attribute is not always available.
sharepoint.createdBy.<identity>.email An email of the identity that created the Sharepoint item. This attribute is not always available.
sharepoint.lastModifiedBy.<identity>.id An id of the identity that modified the Sharepoint item last. This attribute is not always available.
sharepoint.lastModifiedBy.<identity>.displayName A display name of the identity that modified the Sharepoint item last. This attribute is not always available.
sharepoint.lastModifiedBy.<identity>.email An email of the identity that modified the Sharepoint item last. This attribute is not always available.
sharepoint.drive.id The ID of the Sharepoint Drive that contains the item.
sharepoint.site.id The ID of the Sharepoint Site that contains the item.
sharepoint.ctag The CTag of the Sharepoint item.
sharepoint.etag The ETag of the Sharepoint item.
sharepoint.webUrl The browser view url of the Sharepoint item.
sharepoint.permissions.read.groups A comma-separated list of groups that have read permissions on the Sharepoint item. For each group, if an e-mail address is available in Sharepoint, it will be included. Additionally, the group principal, such as _mygroup@mytenant.onmicrosoft.com_, is included.
sharepoint.permissions.read.groups.ids A comma-separated list of group IDs that have read permissions on the Sharepoint item.
sharepoint.permissions.read.users A comma-separated list of users that have read permissions on the Sharepoint item. For each user, if an e-mail address is available in Sharepoint, it will be included. Additionally, the user principal, such as _johndoe@mytenant.onmicrosoft.com_, is included.
sharepoint.permissions.read.users.ids A comma-separated list of Microsoft365 user IDs that have read permissions on the Sharepoint item.
sharepoint.permissions.read.siteusers A comma-separated list of Sharepoint site user emails that have read permissions on the Sharepoint item.
sharepoint.permissions.read.siteusers.ids A comma-separated list of Sharepoint site user IDs that have read permissions on the Sharepoint item.
sharepoint.permissions.read.sitegroups.ids A comma-separated list of Sharepoint site group IDs that have read permissions on the Sharepoint item.
filename The name of the Sharepoint item.
path The path of the Sharepoint item. This is the path relative to the root of the Document Library.
mime.type The MIME type of the Sharepoint item. This attribute is only available for 'File' items.
hash.quickxor The QuickXor hash of the Sharepoint item. This attribute is not always available.
hash.sha256 The SHA-256 hash of the Sharepoint item. This attribute is not always available.
hash.sha1 The SHA-1 hash of the Sharepoint item. This attribute is not always available.
hash.crc32 The CRC32 hash of the Sharepoint item. This attribute is not always available.
Property Description
Access Token OAuth Access Token used for authenticating/authorizing the Slack request sent by NiFi. This may be either a User Token or a Bot Token. It must be granted the channels:history, groups:history, im:history, or mpim:history scope, depending on the type of conversation being used.
Cache Expiration User emails are cached to reduce network lookups. A longer expiration reduces network overhead but can cause data to be out of sync.
Cache Size User emails are cached to reduce network lookups. A larger cache consumes memory but reduces network overhead.
Channel The Slack Channel ID to retrieve info from. Leave blank to iterate over every available Conversation.
Rate Limiter Service Slack Rate Limiter Service to coordinate rate limiting across processors
Name Description
conversations Each configured Slack Conversation info and members will be routed to this relationship in separate FlowFiles
failure If Slack Conversation metadata is unable to be received the input FlowFile will be routed to this relationship
original Original input FlowFile that has been successfully processed.
Name Description
conversation.members.count Set to the number of members of the conversation
conversation.id Set to the number of members of the conversation
channel.name Set to the name of the channel if the conversation is a channel
mime.type Set to application/json, as the output will always be in JSON format
Property Description
Bot Token The Bot Token that is registered to your Slack application
Channel ID The Slack Channel ID where the file was shared.
File ID The Slack File ID to download.
Rate Limiter Service Slack Rate Limiter Service to coordinate rate limiting across processors
Web Client Service The Web Client Service to use for downloading files from Slack
Name Description
failure FlowFiles that could not be processed are routed to this relationship
success FlowFiles containing successfully downloaded Slack files are routed to this relationship
Name Description
mime.type The MIME type of the downloaded file
filename The name of the downloaded file
slack.file.name The Slack File name
slack.file.mimetype The Slack File MIME type
slack.file.size The Slack File size in bytes
slack.conversation.id The Slack Channel ID
slack.event.ts The Slack event timestamp
Property Description
Access Token OAuth Access Token used for authenticating/authorizing the Slack request sent by NiFi. This may be either a User Token or a Bot Token. It must be granted the channels:history, groups:history, im:history, or mpim:history scope, depending on the type of conversation being used.
Channel The Slack Channel ID to Retrieve a message from.
Include Message Blocks Specifies whether or not the output JSON should include the value of the 'blocks' field for each Slack Message. This field includes information such as individual parts of a message that are formatted using rich text. This may be useful, for instance, for parsing. However, it often accounts for a significant portion of the data and as such may be set to null when it is not useful to you.
Include Null Fields Specifies whether or not fields that have null values should be included in the output JSON. If true, any field in a Slack Message that has a null value will be included in the JSON with a value of null. If false, the key omitted from the output JSON entirely. Omitting null values results in smaller messages that are generally more efficient to process, but including the values may provide a better understanding of the format, especially for schema inference.
Message Timestamp The timestamp of the message which is also its ID within a channel.
Rate Limiter Service Slack Rate Limiter Service to coordinate rate limiting across processors
Resolve Usernames Specifies whether or not User IDs should be resolved to usernames. By default, Slack Messages provide the ID of the user that sends a message, such as U0123456789, but not the username, such as NiFiUser. The username may be resolved, but it may require additional calls to the Slack API and requires that the Token used be granted the users:read scope. If set to true, usernames will be resolved with a best-effort policy: if a username cannot be obtained, it will be skipped over. Also, note that when a username is obtained, the Message's <username> field is populated, and the <text> field is updated such that any mention will be output such as "Hi @user" instead of "Hi <@U1234567>".
Thread Timestamp The timestamp of the thread the message belongs to. This can be null or empty unless the message is a reply to another message.
Name Description
failure Slack messages that fail to be received will be routed to this relationship
not found Slack messages that were not found on the Slack server will be routed to this relationship
success Slack messages that are successfully received will be routed to this relationship
Name Description
mime.type Set to application/json, as the output will always be in JSON format
Property Description
Completion Strategy Specifies what to do with the original file on the server once it has been processed. If the Completion Strategy fails, a warning will be logged but the data will still be transferred.
Create Destination Directory Specifies whether or not the remote directory should be created if it does not exist.
Destination Directory The directory on the remote server to move the original file to once it has been processed.
remote-file The full path of the file to be retrieved from the remote server. Expression language is supported.
smb-client-provider-service Specifies the SMB client provider to use for creating SMB connections.
Name Description
failure A FlowFile will be routed here when failed to fetch its content.
success A FlowFile will be routed here for each successfully fetched file.
Name Description
error.code The error code returned by SMB when the fetch of a file fails.
error.message The error message returned by SMB when the fetch of a file fails.
Property Description
Connection Pool The connection pool to use to connect to Snowflake
Schema Name The name of the schema
Table Metadata Cache Expiration Time The time in seconds after which the cache entry will be removed
Table Name The name of the table
Use Table Metadata Cache Whether to cache table's metadata instead of reading it directly from Snowflake.
Name Description
failure The incoming FlowFile is routed to this relationship if the properties cannot be read
success The incoming FlowFile is routed to this relationship after the table properties has been successfully read
table not found The incoming FlowFile is routed to this relationship if the specified table does not exist.
Property Description
Column Filter Service Specifies the Column Filter Service to be used for filtering out unwanted columns
Connection Pool The connection pool to use to fetch the source table schema
Schema Name The name of the schema that the source table is stored in
Table Name The name of the source table
Name Description
failure FlowFiles are routed to this relationship in the event that the source table's schema cannot be fetched
success FlowFiles are routed to this relationship when the source table's schema is successfully fetched
table not found FlowFiles are routed to this relationship when the source table does not exist
Name Description
mime.type application/json
dbms.type The type of database management system (DBMS) that the source table is stored in. E.g. _POSTGRESQL_
primary.key.count The number of primary keys in the source table
column.count The number of columns in the source table
Property Description
Connection Pool The connection pool to use to fetch the database snapshot
Fetch Size The maximum number of rows loaded into memory at once
JDBC Driver Location Comma-separated list of files/folders and/or URLs containing the driver JAR and its dependencies (if any). For example '/var/tmp/postgresql-java-client-42.7.5.jar'
Max Batch Size The maximum number of rows to fetch in a single batch
Record Writer The record writer to use to write the fetched snapshot
Schema Name The name of the schema to fetch the snapshot from
Table Name The name of the table to fetch the snapshot from
Name Description
complete When the snapshot is complete, the original FlowFile will be routed to this relationship
failure If the data cannot be retrieved from the table represented by the FlowFile, the FlowFile will be routed to this relationship.
retryable failure If the data cannot be retrieved from the table represented by the FlowFile but we expect it to be possible in future, the FlowFile will be routed to this relationship.
rows When the snapshot is successfully retrieved from the table represented by the FlowFile, the rows will be routed to this relationship.
Name Description
snapshot.complete Indicates whether the snapshot is complete
rows.total.fetched The total number of rows fetched for the table
rows.delta.fetched The number of rows fetched for the table in the last iteration
start.row.index The index of the first row within the snapshot for a given iteration, starting from 0
last.row.index The index of the last row within the snapshot for a given iteration, starting from 0
fetch.delta.time.in.millis The time in milliseconds taken to fetch the rows in the last iteration
fetch.total.time.in.millis The time in milliseconds taken so far to fetch the rows
Property Description
Attribute Matching Strategy Specifies the strategy to filter attributes by.
Filter Mode Specifies the strategy to apply on filtered attributes. Either 'Remove' or 'Retain' only the matching attributes.
Filtered Attributes A set of attribute names to filter from FlowFiles. Each attribute name is separated by the comma delimiter ','.
Filtered Attributes Pattern A regular expression to match names of attributes to filter from FlowFiles.
Name Description
success All successful FlowFiles are routed to this relationship
Property Description
Confluence Client Service Controller service for managing connections to Confluence
Confluence Page Name Name of the Confluence Page. If not provided, all pages in the space will be retrieved.
Confluence Space Name Name of the Confluence Space
Name Description
failure Failed to find Confluence pages
not found Pages for given space name and page name not found
retry Retryable failure occurred, e.g. rate limiting
success Successfully found Confluence pages
Name Description
confluence.page.name Unique identifier of the Confluence page.
confluence.page.change.type Informs about status change for the searched page.
confluence.page.url Confluence page url.
confluence.page.title Confluence page title.
confluence.page.last.modification.date Last modification date of the Confluence page.
confluence.space.name Name of the Confluence space.
Property Description
Authentication Service The service that provides authentication for the SharePoint API.
Drive ID The ID of the Sharepoint Drive.
Fallback Retry Duration The time to wait before retrying the operation after a communication failure. This value is used when the response doesn't contain a Retry-After header.
Item Path The path of the Drive Item to find in a Drive.
Name Description
comms.failure A FlowFile is routed here if the processor failed to communicate with the Graph API. Can be retried
failure An incoming FlowFile is routed to this relationship if an unexpected error has occurred
found An incoming FlowFile is routed to this relationship, with attributes about the Item added, if the specified item was found in Sharepoint
not.found An incoming FlowFile is routed to this relationship if the specified item was not found in Sharepoint
Name Description
sharepoint.item.id The ID of the Sharepoint Drive Item.
sharepoint.item.type The type of the Sharepoint Drive Item, possible values are 'File' and 'Folder'.
Property Description
flatten-json-character-set The Character Set in which file is encoded
flatten-json-pretty-print-json Specifies whether or not resulted json should be pretty printed
flatten-json-return-type Specifies the desired return type of json such as flatten/unflatten
flatten-json-separator The separator character used for joining keys. Must be a JSON-legal character.
flatten-mode Specifies how json should be flattened/unflattened
ignore-reserved-characters If true, reserved characters in keys will be ignored
Name Description
failure Files that cannot be flattened/unflattened go to this relationship.
success Successfully flattened/unflattened files go to this relationship.
Name Description
enrichment A clone of the incoming FlowFile will be routed to this relationship, after adding appropriate attributes.
original The incoming FlowFile will be routed to this relationship, after adding appropriate attributes.
Name Description
enrichment.group.id The Group ID to use in order to correlate the 'original' FlowFile with the 'enrichment' FlowFile.
enrichment.role The role to use for enrichment. This will either be ORIGINAL or ENRICHMENT.
Property Description
fork-mode Specifies the forking mode of the processor
include-parent-fields This parameter is only valid with the 'extract' mode. If set to true, all the fields from the root level to the given array will be added as fields of each element of the array to fork.
record-reader Specifies the Controller Service to use for reading incoming data
record-writer Specifies the Controller Service to use for writing out the records
Name Description
failure In case a FlowFile generates an error during the fork operation, it will be routed to this relationship
fork The FlowFiles containing the forked records will be routed to this relationship
original The original FlowFiles will be routed to this relationship
Name Description
record.count The generated FlowFile will have a 'record.count' attribute indicating the number of records that were written to the FlowFile.
mime.type The MIME Type indicated by the Record Writer
<Attributes from Record Writer> Any Attribute that the configured Record Writer returns will be added to the FlowFile.
Display Name API Name Default Value Allowable Values Description
Character Set * Character Set UTF-8 The Character set to use when writing the data to the FlowFile
Text * Text The text to use when writing the results. This property will evaluate the Expression Language using any of the fields available in a Record.
Display Name API Name Default Value Allowable Values Description
Delegation Strategy * Delegation Strategy Service Account - Service Account - Delegated Account The Delegation Strategy determines which account is used when calls are made with the GCP Credential.
Delegation User * Delegation User This user will be impersonated by the service account for api calls. API calls made using this credential will appear as if they are coming from delegate user with the delegate user's access. Any scopes supplied from processors to this credential must have domain-wide delegation setup with the service account.
Use Application Default Credentials application-default-credentials false - true - false If true, uses Google Application Default Credentials, which checks the GOOGLE_APPLICATION_CREDENTIALS environment variable for a filepath to a service account JSON key, the config generated by the gcloud sdk, the App Engine service account, and the Compute Engine service account.
Use Compute Engine Credentials compute-engine-credentials false - true - false If true, uses Google Compute Engine Credentials of the Compute Engine VM Instance which NiFi is running on.
Proxy Configuration Service proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Service Account JSON service-account-json The raw JSON containing a Service Account keyfile.
Service Account JSON File service-account-json-file Path to a file containing a Service Account key file in JSON format.
Required Permission Explanation
access environment credentials The default configuration can read environment variables and system properties for credentials
Display Name API Name Default Value Allowable Values Description
Bucket * Bucket $\{gcs.bucket\} Bucket of the object.
Name * Name $\{filename\} Name of the object.
GCP Credentials Provider Service * gcp-credentials-provider-service The Controller Service used to obtain Google Cloud Platform credentials.
Term Description SQL path
**live** In-progress edits (writable stage). Created automatically when a connector is created via UI or SQL `FROM DEFINITION`. `versions/live`
**default** The committed version the runtime runs when the connector starts. `versions/LAST` (alias)
**LAST** Alias for the most recently committed (default) version. `versions/LAST`
UI label Meaning
**Draft** Live version exists; no default version yet. The connector was created but never committed. Commit before starting.
**Edits not applied** Both live and default versions exist. Changes are in progress but not committed.
*(no label)* Only a default version exists. Stable state.
Created via Initial state
UI or SQL `FROM DEFINITION` Live version exists; no default (**Draft**). Commit before starting.
Stage `FROM '@[/path/]'` or `snow://...` Default version exists; no live version. Ready to start immediately (no **COMMIT** step).
Property Description
Answer Record Path The RecordPath to the synthetically generated answers
Context Record Path The RecordPath to the array of contexts in the record.
LLM Provider Service The provider service for sending evaluation prompts to LLM
Max Character Context Length Maximum character length of context window.
Question Record Path The RecordPath to the question field in the record.
Record Reader The Record Reader to use for reading the FlowFile.
Record Writer The Record Writer to use for writing the results.
Name Description
failure FlowFiles that cannot be processed are routed to this relationship
success FlowFiles that are successfully processed are routed to this relationship
Name Description
answers.successfully.generated The total number of successfully generated synthetic answers for the FlowFile.
answers.failed.generated The total number of synthetic answer generation attempts that failed for the FlowFile.
json.parse.failures Number of JSON parse failures encountered.
Property Description
Answer Record Path The RecordPath to the synthetically generated answers.
Ground Truth Record Path The RecordPath to the ground truth field in the record.
LLM Provider Service The provider service for sending evaluation prompts to LLM
Question Record Path The RecordPath to the question field in the record.
Record Reader The Record Reader to use for reading the FlowFile.
Record Writer The Record Writer to use for writing the results.
Name Description
failure FlowFiles that cannot be processed are routed to this relationship
success FlowFiles that are successfully processed are routed to this relationship
Name Description
answers.successfully.generated The total number of successfully synthetic answers generated for the FlowFile.
answers.failed.generated The total number of failed answer generation for the FlowFile.
json.parse.failures Number of JSON parse failures encountered.
Property Description
Batch Size The number of FlowFiles to be transferred in each invocation
Data Format Specifies whether the data should be Text or Binary
File Size The size of the file that will be used
Unique FlowFiles If true, each FlowFile that is generated will be unique. If false, a random value will be generated and all FlowFiles will get the same content but this offers much higher throughput
character-set Specifies the character set to use when writing the bytes of Custom Text to a flow file.
generate-ff-custom-text If Data Format is text and if Unique FlowFiles is false, then this custom text will be used as content of the generated FlowFiles and the File Size will be ignored. Finally, if Expression Language is used, evaluation will be performed only once per batch of generated FlowFiles
mime-type Specifies the value to set for the "mime.type" attribute.
Name Description
success
Name Description
mime.type Sets the MIME type of the output if the 'Mime Type' property is set
Property Description
Batch Size Number of records generated per FlowFile produced
JSON Schema JSON Schema version 2020-12 describing an object with properties indicating type and format for each field
Output Structure Structure for writing batches of records to each FlowFile
Name Description
success FlowFiles with generated JSON records
Property Description
null-percentage The percent probability (0-100%) that a generated value for any nullable field will be null. Set this property to zero to have no null values, or 100 to have all null values.
nullable-fields Whether the generated fields will be nullable. Note that this property is ignored if Schema Text is set. Also it only affects the schema of the generated data, not whether any values will be null. If this property is true, see 'Null Value Percentage' to set the probability that any generated field will be null.
number-of-records Specifies how many records will be generated for each outgoing FlowFile.
record-writer Specifies the Controller Service to use for writing out the records
schema-text The text of an Avro-formatted Schema used to generate record data. If this property is set, any user-defined properties are ignored.
Name Description
success FlowFiles that are successfully created will be routed to this relationship
Name Description
mime.type Sets the mime.type attribute to the MIME Type specified by the Record Writer
record.count The number of records in the FlowFile
Property Description
Columns to Return A comma-separated list of column names to be used in the query. If your database requires special treatment of the names (quoting, e.g.), each name should include such treatment. If no column names are supplied, all columns in the specified table will be returned. NOTE: It is important to use consistent column names for a given table for incremental fetch to work properly.
Database Connection Pooling Service The Controller Service that is used to obtain a connection to the database.
Database Dialect Service Database Dialect Service for generating statements specific to a particular service or vendor.
Max Wait Time The maximum amount of time allowed for a running SQL select query , zero means there is no limit. Max time less than 1 second will be equal to zero.
Maximum-value Columns A comma-separated list of column names. The processor will keep track of the maximum value for each column that has been returned since the processor started running. Using multiple columns implies an order to the column list, and each column 's values are expected to increase more slowly than the previous columns' values. Thus, using multiple columns implies a hierarchical structure of columns, which is usually used for partitioning tables. This processor can be used to retrieve only those rows that have been added/updated since the last retrieval. Note that some JDBC types such as bit/boolean are not conducive to maintaining maximum value, so columns of these types should not be listed in this property, and will result in error(s) during processing. If no columns are provided, all rows from the table will be considered, which could have a performance impact. NOTE: It is important to use consistent max-value column names for a given table for incremental fetch to work properly.
Table Name The name of the database table to be queried.
db-fetch-db-type Database Type for generating statements specific to a particular service or vendor. The Generic Type supports most cases but selecting a specific type enables optimal processing or additional features.
db-fetch-where-clause A custom clause to be added in the WHERE condition when building SQL queries.
gen-table-column-for-val-partitioning The name of a column whose values will be used for partitioning. The default behavior is to use row numbers on the result set for partitioning into 'pages' to be fetched from the database, using an offset/limit strategy. However for certain databases, it can be more efficient under the right circumstances to use the column values themselves to define the 'pages'. This property should only be used when the default queries are not performing well, when there is no maximum-value column or a single maximum-value column whose type can be coerced to a long integer (i.e. not date or timestamp), and the column values are evenly distributed and not sparse, for best performance.
gen-table-custom-orderby-column The name of a column to be used for ordering the results if Max-Value Columns are not provided and partitioning is enabled. This property is ignored if either Max-Value Columns is set or Partition Size = 0. NOTE: If neither Max-Value Columns nor Custom ORDER BY Column is set, then depending on the database/driver, the processor may report an error and/or the generated SQL may result in missing and/or duplicate rows. This is because without an explicit ordering, fetching each partition is done using an arbitrary ordering.
gen-table-fetch-partition-size The number of result rows to be fetched by each generated SQL statement. The total number of rows in the table divided by the partition size gives the number of SQL statements (i.e. FlowFiles) generated. A value of zero indicates that a single FlowFile is to be generated whose SQL statement will fetch all rows in the table.
gen-table-output-flowfile-on-zero-results Depending on the specified properties, an execution of this processor may not result in any SQL statements generated. When this property is true, an empty FlowFile will be generated (having the parent of the incoming FlowFile if present) and transferred to the 'success' relationship. When this property is false, no output FlowFiles will be generated.
Scopes Description
CLUSTER After performing a query on the specified table, the maximum values for the specified column(s) will be retained for use in future executions of the query. This allows the Processor to fetch only those records that have max values greater than the retained values. This can be used for incremental fetching, fetching of newly added rows, etc. To clear the maximum values, clear the state of the processor per the State Management documentation
Name Description
failure This relationship is only used when SQL query execution (using an incoming FlowFile) failed. The incoming FlowFile will be penalized and routed to this relationship. If no incoming connection(s) are specified, this relationship is unused.
success Successfully created FlowFile from SQL query result set.
Name Description
generatetablefetch.sql.error If the processor has incoming connections, and processing an incoming FlowFile causes a SQL Exception, the FlowFile is routed to failure and this attribute is set to the exception message.
generatetablefetch.tableName The name of the database table to be queried.
generatetablefetch.columnNames The comma-separated list of column names used in the query.
generatetablefetch.whereClause Where clause used in the query to get the expected rows.
generatetablefetch.maxColumnNames The comma-separated list of column names used to keep track of data that has been returned since the processor started running.
generatetablefetch.limit The number of result rows to be fetched by the SQL statement.
generatetablefetch.offset Offset to be used to retrieve the corresponding partition.
fragment.identifier All FlowFiles generated from the same query result set will have the same value for the fragment.identifier attribute. This can then be used to correlate the results.
fragment.count This is the total number of FlowFiles produced by a single ResultSet. This can be used in conjunction with the fragment.identifier attribute in order to know how many FlowFiles belonged to the same incoming ResultSet.
fragment.index This is the position of this FlowFile in the list of outgoing FlowFiles that were all generated from the same execution. This can be used in conjunction with the fragment.identifier attribute to know which FlowFiles originated from the same execution and in what order FlowFiles were produced
Property Description
IP Address Attribute The name of an attribute whose value is a dotted decimal IP address for which enrichment should occur
Log Level The Log Level to use when an IP is not found in the database. Accepted values: INFO, DEBUG, WARN, ERROR.
MaxMind Database File Path to Maxmind IP Enrichment Database File
Name Description
found Where to route flow files after successfully enriching attributes with data provided by database
not found Where to route flow files after unsuccessfully enriching attributes because no data was found
Name Description
X.geo.lookup.micros The number of microseconds that the geo lookup took
X.geo.city The city identified for the IP address
X.geo.accuracy The accuracy radius if provided by the database (in Kilometers)
X.geo.latitude The latitude identified for this IP address
X.geo.longitude The longitude identified for this IP address
X.geo.subdivision.N Each subdivision that is identified for this IP address is added with a one-up number appended to the attribute name, starting with 0
X.geo.subdivision.isocode.N The ISO code for the subdivision that is identified by X.geo.subdivision.N
X.geo.country The country identified for this IP address
X.geo.country.isocode The ISO Code for the country identified
X.geo.postalcode The postal code for the country identified
Property Description
City Record Path Record path for putting the city identified for the IP address
Country ISO Code Record Path Record path for putting the ISO Code for the country identified
Country Postal Code Record Path Record path for putting the postal code for the country identified
Country Record Path Record path for putting the country identified for this IP address
IP Address Record Path The record path to retrieve the IP address for doing the lookup.
Latitude Record Path Record path for putting the latitude identified for this IP address
Log Level The Log Level to use when an IP is not found in the database. Accepted values: INFO, DEBUG, WARN, ERROR.
Longitude Record Path Record path for putting the longitude identified for this IP address
MaxMind Database File Path to Maxmind IP Enrichment Database File
Record Reader Record reader service to use for reading the flowfile contents.
Record Writer Record writer service to use for enriching the flowfile contents.
Separate Enriched From Not Enriched Separate records that have been enriched from ones that have not. Default behavior is to send everything to the found relationship if even one record is enriched.
Name Description
found Where to route flow files after successfully enriching attributes with data provided by database
not found Where to route flow files after unsuccessfully enriching attributes because no data was found
original The original input flowfile goes to this relationship regardless of whether the content was enriched or not.
Property Description
Access Token Provider Service providing OAuth access token.
Amazon Advertising Client ID Client ID of the Amazon Advertising user.
Region Environment from which advertising data will be downloaded.
Report ID ID of the generated report.
Report Profile ID The profile ID associated with an advertising account in a specific marketplace.
Web Client Service Provider Service providing client for REST request execution.
Name Description
failure Error FlowFiles transferred when receiving error response from Amazon Ads Reporting API or when an error occurred during response processing.
retry Response FlowFiles transferred when report prepared by Amazon Ads Reporting API is not yet ready to be downloaded.
success Response FlowFiles transferred when receiving COMPLETED response from Amazon Ads Reporting API.
Name Description
mime.type Mime type of the returned report.
Property Description
AWS Credentials Provider service The Controller Service that is used to obtain AWS credentials provider
AWS Task ID
Communications Timeout
Endpoint Override URL Endpoint URL to use instead of the AWS default including scheme, host, port, and path. The AWS libraries select an endpoint URL based on the AWS region, but this property overrides the selected endpoint URL, allowing use with other S3-compatible endpoints.
Region
SSL Context Service Specifies an optional SSL Context Service that, if provided, will be used to create connections
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
failure The job failed, the original FlowFile will be routed to this relationship.
original Upon successful completion, the original FlowFile will be routed to this relationship.
running The job is currently still being processed
success Job successfully finished. FlowFile will be routed to this relation.
Name Description
PollyS3OutputBucket The bucket name where polly output will be located.
filename Object key of polly output.
outputLocation S3 path-style output location of the result.
Property Description
AWS Credentials Provider service The Controller Service that is used to obtain AWS credentials provider
AWS Task ID
Communications Timeout
Endpoint Override URL Endpoint URL to use instead of the AWS default including scheme, host, port, and path. The AWS libraries select an endpoint URL based on the AWS region, but this property overrides the selected endpoint URL, allowing use with other S3-compatible endpoints.
Region
SSL Context Service Specifies an optional SSL Context Service that, if provided, will be used to create connections
Textract Type Supported values: "Document Analysis", "Document Text Detection", "Expense Analysis"
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
failure The job failed, the original FlowFile will be routed to this relationship.
original Upon successful completion, the original FlowFile will be routed to this relationship.
running The job is currently still being processed
success Job successfully finished. FlowFile will be routed to this relation.
throttled Retrieving results failed for some reason, but the issue is likely to resolve on its own, such as Provisioned Throughput Exceeded or a Throttling failure. It is generally expected to retry this relationship.
Property Description
AWS Credentials Provider service The Controller Service that is used to obtain AWS credentials provider
AWS Task ID
Communications Timeout
Endpoint Override URL Endpoint URL to use instead of the AWS default including scheme, host, port, and path. The AWS libraries select an endpoint URL based on the AWS region, but this property overrides the selected endpoint URL, allowing use with other S3-compatible endpoints.
Region
SSL Context Service Specifies an optional SSL Context Service that, if provided, will be used to create connections
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
failure The job failed, the original FlowFile will be routed to this relationship.
original Upon successful completion, the original FlowFile will be routed to this relationship.
running The job is currently still being processed
success Job successfully finished. FlowFile will be routed to this relation.
throttled Retrieving results failed for some reason, but the issue is likely to resolve on its own, such as Provisioned Throughput Exceeded or a Throttling failure. It is generally expected to retry this relationship.
Name Description
outputLocation S3 path-style output location of the result.
Property Description
AWS Credentials Provider service The Controller Service that is used to obtain AWS credentials provider
AWS Task ID
Communications Timeout
Endpoint Override URL Endpoint URL to use instead of the AWS default including scheme, host, port, and path. The AWS libraries select an endpoint URL based on the AWS region, but this property overrides the selected endpoint URL, allowing use with other S3-compatible endpoints.
Region
SSL Context Service Specifies an optional SSL Context Service that, if provided, will be used to create connections
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
failure The job failed, the original FlowFile will be routed to this relationship.
original Upon successful completion, the original FlowFile will be routed to this relationship.
running The job is currently still being processed
success Job successfully finished. FlowFile will be routed to this relation.
throttled Retrieving results failed for some reason, but the issue is likely to resolve on its own, such as Provisioned Throughput Exceeded or a Throttling failure. It is generally expected to retry this relationship.
Name Description
outputLocation S3 path-style output location of the result.
Property Description
Consumer Group The name of the consumer group to use when pulling events
Event Hub Name Name of Azure Event Hubs source
Event Hub Namespace Namespace of Azure Event Hubs prefixed to Service Bus Endpoint domain
Message Enqueue Time A timestamp (ISO-8601 Instant) formatted as YYYY-MM-DDThhmmss.sssZ (2016-01-01T01:01:01.000Z) from which messages should have been enqueued in the Event Hub to start reading from
Partition Receiver Fetch Size The number of events that a receiver should fetch from an Event Hubs partition before returning. The default is 100
Partition Receiver Timeout The amount of time in milliseconds a Partition Receiver should wait to receive the Fetch Size before returning. The default is 60000
Service Bus Endpoint To support namespaces not in the default windows.net domain.
Shared Access Policy Key The key of the shared access policy. Either the primary or the secondary key can be used.
Shared Access Policy Name The name of the shared access policy. This policy must have Listen claims.
Transport Type Advanced Message Queuing Protocol Transport Type for communication with Azure Event Hubs
Use Azure Managed Identity Choose whether or not to use the managed identity of Azure VM/VMSS
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
success Any FlowFile that is successfully received from the event hub will be transferred to this Relationship.
Name Description
eventhub.enqueued.timestamp The time (in milliseconds since epoch, UTC) at which the message was enqueued in the event hub
eventhub.offset The offset into the partition at which the message was stored
eventhub.sequence The Azure sequence number associated with the message
eventhub.name The name of the event hub from which the message was pulled
eventhub.partition The name of the event hub partition from which the message was pulled
eventhub.property.* The application properties of this message. IE: 'application' would be 'eventhub.property.application'
Property Description
Auto Delete Messages Specifies whether the received message is to be automatically deleted from the queue.
Credentials Service Controller Service used to obtain Azure Storage Credentials.
Endpoint Suffix Storage accounts in public Azure always use a common FQDN suffix. Override this endpoint suffix with a different suffix in certain circumstances (like Azure Stack or non-public Azure regions).
Message Batch Size The number of messages to be retrieved from the queue.
Queue Name Name of the Azure Storage Queue
Request Timeout The timeout for read or write requests to Azure Queue Storage. Defaults to 1 second.
Visibility Timeout The duration during which the retrieved message should be invisible to other consumers.
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests. In case of SOCKS, it is not guaranteed that the selected SOCKS Version will be used by the processor.
Name Description
success All successfully processed FlowFiles are routed to this relationship
Name Description
azure.queue.uri The absolute URI of the configured Azure Queue Storage
azure.queue.insertionTime The time when the message was inserted into the queue storage
azure.queue.expirationTime The time when the message will expire from the queue storage
azure.queue.messageId The ID of the retrieved message
azure.queue.popReceipt The pop receipt of the retrieved message
Property Description
Box Client Service Controller Service used to obtain a Box API connection.
File ID The ID of the Box file to retrieve collaborators for
Roles A comma-separated list of collaboration roles to retrieve. Available roles: editor, viewer, previewer, uploader, previewer uploader, viewer uploader, co-owner, owner. If not specified, no filtering by role will be applied.
Statuses A comma-separated list of collaboration statuses to retrieve. Available statuses: accepted, pending, rejected. If not specified, no filtering by status will be applied.
Name Description
failure FlowFiles that encounter errors during processing will be routed to this relationship
not.found FlowFiles for which the specified Box file was not found
success FlowFiles that have been successfully processed will be routed to this relationship
Name Description
box.id The id of the file
box.collaborations.<status>.users.ids Comma-separated list of user collaborator IDs by status
box.collaborations.<status>.groups.ids Comma-separated list of group collaborator IDs by status
box.collaborations.<status>.users.emails Comma-separated list of user collaborator emails by status
box.collaborations.<status>.groups.emails Comma-separated list of group collaborator emails by status
box.collaborations.<status>.<role>.users.ids Comma-separated list of user collaborator IDs by status and role. Only present when both Roles and Statuses properties are set.
box.collaborations.<status>.<role>.users.logins Comma-separated list of user collaborator logins by status and role. Only present when both Roles and Statuses properties are set.
box.collaborations.<status>.<role>.groups.ids Comma-separated list of group collaborator IDs by status and role. Only present when both Roles and Statuses properties are set.
box.collaborations.<status>.<role>.groups.emails Comma-separated list of group collaborator emails by status and role. Only present when both Roles and Statuses properties are set.
box.collaborations.count Total number of collaborations on the file
error.code The error code returned by Box
error.message The error message returned by Box
Property Description
Box Client Service Controller Service used to obtain a Box API connection.
Group ID The ID of the Group to retrieve members for
Name Description
failure The FlowFile will be routed here when Group memberships retrieval was attempted but failed.
not.found The FlowFile will be routed here when the Group was not found.
success The FlowFile will be routed here after successfully retrieving Group members.
Name Description
box.group.user.ids A comma-separated list of user IDs in the group.
box.group.user.logins A comma-separated list of user Logins (emails) in the group.
error.code An http error code returned by Box.
error.message An error message returned by Box.
Property Description
Audit Log Fetch Limit How many audit logs will be fetched from Confluence API in one request
Confluence Client Service Controller service for managing connections to Confluence
Scopes Description
CLUSTER Stores last synchronization timestamp.
Name Description
failure Failed to fetch Confluence audit records
original The input Flow File is routed to the original relationship.
retry Retryable failure occurred, e.g. rate limiting
success Successfully fetched Confluence audit records
Name Description
confluence.group.ids List of identifiers of the Confluence groups.
confluence.page.names List of the names of the Confluence page.
confluence.space.names List of the Confluence spaces.
confluence.continue.fetching Indicates whether there are more pages to fetch (true/false).
Property Description
Confluence Client Service Controller service for managing connections to Confluence
Confluence Group ID Identifier of the Confluence Group
Name Description
failure Failed to fetch Confluence group users
retry Retryable failure occurred, e.g. rate limiting
success Successfully fetched Confluence group users
Name Description
confluence.group.user.ids Identifiers of the Confluence group users.
confluence.group.user.emails Emails of the Confluence group users.
Property Description
Body Format Format in which body of the Confluence Page will be fetched
Confluence Client Service Controller service for managing connections to Confluence
Confluence Page ID Identifier of the Confluence Page
Name Description
failure Failed to fetch Confluence page
not found Confluence page not found
removed Confluence page was removed
retry Retryable failure occurred, e.g. rate limiting
success Successfully fetched Confluence page
Name Description
mime.type text/html
confluence.page.version Version of the Confluence page.
confluence.page.last.modification.date Last modification date of the Confluence page.
confluence.page.change.type Informs about status change for the searched page.
Property Description
Confluence Client Service Controller service for managing connections to Confluence
Page IDs Comma separated list of page IDs to filter page by; only pages with these IDs are returned
Space IDs Comma separated list of space IDs to filter pages by; only pages from these spaces are returned
Start Date Start date from which the ingestion should happen (format: yyyy-MM-dd, inclusive)
Scopes Description
CLUSTER Stores pagination state to maintain position between restarts.
Name Description
failure Failed to fetch changed Confluence pages
original The input Flow File is routed to the original relationship.
retry Retryable failure occurred, e.g. rate limiting
success Successfully fetched changed Confluence pages
Name Description
confluence.page.id Unique identifier of the Confluence page.
confluence.page.change.type Informs about status change for the searched page.
confluence.page.url Confluence page url.
confluence.page.title Confluence page title.
confluence.page.last.modification.date Last modification date of the Confluence page.
confluence.space.id Unique identifier of the Confluence space.
confluence.continue.fetching Indicates whether there are more pages to fetch (true/false).
Property Description
Confluence Client Service Controller service for managing connections to Confluence
Confluence Page ID Identifier of the Confluence Page
Name Description
failure Failed to fetch and parse Confluence page permissions.
page not found Confluence page not found
restrictions changed Confluence page restrictions changed since last fetch
retry Retryable failure occurred, e.g. rate limiting
success Successfully fetched Confluence page permissions.
Name Description
confluence.permissions.users IDs of users with permissions to the Confluence page
confluence.permissions.emails Emails of users with permissions to the Confluence page
confluence.permissions.groups Groups with permissions to the Confluence page
Property Description
Confluence Client Service Controller service for managing connections to Confluence
Space Keys Comma-separated list of space keys to filter. If not specified, all spaces will be retrieved.
Name Description
retry Retryable failure occurred, e.g. rate limiting
success Successfully fetched Confluence spaces
Name Description
confluence.space.ids List of identifiers of the Confluence spaces.
Property Description
Confluence Client Service Controller service for managing connections to Confluence
Confluence Space ID Identifier of the Confluence Space.
Name Description
failure Failed to fetch and parse Confluence space permissions.
retry Retryable failure occurred, e.g. rate limiting
space not found Confluence space not found
success Successfully fetched Confluence space permissions.
Name Description
confluence.permissions.users IDs of users with permissions to the Confluence space
confluence.permissions.emails Emails of users with permissions to the Confluence space
confluence.permissions.groups Groups with permissions to the Confluence space
Property Description
Calculated Insights Objects Comma separated list of Calculated Insight Object names to describe.
Connection Pooling Service The Connection Pooling Service that is used to create the Snowflake volumes holding the credentials.
Data Lake Objects Comma separated list of Data Lake Object names to describe.
Data Model Objects Comma separated list of Data Model Object names to describe.
Data Share Name The name of the Data Share to describe.
Salesforce Data Cloud Client Salesforce Data Cloud Client to interact with the APIs
Scopes Description
CLUSTER Provides information about the last time an external volume has been created/updated for credentials.
Name Description
comms.failure A FlowFile is routed to this relationship if the data share credentials metadata could not be retrieved but the operation might be retried
failure A FlowFile is routed to this relationship if the data share credentials cannot be retrieved or volumes cannot be created
success FlowFile containing the data share metadata after successful creation of the volumes will be routed to this relationship
Property Description
Calculated Insights Objects Comma separated list of Calculated Insight Object names to describe.
Data Lake Objects Comma separated list of Data Lake Object names to describe.
Data Model Objects Comma separated list of Data Model Object names to describe.
Data Share Name The name of the Data Share to describe.
Salesforce Data Cloud Client Salesforce Data Cloud Client to interact with the APIs
Name Description
comms.failure A FlowFile is routed to this relationship if the data share tables metadata could not be retrieved but the operation might be retried
failure A FlowFile is routed to this relationship if the data share tables metadata could not be retrieved
success FlowFile containing the data share tables metadata will be routed to this relationship
Property Description
DBFS File Path DBFS file path e.g. /directory/file.txt
Databricks Client Databricks Client Service.
Name Description
failure Databricks failure relationship
success Databricks success relationship
Name Description
error.code The error code for the SQL statement if an error occurred.
error.message The error message for the SQL statement if an error occurred.
Property Description
AWS Credentials Provider service The Controller Service that is used to obtain AWS credentials provider
Batch items for each request (between 1 and 50) The items to be retrieved in one batch
Communications Timeout
Endpoint Override URL Endpoint URL to use instead of the AWS default including scheme, host, port, and path. The AWS libraries select an endpoint URL based on the AWS region, but this property overrides the selected endpoint URL, allowing use with other S3-compatible endpoints.
Hash Key Name The hash key name of the item
Hash Key Value The hash key value of the item
Hash Key Value Type The hash key value type of the item
Json Document attribute The Json document to be retrieved from the dynamodb item ( 's' type in the schema)
Range Key Name The range key name of the item
Range Key Value
Range Key Value Type The range key value type of the item
Region
SSL Context Service Specifies an optional SSL Context Service that, if provided, will be used to create connections
Table Name The DynamoDB table name
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
failure FlowFiles are routed to failure relationship
not found FlowFiles are routed to not found relationship if key not found in the table
success FlowFiles are routed to success relationship
unprocessed FlowFiles are routed to unprocessed relationship when DynamoDB is not able to process all the items in the request. Typical reasons are insufficient table throughput capacity and exceeding the maximum bytes per request. Unprocessed FlowFiles can be retried with a new request.
Name Description
dynamodb.key.error.unprocessed DynamoDB unprocessed keys
dynmodb.range.key.value.error DynamoDB range key error
dynamodb.key.error.not.found DynamoDB key not found
dynamodb.error.exception.message DynamoDB exception message
dynamodb.error.code DynamoDB error code
dynamodb.error.message DynamoDB error message
dynamodb.error.service DynamoDB error service
dynamodb.error.retryable DynamoDB error is retryable
dynamodb.error.request.id DynamoDB error request id
dynamodb.error.status.code DynamoDB status code
Property Description
Attribute Name The name of the FlowFile attribute to use for the retrieved document output.
Client Service An Elasticsearch client service to use for running queries.
Destination Indicates whether the retrieved document is written to the FlowFile content or a FlowFile attribute.
Document Id The _id of the document to retrieve.
Index The name of the index to use.
Type The type of this document (used by Elasticsearch for indexing and searching).
Name Description
document Fetched documents are routed to this relationship.
failure All flowfiles that fail for reasons unrelated to server availability go to this relationship.
not_found A FlowFile is routed to this relationship if the specified document does not exist in the Elasticsearch cluster.
retry All flowfiles that fail due to server/cluster availability go to this relationship.
Name Description
filename The filename attribute is set to the document identifier
elasticsearch.index The Elasticsearch index containing the document
elasticsearch.type The Elasticsearch document type
elasticsearch.get.error The error message provided by Elasticsearch if there is an error fetching the document.
Property Description
Batch Size The maximum number of files to pull in each invocation of the processor
File Filter Only files whose names match the given regular expression will be picked up
Ignore Hidden Files Indicates whether or not hidden files should be ignored
Input Directory The input directory from which to pull files
Keep Source File If true, the file is not deleted after it has been copied to the Content Repository; this causes the file to be picked up continually and is useful for testing purposes. If not keeping original NiFi will need write permissions on the directory it is pulling from otherwise it will ignore the file.
Maximum File Age The maximum age that a file must be in order to be pulled; any file older than this amount of time (according to last modification date) will be ignored
Maximum File Size The maximum size that a file can be in order to be pulled
Minimum File Age The minimum age that a file must be in order to be pulled; any file younger than this amount of time (according to last modification date) will be ignored
Minimum File Size The minimum size that a file must be in order to be pulled
Path Filter When Recurse Subdirectories is true, then only subdirectories whose path matches the given regular expression will be scanned
Polling Interval Indicates how long to wait before performing a directory listing
Recurse Subdirectories Indicates whether or not to pull files from subdirectories
Required Permission Explanation
read filesystem Provides operator the ability to read from any file that NiFi has access to.
write filesystem Provides operator the ability to delete any file that NiFi has access to.
Name Description
success All files are routed to success
Name Description
filename The filename is set to the name of the file on disk
path The path is set to the relative path of the file's directory on disk. For example, if the <Input Directory> property is set to /tmp, files picked up from /tmp will have the path attribute set to ./. If the <Recurse Subdirectories> property is set to true and a file is picked up from /tmp/abc/1/2/3, then the path attribute will be set to abc/1/2/3
file.creationTime The date and time that the file was created. May not work on all file systems
file.lastModifiedTime The date and time that the file was last modified. May not work on all file systems
file.lastAccessTime The date and time that the file was last accessed. May not work on all file systems
file.owner The owner of the file. May not work on all file systems
file.group The group owner of the file. May not work on all file systems
file.permissions The read/write/execute permissions of the file. May not work on all file systems
absolute.path The full/absolute path from where a file was picked up. The current 'path' attribute is still populated, but may be a relative path
Property Description
File Resource Location of the File Resource (Local File or URL). This file will be used as content of the generated FlowFiles.
MIME Type Specifies the value to set for the [mime.type] attribute.
Required Permission Explanation
read filesystem Provides operator the ability to read from any file that NiFi has access to.
reference remote resources File Resource can reference resources over HTTP/HTTPS
Name Description
success
Name Description
mime.type Sets the MIME type of the output if the 'MIME Type' property is set
Dynamic property key Value for the corresponding dynamic property, if any is set
Property Description
Connection Mode The FTP Connection Mode
Connection Timeout Amount of time to wait before timing out while creating a connection
Data Timeout When transferring a file between the local and remote system, this value specifies how long is allowed to elapse without any data being transferred between systems
Delete Original Determines whether or not the file is deleted from the remote system after it has been successfully transferred
File Filter Regex Provides a Java Regular Expression for filtering Filenames; if a filter is supplied, only files whose names match that Regular Expression will be fetched
Follow Symbolic Links If true, will pull even symbolic files and also nested symbolic subdirectories; otherwise, will not read symbolic files and will not traverse symbolic link subdirectories
Hostname The fully qualified hostname or IP address of the remote system
Ignore Dotted Files If true, files whose names begin with a dot (".") will be ignored
Internal Buffer Size Set the internal buffer size for buffered data streams
Max Selects The maximum number of files to pull in a single connection
Password Password for the user account
Path Filter Regex When Search Recursively is true, then only subdirectories whose path matches the given Regular Expression will be scanned
Polling Interval Determines how long to wait between fetching the listing for new files
Port The port that the remote system is listening on for file transfers
Remote Path The path on the remote system from which to pull or push files
Remote Poll Batch Size The value specifies how many file paths to find in a given directory on the remote system when doing a file listing. This value in general should not need to be modified but when polling against a remote system with a tremendous number of files this value can be critical. Setting this value too high can result very poor performance and setting it too low can cause the flow to be slower than normal.
Search Recursively If true, will pull files from arbitrarily nested subdirectories; otherwise, will not traverse subdirectories
Transfer Mode The FTP Transfer Mode
Use Natural Ordering If true, will pull files in the order in which they are naturally listed; otherwise, the order in which the files will be pulled is not defined
Username Username
ftp-use-utf8 Tells the client to use UTF-8 encoding when processing files and filenames. If set to true, the server must also support UTF-8 encoding.
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
success All FlowFiles that are received are routed to success
Name Description
filename The filename is set to the name of the file on the remote server
path The path is set to the path of the file's directory on the remote server. For example, if the <Remote Path> property is set to /tmp, files picked up from /tmp will have the path attribute set to /tmp. If the <Search Recursively> property is set to true and a file is picked up from /tmp/abc/1/2/3, then the path attribute will be set to /tmp/abc/1/2/3
file.lastModifiedTime The date and time that the source file was last modified
file.lastAccessTime The date and time that the file was last accessed. May not work on all file systems
file.owner The numeric owner id of the source file
file.group The numeric group id of the source file
file.permissions The read/write/execute permissions of the source file
absolute.path The full/absolute path from where a file was picked up. The current 'path' attribute is still populated, but may be a relative path
Property Description
gcp-credentials-provider-service The Controller Service used to obtain Google Cloud Platform credentials.
operationKey The unique identifier of the Vision operation.
Name Description
failure FlowFiles are routed to failure relationship
original Upon successful completion, the original FlowFile will be routed to this relationship.
running The job is currently still being processed
success FlowFiles are routed to success relationship
Property Description
gcp-credentials-provider-service The Controller Service used to obtain Google Cloud Platform credentials.
operationKey The unique identifier of the Vision operation.
Name Description
failure FlowFiles are routed to failure relationship
original Upon successful completion, the original FlowFile will be routed to this relationship.
running The job is currently still being processed
success FlowFiles are routed to success relationship
Property Description
Client Account ID ID of the Google Ads account for which the report should be fetched
GCP Credentials Service Controller Service used to obtain Google Cloud Platform credentials.
Google Ads Resource Name Name of the resource that should be used in 'FROM' clause of the query
Google Developer Token Developer token required to access Google APIs
Report Attributes List of comma-separated report attributes
Report Metrics List of comma-separated report metrics
Report Segments List of comma-separated report segments
Report Start Date Start date from which the ingestion should happen.
Scopes Description
CLUSTER Stores information about last report definition in form of hash to detect schema changes. In incremental ingestion (when the 'segments.date' segment is selected) it keeps track of latest ingested date to download only new data chunks. Additionally start date is saved.
Name Description
failure Error FlowFiles transferred when receiving error response from Google Ads Reporting API or when an error occurred during response processing.
success Response FlowFiles transferred when receiving success response from Google Ads Reporting API.
Name Description
google.ads.client.account.id ID of the account in Google Ads for which given report should be ingested
google.ads.resource.name Name of the resource in Google Ads that is a source for the report
google.ads.query Query used to fetch data from Google Ads StreamSearch API
google.ads.attributes Attributes of the selected resource
google.ads.metrics Metrics collected in the context of a given resource
google.ads.segments Buckets in which metrics should be grouped
google.ads.ingestion.strategy The strategy used for ingestion. Can be 'SNAPSHOT' or 'INCREMENTAL'
google.ads.start.date Date from which data is downloaded from Google Ads (including given date)
google.ads.end.date Date to which data is downloaded from Google Ads (including given date)
google.ads.report.schema.changed Flag meaning if the report schema has changed between processor executions
google.ads.report.conversion.window Number of days which are fetched from Google Ads during incremental load. Based on Conversion Window values
fragment.identifier A unique ID of each ingestion run. Lets you identify all flow files generated during a single run.
fragment.index Number representing unique identifier in batch of flowfiles generated during one ingestion run
fragment.count Amount of flowfiles generated during processor execution
avro.schema Avro schema representing fetched data
mime.type Mime type of the returned report.
Property Description
Fetch Nested Groups When enabled, recursively fetches members from nested groups within the specified groups. When disabled, only top-level members are retrieved.
GCP Credentials Service Specifies the Controller Service used to obtain Google Cloud Platform credentials.
Google Group IDs Specifies the comma-separated list of Google Group IDs (email addresses for the groups). Supports Expression Language.
Nested Depth Limit Maximum depth to traverse when fetching nested group members.
Name Description
failure A FlowFile is routed here if the processor fails to retrieve Google group members.
not.found A FlowFile is routed here if for each Google group that was not found.
retry A FlowFile is routed here if the processor should retry the request (e.g., after rate limiting).
success A FlowFile is routed here after successfully retrieving Google group members.
Name Description
google.group.ids A comma-separated list of Google Group IDs that were found.
google.group.member.user.ids A comma-separated list of user IDs found in the specified groups. When nested fetching is enabled, includes users from nested groups up to the specified depth.
google.group.member.user.emails A comma-separated list of user email addresses found in the specified groups. When nested fetching is enabled, includes users from nested groups up to the specified depth.
google.group.member.group.ids A comma-separated list of nested group IDs found in the specified groups. When nested fetching is enabled, includes all groups discovered during recursive traversal.
google.group.member.group.emails A comma-separated list of nested group email addresses found in the specified groups. When nested fetching is enabled, includes all groups discovered during recursive traversal.
Property Description
Date Time Render Option Determines how dates should be rendered in the output.
GCP Credentials Service Controller Service used to obtain Google Cloud Platform credentials.
Ranges The A1 notation or R1C1 notation of the comma-separated ranges to retrieve values from. For example: Sheet1!A1:B2,Sheet2!D4:E5,Sheet3. The first row in a sheet must represent column names. If not specified, all sheets will be downloaded.
Spreadsheet ID ID of the Google Sheets Spreadsheet. Can be found in the URL of the spreadsheet.
Value Render Option Determines how values should be rendered in the output.
Name Description
failure FlowFile with errors occurred while fetching from Google Sheets.
success FlowFile containing a JSON array where each object represents a row from the source sheet. Keys correspond to column headers from the first row, and values to the respective row entries.
Name Description
google.sheets.spreadsheet.id ID of the Google Sheets Spreadsheet.
google.sheets.range Range in Google Sheets Spreadsheet that was fetched.
run.id A unique ID of each ingestion run. Lets you identify all flow files generated during a single run.
destination.table.schema A Snowflake schema of the destination table in the following format: \{ "columns": [ \{ "name": "<column name>", "type": "<column type>", "nullable": <true/false>, "precision": <precision, only for numeric type>, "scale": <scale, only for numeric type> \}, ... ], "primaryKeys": ["<name of first primary key column>", "<name of second primary key column>", ...] \}
Property Description
access-token Access Token to authenticate requests
incremental-delay The ending timestamp of the time window will be adjusted earlier by the amount configured in this property. For example, with a property value of 10 seconds, an ending timestamp of 12:30:45 would be changed to 12:30:35. Set this property to avoid missing objects when the clock of your local machines and HubSpot servers 'clock are not in sync and to protect against HubSpot's mechanism that changes last updated timestamps after object creation.
incremental-initial-start-time This property specifies the start time that the processor applies when running the first request. The expected format is a UTC date-time such as '2011-12-03T10:15:30Z'
is-incremental The processor can incrementally load the queried objects so that each object is queried exactly once. For each query, the processor queries objects within a time window where the objects were modified between the previous run time and the current time (optionally adjusted by the Incremental Delay property).
object-type The HubSpot Object Type requested
result-limit The maximum number of results to request for each invocation of the Processor
web-client-service-provider Controller service for HTTP client operations
Scopes Description
CLUSTER In case of incremental loading, the start and end timestamps of the last query time window are stored in the state. When the 'Result Limit' property is set, the paging cursor is saved after executing a request. Only the objects after the paging cursor will be retrieved. The maximum number of retrieved objects can be set in the 'Result Limit' property.
Name Description
success For FlowFiles created as a result of a successful HTTP request.
Name Description
mime.type Sets the MIME type to application/json
Property Description
HubSpot Service HubSpot Client Service.
Object ID Property HubSpot property used to uniquely identify the object.
Object ID Value Matching HubSpot property value to search for.
Object Type HubSpot object type
Name Description
failure HubSpot fail relationship
missing HubSpot object does not exist.
retry HubSpot retry relationship. FlowFiles that failed to process due to a server timeout or rate limit related error. FlowFiles routed here should be routed back into the processor.
success HubSpot success relationship
Property Description
HubSpot Service HubSpot Client Service.
Object Type HubSpot object type
Name Description
failure HubSpot fail relationship
retry HubSpot retry relationship. FlowFiles that failed to process due to a server timeout or rate limit related error. FlowFiles routed here should be routed back into the processor.
success HubSpot success relationship
Name Description
hubspot.object.type The HubSpot object type
hubspot.field.count Number of fields retrieved
mime.type MIME type of the output (application/json)
Property Description
Accounts List of comma-separated accounts.
Campaign Groups List of comma-separated campaign groups.
Campaigns List of comma-separated campaigns.
Companies List of comma-separated companies.
Conversion Window Timeframe for which data is refreshed during incremental load.
Metrics List of comma-separated metrics.
OAuth Token Provider Service providing OAuth access token.
Pivots List of comma-separated pivots.
Report Name Unique name of the report.
Shares List of comma-separated shares.
Start Date Start date from which ingestion should begin. It must be in the yyyy-MM-dd format.
Time Granularity Time granularity of results.
Web Client Service Provider Service providing client for REST request execution.
Scopes Description
CLUSTER Stores information about last report definition in form of hash to detect schema changes. Incrementally loaded reports persist last ingestion date to define ingestion date ranges after initial load. Additionally start date is saved.
Name Description
success Response FlowFiles transferred when successfully processed a response from the LinkedIn Ads Reporting API.
Name Description
linkedin.ads.report.name Unique name of the report.
linkedin.ads.run.id Unique identifier of the run.
avro.schema Avro schema that contains a set of all configured metrics and pivots.
linkedin.ads.ingestion.strategy Strategy that defines whether the report will be downloaded as SNAPSHOT or INCREMENTAL.
linkedin.ads.report.schema.changed Flag that indicates whether the report schema has changed between processor executions.
linkedin.ads.ingestion.start.date Date from which data is downloaded from LinkedIn Ads (including a given date).
linkedin.ads.ingestion.end.date Date to which data is downloaded from LinkedIn Ads (including a given date).
Property Description
Authentication Service The service that provides authentication for the SharePoint API
Fallback Retry Duration The time to wait before retrying the operation after a communication failure. This value is used when the response doesn't contain a Retry-After header.
Microsoft365 Group id Specifies a Microsoft365 group id to retrieve the members for. Supports Expression Language.
Name Description
comms.failure A FlowFile is routed here if the processor failed to communicate with the Graph API. Can be retried
failure An incoming FlowFile is routed to this relationship if the group members could not be fetched
not.found A FlowFile is routed here if the group was not found
success A FlowFile is routed here if the group members were successfully retrieved
Name Description
microsoft365.group.user.ids A comma-separated list of Microsoft365 user ids that are members of the Microsoft365 group.
microsoft365.group.user.emails A comma-separated list of user emails that are members of the Microsoft365 group.
Property Description
Batch Size The number of elements to be returned from the server in one batch
Limit The maximum number of elements to return
Mongo Collection Name The name of the collection to use
Mongo Database Name The name of the database to use
Projection The fields to be returned from the documents in the result set; must be a valid BSON document
Query The selection criteria to do the lookup. If the field is left blank, it will look for input from an incoming connection from another processor to provide the query as a valid JSON document inside of the FlowFile's body. If this field is left blank and a timer is enabled instead of an incoming connection, that will result in a full collection fetch using a "\{\}" query.
Sort The fields by which to sort; must be a valid BSON document
get-mongo-send-empty If a query executes successfully, but returns no results, send an empty JSON document signifying no result.
json-type By default, MongoDB's Java driver returns "extended JSON". Some of the features of this variant of JSON may cause problems for other JSON parsers that expect only standard JSON types and conventions. This configuration setting controls whether to use extended JSON or provide a clean view that conforms to standard JSON.
mongo-charset Specifies the character set of the document data.
mongo-client-service If configured, this property will use the assigned client service for connection pooling.
mongo-date-format The date format string to use for formatting Date fields that are returned from Mongo. It is only applied when the JSON output format is set to Standard JSON.
mongo-query-attribute If set, the query will be written to a specified attribute on the output flowfiles.
results-per-flowfile How many results to put into a FlowFile at once. The whole body will be treated as a JSON array of results.
use-pretty-printing Choose whether or not to pretty print the JSON from the results of the query. Choosing 'True' can greatly increase the space requirements on disk depending on the complexity of the JSON document
Name Description
failure All input FlowFiles that are part of a failed query execution go here.
original All input FlowFiles that are part of a successful query execution go here.
success All FlowFiles that have the results of a successful query execution go here.
Name Description
mongo.database.name The database where the results came from.
mongo.collection.name The collection where the results came from.
Property Description
Batch Size The number of elements to be returned from the server in one batch
Limit The maximum number of elements to return
Mongo Collection Name The name of the collection to use
Mongo Database Name The name of the database to use
Projection The fields to be returned from the documents in the result set; must be a valid BSON document
Query The selection criteria to do the lookup. If the field is left blank, it will look for input from an incoming connection from another processor to provide the query as a valid JSON document inside of the FlowFile's body. If this field is left blank and a timer is enabled instead of an incoming connection, that will result in a full collection fetch using a "\{\}" query.
Sort The fields by which to sort; must be a valid BSON document
get-mongo-record-writer-factory The record writer to use to write the result sets.
mongo-client-service If configured, this property will use the assigned client service for connection pooling.
mongo-query-attribute If set, the query will be written to a specified attribute on the output flowfiles.
mongodb-schema-name The name of the schema in the configured schema registry to use for the query results.
Name Description
failure All input FlowFiles that are part of a failed query execution go here.
original All input FlowFiles that are part of a successful query execution go here.
success All FlowFiles that have the results of a successful query execution go here.
Name Description
mongo.database.name The database where the results came from.
mongo.collection.name The collection where the results came from.
Property Description
Job ID The ID of the job for which the status is checked.
Salesforce Client Salesforce Client to interact with the APIs
Name Description
comms.failure A FlowFile is routed to this relationship if the Query Job result could not be retrieved but the operation might be retried
failure A FlowFile is routed to this relationship if the Query Job Results could not be retrieved
success If Query Job Results have been successfully retrieved, the FlowFile is routed to this relationship
Property Description
Job ID The ID of the job for which the status is checked.
Salesforce Client Salesforce Client to interact with the APIs
Name Description
comms.failure A FlowFile is routed to this relationship if the Query Job status could not be retrieved but the operation might be retried
failure A FlowFile is routed to this relationship if the Query Job status could not be retrieved
job.aborted If the Query Job has been aborted, the FlowFile is routed to this relationship
job.completed If the Query Job completed, the FlowFile is routed to this relationship
job.failed If the Query Job failed, the FlowFile is routed to this relationship
wait If the Query Job is in the processing queue or in progress, the FlowFile is routed to this relationship
Name Description
jobState The current state of processing for the job.
systemModstamp The UTC date and time when the API last updated the job information.
numberRecordsProcessed The number of records processed in this job.
retries The number of times that Salesforce attempted to save the results of an operation. Repeated attempts indicate a problem such as a lock contention.
totalProcessingTime The number of milliseconds taken to process the job.
isPkChunkingSupported Whether PK chunking is supported for the queried object (true), or isn't supported (false).
Property Description
AWS Credentials Provider service The Controller Service that is used to obtain AWS credentials provider
Bucket The S3 Bucket to interact with
Communications Timeout The amount of time to wait in order to establish a connection to AWS or receive data from AWS before timing out.
Custom Signer Class Name Fully qualified class name of the custom signer class. The signer must implement com.amazonaws.auth. Signer interface.
Custom Signer Module Location Comma-separated list of paths to files and/or directories which contain the custom signer's JAR file and its dependencies (if any).
Endpoint Override URL Endpoint URL to use instead of the AWS default including scheme, host, port, and path. The AWS libraries select an endpoint URL based on the AWS region, but this property overrides the selected endpoint URL, allowing use with other S3-compatible endpoints.
FullControl User List A comma-separated list of Amazon User ID's or E-mail addresses that specifies who should have Full Control for an object
Metadata Attribute Include Pattern A regular expression pattern to use for determining which object metadata entries are included as FlowFile attributes. This pattern is only applied to the 'found' relationship and will not be used to filter the error attributes in the 'failure' relationship.
Metadata Target This determines where the metadata will be written when found.
Object Key The S3 Object Key to use. This is analogous to a filename for traditional file systems.
Owner The Amazon ID to use for the object's owner
Read ACL User List A comma-separated list of Amazon User ID's or E-mail addresses that specifies who should have permissions to read the Access Control List for an object
Read Permission User List A comma-separated list of Amazon User ID's or E-mail addresses that specifies who should have Read Access for an object
Region The AWS Region to connect to.
SSL Context Service Specifies an optional SSL Context Service that, if provided, will be used to create connections
Signer Override The AWS S3 library uses Signature Version 4 by default but this property allows you to specify the Version 2 signer to support older S3-compatible services or even to plug in your own custom signer implementation.
Version The Version of the Object for which to retrieve Metadata
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
failure If the Processor is unable to process a given FlowFile, it will be routed to this Relationship.
found An object was found in the bucket at the supplied key
not found No object was found in the bucket the supplied key
Property Description
AWS Credentials Provider service The Controller Service that is used to obtain AWS credentials provider
Bucket The S3 Bucket to interact with
Communications Timeout The amount of time to wait in order to establish a connection to AWS or receive data from AWS before timing out.
Custom Signer Class Name Fully qualified class name of the custom signer class. The signer must implement com.amazonaws.auth. Signer interface.
Custom Signer Module Location Comma-separated list of paths to files and/or directories which contain the custom signer's JAR file and its dependencies (if any).
Endpoint Override URL Endpoint URL to use instead of the AWS default including scheme, host, port, and path. The AWS libraries select an endpoint URL based on the AWS region, but this property overrides the selected endpoint URL, allowing use with other S3-compatible endpoints.
FullControl User List A comma-separated list of Amazon User ID's or E-mail addresses that specifies who should have Full Control for an object
Object Key The S3 Object Key to use. This is analogous to a filename for traditional file systems.
Owner The Amazon ID to use for the object's owner
Read ACL User List A comma-separated list of Amazon User ID's or E-mail addresses that specifies who should have permissions to read the Access Control List for an object
Read Permission User List A comma-separated list of Amazon User ID's or E-mail addresses that specifies who should have Read Access for an object
Region The AWS Region to connect to.
SSL Context Service Specifies an optional SSL Context Service that, if provided, will be used to create connections
Signer Override The AWS S3 library uses Signature Version 4 by default but this property allows you to specify the Version 2 signer to support older S3-compatible services or even to plug in your own custom signer implementation.
Tag Attribute Include Pattern A regular expression pattern to use for determining which object tags are included as FlowFile attributes. This pattern is only applied to the 'found' relationship and will not be used to filter the error attributes in the 'failure' relationship.
Tags Target This determines where the tags will be written when found.
Version The Version of the Object for which to retrieve Tags
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
failure If the Processor is unable to process a given FlowFile, it will be routed to this Relationship.
found An object was found in the bucket at the supplied key
not found No object was found in the bucket the supplied key
Property Description
Algorithm Negotiation Configuration strategy for SSH algorithm negotiation
Ciphers Allowed A comma-separated list of Ciphers allowed for SFTP connections. Leave unset to allow all. Available options are: 3des-cbc, aes128-cbc, aes128-ctr, [aes128-gcm@openssh.com](mailto:aes128-gcm@openssh.com), aes192-cbc, aes192-ctr, aes256-cbc, aes256-ctr, [aes256-gcm@openssh.com](mailto:aes256-gcm@openssh.com), arcfour128, arcfour256, blowfish-cbc, [chacha20-poly1305@openssh.com](mailto:chacha20-poly1305@openssh.com), none
Connection Timeout Amount of time to wait before timing out while creating a connection
Data Timeout When transferring a file between the local and remote system, this value specifies how long is allowed to elapse without any data being transferred between systems
Delete Original Determines whether or not the file is deleted from the remote system after it has been successfully transferred
File Filter Regex Provides a Java Regular Expression for filtering Filenames; if a filter is supplied, only files whose names match that Regular Expression will be fetched
Follow Symbolic Links If true, will pull even symbolic files and also nested symbolic subdirectories; otherwise, will not read symbolic files and will not traverse symbolic link subdirectories
Host Key File If supplied, the given file will be used as the Host Key; otherwise, if 'Strict Host Key Checking' property is applied (set to true) then uses the 'known_hosts' and 'known_hosts2' files from ~/.ssh directory else no host key file will be used
Hostname The fully qualified hostname or IP address of the remote system
Ignore Dotted Files If true, files whose names begin with a dot (".") will be ignored
Key Algorithms Allowed A comma-separated list of Key Algorithms allowed for SFTP connections. Leave unset to allow all. Available options are: ecdsa-sha2-nistp256, [ecdsa-sha2-nistp256-cert-v01@openssh.com](mailto:ecdsa-sha2-nistp256-cert-v01@openssh.com), ecdsa-sha2-nistp384, [ecdsa-sha2-nistp384-cert-v01@openssh.com](mailto:ecdsa-sha2-nistp384-cert-v01@openssh.com), ecdsa-sha2-nistp521, [ecdsa-sha2-nistp521-cert-v01@openssh.com](mailto:ecdsa-sha2-nistp521-cert-v01@openssh.com), rsa-sha2-256, [rsa-sha2-256-cert-v01@openssh.com](mailto:rsa-sha2-256-cert-v01@openssh.com), rsa-sha2-512, [rsa-sha2-512-cert-v01@openssh.com](mailto:rsa-sha2-512-cert-v01@openssh.com), [sk-ecdsa-sha2-nistp256@openssh.com](mailto:sk-ecdsa-sha2-nistp256@openssh.com), [sk-ssh-ed25519@openssh.com](mailto:sk-ssh-ed25519@openssh.com), ssh-dss, [ssh-dss-cert-v01@openssh.com](mailto:ssh-dss-cert-v01@openssh.com), ssh-ed25519, [ssh-ed25519-cert-v01@openssh.com](mailto:ssh-ed25519-cert-v01@openssh.com), ssh-rsa, [ssh-rsa-cert-v01@openssh.com](mailto:ssh-rsa-cert-v01@openssh.com)
Key Exchange Algorithms Allowed A comma-separated list of Key Exchange Algorithms allowed for SFTP connections. Leave unset to allow all. Available options are: curve25519-sha256, [curve25519-sha256@libssh.org](mailto:curve25519-sha256@libssh.org), curve448-sha512, diffie-hellman-group-exchange-sha1, diffie-hellman-group-exchange-sha256, diffie-hellman-group1-sha1, diffie-hellman-group14-sha1, diffie-hellman-group14-sha256, diffie-hellman-group15-sha512, diffie-hellman-group16-sha512, diffie-hellman-group17-sha512, diffie-hellman-group18-sha512, ecdh-sha2-nistp256, ecdh-sha2-nistp384, ecdh-sha2-nistp521, mlkem1024nistp384-sha384, mlkem768nistp256-sha256, mlkem768x25519-sha256, sntrup761x25519-sha512, [sntrup761x25519-sha512@openssh.com](mailto:sntrup761x25519-sha512@openssh.com)
Max Selects The maximum number of files to pull in a single connection
Message Authentication Codes Allowed A comma-separated list of Message Authentication Codes allowed for SFTP connections. Leave unset to allow all. Available options are: hmac-md5, hmac-md5-96, hmac-sha1, hmac-sha1-96, [hmac-sha1-etm@openssh.com](mailto:hmac-sha1-etm@openssh.com), hmac-sha2-256, [hmac-sha2-256-etm@openssh.com](mailto:hmac-sha2-256-etm@openssh.com), hmac-sha2-512, [hmac-sha2-512-etm@openssh.com](mailto:hmac-sha2-512-etm@openssh.com)
Password Password for the user account
Path Filter Regex When Search Recursively is true, then only subdirectories whose path matches the given Regular Expression will be scanned
Polling Interval Determines how long to wait between fetching the listing for new files
Port The port that the remote system is listening on for file transfers
Private Key Passphrase Password for the private key
Private Key Path The fully qualified path to the Private Key file
Remote Path The path on the remote system from which to pull or push files
Remote Poll Batch Size The value specifies how many file paths to find in a given directory on the remote system when doing a file listing. This value in general should not need to be modified but when polling against a remote system with a tremendous number of files this value can be critical. Setting this value too high can result very poor performance and setting it too low can cause the flow to be slower than normal.
Search Recursively If true, will pull files from arbitrarily nested subdirectories; otherwise, will not traverse subdirectories
Send Keep Alive On Timeout Send a Keep Alive message every 5 seconds up to 5 times for an overall timeout of 25 seconds.
Strict Host Key Checking Indicates whether or not strict enforcement of hosts keys should be applied
Use Compression Indicates whether or not ZLIB compression should be used when transferring files
Use Natural Ordering If true, will pull files in the order in which they are naturally listed; otherwise, the order in which the files will be pulled is not defined
Username Username
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
success All FlowFiles that are received are routed to success
Name Description
filename The filename is set to the name of the file on the remote server
path The path is set to the path of the file's directory on the remote server. For example, if the <Remote Path> property is set to /tmp, files picked up from /tmp will have the path attribute set to /tmp. If the <Search Recursively> property is set to true and a file is picked up from /tmp/abc/1/2/3, then the path attribute will be set to /tmp/abc/1/2/3
file.lastModifiedTime The date and time that the source file was last modified
file.owner The numeric owner id of the source file
file.group The numeric group id of the source file
file.permissions The read/write/execute permissions of the source file
absolute.path The full/absolute path from where a file was picked up. The current 'path' attribute is still populated, but may be a relative path
Property Description
Group ID The ID of the SharePoint group.
OAuth2 Access Token Provider Enables managed retrieval of OAuth2 Bearer Token.
Site URL The URL of the SharePoint site.
Web Client Service The Web Client Service to use for communicating with SharePoint.
Name Description
comms.failure A FlowFile is routed here if the processor failed to communicate with SharePoint. Can be retried
failure A FlowFile is routed here if the group members could not be fetched
success A FlowFile is routed here if the group members were successfully retrieved
Name Description
sharepoint.group.user.ids The IDs of the users in the SharePoint site group.
sharepoint.group.user.emails The emails of the users in the SharePoint site group.
Property Description
CUSTOMERS Customer resource to query
DISCOUNTS Discount resource to query
INVENTORY Inventory resource to query
ONLINE_STORE Online Store resource to query
ORDERS Order resource to query
PRODUCT Product resource to query
SALES_CHANNELS Sales Channel resource to query
STORE_PROPERTIES Store Property resource to query
access-token Access Token to authenticate requests
api-version The Shopify REST API version
incremental-delay The ending timestamp of the time window will be adjusted earlier by the amount configured in this property. For example, with a property value of 10 seconds, an ending timestamp of 12:30:45 would be changed to 12:30:35. Set this property to avoid missing objects when the clock of your local machines and Shopify servers' clock are not in sync.
incremental-initial-start-time This property specifies the start time when running the first request. Represents an ISO 8601-encoded date and time string. For example, 3:50 pm on September 7, 2019 in the time zone of UTC (Coordinated Universal Time) is represented as "2019-09-07T15:50:00Z".
is-incremental The processor can incrementally load the queried objects so that each object is queried exactly once. For each query, the processor queries objects which were created or modified after the previous run time but before the current time.
object-category Shopify object category
result-limit The maximum number of results to request for each invocation of the Processor
store-domain The domain of the Shopify store, e.g. nifistore.myshopify.com
web-client-service-provider Controller service for HTTP client operations
Scopes Description
CLUSTER For a few resources the processor supports incremental loading. The list of the resources with the supported parameters can be found in the additional details.
Name Description
success For FlowFiles created as a result of a successful query.
Name Description
mime.type Sets the MIME type to application/json
Property Description
Batch Size The maximum number of files to pull in each iteration
Directory The network folder to which files should be written. This is the remaining relative path after the share: \hostnameshare[dir1dir2].
Domain The domain used for authentication. Optional, in most cases username and password is sufficient.
File Filter Only files whose names match the given regular expression will be picked up
Hostname The network host to which files should be written.
Ignore Hidden Files Indicates whether or not hidden files should be ignored
Keep Source File If true, the file is not deleted after it has been copied to the Content Repository; this causes the file to be picked up continually and is useful for testing purposes. If not keeping original NiFi will need write permissions on the directory it is pulling from otherwise it will ignore the file.
Password The password used for authentication. Required if Username is set.
Path Filter When Recurse Subdirectories is true, then only subdirectories whose path matches the given regular expression will be scanned
Polling Interval Indicates how long to wait before performing a directory listing
Recurse Subdirectories Indicates whether or not to pull files from subdirectories
Share The network share to which files should be written. This is the "first folder"after the hostname: \hostname[share]dir1dir2
Share Access Strategy Indicates which shared access are granted on the file during the read. None is the most restrictive, but the safest setting to prevent corruption.
Username The username used for authentication. If no username is set then anonymous authentication is attempted.
enable-dfs Enables accessing Distributed File System (DFS) and following DFS links during SMB operations.
smb-dialect The SMB dialect is negotiated between the client and the server by default to the highest common version supported by both end. In some rare cases, the client-server communication may fail with the automatically negotiated dialect. This property can be used to set the dialect explicitly (e.g. to downgrade to a lower version), when those situations would occur.
timeout Timeout for read and write operations.
use-encryption Turns on/off encrypted communication between the client and the server. The property's behavior is SMB dialect dependent: SMB 2.x does not support encryption and the property has no effect. In case of SMB 3.x, it is a hint/request to the server to turn encryption on if the server also supports it.
Name Description
success All files are routed to success
Name Description
filename The filename is set to the name of the file on the network share
path The path is set to the relative path of the file's network share name. For example, if the input is set to \hostnamesharetmp, files picked up from tmp will have the path attribute set to tmp
file.creationTime The date and time that the file was created. May not work on all file systems
file.lastModifiedTime The date and time that the file was last modified. May not work on all file systems
file.lastAccessTime The date and time that the file was last accessed. May not work on all file systems
absolute.path The full path from where a file was picked up. This includes the hostname and the share name
Property Description
API Version Select which version of the Splunk Search API to use for search operations. Version 2 is recommended for newer Splunk instances.
Application The Splunk Application to query.
Connection Timeout Max wait time for connection to the Splunk server.
Earliest Time The value to use for the earliest time when querying. Only used with a Time Range Strategy of Provided. See Splunk's documentation on Search Time Modifiers for guidance in populating this field.
Hostname The ip address or hostname of the Splunk server.
Latest Time The value to use for the latest time when querying. Only used with a Time Range Strategy of Provided. See Splunk's documentation on Search Time Modifiers for guidance in populating this field.
Output Mode The output mode for the results.
Owner The owner to pass to Splunk.
Password The password to authenticate to Splunk.
Port The port of the Splunk server.
Query The query to execute. Typically beginning with a <search> command followed by a search clause, such as <search source="[tcp:7689](tcp:7689)"> to search for messages received on TCP port 7689.
Read Timeout Max wait time for response from the Splunk server.
SSL Context Service The SSL Context Service used to provide client certificate information for TLS/SSL connections.
Scheme The scheme for connecting to Splunk.
Security Protocol The security protocol to use for communicating with Splunk.
Time Field Strategy Indicates whether to search by the time attached to the event, or by the time the event was indexed in Splunk.
Time Range Strategy Indicates how to apply time ranges to each execution of the query. Selecting a managed option allows the processor to apply a time range from the last execution time to the current execution time. When using <Managed from Beginning>, an earliest time will not be applied on the first execution, and thus all records searched. When using <Managed from Current> the earliest time of the first execution will be the initial execution time. When using <Provided>, the time range will come from the Earliest Time and Latest Time properties, or no time range will be applied if these properties are left blank.
Time Zone The Time Zone to use for formatting dates when performing a search. Only used with Managed time strategies.
Token The token to pass to Splunk.
Username The username to authenticate to Splunk.
Scopes Description
CLUSTER If using one of the managed Time Range Strategies, this processor will store the values of the latest and earliest times from the previous execution so that the next execution of the can pick up where the last execution left off. The state will be cleared and start over if the query is changed.
Name Description
success Results retrieved from Splunk are sent out this relationship.
Name Description
splunk.query The query that performed to produce the FlowFile.
splunk.earliest.time The value of the earliest time that was used when performing the query.
splunk.latest.time The value of the latest time that was used when performing the query.
Property Description
AWS Credentials Provider service The Controller Service that is used to obtain AWS credentials provider
Auto Delete Messages Specifies whether the messages should be automatically deleted by the processors once they have been received.
Batch Size The maximum number of messages to send in a single network request
Character Set The Character Set that should be used to encode the textual content of the SQS message
Communications Timeout
Endpoint Override URL Endpoint URL to use instead of the AWS default including scheme, host, port, and path. The AWS libraries select an endpoint URL based on the AWS region, but this property overrides the selected endpoint URL, allowing use with other S3-compatible endpoints.
Queue URL The URL of the queue to get messages from
Receive Message Wait Time The maximum amount of time to wait on a long polling receive call. Setting this to a value of 1 second or greater will reduce the number of SQS requests and decrease fetch latency at the cost of a constantly active thread.
Region
SSL Context Service Specifies an optional SSL Context Service that, if provided, will be used to create connections
Visibility Timeout The amount of time after a message is received but not deleted that the message is hidden from other consumers
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
success FlowFiles are routed to success relationship
Name Description
hash.value The MD5 sum of the message
hash.algorithm MD5
sqs.message.id The unique identifier of the SQS message
sqs.receipt.handle The SQS Receipt Handle that is to be used to delete the message from the queue
Property Description
Databricks Client Databricks Client Service.
Unity Catalog File Path Unity Catalog file path e.g. /Volumes/catalog/schema/volume_name/file.txt
Name Description
failure Databricks failure relationship
success Databricks success relationship
Name Description
error.code The error code for the SQL statement if an error occurred.
error.message The error message for the SQL statement if an error occurred.
Property Description
Databricks Client Databricks Client Service.
Unity Catalog File Path Unity Catalog file path e.g. /Volumes/catalog/schema/volume_name/file.txt
Name Description
failure Databricks failure relationship
not.found The original FlowFile is transferred to this relationship if no Unity Catalog can be found at the specified path
success Databricks success relationship
Name Description
mime.type The content type of the checked file.
uc.size The size of the Unity Catalog file.
uc.lastModifiedTime The last modified time of the Unity Catalog file in milliseconds since epoch in UTC time.
error.code The error code for the SQL statement if an error occurred.
error.message The error message for the SQL statement if an error occurred.
Property Description
Access Token Provider Enables managed retrieval of OAuth2 Bearer Token.
Authorization Type The type of authorization for retrieving data from Workday resources.
Web Client Service Provider Web client which is used to communicate with the Workday API.
Workday Password The password provided for authentication of Workday requests. Encoded using Base64 for HTTP Basic Authentication as described in RFC 7617.
Workday Report URL HTTP remote URL of Workday report including a scheme of http or https, as well as a hostname or IP address with optional port and path elements.
Workday Username The username provided for authentication of Workday requests. Encoded using Base64 for HTTP Basic Authentication as described in RFC 7617.
record-reader Specifies the Controller Service to use for parsing incoming data and determining the data's schema.
record-writer The Record Writer to use for serializing Records to an output FlowFile.
Name Description
failure Request FlowFiles transferred when receiving socket communication errors.
original Request FlowFiles transferred when receiving HTTP responses with a status code between 200 and 299.
success Response FlowFiles transferred when receiving HTTP responses with a status code between 200 and 299.
Name Description
getworkdayreport.java.exception.class The Java exception class raised when the processor fails
getworkdayreport.java.exception.message The Java exception message raised when the processor fails
mime.type Sets the mime.type attribute to the MIME Type specified by the Source / Record Writer
record.count The number of records in an outgoing FlowFile. This is only populated on the 'success' relationship when Record Reader and Writer is set.
Property Description
web-client-service-provider Controller service for HTTP client operations.
zendesk-authentication-type-name Type of authentication to Zendesk API.
zendesk-authentication-value-name Password or authentication token for Zendesk login user.
zendesk-export-method Method for incremental export.
zendesk-query-start-timestamp Initial timestamp to query Zendesk API from in Unix timestamp seconds format.
zendesk-resource The particular Zendesk resource which is meant to be exported.
zendesk-subdomain Name of the Zendesk subdomain.
zendesk-user Login user to Zendesk subdomain.
Scopes Description
CLUSTER Paging cursor for Zendesk API is stored. Cursor is updated after each successful request.
Name Description
success For FlowFiles created as a result of a successful HTTP request.
Name Description
record.count The number of records fetched by the processor.
Display Name API Name Default Value Allowable Values Description
Grok Expressions * Grok Expression Specifies the format of a log line in Grok format. This allows the Record Reader to understand how to parse each log line. The property supports one or more Grok expressions. The Reader attempts to parse input lines according to the configured order of the expressions.If a line in the log file does not match any expressions, the line will be assumed to belong to the previous log message.If other Grok patterns are referenced by this expression, they need to be supplied in the Grok Pattern File property.
Grok Patterns Grok Pattern File Grok Patterns to use for parsing logs. If not specified, a built-in default Pattern file will be used. If specified, all patterns specified will override the default patterns. See the Controller Service's Additional Details for a list of pre-defined patterns.
Schema Access Strategy * Schema Access Strategy string-fields-from-grok-expression - Use String Fields From Grok Expression - Use 'Schema Name' Property - Use 'Schema Text' Property - Schema Reference Reader Specifies how to obtain the schema that is to be used for interpreting the data.
Schema Branch Schema Branch Specifies the name of the branch to use when looking up the schema in the Schema Registry property. If the chosen Schema Registry does not support branching, this value will be ignored.
Schema Name Schema Name $\{schema.name\} Specifies the name of the schema to lookup in the Schema Registry property
Schema Reference Reader * Schema Reference Reader Service implementation responsible for reading FlowFile attributes or content to determine the Schema Reference Identifier
Schema Registry Schema Registry Specifies the Controller Service to use for the Schema Registry
Schema Text Schema Text $\{avro.schema\} The text of an Avro-formatted Schema
Schema Version Schema Version Specifies the version of the schema to lookup in the Schema Registry. If not specified then the latest version of the schema will be retrieved.
No Match Behavior * no-match-behavior append-to-previous-message - Append to Previous Message - Skip Line - Raw Line If a line of text is encountered and it does not match the given Grok Expression, and it is not part of a stack trace, this property specifies how the text should be processed.
Required Permission Explanation
reference remote resources Patterns and Expressions can reference resources over HTTP
Processor type Java processor Python processor
Runtime environment JVM internal threads External OS process
Memory management Managed within JVM heap Separate process memory
Lifecycle NiFi-controlled External process lifecycle
Monitoring Full NiFi observability Limited visibility
Runtime size Python support Notes
Small Not supported Python processors are blocked on Small runtimes due to CPU and memory constraints.
Medium Limited (up to 2 Python processors) The limit is for the entire runtime, not per connector or process group. This limit is currently a recommendation that will be an enforced maximum value for Openflow runtimes in the future.
Large Limited (up to 4 Python processors) The limit is for the entire runtime, not per connector or process group. This limit is currently a recommendation that will be an enforced maximum value for Openflow runtimes in the future.
Property Description
Additional HTTP Methods A comma-separated list of non-standard HTTP Methods that should be allowed
Allow DELETE Allow HTTP DELETE Method
Allow GET Allow HTTP GET Method
Allow HEAD Allow HTTP HEAD Method
Allow OPTIONS Allow HTTP OPTIONS Method
Allow POST Allow HTTP POST Method
Allow PUT Allow HTTP PUT Method
Allowed Paths A Regular Expression that specifies the valid HTTP Paths that are allowed in the incoming URL Requests. If this value is specified and the path of the HTTP Requests does not match this Regular Expression, the Processor will respond with a 404: NotFound
Client Authentication Specifies whether or not the Processor should authenticate clients. This value is ignored if the <SSL Context Service> Property is not specified or the SSL Context provided uses only a KeyStore and not a TrustStore.
Default URL Character Set The character set to use for decoding URL parameters if the HTTP Request does not supply one
HTTP Context Map The HTTP Context Map Controller Service to use for caching the HTTP Request Information
HTTP Protocols HTTP Protocols supported for Application Layer Protocol Negotiation with TLS
Hostname The Hostname to bind to. If not specified, will bind to all hosts
Listening Port The Port to listen on for incoming HTTP requests
Maximum Threads The maximum number of threads that the embedded HTTP server will use for handling requests.
Request Header Maximum Size The maximum supported size of HTTP headers in requests sent to this processor
SSL Context Service The SSL Context Service to use in order to secure the server. If specified, the server will accept only HTTPS requests; otherwise, the server will accept only HTTP requests
container-queue-size The size of the queue for Http Request Containers
multipart-read-buffer-size The threshold size, at which the contents of an incoming file would be written to disk. Only applies for requests with Content-Type: multipart/form-data. It is used to prevent denial of service type of attacks, to prevent filling up the heap or disk space.
multipart-request-max-size The max size of the request. Only applies for requests with Content-Type: multipart/form-data, and is used to prevent denial of service type of attacks, to prevent filling up the heap or disk space
parameters-to-attributes A comma-separated list of HTTP parameters or form data to output as attributes
Name Description
success All content that is received is routed to the 'success' relationship
Name Description
http.context.identifier An identifier that allows the HandleHttpRequest and HandleHttpResponse to coordinate which FlowFile belongs to which HTTP Request/Response.
mime.type The MIME Type of the data, according to the HTTP Header "Content-Type"
http.servlet.path The part of the request URL that is considered the Servlet Path
http.context.path The part of the request URL that is considered to be the Context Path
http.method The HTTP Method that was used for the request, such as GET or POST
http.local.name IP address/hostname of the server
http.server.port Listening port of the server
http.query.string The query string portion of the Request URL
http.remote.host The hostname of the requestor
http.remote.addr The hostname:port combination of the requestor
http.remote.user The username of the requestor
http.protocol The protocol used to communicate
http.request.uri The full Request URL
http.auth.type The type of HTTP Authorization used
http.principal.name The name of the authenticated user making the request
http.query.param.XXX Each of query parameters in the request will be added as an attribute, prefixed with "http.query.param."
http.param.XXX Form parameters in the request that are configured by "Parameters to Attributes List" will be added as an attribute, prefixed with "http.param.". Putting form parameters of large size is not recommended.
http.subject.dn The Distinguished Name of the requestor. This value will not be populated unless the Processor is configured to use an SSLContext Service
http.issuer.dn The Distinguished Name of the entity that issued the Subject's certificate. This value will not be populated unless the Processor is configured to use an SSLContext Service
http.certificate.sans.N.name X.509 Client Certificate Subject Alternative Name value from mutual TLS authentication. The attribute name has a zero-based index ordered according to the content of Client Certificate
http.certificate.sans.N.nameType X.509 Client Certificate Subject Alternative Name type from mutual TLS authentication. The attribute name has a zero-based index ordered according to the content of Client Certificate. The attribute value is one of the General Names from RFC 3280 Section 4.1.2.7
http.headers.XXX Each of the HTTP Headers that is received in the request will be added as an attribute, prefixed with "http.headers." For example, if the request contains an HTTP Header named "x-my-header", then the value will be added to an attribute named "http.headers.x-my-header"
http.headers.multipart.XXX Each of the HTTP Headers that is received in the multipart request will be added as an attribute, prefixed with "http.headers.multipart." For example, if the multipart request contains an HTTP Header named "content-disposition", then the value will be added to an attribute named "http.headers.multipart.content-disposition"
http.multipart.size For requests with Content-Type "multipart/form-data", the part's content size is recorded into this attribute
http.multipart.content.type For requests with Content-Type "multipart/form-data", the part's content type is recorded into this attribute
http.multipart.name For requests with Content-Type "multipart/form-data", the part's name is recorded into this attribute
http.multipart.filename For requests with Content-Type "multipart/form-data", when the part contains an uploaded file, the name of the file is recorded into this attribute. Files are stored temporarily at the default temporary-file directory specified in "java.io.File" Java Docs)
http.multipart.fragments.sequence.number For requests with Content-Type "multipart/form-data", the part's index is recorded into this attribute. The index starts with 1.
http.multipart.fragments.total.number For requests with Content-Type "multipart/form-data", the count of all parts is recorded into this attribute.
Property Description
Attributes to add to the HTTP Response (Regex) Specifies the Regular Expression that determines the names of FlowFile attributes that should be added to the HTTP response
HTTP Context Map The HTTP Context Map Controller Service to use for caching the HTTP Request Information
HTTP Status Code The HTTP Status Code to use when responding to the HTTP Request. See Section 10 of RFC 2616 for more information.
Name Description
failure FlowFiles will be routed to this Relationship if the Processor is unable to respond to the requestor. This may happen, for instance, if the connection times out or if NiFi is restarted before responding to the HTTP Request.
success FlowFiles will be routed to this Relationship after the response has been successfully sent to the requestor
Display Name API Name Default Value Allowable Values Description
Hazelcast Cache Manager * hazelcast-cache-manager A Hazelcast Cache Manager which manages connections to Hazelcast and provides cache instances.
Hazelcast Cache Name * hazelcast-cache-name The name of a given cache. A Hazelcast cluster may handle multiple independent caches, each identified by a name. Clients using caches with the same name are working on the same data structure within Hazelcast.
Hazelcast Entry Lifetime * hazelcast-entry-ttl 5 min Indicates how long the written entries should exist in Hazelcast. Setting it to '0 secs' means that the data will exist until its deletion or until the Hazelcast server is shut down. Using _EmbeddedHazelcastCacheManager_ as cache manager will not provide policies to limit the size of the cache.
Display Name API Name Default Value Allowable Values Description
Database Connection URL * hikaricp-connection-url A database connection URL used to connect to a database. May contain database system name, host, port, database name and some parameters. The exact syntax of a database connection URL is specified by your DBMS.
Database Driver Class Name * hikaricp-driver-classname The fully-qualified class name of the JDBC driver. Example: com.mysql.jdbc.Driver
Database Driver Location(s) hikaricp-driver-locations Comma-separated list of files/folders and/or URLs containing the driver JAR and its dependencies (if any). For example '/var/tmp/mariadb-java-client-1.1.7.jar'
Kerberos User Service hikaricp-kerberos-user-service Specifies the Kerberos User Controller Service that should be used for authenticating with Kerberos
Max Connection Lifetime hikaricp-max-conn-lifetime -1 The maximum lifetime of a connection. After this time is exceeded the connection will fail the next activation, passivation or validation test. A value of zero or less means the connection has an infinite lifetime.
Max Total Connections * hikaricp-max-total-conns 10 This property controls the maximum size that the pool is allowed to reach, including both idle and in-use connections. Basically this value will determine the maximum number of actual connections to the database backend. A reasonable value for this is best determined by your execution environment. When the pool reaches this size, and no idle connections are available, the service will block for up to connectionTimeout milliseconds before timing out.
Max Wait Time * hikaricp-max-wait-time 500 millis The maximum amount of time that the pool will wait (when there are no available connections) for a connection to be returned before failing, or 0 <time units> to wait indefinitely.
Minimum Idle Connections * hikaricp-min-idle-conns 10 This property controls the minimum number of idle connections that HikariCP tries to maintain in the pool. If the idle connections dip below this value and total connections in the pool are less than 'Max Total Connections', HikariCP will make a best effort to add additional connections quickly and efficiently. It is recommended that this property to be set equal to 'Max Total Connections'.
Password hikaricp-password The password for the database user
Database User hikaricp-username Database user name
Validation Query hikaricp-validation-query Validation Query used to validate connections before returning them. When connection is invalid, it gets dropped and new valid connection will be returned. NOTE: Using validation might have some performance penalty.
Required Permission Explanation
reference remote resources Database Driver Location can reference resources over HTTP
Display Name API Name Default Value Allowable Values Description
API URL * API URL The URL which receives the HTTP requests.
Maximum Batch Size * Maximum Batch Size 0 Specifies the maximum number of records to send in the body of each HTTP request. Zero means the batch size is not limited, and all records are sent together in a single HTTP request.
OAuth2 Access Token Provider OAuth2 Access Token Provider OAuth2 service that provides the access tokens for the HTTP requests.
Web Service Client Provider * Web Service Client Provider Controller service to provide the HTTP client for sending the HTTP requests.
Record Writer * record-sink-record-writer Specifies the Controller Service to use for writing out the records.
Property Description
Custom MIME Configuration A URL or file path to a custom Tika Mime type configuration or the actual content of a custom Tika Mime type configuration.
config-strategy Select the loading strategy for MIME Type configuration to be used.
use-filename-in-detection If true will pass the filename to Tika to aid in detection.
Name Description
success All FlowFiles are routed to success
Name Description
mime.type This Processor sets the FlowFile's mime.type attribute to the detected MIME Type. If unable to detect the MIME Type, the attribute's value will be set to application/octet-stream
mime.extension This Processor sets the FlowFile's mime.extension attribute to the file extension associated with the detected MIME Type. If there is no correlated extension, the attribute's value will be empty
mime.charset This Processor sets the FlowFile's mime.charset attribute to the detected charset. If unable to detect the charset or the detected MIME type is not of type text/*, the attribute will not be set
Parameter Description Required
Destination Database The database where data is persisted. It must already exist in Snowflake and the connector's role must have `USAGE` and `CREATE SCHEMA` on it. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. Yes
Destination Schema Pattern A pattern for the names of destination schemas where data is persisted. The connector creates the schemas if they don't exist. You can customize the pattern per ingested table using these optional variables: - `${source.database.name}`: a source table's database. - `${source.schema.name}`: a source table's schema. - `${source.table.name}`: a source table's name. For example, for a table with the qualified name `source_db.tenant_a.data`, the pattern `prefix_${source.database.name}_${source.schema.name}` evaluates to `prefix_source_db_tenant_a`. To ingest all tables into a single schema, provide a schema name without any variables, like `destination_schema`. Don't change this setting after the connector has begun ingesting data. Changing this setting after ingestion has begun breaks the existing ingestion. If you must change this setting, create a new connector instance. Yes
Snowflake Authentication Strategy When using: - **Snowflake Openflow Deployment** or **BYOC**: Use SNOWFLAKE_MANAGED. This token is managed automatically by Snowflake. BYOC deployments must have previously configured [execute-as roles](#label-deployment-byoc-setup-runtime-role) to use SNOWFLAKE_MANAGED. - **BYOC**: Alternatively, BYOC can use KEY_PAIR as the value for the authentication strategy. Yes
Snowflake Account Identifier When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Snowflake account name formatted as [organization-name]-[account-name]. Yes
Snowflake Connection Strategy When using KEY_PAIR, specify the strategy for connecting to Snowflake: - **STANDARD** (default): Connect using standard public routing to Snowflake services. - **PRIVATE_CONNECTIVITY**: Connect using private addresses associated with the supporting cloud platform such as AWS PrivateLink. Required for BYOC with KEY_PAIR only, otherwise ignored.
Snowflake Private Key When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank.
**KEY_PAIR**: Must be the RSA private key used for authentication.
The RSA key must be formatted according to PKCS8 standards and have standard PEM headers and footers. Note that either a Snowflake Private Key File or a Snowflake Private Key must be defined.
No
Snowflake Private Key File When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: The private key file must be blank. - **KEY_PAIR**: Upload the file that contains the RSA private key used for authentication to Snowflake, formatted according to PKCS8 standards and including standard PEM headers and footers. The header line begins with `-----BEGIN PRIVATE`. To upload the private key file, select the **Reference asset** checkbox. No
Snowflake Private Key Password When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the password associated with the Snowflake Private Key File. No
Snowflake Role When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Use the runtime's execute-as role (or a child role granted to it). You can find your execute-as role in the Openflow UI by navigating to **View Details** for your runtime. - **KEY_PAIR**: Use a valid role configured for your service user. Yes
Snowflake Username When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the username used to connect to the Snowflake instance. Yes
Oversized Value Strategy Determines how the connector handles values that exceed its internal size limits (16 MB) during replication. Possible values are:
- **Fail Table** (default): The table is marked as permanently failed, and replication stops for that table. - **Set Null**: The value is replaced with `NULL` in the destination table. Use this to prevent table failures when it is acceptable to lose data in tables beyond the oversized value.
No
Error Handling Strategy Determines how the connector handles invalid rows that Snowflake rejects during ingestion. Possible values are:
- **Fail Table** (default): The table is marked as failed on the first invalid row, and replication stops for that table. - **Log Errors and Continue** : The connector keeps replicating the valid rows and records each rejected row in the table's error table.
No
Table Storage Format Standard Snowflake tables or Iceberg tables. Defaults to **STANDARD**. Don't change after the connector starts. Yes
Iceberg Version The Iceberg table version, 2 or 3 (default 3). Ignored unless Table Storage Format is **ICEBERG**. Don't change this value after ingestion begins. No
Snowflake Warehouse Snowflake warehouse used to run merge queries. Start with `XSMALL`; for many tables, a multi-cluster warehouse scales better than a larger size. Yes
Parameter Description
Included Table Names Comma-separated list of fully-qualified table paths. Tables must be specified using fully-qualified database, schema, and table name format: DATABASE_NAME.SCHEMA_NAME.TABLE_NAME. For example: `MYPDB.SALES.CUSTOMERS, MYPDB.SALES.ORDERS`
Included Table Regex A regular expression to match table paths for automatic inclusion of existing and new tables. The regex pattern must match the three-part naming convention: DATABASE_NAME.SCHEMA_NAME.TABLE_NAME. For example: `MYPDB\.SALES\..*` to match all tables in the SALES schema within the MYPDB database.
Column Filter JSON Optional. A JSON array of filter objects specifying which columns to include or exclude per table. For syntax details and examples, see [Replicate a subset of columns in a table](#replicate-a-subset-of-columns-in-a-table).
Table Key Configuration Service Optional. A `MultiDatabaseJsonTableKeyConfigService` controller service that supplies a user-declared logical key for one or more tables. The service exposes a **Table Key Configuration JSON** property where you define the key mappings. When configured, the logical key takes the highest priority and overrides any primary key, unique constraint, or unique index that the connector would otherwise auto-detect. For more information on when to use this and how to configure it, see [](#label-oracle-logical-key).
Merge Task Schedule CRON CRON expression defining periods when merge operations from Journal to Destination Table will be triggered. Set it to `* * * * * ?` if you want continuous merges, or configure a time schedule to limit warehouse run time. The connector evaluates the schedule in the UTC time zone. For example:
- The string `* 0 * * * ?` indicates that you want to schedule merges at the full hour for one minute. - The string `* 20 14 ? * MON-FRI` indicates that you want to schedule merges at 2:20 PM every Monday through Friday.
For additional information and examples, see the cron triggers tutorial in the Quartz Documentation (https://www.quartz-scheduler.org/documentation/quartz-2.5.x/tutorials/crontrigger.html).
Object Identifier Resolution Specifies how source object identifiers such as schemas, tables, and column names are stored and queried in Snowflake. This setting determines if you must use double quotes in SQL queries.

Option 1: Default, case-insensitive (recommended).

- **Transformation**: All identifiers are converted to uppercase. For example, `My_Table` becomes `MY_TABLE`. - **Queries**: SQL queries are case-insensitive and don't require SQL double quotes. For example `SELECT * FROM my_table;` returns the same results as `SELECT * FROM MY_TABLE;`. Snowflake recommends using this option if database objects aren't expected to have mixed case names.

Option 2: Case-sensitive.

- **Transformation**: Case is preserved. For example, `My_Table` remains `My_Table`. - **Queries**: SQL queries must use double quotes to match the exact case for database objects. For example, `SELECT * FROM "My_Table";`. Do not change this setting after connector ingestion has begun. Changing this setting after ingestion has begun breaks the existing ingestion. If you must change this setting, create a new connector instance.
Snapshot Fetching Strategy Determines the snapshot load fetching strategy: - **CONCURRENT_BY_ROWID** (default): Splits tables into chunks bound by ranges of physical row ids, and retrieves each chunk in parallel. This strategy isn't currently supported when the connector reads from a read-only database like Active Data Guard physical standby. - **SEQUENTIAL_BY_PRIMARY_KEY**: Uses fixed-size batches retrieved sequentially by the table's replication key (primary key, unique constraint, unique index, or logical key). Despite the name, this strategy uses whatever key the connector resolved for the table, not specifically the primary key.
Concurrent Snapshot Queries Maximum number of concurrent queries to the source database to run in the Snapshot flow. Increasing this can speed up snapshotting large numbers of tables, but will also increase the load on the source database.
Parameter Description Required
Oracle Connection URL JDBC URL of the database connection to the DB. The URL must specify the target container (PDB or CDB) that contains the data to be replicated. For example `jdbc:oracle:thin:@:/YOUR_DB_NAME` where YOUR_DB_NAME is the name of your PDB or CDB. When SSL is enabled, use the TCPS protocol, for example `jdbc:oracle:thin:@tcps://:/YOUR_DB_NAME`. The connector works within a single database/container. Ensure the JDBC URL points directly to the container that holds the tables to be replicated. Yes
Oracle Username Username of the connect user that has access to the XStream Server. Yes
Oracle Password Password of the connect user that has access to the XStream Server. Yes
Oracle SSL Mode Controls SSL encryption for connections to the Oracle database. - **DISABLED**, which is the default: Connect without SSL. - **VERIFY_CA**: Connect with SSL. Verifies that a trusted Certificate Authority issued the server certificate. - **VERIFY_IDENTITY**: Connect with SSL. Verifies the CA certificate and that the server hostname matches the certificate's subject. When set to VERIFY_CA or VERIFY_IDENTITY, you must also provide the Oracle Wallet Filename parameter. Yes
Oracle Wallet Filename Upload the file that contains the Oracle auto-login wallet file (`cwallet.sso`). The wallet must contain the trusted server certificate for SSL connections. For information about creating the wallet, see [](#label-configure-ssl-connections). Required when SSL Mode is not DISABLED
Oracle Database Processor Multiplier Core Processor Licensing Factor as described in Oracle Processor Core Factor Table (https://www.oracle.com/contracts/docs/processor-core-factor-table-070634.pdf). Required for Embedded License only
Oracle Database Processor Cores The number of processor cores in your Oracle database. Required for Embedded License only
XStream Billing Acknowledgement A confirmation of the licensing agreement. Required for Embedded License only
XStream Out Server Name The name of the XStream Server that must already exist in Oracle. Yes
XStream Out Server URL JDBC URL of the database connection for XStream, which must use the OCI driver. For example `jdbc:oracle:oci:@:/SID`. When SSL is enabled, use the TCPS protocol, for example `jdbc:oracle:oci:@tcps://:/SID`. When SSL Mode is enabled, the connector automatically adds `SSL_SERVER_DN_MATCH` and `MY_WALLET_DIRECTORY` to the XStream URL. You don't need to include these manually. Yes
" | "tablePattern": "", "included": ["", ""], "excluded": ["", ""], "includedPattern": "", "excludedPattern": "" } ] ``` The following rules apply: - Use `database`, `schema`, and `table` for exact name matching, or `databasePattern`, `schemaPattern`, and `tablePattern` for regex matching. You can't use both a field and its pattern variant in the same object (for example, `schema` and `schemaPattern` can't both appear). - At least one of `included`, `excluded`, `includedPattern`, or `excludedPattern` must be provided. - When both included and excluded filters are specified, exclusions take precedence. - When multiple filters match the same table, the last matching filter is used, with exact matches taking precedence over pattern-based filters. - The value can be an array of objects to apply different filters to different tables. ## Examples Include specific columns by name: ```javascript [ { "database": "my_db", "schema": "dbo", "table": "orders", "included": ["account_id", "status", "created_at"] } ] ``` Exclude specific columns by name: ```javascript [ { "database": "my_db", "schema": "dbo", "table": "orders", "excluded": ["internal_note", "debug_flag"] } ] ``` Combine an include pattern with a specific exclusion (for example, include all email columns except `admin_email`): ```javascript [ { "database": "my_db", "schema": "dbo", "table": "contacts", "includedPattern": ".*_email", "excluded": ["admin_email"] } ] ``` Mix a database pattern with an exact schema and table name to apply a filter across databases: ```javascript [ { "databasePattern": "prod_.*", "schema": "dbo", "table": "customers", "excluded": ["internal_note"] } ] ``` Pass multiple filter objects to apply different rules to different tables: ```javascript [ {"database": "my_db", "schema": "dbo", "table": "orders", "included": ["account_id", "status"]}, {"database": "my_db", "schema": "dbo", "table": "customers", "excludedPattern": ".*_internal"} ] ``` ### Including and excluding the same column Removing a column from a table's replicated set (by excluding it or by removing it from the included list) has the same effect on the destination as dropping the column at the source: the connector soft-deletes the column on the destination by renaming it with a suffix (by default, `__SNOWFLAKE_DELETED`). If you then add the column back to the replicated set and later remove it a second time, replication for the affected table fails because the soft-deleted column name is already taken. To recover, restart replication for the affected table. ## Specify a logical key for a table The connector requires a replication key for every table it replicates. By default, the connector picks the replication key automatically, in this order: a primary key, then a qualifying unique constraint, then a qualifying unique index. For the full selection rules, see [](#label-oracle-replication-key-selection). A *logical key* is a user-declared replacement for the auto-detected key. Configure a logical key when: - A table has no primary key and no qualifying unique constraint or unique index, but one or more columns are unique in the data. - A specific column or set of columns should be used as the replication key, regardless of what the connector would auto-detect (for example, to override a synthetic primary key). A logical key takes the highest priority. When the connector finds a logical key for a table, it uses that key and ignores any primary key, unique constraint, or unique index on the table. ### JSON syntax The **Table Key Configuration JSON** value is a JSON array. Each entry maps one table to its logical key columns: ```json [ { "database": "", "schema": "", "table": "
", "logicalKey": ["", ""] } ] ``` The fields are:
The following rules apply: - `database`, `schema`, and `table` matching is **case-sensitive**. Oracle stores identifiers in uppercase by default, so use uppercase names unless the identifiers were created with double-quoted mixed-case or lowercase names. - `logicalKey` column matching is case-insensitive. The connector matches column names against the source table schema regardless of case. - An entry whose `database`, `schema`, and `table` don't match any replicated table is silently ignored. ### Logical key configuration examples A single-column logical key on a table without a primary key: ```json [ { "database": "MYPDB", "schema": "SALES", "table": "AUDIT_LOG", "logicalKey": ["EVENT_ID"] } ] ``` A composite logical key: ```json [ { "database": "MYPDB", "schema": "SALES", "table": "ORDER_LINES", "logicalKey": ["ORDER_ID", "LINE_ITEM_ID"] } ] ``` Logical keys for several tables in one JSON value: ```json [ { "database": "MYPDB", "schema": "SALES", "table": "AUDIT_LOG", "logicalKey": ["EVENT_ID"] }, { "database": "MYPDB", "schema": "SALES", "table": "ORDER_LINES", "logicalKey": ["ORDER_ID", "LINE_ITEM_ID"] } ] ``` ### Restrictions The connector rejects the configuration when any of the following is true: - `logicalKey` is missing, empty, or not an array. - `logicalKey` contains duplicate column names (compared case-insensitively). - `logicalKey` contains the pseudo-column `ROWID`. `ROWID` isn't a reliable replication key because it can change when a row is moved (for example, after a table rebuild or partition operation). - `logicalKey` contains a column name that doesn't exist in the source table. When the configuration is rejected, the connector either fails to enable the controller service (for structural issues detected at enablement time) or holds the table in the `NEW` state (for issues detected when the table is initialized). After you fix the configuration, replication for the table resumes without resetting state. ### Warnings logged for risky configurations The connector accepts the following configurations but logs a warning at table initialization. Verify the data carefully or arrange a periodic full reload to correct drift. When choosing logical-key columns, prefer columns with high cardinality and, where possible, monotonically increasing values. Low-cardinality or non-monotonic keys can degrade snapshot performance if you use the `SEQUENTIAL_BY_PRIMARY_KEY` strategy, which orders rows by the replication key. - A logical-key column is a large-object type (`BLOB`, `CLOB`, `NCLOB`, `LONG`, `LONG RAW`). Using large objects as keys severely degrades MERGE performance. - A logical-key column is a floating-point type (`FLOAT`, `DOUBLE`, `REAL`, `BINARY_FLOAT`, `BINARY_DOUBLE`). Floating-point comparisons can produce inconsistent results because of precision differences. - The composite logical key has more than five columns. Long composite keys often indicate a design issue and might degrade MERGE performance. - The logical key replaces an existing primary key on the table. ### Limitation: Changes to a logical-key value When a source `UPDATE` changes the value of a logical-key column, the connector does **not** soft-delete the row keyed by the old value before inserting the row keyed by the new value. The destination table ends up with two active rows for what's a single row in the source: the original row, still active under its old key value, and a new row under the new key value. This differs from how the connector handles a primary-key value change on tables that don't use a logical key. For more information on that behavior, see [](#label-oracle-replication-key-value-change). To avoid this limitation, choose logical-key columns whose values don't change in the source. If logical-key values do change, periodically run a full reload for the affected tables to reconcile the destination with the source. ### Schema changes that affect a logical key Logical keys reference column names. The connector doesn't follow renames or drops of those columns: - If a logical-key column is dropped on the source, replication for the affected table fails. The table is marked `FAILED`. For recovery steps, see [](#label-oracle-logical-key-invalidated) in the troubleshooting topic. - If a logical-key column is renamed on the source, the configuration still references the old name and replication fails. Update the JSON to use the new name and restart table replication. ## Configure scheduling of merge tasks The connector uses a warehouse to merge change data capture (CDC) data into destination tables. The processor named Merge Journal to Destination triggers this operation. When there are no new changes, or when no new FlowFiles are waiting in the Merge Journal to Destination queue, no merge is triggered and the warehouse is available for auto-suspension. To limit warehouse cost and restrict merges to scheduled times, use the CRON expression in the Merge Task Schedule CRON parameter. It throttles the FlowFiles that reach the Merge Journal to Destination processor, so merges are triggered only during the specified period. The connector evaluates the schedule in the UTC time zone. For additional information and examples, see the cron triggers tutorial in the Quartz Documentation (https://www.quartz-scheduler.org/documentation/quartz-2.5.x/tutorials/crontrigger.html). ## Run the flow 1. Right-click on the plane and select **Enable all Controller Services**. 2. Right-click on the imported process group and select **Start**. The connector starts the data ingestion. ## Next steps - (Optional) [Set up incremental replication without snapshots](/user-guide/data-integration/openflow/connectors/oracle/incremental-replication). - [Monitor the flow](/user-guide/data-integration/openflow/monitor). --- title: InvokeHTTP 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/invokehttp.md section: Loading & Unloading Data --- # InvokeHTTP 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description An HTTP client processor which can interact with a configurable HTTP Endpoint. The destination URL and HTTP Method are configurable. When the HTTP Method is PUT, POST or PATCH, the FlowFile contents are included as the body of the request and FlowFile attributes are converted to HTTP headers, optionally, based on configuration properties. ## Tags client, http, https, rest ## Input Requirement ALLOWED ## Supports Sensitive Dynamic Properties true ## Properties
## Relationships
## Writes attributes
--- title: InvokeScriptedProcessor 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/invokescriptedprocessor.md section: Loading & Unloading Data --- # InvokeScriptedProcessor 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-scripting-nar ## Description Experimental - Invokes a script engine for a Processor defined in the given script. The script must define a valid class that implements the Processor interface, and it must set a variable 'processor' to an instance of the class. Processor methods such as onTrigger() will be delegated to the scripted Processor instance. Also any Relationships or PropertyDescriptors defined by the scripted processor will be added to the configuration dialog. The scripted processor can implement public void setLogger(ComponentLog logger) to get access to the parent logger, as well as public void onScheduled(ProcessContext context) and public void onStopped(ProcessContext context) methods to be invoked when the parent InvokeScriptedProcessor is scheduled or stopped, respectively. NOTE: The script will be loaded when the processor is populated with property values, see the Restrictions section for more security implications. Experimental: Impact of sustained usage not yet verified. ## Tags groovy, invoke, script ## Input Requirement ## Supports Sensitive Dynamic Properties true ## Properties
## State management
## Restrictions
## See also - [org.apache.nifi.processors.script.ExecuteScript](/user-guide/data-integration/openflow/processors/executescript) --- title: IPLookupService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/iplookupservice.md section: Loading & Unloading Data --- # IPLookupService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description A lookup service that provides several types of enrichment information for IP addresses. The service is configured by providing a MaxMind Database file and specifying which types of enrichment should be provided for an IP Address or Hostname. Each type of enrichment is a separate lookup, so configuring the service to provide all of the available enrichment data may be slower than returning only a portion of the available enrichments. In order to use this service, a lookup must be performed using key of 'ip' and a value that is a valid IP address or hostname. View the Usage of this component and choose to view Additional Details for more information, such as the Schema that pertains to the information that is returned. ## Tags anonymous, cellular, domain, enrich, geo, ip, ipgeo, isp, lookup, maxmind, tor ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: ISPEnrichIP 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/ispenrichip.md section: Loading & Unloading Data --- # ISPEnrichIP 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-enrich-nar ## Description Looks up ISP information for an IP address and adds the information to FlowFile attributes. The ISP data is provided as a MaxMind ISP database. (Note that this is NOT the same as the GeoLite database utilized by some geo enrichment tools). The attribute that contains the IP address to lookup is provided by the 'IP Address Attribute' property. If the name of the attribute provided is 'X', then the attributes added by enrichment will take the form X.isp.<fieldName> ## Tags ISP, enrich, ip, maxmind ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: JettyWebSocketClient source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/jettywebsocketclient.md section: Loading & Unloading Data --- # JettyWebSocketClient This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Implementation of WebSocketClientService. This service uses Jetty WebSocket client module to provide WebSocket session management throughout the application. ## Tags Jetty, WebSocket, client ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: JettyWebSocketServer source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/jettywebsocketserver.md section: Loading & Unloading Data --- # JettyWebSocketServer This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Implementation of WebSocketServerService. This service uses Jetty WebSocket server module to provide WebSocket session management throughout the application. ## Tags Jetty, WebSocket, server ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: JMSConnectionFactoryProvider source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/jmsconnectionfactoryprovider.md section: Loading & Unloading Data --- # JMSConnectionFactoryProvider This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides a generic service to create vendor specific javax.jms. ConnectionFactory implementations. The Connection Factory can be served once this service is configured successfully. ## Tags integration, jms, messaging, publish, queue, subscribe, topic ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted ## Restrictions
## System Resource Considerations This component does not specify system resource considerations. --- title: JndiJmsConnectionFactoryProvider source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/jndijmsconnectionfactoryprovider.md section: Loading & Unloading Data --- # JndiJmsConnectionFactoryProvider This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides a service to lookup an existing JMS ConnectionFactory using the Java Naming and Directory Interface (JNDI). ## Tags integration, jms, jndi, messaging, publish, queue, subscribe, topic ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: JoinEnrichment 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/joinenrichment.md section: Loading & Unloading Data --- # JoinEnrichment 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Joins together Records from two different FlowFiles where one FlowFile, the 'original' contains arbitrary records and the second FlowFile, the 'enrichment' contains additional data that should be used to enrich the first. See Additional Details for more information on how to configure this processor and the different use cases that it aims to accomplish. ## Tags combine, enrichment, fork, join, merge, record, recordpath, sql, streams, wrap ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.standard.ForkEnrichment](/user-guide/data-integration/openflow/processors/forkenrichment) --- title: JoltTransformJSON 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/jolttransformjson.md section: Loading & Unloading Data --- # JoltTransformJSON 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-jolt-nar ## Description Applies a list of Jolt specifications to either the FlowFile JSON content or a specified FlowFile JSON attribute. If the JSON transform fails, the original FlowFile is routed to the 'failure' relationship. ## Tags cardinality, chainr, default, jolt, json, remove, shift, sort, transform ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: JoltTransformRecord 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/jolttransformrecord.md section: Loading & Unloading Data --- # JoltTransformRecord 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-jolt-nar ## Description Applies a JOLT specification to each record in the FlowFile payload. A new FlowFile is created with transformed content and is routed to the 'success' relationship. If the transform fails, the original FlowFile is routed to the 'failure' relationship. ## Tags cardinality, chainr, defaultr, jolt, record, removr, shiftr, sort, transform ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: JSLTTransformJSON 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/jslttransformjson.md section: Loading & Unloading Data --- # JSLTTransformJSON 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-jslt-nar ## Description Applies a JSLT transformation to the FlowFile JSON payload. A new FlowFile is created with transformed content and is routed to the 'success' relationship. If the JSLT transform fails, the original FlowFile is routed to the 'failure' relationship. ## Tags jslt, json, transform ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: JsonConfigBasedBoxClientService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/jsonconfigbasedboxclientservice.md section: Loading & Unloading Data --- # JsonConfigBasedBoxClientService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides Box client objects through which Box API calls can be used. ## Tags box, client, provider ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: JsonPathReader source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/jsonpathreader.md section: Loading & Unloading Data --- # JsonPathReader This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Parses JSON records and evaluates user-defined JSON Path 's against each JSON object. While the reader expects each record to be well-formed JSON, the content of a FlowFile may consist of many records, each as a well-formed JSON array or JSON object with optional whitespace between them, such as the common'JSON-per-line' format. If an array is encountered, each element in that array will be treated as a separate record. User-defined properties define the fields that should be extracted from the JSON in order to form the fields of a Record. Any JSON field that is not extracted via a JSONPath will not be returned in the JSON Records. ## Tags json, jsonpath, parser, reader, record ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: JsonQueryElasticsearch 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/jsonqueryelasticsearch.md section: Loading & Unloading Data --- # JsonQueryElasticsearch 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-elasticsearch-restapi-nar ## Description A processor that allows the user to run a query (with aggregations) written with the Elasticsearch JSON DSL. It does not automatically paginate queries for the user. If an incoming relationship is added to this processor, it will use the flowfile's content for the query. Care should be taken on the size of the query because the entire response from Elasticsearch will be loaded into memory all at once and converted into the resulting flowfiles. ## Tags elasticsearch, elasticsearch7, elasticsearch8, elasticsearch9, get, json, query, read ## Input Requirement ALLOWED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.elasticsearch.PaginatedJsonQueryElasticsearch](/user-guide/data-integration/openflow/processors/paginatedjsonqueryelasticsearch) --- title: JsonRecordSetWriter source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/jsonrecordsetwriter.md section: Loading & Unloading Data --- # JsonRecordSetWriter This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Writes the results of a RecordSet as either a JSON Array or one JSON object per line. If using Array output, then even if the RecordSet consists of a single row, it will be written as an array with a single element. If using One Line Per Object output, the JSON objects cannot be pretty-printed. ## Tags json, record, recordset, resultset, row, serialize, writer ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: JsonTableColumnFilter source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/jsontablecolumnfilter.md section: Loading & Unloading Data --- # JsonTableColumnFilter This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides a table column filter based on a JSON configuration. The JSON configuration should be an array of objects, where each object represents a table and its column filter. The object should have the following properties: - schema: the schema name of the table - table: the table name - included: an array of column names to include - excluded: an array of column names to exclude - includedPattern: a regular expression pattern to include columns - excludedPattern: a regular expression pattern to exclude columns The schema and table must be provided for each object, and one or more of the *included*, *excluded*, *includedPattern*, or *excludedPattern* properties must be provided. If any column is included as both included and excluded, the column will be excluded. If only a single filter is provided, the JSON configuration may be a single JSON object, rather than an array. ## Tags column, database, filter, snowflake, table ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: JsonTreeReader source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/jsontreereader.md section: Loading & Unloading Data --- # JsonTreeReader This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Parses JSON into individual Record objects. While the reader expects each record to be well-formed JSON, the content of a FlowFile may consist of many records, each as a well-formed JSON array or JSON object with optional whitespace between them, such as the common 'JSON-per-line' format. If an array is encountered, each element in that array will be treated as a separate record. If the schema that is configured contains a field that is not present in the JSON, a null value will be used. If the JSON contains a field that is not present in the schema, that field will be skipped. See the Usage of the Controller Service for more information and examples. ## Tags json, parser, reader, record, tree ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: JWTBearerOAuth2AccessTokenProvider source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/jwtbeareroauth2accesstokenprovider.md section: Loading & Unloading Data --- # JWTBearerOAuth2AccessTokenProvider This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides OAuth 2.0 access tokens that can be used as Bearer authorization header in HTTP requests. This controller service is for implementing the OAuth 2.0 JWT Bearer Flow. ## Tags access token, authorization, hjwt, oauth2, provider ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: Kafka3ConnectionService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/kafka3connectionservice.md section: Loading & Unloading Data --- # Kafka3ConnectionService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides and manages connections to Kafka Brokers for producer or consumer operations. ## Tags kafka, openflow ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: ListArchivedHubSpotData 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listarchivedhubspotdata.md section: Loading & Unloading Data --- # ListArchivedHubSpotData 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-hubspot-processors-nar ## Description Lists archived data from HubSpot for the chosen object type and generates one FlowFile per listed object with the corresponding metadata as FlowFile attributes. The object type must be searchable, which means it supports access to the /search endpoint. For more information about searchable object types, see: https://developers.hubspot.com/docs/reference/api/crm/objects/objects#search (https://developers.hubspot.com/docs/reference/api/crm/objects/objects#search)") ## Tags Preview, hubspot ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
## Use cases | This processor is typically used in conjunction with a GenerateFlowFile processor | | --------------------------------------------------------------------------------- | ## See also - [com.snowflake.openflow.runtime.processors.hubspot.GetHubSpotObject](/user-guide/data-integration/openflow/processors/gethubspotobject) - [com.snowflake.openflow.runtime.processors.hubspot.GetHubSpotSchema](/user-guide/data-integration/openflow/processors/gethubspotschema) - [com.snowflake.openflow.runtime.processors.hubspot.ListHubSpotObjects](/user-guide/data-integration/openflow/processors/listhubspotobjects) - [com.snowflake.openflow.runtime.processors.hubspot.PutHubSpot](/user-guide/data-integration/openflow/processors/puthubspot) --- title: ListAzureBlobStorage_v12 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listazureblobstorage_v12.md section: Loading & Unloading Data --- # ListAzureBlobStorage_v12 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-azure-nar ## Description Lists blobs in an Azure Blob Storage container. Listing details are attached to an empty FlowFile for use with FetchAzureBlobStorage. This Processor is designed to run on Primary Node only in a cluster. If the primary node changes, the new Primary Node will pick up where the previous node left off without duplicating all of the data. The processor uses Azure Blob Storage client library v12. ## Tags azure, blob, cloud, microsoft, storage ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.azure.storage.CopyAzureBlobStorage_v12](/user-guide/data-integration/openflow/processors/copyazureblobstorage_v12) - [org.apache.nifi.processors.azure.storage.DeleteAzureBlobStorage_v12](/user-guide/data-integration/openflow/processors/deleteazureblobstorage_v12) - [org.apache.nifi.processors.azure.storage.FetchAzureBlobStorage_v12](/user-guide/data-integration/openflow/processors/fetchazureblobstorage_v12) - [org.apache.nifi.processors.azure.storage.PutAzureBlobStorage_v12](/user-guide/data-integration/openflow/processors/putazureblobstorage_v12) --- title: ListAzureDataLakeStorage 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listazuredatalakestorage.md section: Loading & Unloading Data --- # ListAzureDataLakeStorage 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-azure-nar ## Description Lists directory in an Azure Data Lake Storage Gen 2 filesystem ## Tags adlsgen2, azure, cloud, datalake, microsoft, storage ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.azure.storage.DeleteAzureDataLakeStorage](/user-guide/data-integration/openflow/processors/deleteazuredatalakestorage) - [org.apache.nifi.processors.azure.storage.FetchAzureDataLakeStorage](/user-guide/data-integration/openflow/processors/fetchazuredatalakestorage) - [org.apache.nifi.processors.azure.storage.PutAzureDataLakeStorage](/user-guide/data-integration/openflow/processors/putazuredatalakestorage) --- title: ListBoxFile 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listboxfile.md section: Loading & Unloading Data --- # ListBoxFile 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-box-nar ## Description Lists files in a Box folder. Each listed file may result in one FlowFile, the metadata being written as FlowFile attributes. Or - in case the 'Record Writer' property is set - the entire result is written as records to a single FlowFile. This Processor is designed to run on Primary Node only in a cluster. If the primary node changes, the new Primary Node will pick up where the previous node left off without duplicating all of the data. ## Tags box, storage ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.box.FetchBoxFile](/user-guide/data-integration/openflow/processors/fetchboxfile) - [org.apache.nifi.processors.box.PutBoxFile](/user-guide/data-integration/openflow/processors/putboxfile) --- title: ListBoxFileInfo 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listboxfileinfo.md section: Loading & Unloading Data --- # ListBoxFileInfo 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-box-nar ## Description Fetches file metadata for each file in a Box Folder. Takes a flowFile with a folder ID attribute and outputs flowFiles with records containing all file metadata. ## Tags box, fetch, files, folder, storage ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.box.FetchBoxFile](/user-guide/data-integration/openflow/processors/fetchboxfile) - [org.apache.nifi.processors.box.ListBoxFile](/user-guide/data-integration/openflow/processors/listboxfile) - [org.apache.nifi.processors.box.PutBoxFile](/user-guide/data-integration/openflow/processors/putboxfile) --- title: ListBoxFileMetadataInstances 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listboxfilemetadatainstances.md section: Loading & Unloading Data --- # ListBoxFileMetadataInstances 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-box-nar ## Description Retrieves all metadata instances associated with a Box file. ## Tags box, instances, metadata, storage, templates ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.box.FetchBoxFile](/user-guide/data-integration/openflow/processors/fetchboxfile) - [org.apache.nifi.processors.box.FetchBoxFileInfo](/user-guide/data-integration/openflow/processors/fetchboxfileinfo) - [org.apache.nifi.processors.box.ListBoxFile](/user-guide/data-integration/openflow/processors/listboxfile) --- title: ListBoxFileMetadataTemplates 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listboxfilemetadatatemplates.md section: Loading & Unloading Data --- # ListBoxFileMetadataTemplates 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-box-nar ## Description Retrieves all metadata templates associated with a Box file. ## Tags box, metadata, storage, templates ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.box.FetchBoxFile](/user-guide/data-integration/openflow/processors/fetchboxfile) - [org.apache.nifi.processors.box.FetchBoxFileInfo](/user-guide/data-integration/openflow/processors/fetchboxfileinfo) - [org.apache.nifi.processors.box.ListBoxFile](/user-guide/data-integration/openflow/processors/listboxfile) --- title: ListConfluenceGroups 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listconfluencegroups.md section: Loading & Unloading Data --- # ListConfluenceGroups 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-atlassian-processors-nar ## Description Processor listing Confluence groups. ## Tags Preview, atlassian, confluence, groups ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: ListDatabaseTables 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listdatabasetables.md section: Loading & Unloading Data --- # ListDatabaseTables 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Generates a set of flow files, each containing attributes corresponding to metadata about a table from a database connection. Once metadata about a table has been fetched, it will not be fetched again until the Refresh Interval (if set) has elapsed, or until state has been manually cleared. ## Tags database, jdbc, list, sql, table ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
## Use Cases Involving Other Components | Perform a full load of a database, retrieving all rows from all tables, or a specific set of tables. | | ---------------------------------------------------------------------------------------------------- | --- title: ListDBFSDirectory 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listdbfsdirectory.md section: Loading & Unloading Data --- # ListDBFSDirectory 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-databricks-processors-nar ## Description List file names in a DBFS directory and output a new FlowFile with the filename. ## Tags databricks, dbfs, openflow ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: ListDropbox 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listdropbox.md section: Loading & Unloading Data --- # ListDropbox 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-dropbox-processors-nar ## Description Retrieves a listing of files from Dropbox (shortcuts are ignored). Each listed file may result in one FlowFile, the metadata being written as FlowFile attributes. When the 'Record Writer' property is set, the entire result is written as records to a single FlowFile. This Processor is designed to run on Primary Node only in a cluster. If the primary node changes, the new Primary Node will pick up where the previous node left off without duplicating all of the data. ## Tags dropbox, storage ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.dropbox.FetchDropbox](/user-guide/data-integration/openflow/processors/fetchdropbox) - [org.apache.nifi.processors.dropbox.PutDropbox](/user-guide/data-integration/openflow/processors/putdropbox) --- title: ListenFTP 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listenftp.md section: Loading & Unloading Data --- # ListenFTP 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Starts an FTP server that listens on the specified port and transforms incoming files into FlowFiles. The URI of the service will be ftp://\{hostname\}:\{port\}. The default port is 2221. ## Tags FTP, FTPS, ingest, listen ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: ListenHTTP 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listenhttp.md section: Loading & Unloading Data --- # ListenHTTP 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Starts an HTTP Server and listens on a given base path to transform incoming requests into FlowFiles. The default URI of the Service will be http://\{hostname\}:\{port\}/contentListener. Only HEAD and POST requests are supported. GET, PUT, DELETE, OPTIONS and TRACE will result in an error and the HTTP response status code 405; CONNECT will also result in an error and the HTTP response status code 400. GET is supported on <service_URI>/healthcheck. If the service is available, it returns "200 OK" with the content "OK". The health check functionality can be configured to be accessible via a different port. For details, see the documentation of the "Listening Port for health check requests" property. A Record Reader and Record Writer property can be enabled on the processor to process incoming requests as records. Record processing is not allowed for multipart requests and request in FlowFileV3 format (minifi). If the incoming request contains a FlowFileV3 package format, the data will be unpacked automatically into individual FlowFile(s) contained within the package; the original FlowFile names are restored. ## Tags http, https, ingest, listen, rest ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Use cases | Unpack FlowFileV3 content received in a POST | | -------------------------------------------- | ## Use Cases Involving Other Components | Limit the date flow rate that is accepted | | ----------------------------------------- | --- title: ListenOTLP 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listenotlp.md section: Loading & Unloading Data --- # ListenOTLP 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-opentelemetry-nar ## Description Collect OpenTelemetry messages over HTTP or gRPC. Supports standard Export Service Request messages for logs, metrics, and traces. Implements OpenTelemetry OTLP Specification 1.0.0 with OTLP/gRPC and OTLP/HTTP. Provides protocol detection using the HTTP Content-Type header. ## Tags OTLP, OTel, OpenTelemetry, logs, metrics, telemetry, traces ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: ListenSlack 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listenslack.md section: Loading & Unloading Data --- # ListenSlack 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-slack-nar ## Description Retrieves real-time messages or Slack commands from one or more Slack conversations. The messages are written out in JSON format. Note that this Processor should be used to obtain real-time messages and commands from Slack and does not provide a mechanism for obtaining historical messages. The ConsumeSlack Processor should be used for an initial load of messages from a channel. See Usage / Additional Details for more information about how to configure this Processor and enable it to retrieve messages and commands from Slack. ## Tags command, event, listen, message, real-time, receive, slack, social media, team, text, unstructured ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.slack.ConsumeSlack](/user-guide/data-integration/openflow/processors/consumeslack) --- title: ListenSyslog 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listensyslog.md section: Loading & Unloading Data --- # ListenSyslog 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Listens for Syslog messages being sent to a given port over TCP or UDP. Incoming messages are checked against regular expressions for RFC5424 and RFC3164 formatted messages. The format of each message is: (<PRIORITY>)(VERSION )(TIMESTAMP) (HOSTNAME) (BODY) where version is optional. The timestamp can be an RFC5424 timestamp with a format of "yyyy-MM-dd 'T'HH:mm:ss. SZ" or "yyyy-MM-dd 'T'HH:mm:ss. S+hh:mm", or it can be an RFC3164 timestamp with a format of "MMM d HH:mm:ss". If an incoming messages matches one of these patterns, the message will be parsed and the individual pieces will be placed in FlowFile attributes, with the original message in the content of the FlowFile. If an incoming message does not match one of these patterns it will not be parsed and the syslog.valid attribute will be set to false with the original message in the content of the FlowFile. Valid messages will be transferred on the success relationship, and invalid messages will be transferred on the invalid relationship. ## Tags listen, logs, syslog, tcp, udp ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.standard.ParseSyslog](/user-guide/data-integration/openflow/processors/parsesyslog) - [org.apache.nifi.processors.standard.PutSyslog](/user-guide/data-integration/openflow/processors/putsyslog) --- title: ListenTCP 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listentcp.md section: Loading & Unloading Data --- # ListenTCP 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Listens for incoming TCP connections and reads data from each connection using a line separator as the message demarcator. The default behavior is for each message to produce a single FlowFile, however this can be controlled by increasing the Batch Size to a larger value for higher throughput. The Receive Buffer Size must be set as large as the largest messages expected to be received, meaning if every 100kb there is a line separator, then the Receive Buffer Size must be greater than 100kb. The processor can be configured to use an SSL Context Service to only allow secure connections. When connected clients present certificates for mutual TLS authentication, the Distinguished Names of the client certificate's issuer and subject are added to the outgoing FlowFiles as attributes. The processor does not perform authorization based on Distinguished Name values, but since these values are attached to the outgoing FlowFiles, authorization can be implemented based on these attributes. ## Tags listen, ssl, tcp, tls ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: ListenUDP 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listenudp.md section: Loading & Unloading Data --- # ListenUDP 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Listens for Datagram Packets on a given port. The default behavior produces a FlowFile per datagram, however for higher throughput the Max Batch Size property may be increased to specify the number of datagrams to batch together in a single FlowFile. This processor can be restricted to listening for datagrams from a specific remote host and port by specifying the Sending Host and Sending Host Port properties, otherwise it will listen for datagrams from all hosts and ports. ## Tags ingest, listen, source, udp ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: ListenUDPRecord 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listenudprecord.md section: Loading & Unloading Data --- # ListenUDPRecord 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Listens for Datagram Packets on a given port and reads the content of each datagram using the configured Record Reader. Each record will then be written to a flow file using the configured Record Writer. This processor can be restricted to listening for datagrams from a specific remote host and port by specifying the Sending Host and Sending Host Port properties, otherwise it will listen for datagrams from all hosts and ports. ## Tags ingest, listen, record, source, udp ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: ListenWebSocket 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listenwebsocket.md section: Loading & Unloading Data --- # ListenWebSocket 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-websocket-processors-nar ## Description Acts as a WebSocket server endpoint to accept client connections. FlowFiles are transferred to downstream relationships according to received message types as the WebSocket server configured with this processor receives client requests ## Tags WebSocket, consume, listen, subscribe ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: ListFile 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listfile.md section: Loading & Unloading Data --- # ListFile 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Retrieves a listing of files from the input directory. For each file listed, creates a FlowFile that represents the file so that it can be fetched in conjunction with FetchFile. This Processor is designed to run on Primary Node only in a cluster when 'Input Directory Location' is set to 'Remote'. If the primary node changes, the new Primary Node will pick up where the previous node left off without duplicating all the data. When 'Input Directory Location' is 'Local', the 'Execution' mode can be anything, and synchronization won't happen. Unlike GetFile, this Processor does not delete any data from the local filesystem. ## Tags file, filesystem, get, ingest, list, source ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.standard.FetchFile](/user-guide/data-integration/openflow/processors/fetchfile) - [org.apache.nifi.processors.standard.GetFile](/user-guide/data-integration/openflow/processors/getfile) - [org.apache.nifi.processors.standard.PutFile](/user-guide/data-integration/openflow/processors/putfile) --- title: ListFTP 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listftp.md section: Loading & Unloading Data --- # ListFTP 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Performs a listing of the files residing on an FTP server. For each file that is found on the remote server, a new FlowFile will be created with the filename attribute set to the name of the file on the remote server. This can then be used in conjunction with FetchFTP in order to fetch those files. ## Tags files, ftp, ingest, input, list, remote, source ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.standard.FetchFTP](/user-guide/data-integration/openflow/processors/fetchftp) - [org.apache.nifi.processors.standard.GetFTP](/user-guide/data-integration/openflow/processors/getftp) - [org.apache.nifi.processors.standard.PutFTP](/user-guide/data-integration/openflow/processors/putftp) --- title: ListGCSBucket 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listgcsbucket.md section: Loading & Unloading Data --- # ListGCSBucket 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-gcp-nar ## Description Retrieves a listing of objects from a GCS bucket. For each object that is listed, creates a FlowFile that represents the object so that it can be fetched in conjunction with FetchGCSObject. This Processor is designed to run on Primary Node only in a cluster. If the primary node changes, the new Primary Node will pick up where the previous node left off without duplicating all of the data. ## Tags gcs, google, google cloud, list, storage ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.gcp.storage.DeleteGCSObject](/user-guide/data-integration/openflow/processors/deletegcsobject) - [org.apache.nifi.processors.gcp.storage.FetchGCSObject](/user-guide/data-integration/openflow/processors/fetchgcsobject) - [org.apache.nifi.processors.gcp.storage.PutGCSObject](/user-guide/data-integration/openflow/processors/putgcsobject) --- title: ListGoogleDrive 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listgoogledrive.md section: Loading & Unloading Data --- # ListGoogleDrive 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-gcp-nar ## Description Performs a listing of concrete files (shortcuts are ignored) in a Google Drive folder. If the 'Record Writer' property is set, a single Output FlowFile is created, and each file in the listing is written as a single record to the output file. Otherwise, for each file in the listing, an individual FlowFile is created, the metadata being written as FlowFile attributes. This Processor is designed to run on Primary Node only in a cluster. If the primary node changes, the new Primary Node will pick up where the previous node left off without duplicating all of the data. Please see Additional Details to set up access to Google Drive. ## Tags drive, google, storage ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.gcp.drive.FetchGoogleDrive](/user-guide/data-integration/openflow/processors/fetchgoogledrive) - [org.apache.nifi.processors.gcp.drive.PutGoogleDrive](/user-guide/data-integration/openflow/processors/putgoogledrive) --- title: ListGoogleDriveFileInfo 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listgoogledrivefileinfo.md section: Loading & Unloading Data --- # ListGoogleDriveFileInfo 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-google-drive-nar ## Description Lists all files and folders in a specified Google Drive. The processor requires a Drive ID and can optionally list files recursively through all folders within the drive. ## Tags cloud, drive, files, gcp, google, list, openflow, storage ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [com.snowflake.openflow.runtime.processors.google.CaptureGoogleDriveChanges](/user-guide/data-integration/openflow/processors/capturegoogledrivechanges) - [com.snowflake.openflow.runtime.processors.google.FetchGoogleDriveMetadata](/user-guide/data-integration/openflow/processors/fetchgoogledrivemetadata) --- title: ListGoogleGroups 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listgooglegroups.md section: Loading & Unloading Data --- # ListGoogleGroups 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-google-drive-nar ## Description Lists all of the groups for a given domain in Google Workspace. It supports an optional 'Query' to filter the groups. The retrieved group metadata (id, etag, email, name, directMembersCount, description) are output to a Record Writer. ## Tags cloud, directory, domain, gcp, google, groups, list ## Input Requirement ALLOWED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [com.snowflake.openflow.runtime.processors.google.GetGoogleGroupMembers](/user-guide/data-integration/openflow/processors/getgooglegroupmembers) --- title: ListHubSpotObjects 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listhubspotobjects.md section: Loading & Unloading Data --- # ListHubSpotObjects 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-hubspot-processors-nar ## Description Fetches data from HubSpot for specified object types, and generates one FlowFile per listed object with the corresponding metadata as FlowFile attributes. The object type must be searchable, which means it supports access to the /search endpoint. For more information about searchable object types, see: https://developers.hubspot.com/docs/reference/api/crm/objects/objects#search (https://developers.hubspot.com/docs/reference/api/crm/objects/objects#search)") ## Tags Preview, hubspot ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
## Use cases | This processor is typically used in conjunction with a GenerateFlowFile processor | | --------------------------------------------------------------------------------- | ## See also - [com.snowflake.openflow.runtime.processors.hubspot.GetHubSpotObject](/user-guide/data-integration/openflow/processors/gethubspotobject) - [com.snowflake.openflow.runtime.processors.hubspot.GetHubSpotSchema](/user-guide/data-integration/openflow/processors/gethubspotschema) - [com.snowflake.openflow.runtime.processors.hubspot.ListArchivedHubSpotData](/user-guide/data-integration/openflow/processors/listarchivedhubspotdata) - [com.snowflake.openflow.runtime.processors.hubspot.PutHubSpot](/user-guide/data-integration/openflow/processors/puthubspot) --- title: ListMicrosoftDataverseTables 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listmicrosoftdataversetables.md section: Loading & Unloading Data --- # ListMicrosoftDataverseTables 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-dataverse-processors-nar ## Description List Tables from Microsoft Dataverse environments ## Tags dataverse ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: ListS3 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/lists3.md section: Loading & Unloading Data --- # ListS3 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-aws-nar ## Description Retrieves a listing of objects from an S3 bucket. For each object that is listed, creates a FlowFile that represents the object so that it can be fetched in conjunction with FetchS3Object. This Processor is designed to run on Primary Node only in a cluster. If the primary node changes, the new Primary Node will pick up where the previous node left off without duplicating all of the data. ## Tags AWS, Amazon, S3, list ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.aws.s3.CopyS3Object](/user-guide/data-integration/openflow/processors/copys3object) - [org.apache.nifi.processors.aws.s3.DeleteS3Object](/user-guide/data-integration/openflow/processors/deletes3object) - [org.apache.nifi.processors.aws.s3.FetchS3Object](/user-guide/data-integration/openflow/processors/fetchs3object) - [org.apache.nifi.processors.aws.s3.GetS3ObjectMetadata](/user-guide/data-integration/openflow/processors/gets3objectmetadata) - [org.apache.nifi.processors.aws.s3.GetS3ObjectTags](/user-guide/data-integration/openflow/processors/gets3objecttags) - [org.apache.nifi.processors.aws.s3.PutS3Object](/user-guide/data-integration/openflow/processors/puts3object) - [org.apache.nifi.processors.aws.s3.TagS3Object](/user-guide/data-integration/openflow/processors/tags3object) --- title: ListSFDCDataShares 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listsfdcdatashares.md section: Loading & Unloading Data --- # ListSFDCDataShares 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-salesforce-processors-nar ## Description List the available data shares in the organization that are available to the identified user. ## Tags list, objects, preview, salesforce, sfdc ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [com.snowflake.openflow.runtime.processors.salesforce.DeleteQueryJob](/user-guide/data-integration/openflow/processors/deletequeryjob) - [com.snowflake.openflow.runtime.processors.salesforce.DescribeSFDCObject](/user-guide/data-integration/openflow/processors/describesfdcobject) - [com.snowflake.openflow.runtime.processors.salesforce.GetQueryJobResult](/user-guide/data-integration/openflow/processors/getqueryjobresult) - [com.snowflake.openflow.runtime.processors.salesforce.SubmitQueryJob](/user-guide/data-integration/openflow/processors/submitqueryjob) --- title: ListSFDCObjects 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listsfdcobjects.md section: Loading & Unloading Data --- # ListSFDCObjects 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-salesforce-processors-nar ## Description List the available objects in the organization that are available to the identified user. ## Tags list, objects, preview, salesforce, sfdc ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [com.snowflake.openflow.runtime.processors.salesforce.DeleteQueryJob](/user-guide/data-integration/openflow/processors/deletequeryjob) - [com.snowflake.openflow.runtime.processors.salesforce.DescribeSFDCObject](/user-guide/data-integration/openflow/processors/describesfdcobject) - [com.snowflake.openflow.runtime.processors.salesforce.GetQueryJobResult](/user-guide/data-integration/openflow/processors/getqueryjobresult) - [com.snowflake.openflow.runtime.processors.salesforce.SubmitQueryJob](/user-guide/data-integration/openflow/processors/submitqueryjob) --- title: ListSFTP 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listsftp.md section: Loading & Unloading Data --- # ListSFTP 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Performs a listing of the files residing on an SFTP server. For each file that is found on the remote server, a new FlowFile will be created with the filename attribute set to the name of the file on the remote server. This can then be used in conjunction with FetchSFTP in order to fetch those files. ## Tags files, ingest, input, list, remote, sftp, source ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.standard.FetchSFTP](/user-guide/data-integration/openflow/processors/fetchsftp) - [org.apache.nifi.processors.standard.GetSFTP](/user-guide/data-integration/openflow/processors/getsftp) - [org.apache.nifi.processors.standard.PutSFTP](/user-guide/data-integration/openflow/processors/putsftp) --- title: ListSharepointDrives 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listsharepointdrives.md section: Loading & Unloading Data --- # ListSharepointDrives 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-msgraph-nar ## Description Emits a FlowFile for each Drive present in the specified Sharepoint Site. ## Tags document, graph, microsoft, openflow, sharepoint, unstructured ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [com.snowflake.openflow.runtime.processors.sharepoint.FetchSharepointFile](/user-guide/data-integration/openflow/processors/fetchsharepointfile) - [com.snowflake.openflow.runtime.processors.sharepoint.FindSharepointDriveItem](/user-guide/data-integration/openflow/processors/findsharepointdriveitem) --- title: ListSharepointSiteGroups 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listsharepointsitegroups.md section: Loading & Unloading Data --- # ListSharepointSiteGroups 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-sharepoint-rest-nar ## Description Lists all SharePoint site groups available on a specified SharePoint site. ## Tags groups, list, microsoft, openflow, sharepoint ## Input Requirement ALLOWED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [com.snowflake.openflow.runtime.processors.sharepoint.rest.GetSharepointSiteGroupMembers](/user-guide/data-integration/openflow/processors/getsharepointsitegroupmembers) --- title: ListSmb 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listsmb.md section: Loading & Unloading Data --- # ListSmb 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-smb-nar ## Description Lists concrete files shared via SMB protocol. Each listed file may result in one FlowFile, the metadata being written as FlowFile attributes. Or - in case the 'Record Writer' property is set - the entire result is written as records to a single FlowFile. This Processor is designed to run on Primary Node only in a cluster. If the primary node changes, the new Primary Node will pick up where the previous node left off without duplicating all of the data. ## Tags list, samba, smb, cifs, files ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.smb.FetchSmb](/user-guide/data-integration/openflow/processors/fetchsmb) - [org.apache.nifi.processors.smb.GetSmbFile](/user-guide/data-integration/openflow/processors/getsmbfile) - [org.apache.nifi.processors.smb.PutSmbFile](/user-guide/data-integration/openflow/processors/putsmbfile) --- title: ListTableNames 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listtablenames.md section: Loading & Unloading Data --- # ListTableNames 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-database-cdc-processors-nar ## Description Fetches all source table names and matches them with one of the possible configurations: - regexp expression e.g. "(?i)customer.(orders|payments)" - it matches names in case insensitive way. It would match both "CUSTOMER.ORDERS" and "customer.orders" source table names. - comma separated list of source table names. e.g. "customer.orders, customer.payments". It matches source table names in case sensitive way i.e. "customer.orders" source table will be forwarded to MATCH relationship but "customer. ORDERS" won 't match. Matched source tables that cannot be replicated will be routed to FAILURE relationship, each table in a separate FlowFile, with a reason in attributes. Configuration is passed as a FlowFile attribute. Source table name is represented as <schema_name>.<table_name> so both inputs should take that into consideration. Matched source table names are forwarded to MATCHED relationship. Processor generates a single FlowFile with matching tables. Disclaimers - Postgresql lets you define database object names in case sensitive or case insensitive way. When user creates a table using following query'CREATE TABLE ORDERS(id int not null) 'then internally Postgresql stores it using lower case letters i.e. orders. To enforce case sensitivity user has to wrap the table name with double quotes i.e.'CREATE TABLE "ORDERS"(id int not null)'. This is important aspect when configuring table that we would like to replicate. ## Tags ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: ListUnityCatalogDirectory 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/listunitycatalogdirectory.md section: Loading & Unloading Data --- # ListUnityCatalogDirectory 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-databricks-processors-nar ## Description List file names in a Unity Catalog directory and output a new FlowFile with the filename. ## Tags databricks, openflow, unity catalog ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: LogAttribute 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/logattribute.md section: Loading & Unloading Data --- # LogAttribute 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Emits attributes of the FlowFile at the specified log level ## Tags attributes, logging ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: LoggingRecordSink source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/loggingrecordsink.md section: Loading & Unloading Data --- # LoggingRecordSink This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides a RecordSinkService that can be used to log records to the application log (nifi-app.log, e.g.) using the specified writer for formatting. ## Tags log, record, sink ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: LogMessage 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/logmessage.md section: Loading & Unloading Data --- # LogMessage 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Emits a log message at the specified log level ## Tags attributes, logging ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: LookupAttribute 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/lookupattribute.md section: Loading & Unloading Data --- # LookupAttribute 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Lookup attributes from a lookup service ## Tags Attribute Expression Language, attributes, cache, enrich, join, lookup ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: LookupRecord 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/lookuprecord.md section: Loading & Unloading Data --- # LookupRecord 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Extracts one or more fields from a Record and looks up a value for those fields in a LookupService. If a result is returned by the LookupService, that result is optionally added to the Record. In this case, the processor functions as an Enrichment processor. Regardless, the Record is then routed to either the 'matched' relationship or 'unmatched' relationship (if the 'Routing Strategy' property is configured to do so), indicating whether or not a result was returned by the LookupService, allowing the processor to also function as a Routing processor. The "coordinates" to use for looking up a value in the Lookup Service are defined by adding a user-defined property. Each property that is added will have an entry added to a Map, where the name of the property becomes the Map Key and the value returned by the RecordPath becomes the value for that key. If multiple values are returned by the RecordPath, then the Record will be routed to the 'unmatched' relationship (or 'success', depending on the 'Routing Strategy' property's configuration). If one or more fields match the Result RecordPath, all fields that match will be updated. If there is no match in the configured LookupService, then no fields will be updated. I.e., it will not overwrite an existing value in the Record with a null value. Please note, however, that if the results returned by the LookupService are not accounted for in your schema (specifically, the schema that is configured for your Record Writer) then the fields will not be written out to the FlowFile. ## Tags avro, convert, csv, database, db, enrichment, filter, json, logs, lookup, record, route ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.standard.ConvertRecord](/user-guide/data-integration/openflow/processors/convertrecord) - [org.apache.nifi.processors.standard.SplitRecord](/user-guide/data-integration/openflow/processors/splitrecord) --- title: Maintain Openflow Connector for Amazon Kinesis Data Streams source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/kinesis/maintenance.md section: Loading & Unloading Data --- # Maintain %kinesis% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Openflow Connector for Amazon Kinesis Data Streams](/user-guide/data-integration/openflow/connectors/kinesis/about) - [Set up Openflow Connector for Amazon Kinesis Data Streams](/user-guide/data-integration/openflow/connectors/kinesis/setup) - [Troubleshooting the Openflow Connector for Amazon Kinesis Data Streams](/user-guide/data-integration/openflow/connectors/kinesis/troubleshoot) - [Performance tuning of the Openflow Connector for Amazon Kinesis Data Streams](/user-guide/data-integration/openflow/connectors/kinesis/performance-tuning) This topic describes how to maintain the %kinesis% connector, including how to manage and reset the connector state. ## Manage connector state The %kinesis% connector uses DynamoDB to store the consumer application state. ### DynamoDB table created by the connector The connector creates a DynamoDB table with the name specified in `AWS Kinesis Application Name`. The table stores the checkpointed sequence number for each shard in the stream. This tracks which records have been processed. If multiple processors use the same application name, they cooperate to consume data from the stream and share this table. If processors have different application names, each creates its own table to independently track consumed records. ## Reset the connector state If the connector state in DynamoDB becomes corrupted or inconsistent, you may need to reset it. There are two approaches to reset the connector state. ### Reset by changing the application name The simplest way to reset the connector state is to change the AWS Kinesis Application Name parameter: 1. Stop the connector. 2. Navigate to the connector's parameter context. 3. Change the `AWS Kinesis Application Name` parameter value to a new value. 4. Start the connector. The connector creates a new DynamoDB table with the new application name and begins consuming records from the position specified by the [AWS Kinesis Initial Stream Position](#label-kinesis-json-source-parameters) parameter. - When you change the application name, the connector doesn't delete the old DynamoDB table. You must manually delete it through the AWS Console or the AWS CLI. - If your IAM policy restricts DynamoDB access to a specific table name, you must update the policy to allow access to the new table name. For more information on configuring IAM permissions, see [Set up Openflow Connector for Amazon Kinesis Data Streams](/user-guide/data-integration/openflow/connectors/kinesis/setup). ### Reset by deleting the DynamoDB table Alternatively, you can delete the existing DynamoDB table to reset the state: 1. Stop the connector. 2. In the AWS Console or using the AWS CLI, delete the DynamoDB table associated with the application name. 3. Start the connector. The connector recreates the table and begins consuming records from the position specified by the [AWS Kinesis Initial Stream Position](#label-kinesis-json-source-parameters) parameter. Resetting the connector state causes the connector to reprocess records from the position specified by the initial stream position. Depending on your [AWS Kinesis Initial Stream Position](#label-kinesis-json-source-parameters) setting, this may result in duplicate data being ingested into Snowflake or data not being ingested at all. --- title: Maintain the Openflow Connector for Shopify source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/shopify/maintain.md section: Loading & Unloading Data --- # Maintain the %shopifyof% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About the Openflow Connector for Shopify](/user-guide/data-integration/openflow/connectors/shopify/about) - [Set up the Openflow Connector for Shopify](/user-guide/data-integration/openflow/connectors/shopify/setup) - [Object definition overrides for the Openflow Connector for Shopify](/user-guide/data-integration/openflow/connectors/shopify/object-definitions) - [Troubleshoot the Openflow Connector for Shopify](/user-guide/data-integration/openflow/connectors/shopify/troubleshoot) This topic describes maintenance tasks for the %shopifyof%, including how to reset connector state to trigger a fresh bulk load. ## Reset connector state The connector maintains an internal state to track bulk-load completion status and the incremental watermark for each object type. In some situations, you might need to reset the connector to perform a fresh bulk load, for example, after resolving a data issue or after the connector has been stopped for an extended period. ### Reset all objects To reset all objects and force a full bulk reload: 1. Stop all processors in the flow by right-clicking on the connector process group and selecting **Stop**. 2. Ensure that no in-flight FlowFiles are being processed. You can verify this by checking that all queues in the flow are empty. 3. Right-click on the canvas and select **Disable all controller services**. 4. Go to **Controller services** and locate the **Shopify State Service**. 5. Select the menu for **Shopify State Service**, then select **View state** and select **Clear state**. 6. Right-click on the canvas and select **Enable all controller services**, then start all processors to resume the connector. The connector treats a cleared state as a fresh start and performs a bulk load for all configured objects on the next execution. ### Reset a specific object To reset a single object type and re-ingest it from scratch without affecting other objects: 1. Stop all processors in the flow. 2. Ensure all queues are empty. 3. Right-click on the canvas and select **Disable all controller services**. 4. Go to **Controller services** and locate the **Shopify State Service**. 5. Select the menu for **Shopify State Service**, then select **View state**. 6. Select the trash icon next to the specific object type (for example, `orders`) to delete its state entry. 7. Re-enable all controller services and start the flow. The connector performs a fresh bulk load for that object type and then resumes incremental updates, while other objects continue from their existing watermark. --- title: Manage Openflow source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/manage.md section: Loading & Unloading Data --- # Manage Openflow This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions). - [About Openflow](/user-guide/data-integration/openflow/about) - [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) - [Set up Openflow - Snowflake Deployment - Task overview](/user-guide/data-integration/openflow/setup-openflow-spcs) - [Monitor Openflow using telemetry data](/user-guide/data-integration/openflow/monitor) - [Snowflake Openflow version history](/user-guide/data-integration/openflow/version-history) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) This topic covers the following management tasks: - [Back up flow definitions and protect runtime state](#back-up-flow-definitions-and-protect-runtime-state) - [Runtime availability and autoscaling behavior](#runtime-availability-and-autoscaling-behavior) - [Delete a deployment](#delete-a-deployment) - [Upgrade a deployment](#upgrade-a-deployment) - [Upgrade a runtime](#upgrade-a-runtime) - [Upgrade a connector](#upgrade-a-connector) ## Back up flow definitions and protect runtime state Flow definitions and runtime-local state (including processor configuration and Apache NiFi flow state held on the runtime) live on **Openflow runtime storage**, not in Snowflake tables. If you remove, replace, or manually tear down that infrastructure **without** exporting your flows first, that data can be **lost permanently**. Snowflake does not provide Time Travel or Fail-safe for this storage. Before you delete a deployment, delete or recreate a runtime, or manually remove underlying Snowpark Container Services resources or compute tied to Openflow, **export** your flows from the canvas. Right-click the **process group** %ra% **Version** %ra% **Export** (or use the equivalent command your canvas shows). **Routine upgrades** through the supported Openflow UI ([Upgrade a deployment](#label-update-a-deployment) and [Upgrade a runtime](#label-openflow-upgrading-a-runtime)) are different from destructive removal. You should still export flows regularly as a best practice. Do not run [DROP ROLE](/sql-reference/sql/drop-role) for a role that provisions or owns Openflow objects until you transfer ownership and privileges to another role you intend to keep (for example with `GRANT OWNERSHIP`). Dropping a role revokes grants and can leave deployments in a broken state. ## Runtime availability and autoscaling behavior Openflow runtime nodes are not strictly always-on, single-host processes. Each runtime is a Kubernetes workload that the cluster can reschedule onto a different compute host. When that happens, the runtime briefly restarts while a new pod becomes ready. Plan your flows to tolerate short interruptions rather than assuming the runtime stays on the same host indefinitely. Snowflake doesn't automatically upgrade BYOC runtimes. Upgrades happen only when a deployment owner initiates them through the Openflow UI or the deployment agent. Restarts you observe outside of an upgrade window are typically caused by cluster rebalancing or by host-level events on the underlying compute. For Openflow Snowflake deployments running on [Snowpark Container Services](/developer-guide/snowpark-container-services/overview) (SPCS), runtimes can also be affected briefly by the scheduled SPCS [maintenance window](/developer-guide/snowpark-container-services/working-with-compute-pool#label-spcs-working-with-compute-pool-maintenance-window). ### Causes of runtime restarts
Runtime or deployment upgrades
When the owner of a deployment runs an upgrade, the affected runtime restarts to pick up the new version. See [Upgrade a runtime](#label-openflow-upgrading-a-runtime) and [Upgrade a deployment](#label-update-a-deployment).
Cluster rebalancing and autoscaling
Openflow scales the underlying compute up and down based on demand. See [Openflow BYOC cost and scaling considerations](/user-guide/data-integration/openflow/cost-byoc) for details on how BYOC deployments scale the EC2 node group. During scale-in, node-drain, or rebalancing events, the cluster can reschedule a runtime pod from one node to another so that the cluster continues to run efficiently.
Cloud provider host events
The virtual machines that host BYOC runtimes are subject to events outside Snowflake's control, including instance retirement, unexpected reboots, and host-level maintenance performed by the cloud service provider. When a host becomes unavailable, the cluster reschedules the affected runtime onto a healthy node.
### What to expect during a restart - Openflow runtimes and connectors maintain data integrity across restarts. In-flight data held in the runtime's persistent storage is preserved, and the flow resumes after the new pod is ready. - Expect a short service interruption while the new pod starts and reattaches its storage. - Diagnostic output may report `LAST_REQUESTED_RESTART_REASON: "nifi.properties changed"` after a reschedule, even when no NiFi configuration was modified. The runtime operator reconciles the underlying StatefulSet whenever the pod identity or node assignment changes, so this message can reflect a reschedule rather than an actual configuration change. ### Design flows for resilience Because brief runtime interruptions are expected, design your flows to recover automatically: - Configure source and destination connectors to checkpoint progress so that processing resumes from the last committed position after a restart. - For streaming sources such as [Kafka](/user-guide/data-integration/openflow/connectors/kafka/about) or [Kinesis](/user-guide/data-integration/openflow/connectors/kinesis/about), rely on consumer-group offsets or sequence numbers rather than in-memory state on the runtime. - [Monitor your runtimes](/user-guide/data-integration/openflow/monitor) so that you're notified if a restart doesn't recover on its own within the expected window. - Choose your caching strategy with restarts in mind. A local, in-memory cache is cleared when a runtime node restarts, and Openflow's locally persisted caches are managed per runtime node rather than shared across the cluster. If your flow depends on cache state surviving restarts or being shared across nodes, use an external cache service such as Redis. ## Delete a deployment Deleting a deployment removes the management compute pool and all deployment-level configuration. You must delete all runtimes first. Any data or objects already integrated into Snowflake aren't affected. Deleting a deployment can't be undone. Before you delete, make sure all runtimes have been removed and you no longer need the deployment configuration. **Gen 2 (SQL):** Drop the deployment directly: ```sql DROP OPENFLOW DEPLOYMENT my_deployment; ``` **Gen 1 BYOC (AWS Console):** 1. Navigate to EC2 Instances. 2. Select the `openflow-agent-{deployment-key}` instance with your deployment key. 3. Click **Connect** at the top of the page. 4. Switch from **EC2 Instance Connect** to **Connect using EC2 Instance Connect Endpoint**. Leave the default EC2 Instance Connect Endpoint in place. 5. Click **Connect**. A new browser tab or window will appear with a command-line interface. 6. Run `./destroy.sh` from the shell. - This may take 20-30 minutes. If your connection is interrupted, the process continues running in the background. - You can log back in and view its status with the command: `journalctl -u docker -f -n 250` - The `destroy` process is complete when you see output of `delete successful`. 7. Navigate to CloudFormation (https://us-east-1.console.aws.amazon.com/cloudformation/home) in the AWS Console for your region. 8. Delete the CloudFormation stack for your deployment. From Snowsight: 1. In the navigation menu, select **Ingestion** %raa% **Openflow**. 2. Select **Launch Openflow**. 3. Select the **Deployments** tab. 4. In the row of the deployment you want to delete, select the More options icon. 5. Select **Delete**. 6. In the confirmation dialog, type `delete` to confirm deletion. 7. Click **Delete deployment**. ## Upgrade a deployment A deployment includes several components: the agent, deployment service, deployment UI, runtime gateway, and runtime operator. You can upgrade Snowflake deployments and eligible BYOC deployments directly from the UI: on the **Deployments** tab, an eligible deployment shows an **Upgrade** option in its More options (%sf-vertical-more-button%) menu. If a BYOC deployment isn't eligible, that option doesn't appear, so upgrade it using the deployment agent script instead. For details on what's included in each release, see [Openflow version history](/user-guide/data-integration/openflow/version-history). **Snowflake deployments** are upgraded automatically by Snowflake on a rolling basis. If your deployment is on an older version, it will be upgraded to the latest version automatically; you do not need to initiate the upgrade yourself. Once a deployment has been upgraded to a recent version, it will continue to receive automatic upgrades going forward. **BYOC deployments** are not upgraded automatically. You determine upgrade timing and frequency using the [deployment agent script](#upgrade-via-the-deployment-agent-byoc) or the [UI](#upgrade-from-the-ui). ### Upgrade from the UI The UI upgrade path applies to BYOC deployments. Snowflake deployments are upgraded automatically and do not require manual intervention. 1. Sign in to %sf-web-interface-link%. 2. In the navigation menu, select **Ingestion** %raa% **Openflow**. 3. Select **Launch Openflow**. 4. Select the **Deployments** tab. 5. Look for the upgrade arrow to the left of the deployment name. This indicates an upgrade is available. ![Deployments tab showing the upgrade arrow indicator next to a deployment name](/static/images/openflow/upgrade-available-deployment.png) 6. Select %sf-vertical-more-button% next to the deployment %raa% **Upgrade**. ### Upgrade via the deployment agent (BYOC) Use the deployment agent script for older BYOC deployments that cannot be upgraded via the UI, or when you prefer to upgrade manually. This upgrades the agent, deployment service, deployment UI, ingress controller, runtime operator, and all other component dependencies. #### Connect to the deployment agent 1. Navigate to Openflow. 2. Select the **Deployments** tab. 3. View your deployment details and note the deployment key. 4. In your AWS account, view the EC2 instances and filter using the deployment key. 5. Locate the deployment agent EC2 instance named `openflow-agent-{deployment-key}`. 6. Connect using EC2 Instance Connect Endpoint and accepting all defaults. 7. Run the remaining commands from the new browser tab or window that appears with a command-line interface. #### Check for available upgrades ```bash cat ~/.upgrade ``` The script will display the latest available version of the various deployment components. If no upgrades are available, you will see an output similar to this: ```text AGENT_IMAGE_VERSION_UPGRADE= OPERATOR_CHART_VERSION_UPGRADE= GATEWAY_IMAGE_VERSION_UPGRADE= DPS_CHART_VERSION_UPGRADE= DPUI_CHART_VERSION_UPGRADE= ``` Otherwise, you will see the version that upgraded components will use, such as: ```text AGENT_IMAGE_VERSION_UPGRADE=0.17.0 OPERATOR_CHART_VERSION_UPGRADE=0.31.0 GATEWAY_IMAGE_VERSION_UPGRADE= DPS_CHART_VERSION_UPGRADE= DPUI_CHART_VERSION_UPGRADE= ``` #### Upgrading the AMI for the Openflow BYOC deployment When you upgrade your Openflow BYOC deployment, Openflow will find and upgrade to the latest AMI for Amazon Linux 2023 recommended by AWS Systems Manager (https://aws.amazon.com/systems-manager/). If a new AMI is found, it will restart all Openflow services in your deployment, and runtimes will be temporarily halted. Openflow runtimes and connectors maintain data integrity across restarts automatically. Snowflake does not automatically upgrade deployments. You determine upgrade timing and frequency. #### Initiate the upgrade If the output indicates that upgrades are available, run the following script to initiate the upgrade. Older Openflow deployments may use the script `upgrade-data-plane.sh` instead. ```bash ./upgrade.sh ``` You will see output similar to this: ```text openflow-data-plane-agent-aws is set to version 0.16.0 Upgrade set to version 0.17.0 openflow-dataplane-service-chart is set to version 0.47.0 No upgrade is available openflow-dataplane-ui-chart is set to version 0.5.0 No upgrade is available openflow-runtime-gateway is set to version 2025.6.8.2 No upgrade is available runtime-operator-chart is set to version 0.30.0 Upgrade set to version 0.31.0 ``` Then, you have two options: - Wait for an automatic upgrade: The system will automatically initiate the upgrade process within approximately 10 minutes. - Manual upgrade: To start the upgrade immediately, run the following command: ```bash ./create.sh ``` #### Monitor the upgrade process To track the progress of the upgrade, use the `journalctl` command: ```bash journalctl -u openflow-apply-infrastructure -f -n 250 ``` #### Verify a successful upgrade A successful upgrade will typically show output similar to this: ```text All resources applied successfully and log uploaded to s3 openflow-apply-infrastructure.service: Deactivated successfully ``` ## Upgrade a runtime Snowflake periodically releases runtime updates that introduce new Openflow processors, newer versions of existing processors, or new runtime functionality. When updates are available, an indicator appears next to the runtime name in the UI. For details on what's included in each release, see [Openflow version history](/user-guide/data-integration/openflow/version-history). Only the owner of a deployment can perform an upgrade. 1. Sign in to %sf-web-interface-link%. 2. In the navigation menu, select **Ingestion** %raa% **Openflow**. 3. Select **Launch Openflow**. 4. Select the **Runtimes** tab. 5. Look for the upgrade arrow to the left of the runtime name. This indicates an upgrade is available. ![Runtimes tab showing the upgrade arrow indicator next to a runtime name](/static/images/openflow/upgrade-available-runtime.png) 6. Select %sf-vertical-more-button% next to the runtime %raa% **Upgrade**. ## Upgrade a connector Connector updates are made available by Snowflake when functionality is added, processing logic is improved, or new processor versions are used–for example, to add support for a new source API version. This section describes upgrading **gen 1** connectors on the runtime canvas. For gen 2 connectors, see [Manage the gen 2 Openflow connector lifecycle](/user-guide/data-integration/openflow/gen2/manage-connector-lifecycle). When connector updates are available, you will see an **Upgrade** icon in your process group on the canvas. You can only upgrade connectors after you have [upgraded their runtime](#label-openflow-upgrading-a-runtime). To upgrade a connector, do the following: 1. In the navigation menu, select **Ingestion** %raa% **Openflow**. 2. Select **Launch Openflow**. 3. Select the **Runtimes** tab. 4. Select the runtime name, or select **View Canvas** in the **More Options** menu to navigate to the canvas. 5. Find the processor groups with a red upgrade arrow next to their names. For each of these groups, change the version: 1. Recommended: Check to see whether the parameter uses a custom value for the Parameter context. If so, make a note of the custom value. You will need to reapply it after the upgrade. 1. Right-click the process group and select **Parameters**. 2. Select **Parameters** in the Parameter Contexts list. 3. Select the **Inheritance** tab, and check if it uses custom values. If so, make a note of the custom values. 2. Right-click the group and select **Version** %ra% **Change Version**. 3. Select the latest available version and select **Change**. 4. Confirm that the connector was upgraded to the latest version. The upgraded version should show a green check mark. 5. Confirm that all processors in the connector's process group are running. If not, start them. You can also validate the version by hovering over the speech bubble at the bottom right of the process group. 6. If you noted a custom parameter value in step 4, reapply the custom value. For more information, see [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors). ### Configure Snowflake Connector Flow Registry Early preview releases of Openflow did not configure a runtime for connector upgrades. If you don't see the Version option when right clicking on a process group, you have to configure the Snowflake Connector Flow Registry and manually enable version control for existing connectors. To configure the Snowflake Connector Flow Registry, do the following: 1. Navigate to the canvas. 2. Click on the menu in the top right corner and select **Controller Settings**. 3. Switch to the **Registry Clients** tab. 4. Click the **+** icon to add a new Registry Client. 5. Select the **ConnectorFlowRegistryClient** and select **Add**. 6. Click **More Options** for the **ConnectorFlowRegistryClient** row and select **Edit**. 7. Enter `/nifi/configuration_resources/connector_flow_registry` as the value for **Storage Location** and select **Apply**. After configuring the Snowflake Connector Flow Registry you can now enable version control for your existing connectors. To enable version control for existing connectors, do the following: 1. Navigate to the canvas and locate the process group where you want to add version control. 2. Right click on the process group and select **Version** %raa% **Set Version**. 3. In the **Set Version** dialog, choose the flow that matches your process group. For example, choose **sqlserver** if you are using the SQL Server connector. Note that flow names do not exactly match the connector name. 4. Select the latest version and then select **Set version** to enable version control. 5. From the canvas, right click on the process group again and select **Version** %raa% **Revert Local Changes** to apply the latest connector version. 6. Review the list of changes and select **Revert**. 7. Confirm that your connector was upgraded to the latest version which should now show a green check mark. You can also validate the version by hovering over the speech bubble at the bottom right of the process group. --- title: Manage the gen 2 Openflow connector lifecycle source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/gen2/manage-connector-lifecycle.md section: Loading & Unloading Data --- # Manage the gen 2 Openflow connector lifecycle Available to all accounts. - [Second generation Openflow objects and interfaces](/user-guide/data-integration/openflow/gen2/index) - [Openflow gen 1 and gen 2](/user-guide/data-integration/openflow/gen2/openflow-generations) - [Configure a connector with the setup wizard](/user-guide/data-integration/openflow/gen2/setup-connector-wizard) - [Monitor connectors using the Openflow Connectors Dashboard](/user-guide/data-integration/openflow/connectors-dashboard) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [ALTER OPENFLOW CONNECTOR](/sql-reference/sql/alter-openflow-connector) - [SYSTEM$WAIT_FOR_STABLE_OPENFLOW_CONNECTORS](/sql-reference/functions/system_wait_for_stable_openflow_connectors) This topic describes how to manage the **gen 2** Openflow connector lifecycle: **start and stop** ingestion and **remove** a gen 2 connector after it is created. To monitor connector health, throughput, and ingestion status, use the [Openflow Connectors Dashboard](/user-guide/data-integration/openflow/connectors-dashboard). For gen 1 connectors, follow the lifecycle guidance in each connector's public setup topic. See [Openflow gen 1 and gen 2](/user-guide/data-integration/openflow/gen2/openflow-generations) for how to tell gen 1 resources from gen 2. These tasks apply no matter how the gen 2 connector was created: using the [Configure a connector with the setup wizard](/user-guide/data-integration/openflow/gen2/setup-connector-wizard), [Configure a gen 2 connector with SQL](/user-guide/data-integration/openflow/gen2/configure-connector-sql), or other supported SQL/API automation. ## Start and stop data movement After a gen 2 connector is installed on a runtime, start it to begin reading from the source and writing to Snowflake. Use **Start** from the connector's menu on the **Installed Connectors** tab. Use **Stop** when you need to pause ingestion—for example before maintenance, upgrades described in your connector's documentation, or before removal. Stopping leaves the connector installed but idle. Some connectors retain external resources while stopped (for example, database replication slots). Do not leave connectors stopped for long periods on busy sources unless you understand the impact; see your connector's setup or maintenance topic. For **gen 2** connectors, use **Start** and **Stop** from the connector menu on **Installed Connectors**, or run `ALTER OPENFLOW CONNECTOR ... START` or `STOP` with SQL. Do not use the canvas for configuration or processor-level start/stop. See [ALTER OPENFLOW CONNECTOR](/sql-reference/sql/alter-openflow-connector) for syntax and wait functions. ## Remove a connector Gen 2 connector removal follows **stop** → **terminate** → **drop**. **`TERMINATE` drains** in-flight data before removal. Complete each step before starting the next. In UI-driven workflows, wait for each step to finish before starting the next. In scripts, call `SYSTEM$WAIT_FOR_STABLE_OPENFLOW_CONNECTORS` after asynchronous `ALTER` commands. See [SYSTEM$WAIT_FOR_STABLE_OPENFLOW_CONNECTORS](/sql-reference/functions/system_wait_for_stable_openflow_connectors). ### Remove a connector (UI) 1. From the **Installed Connectors** tab, open the connector **menu** and select **Stop**. 2. From the connector **menu** on **Installed Connectors**, select **Delete** (terminates the connector and drains in-flight data). 3. From the same menu, select **Drop**. ### Remove a connector (SQL) **Delete** in the UI corresponds to `ALTER OPENFLOW CONNECTOR ... TERMINATE`; **Drop** corresponds to `DROP OPENFLOW CONNECTOR`. `DROP` requires `OWNERSHIP` on the connector. ```sql ALTER OPENFLOW CONNECTOR my_db.my_schema.my_connector STOP; SELECT SYSTEM$WAIT_FOR_STABLE_OPENFLOW_CONNECTORS(600, 'my_db.my_schema.my_connector'); ALTER OPENFLOW CONNECTOR my_db.my_schema.my_connector TERMINATE; SELECT SYSTEM$WAIT_FOR_STABLE_OPENFLOW_CONNECTORS(600, 'my_db.my_schema.my_connector'); DROP OPENFLOW CONNECTOR my_db.my_schema.my_connector; ``` For full command syntax, privileges, and additional `ALTER` options, see [ALTER OPENFLOW CONNECTOR](/sql-reference/sql/alter-openflow-connector). **Delete**, **Drop**, `TERMINATE`, and `DROP OPENFLOW CONNECTOR` are irreversible for Openflow entities. Snowflake does not support undrop for these objects. These steps do not remove destination tables or external resources (such as PostgreSQL replication slots). Read confirmation dialogs carefully. For source-specific cleanup after removal (for example PostgreSQL replication slots), see **Stop or delete the connector** in [Set up the Openflow Connector for PostgreSQL](/user-guide/data-integration/openflow/connectors/postgres/setup) and analogous sections for other connectors. --- title: MapCacheClientService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/mapcacheclientservice.md section: Loading & Unloading Data --- # MapCacheClientService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides the ability to communicate with a MapCacheServer. This can be used in order to share a Map between nodes in a NiFi cluster ## Tags cache, cluster, distributed, map, state ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: MapCacheServer source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/mapcacheserver.md section: Loading & Unloading Data --- # MapCacheServer This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides a map (key/value) cache that can be accessed over a socket. Interaction with this service is typically accomplished via a Map Cache Client Service. ## Tags cache, cluster, distributed, key/value, map, server ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: MergeContent 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/mergecontent.md section: Loading & Unloading Data --- # MergeContent 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Merges a Group of FlowFiles together based on a user-defined strategy and packages them into a single FlowFile. It is recommended that the Processor be configured with only a single incoming connection, as Group of FlowFiles will not be created from FlowFiles in different connections. This processor updates the mime.type attribute as appropriate. NOTE: this processor should NOT be configured with Cron Driven for the Scheduling Strategy. ## Tags archive, concatenation, content, correlation, flowfile-stream, flowfile-stream-v3, merge, stream, tar, zip ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## Use cases | Concatenate FlowFiles with textual content together in order to create fewer, larger FlowFiles. | | ----------------------------------------------------------------------------------------------------------------------------------------------- | | Concatenate FlowFiles with binary content together in order to create fewer, larger FlowFiles. | | Reassemble a FlowFile that was previously split apart into smaller FlowFiles by a processor such as SplitText, UnpackContext, SplitRecord, etc. | ## See also - [org.apache.nifi.processors.standard.MergeRecord](/user-guide/data-integration/openflow/processors/mergerecord) - [org.apache.nifi.processors.standard.SegmentContent](/user-guide/data-integration/openflow/processors/segmentcontent) --- title: MergeRecord 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/mergerecord.md section: Loading & Unloading Data --- # MergeRecord 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description This Processor merges together multiple record-oriented FlowFiles into a single FlowFile that contains all of the Records of the input FlowFiles. This Processor works by creating 'bins' and then adding FlowFiles to these bins until they are full. Once a bin is full, all of the FlowFiles will be combined into a single output FlowFile, and that FlowFile will be routed to the 'merged' Relationship. A bin will consist of potentially many 'like FlowFiles'. In order for two FlowFiles to be considered 'like FlowFiles', they must have the same Schema (as identified by the Record Reader) and, if the <Correlation Attribute Name> property is set, the same value for the specified attribute. See Processor Usage and Additional Details for more information. NOTE: this processor should NOT be configured with Cron Driven for the Scheduling Strategy. ## Tags content, correlation, event, merge, record, stream ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## Use cases | Combine together many arbitrary Records in order to create a single, larger file | | -------------------------------------------------------------------------------- | ## Use Cases Involving Other Components | Combine together many Records that have the same value for a particular field in the data, in order to create a single, larger file | | ----------------------------------------------------------------------------------------------------------------------------------- | ## See also - [org.apache.nifi.processors.standard.MergeContent](/user-guide/data-integration/openflow/processors/mergecontent) - [org.apache.nifi.processors.standard.PartitionRecord](/user-guide/data-integration/openflow/processors/partitionrecord) - [org.apache.nifi.processors.standard.SplitRecord](/user-guide/data-integration/openflow/processors/splitrecord) --- title: MergeSnowflakeJournalTable 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/mergesnowflakejournaltable.md section: Loading & Unloading Data --- # MergeSnowflakeJournalTable 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-database-cdc-processors-nar ## Description Triggers a merge operation on changes from journal table to a destination table in Snowflake. The merge operation is performed asynchronously and the processor polls the result of the operation. If the query is still in progress the FlowFile will be penalized. ## Tags ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: MicrosoftClientCertificateOAuth2TokenProvider source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/microsoftclientcertificateoauth2tokenprovider.md section: Loading & Unloading Data --- # MicrosoftClientCertificateOAuth2TokenProvider This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides OAuth2 access tokens for the Microsoft Graph API using client_credentials with a client certificate. ## Tags access token, authorization, graph, http, microsoft, oauth2, provider ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: MicrosoftGraphAuthenticationProvider source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/microsoftgraphauthenticationprovider.md section: Loading & Unloading Data --- # MicrosoftGraphAuthenticationProvider This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides authentication for the Microsoft Graph API, which can be used for interacting with Microsoft 365 services. ## Tags graph, microsoft, openflow ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: Migrate from the legacy Openflow Connector for Jira Cloud source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/jira-cloud/migrate-from-legacy.md section: Loading & Unloading Data --- # Migrate from the legacy %jira% This feature is not available in the People's Republic of China. - **Generally available:** The %jiracore% flow. - **[Public Preview](https://www.snowflake.cn/en/legal/optional-offerings/offering-specific-terms/preview-terms-of-service/):** The %jiraagile% flow. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and Google Cloud Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow Connector for Jira Cloud](/user-guide/data-integration/openflow/connectors/jira-cloud/about) - [Set up the Atlassian Jira Cloud (Core) flow](/user-guide/data-integration/openflow/connectors/jira-cloud/setup-core) - [Set up the Atlassian Jira Cloud (Agile) flow](/user-guide/data-integration/openflow/connectors/jira-cloud/setup-agile) This topic describes how to migrate from the legacy %jira% to the new %jira%. ## Overview The new connector is a complete rewrite that changes how data is stored in Snowflake. It consists of two separate flows: a **core flow** (issues, projects, comments, changelogs, worklogs, users, votes, watchers, remote links, issue security schemes, deleted issues, and lookup tables for issue type, priority, resolution, and status) and an **agile flow** (boards, sprints, board mappings). The core flow and agile flow can write to the same Snowflake destination schema, since they create tables with different names. The legacy connector and the new connector can run side by side during migration — including on the same Openflow runtime — as long as they write to **separate** destination schemas, so you can validate the new output before decommissioning the legacy connector. ## Feature comparison
## Key differences ### Schema changes The most significant difference is how data is stored in Snowflake:
Field Description
`database` Required. The exact source database (PDB or CDB) name, matching the database in the table's three-part fully qualified name.
`schema` Required. The exact source schema name.
`table` Required. The exact source table name.
`logicalKey` Required. A non-empty array of source column names that uniquely identify rows in the table.
Property Description
Connection Timeout Maximum time to wait for initial socket connection to the HTTP URL.
HTTP Method HTTP request method (GET, POST, PUT, PATCH, DELETE, HEAD, OPTIONS). Arbitrary methods are also supported. Methods other than POST, PUT and PATCH will be sent without a message body.
HTTP URL HTTP remote URL including a scheme of http or https, as well as a hostname or IP address with optional port and path elements. Any encoding of the URL must be done by the user.
HTTP/2 Disabled Disable negotiation of HTTP/2 protocol. HTTP/2 requires TLS. HTTP/1.1 protocol supported is required when HTTP/2 is disabled.
OAuth2 Access Token Refresh Strategy Specifies which strategy should be used to refresh the OAuth2 Access Token.
Request Body Enabled Enable sending HTTP request body for PATCH, POST, or PUT methods.
Request Chunked Transfer-Encoding Enabled Enable sending HTTP requests with the Transfer-Encoding Header set to chunked, and disable sending the Content-Length Header. Transfer-Encoding applies to the body in HTTP/1.1 requests as described in RFC 7230 Section 3.3.1
Request Content-Encoding HTTP Content-Encoding applied to request body during transmission. The receiving server must support the selected encoding to avoid request failures.
Request Content-Type HTTP Content-Type Header applied to when sending an HTTP request body for PATCH, POST, or PUT methods. The Content-Type defaults to application/octet-stream when not configured.
Request Date Header Enabled Enable sending HTTP Date Header on HTTP requests as described in RFC 7231 Section 7.1.1.2.
Request Digest Authentication Enabled Enable Digest Authentication on HTTP requests with Username and Password credentials as described in RFC 7616.
Request Failure Penalization Enabled Enable penalization of request FlowFiles when receiving HTTP response with a status code between 400 and 499.
Request Header Attributes Pattern Regular expression that defines which FlowFile attributes to send as HTTP headers in the request. If not defined, no attributes are sent as headers. Dynamic properties will be always be sent as headers. The dynamic property name will be the header key and the dynamic property value, interpreted as Expression Language, will be the header value. Attributes and their values are limited to ASCII characters due to the requirement of the HTTP protocol.
Request Multipart Form-Data Filename Enabled Enable sending the FlowFile filename attribute as the filename parameter in the Content-Disposition Header for multipart/form-data HTTP requests.
Request Multipart Form-Data Name Enable sending HTTP request body formatted using multipart/form-data and using the form name configured.
Request OAuth2 Access Token Provider Enables managed retrieval of OAuth2 Bearer Token applied to HTTP requests using the Authorization Header.
Request Password The password provided for authentication of HTTP requests. Encoded using Base64 for HTTP Basic Authentication as described in RFC 7617.
Request User-Agent HTTP User-Agent Header applied to requests. RFC 7231 Section 5.5.3 describes recommend formatting.
Request Username The username provided for authentication of HTTP requests. Encoded using Base64 for HTTP Basic Authentication as described in RFC 7617.
Response Body Attribute Name FlowFile attribute name used to write an HTTP response body for FlowFiles transferred to the Original relationship.
Response Body Attribute Size Maximum size in bytes applied when writing an HTTP response body to a FlowFile attribute. Attributes exceeding the maximum will be truncated.
Response Body Ignored Disable writing HTTP response FlowFiles to Response relationship
Response Cache Enabled Enable HTTP response caching described in RFC 7234. Caching responses considers ETag and other headers.
Response Cache Size Maximum size of HTTP response cache in bytes. Caching responses considers ETag and other headers.
Response Cookie Strategy Strategy for accepting and persisting HTTP cookies. Accepting cookies enables persistence across multiple requests.
Response FlowFile Naming Strategy Determines the strategy used for setting the filename attribute of FlowFiles transferred to the Response relationship.
Response Generation Required Enable generation and transfer of a FlowFile to the Response relationship regardless of HTTP response status code received.
Response Header Request Attributes Enabled Enable adding HTTP response headers as attributes to FlowFiles transferred to the Original, Retry or No Retry relationships.
Response Header Request Attributes Prefix Prefix to HTTP response headers when included as attributes to FlowFiles transferred to the Original, Retry or No Retry relationships. It is recommended to end with a separator character like '.' or '-'.
Response Redirects Enabled Enable following HTTP redirects sent with HTTP 300 series responses as described in RFC 7231 Section 6.4.
SSL Context Service SSL Context Service provides trusted certificates and client certificates for TLS communication.
Socket Idle Connections Maximum number of idle connections to the HTTP URL.
Socket Idle Timeout Maximum time to wait before closing idle connections to the HTTP URL.
Socket Read Timeout Maximum time to wait for receiving responses from a socket connection to the HTTP URL.
Socket Write Timeout Maximum time to wait for write operations while sending requests from a socket connection to the HTTP URL.
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests. In case of SOCKS, it is not guaranteed that the selected SOCKS Version will be used by the processor.
Name Description
Failure Request FlowFiles transferred when receiving socket communication errors.
No Retry Request FlowFiles transferred when receiving HTTP responses with a status code between 400 an 499.
Original Request FlowFiles transferred when receiving HTTP responses with a status code between 200 and 299.
Response Response FlowFiles transferred when receiving HTTP responses with a status code between 200 and 299. Enabling [Response Generation Required] changes routing behavior, sending unsuccessful responses to their corresponding relationships and also sending FlowFiles to the Response relationship as well, regardless of status code received.
Retry Request FlowFiles transferred when receiving HTTP responses with a status code between 500 and 599.
Name Description
invokehttp.status.code The status code that is returned
invokehttp.status.message The status message that is returned
invokehttp.response.body In the instance where the status code received is not a success (2xx) then the response body will be put to the 'invokehttp.response.body' attribute of the request FlowFile.
invokehttp.request.url The original request URL
invokehttp.request.duration Duration (in milliseconds) of the HTTP call to the external endpoint
invokehttp.response.url The URL that was ultimately requested after any redirects were followed
invokehttp.tx.id The transaction ID that is returned after reading the response
invokehttp.remote.dn The DN of the remote server
invokehttp.java.exception.class The Java exception class raised when the processor fails
invokehttp.java.exception.message The Java exception message raised when the processor fails
user-defined If the 'Put Response Body In Attribute' property is set then whatever it is set to will become the attribute key and the value would be the body of the HTTP response.
Property Description
Module Directory Comma-separated list of paths to files and/or directories which contain modules required by the script.
Script Body Body of script to execute. Only one of Script File or Script Body may be used
Script Engine Language Engine for executing scripts
Script File Path to script file to execute. Only one of Script File or Script Body may be used
Scopes Description
LOCAL Scripts can store and retrieve state using the State Management APIs. Consult the State Manager section of the Developer's Guide for more details.
CLUSTER Scripts can store and retrieve state using the State Management APIs. Consult the State Manager section of the Developer's Guide for more details.
Required Permission Explanation
execute code Provides operator the ability to execute arbitrary code assuming all permissions that NiFi has.
Display Name API Name Default Value Allowable Values Description
MaxMind Database File * database-file Path to Maxmind IP Enrichment Database File
Lookup Anonymous IP Information * lookup-anonymous-ip false - true - false Specifies whether or not information about whether or not the IP address belongs to an anonymous network should be returned.
Lookup Geo Enrichment * lookup-city true - true - false Specifies whether or not information about the geographic information, such as cities, corresponding to the IP address should be returned
Lookup Connection Type * lookup-connection-type false - true - false Specifies whether or not information about the Connection Type corresponding to the IP address should be returned. If true, the lookup will contain a 'connectionType' field that (if populated) will contain a value of 'Dialup', 'Cable/DSL', 'Corporate', or 'Cellular'
Lookup Domain Name * lookup-domain false - true - false Specifies whether or not information about the Domain Name corresponding to the IP address should be returned. If true, the lookup will contain second-level domain information, such as foo.com but will not contain bar.foo.com
Lookup ISP * lookup-isp false - true - false Specifies whether or not information about the Information Service Provider corresponding to the IP address should be returned
Property Description
IP Address Attribute The name of an attribute whose value is a dotted decimal IP address for which enrichment should occur
Log Level The Log Level to use when an IP is not found in the database. Accepted values: INFO, DEBUG, WARN, ERROR.
MaxMind Database File Path to Maxmind IP Enrichment Database File
Name Description
found Where to route flow files after successfully enriching attributes with data provided by database
not found Where to route flow files after unsuccessfully enriching attributes because no data was found
Name Description
X.isp.lookup.micros The number of microseconds that the geo lookup took
X.isp.asn The Autonomous System Number (ASN) identified for the IP address
X.isp.asn.organization The Organization Associated with the ASN identified
X.isp.name The name of the ISP associated with the IP address provided
X.isp.organization The Organization associated with the IP address provided
Display Name API Name Default Value Allowable Values Description
Authentication Header Charset * Authentication Header Charset US-ASCII The charset for Basic Authentication header base64 string.
Connection Attempt Count * Connection Attempt Count 3 The number of times to try and establish a connection.
Connection Timeout * Connection Timeout 3 sec The timeout to connect the WebSocket URI.
Custom Authorization Custom Authorization Configures a custom HTTP Authorization Header as described in RFC 7235 Section 4.2. Setting a custom Authorization Header excludes configuring the User Name and User Password properties for Basic Authentication.
HTTP Proxy Host HTTP Proxy Host The host name of the HTTP Proxy.
HTTP Proxy Port HTTP Proxy Port The port number of the HTTP Proxy.
Idle Timeout * Idle Timeout 0 sec The maximum amount of time that a WebSocket connection may remain idle before it is closed. A value of 0 sec disables the timeout.
Input Buffer Size * Input Buffer Size 4 kb The size of the input (read from network layer) buffer size.
Max Binary Message Size * Max Binary Message Size 64 kb The maximum size of a binary message during parsing/generating.
Max Text Message Size * Max Text Message Size 64 kb The maximum size of a text message during parsing/generating.
Password Password The user password for Basic Authentication.
SSL Context Service SSL Context Service The SSL Context Service to use in order to secure the server. If specified, the server will accept only WSS requests; otherwise, the server will accept only WS requests
Session Maintenance Interval * Session Maintenance Interval 10 sec The interval between session maintenance activities. A WebSocket session established with a WebSocket server can be terminated due to different reasons including restarting the WebSocket server or timing out inactive sessions. This session maintenance activity is periodically executed in order to reconnect those lost sessions, so that a WebSocket client can reuse the same session id transparently after it reconnects successfully. The maintenance activity is executed until corresponding processors or this controller service is stopped.
Username Username The user name for Basic Authentication.
WebSocket URI * WebSocket URI The WebSocket URI this client connects to.
Display Name API Name Default Value Allowable Values Description
Basic Authentication Enabled * Basic Authentication Enabled false - true - false If enabled, client connection requests are authenticated with Basic authentication using the specified Login Provider.
Basic Authentication Path Spec Basic Authentication Path Spec /* Specify a Path Spec to apply Basic Authentication.
Basic Authentication Roles Basic Authentication Roles `**` The authenticated user must have one of specified role. Multiple roles can be set as comma separated string. '*' represents any role and so does '**' any role including no role.
Client Authentication * Client Authentication no - No Authentication - Want Authentication - Need Authentication Specifies whether or not the Processor should authenticate client by its certificate. This value is ignored if the <SSL Context Service> Property is not specified or the SSL Context provided uses only a KeyStore and not a TrustStore.
Idle Timeout * Idle Timeout 0 sec The maximum amount of time that a WebSocket connection may remain idle before it is closed. A value of 0 sec disables the timeout.
Input Buffer Size * Input Buffer Size 4 kb The size of the input (read from network layer) buffer size.
Login Service Login Service hash - HashLoginService Specify which Login Service to use for Basic Authentication.
Max Binary Message Size * Max Binary Message Size 64 kb The maximum size of a binary message during parsing/generating.
Max Text Message Size * Max Text Message Size 64 kb The maximum size of a text message during parsing/generating.
Port * Port The port number on which this WebSocketServer listens to.
SSL Context Service SSL Context Service The SSL Context Service to use in order to secure the server. If specified, the server will accept only WSS requests; otherwise, the server will accept only WS requests
Users Properties File users-properties-file Specify a property file containing users for Basic Authentication using HashLoginService. See http://www.eclipse.org/jetty/documentation/current/configuring-security.html (http://www.eclipse.org/jetty/documentation/current/configuring-security.html) for detail.
Display Name API Name Default Value Allowable Values Description
JMS SSL Context Service SSL Context Service The SSL Context Service used to provide client certificate information for TLS/SSL connections.
JMS Broker URI broker URI pointing to the network location of the JMS Message broker. Example for ActiveMQ: '[tcp://myhost:61616](tcp://myhost:61616)'. Examples for IBM MQ: 'myhost(1414)' and 'myhost01(1414),myhost02(1414)'.
JMS Connection Factory Implementation Class * cf The fully qualified name of the JMS ConnectionFactory implementation class (eg. org.apache.activemq.ActiveMQConnectionFactory).
JMS Client Libraries cflib Path to the directory with additional resources (eg. JARs, configuration files etc.) to be added to the classpath (defined as a comma separated list of values). Such resources typically represent target JMS client libraries for the ConnectionFactory implementation.
Required Permission Explanation
reference remote resources Client Library Location can reference resources over HTTP
Display Name API Name Default Value Allowable Values Description
JNDI Name of the Connection Factory * connection.factory.name The name of the JNDI Object to lookup for the Connection Factory.
JNDI Initial Context Factory Class * java.naming.factory.initial The fully qualified class name of the JNDI Initial Context Factory Class (java.naming.factory.initial).
JNDI Provider URL * java.naming.provider.url The URL of the JNDI Provider to use as the value for java.naming.provider.url. See additional details documentation for allowed URL schemes.
JNDI Credentials java.naming.security.credentials The Credentials to use when authenticating with JNDI (java.naming.security.credentials).
JNDI Principal java.naming.security.principal The Principal to use when authenticating with JNDI (java.naming.security.principal).
JNDI / JMS Client Libraries naming.factory.libraries Specifies jar files and/or directories to add to the ClassPath in order to load the JNDI / JMS client libraries. This should be a comma-separated list of files, directories, and/or URLs. If a directory is given, any files in that directory will be included, but subdirectories will not be included (i.e., it is not recursive).
Property Description
Default Decimal Precision When a DECIMAL/NUMBER value is written as a 'decimal' Avro logical type, a specific 'precision' denoting number of available digits is required. Generally, precision is defined by column data type definition or database engines default. However undefined precision (0) can be returned from some database engines. 'Default Decimal Precision' is used when writing those undefined precision numbers.
Default Decimal Scale When a DECIMAL/NUMBER value is written as a 'decimal' Avro logical type, a specific 'scale' denoting number of available decimal digits is required. Generally, scale is defined by column data type definition or database engines default. However when undefined precision (0) is returned, scale can also be uncertain with some database engines. 'Default Decimal Scale' is used when writing those undefined numbers. If a value has more decimals than specified scale, then the value will be rounded-up, e.g. 1.53 becomes 2 with scale 0, and 1.5 with scale 1.
Enrichment Record Reader The Record Reader for reading the 'enrichment' FlowFile
Insertion Record Path Specifies where in the 'original' Record the 'enrichment' Record's fields should be inserted. Note that if the RecordPath does not point to any existing field in the original Record, the enrichment will not be inserted.
Join Strategy Specifies how to join the two FlowFiles into a single FlowFile
Maximum number of Bins Specifies the maximum number of bins that can be held in memory at any one time
Original Record Reader The Record Reader for reading the 'original' FlowFile
Record Writer The Record Writer to use for writing the results. If the Record Writer is configured to inherit the schema from the Record, the schema that it will inherit will be the result of merging both the 'original' record schema and the 'enrichment' record schema.
SQL The SQL SELECT statement to evaluate. Expression Language may be provided, but doing so may result in poorer performance. Because this Processor is dealing with two FlowFiles at a time, it 's also important to understand how attributes will be referenced. If both FlowFiles have an attribute with the same name but different values, the Expression Language will resolve to the value provided by the' enrichment' FlowFile.
Timeout Specifies the maximum amount of time to wait for the second FlowFile once the first arrives at the processor, after which point the first FlowFile will be routed to the 'timeout' relationship.
Name Description
failure If both the 'original' and 'enrichment' FlowFiles arrive at the processor but there was a failure in joining the records, both of those FlowFiles will be routed to this relationship.
joined The resultant FlowFile with Records joined together from both the original and enrichment FlowFiles will be routed to this relationship
original Both of the incoming FlowFiles ('original' and 'enrichment') will be routed to this Relationship. I.e., this is the 'original' version of both of these FlowFiles.
timeout If one of the incoming FlowFiles (i.e., the 'original' FlowFile or the 'enrichment' FlowFile) arrives to this Processor but the other does not arrive within the configured Timeout period, the FlowFile that did arrive is routed to this relationship.
Name Description
mime.type Sets the mime.type attribute to the MIME Type specified by the Record Writer
record.count The number of records in the FlowFile
Property Description
Custom Module Directory Comma-separated list of paths to files and/or directories which contain modules containing custom transformations (that are not included on NiFi's classpath).
Custom Transformation Class Name Fully Qualified Class Name for Custom Transformation
JSON Source Specifies whether the Jolt transformation is applied to FlowFile JSON content or to specified FlowFile JSON attribute.
JSON Source Attribute The FlowFile attribute containing JSON to be transformed.
Jolt Specification Jolt Specification for transformation of JSON data. The value for this property may be the text of a Jolt specification or the path to a file containing a Jolt specification. 'Jolt Specification' must be set, or the value is ignored if the Jolt Sort Transformation is selected.
Jolt Transform Specifies the Jolt Transformation that should be used with the provided specification.
Max String Length The maximum allowed length of a string value when parsing the JSON document
Pretty Print Apply pretty print formatting to the output of the Jolt transform
Transform Cache Size Compiling a Jolt Transform can be fairly expensive. Ideally, this will be done only once. However, if the Expression Language is used in the transform, we may need a new Transform for each FlowFile. This value controls how many of those Transforms we cache in memory in order to avoid having to compile the Transform each time.
Name Description
failure If the JSON transformation fails (e.g., due to invalid JSON in the content or attribute), the original FlowFile is routed to this relationship.
success The FlowFile with successfully transformed content or updated attribute will be routed to this relationship
Name Description
mime.type Always set to application/json
Property Description
Custom Module Directory Comma-separated list of paths to files and/or directories which contain modules containing custom transformations (that are not included on NiFi's classpath).
Custom Transformation Class Name Fully Qualified Class Name for Custom Transformation
Jolt Specification Jolt Specification for transformation of JSON data. The value for this property may be the text of a Jolt specification or the path to a file containing a Jolt specification. 'Jolt Specification' must be set, or the value is ignored if the Jolt Sort Transformation is selected.
Jolt Transform Specifies the Jolt Transformation that should be used with the provided specification.
Transform Cache Size Compiling a Jolt Transform can be fairly expensive. Ideally, this will be done only once. However, if the Expression Language is used in the transform, we may need a new Transform for each FlowFile. This value controls how many of those Transforms we cache in memory in order to avoid having to compile the Transform each time.
jolt-record-record-reader Specifies the Controller Service to use for parsing incoming data and determining the data's schema.
jolt-record-record-writer Specifies the Controller Service to use for writing out the records
Name Description
failure If a FlowFile fails processing for any reason (for example, the FlowFile records cannot be parsed), it will be routed to this relationship
original The original FlowFile that was transformed. If the FlowFile fails processing, nothing will be sent to this relationship
success The FlowFile with transformed content will be routed to this relationship
Name Description
record.count The number of records in an outgoing FlowFile
mime.type The MIME Type that the configured Record Writer indicates is appropriate
Property Description
jslt-transform-cache-size Compiling a JSLT Transform can be fairly expensive. Ideally, this will be done only once. However, if the Expression Language is used in the transform, we may need a new Transform for each FlowFile. This value controls how many of those Transforms we cache in memory in order to avoid having to compile the Transform each time.
jslt-transform-pretty_print Apply pretty-print formatting to the output of the JSLT transform
jslt-transform-result-filter A filter for output JSON results using a JSLT expression. This property supports changing the default filter, which removes JSON objects with null values, empty objects and empty arrays from the output JSON. This JSLT must return true for each JSON object to be included and false for each object to be removed. Using a filter value of "true" to disables filtering.
jslt-transform-transformation JSLT Transformation for transform of JSON data. Any NiFi Expression Language present will be evaluated first to get the final transform to be applied. The JSLT Tutorial provides an overview of supported expressions: https://github.com/schibsted/jslt/blob/master/tutorial.md (https://github.com/schibsted/jslt/blob/master/tutorial.md)
jslt-transform-transformation-strategy Whether to apply the JSLT transformation to the entire FlowFile contents or each JSON object in the root-level array
Name Description
failure If a FlowFile fails processing for any reason (for example, the FlowFile is not valid JSON), it will be routed to this relationship
success The FlowFile with transformed content will be routed to this relationship
Name Description
mime.type Always set to application/json
Display Name API Name Default Value Allowable Values Description
Account ID * Account ID The ID of the Box account which the app will act on behalf of.
App Actor * App Actor impersonated-user - Service Account - Impersonated User Specifies on behalf of whom Box API calls will be made.
App Config File App Config File Full path of an App config JSON file. See Additional Details for more information.
App Config JSON App Config JSON The raw JSON containing an App config. See Additional Details for more information.
Connect Timeout * Connect Timeout 10 secs Maximum amount of time to wait before failing during initial socket connection.
Read Timeout * Read Timeout 30 secs Maximum amount of time to wait before failing while reading socket responses.
Proxy Configuration Service proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Display Name API Name Default Value Allowable Values Description
Allow Comments * Allow Comments false - true - false Whether to allow comments when parsing the JSON document
Date Format Date Format Specifies the format to use when reading/writing Date fields. If not specified, Date fields will be assumed to be number of milliseconds since epoch (Midnight, Jan 1, 1970 GMT). If specified, the value must match the Java java.time.format.DateTimeFormatter format (for example, MM/dd/yyyy for a two-digit month, followed by a two-digit day, followed by a four-digit year, all separated by '/' characters, as in 01/01/2017).
Max String Length * Max String Length 20 MB The maximum allowed length of a string value when parsing the JSON document
Schema Access Strategy * Schema Access Strategy infer-schema - Use 'Schema Name' Property - Use 'Schema Text' Property - Schema Reference Reader - Infer Schema Specifies how to obtain the schema that is to be used for interpreting the data.
Schema Branch Schema Branch Specifies the name of the branch to use when looking up the schema in the Schema Registry property. If the chosen Schema Registry does not support branching, this value will be ignored.
Schema Name Schema Name $\{schema.name\} Specifies the name of the schema to lookup in the Schema Registry property
Schema Reference Reader * Schema Reference Reader Service implementation responsible for reading FlowFile attributes or content to determine the Schema Reference Identifier
Schema Registry Schema Registry Specifies the Controller Service to use for the Schema Registry
Schema Text Schema Text $\{avro.schema\} The text of an Avro-formatted Schema
Schema Version Schema Version Specifies the version of the schema to lookup in the Schema Registry. If not specified then the latest version of the schema will be retrieved.
Time Format Time Format Specifies the format to use when reading/writing Time fields. If not specified, Time fields will be assumed to be number of milliseconds since epoch (Midnight, Jan 1, 1970 GMT). If specified, the value must match the Java java.time.format.DateTimeFormatter format (for example, HH:mm:ss for a two-digit hour in 24-hour format, followed by a two-digit minute, followed by a two-digit second, all separated by ':' characters, as in 18:04:15).
Timestamp Format Timestamp Format Specifies the format to use when reading/writing Timestamp fields. If not specified, Timestamp fields will be assumed to be number of milliseconds since epoch (Midnight, Jan 1, 1970 GMT). If specified, the value must match the Java java.time.format.DateTimeFormatter format (for example, MM/dd/yyyy HH:mm:ss for a two-digit month, followed by a two-digit day, followed by a four-digit year, all separated by '/' characters; and then followed by a two-digit hour in 24-hour format, followed by a two-digit minute, followed by a two-digit second, all separated by ':' characters, as in 01/01/2017 18:04:15).
Property Description
Aggregation Results Format Format of Aggregation output.
Aggregation Results Split Output a flowfile containing all aggregations or one flowfile for each individual aggregation.
Aggregations One or more query aggregations (or "aggs"), in JSON syntax. Ex: \{"items": \{"terms": \{"field": "product", "size": 10\}\}\}
Client Service An Elasticsearch client service to use for running queries.
Fields Fields of indexed documents to be retrieved, in JSON syntax. Ex: ["user.id", "http.response.*", \{"field": "@timestamp", "format": "epoch_millis"\}]
Index The name of the index to use.
Max JSON Field String Length The maximum allowed length of a string value when parsing a JSON document or attribute.
Output No Hits Output a "hits" flowfile even if no hits found for query. If true, an empty "hits" flowfile will be output even if "aggregations" are output.
Query A query in JSON syntax, not Lucene syntax. Ex: \{"query":\{"match":\{"somefield":"somevalue"\}\}\}. If this parameter is not set, the query will be read from the flowfile content. If the query (property and flowfile content) is empty, a default empty JSON Object will be used, which will result in a "match_all" query in Elasticsearch.
Query Attribute If set, the executed query will be set on each result flowfile in the specified attribute.
Query Clause A "query" clause in JSON syntax, not Lucene syntax. Ex: \{"match":\{"somefield":"somevalue"\}\}. If the query is empty, a default JSON Object will be used, which will result in a "match_all" query in Elasticsearch.
Query Definition Style How the JSON Query will be defined for use by the processor.
Script Fields Fields to created using script evaluation at query runtime, in JSON syntax. Ex: \{"test1": \{"script": \{"lang": "painless", "source": "doc[ 'price'].value * 2"\}\}, "test2": \{"script": \{"lang": "painless", "source": "doc[ 'price'].value * params.factor", "params": \{"factor": 2.0\}\}\}\}
Search Results Format Format of Hits output.
Search Results Split Output a flowfile containing all hits or one flowfile for each individual hit.
Size The maximum number of documents to retrieve in the query. If the query is paginated, this "size" applies to each page of the query, not the "size" of the entire result set.
Sort Sort results by one or more fields, in JSON syntax. Ex: [\{"price" : \{"order" : "asc", "mode" : "avg"\}\}, \{"post_date" : \{"format": "strict_date_optional_time_nanos"\}\}]
Type The type of this document (used by Elasticsearch for indexing and searching).
Name Description
aggregations Aggregations are routed to this relationship.
failure All flowfiles that fail for reasons unrelated to server availability go to this relationship.
hits Search hits are routed to this relationship.
original All original flowfiles that don't cause an error to occur go to this relationship.
Name Description
mime.type application/json
aggregation.name The name of the aggregation whose results are in the output flowfile
aggregation.number The number of the aggregation whose results are in the output flowfile
hit.count The number of hits that are in the output flowfile
elasticsearch.query.error The error message provided by Elasticsearch if there is an error querying the index.
Display Name API Name Default Value Allowable Values Description
Allow Scientific Notation * Allow Scientific Notation false - true - false Specifies whether or not scientific notation should be used when writing numbers
Date Format Date Format Specifies the format to use when reading/writing Date fields. If not specified, Date fields will be assumed to be number of milliseconds since epoch (Midnight, Jan 1, 1970 GMT). If specified, the value must match the Java java.time.format.DateTimeFormatter format (for example, MM/dd/yyyy for a two-digit month, followed by a two-digit day, followed by a four-digit year, all separated by '/' characters, as in 01/01/2017).
Pretty Print JSON * Pretty Print JSON false - true - false Specifies whether or not the JSON should be pretty printed
Schema Access Strategy * Schema Access Strategy inherit-record-schema - Inherit Record Schema - Use 'Schema Name' Property - Use 'Schema Text' Property Specifies how to obtain the schema that is to be used for interpreting the data.
Schema Branch Schema Branch Specifies the name of the branch to use when looking up the schema in the Schema Registry property. If the chosen Schema Registry does not support branching, this value will be ignored.
Schema Cache Schema Cache Specifies a Schema Cache to add the Record Schema to so that Record Readers can quickly lookup the schema.
Schema Name Schema Name $\{schema.name\} Specifies the name of the schema to lookup in the Schema Registry property
Schema Reference Reader * Schema Reference Reader Service implementation responsible for reading FlowFile attributes or content to determine the Schema Reference Identifier
Schema Reference Writer * Schema Reference Writer Service implementation responsible for writing FlowFile attributes or content header with Schema reference information
Schema Registry Schema Registry Specifies the Controller Service to use for the Schema Registry
Schema Text Schema Text $\{avro.schema\} The text of an Avro-formatted Schema
Schema Version Schema Version Specifies the version of the schema to lookup in the Schema Registry. If not specified then the latest version of the schema will be retrieved.
Schema Write Strategy * Schema Write Strategy no-schema - Do Not Write Schema - Set 'schema.name' Attribute - Set 'avro.schema' Attribute - Schema Reference Writer Specifies how the schema for a Record should be added to the data.
Time Format Time Format Specifies the format to use when reading/writing Time fields. If not specified, Time fields will be assumed to be number of milliseconds since epoch (Midnight, Jan 1, 1970 GMT). If specified, the value must match the Java java.time.format.DateTimeFormatter format (for example, HH:mm:ss for a two-digit hour in 24-hour format, followed by a two-digit minute, followed by a two-digit second, all separated by ':' characters, as in 18:04:15).
Timestamp Format Timestamp Format Specifies the format to use when reading/writing Timestamp fields. If not specified, Timestamp fields will be assumed to be number of milliseconds since epoch (Midnight, Jan 1, 1970 GMT). If specified, the value must match the Java java.time.format.DateTimeFormatter format (for example, MM/dd/yyyy HH:mm:ss for a two-digit month, followed by a two-digit day, followed by a four-digit year, all separated by '/' characters; and then followed by a two-digit hour in 24-hour format, followed by a two-digit minute, followed by a two-digit second, all separated by ':' characters, as in 01/01/2017 18:04:15).
Compression Format * compression-format none - none - gzip - bzip2 - xz-lzma2 - snappy - snappy framed - zstd The compression format to use. Valid values are: GZIP, BZIP2, ZSTD, XZ-LZMA2, LZMA, Snappy, and Snappy Framed
Compression Level * compression-level 1 - 0 - 1 - 2 - 3 - 4 - 5 - 6 - 7 - 8 - 9 The compression level to use; this is valid only when using GZIP compression. A lower value results in faster processing but less compression; a value of 0 indicates no compression but simply archiving
Output Grouping * output-grouping output-array - Array - One Line Per Object Specifies how the writer should output the JSON records (as an array or one object per line, e.g.) Note that if 'One Line Per Object' is selected, then Pretty Print JSON must be false.
Suppress Null Values * suppress-nulls never-suppress - Never Suppress - Always Suppress - Suppress Missing Values Specifies how the writer should handle a null field
Display Name API Name Default Value Allowable Values Description
Filter JSON Filter JSON JSON representation of the column filter
Display Name API Name Default Value Allowable Values Description
Allow Comments * Allow Comments false - true - false Whether to allow comments when parsing the JSON document
Date Format Date Format Specifies the format to use when reading/writing Date fields. If not specified, Date fields will be assumed to be number of milliseconds since epoch (Midnight, Jan 1, 1970 GMT). If specified, the value must match the Java java.time.format.DateTimeFormatter format (for example, MM/dd/yyyy for a two-digit month, followed by a two-digit day, followed by a four-digit year, all separated by '/' characters, as in 01/01/2017).
Max String Length * Max String Length 20 MB The maximum allowed length of a string value when parsing the JSON document
Schema Access Strategy * Schema Access Strategy infer-schema - Infer Schema - Use 'Schema Name' Property - Use 'Schema Text' Property - Schema Reference Reader Specifies how to obtain the schema that is to be used for interpreting the data.
Schema Branch Schema Branch Specifies the name of the branch to use when looking up the schema in the Schema Registry property. If the chosen Schema Registry does not support branching, this value will be ignored.
Schema Name Schema Name $\{schema.name\} Specifies the name of the schema to lookup in the Schema Registry property
Schema Reference Reader * Schema Reference Reader Service implementation responsible for reading FlowFile attributes or content to determine the Schema Reference Identifier
Schema Registry Schema Registry Specifies the Controller Service to use for the Schema Registry
Schema Text Schema Text $\{avro.schema\} The text of an Avro-formatted Schema
Schema Version Schema Version Specifies the version of the schema to lookup in the Schema Registry. If not specified then the latest version of the schema will be retrieved.
Time Format Time Format Specifies the format to use when reading/writing Time fields. If not specified, Time fields will be assumed to be number of milliseconds since epoch (Midnight, Jan 1, 1970 GMT). If specified, the value must match the Java java.time.format.DateTimeFormatter format (for example, HH:mm:ss for a two-digit hour in 24-hour format, followed by a two-digit minute, followed by a two-digit second, all separated by ':' characters, as in 18:04:15).
Timestamp Format Timestamp Format Specifies the format to use when reading/writing Timestamp fields. If not specified, Timestamp fields will be assumed to be number of milliseconds since epoch (Midnight, Jan 1, 1970 GMT). If specified, the value must match the Java java.time.format.DateTimeFormatter format (for example, MM/dd/yyyy HH:mm:ss for a two-digit month, followed by a two-digit day, followed by a four-digit year, all separated by '/' characters; and then followed by a two-digit hour in 24-hour format, followed by a two-digit minute, followed by a two-digit second, all separated by ':' characters, as in 01/01/2017 18:04:15).
Schema Application Strategy * schema-application-strategy SELECTED_PART - Whole JSON - Selected Part Specifies whether the schema is defined for the whole JSON or for the selected part starting from "Starting Field Name".
Schema Inference Cache schema-inference-cache Specifies a Schema Cache to use when inferring the schema. If not populated, the schema will be inferred each time. However, if a cache is specified, the cache will first be consulted and if the applicable schema can be found, it will be used instead of inferring the schema.
Starting Field Name starting-field-name Skips forward to the given nested JSON field (array or object) to begin processing.
Starting Field Strategy * starting-field-strategy ROOT_NODE - Root Node - Nested Field Start processing from the root node or from a specified nested node.
Display Name API Name Default Value Allowable Values Description
Assertion Parameter Name * Assertion Parameter Name assertion Name of the parameter to use for the JWT assertion in the request to the token endpoint.
Audience Audience The audience claim (aud) for the JWT. Space-separated list of audiences if multiple are expected.
Grant Type * Grant Type [urn:ietf:params:oauth:grant-type:jwt-bearer](urn:ietf:params:oauth:grant-type:jwt-bearer) Value to set for the grant_type parameter in the request to the token endpoint.
Issuer Issuer The issuer claim (iss) for the JWT.
JWT Expiration Time * JWT Expiration Time 1 hour Expiration time used to set the corresponding claim of the JWT. In case the returned access token does not includean expiration time, this will be used with the refresh window to re-acquire a new access token.
JWT ID JWT ID The "jti" (JWT ID) claim provides a unique identifier for the JWT. The identifier value must be assigned in amanner that ensures that there's a negligible probability that the same value will be accidentally assigned to adifferent data object; if the application uses multiple issuers, collisions MUST be prevented among values producedby different issuers as well. The "jti" value is a case-sensitive string. If set, it is recommended to set thisvalue to $\{UUID()\}.
Key ID Key ID The ID of the public key used to sign the JWT. It'll be used as the kid header in the JWT.
Private Key Service * Private Key Service The private key service to use for signing JWTs.
Refresh Window * Refresh Window 5 minutes The service will attempt to refresh tokens expiring within the refresh window, subtracting the configured duration from the token expiration.
SSL Context Service * SSL Context Service An instance of SSLContextProvider configured with a certificate that will be used to set the x5t header. Must be using RSA algorithm.
Scope Scope The scope claim (scope) for the JWT.
Set JWT Header X.509 Cert Thumbprint * Set JWT Header X.509 Cert Thumbprint false - true - false If true, will set the JWT header x5t field with the base64url-encoded SHA-256 thumbprint of the X.509 certificate's DER encoding.If set to true, an instance of SSLContextProvider must be configured with a certificate using RSA algorithm.
Signing Algorithm * Signing Algorithm PS256 - RS256 - RS384 - RS512 - PS256 - PS384 - PS512 - ES256 - ES384 - ES512 - Ed25519 The algorithm to use for signing the JWT.
Subject Subject The subject claim (sub) for the JWT.
Token Endpoint URL * Token Endpoint URL The URL of the OAuth2 token endpoint.
Web Client Service * Web Client Service The Web Client Service to use for calling the token endpoint.
Display Name API Name Default Value Allowable Values Description
SSL Context Service SSL Context Service Service supporting SSL communication with Kafka brokers
Acknowledgment Wait Time * ack.wait.time 5 sec After sending a message to Kafka, this indicates the amount of time that the service will wait for a response from Kafka.If Kafka does not acknowledge the message within this time period, the service will throw an exception.
Bootstrap Servers * bootstrap.servers Comma-separated list of Kafka Bootstrap Servers in the format host:port. Corresponds to Kafka bootstrap.servers property
Client Timeout * default.api.timeout.ms 60 sec Default timeout for Kafka client operations. Mapped to Kafka default.api.timeout.ms. The Kafka request.timeout.ms property is derived from half of the configured timeout
Transaction Isolation Level * isolation.level read_committed - Read Committed - Read Uncommitted Specifies how the service should handle transaction isolation levels when communicating with Kafka.The uncommitted option means that messages will be received as soon as they are written to Kafka but will be pulled, even if the producer cancels the transactions.The committed option configures the service to not receive any messages for which the producer's transaction was canceled, but this can result in some latency since theconsumer must wait for the producer to finish its entire transaction instead of pulling as the messages become available.Corresponds to Kafka isolation.level property.
Max Metadata Wait Time * max.block.ms 5 sec The amount of time publisher will wait to obtain metadata or wait for the buffer to flush during the 'send' call before failing theentire 'send' call. Corresponds to Kafka max.block.ms property
Max Poll Records * max.poll.records 10000 Maximum number of records Kafka should return in a single poll.
SASL Mechanism * sasl.mechanism GSSAPI - GSSAPI - PLAIN - SCRAM-SHA-256 - SCRAM-SHA-512 SASL mechanism used for authentication. Corresponds to Kafka Client sasl.mechanism property
SASL Password * sasl.password Password provided with configured username when using PLAIN or SCRAM SASL Mechanisms
SASL Username * sasl.username Username provided with configured password when using PLAIN or SCRAM SASL Mechanisms
Security Protocol * security.protocol PLAINTEXT - PLAINTEXT - SSL - SASL_PLAINTEXT - SASL_SSL Security protocol used to communicate with brokers. Corresponds to Kafka Client security.protocol property
Property Description
HubSpot Service HubSpot Client Service.
Object Type HubSpot object type
Updated After Filter objects updated after specified date (format: yyyy-MM-dd)
Scopes Description
CLUSTER Maintains pagination state and last sync timestamp to continue data retrieval from the last known position after restarts and to fetch only changed data.
Name Description
failure HubSpot fail relationship
original The input Flow File is routed to the original relationship.
retry HubSpot retry relationship. FlowFiles that failed to process due to a server timeout or rate limit related error. FlowFiles routed here should be routed back into the processor.
success HubSpot success relationship
Name Description
mime.type application/json
statement.type DELETE
hubspot.object.type HubSpot Object Type for this fetch
hubspot.object.id HubSpot Object ID for this fetch
hubspot.run.id Timestamp of the start of this run. Obtained from the incoming FlowFile or current time if not available
hubspot.is_last Whether this is the last paged object of the ingestion
Property Description
Blob Name Prefix Search prefix for listing
Container Name Name of the Azure storage container. In case of PutAzureBlobStorage processor, container can be created if it does not exist.
Entity Tracking Initial Listing Target Specify how initial listing should be handled. Used by 'Tracking Entities'strategy.
Entity Tracking State Cache Listed entities are stored in the specified cache storage so that this processor can resume listing across NiFi restart or in case of primary node change. 'Tracking Entities'strategy require tracking information of all listed entities within the last 'Tracking Time Window'. To support large number of entities, the strategy uses DistributedMapCache instead of managed state. Cache key format is 'ListedEntities::\{processorId\}(::\{nodeId\})'. If it tracks per node listed entities, then the optional '::\{nodeId\}' part is added to manage state separately. E.g. cluster wide cache key ='ListedEntities::8dda2321-0164-1000-50fa-3042fe7d6a7b', per node cache key ='ListedEntities::8dda2321-0164-1000-50fa-3042fe7d6a7b::nifi-node3' The stored cache content is Gzipped JSON string. The cache key will be deleted when target listing configuration is changed. Used by 'Tracking Entities'strategy.
Entity Tracking Time Window Specify how long this processor should track already-listed entities. 'Tracking Entities'strategy can pick any entity whose timestamp is inside the specified time window. For example, if set to '30 minutes', any entity having timestamp in recent 30 minutes will be the listing target when this processor runs. A listed entity is considered 'new/updated' and a FlowFile is emitted if one of following condition meets: 1. does not exist in the already-listed entities, 2. has newer timestamp than the cached entity, 3. has different size than the cached entity. If a cached entity 's timestamp becomes older than specified time window, that entity will be removed from the cached already-listed entities. Used by'Tracking Entities'strategy.
Listing Strategy Specify how to determine new/updated entities. See each strategy descriptions for detail.
Maximum File Age The maximum age that a file must be in order to be pulled; any file older than this amount of time (according to last modification date) will be ignored
Maximum File Size The maximum size that a file can be in order to be pulled
Minimum File Age The minimum age that a file must be in order to be pulled; any file younger than this amount of time (according to last modification date) will be ignored
Minimum File Size The minimum size that a file must be in order to be pulled
Record Writer Specifies the Record Writer to use for creating the listing. If not specified, one FlowFile will be created for each entity that is listed. If the Record Writer is specified, all entities will be written to a single FlowFile instead of adding attributes to individual FlowFiles.
Storage Credentials Controller Service used to obtain Azure Blob Storage Credentials.
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests. In case of SOCKS, it is not guaranteed that the selected SOCKS Version will be used by the processor.
Scopes Description
CLUSTER After performing a listing of blobs, the timestamp of the newest blob is stored if 'Tracking Timestamps' Listing Strategy is in use (by default). This allows the Processor to list only blobs that have been added or modified after this date the next time that the Processor is run. State is stored across the cluster so that this Processor can be run on Primary Node only and if a new Primary Node is selected, the new node can pick up where the previous node left off, without duplicating the data.
Name Description
success All FlowFiles that are received are routed to success
Name Description
azure.container The name of the Azure Blob Storage container
azure.blobname The name of the blob on Azure Blob Storage
azure.primaryUri Primary location of the blob
azure.etag ETag of the blob
azure.blobtype Type of the blob (either BlockBlob, PageBlob or AppendBlob)
mime.type MIME Type of the content
lang Language code for the content
azure.timestamp Timestamp of the blob
azure.length Length of the blob
Property Description
ADLS Credentials Controller Service used to obtain Azure Credentials.
Directory Name Name of the Azure Storage Directory. The Directory Name cannot contain a leading '/'. The root directory can be designated by the empty string value. In case of the PutAzureDataLakeStorage processor, the directory will be created if not already existing.
Entity Tracking Initial Listing Target Specify how initial listing should be handled. Used by 'Tracking Entities'strategy.
Entity Tracking State Cache Listed entities are stored in the specified cache storage so that this processor can resume listing across NiFi restart or in case of primary node change. 'Tracking Entities'strategy require tracking information of all listed entities within the last 'Tracking Time Window'. To support large number of entities, the strategy uses DistributedMapCache instead of managed state. Cache key format is 'ListedEntities::\{processorId\}(::\{nodeId\})'. If it tracks per node listed entities, then the optional '::\{nodeId\}' part is added to manage state separately. E.g. cluster wide cache key ='ListedEntities::8dda2321-0164-1000-50fa-3042fe7d6a7b', per node cache key ='ListedEntities::8dda2321-0164-1000-50fa-3042fe7d6a7b::nifi-node3' The stored cache content is Gzipped JSON string. The cache key will be deleted when target listing configuration is changed. Used by 'Tracking Entities'strategy.
Entity Tracking Time Window Specify how long this processor should track already-listed entities. 'Tracking Entities'strategy can pick any entity whose timestamp is inside the specified time window. For example, if set to '30 minutes', any entity having timestamp in recent 30 minutes will be the listing target when this processor runs. A listed entity is considered 'new/updated' and a FlowFile is emitted if one of following condition meets: 1. does not exist in the already-listed entities, 2. has newer timestamp than the cached entity, 3. has different size than the cached entity. If a cached entity 's timestamp becomes older than specified time window, that entity will be removed from the cached already-listed entities. Used by'Tracking Entities'strategy.
File Filter Only files whose names match the given regular expression will be listed
Filesystem Name Name of the Azure Storage File System (also called Container). It is assumed to be already existing.
Include Temporary Files Whether to include temporary files when listing the contents of configured directory paths.
Listing Strategy Specify how to determine new/updated entities. See each strategy descriptions for detail.
Maximum File Age The maximum age that a file must be in order to be pulled; any file older than this amount of time (according to last modification date) will be ignored
Maximum File Size The maximum size that a file can be in order to be pulled
Minimum File Age The minimum age that a file must be in order to be pulled; any file younger than this amount of time (according to last modification date) will be ignored
Minimum File Size The minimum size that a file must be in order to be pulled
Path Filter When 'Recurse Subdirectories' is true, then only subdirectories whose paths match the given regular expression will be scanned
Record Writer Specifies the Record Writer to use for creating the listing. If not specified, one FlowFile will be created for each entity that is listed. If the Record Writer is specified, all entities will be written to a single FlowFile instead of adding attributes to individual FlowFiles.
Recurse Subdirectories Indicates whether to list files from subdirectories of the directory
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests. In case of SOCKS, it is not guaranteed that the selected SOCKS Version will be used by the processor.
Scopes Description
CLUSTER After performing a listing of files, the timestamp of the newest file is stored. This allows the Processor to list only files that have been added or modified after this date the next time that the Processor is run. State is stored across the cluster so that this Processor can be run on Primary Node only and if a new Primary Node is selected, the new node can pick up where the previous node left off, without duplicating the data.
Name Description
success All FlowFiles that are received are routed to success
Name Description
azure.filesystem The name of the Azure File System
azure.filePath The full path of the Azure File
azure.directory The name of the Azure Directory
azure.filename The name of the Azure File
azure.length The length of the Azure File
azure.lastModified The last modification time of the Azure File
azure.etag The ETag of the Azure File
Property Description
Box Client Service Controller Service used to obtain a Box API connection.
Entity Tracking Initial Listing Target Specify how initial listing should be handled. Used by 'Tracking Entities'strategy.
Entity Tracking State Cache Listed entities are stored in the specified cache storage so that this processor can resume listing across NiFi restart or in case of primary node change. 'Tracking Entities'strategy require tracking information of all listed entities within the last 'Tracking Time Window'. To support large number of entities, the strategy uses DistributedMapCache instead of managed state. Cache key format is 'ListedEntities::\{processorId\}(::\{nodeId\})'. If it tracks per node listed entities, then the optional '::\{nodeId\}' part is added to manage state separately. E.g. cluster wide cache key ='ListedEntities::8dda2321-0164-1000-50fa-3042fe7d6a7b', per node cache key ='ListedEntities::8dda2321-0164-1000-50fa-3042fe7d6a7b::nifi-node3' The stored cache content is Gzipped JSON string. The cache key will be deleted when target listing configuration is changed. Used by 'Tracking Entities'strategy.
Entity Tracking Time Window Specify how long this processor should track already-listed entities. 'Tracking Entities'strategy can pick any entity whose timestamp is inside the specified time window. For example, if set to '30 minutes', any entity having timestamp in recent 30 minutes will be the listing target when this processor runs. A listed entity is considered 'new/updated' and a FlowFile is emitted if one of following condition meets: 1. does not exist in the already-listed entities, 2. has newer timestamp than the cached entity, 3. has different size than the cached entity. If a cached entity 's timestamp becomes older than specified time window, that entity will be removed from the cached already-listed entities. Used by'Tracking Entities'strategy.
Folder ID The ID of the folder from which to pull list of files.
Listing Strategy Specify how to determine new/updated entities. See each strategy descriptions for detail.
Minimum File Age The minimum age a file must be in order to be considered; any files younger than this will be ignored.
Record Writer Specifies the Record Writer to use for creating the listing. If not specified, one FlowFile will be created for each entity that is listed. If the Record Writer is specified, all entities will be written to a single FlowFile instead of adding attributes to individual FlowFiles.
Search Recursively When 'true', will include list of files from sub-folders. Otherwise, will return only files that are within the folder defined by the 'Folder ID' property.
Scopes Description
CLUSTER The processor stores necessary data to be able to keep track what files have been listed already. What exactly needs to be stored depends on the 'Listing Strategy'.
Name Description
success All FlowFiles that are received are routed to success
Name Description
box.id The id of the file
filename The name of the file
path The folder path where the file is located
box.size The size of the file
box.timestamp The last modified time of the file
Property Description
Box Client Service Controller Service used to obtain a Box API connection.
Folder ID The ID of the folder from which to fetch files.
Minimum File Age The minimum age a file must be in order to be considered; any files younger than this will be ignored.
Record Writer Specifies the Controller Service to use for writing the metadata records. Must be set.
Search Recursively When 'true', will include files from sub-folders. Otherwise, will return only files that are within the folder defined by the 'Folder ID' property.
Name Description
failure A FlowFile will be routed here if there is an error fetching file metadata from the folder.
not.found FlowFiles for which the specified Box folder was not found will be routed to this relationship.
success A FlowFile containing the file metadata records will be routed to this relationship upon successful processing.
Name Description
box.folder.id The ID of the folder from which files were fetched
record.count The number of records in the FlowFile
mime.type The MIME Type specified by the Record Writer
error.code The error code returned by Box
error.message The error message returned by Box
Property Description
Box Client Service Controller Service used to obtain a Box API connection.
File ID The ID of the file for which to fetch metadata.
Name Description
failure A FlowFile will be routed here if there is an error fetching metadata instances from the file.
not found FlowFiles for which the specified Box file was not found will be routed to this relationship.
success A FlowFile containing the metadata instances records will be routed to this relationship upon successful processing.
Name Description
box.id The ID of the file from which metadata was fetched
record.count The number of records in the FlowFile
mime.type The MIME Type specified by the Record Writer
box.metadata.instances.names Comma-separated list of instances names
box.metadata.instances.count Number of metadata instances found
error.code The error code returned by Box
error.message The error message returned by Box
Property Description
Box Client Service Controller Service used to obtain a Box API connection.
File ID The ID of the file for which to fetch metadata.
Name Description
failure A FlowFile will be routed here if there is an error fetching metadata templates from the file.
not found FlowFiles for which the specified Box file was not found will be routed to this relationship.
success A FlowFile containing the metadata template records will be routed to this relationship upon successful processing.
Name Description
box.file.id The ID of the file from which metadata was fetched
record.count The number of records in the FlowFile
mime.type The MIME Type specified by the Record Writer
box.metadata.templates.names Comma-separated list of template names
box.metadata.templates.count Number of metadata templates found
error.code The error code returned by Box
error.message The error message returned by Box
Property Description
Confluence Client Service Controller service for managing connections to Confluence
Name Description
retry Retryable failure occurred, e.g. rate limiting
success Successfully fetched Confluence group page
Name Description
confluence.group.ids List of identifiers of the Confluence groups.
Property Description
list-db-include-count Whether to include the table's row count as a flow file attribute. This affects performance as a database query will be generated for each table in the retrieved list.
list-db-refresh-interval The amount of time to elapse before resetting the processor state, thereby causing all current tables to be listed. During this interval, the processor may continue to run, but tables that have already been listed will not be re-listed. However new/added tables will be listed as the processor runs. A value of zero means the state will never be automatically reset, the user must Clear State manually.
list-db-tables-catalog The name of a catalog from which to list database tables. The name must match the catalog name as it is stored in the database. If the property is not set, the catalog name will not be used to narrow the search for tables. If the property is set to an empty string, tables without a catalog will be listed.
list-db-tables-db-connection The Controller Service that is used to obtain connection to database
list-db-tables-name-pattern A pattern for matching tables in the database. Within a pattern, "%" means match any substring of 0 or more characters, and "_" means match any one character. The pattern must match the table name as it is stored in the database. If the property is not set, all tables will be retrieved.
list-db-tables-schema-pattern A pattern for matching schemas in the database. Within a pattern, "%" means match any substring of 0 or more characters, and "_" means match any one character. The pattern must match the schema name as it is stored in the database. If the property is not set, the schema name will not be used to narrow the search for tables. If the property is set to an empty string, tables without a schema will be listed.
list-db-tables-types A comma-separated list of table types to include. For example, some databases support TABLE and VIEW types. If the property is not set, tables of all types will be returned.
record-writer Specifies the Record Writer to use for creating the listing. If not specified, one FlowFile will be created for each entity that is listed. If the Record Writer is specified, all entities will be written to a single FlowFile instead of adding attributes to individual FlowFiles.
Scopes Description
CLUSTER After performing a listing of tables, the timestamp of the query is stored. This allows the Processor to not re-list tables the next time that the Processor is run. Specifying the refresh interval in the processor properties will indicate that when the processor detects the interval has elapsed, the state will be reset and tables will be re-listed as a result. This processor is meant to be run on the primary node only.
Name Description
success All FlowFiles that are received are routed to success
Name Description
db.table.name Contains the name of a database table from the connection
db.table.catalog Contains the name of the catalog to which the table belongs (may be null)
db.table.schema Contains the name of the schema to which the table belongs (may be null)
db.table.fullname Contains the fully-qualified table name (possibly including catalog, schema, etc.)
db.table.type Contains the type of the database table from the connection. Typical types are "TABLE", "VIEW", "SYSTEM TABLE", "GLOBAL TEMPORARY", "LOCAL TEMPORARY", "ALIAS", "SYNONYM"
db.table.remarks Contains the name of a database table from the connection
db.table.count Contains the number of rows in the table
Property Description
DBFS File Path DBFS file path e.g. /directory/file.txt
Databricks Client Databricks Client Service.
Include Directories Include directories in FlowFiles produced.
Recursive Directory Listing Recursively list files in sub directories.
Name Description
failure Databricks failure relationship
original The original FlowFile is routed to this relationship when processing is successful.
success Databricks success relationship
Name Description
filename Base filename of the DBFS file or directory.
path Path to parent directory containing the DBFS file or directory.
absolute.path Full path to the DBFS file or directory.
dbfs.resourceType The type of resource, 'file' or 'directory' of the DBFS resource.
dbfs.size The size of the DBFS file.
dbfs.lastModifiedTime The last modified time of the DBFS file, in milliseconds since epoch in UTC time.
error.code The error code for the SQL statement if an error occurred.
error.message The error message for the SQL statement if an error occurred.
Property Description
Dropbox Credential Service Controller Service used to obtain Dropbox credentials (App Key, App Secret, Access Token, Refresh Token). See controller service's Additional Details for more information.
Entity Tracking Initial Listing Target Specify how initial listing should be handled. Used by 'Tracking Entities'strategy.
Entity Tracking State Cache Listed entities are stored in the specified cache storage so that this processor can resume listing across NiFi restart or in case of primary node change. 'Tracking Entities'strategy require tracking information of all listed entities within the last 'Tracking Time Window'. To support large number of entities, the strategy uses DistributedMapCache instead of managed state. Cache key format is 'ListedEntities::\{processorId\}(::\{nodeId\})'. If it tracks per node listed entities, then the optional '::\{nodeId\}' part is added to manage state separately. E.g. cluster wide cache key ='ListedEntities::8dda2321-0164-1000-50fa-3042fe7d6a7b', per node cache key ='ListedEntities::8dda2321-0164-1000-50fa-3042fe7d6a7b::nifi-node3' The stored cache content is Gzipped JSON string. The cache key will be deleted when target listing configuration is changed. Used by 'Tracking Entities'strategy.
Entity Tracking Time Window Specify how long this processor should track already-listed entities. 'Tracking Entities'strategy can pick any entity whose timestamp is inside the specified time window. For example, if set to '30 minutes', any entity having timestamp in recent 30 minutes will be the listing target when this processor runs. A listed entity is considered 'new/updated' and a FlowFile is emitted if one of following condition meets: 1. does not exist in the already-listed entities, 2. has newer timestamp than the cached entity, 3. has different size than the cached entity. If a cached entity 's timestamp becomes older than specified time window, that entity will be removed from the cached already-listed entities. Used by'Tracking Entities'strategy.
Folder The Dropbox identifier or path of the folder from which to pull list of files. 'Folder'should match the following regular expression pattern: /.*|id:.* . Example for folder identifier: id:odTlUvbpIEAAAAAAAAAGGQ. Example for folder path: /Team1/Task1.
Listing Strategy Specify how to determine new/updated entities. See each strategy descriptions for detail.
Minimum File Age The minimum age a file must be in order to be considered; any files newer than this will be ignored.
Record Writer Specifies the Record Writer to use for creating the listing. If not specified, one FlowFile will be created for each entity that is listed. If the Record Writer is specified, all entities will be written to a single FlowFile instead of adding attributes to individual FlowFiles.
Search Recursively Indicates whether to list files from subfolders of the Dropbox folder.
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Scopes Description
CLUSTER The processor stores necessary data to be able to keep track what files have been listed already. What exactly needs to be stored depends on the 'Listing Strategy'.
Name Description
success All FlowFiles that are received are routed to success
Name Description
dropbox.id The Dropbox identifier of the file
path The folder path where the file is located
filename The name of the file
dropbox.size The size of the file
dropbox.timestamp The server modified time of the file
dropbox.revision Revision of the file
Property Description
Address The address the FTP server should be bound to. If not set (or set to 0.0.0.0), the server binds to all available addresses (i.e. all network interfaces of the host machine).
Password If the Username is set, then a password must also be specified. The password provided by the client trying to log in to the FTP server will be checked against this password.
Port The Port to listen on for incoming connections. On Linux, root privileges are required to use port numbers below 1024.
SSL Context Service Specifies the SSL Context Service that can be used to create secure connections. If an SSL Context Service is selected, then a keystore file must also be specified in the SSL Context Service. Without a keystore file, the processor cannot be started successfully. Specifying a truststore file is optional. If a truststore file is specified, client authentication is required (the client needs to send a certificate to the server).Regardless of the selected TLS protocol, the highest available protocol is used for the connection. For example if NiFi is running on Java 11 and TLSv1.2 is selected in the controller service as the preferred TLS Protocol, TLSv1.3 will be used (regardless of TLSv1.2 being selected) because Java 11 supports TLSv1.3.
Username The name of the user that is allowed to log in to the FTP server. If a username is provided, a password must also be provided. If no username is specified, anonymous connections will be permitted.
Name Description
success Relationship for successfully received files.
Name Description
filename The name of the file received via the FTP/FTPS connection.
path The path pointing to the file's target directory. E.g.: file.txt is uploaded to /Folder1/SubFolder, then the value of the path attribute will be "/Folder1/SubFolder/" (note that it ends with a separator character).
Property Description
Authorized DN Pattern A Regular Expression to apply against the Subject's Distinguished Name of incoming connections. If the Pattern does not match the Subject DN, the processor will respond with a status of HTTP 403 Forbidden.
Base Path Base path for incoming connections
HTTP Headers to receive as Attributes (Regex) Specifies the Regular Expression that determines the names of HTTP Headers that should be passed along as FlowFile attributes
HTTP Protocols HTTP Protocols supported for Application Layer Protocol Negotiation with TLS
Listening Port The Port to listen on for incoming connections
Max Unconfirmed Flowfile Time The maximum amount of time to wait for a FlowFile to be confirmed before it is removed from the cache
Request Header Maximum Size The maximum supported size of HTTP headers in requests sent to this processor
Return Code The HTTP return code returned after every HTTP call
SSL Context Service SSL Context Service enables support for HTTPS
authorized-issuer-dn-pattern A Regular Expression to apply against the Issuer's Distinguished Name of incoming connections. If the Pattern does not match the Issuer DN, the processor will respond with a status of HTTP 403 Forbidden.
client-authentication Client Authentication policy for TLS connections. Required when SSL Context Service configured.
health-check-port The port to listen on for incoming health check requests. If set, it must be different from the Listening Port. Configure this port if the processor is set to use two-way SSL and a load balancer that does not support client authentication for health check requests is used. Only /<base_path>/healthcheck service is available via this port and only GET and HEAD requests are supported. If the processor is set not to use SSL, SSL will not be used on this port, either. If the processor is set to use one-way SSL, one-way SSL will be used on this port. If the processor is set to use two-way SSL, one-way SSL will be used on this port (client authentication not required).
max-thread-pool-size The maximum number of threads to be used by the embedded Jetty server. The value can be set between 8 and 1000. The value of this property affects the performance of the flows and the operating system, therefore the default value should only be changed in justified cases. A value that is less than the default value may be suitable if only a small number of HTTP clients connect to the server. A greater value may be suitable if a large number of HTTP clients are expected to make requests to the server simultaneously.
multipart-read-buffer-size The threshold size, at which the contents of an incoming file would be written to disk. Only applies for requests with Content-Type: multipart/form-data. It is used to prevent denial of service type of attacks, to prevent filling up the heap or disk space.
multipart-request-max-size The max size of the request. Only applies for requests with Content-Type: multipart/form-data, and is used to prevent denial of service type of attacks, to prevent filling up the heap or disk space
record-reader The Record Reader to use parsing the incoming FlowFile into Records
record-writer The Record Writer to use for serializing Records after they have been transformed
Name Description
success Relationship for successfully received FlowFiles
Property Description
Address Internet Protocol Address on which to listen for OTLP Export Service Requests. The default value enables listening on all addresses.
Batch Size Maximum number of OTLP request resource elements included in each FlowFile produced
Client Authentication Client authentication policy for TLS communication with HTTPS
Port TCP port number on which to listen for OTLP Export Service Requests over HTTP and gRPC
Queue Capacity Maximum number of OTLP request resource elements that can be received and queued
SSL Context Service SSL Context Service enables TLS communication for HTTPS
Worker Threads Number of threads responsible for decoding and queuing incoming OTLP Export Service Requests
Name Description
success Export Service Requests containing OTLP Telemetry
Name Description
mime.type Content-Type set to application/json
resource.type OpenTelemetry Resource Type: LOGS, METRICS, or TRACES
resource.count Count of resource elements included in messages
Property Description
App Token The Application Token that is registered to your Slack application
Bot Token The Bot Token that is registered to your Slack application
Event Type to Receive Specifies the type of Event that the Processor should respond to
Resolve User Details Specifies whether the Processor should lookup details about the Slack User who sent the received message. If true, the output JSON will contain an additional field named 'userDetails'. The 'user' field will still contain the ID of the user. In order to enable this capability, the Bot Token must be granted the 'users:read' and optionally the 'users.profile:read' Bot Token Scope. If the rate limit is exceeded when retrieving this information, the received message will be rejected and must be re-delivered.
Name Description
success All FlowFiles that are created will be sent to this Relationship.
Name Description
mime.type Set to application/json, as the output will always be in JSON format
slack.event.type Set to the type of Slack event that occurred
Property Description
Character Set Specifies the character set of the Syslog messages. Note that Expression language is not evaluated per FlowFile.
Client Auth The client authentication policy to use for the SSL Context. Only used if an SSL Context Service is provided.
Local Network Interface The name of a local network interface to be used to restrict listening to a specific LAN.
Max Batch Size The maximum number of Syslog events to add to a single FlowFile. If multiple events are available, they will be concatenated along with the <Message Delimiter> up to this configured maximum number of messages
Max Size of Message Queue The maximum size of the internal queue used to buffer messages being transferred from the underlying channel to the processor. Setting this value higher allows more messages to be buffered in memory during surges of incoming messages, but increases the total memory used by the processor.
Max Size of Socket Buffer The maximum size of the socket buffer that should be used. This is a suggestion to the Operating System to indicate how big the socket buffer should be. If this value is set too low, the buffer may fill up before the data can be read, and incoming data will be dropped.
Message Delimiter Specifies the delimiter to place between Syslog messages when multiple messages are bundled together (see <Max Batch Size> property).
Parse Messages Indicates if the processor should parse the Syslog messages. If set to false, each outgoing FlowFile will only contain the sender, protocol, and port, and no additional attributes.
Port The port for Syslog communication. Note that Expression language is not evaluated per FlowFile.
Protocol The protocol for Syslog communication.
Receive Buffer Size The size of each buffer used to receive Syslog messages. Adjust this value appropriately based on the expected size of the incoming Syslog messages. When UDP is selected each buffer will hold one Syslog message. When TCP is selected messages are read from an incoming connection until the buffer is full, or the connection is closed.
SSL Context Service The Controller Service to use in order to obtain an SSL Context. If this property is set, syslog messages will be received over a secure connection.
Socket Keep Alive Whether or not to have TCP socket keep alive turned on. Timing details depend on operating system properties.
Worker Threads Number of threads responsible for decoding and queuing incoming syslog messages
Name Description
invalid Syslog messages that do not match one of the expected formats will be sent out this relationship as a FlowFile per message.
success Syslog messages that match one of the expected formats will be sent out this relationship as a FlowFile per message.
Name Description
syslog.priority The priority of the Syslog message.
syslog.severity The severity of the Syslog message derived from the priority.
syslog.facility The facility of the Syslog message derived from the priority.
syslog.version The optional version from the Syslog message.
syslog.timestamp The timestamp of the Syslog message.
syslog.hostname The hostname or IP address of the Syslog message.
syslog.sender The hostname of the Syslog server that sent the message.
syslog.body The body of the Syslog message, everything after the hostname.
syslog.valid An indicator of whether this message matched the expected formats. If this value is false, the other attributes will be empty and only the original message will be available in the content.
syslog.protocol The protocol over which the Syslog message was received.
syslog.port The port over which the Syslog message was received.
mime.type The mime.type of the FlowFile which will be text/plain for Syslog messages.
Property Description
Batching Message Delimiter Specifies the delimiter to place between messages when multiple messages are bundled together (see <Max Batch Size> property).
Character Set Specifies the character set of the received data.
Client Auth The client authentication policy to use for the SSL Context. Only used if an SSL Context Service is provided.
Local Network Interface The name of a local network interface to be used to restrict listening to a specific LAN.
Max Batch Size The maximum number of messages to add to a single FlowFile. If multiple messages are available, they will be concatenated along with the <Message Delimiter> up to this configured maximum number of messages
Max Size of Message Queue The maximum size of the internal queue used to buffer messages being transferred from the underlying channel to the processor. Setting this value higher allows more messages to be buffered in memory during surges of incoming messages, but increases the total memory used by the processor during these surges.
Max Size of Socket Buffer The maximum size of the socket buffer that should be used. This is a suggestion to the Operating System to indicate how big the socket buffer should be. If this value is set too low, the buffer may fill up before the data can be read, and incoming data will be dropped.
Port The port to listen on for communication.
Receive Buffer Size The size of each buffer used to receive messages. Adjust this value appropriately based on the expected size of the incoming messages.
SSL Context Service The Controller Service to use in order to obtain an SSL Context. If this property is set, messages will be received over a secure connection.
Worker Threads The maximum number of worker threads available for servicing TCP connections.
idle-timeout The amount of time a client's connection will remain open if no data is received. The default of 0 seconds will leave connections open until they are closed by the client.
pool-receive-buffers Enable or disable pooling of buffers that the processor uses for handling bytes received on socket connections. The framework allocates buffers as needed during processing.
Name Description
success Messages received successfully will be sent out this relationship.
Name Description
tcp.sender The sending host of the messages.
tcp.port The sending port the messages were received.
client.certificate.issuer.dn For connections using mutual TLS, the Distinguished Name of the Certificate Authority that issued the client's certificate is attached to the FlowFile.
client.certificate.subject.dn For connections using mutual TLS, the Distinguished Name of the client certificate's owner (subject) is attached to the FlowFile.
Property Description
Batching Message Delimiter Specifies the delimiter to place between messages when multiple messages are bundled together (see <Max Batch Size> property).
Character Set Specifies the character set of the received data.
Local Network Interface The name of a local network interface to be used to restrict listening to a specific LAN.
Max Batch Size The maximum number of messages to add to a single FlowFile. If multiple messages are available, they will be concatenated along with the <Message Delimiter> up to this configured maximum number of messages
Max Size of Message Queue The maximum size of the internal queue used to buffer messages being transferred from the underlying channel to the processor. Setting this value higher allows more messages to be buffered in memory during surges of incoming messages, but increases the total memory used by the processor.
Max Size of Socket Buffer The maximum size of the socket buffer that should be used. This is a suggestion to the Operating System to indicate how big the socket buffer should be. If this value is set too low, the buffer may fill up before the data can be read, and incoming data will be dropped.
Port The port to listen on for communication.
Receive Buffer Size The size of each buffer used to receive messages. Adjust this value appropriately based on the expected size of the incoming messages.
Sending Host IP, or name, of a remote host. Only Datagrams from the specified Sending Host Port and this host will be accepted. Improves Performance. May be a system property or an environment variable.
Sending Host Port Port being used by remote host to send Datagrams. Only Datagrams from the specified Sending Host and this port will be accepted. Improves Performance. May be a system property or an environment variable.
Name Description
success Messages received successfully will be sent out this relationship.
Name Description
udp.sender The sending host of the messages.
udp.port The sending port the messages were received.
Property Description
Character Set Specifies the character set of the received data.
Local Network Interface The name of a local network interface to be used to restrict listening to a specific LAN.
Max Size of Message Queue The maximum size of the internal queue used to buffer messages being transferred from the underlying channel to the processor. Setting this value higher allows more messages to be buffered in memory during surges of incoming messages, but increases the total memory used by the processor.
Max Size of Socket Buffer The maximum size of the socket buffer that should be used. This is a suggestion to the Operating System to indicate how big the socket buffer should be. If this value is set too low, the buffer may fill up before the data can be read, and incoming data will be dropped.
Port The port to listen on for communication.
Receive Buffer Size The size of each buffer used to receive messages. Adjust this value appropriately based on the expected size of the incoming messages.
batch-size The maximum number of datagrams to write as records to a single FlowFile. The Batch Size will only be reached when data is coming in more frequently than the Poll Timeout.
poll-timeout The amount of time to wait when polling the internal queue for more datagrams. If no datagrams are found after waiting for the configured timeout, then the processor will emit whatever records have been obtained up to that point.
record-reader The Record Reader to use for reading the content of incoming datagrams.
record-writer The Record Writer to use in order to serialize the data before writing to a flow file.
sending-host IP, or name, of a remote host. Only Datagrams from the specified Sending Host Port and this host will be accepted. Improves Performance. May be a system property or an environment variable.
sending-host-port Port being used by remote host to send Datagrams. Only Datagrams from the specified Sending Host and this port will be accepted. Improves Performance. May be a system property or an environment variable.
Name Description
parse.failure If a datagram cannot be parsed using the configured Record Reader, the contents of the message will be routed to this Relationship as its own individual FlowFile.
success Messages received successfully will be sent out this relationship.
Name Description
udp.sender The sending host of the messages.
udp.port The sending port the messages were received.
record.count The number of records written to the flow file.
mime.type The mime-type of the writer used to write the records to the flow file.
Property Description
server-url-path The WebSocket URL Path on which this processor listens to. Must starts with '/', e.g. '/example'.
websocket-server-controller-service A WebSocket SERVER Controller Service which can accept WebSocket requests.
Name Description
binary message The WebSocket binary message output
connected The WebSocket session is established
disconnected The WebSocket session is disconnected
text message The WebSocket text message output
Name Description
websocket.controller.service.id WebSocket Controller Service id.
websocket.session.id Established WebSocket session id.
websocket.endpoint.id WebSocket endpoint id.
websocket.local.address WebSocket server address.
websocket.remote.address WebSocket client address.
websocket.message.type TEXT or BINARY.
Property Description
Entity Tracking Initial Listing Target Specify how initial listing should be handled. Used by 'Tracking Entities'strategy.
Entity Tracking Node Identifier The configured value will be appended to the cache key so that listing state can be tracked per NiFi node rather than cluster wide when tracking state is scoped to LOCAL. Used by 'Tracking Entities'strategy.
Entity Tracking State Cache Listed entities are stored in the specified cache storage so that this processor can resume listing across NiFi restart or in case of primary node change. 'Tracking Entities'strategy require tracking information of all listed entities within the last 'Tracking Time Window'. To support large number of entities, the strategy uses DistributedMapCache instead of managed state. Cache key format is 'ListedEntities::\{processorId\}(::\{nodeId\})'. If it tracks per node listed entities, then the optional '::\{nodeId\}' part is added to manage state separately. E.g. cluster wide cache key ='ListedEntities::8dda2321-0164-1000-50fa-3042fe7d6a7b', per node cache key ='ListedEntities::8dda2321-0164-1000-50fa-3042fe7d6a7b::nifi-node3' The stored cache content is Gzipped JSON string. The cache key will be deleted when target listing configuration is changed. Used by 'Tracking Entities'strategy.
Entity Tracking Time Window Specify how long this processor should track already-listed entities. 'Tracking Entities'strategy can pick any entity whose timestamp is inside the specified time window. For example, if set to '30 minutes', any entity having timestamp in recent 30 minutes will be the listing target when this processor runs. A listed entity is considered 'new/updated' and a FlowFile is emitted if one of following condition meets: 1. does not exist in the already-listed entities, 2. has newer timestamp than the cached entity, 3. has different size than the cached entity. If a cached entity 's timestamp becomes older than specified time window, that entity will be removed from the cached already-listed entities. Used by'Tracking Entities'strategy.
File Filter Only files whose names match the given regular expression will be picked up
Ignore Hidden Files Indicates whether or not hidden files should be ignored
Include File Attributes Whether or not to include information such as the file's Last Modified Time and Owner as FlowFile Attributes. Depending on the File System being used, gathering this information can be expensive and as a result should be disabled. This is especially true of remote file shares.
Input Directory The input directory from which files to pull files
Input Directory Location Specifies where the Input Directory is located. This is used to determine whether state should be stored locally or across the cluster.
Listing Strategy Specify how to determine new/updated entities. See each strategy descriptions for detail.
Maximum File Age The maximum age that a file must be in order to be pulled; any file older than this amount of time (according to last modification date) will be ignored
Maximum File Size The maximum size that a file can be in order to be pulled
Minimum File Age The minimum age that a file must be in order to be pulled; any file younger than this amount of time (according to last modification date) will be ignored
Minimum File Size The minimum size that a file must be in order to be pulled
Path Filter When Recurse Subdirectories is true, then only subdirectories whose path matches the given regular expression will be scanned
Record Writer Specifies the Record Writer to use for creating the listing. If not specified, one FlowFile will be created for each entity that is listed. If the Record Writer is specified, all entities will be written to a single FlowFile instead of adding attributes to individual FlowFiles.
Recurse Subdirectories Indicates whether to list files from subdirectories of the directory
Target System Timestamp Precision Specify timestamp precision at the target system. Since this processor uses timestamp of entities to decide which should be listed, it is crucial to use the right timestamp precision.
max-listing-time The maximum amount of time that listing any single directory is expected to take. If the listing for the directory specified by the 'Input Directory' property, or the listing of any subdirectory (if 'Recurse' is set to true) takes longer than this amount of time, a warning bulletin will be generated for each directory listing that exceeds this amount of time.
max-operation-time The maximum amount of time that any single disk operation is expected to take. If any disk operation takes longer than this amount of time, a warning bulletin will be generated for each operation that exceeds this amount of time.
max-performance-metrics If the 'Track Performance' property is set to 'true', this property indicates the maximum number of files whose performance metrics should be held onto. A smaller value for this property will result in less heap utilization, while a larger value may provide more accurate insights into how the disk access operations are performing
track-performance Whether or not the Processor should track the performance of disk access operations. If true, all accesses to disk will be recorded, including the file being accessed, the information being obtained, and how long it takes. This is then logged periodically at a DEBUG level. While the amount of data will be capped, this option may still consume a significant amount of heap (controlled by the 'Maximum Number of Files to Track' property), but it can be very useful for troubleshooting purposes if performance is poor is degraded.
Scopes Description
LOCAL After performing a listing of files, the timestamp of the newest file is stored. This allows the Processor to list only files that have been added or modified after this date the next time that the Processor is run. Whether the state is stored with a Local or Cluster scope depends on the value of the <Input Directory Location> property.
CLUSTER After performing a listing of files, the timestamp of the newest file is stored. This allows the Processor to list only files that have been added or modified after this date the next time that the Processor is run. Whether the state is stored with a Local or Cluster scope depends on the value of the <Input Directory Location> property.
Name Description
success All FlowFiles that are received are routed to success
Name Description
filename The name of the file that was read from filesystem.
path The path is set to the relative path of the file's directory on filesystem compared to the Input Directory property. For example, if Input Directory is set to /tmp, then files picked up from /tmp will have the path attribute set to "/". If the Recurse Subdirectories property is set to true and a file is picked up from /tmp/abc/1/2/3, then the path attribute will be set to "abc/1/2/3/".
absolute.path The absolute.path is set to the absolute path of the file's directory on filesystem. For example, if the Input Directory property is set to /tmp, then files picked up from /tmp will have the path attribute set to "/tmp/". If the Recurse Subdirectories property is set to true and a file is picked up from /tmp/abc/1/2/3, then the path attribute will be set to "/tmp/abc/1/2/3/".
file.owner The user that owns the file in filesystem
file.group The group that owns the file in filesystem
file.size The number of bytes in the file in filesystem
file.permissions The permissions for the file in filesystem. This is formatted as 3 characters for the owner, 3 for the group, and 3 for other users. For example rw-rw-r–
file.lastModifiedTime The timestamp of when the file in filesystem was last modified as 'yyyy-MM-dd'T'HH:mm:ssZ'
file.lastAccessTime The timestamp of when the file in filesystem was last accessed as 'yyyy-MM-dd'T'HH:mm:ssZ'
file.creationTime The timestamp of when the file in filesystem was created as 'yyyy-MM-dd'T'HH:mm:ssZ'
Property Description
Connection Mode The FTP Connection Mode
Connection Timeout Amount of time to wait before timing out while creating a connection
Data Timeout When transferring a file between the local and remote system, this value specifies how long is allowed to elapse without any data being transferred between systems
Entity Tracking Initial Listing Target Specify how initial listing should be handled. Used by 'Tracking Entities'strategy.
Entity Tracking State Cache Listed entities are stored in the specified cache storage so that this processor can resume listing across NiFi restart or in case of primary node change. 'Tracking Entities'strategy require tracking information of all listed entities within the last 'Tracking Time Window'. To support large number of entities, the strategy uses DistributedMapCache instead of managed state. Cache key format is 'ListedEntities::\{processorId\}(::\{nodeId\})'. If it tracks per node listed entities, then the optional '::\{nodeId\}' part is added to manage state separately. E.g. cluster wide cache key ='ListedEntities::8dda2321-0164-1000-50fa-3042fe7d6a7b', per node cache key ='ListedEntities::8dda2321-0164-1000-50fa-3042fe7d6a7b::nifi-node3' The stored cache content is Gzipped JSON string. The cache key will be deleted when target listing configuration is changed. Used by 'Tracking Entities'strategy.
Entity Tracking Time Window Specify how long this processor should track already-listed entities. 'Tracking Entities'strategy can pick any entity whose timestamp is inside the specified time window. For example, if set to '30 minutes', any entity having timestamp in recent 30 minutes will be the listing target when this processor runs. A listed entity is considered 'new/updated' and a FlowFile is emitted if one of following condition meets: 1. does not exist in the already-listed entities, 2. has newer timestamp than the cached entity, 3. has different size than the cached entity. If a cached entity 's timestamp becomes older than specified time window, that entity will be removed from the cached already-listed entities. Used by'Tracking Entities'strategy.
File Filter Regex Provides a Java Regular Expression for filtering Filenames; if a filter is supplied, only files whose names match that Regular Expression will be fetched
Follow Symbolic Links If true, will pull even symbolic files and also nested symbolic subdirectories; otherwise, will not read symbolic files and will not traverse symbolic link subdirectories
Hostname The fully qualified hostname or IP address of the remote system
Ignore Dotted Files If true, files whose names begin with a dot (".") will be ignored
Internal Buffer Size Set the internal buffer size for buffered data streams
Listing Strategy Specify how to determine new/updated entities. See each strategy descriptions for detail.
Password Password for the user account
Path Filter Regex When Search Recursively is true, then only subdirectories whose path matches the given Regular Expression will be scanned
Port The port to connect to on the remote host to fetch the data from
Record Writer Specifies the Record Writer to use for creating the listing. If not specified, one FlowFile will be created for each entity that is listed. If the Record Writer is specified, all entities will be written to a single FlowFile instead of adding attributes to individual FlowFiles.
Remote Path The path on the remote system from which to pull or push files
Remote Poll Batch Size The value specifies how many file paths to find in a given directory on the remote system when doing a file listing. This value in general should not need to be modified but when polling against a remote system with a tremendous number of files this value can be critical. Setting this value too high can result very poor performance and setting it too low can cause the flow to be slower than normal.
Search Recursively If true, will pull files from arbitrarily nested subdirectories; otherwise, will not traverse subdirectories
Target System Timestamp Precision Specify timestamp precision at the target system. Since this processor uses timestamp of entities to decide which should be listed, it is crucial to use the right timestamp precision.
Transfer Mode The FTP Transfer Mode
Username Username
ftp-use-utf8 Tells the client to use UTF-8 encoding when processing files and filenames. If set to true, the server must also support UTF-8 encoding.
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Scopes Description
CLUSTER After performing a listing of files, the timestamp of the newest file is stored. This allows the Processor to list only files that have been added or modified after this date the next time that the Processor is run. State is stored across the cluster so that this Processor can be run on Primary Node only and if a new Primary Node is selected, the new node will not duplicate the data that was listed by the previous Primary Node.
Name Description
success All FlowFiles that are received are routed to success
Name Description
ftp.remote.host The hostname of the FTP Server
ftp.remote.port The port that was connected to on the FTP Server
ftp.listing.user The username of the user that performed the FTP Listing
file.owner The numeric owner id of the source file
file.group The numeric group id of the source file
file.permissions The read/write/execute permissions of the source file
file.size The number of bytes in the source file
file.lastModifiedTime The timestamp of when the file in the filesystem waslast modified as 'yyyy-MM-dd'T'HH:mm:ssZ'
filename The name of the file on the FTP Server
path The fully qualified name of the directory on the FTP Server from which the file was pulled
Property Description
Entity Tracking Initial Listing Target Specify how initial listing should be handled. Used by 'Tracking Entities'strategy.
Entity Tracking State Cache Listed entities are stored in the specified cache storage so that this processor can resume listing across NiFi restart or in case of primary node change. 'Tracking Entities'strategy require tracking information of all listed entities within the last 'Tracking Time Window'. To support large number of entities, the strategy uses DistributedMapCache instead of managed state. Cache key format is 'ListedEntities::\{processorId\}(::\{nodeId\})'. If it tracks per node listed entities, then the optional '::\{nodeId\}' part is added to manage state separately. E.g. cluster wide cache key ='ListedEntities::8dda2321-0164-1000-50fa-3042fe7d6a7b', per node cache key ='ListedEntities::8dda2321-0164-1000-50fa-3042fe7d6a7b::nifi-node3' The stored cache content is Gzipped JSON string. The cache key will be deleted when target listing configuration is changed. Used by 'Tracking Entities'strategy.
Entity Tracking Time Window Specify how long this processor should track already-listed entities. 'Tracking Entities'strategy can pick any entity whose timestamp is inside the specified time window. For example, if set to '30 minutes', any entity having timestamp in recent 30 minutes will be the listing target when this processor runs. A listed entity is considered 'new/updated' and a FlowFile is emitted if one of following condition meets: 1. does not exist in the already-listed entities, 2. has newer timestamp than the cached entity, 3. has different size than the cached entity. If a cached entity 's timestamp becomes older than specified time window, that entity will be removed from the cached already-listed entities. Used by'Tracking Entities'strategy.
GCP Credentials Provider Service The Controller Service used to obtain Google Cloud Platform credentials.
gcp-project-id Google Cloud Project ID
gcp-retry-count How many retry attempts should be made before routing to the failure relationship.
gcs-bucket Bucket of the object.
gcs-prefix The prefix used to filter the object list. In most cases, it should end with a forward slash ( '/').
gcs-use-generations Specifies whether to use GCS Generations, if applicable. If false, only the latest version of each object will be returned.
listing-strategy Specify how to determine new/updated entities. See each strategy descriptions for detail.
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
record-writer Specifies the Record Writer to use for creating the listing. If not specified, one FlowFile will be created for each entity that is listed. If the Record Writer is specified, all entities will be written to a single FlowFile instead of adding attributes to individual FlowFiles.
storage-api-url Overrides the default storage URL. Configuring an alternative Storage API URL also overrides the HTTP Host header on requests as described in the Google documentation for Private Service Connections.
Scopes Description
CLUSTER After performing a listing of keys, the timestamp of the newest key is stored, along with the keys that share that same timestamp. This allows the Processor to list only keys that have been added or modified after this date the next time that the Processor is run. State is stored across the cluster so that this Processor can be run on Primary Node only and if a new Primary Node is selected, the new node can pick up where the previous node left off, without duplicating the data.
Name Description
success FlowFiles are routed to this relationship after a successful Google Cloud Storage operation.
Name Description
filename The name of the file
gcs.bucket Bucket of the object.
gcs.key Name of the object.
gcs.size Size of the object.
gcs.cache.control Data cache control of the object.
gcs.component.count The number of components which make up the object.
gcs.content.disposition The data content disposition of the object.
gcs.content.encoding The content encoding of the object.
gcs.content.language The content language of the object.
mime.type The MIME/Content-Type of the object
gcs.crc32c The CRC32C checksum of object's data, encoded in base64 in big-endian order.
gcs.create.time The creation time of the object (milliseconds)
gcs.update.time The last modification time of the object (milliseconds)
gcs.encryption.algorithm The algorithm used to encrypt the object.
gcs.encryption.sha256 The SHA256 hash of the key used to encrypt the object
gcs.etag The HTTP 1.1 Entity tag for the object.
gcs.generated.id The service-generated for the object
gcs.generation The data generation of the object.
gcs.md5 The MD5 hash of the object's data encoded in base64.
gcs.media.link The media download link to the object.
gcs.metageneration The metageneration of the object.
gcs.owner The owner (uploader) of the object.
gcs.owner.type The ACL entity type of the uploader of the object.
gcs.acl.owner A comma-delimited list of ACL entities that have owner access to the object. Entities will be either email addresses, domains, or project IDs.
gcs.acl.writer A comma-delimited list of ACL entities that have write access to the object. Entities will be either email addresses, domains, or project IDs.
gcs.acl.reader A comma-delimited list of ACL entities that have read access to the object. Entities will be either email addresses, domains, or project IDs.
gcs.uri The URI of the object as a string.
Property Description
Entity Tracking Initial Listing Target Specify how initial listing should be handled. Used by 'Tracking Entities'strategy.
Entity Tracking State Cache Listed entities are stored in the specified cache storage so that this processor can resume listing across NiFi restart or in case of primary node change. 'Tracking Entities'strategy require tracking information of all listed entities within the last 'Tracking Time Window'. To support large number of entities, the strategy uses DistributedMapCache instead of managed state. Cache key format is 'ListedEntities::\{processorId\}(::\{nodeId\})'. If it tracks per node listed entities, then the optional '::\{nodeId\}' part is added to manage state separately. E.g. cluster wide cache key ='ListedEntities::8dda2321-0164-1000-50fa-3042fe7d6a7b', per node cache key ='ListedEntities::8dda2321-0164-1000-50fa-3042fe7d6a7b::nifi-node3' The stored cache content is Gzipped JSON string. The cache key will be deleted when target listing configuration is changed. Used by 'Tracking Entities'strategy.
Entity Tracking Time Window Specify how long this processor should track already-listed entities. 'Tracking Entities'strategy can pick any entity whose timestamp is inside the specified time window. For example, if set to '30 minutes', any entity having timestamp in recent 30 minutes will be the listing target when this processor runs. A listed entity is considered 'new/updated' and a FlowFile is emitted if one of following condition meets: 1. does not exist in the already-listed entities, 2. has newer timestamp than the cached entity, 3. has different size than the cached entity. If a cached entity 's timestamp becomes older than specified time window, that entity will be removed from the cached already-listed entities. Used by'Tracking Entities'strategy.
Listing Strategy Specify how to determine new/updated entities. See each strategy descriptions for detail.
Record Writer Specifies the Record Writer to use for creating the listing. If not specified, one FlowFile will be created for each entity that is listed. If the Record Writer is specified, all entities will be written to a single FlowFile instead of adding attributes to individual FlowFiles.
connect-timeout Maximum wait time for connection to Google Drive service.
folder-id The ID of the folder from which to pull list of files. Please see Additional Details to set up access to Google Drive and obtain Folder ID. WARNING: Unauthorized access to the folder is treated as if the folder was empty. This results in the processor not creating outgoing FlowFiles. No additional error message is provided.
gcp-credentials-provider-service The Controller Service used to obtain Google Cloud Platform credentials.
min-age The minimum age a file must be in order to be considered; any files younger than this will be ignored.
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
read-timeout Maximum wait time for response from Google Drive service.
recursive-search When 'true', will include list of files from concrete sub-folders (ignores shortcuts). Otherwise, will return only files that have the defined 'Folder ID' as their parent directly. WARNING: The listing may fail if there are too many sub-folders (500+).
Scopes Description
CLUSTER The processor stores necessary data to be able to keep track what files have been listed already. What exactly needs to be stored depends on the 'Listing Strategy'. State is stored across the cluster so that this Processor can be run on Primary Node only and if a new Primary Node is selected, the new node can pick up where the previous node left off, without duplicating the data.
Name Description
success All FlowFiles that are received are routed to success
Name Description
drive.id The id of the file
filename The name of the file
mime.type The MIME type of the file
drive.size The size of the file. Set to 0 when the file size is not available (e.g. externally stored files).
drive.size.available Indicates if the file size is known / available
drive.timestamp The last modified time or created time (whichever is greater) of the file. The reason for this is that the original modified date of a file is preserved when uploaded to Google Drive. 'Created time' takes the time when the upload occurs. However uploaded files can still be modified later.
drive.created.time The file's creation time
drive.modified.time The file's last modification time
drive.path The path of the file's directory from the base directory. The path contains the folder names in URL encoded form because Google Drive allows special characters in file names, including '/' (slash) and '' (backslash). The URL encoded folder names are separated by '/' in the path.
drive.owner The owner of the file
drive.last.modifying.user The last modifying user of the file
drive.web.view.link Web view link to the file
drive.web.content.link Web content link to the file
drive.parent.folder.id The id of the file's parent folder
drive.parent.folder.name The name of the file's parent folder
drive.listed.folder.id The id of the base folder that was listed
drive.listed.folder.name The name of the base folder that was listed
drive.shared.drive.id The id of the shared drive (if the file is located on a shared drive)
drive.shared.drive.name The name of the shared drive (if the file is located on a shared drive)
Property Description
Drive ID The ID of the drive to list files from. This can be a shared drive ID.
GCP Credentials Service The Controller Service used to obtain Google Cloud Platform credentials.
Include Folders When 'true', both files and folders will be included in the results. When 'false', only files (not folders) will be included.
Minimum File Age The minimum age a file must be in order to be considered; any files younger than this will be ignored.
Record Writer Specifies the Controller Service to use for writing the metadata records. Must be set.
Search Recursively When 'true', will recursively list files in all folders within the drive. When 'false', will only list files at the root level of the drive.
Name Description
failure A FlowFile will be routed here if there is an error fetching file metadata.
retry A FlowFile is routed here if the processor should retry the request (e.g., after rate limiting).
success A FlowFile containing the file metadata records will be routed to this relationship upon successful processing.
Name Description
google.drive.drive.id The ID of the drive from which files were listed
record.count The number of records in the FlowFile
mime.type The MIME Type specified by the Record Writer
google.drive.error.code The error code if the request to Google Drive API fails
google.drive.error.message The error message if the request to Google Drive API fails
Property Description
Custom Query Custom query to filter the returned groups. For example, 'email=test-*'. See Google's Admin SDK Directory API documentation for supported syntax.
GCP Credentials Service Controller Service used to obtain Google Cloud Platform credentials.
Google Domain Domain name to list Google Groups (e.g., 'example.com').
Record Writer Record writer used for writing out the records of retrieved Google Groups.
Name Description
failure FlowFiles are routed here if the processor fails to retrieve Google Groups.
retry FlowFiles are routed here if a transient failure occurs (e.g. rate-limited, socket timeouts) and should be retried.
success A FlowFile containing a record set of the groups is routed here upon success.
Name Description
record.count The number of records (groups) returned.
mime.type The MIME type for the resulting FlowFile.
Property Description
HubSpot Service HubSpot Client Service.
Object Type HubSpot object type
Updated After Filter objects updated after specified date (format: yyyy-MM-dd)
Scopes Description
CLUSTER Maintains pagination state and last sync timestamp to continue data retrieval from the last known position after restarts and to fetch only changed data.
Name Description
failure HubSpot fail relationship
original The input Flow File is routed to the original relationship.
retry HubSpot retry relationship. FlowFiles that failed to process due to a server timeout or rate limit related error. FlowFiles routed here should be routed back into the processor.
success HubSpot success relationship
Name Description
mime.type application/json
statement.type Always 'UPSERT' for this processor
hubspot.object.type HubSpot Object Type for this fetch
hubspot.object.id HubSpot Object ID for this fetch
hubspot.run.id Timestamp of the start of this run. Obtained from the incoming FlowFile or current time if not available
hubspot.is_last Whether this is the last paged object of the ingestion
Property Description
Environment URL URL to Microsoft Dataverse Environment
OAuth2 Access Token Provider Enables managed retrieval of OAuth2 Bearer Token.
Tables Filter Strategy List of table names. Output will be limited to those names if defined.
Tables Filter Value Value of Table Names filter. It is regexp or separated list, depending on selected filtering strategy.
Web Client Service Provider Creates instance of web client.
Name Description
failure FlowFile with errors occurred while fetching from Dataverse.
success FlowFile with listed tables from Dataverse.
Property Description
AWS Credentials Provider service The Controller Service that is used to obtain AWS credentials provider
Bucket The S3 Bucket to interact with
Communications Timeout The amount of time to wait in order to establish a connection to AWS or receive data from AWS before timing out.
Custom Signer Class Name Fully qualified class name of the custom signer class. The signer must implement com.amazonaws.auth. Signer interface.
Custom Signer Module Location Comma-separated list of paths to files and/or directories which contain the custom signer's JAR file and its dependencies (if any).
Delimiter The string used to delimit directories within the bucket. Please consult the AWS documentation for the correct use of this field.
Endpoint Override URL Endpoint URL to use instead of the AWS default including scheme, host, port, and path. The AWS libraries select an endpoint URL based on the AWS region, but this property overrides the selected endpoint URL, allowing use with other S3-compatible endpoints.
Entity Tracking Initial Listing Target Specify how initial listing should be handled. Used by 'Tracking Entities'strategy.
Entity Tracking State Cache Listed entities are stored in the specified cache storage so that this processor can resume listing across NiFi restart or in case of primary node change. 'Tracking Entities'strategy require tracking information of all listed entities within the last 'Tracking Time Window'. To support large number of entities, the strategy uses DistributedMapCache instead of managed state. Cache key format is 'ListedEntities::\{processorId\}(::\{nodeId\})'. If it tracks per node listed entities, then the optional '::\{nodeId\}' part is added to manage state separately. E.g. cluster wide cache key ='ListedEntities::8dda2321-0164-1000-50fa-3042fe7d6a7b', per node cache key ='ListedEntities::8dda2321-0164-1000-50fa-3042fe7d6a7b::nifi-node3' The stored cache content is Gzipped JSON string. The cache key will be deleted when target listing configuration is changed. Used by 'Tracking Entities'strategy.
Entity Tracking Time Window Specify how long this processor should track already-listed entities. 'Tracking Entities'strategy can pick any entity whose timestamp is inside the specified time window. For example, if set to '30 minutes', any entity having timestamp in recent 30 minutes will be the listing target when this processor runs. A listed entity is considered 'new/updated' and a FlowFile is emitted if one of following condition meets: 1. does not exist in the already-listed entities, 2. has newer timestamp than the cached entity, 3. has different size than the cached entity. If a cached entity 's timestamp becomes older than specified time window, that entity will be removed from the cached already-listed entities. Used by'Tracking Entities'strategy.
List Type Specifies whether to use the original List Objects or the newer List Objects Version 2 endpoint.
Listing Batch Size If not using a Record Writer, this property dictates how many S3 objects should be listed in a single batch. Once this number is reached, the FlowFiles that have been created will be transferred out of the Processor. Setting this value lower may result in lower latency by sending out the FlowFiles before the complete listing has finished. However, it can significantly reduce performance. Larger values may take more memory to store all of the information before sending the FlowFiles out. This property is ignored if using a Record Writer, as one of the main benefits of the Record Writer is being able to emit the entire listing as a single FlowFile.
Listing Strategy Specify how to determine new/updated entities. See each strategy descriptions for detail.
Maximum Object Age The maximum age that an S3 object can be in order to be considered; any object older than this amount of time (according to last modification date) will be ignored
Minimum Object Age The minimum age that an S3 object must be in order to be considered; any object younger than this amount of time (according to last modification date) will be ignored
Prefix The prefix used to filter the object list. Do not begin with a forward slash '/'. In most cases, it should end with a forward slash '/'.
Record Writer Specifies the Record Writer to use for creating the listing. If not specified, one FlowFile will be created for each entity that is listed. If the Record Writer is specified, all entities will be written to a single FlowFile instead of adding attributes to individual FlowFiles.
Region The AWS Region to connect to.
Requester Pays If true, indicates that the requester consents to pay any charges associated with listing the S3 bucket. This sets the 'x-amz-request-payer' header to 'requester'. Note that this setting is not applicable when 'Use Versions' is 'true'.
SSL Context Service Specifies an optional SSL Context Service that, if provided, will be used to create connections
Signer Override The AWS S3 library uses Signature Version 4 by default but this property allows you to specify the Version 2 signer to support older S3-compatible services or even to plug in your own custom signer implementation.
Use Versions Specifies whether to use S3 versions, if applicable. If false, only the latest version of each object will be returned.
Write Object Tags If set to 'True', the tags associated with the S3 object will be written as FlowFile attributes
Write User Metadata If set to 'True', the user defined metadata associated with the S3 object will be added to FlowFile attributes/records
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Scopes Description
CLUSTER After performing a listing of keys, the timestamp of the newest key is stored, along with the keys that share that same timestamp. This allows the Processor to list only keys that have been added or modified after this date the next time that the Processor is run. State is stored across the cluster so that this Processor can be run on Primary Node only and if a new Primary Node is selected, the new node can pick up where the previous node left off, without duplicating the data.
Name Description
success FlowFiles are routed to this Relationship after they have been successfully processed.
Name Description
s3.bucket The name of the S3 bucket
s3.region The region of the S3 bucket
filename The name of the file
s3.etag The ETag that can be used to see if the file has changed
s3.isLatest A boolean indicating if this is the latest version of the object
s3.lastModified The last modified time in milliseconds since epoch in UTC time
s3.length The size of the object in bytes
s3.storeClass The storage class of the object
s3.version The version of the object, if applicable
s3.tag.___ If 'Write Object Tags' is set to 'True', the tags associated to the S3 object that is being listed will be written as part of the flowfile attributes
s3.user.metadata.___ If 'Write User Metadata' is set to 'True', the user defined metadata associated to the S3 object that is being listed will be written as part of the flowfile attributes
Property Description
Salesforce Data Cloud Client Salesforce Data Cloud Client to interact with the APIs
Name Description
success FlowFile containing the list of available objects will be routed to this relationship
Name Description
nbObjects The number of data shares listed in the organization that are available to the identified user.
Property Description
Salesforce Client Salesforce Client to interact with the APIs
Name Description
success FlowFile containing the list of available objects will be routed to this relationship
Name Description
nbObjects The number of objects listed in the organization that are available to the identified user.
Property Description
Algorithm Negotiation Configuration strategy for SSH algorithm negotiation
Ciphers Allowed A comma-separated list of Ciphers allowed for SFTP connections. Leave unset to allow all. Available options are: 3des-cbc, aes128-cbc, aes128-ctr, [aes128-gcm@openssh.com](mailto:aes128-gcm@openssh.com), aes192-cbc, aes192-ctr, aes256-cbc, aes256-ctr, [aes256-gcm@openssh.com](mailto:aes256-gcm@openssh.com), arcfour128, arcfour256, blowfish-cbc, [chacha20-poly1305@openssh.com](mailto:chacha20-poly1305@openssh.com), none
Connection Timeout Amount of time to wait before timing out while creating a connection
Data Timeout When transferring a file between the local and remote system, this value specifies how long is allowed to elapse without any data being transferred between systems
Entity Tracking Initial Listing Target Specify how initial listing should be handled. Used by 'Tracking Entities'strategy.
Entity Tracking State Cache Listed entities are stored in the specified cache storage so that this processor can resume listing across NiFi restart or in case of primary node change. 'Tracking Entities'strategy require tracking information of all listed entities within the last 'Tracking Time Window'. To support large number of entities, the strategy uses DistributedMapCache instead of managed state. Cache key format is 'ListedEntities::\{processorId\}(::\{nodeId\})'. If it tracks per node listed entities, then the optional '::\{nodeId\}' part is added to manage state separately. E.g. cluster wide cache key ='ListedEntities::8dda2321-0164-1000-50fa-3042fe7d6a7b', per node cache key ='ListedEntities::8dda2321-0164-1000-50fa-3042fe7d6a7b::nifi-node3' The stored cache content is Gzipped JSON string. The cache key will be deleted when target listing configuration is changed. Used by 'Tracking Entities'strategy.
Entity Tracking Time Window Specify how long this processor should track already-listed entities. 'Tracking Entities'strategy can pick any entity whose timestamp is inside the specified time window. For example, if set to '30 minutes', any entity having timestamp in recent 30 minutes will be the listing target when this processor runs. A listed entity is considered 'new/updated' and a FlowFile is emitted if one of following condition meets: 1. does not exist in the already-listed entities, 2. has newer timestamp than the cached entity, 3. has different size than the cached entity. If a cached entity 's timestamp becomes older than specified time window, that entity will be removed from the cached already-listed entities. Used by'Tracking Entities'strategy.
File Filter Regex Provides a Java Regular Expression for filtering Filenames; if a filter is supplied, only files whose names match that Regular Expression will be fetched
Follow Symbolic Links If true, will pull even symbolic files and also nested symbolic subdirectories; otherwise, will not read symbolic files and will not traverse symbolic link subdirectories
Host Key File If supplied, the given file will be used as the Host Key; otherwise, if 'Strict Host Key Checking' property is applied (set to true) then uses the 'known_hosts' and 'known_hosts2' files from ~/.ssh directory else no host key file will be used
Hostname The fully qualified hostname or IP address of the remote system
Ignore Dotted Files If true, files whose names begin with a dot (".") will be ignored
Key Algorithms Allowed A comma-separated list of Key Algorithms allowed for SFTP connections. Leave unset to allow all. Available options are: ecdsa-sha2-nistp256, [ecdsa-sha2-nistp256-cert-v01@openssh.com](mailto:ecdsa-sha2-nistp256-cert-v01@openssh.com), ecdsa-sha2-nistp384, [ecdsa-sha2-nistp384-cert-v01@openssh.com](mailto:ecdsa-sha2-nistp384-cert-v01@openssh.com), ecdsa-sha2-nistp521, [ecdsa-sha2-nistp521-cert-v01@openssh.com](mailto:ecdsa-sha2-nistp521-cert-v01@openssh.com), rsa-sha2-256, [rsa-sha2-256-cert-v01@openssh.com](mailto:rsa-sha2-256-cert-v01@openssh.com), rsa-sha2-512, [rsa-sha2-512-cert-v01@openssh.com](mailto:rsa-sha2-512-cert-v01@openssh.com), [sk-ecdsa-sha2-nistp256@openssh.com](mailto:sk-ecdsa-sha2-nistp256@openssh.com), [sk-ssh-ed25519@openssh.com](mailto:sk-ssh-ed25519@openssh.com), ssh-dss, [ssh-dss-cert-v01@openssh.com](mailto:ssh-dss-cert-v01@openssh.com), ssh-ed25519, [ssh-ed25519-cert-v01@openssh.com](mailto:ssh-ed25519-cert-v01@openssh.com), ssh-rsa, [ssh-rsa-cert-v01@openssh.com](mailto:ssh-rsa-cert-v01@openssh.com)
Key Exchange Algorithms Allowed A comma-separated list of Key Exchange Algorithms allowed for SFTP connections. Leave unset to allow all. Available options are: curve25519-sha256, [curve25519-sha256@libssh.org](mailto:curve25519-sha256@libssh.org), curve448-sha512, diffie-hellman-group-exchange-sha1, diffie-hellman-group-exchange-sha256, diffie-hellman-group1-sha1, diffie-hellman-group14-sha1, diffie-hellman-group14-sha256, diffie-hellman-group15-sha512, diffie-hellman-group16-sha512, diffie-hellman-group17-sha512, diffie-hellman-group18-sha512, ecdh-sha2-nistp256, ecdh-sha2-nistp384, ecdh-sha2-nistp521, mlkem1024nistp384-sha384, mlkem768nistp256-sha256, mlkem768x25519-sha256, sntrup761x25519-sha512, [sntrup761x25519-sha512@openssh.com](mailto:sntrup761x25519-sha512@openssh.com)
Listing Strategy Specify how to determine new/updated entities. See each strategy descriptions for detail.
Maximum File Age The maximum age that a file must be in order to be pulled; any file older than this amount of time (according to last modification date) will be ignored
Maximum File Size The maximum size that a file can be in order to be pulled
Message Authentication Codes Allowed A comma-separated list of Message Authentication Codes allowed for SFTP connections. Leave unset to allow all. Available options are: hmac-md5, hmac-md5-96, hmac-sha1, hmac-sha1-96, [hmac-sha1-etm@openssh.com](mailto:hmac-sha1-etm@openssh.com), hmac-sha2-256, [hmac-sha2-256-etm@openssh.com](mailto:hmac-sha2-256-etm@openssh.com), hmac-sha2-512, [hmac-sha2-512-etm@openssh.com](mailto:hmac-sha2-512-etm@openssh.com)
Minimum File Age The minimum age that a file must be in order to be pulled; any file younger than this amount of time (according to last modification date) will be ignored
Minimum File Size The minimum size that a file must be in order to be pulled
Password Password for the user account
Path Filter Regex When Search Recursively is true, then only subdirectories whose path matches the given Regular Expression will be scanned
Port The port that the remote system is listening on for file transfers
Private Key Passphrase Password for the private key
Private Key Path The fully qualified path to the Private Key file
Record Writer Specifies the Record Writer to use for creating the listing. If not specified, one FlowFile will be created for each entity that is listed. If the Record Writer is specified, all entities will be written to a single FlowFile instead of adding attributes to individual FlowFiles.
Remote Path The path on the remote system from which to pull or push files
Search Recursively If true, will pull files from arbitrarily nested subdirectories; otherwise, will not traverse subdirectories
Send Keep Alive On Timeout Send a Keep Alive message every 5 seconds up to 5 times for an overall timeout of 25 seconds.
Strict Host Key Checking Indicates whether or not strict enforcement of hosts keys should be applied
Target System Timestamp Precision Specify timestamp precision at the target system. Since this processor uses timestamp of entities to decide which should be listed, it is crucial to use the right timestamp precision.
Use Compression Indicates whether or not ZLIB compression should be used when transferring files
Username Username
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Scopes Description
CLUSTER After performing a listing of files, the timestamp of the newest file is stored. This allows the Processor to list only files that have been added or modified after this date the next time that the Processor is run. State is stored across the cluster so that this Processor can be run on Primary Node only and if a new Primary Node is selected, the new node will not duplicate the data that was listed by the previous Primary Node.
Name Description
success All FlowFiles that are received are routed to success
Name Description
sftp.remote.host The hostname of the SFTP Server
sftp.remote.port The port that was connected to on the SFTP Server
sftp.listing.user The username of the user that performed the SFTP Listing
file.owner The numeric owner id of the source file
file.group The numeric group id of the source file
file.permissions The read/write/execute permissions of the source file
file.size The number of bytes in the source file
file.lastModifiedTime The timestamp of when the file in the filesystem waslast modified as 'yyyy-MM-dd'T'HH:mm:ssZ'
filename The name of the file on the SFTP Server
path The fully qualified name of the directory on the SFTP Server from which the file was pulled
mime.type The MIME Type that is provided by the configured Record Writer
Property Description
Authentication Service The service that provides authentication for the SharePoint API.
Site URL The URL of the Sharepoint Site.
Name Description
success FlowFiles for each Drive are routed to this relationship
Name Description
sharepoint.site.url The URL of the Sharepoint Site.
sharepoint.site.id The ID of the Sharepoint Site.
sharepoint.drive.name The name of the Sharepoint Drive.
sharepoint.drive.id The ID of the Sharepoint Drive.
Property Description
OAuth2 Access Token Provider Enables managed retrieval of OAuth2 Bearer Token.
Record Writer Record writer used for writing out the records of retrieved Sharepoint Site Groups.
Site URL The URL of the SharePoint site.
Web Client Service The Web Client Service to use for communicating with Sharepoint.
Name Description
success Successfully listed all SharePoint site groups. Each group will be represented as a separate FlowFile.
Name Description
record.count The number of records (groups) returned.
mime.type The MIME type for the resulting FlowFile.
Property Description
Entity Tracking Initial Listing Target Specify how initial listing should be handled. Used by 'Tracking Entities'strategy.
Entity Tracking State Cache Listed entities are stored in the specified cache storage so that this processor can resume listing across NiFi restart or in case of primary node change. 'Tracking Entities'strategy require tracking information of all listed entities within the last 'Tracking Time Window'. To support large number of entities, the strategy uses DistributedMapCache instead of managed state. Cache key format is 'ListedEntities::\{processorId\}(::\{nodeId\})'. If it tracks per node listed entities, then the optional '::\{nodeId\}' part is added to manage state separately. E.g. cluster wide cache key ='ListedEntities::8dda2321-0164-1000-50fa-3042fe7d6a7b', per node cache key ='ListedEntities::8dda2321-0164-1000-50fa-3042fe7d6a7b::nifi-node3' The stored cache content is Gzipped JSON string. The cache key will be deleted when target listing configuration is changed. Used by 'Tracking Entities'strategy.
Entity Tracking Time Window Specify how long this processor should track already-listed entities. 'Tracking Entities'strategy can pick any entity whose timestamp is inside the specified time window. For example, if set to '30 minutes', any entity having timestamp in recent 30 minutes will be the listing target when this processor runs. A listed entity is considered 'new/updated' and a FlowFile is emitted if one of following condition meets: 1. does not exist in the already-listed entities, 2. has newer timestamp than the cached entity, 3. has different size than the cached entity. If a cached entity 's timestamp becomes older than specified time window, that entity will be removed from the cached already-listed entities. Used by'Tracking Entities'strategy.
Listing Strategy Specify how to determine new/updated entities. See each strategy descriptions for detail.
Record Writer Specifies the Record Writer to use for creating the listing. If not specified, one FlowFile will be created for each entity that is listed. If the Record Writer is specified, all entities will be written to a single FlowFile instead of adding attributes to individual FlowFiles.
Target System Timestamp Precision Specify timestamp precision at the target system. Since this processor uses timestamp of entities to decide which should be listed, it is crucial to use the right timestamp precision.
directory The network folder from which to list files. This is the remaining relative path after the share: [smb://HOSTNAME:PORT/SHARE/[DIRECTORY]/sub/directories](smb://HOSTNAME:PORT/SHARE/[DIRECTORY]/sub/directories). It is also possible to add subdirectories. The given path on the remote file share must exist. This can be checked using verification. You may mix Windows and Linux-style directory separators.
file-filter Only files whose names match the given regular expression will be listed.
file-name-suffix-filter Files ending with the given suffix will be omitted. Can be used to make sure that files that are still uploading are not listed multiple times, by having those files have a suffix and remove the suffix once the upload finishes. This is highly recommended when using 'Tracking Entities' or 'Tracking Timestamps' listing strategies.
initial-listing-strategy Specifies how to handle existing files on the SMB share when the processor is started for the first time (or its state has been cleared).
initial-listing-timestamp The timestamp from which the files will be listed when the processor is started for the first time (or its state has been cleared). The value can be specified as an epoch timestamp in milliseconds or as a UTC datetime in a format such as 2025-02-01T00:00:00Z
max-file-age Any file older than the given value will be omitted.
max-file-size Any file larger than the given value will be omitted.
min-file-age The minimum age that a file must be in order to be listed; any file younger than this amount of time will be ignored.
min-file-size Any file smaller than the given value will be omitted.
path-filter Only files whose paths (up to the file's parent directory) match the given regular expression will be listed.
smb-client-provider-service Specifies the SMB client provider to use for creating SMB connections.
Scopes Description
CLUSTER After performing a listing of files, the state of the previous listing can be stored in order to list files continuously without duplication.
Name Description
success All FlowFiles that are received are routed to success
Name Description
filename The name of the file that was read from filesystem.
shortName The short name of the file that was read from filesystem.
path The path is set to the relative path of the file's directory on the remote filesystem compared to the Share root directory. For example, for a given remote locationsmb://HOSTNAME:PORT/SHARE/DIRECTORY, and a file is being listed from smb://HOSTNAME:PORT/SHARE/DIRECTORY/sub/folder/file then the path attribute will be set to "DIRECTORY/sub/folder".
serviceLocation The SMB URL of the share.
lastModifiedTime The timestamp of when the file's content changed in the filesystem as 'yyyy-MM-dd'T'HH:mm:ss'.
creationTime The timestamp of when the file was created in the filesystem as 'yyyy-MM-dd'T'HH:mm:ss'.
lastAccessTime The timestamp of when the file was accessed in the filesystem as 'yyyy-MM-dd'T'HH:mm:ss'.
changeTime The timestamp of when the file's attributes was changed in the filesystem as 'yyyy-MM-dd'T'HH:mm:ss'.
size The size of the file in bytes.
allocationSize The number of bytes allocated for the file on the server.
Property Description
Connection Pool The Controller Service that is used to obtain a connection to the database.
Included Comma Separated Source Table Names The list of comma separated list of tables to replicate. A single table should be formatted as <schema_name>.<table_name> e.g. customer.orders, customer.payments. This is combined with the regular expression to include any matching table.
Included Source Table Pattern Regular Expression for specifying table names to replicate e.g. customer.(orders|payments). This is combined with the comma-separated list to include any matching table.
Name Description
failure If a FlowFile attribute cannot be read or is incorrect, it will be routed to this Relationship.
matched Successfully created FlowFile, with a list of matching tables found in the source database.
Name Description
source.schema.name Name of the schema of the table from which an event originated
source.table.name Name of the table from which an event originated
source.entry The original entry that was attempted to parse when processing table names
reason Reason why table cannot be replicated
source.database.version.major The major version of the source database.
mime.type The MIME type of the FlowFile content.
Property Description
Databricks Client Databricks Client Service.
Include Directories Include directories in FlowFiles produced.
Recursive Directory Listing Recursively list files in sub directories.
Unity Catalog Directory Path Unity Catalog directory path e.g. /Volumes/catalog/schema/volume_name/directory
Name Description
failure Databricks failure relationship
original The original FlowFile is routed to this relationship when processing is successful.
success Databricks success relationship
Name Description
filename Base filename of the Unity Catalog file or directory.
path Path to parent directory containing the Unity Catalog file or directory.
absolute.path Full path to the Unity Catalog file or directory.
uc.resourceType The type of resource, 'file' or 'directory' of the Unity Catalog resource.
uc.size The size of the Unity Catalog file.
uc.lastModifiedTime The last modified time of the Unity Catalog file in milliseconds since epoch in UTC time.
error.code The error code for the SQL statement if an error occurred.
error.message The error message for the SQL statement if an error occurred.
Property Description
Attributes to Ignore A comma-separated list of Attributes to ignore. If not specified, no attributes will be ignored unless _Attributes to Ignore by Regular Expression_ is modified. There's an OR relationship between the two properties.
Attributes to Log A comma-separated list of Attributes to Log. If not specified, all attributes will be logged unless _Attributes to Log by Regular Expression_ is modified. There's an AND relationship between the two properties.
Log FlowFile Properties Specifies whether or not to log FlowFile "properties", such as Entry Date, Lineage Start Date, and content size
Log Level The Log Level to use when logging the Attributes
Log Payload If true, the FlowFile's payload will be logged, in addition to its attributes; otherwise, just the Attributes will be logged.
Log prefix Log prefix appended to the log lines. It helps to distinguish the output of multiple LogAttribute processors.
Output Format Specifies the format to use for logging FlowFile attributes
attributes-to-ignore-regex A regular expression indicating the Attributes to Ignore. If not specified, no attributes will be ignored unless _Attributes to Ignore_ is modified. There's an OR relationship between the two properties.
attributes-to-log-regex A regular expression indicating the Attributes to Log. If not specified, all attributes will be logged unless _Attributes to Log_ is modified. There's an AND relationship between the two properties.
character-set The name of the CharacterSet to use
Name Description
success All FlowFiles are routed to this relationship
Display Name API Name Default Value Allowable Values Description
Log Level * logsink-log-level INFO - TRACE - DEBUG - INFO - WARN - ERROR - FATAL - NONE The Log Level at which to log records (INFO, DEBUG, e.g.)
Record Writer * record-sink-record-writer Specifies the Controller Service to use for writing out the records.
Property Description
log-level The Log Level to use when logging the message: [trace, debug, info, warn, error]
log-message The log message to emit
log-prefix Log prefix appended to the log lines. It helps to distinguish the output of multiple LogMessage processors.
Name Description
success All FlowFiles are routed to this relationship
Property Description
include-empty-values Include null or blank values for keys that are null or blank
lookup-service The lookup service to use for attribute lookups
Name Description
failure FlowFiles with failing lookups are routed to this relationship
matched FlowFiles with matching lookups are routed to this relationship
unmatched FlowFiles with missing lookups are routed to this relationship
Property Description
Root Record Path A RecordPath that points to a child Record within each of the top-level Records in the FlowFile. If specified, the additional RecordPath properties will be evaluated against this child Record instead of the top-level Record. This allows for performing enrichment against multiple child Records within a single top-level Record.
lookup-service The Lookup Service to use in order to lookup a value in each Record
record-path-lookup-miss-result-cache-size Specifies how many lookup values/records should be cached. Setting this property to zero means no caching will be done and the table will be queried for each lookup value in each record. If the lookup table changes often or the most recent data must be retrieved, do not use the cache.
record-reader Specifies the Controller Service to use for reading incoming data
record-update-strategy This property defines the strategy to use when updating the record with the value returned by the Lookup Service.
record-writer Specifies the Controller Service to use for writing out the records
result-contents When a result is obtained that contains a Record, this property determines whether the Record itself is inserted at the configured path or if the contents of the Record (i.e., the sub-fields) will be inserted at the configured path.
result-record-path A RecordPath that points to the field whose value should be updated with whatever value is returned from the Lookup Service. If not specified, the value that is returned from the Lookup Service will be ignored, except for determining whether the FlowFile should be routed to the 'matched' or 'unmatched' Relationship.
routing-strategy Specifies how to route records after a Lookup has completed
Name Description
failure If a FlowFile cannot be enriched, the unchanged FlowFile will be routed to this relationship
success All records will be sent to this Relationship if configured to do so, unless a failure occurs
Name Description
mime.type Sets the mime.type attribute to the MIME Type specified by the Record Writer
record.count The number of records in the FlowFile
Display Name API Name Default Value Allowable Values Description
Communications Timeout * Communications Timeout 30 secs Specifies how long to wait when communicating with the remote server before determining that there is a communications failure if data cannot be sent or received
SSL Context Service SSL Context Service If specified, indicates the SSL Context Service that is used to communicate with the remote server. If not specified, communications will not be encrypted
Server Hostname * Server Hostname The name of the server that is running the DistributedMapCacheServer service
Server Port * Server Port 4557 The port on the remote server that is to be used when communicating with the DistributedMapCacheServer service
Display Name API Name Default Value Allowable Values Description
Eviction Strategy * Eviction Strategy Least Frequently Used - Least Frequently Used - Least Recently Used - First In, First Out Determines which strategy should be used to evict values from the cache to make room for new entries
Maximum Cache Entries * Maximum Cache Entries 10000 The maximum number of cache entries that the cache can hold
Persistence Directory Persistence Directory If specified, the cache will be persisted in the given directory; if not specified, the cache will be in-memory only
Port * Port 4557 The port to listen on for incoming connections
SSL Context Service SSL Context Service If specified, this service will be used to create an SSL Context that will be used to secure communications; if not specified, communications will not be secure
Maximum Read Size maximum-read-size 1 MB The maximum number of network bytes to read for a single cache item
Property Description
Attribute Strategy Determines which FlowFile attributes should be added to the bundle. If 'Keep All Unique Attributes' is selected, any attribute on any FlowFile that gets bundled will be kept unless its value conflicts with the value from another FlowFile. If 'Keep Only Common Attributes' is selected, only the attributes that exist on all FlowFiles in the bundle, with the same value, will be preserved.
Bin Termination Check Specifies an Expression Language Expression that is to be evaluated against each FlowFile. If the result of the expression is 'true', the bin that the FlowFile corresponds to will be terminated, even if the bin has not met the minimum number of entries or minimum size. Note that if the FlowFile that triggers the termination of the bin is itself larger than the Maximum Bin Size, it will be placed into its own bin without triggering the termination of any other bin. When using this property, it is recommended to use Prioritizers in the flow's connections to ensure that the ordering is as desired.
Compression Level Specifies the compression level to use when using the Zip Merge Format; if not using the Zip Merge Format, this value is ignored
Correlation Attribute Name If specified, like FlowFiles will be binned together, where 'like FlowFiles' means FlowFiles that have the same value for this Attribute. If not specified, FlowFiles are bundled by the order in which they are pulled from the queue.
Delimiter Strategy Determines if Header, Footer, and Demarcator should point to files containing the respective content, or if the values of the properties should be used as the content.
Demarcator File Filename or text specifying the demarcator to use. If not specified, no demarcator is supplied.
FlowFile Insertion Strategy If a given FlowFile terminates the bin based on the <Bin Termination Check> property, specifies where the FlowFile should be included in the bin.
Footer File Filename or text specifying the footer to use. If not specified, no footer is supplied.
Header File Filename or text specifying the header to use. If not specified, no header is supplied.
Keep Path If using the Zip or Tar Merge Format, specifies whether or not the FlowFiles' paths should be included in their entry names.
Max Bin Age The maximum age of a Bin that will trigger a Bin to be complete. Expected format is <duration> <time unit> where <duration> is a positive integer and time unit is one of seconds, minutes, hours
Maximum Group Size The maximum size for the bundle. If not specified, there is no maximum.
Maximum Number of Entries The maximum number of files to include in a bundle
Maximum number of Bins Specifies the maximum number of bins that can be held in memory at any one time
Merge Format Determines the format that will be used to merge the content.
Merge Strategy Specifies the algorithm used to merge content. The 'Defragment' algorithm combines fragments that are associated by attributes back into a single cohesive FlowFile. The 'Bin-Packing Algorithm' generates a FlowFile populated by arbitrarily chosen FlowFiles
Minimum Group Size The minimum size for the bundle
Minimum Number of Entries The minimum number of files to include in a bundle
Tar Modified Time If using the Tar Merge Format, specifies if the Tar entry should store the modified timestamp either by expression (e.g. $\{file.lastModifiedTime\} or static value, both of which must match the ISO8601 format 'yyyy-MM-dd'T 'HH:mm:ssZ'.
mergecontent-metadata-strategy For FlowFiles whose input format supports metadata (Avro, e.g.), this property determines which metadata should be added to the bundle. If 'Use First Metadata' is selected, the metadata keys/values from the first FlowFile to be bundled will be used. If 'Keep Only Common Metadata' is selected, only the metadata that exists on all FlowFiles in the bundle, with the same value, will be preserved. If 'Ignore Metadata' is selected, no metadata is transferred to the outgoing bundled FlowFile. If 'Do Not Merge Uncommon Metadata' is selected, any FlowFile whose metadata values do not match those of the first bundled FlowFile will not be merged.
Name Description
failure If the bundle cannot be created, all FlowFiles that would have been used to created the bundle will be transferred to failure
merged The FlowFile containing the merged content
original The FlowFiles that were used to create the bundle
Name Description
filename When more than 1 file is merged, the filename comes from the segment.original.filename attribute. If that attribute does not exist in the source FlowFiles, then the filename is set to the number of nanoseconds matching system time. Then a filename extension may be applied:if Merge Format is TAR, then the filename will be appended with .tar, if Merge Format is ZIP, then the filename will be appended with .zip, if Merge Format is FlowFileStream, then the filename will be appended with .pkg
merge.count The number of FlowFiles that were merged into this bundle
merge.bin.age The age of the bin, in milliseconds, when it was merged and output. Effectively this is the greatest amount of time that any FlowFile in this bundle remained waiting in this processor before it was output
merge.uuid UUID of the merged flow file that will be added to the original flow files attributes.
merge.reason This processor allows for several thresholds to be configured for merging FlowFiles. This attribute indicates which of the Thresholds resulted in the FlowFiles being merged. For an explanation of each of the possible values and their meanings, see the Processor's Usage / documentation and see the 'Additional Details' page.
Property Description
Attribute Strategy Determines which FlowFile attributes should be added to the bundle. If 'Keep All Unique Attributes' is selected, any attribute on any FlowFile that gets bundled will be kept unless its value conflicts with the value from another FlowFile. If 'Keep Only Common Attributes' is selected, only the attributes that exist on all FlowFiles in the bundle, with the same value, will be preserved.
correlation-attribute-name If specified, two FlowFiles will be binned together only if they have the same value for this Attribute. If not specified, FlowFiles are bundled by the order in which they are pulled from the queue.
max-bin-age The maximum age of a Bin that will trigger a Bin to be complete. Expected format is <duration> <time unit> where <duration> is a positive integer and time unit is one of seconds, minutes, hours
max-bin-size The maximum size for the bundle. If not specified, there is no maximum. This is a 'soft limit' in that if a FlowFile is added to a bin, all records in that FlowFile will be added, so this limit may be exceeded by up to the number of bytes in last input FlowFile.
max-records The maximum number of Records to include in a bin. This is a 'soft limit' in that if a FlowFIle is added to a bin, all records in that FlowFile will be added, so this limit may be exceeded by up to the number of records in the last input FlowFile.
max.bin.count Specifies the maximum number of bins that can be held in memory at any one time. This number should not be smaller than the maximum number of concurrent threads for this Processor, or the bins that are created will often consist only of a single incoming FlowFile.
merge-strategy Specifies the algorithm used to merge records. The 'Defragment' algorithm combines fragments that are associated by attributes back into a single cohesive FlowFile. The 'Bin-Packing Algorithm' generates a FlowFile populated by arbitrarily chosen FlowFiles
min-bin-size The minimum size of for the bin
min-records The minimum number of records to include in a bin
record-reader Specifies the Controller Service to use for reading incoming data
record-writer Specifies the Controller Service to use for writing out the records
Name Description
failure If the bundle cannot be created, all FlowFiles that would have been used to created the bundle will be transferred to failure
merged The FlowFile containing the merged records
original The FlowFiles that were used to create the bundle
Name Description
record.count The merged FlowFile will have a 'record.count' attribute indicating the number of records that were written to the FlowFile.
mime.type The MIME Type indicated by the Record Writer
merge.count The number of FlowFiles that were merged into this bundle
merge.bin.age The age of the bin, in milliseconds, when it was merged and output. Effectively this is the greatest amount of time that any FlowFile in this bundle remained waiting in this processor before it was output
merge.uuid UUID of the merged FlowFile that will be added to the original FlowFiles attributes
merge.completion.reason This processor allows for several thresholds to be configured for merging FlowFiles. This attribute indicates which of the Thresholds resulted in the FlowFiles being merged. For an explanation of each of the possible values and their meanings, see the Processor's Usage / documentation and see the 'Additional Details' page.
<Attributes from Record Writer> Any Attribute that the configured Record Writer returns will be added to the FlowFile.
Property Description
Destination Database Name The name of the Snowflake database where the data is being ingested to.
Merge Query Retry Count Indicates how many times the merge query should be retried if it fails.
Object Identifier Resolution Controls how source object identifiers (schemas, tables, columns) are stored and queried in Snowflake. This setting determines whether you will need to use double quotes in your SQL queries. The 'Case-Sensitive' option is the default, production behavior — 'Case-Insensitive' is considered preview for the time being.
Placeholder Value The value of the payload placeholder to look for in a MERGE. This will be converted to the destination column's data type.
Snowflake Connection Pool The Controller Service that is used to obtain a connection to the Snowflake database to perform merge operation.
Unchanged Value Strategy Determines how the MERGE query should handle unchanged values in journal columns. By default it expects full values.
Name Description
ddl DDL to execute.
deleted during compaction FlowFile deleted during compaction based on table name and generation.
failure Failure query execution.
failure retry Retry failure query execution.
poll query result Scheduled async query execution.
success Success query execution.
unknown file type Unknown file type.
Name Description
merge.query.id The ID of the query that is used to merge the journal table into the target table.
Display Name API Name Default Value Allowable Values Description
Client ID * Client ID The Client ID for the Microsoft Graph API
Refresh Window * Refresh Window 5 s The service will attempt to refresh tokens expiring within the refresh window, subtracting the configured duration from the token expiration.
SSL Context Service * SSL Context Service An instance of SSLContextProvider configured with a certificate and a private key which will be used to sign the JWT assertion. The keys must use RSA algorithm.
Tenant ID * Tenant ID The Tenant ID for the Microsoft Graph API
Token Scope * Token Scope The scope of the requested token.For Graph API should be: https://graph.microsoft.com/.defaultFor (https://graph.microsoft.com/.defaultFor) Sharepoint should in the following format: https://organization.sharepoint.com/.default (https://organization.sharepoint.com/.default)
Web Client Service * Web Client Service The Web Client Service to retrieve access tokens.
Display Name API Name Default Value Allowable Values Description
Authentication Mechanism * Authentication Mechanism Client Secret - Client Secret - Username / Password The mechanism to use for authenticating with the Microsoft Graph API
Client ID * Client ID The Client ID for the Microsoft Graph API
Client Secret * Client Secret The Client Secret for the Microsoft Graph API
Password * Password The password to use for authentication
Tenant ID * Tenant ID The Tenant ID for the Microsoft Graph API
Username * Username The username to use for authentication
Aspect Legacy connector New connector
Entities Issues only (with optional worklog enrichment). Core flow: issues, projects, users, comments, changelogs, worklogs, votes, watchers, remote links, security schemes, permissions, project components, project versions, user groups, deleted issues, and lookup tables for issue type, priority, resolution, and status. Agile flow: boards, sprints, board-sprint, board-project, board-issue mappings.
Concurrency Single-threaded. Parallel per-project issue fetching, with optional multi-node distribution.
Schema strategy Raw JSON in an `OBJECT` column with a dynamically generated flattened view. Explicit column schemas per entity, evolved additively from the API responses.
Deletion tracking Not supported. Tracks deleted issues via Jira audit log polling (optional).
Agile data Not supported. Available through a separate agile flow.
Aspect Legacy connector New connector
Issues table Single table with an `ISSUE` column containing the full raw JSON as an `OBJECT` type. A flattened `_VIEW` is auto-generated. Explicit columns per field. Column names are derived from Jira field display names. No raw JSON fallback.
Other entities Not available. Comments and worklogs are embedded in the issue JSON. Separate tables: `BOARD`, `BOARD_ISSUE`, `BOARD_PROJECT`, `BOARD_SPRINT`, `CHANGELOG`, `COMMENT`, `DELETED_ISSUE`, `FIELD`, `ISSUE_REMOTE_LINK`, `ISSUE_SECURITY_SCHEME`, `ISSUE_TYPE`, `ISSUE_VOTE`, `ISSUE_WATCHER`, `PERMISSION`, `PRIORITY`, `PROJECT`, `PROJECT_COMPONENT`, `PROJECT_VERSION`, `RESOLUTION`, `SPRINT`, `STATUS`, `USER`, `USER_GROUP`, `WORKLOG`. See [](#label-jira-entities) for the full inventory.
Views Auto-generated `_VIEW` with all issue fields flattened. Any queries that reference the legacy `ISSUE` column (for example, `SELECT issue:fields:summary`) or the auto-generated `_VIEW` must be rewritten to use the new column names directly (for example, `SELECT SUMMARY`). ### Parameter changes The following parameters from the legacy connector are not available in the new connector:
The following parameters are introduced in the new connector:
Additionally, agile data (boards, sprints, and board mappings) is now available through a separate agile flow rather than a parameter toggle. See [Set up the Atlassian Jira Cloud (Agile) flow](/user-guide/data-integration/openflow/connectors/jira-cloud/setup-agile) for details on installing and configuring the agile flow. ### API token scopes If you're using API tokens with scopes, the new connector may require additional scopes depending on the features you enable. See [](#label-jira-core-api-scopes) for the core flow scopes and [](#label-jira-agile-api-scopes) for the agile flow scopes. ### Snowflake privileges The new connector requires only `CREATE TABLE` on the destination schema. The legacy connector additionally required `CREATE VIEW` to create flattened issue views. The new connector doesn't create views, so the `CREATE VIEW` privilege is no longer needed. If you're reusing an existing role, you can revoke `CREATE VIEW` after the legacy connector is decommissioned. ## Migration steps 1. **Set up the new connector.** Install the core flow on the same or a different Openflow runtime. If you need agile data, also install the agile flow. Configure both flows to write to a **different destination schema** than the one used by the legacy connector. This allows the legacy and new connectors to run simultaneously. 2. **Map your legacy configuration to the new parameters.** - Copy the `Jira Email`, `Jira API Token`, and `Environment URL` values from the legacy connector to the new core flow. If using the agile flow, configure these values separately for that flow as well. - If the legacy connector uses `Project Names`, convert them to project keys for the `Project Keys Filter` parameter. - If the legacy connector uses a `JQL Query`, evaluate whether `Project Keys Filter` covers your use case. If your JQL filters by criteria other than project (for example, status or custom fields), those filters aren't available in the new connector. All matching issues from the configured projects are ingested. - Set `Issue Fields` to match your previous configuration. The default changed from `*all` (legacy) to `*standard`. - Configure the Snowflake destination parameters (database, schema, warehouse, credentials) for each flow. 3. **Start the new connector.** Run the core flow and allow the initial load to complete. If using the agile flow, start it as well. 4. **Validate the data.** Compare the data in the new destination tables against the legacy destination table to check for completeness. Expect some differences: the legacy connector didn't track deletes, so issues that were deleted in Jira still appear in the legacy table but not in the new `ISSUE` table (or they appear with `_SNOWFLAKE_DELETED = TRUE` if delete tracking is enabled). Row counts will not match exactly when any issues have been deleted. ```sql -- Compare issue counts (expect differences if issues were deleted in Jira) SELECT COUNT(*) AS legacy_count FROM legacy_schema.JIRA_ISSUES; SELECT COUNT(*) AS new_count FROM new_schema.ISSUE; -- Spot-check specific issues. ISSUE_TYPE, PRIORITY, RESOLUTION, and STATUS -- are Jira IDs; join the lookup tables to resolve names. SELECT i.KEY, i.SUMMARY, s.NAME AS status_name FROM new_schema.ISSUE i LEFT JOIN new_schema.STATUS s ON i.STATUS = s.ID WHERE i.KEY = 'PROJ-123'; ``` 5. **Update downstream queries.** Rewrite any queries, views, dashboards, or pipelines that reference the legacy table structure. Key changes: - Replace references to the legacy `ISSUE` `OBJECT` column or `_VIEW` with direct column references. - Replace `FLATTEN`-based queries with standard `SELECT` statements. - Add `JOIN` statements to combine data across the new entity tables (for example, join `ISSUE` with `COMMENT` on `ISSUE_ID`, or join `ISSUE` to `STATUS` on `ISSUE.STATUS = STATUS.ID` to resolve status names). - If you want queries to ignore deleted issues, filter on the new `_SNOWFLAKE_DELETED` column (`WHERE _SNOWFLAKE_DELETED = FALSE`). The legacy connector didn't track deletes at all, so legacy queries against `JIRA_ISSUES` returned issues that had since been removed in Jira. 6. **Stop the legacy connector.** Once you've confirmed that the new data is complete and downstream consumers have been updated, stop the legacy connector process group. Both new flows (core and agile) can continue running independently. 7. **Clean up.** Optionally, drop the legacy destination table and view after confirming they're no longer needed. When the legacy connector and the new connector use the same Jira API token, they share the same Jira API rate limits. Running both simultaneously roughly doubles the API call volume, which may cause rate limiting on Jira instances with heavy API usage. Consider reducing the legacy ingestion frequency during the migration period, or run the new connector with a separate API token whose rate budget you can manage independently. --- title: ModifyBytes 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/modifybytes.md section: Loading & Unloading Data --- # ModifyBytes 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Discard byte range at the start and end or all content of a binary file. ## Tags binary, discard, keep ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: ModifyCompression 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/modifycompression.md section: Loading & Unloading Data --- # ModifyCompression 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-compress-nar ## Description Changes the compression algorithm used to compress the contents of a FlowFile by decompressing the contents of FlowFiles using a user-specified compression algorithm and recompressing the contents using the specified compression format properties. This processor operates in a very memory efficient way so very large objects well beyond the heap size are generally fine to process ## Tags brotli, bzip2, compress, content, deflate, gzip, lz4-framed, lzma, recompress, snappy, snappy framed, snappy-hadoop, xz-lzma2, zstd ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: MongoDBControllerService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/mongodbcontrollerservice.md section: Loading & Unloading Data --- # MongoDBControllerService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides a controller service that configures a connection to MongoDB and provides access to that connection to other Mongo-related components. ## Tags mongo, mongodb, service ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: MongoDBLookupService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/mongodblookupservice.md section: Loading & Unloading Data --- # MongoDBLookupService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides a lookup service based around MongoDB. Each key that is specified will be added to a query as-is. For example, if you specify the two keys, user and email, the resulting query will be \{ "user": "tester", "email": "[tester@test.com](mailto:tester@test.com)" \}. The query is limited to the first result (findOne in the Mongo documentation). If no "Lookup Value Field" is specified then the entire MongoDB result document minus the _id field will be returned as a record. ## Tags lookup, mongo, mongodb, record ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: Monitor connectors using the Openflow Connectors Dashboard source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors-dashboard.md section: Loading & Unloading Data --- " /> # Monitor connectors using the Openflow Connectors Dashboard This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions). - [Monitor Openflow using telemetry data](/user-guide/data-integration/openflow/monitor) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) The Openflow Connectors Dashboard provides a high-level view of all installed connectors, health snapshots, and key performance indicators, such as the aggregated average throughput and total data ingested by all connectors matching the filter criteria. ## Prerequisites To use the Openflow Connectors Dashboard, the following prerequisites must be met: - You need at least read-only permissions on the event table. - You must have the following minimum Openflow versions: - BYOC deployment: 1.36.0 - Snowflake deployment: 1.26.0 - Runtime: 2026.3.17.13 - You must have the following minimum connector versions. These versions apply to Database connectors only. Other connector types don't have a minimum version requirement for dashboard support.
See [Snowflake Openflow version history](/user-guide/data-integration/openflow/version-history) for more information. ## Access the Openflow Connectors Dashboard 1. Sign in to %sf-web-interface-link%. 2. In the navigation menu, select **Ingestion** %raa% **Openflow** and navigate to the **Connector Observability** tab. The Openflow Connectors Dashboard appears. ## The Openflow Connectors Dashboard overview The Openflow Connectors Dashboard displays the following information:
**Status**
Shows the number of connectors with the following statuses: - **Healthy**: Didn't encounter any errors during the selected time period. - **Unhealthy**: Logged errors in the event table during the selected time period or has one or more tables in **Failed** state (Database connectors only). - **Upgrade required**: Openflow deployment, runtime, or connector aren't running the minimum required versions to display health and performance metrics. Review the version prerequisites and upgrade as needed.
**Average throughput**
Measures the rate at which data is read from source systems and sent to Snowflake across all connectors. - The **Average throughput** %raa% **Ingested** metric measures how fast data is sent to Snowflake across all connectors that match the primary filter criteria (time frame and event table). - The **Average throughput** %raa% **Read** metric measures how fast Openflow reads data from source systems across all connectors that match the primary filter criteria (time frame and event table).
**Total data ingested**
Shows how much data all connectors that match the primary filter criteria for time frame and event table have sent to Snowflake during the selected time period. Use this metric to quickly identify ingestion anomalies over a specific time period.
For custom telemetry queries beyond the dashboard, see [Monitor Openflow using telemetry data](/user-guide/data-integration/openflow/monitor). - **Total data ingested** and **Average throughput** metrics include both raw payload and structural overhead such as JSON keys, braces, and delimiters. Because these metrics track the total transmitted volume, these figures might be higher than the uncompressed data reported by Snowpipe Streaming or the final storage volume in your destination table. - The connectors appear in the list if they match the selected filter criteria and have recorded telemetry events during the selected time frame. - If you examine longer time frames, the list might show connectors that were previously deleted. For example, you deployed a connector six days ago, and then deleted that connector two days ago. If you set the time frame to **Last 7 days**, the connector appears in the list because it recorded telemetry events in the last 7 days. ### Filtering connectors The Openflow Connectors Dashboard supports the following filters:
**Event table**
The Openflow connectors event table you want to monitor. This filter displays event tables that are associated with at least one Openflow deployment, as well as the default event table and the account event table. You can select only one event table at a time. Event table views are also supported. The event table is set when you set up Openflow. To view the event table associated with an Openflow deployment, use the [DESCRIBE OPENFLOW DATA PLANE INTEGRATION](/sql-reference/sql/desc-oflow-data-plane-integration) command. See [Set up Openflow - Snowflake Deployment](/user-guide/data-integration/openflow/setup-openflow-spcs-deployment) or [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) for more information on configuring event tables.
Time frame
Use this filter to identify relevant connectors in a specific time frame. To get the most up-to-date results about the connector health, select the **Last Hour** time period.
**Status**
Enables filtering for **Healthy**, **Unhealthy**, or **All** connectors.
**Source**
Enables filtering by the source system based on known deployed connectors. The filter only shows sources that are used by your connectors.
**Deployment**
Enables filtering by Snowflake Openflow deployments. This filter displays data plane integration names, which are composed of the prefix `OPENFLOW_DATAPLANE_` followed by the deployment ID. To find the deployment ID, navigate to Openflow, select the **Deployments** tab, then select **View Details**.
**Runtime**
Enables filtering by Snowflake Openflow runtimes. This filter displays the runtime keys. To match runtime keys with Openflow runtime names in the UI, navigate to Openflow, select the **Runtimes** tab, then select **View Details**, and find the corresponding key.
**Type**
Enables filtering by connector type: Databases, SaaS, Streaming, Unstructured, Other.
- Primary filters (event table and time frame) are applied before secondary filters (status, source, deployment, runtime, or type). - The secondary filters (status, source, deployment, runtime, type) don't apply to the throughput and data ingested visuals. ## Monitoring Openflow connectors To monitor the connector details, select %vertical-more-icon% %raa% **View Details**. ### Database connectors The details page shows the following information for each table that is part of the Database connector configuration:
**Table replication status**
Tables can either be in **Active** or **Failed** replication status. The replication status is based on the most recent telemetry event that is available for the table. Events that cause replication to fail for a table immediately result in a **Failed** replication status in the dashboard. Use the **Failure Reason** message to identify the issue.
**Error distribution**
Helps you understand when the connector experienced issues, so that you can identify any potential problems with source systems, connector configuration, or the Snowflake destination.
**Table name**
Shows the schema and table names for all tables that are configured to be replicated by the connector. The list matches the **Included Table Names** or **Included Table Regex** configuration parameters of the connector.
**Replication status**
Shows whether each table is in **Active** or **Failed** replication status.
**Replication phase**
Shows the current table replication phase. After configuration in the connector, tables enter the **New** replication phase, progress to the **Snapshot Load** phase, perform the initial load, and ultimately enter the **Incremental Replication** phase when individual change data capture events are processed.
**Last Ingested**
Shows the timestamp of the last inserted record into the destination table during the selected time frame. When looking at this metric, consider a short delay between the records being ingested and events being logged and available to query. The connector updates this timestamp after each merge query and continues to emit the last known value every minute, even when no new data is being ingested. If no merge query has occurred for more than 3 days, the connector stops emitting the metric entirely and the dashboard shows **More than 3 days ago** instead of a timestamp. If the last ingestion timestamp falls outside the selected time frame, switch to a longer window such as **Last 24 hours** or **Last 7 days** to retrieve it.
You can use the **Replication status**, **Replication phase**, and time frame filters to narrow down the table list. ### All connectors
**Connector status**
Shows the connector health status: **Healthy** if no error messages were encountered during the selected time frame, or **Unhealthy** if any error messages were encountered.
**Error distribution**
Shows a count of how many errors this connector encountered during the selected time period.
**Average throughput**
Measures the rate at which data is read from source systems and ingested into Snowflake for the selected connector. - The **Average throughput** %raa% **Ingested** metric measures how fast the selected connector ingests data into Snowflake. - The **Average throughput** %raa% **Read** metric measures how fast the selected connector reads data from source systems.
**Total data ingested**
Shows how much data the selected connector has ingested into Snowflake during the selected time period. Use this metric to quickly identify ingestion anomalies over a specific time period.
### Custom flows Custom flows built on the Openflow canvas can also be monitored on the dashboard, but only if they are represented as process groups on the root canvas and are actively version-controlled in a customer Git repository using the Openflow Git integration. Custom flows that don't meet these criteria don't appear in the dashboard. For more information, see [Version control for custom flows](/user-guide/data-integration/openflow/version-control-custom-flows). ## Debugging Openflow connectors The Openflow Connectors Dashboard serves as an entry point for debugging connector-specific issues and makes all connector logs easily accessible to users. ### Troubleshoot connectors with AI Use AI-assisted troubleshooting to get root cause analysis and remediation steps for unhealthy connectors directly from the dashboard, without writing a prompt or switching tools. The AI assistant combines event table logs, connector metrics, and built-in runbooks to identify the issue and recommend next steps. It can also surface source system or Snowflake destination configuration problems that contribute to the failure. You can start AI-assisted troubleshooting at two scopes:
**Troubleshoot a whole connector**
Use this option to investigate everything affecting a connector. The AI assistant looks at all errors and metrics for the connector during the selected time frame and reports back with the most impactful issues and how to address them. To troubleshoot a whole connector, do one of the following: - In the connectors list, select the troubleshoot icon next to the status on the row of an **Unhealthy** connector. In the list, the control is an icon only, without a text label. - On the connector details page, select the **Troubleshoot** button in the page header.
**Troubleshoot a specific issue**
Use this option to focus on a single error. The AI assistant scopes its analysis to that error and returns targeted root cause analysis and remediation steps. To troubleshoot a specific issue, navigate to the connector details page, select the **Issues** tab, locate the error you want to investigate, and select the **Troubleshoot** button on that error.
The troubleshoot control, shown as an icon in the connectors list and as a **Troubleshoot** button elsewhere, only appears for connectors or issues in an **Unhealthy** state. ### Viewing the connector errors To view all errors that a connector encountered in the selected time frame, first navigate to the connector details page by selecting %vertical-more-icon% %raa% **View Details**, and then select the **Issues** tab. The error headline tells you what type of error the connector encountered, and the content provides the entire stacktrace of the error. ### Viewing the connector logs You might also want to look at additional connector logs to understand the context around an error message. To view all logs for the selected connector, select %vertical-more-icon% %raa% **View logs**. After you open the log explorer, you can also change the filters to view logs for different connectors or for entire runtimes or deployments. The log explorer supports Openflow-specific filters like the dataplane ID, the runtime key, and the process group ID. ### Accessing the Openflow canvas When you identify a connector issue, you probably need to navigate to the Openflow canvas to fix it; for example, adjust some configuration parameters or upgrade to a newer connector version. To navigate to the selected connector in the Openflow canvas, select %vertical-more-icon% %raa% **Go to canvas**. ## Optimizing performance ### Select a larger warehouse Use the warehouse selector in the top right section of the screen to choose a different warehouse to run the queries. While larger warehouses run queries faster, they take longer to resume, which might increase the initial page load time. ### Set up clustering on the Openflow event table By using clustering keys, you can avoid unnecessary scanning of micro-partitions during querying, significantly accelerating the performance of queries that reference these columns. For more information, see [](#label-data-clustering). Run the following query, replacing the placeholders with your Openflow event table: ```sqlsyntax ALTER TABLE .. CLUSTER BY ( DATE_TRUNC('HOUR', timestamp), RECORD_TYPE, CAST(record_attributes:"metricNameHash" AS STRING) ); ``` - Automatic clustering consumes Snowflake credits using serverless compute resources. To learn how many credits per compute-hour are consumed, refer to the "Serverless Feature Credit Table" in the [Snowflake Service Consumption Table](https://www.snowflake.cn/legal-files/CreditConsumptionTable.pdf). - After you enable clustering on your event table, a background process starts that takes some time to complete. After the process is complete, you should see improved performance when using the dashboard. ### Reduce the queried time frame Selecting a smaller time frame in the filter scans less data and leads to faster query performance. Use the **Last Hour** filter for the best performance and the most up-to-date view of your connector health and performance. ## Limitations - The Openflow Connectors Dashboard uses data stored in event tables to provide insight into Openflow connectors. Depending on the selected time period and event table, information provided on the dashboard might not reflect the current status of a connector. - Detailed health monitoring is currently only available for Database connectors. - The connector details page for Database connectors displays up to 75,000 tables. - The **Deployment** and **Runtime** filters use internal names that differ from the display names in the Openflow UI. For details on matching these names, see [Filtering connectors](#label-openflow-dashboard-filtering). - The **Last Ingested** column for Database connector tables shows **More than 3 days ago** when the connector hasn't performed a merge query in more than 3 days, because the connector stops emitting the last-ingestion metric after that period. If the last ingestion timestamp falls outside the selected time frame, switch to a longer window such as **Last 24 hours** or **Last 7 days** to retrieve it. ## Known issues - After upgrading the deployment, runtime, and connector to the versions mentioned in the prerequisites, the error count metric is only accurate for errors encountered after the upgrade. --- title: Monitor Openflow source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/monitor-overview.md section: Loading & Unloading Data --- # Monitor Openflow This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions). - [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) - [Set up Openflow - Snowflake Deployment - Task overview](/user-guide/data-integration/openflow/setup-openflow-spcs) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) Openflow provides two approaches for monitoring your data integration pipelines:
[Monitor connectors using the Openflow Connectors Dashboard](/user-guide/data-integration/openflow/connectors-dashboard)
Use the Openflow Connectors Dashboard in Snowsight to get a high-level view of connector health, throughput, and data ingestion. The dashboard provides filtering, error distribution, and per-connector detail pages.
[Monitor Openflow using telemetry data](/user-guide/data-integration/openflow/monitor)
Query the Openflow telemetry data stored in your event table to monitor logs, application metrics, JVM and system metrics, and build custom queries tailored to your environment.
--- title: Monitor Openflow using telemetry data source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/monitor.md section: Loading & Unloading Data --- # Monitor Openflow using telemetry data This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions). - [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) - [Set up Openflow - Snowflake Deployment - Task overview](/user-guide/data-integration/openflow/setup-openflow-spcs) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index) This topic describes how to monitor the state of Openflow and troubleshoot problems. ## Accessing Openflow logs Snowflake sends Openflow logs to the event table you configured when you set up Openflow ([BYOC](#label-openflow-event-table) | [Snowflake deployment](#label-openflow-spcs-event-table)). Snowflake recommends that you include a timestamp in the WHERE clause of event table queries. This is particularly important because of the potential volume of data generated by various Snowflake components. By applying filters, you can retrieve a smaller subset of data, which improves query performance. To get started quickly with Openflow's telemetry, see [Example Queries](#label-openflow-example-queries) below. ## Openflow Telemetry Schema For information about the event table columns, see [Event table columns](/developer-guide/logging-tracing/event-table-columns). The following sections describe how Openflow structures telemetry in an Event Table. ### Resource Attributes Describes the event metadata set by Openflow. For general information on other types of resource attributes see [](#label-event-table-resource-attributes-column) in the Event Table columns documentation.
Resource Attributes Example:
```json { "application": "openflow", "cloud.service.provider": "aws", "container.id": "a1b2c3d4e5f6", "container.image.name": "example-openflow-prod.registry-internal.snowflakecomputing.cn/openflow/openflow/openflow_repo/runtime-server", "container.image.tag": "2026.3.17.13", "deployment.version": "1.35.0", "k8s.container.name": "pg-dev-server", "k8s.container.restart_count": "0", "k8s.namespace.name": "runtime-pg-dev", "k8s.node.name": "ip-10-10-62-36.us-east-2.compute.internal", "k8s.pod.name": "pg-dev-0", "k8s.pod.start_time": "2025-04-25T22:14:29Z", "k8s.pod.uid": "94610175-1685-4c8f-b0a1-42898d1058e6", "openflow.dataplane.id": "abeddb4f-95ae-45aa-95b1-b4752f30c64a" } ```
### Scope
Scope Example:
```json { "name": "runtime" } ```
### Record Type Depending on the type of Openflow telemetry represented by this row, this will be one of: - LOG - METRIC Openflow does not collect TRACE records, but that is also a valid type for this column in Snowflake Event Tables. ### Record Optional. This JSON object describes the type of metric represented by this row.
Record Example:
```json { "metric": { "name": "connection.queued.duration.max", "unit": "millisecond" }, "metric_type": "gauge", "value_type": "INT" } ```
### Record Attributes #### Logs Record attributes for Logs will typically indicate where this log was sourced. For example, logs from an Openflow Runtime named *testruntime* could have Record Attributes of:
```json { "log.file.path": "/var/log/pods/runtime-testruntime_testruntime-0_66d80cdb-9484-40a4-bdba-f92eb0af14c7/testruntime-server/0.log", "log.iostream": "stdout", "logtag": "F" } ```
#### System Metrics System metrics like CPU usage will typically not set Record Attributes, so this will be *null*. #### Openflow Application Metrics Record Attributes for Application or "Flow" metrics provide details about the component in the data pipeline that produced the metric. This will vary based on the type of component. See [Application Metrics](#label-openflow-application-metrics)
```json { "component": "PutSnowpipeStreaming", "execution.node": "ALL", "group.id": "c052f9d7-7f76-3013-a2c5-d3b064fa7326", "id": "c69e2913-22a9-36bb-a159-6a5ed1fb9d63", "name": "PutSnowpipeStreaming", "type": "processor" } ```
### Value This column contains the raw value of the telemetry. For metrics, this will be a numeric value (integer or double). For logs, this will either be a semi-structured string value or a well-formatted JSON string. #### Openflow Runtime Logs Openflow Runtimes emit most logs as JSON, so applying Snowflake's [TRY_PARSE_JSON](/sql-reference/functions/try_parse_json) to the *VALUE* column allows you to further break this value into the following structured fields:
## Application Metrics The following list covers all application metrics available for Openflow Runtimes. Runtimes only emit a subset of metrics relevant to Openflow Connectors to persist in a Snowflake Event Table. Snowflake's OpenTelemetry Reporting Task can send some or all metrics to any OTLP destination. ### Connection Metrics
### Connection Record Attributes Each Connection metric includes the following Record Attributes:
### Input and Output Port Metrics Input Port and Output Ports are technically two separate types of components. For consistency, metrics and attributes for Input and Output Ports are the same, with the exception of the *type* attribute that indicates whether it is an input port or an output port.
### Input and Output Port Record Attributes Each Port metric includes the following Record Attributes:
### Process Group Metrics
### Process Group Record Attributes Each Process Group metric includes the following Record Attributes:
### Processor Metrics
### Processor Record Attributes Each Processor metric includes the following Record Attributes:
### Additional Attributes for Counters​ In addition to the standard Processor attributes above, *processor.counter* metrics include the following:
### Remote Process Group Metrics
### Remote Process Group Record Attributes Each Remote Process Group metric includes the following Record Attributes:
### JVM Metrics
### JVM Record Attributes JVM metrics do not provide Record Attributes. ### CPU Metrics
### CPU Record Attributes
### Storage Metrics
### Storage Record Attributes
## Example Queries The following queries are examples to get you started with Openflow Telemetry. All queries assume that Openflow is configured to send telemetry to the default Event Table of *SNOWFLAKE.TELEMETRY.EVENTS*. If your Snowflake Account or Openflow Deployment is configured with a different Event Table, substitute that table name where you see *SNOWFLAKE.TELEMETRY.EVENTS*. ### Find Stuck FlowFiles This query returns connections with FlowFiles that have been queued for more than some threshold, indicating that they may be stuck and require intervention. Adjust the 30 minute threshold as needed for your use case. ```sql SELECT * FROM ( SELECT resource_attributes:"openflow.dataplane.id" as Deployment_ID, resource_attributes:"k8s.namespace.name" as Runtime_Key, record_attributes:name as Connection_Name, record_attributes:id as Connection_ID, MAX(TO_NUMBER(value / 60 / 1000)) as Max_Queued_File_Minutes FROM snowflake.telemetry.events WHERE true AND record_type = 'METRIC' AND record:metric:name = 'connection.queued.duration.max' AND timestamp > dateadd(minutes, -30, sysdate()) GROUP BY 1, 2, 3, 4 ORDER BY Max_Queued_File_Minutes DESC ) WHERE Max_Queued_File_Minutes > 30; ``` ### Find Error Logs for Openflow Runtimes ```sql SELECT timestamp, Deployment_ID, Runtime_Key, parsed_log:level as log_level, parsed_log:loggerName as logger, parsed_log:formattedMessage as message, parsed_log FROM ( SELECT timestamp, resource_attributes:"openflow.dataplane.id" as Deployment_ID, resource_attributes:"k8s.namespace.name" as Runtime_Key, TRY_PARSE_JSON(value) as parsed_log FROM snowflake.telemetry.events WHERE true AND timestamp > dateadd('minutes', -30, sysdate()) AND record_type = 'LOG' AND resource_attributes:"k8s.namespace.name" like 'runtime-%' ORDER BY timestamp DESC ) WHERE log_level = 'ERROR'; ``` ### Find Running and Non-Running Processors Some flows expect that all processors are in a "running" state, even if they are not actively processing data. This query helps you find any processors that are running or in another state, such as: - stopped - invalid - disabled ```sql SELECT timestamp, resource_attributes:"openflow.dataplane.id" as Deployment_ID, resource_attributes:"k8s.namespace.name" as Runtime_Key, record_attributes:component as Processor, record_attributes:id as Processor_ID, TO_NUMBER(value) as Running FROM snowflake.telemetry.events WHERE true AND record:metric:name = 'processor.run.status.running' AND record_type = 'METRIC' AND timestamp > dateadd(minutes, -30, sysdate()); ``` ### Find High CPU Usage for Openflow Runtimes Slow data flows or reduced throughput may be the result of a bottleneck on the CPU. Openflow Runtimes scale up automatically, based on the number of minimum and maximum nodes you have configured. If an Openflow Runtime is using its maximum number of nodes and still CPU usage remains high, consider: 1. Increasing the maximum number of nodes allocated to the Runtime 2. Troubleshoot the Connector or flow to identify the bottleneck Snowsight Charts provide an easy way to visualize query results for CPU usage over time. ```sql SELECT timestamp, resource_attributes:"openflow.dataplane.id" as Deployment_ID, resource_attributes:"k8s.namespace.name" as Runtime_Key, resource_attributes:"k8s.pod.name" as Runtime_Pod, TO_NUMBER(value, 10, 3) * 100 as CPU_Usage_Percentage FROM snowflake.telemetry.events WHERE true AND timestamp > dateadd(minute, -30, sysdate()) AND record_type = 'METRIC' AND record:metric:name ilike 'container.cpu.usage' AND resource_attributes:"k8s.namespace.name" ilike 'runtime-%' AND resource_attributes:"k8s.container.name" ilike '%-server' ORDER BY timestamp desc, CPU_Usage_Percentage desc; ``` --- title: Monitor the Openflow Connector for Salesforce Bulk API source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/monitor.md section: Loading & Unloading Data --- # Monitor the %salesforcebulkapiof% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About the Openflow Connector for Salesforce Bulk API](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/about) - [Openflow Connector for Salesforce Bulk API: Configure the connector](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/configure-connector) - [Troubleshooting the Openflow Connector for Salesforce Bulk API](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/troubleshoot) - [Monitor Openflow using telemetry data](/user-guide/data-integration/openflow/monitor) The connector writes information about completed Salesforce Bulk API jobs to logs in the event table. You can query these logs to track the objects and number of records replicated to Snowflake. The examples on this page query `OPENFLOW.TELEMETRY.EVENTS`. If your Openflow deployment sends telemetry to a different event table, replace the table name in the examples. Adjust the 30-minute time range as needed. ## Query replication activity By default, the connector logs the Salesforce object type, number of records processed, bulk job ID, and system modification timestamp. Use the following query when **Enable Merge Metrics** is set to `false`: ```sql WITH connector_logs AS ( SELECT timestamp, resource_attributes:"openflow.dataplane.id"::VARCHAR AS deployment_id, resource_attributes:"k8s.namespace.name"::VARCHAR AS runtime_key, TRY_PARSE_JSON(value) AS parsed_log FROM OPENFLOW.TELEMETRY.EVENTS WHERE timestamp >= DATEADD('minutes', -30, CURRENT_TIMESTAMP()) AND record_type = 'LOG' AND resource_attributes:"k8s.namespace.name"::VARCHAR LIKE 'runtime-%' ), salesforce_logs AS ( SELECT timestamp, deployment_id, runtime_key, parsed_log:formattedMessage::VARCHAR AS message FROM connector_logs WHERE parsed_log:loggerName::VARCHAR = 'org.apache.nifi.processors.standard.LogMessage' AND CONTAINS(parsed_log:formattedMessage::VARCHAR, 'SALESFORCE_BULK_API - ') ) SELECT timestamp, deployment_id, runtime_key, TRIM(REGEXP_SUBSTR(message, 'ObjectType = ([^;]+)', 1, 1, 'e', 1)) AS object_type, TRY_TO_NUMBER(TRIM(REGEXP_SUBSTR(message, 'Records = ([^;]+)', 1, 1, 'e', 1))) AS records, TRIM(REGEXP_SUBSTR(message, 'BulkJobID = ([^;]*)', 1, 1, 'e', 1)) AS bulk_job_id, TRIM(REGEXP_SUBSTR(message, 'SystemModstamp = ([^;]+)', 1, 1, 'e', 1)) AS system_modstamp FROM salesforce_logs ORDER BY timestamp DESC; ``` ## Query merge metrics Set **Enable Merge Metrics** to `true` to include detailed record counts in the logs. The connector runs an additional query before each incremental merge to calculate the counts. This query uses the warehouse configured in **Snowflake Warehouse**. Merge metrics are available only for Salesforce objects that include the `IsDeleted` field. Use the following query to retrieve the replication activity and merge metrics: ```sql WITH connector_logs AS ( SELECT timestamp, resource_attributes:"openflow.dataplane.id"::VARCHAR AS deployment_id, resource_attributes:"k8s.namespace.name"::VARCHAR AS runtime_key, TRY_PARSE_JSON(value) AS parsed_log FROM OPENFLOW.TELEMETRY.EVENTS WHERE timestamp >= DATEADD('minutes', -30, CURRENT_TIMESTAMP()) AND record_type = 'LOG' AND resource_attributes:"k8s.namespace.name"::VARCHAR LIKE 'runtime-%' ), salesforce_logs AS ( SELECT timestamp, deployment_id, runtime_key, parsed_log:formattedMessage::VARCHAR AS message FROM connector_logs WHERE parsed_log:loggerName::VARCHAR = 'org.apache.nifi.processors.standard.LogMessage' AND CONTAINS(parsed_log:formattedMessage::VARCHAR, 'SALESFORCE_BULK_API - ') ) SELECT timestamp, deployment_id, runtime_key, TRIM(REGEXP_SUBSTR(message, 'ObjectType = ([^;]+)', 1, 1, 'e', 1)) AS object_type, TRY_TO_NUMBER(TRIM(REGEXP_SUBSTR(message, 'Records = ([^;]+)', 1, 1, 'e', 1))) AS records, TRIM(REGEXP_SUBSTR(message, 'BulkJobID = ([^;]*)', 1, 1, 'e', 1)) AS bulk_job_id, TRIM(REGEXP_SUBSTR(message, 'SystemModstamp = ([^;]+)', 1, 1, 'e', 1)) AS system_modstamp, TRY_TO_NUMBER(TRIM(REGEXP_SUBSTR(message, 'ROWS_ADDED = ([^;]+)', 1, 1, 'e', 1))) AS rows_added, TRY_TO_NUMBER(TRIM(REGEXP_SUBSTR(message, 'ROWS_ADDED_DELETED = ([^;]+)', 1, 1, 'e', 1))) AS rows_added_deleted, TRY_TO_NUMBER(TRIM(REGEXP_SUBSTR(message, 'ROWS_UPDATED = ([^;]+)', 1, 1, 'e', 1))) AS rows_updated, TRY_TO_NUMBER(TRIM(REGEXP_SUBSTR(message, 'ROWS_DELETED = ([^;]+)', 1, 1, 'e', 1))) AS rows_deleted, TRY_TO_NUMBER(TRIM(REGEXP_SUBSTR(message, 'ROWS_RESTORED = ([^;]+)', 1, 1, 'e', 1))) AS rows_restored FROM salesforce_logs ORDER BY timestamp DESC; ``` The metrics have the following meanings:
`ROWS_UPDATED` counts active source records that match active destination records. It doesn't compare individual field values and doesn't indicate whether a field value changed. The merge metric columns in the query return `NULL` when the log doesn't contain merge metrics. This occurs when **Enable Merge Metrics** is set to `false`, the Salesforce object doesn't include the `IsDeleted` field, or the log was generated by an earlier connector version that didn't support merge metrics. --- title: MonitorActivity 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/monitoractivity.md section: Loading & Unloading Data --- # MonitorActivity 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Monitors the flow for activity and sends out an indicator when the flow has not had any data for some specified amount of time and again when the flow's activity is restored ## Tags active, activity, detection, flow, inactive, monitor ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
--- title: MoveAzureDataLakeStorage 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/moveazuredatalakestorage.md section: Loading & Unloading Data --- # MoveAzureDataLakeStorage 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-azure-nar ## Description Moves content within an Azure Data Lake Storage Gen 2. After the move, files will be no longer available on source location. ## Tags adlsgen2, azure, cloud, datalake, microsoft, storage ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.azure.storage.DeleteAzureDataLakeStorage](/user-guide/data-integration/openflow/processors/deleteazuredatalakestorage) - [org.apache.nifi.processors.azure.storage.FetchAzureDataLakeStorage](/user-guide/data-integration/openflow/processors/fetchazuredatalakestorage) - [org.apache.nifi.processors.azure.storage.ListAzureDataLakeStorage](/user-guide/data-integration/openflow/processors/listazuredatalakestorage) --- title: Notify 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/notify.md section: Loading & Unloading Data --- # Notify 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Caches a release signal identifier in the distributed cache, optionally along with the FlowFile's attributes. Any flow files held at a corresponding Wait processor will be released once this signal in the cache is discovered. ## Tags cache, distributed, map, notify, release, signal ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.standard.Wait](/user-guide/data-integration/openflow/processors/wait) --- title: Object definition overrides for the Openflow Connector for Shopify source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/shopify/object-definitions.md section: Loading & Unloading Data --- # Object definition overrides for the %shopifyof% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About the Openflow Connector for Shopify](/user-guide/data-integration/openflow/connectors/shopify/about) - [Set up the Openflow Connector for Shopify](/user-guide/data-integration/openflow/connectors/shopify/setup) - [Maintain the Openflow Connector for Shopify](/user-guide/data-integration/openflow/connectors/shopify/maintain) - [Troubleshoot the Openflow Connector for Shopify](/user-guide/data-integration/openflow/connectors/shopify/troubleshoot) This topic describes the **Object Definitions Override** parameter in detail, including the full schema, promoted column and child field definitions, and a complete example. The **Object Definitions Override** parameter accepts a JSON array of object definitions. Each definition can add a new object type or fully replace an existing catalog entry. ## Object definition schema The **Object Definitions Override** value must be valid JSON. If the JSON is malformed, the connector fails to start. Validate your JSON before applying the override. The following fields are supported in each object definition:
## Promoted columns Promoted columns extract specific values from the raw JSON payload into dedicated typed columns in the destination table. This makes frequently queried fields available as first-class Snowflake columns for efficient filtering and aggregation. Each promoted column has the following fields:
## Child fields Child field definitions extract nested connections (such as order line items) into separate Snowflake tables. Each child table includes a `__PARENT_ID` column linking records back to the parent. Each child field has the following fields:
Shopify rejects `pageSize` values above 250 with a `first cannot exceed 250` error. This limit doesn't apply to bulk loads: the Shopify Bulk Operations API ignores the `first:` argument and returns all child records. For more information, see [Limitations](/user-guide/data-integration/openflow/connectors/shopify/about#label-shopify-connector-limitations). ## Union types and GID routing When a query root returns a union type, the records in the Shopify Bulk API response carry GID types that correspond to the **concrete wrapper node types**, not the query root name or the GraphQL union type name. The connector's `PartitionShopifyByObject` processor routes records by GID type, so if the GID type isn't registered in `gidTypeName` or `additionalGidTypeNames`, records are routed to failure. For example, the `discountNodes` query root returns the `Discount` union. The records in the response carry GID types `DiscountCodeNode` and `DiscountAutomaticNode`, not `DiscountNode` or `Discount`. To route all records to the same table, set `gidTypeName` to one concrete type and list the others in `additionalGidTypeNames`. The following example configures `discountNodes` correctly: ```json [ { "apiType": "discountNodes", "tableName": "DISCOUNTS", "gidTypeName": "DiscountCodeNode", "additionalGidTypeNames": ["DiscountAutomaticNode"], "graphqlFields": [ "id", "discount { ... on DiscountCodeBasic { title status startsAt endsAt createdAt updatedAt } ... on DiscountAutomaticBasic { title status startsAt endsAt createdAt updatedAt } }" ] } ] ``` When using `promotedColumns` on a union-type object, the JSON root after partitioning is the wrapper node (for example, `{ id, discount: { … } }`), not the inner union member. Promoted column `path` values must include the wrapper field, for example `$.discount.title`, not `$.title`. For discount syncing with incremental support, use `discountNodes` rather than `codeDiscountNodes` or `automaticDiscountNodes`. The per-subtype query roots don't accept `updated_at` as a filter, so they require `supportsIncremental: false` and `refreshStrategy: "FULL_PERIODIC"`. To verify which GID types appear in a real response before writing the definition, run a small test bulk load or check the Shopify documentation for the concrete types returned by the query root. ## Example: Register a custom object type with promoted columns The following override customizes an existing catalog entry to add scalar fields, nested object selections, a metafield alias, and promoted columns. One promoted column extracts a value directly from the aliased metafield. ```json [ { "apiType": "draftOrders", "tableName": "DRAFT_ORDERS", "gidTypeName": "DraftOrder", "supportsBulk": true, "supportsIncremental": true, "incrementalField": "updatedAt", "ignoredFields": [], "sortKeys": ["UPDATED_AT", "ID"], "supportsDeletes": false, "graphqlFields": [ "id", "createdAt", "updatedAt", "name", "status", "email", "currencyCode", "totalQuantityOfLineItems", "customer { id }", "totalPriceSet { shopMoney { amount currencyCode } }", "billingAddress { address1 city countryCode zip }", "draft_po_number: metafield(key: \"custom.draft_po_number\") { key namespace compareDigest createdAt id jsonValue legacyResourceId updatedAt value definition { id description key pinnedPosition } }" ], "promotedColumns": [ { "name": "STATUS", "path": "$.status", "type": "string" }, { "name": "NAME", "path": "$.name", "type": "string" }, { "name": "CUSTOMER_ID", "path": "$.customer.id", "type": "gid" }, { "name": "TOTAL_PRICE_AMOUNT", "path": "$.totalPriceSet.shopMoney.amount", "type": "money" }, { "name": "DRAFT_PO_NUMBER", "path": "$.draft_po_number.value", "type": "string" } ], "childFields": [] } ] ``` ## Example: Override an object with child fields The following override customizes the `orders` object to extract line items and fulfillments into separate tables. Line items use a paginated connection (`edges`); fulfillments are an inline array in the parent response (`array`). ```json [ { "apiType": "orders", "tableName": "ORDERS", "gidTypeName": "Order", "graphqlFields": [ "id", "createdAt", "updatedAt", "name", "email", "lineItems(first: 250) { edges { cursor node { id title quantity originalUnitPriceSet { shopMoney { amount currencyCode } } } } }", "fulfillments { id status createdAt }" ], "childFields": [ { "fieldName": "lineItems", "tableName": "ORDER_LINE_ITEMS", "gidTypeName": "LineItem", "connectionType": "edges" }, { "fieldName": "fulfillments", "tableName": "ORDER_FULFILLMENTS", "gidTypeName": "Fulfillment", "connectionType": "array" } ] } ] ``` --- title: OpenAiTranscribeAudio 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/openaitranscribeaudio.md section: Loading & Unloading Data --- # OpenAiTranscribeAudio 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-openai-nar ## Description Transcribes audio into English text. The audio data must be in one of these formats: flac, mp3, mp4, mpeg, mpga, m4a, ogg, wav, webm ## Tags audio, flac, m4a, mp3, mp4, mpeg, mpga, ogg, openai, openflow, speech-to-text, text, transcribe, translate, wav, webm ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Use Cases Involving Other Components | Create embeddings for audio data and insert them into Pinecone so that the audio can be made available to a large language model (LLM) such as OpenAI's GPT models. | | ------------------------------------------------------------------------------------------------------------------------------------------------------------------- | --- title: Openflow BYOC - Set up custom ingress source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/setup-openflow-byoc-custom-ingress.md section: Loading & Unloading Data --- # Openflow BYOC - Set up custom ingress This feature is not available in the People's Republic of China. Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions). - [About Openflow: BYOC deployments](/user-guide/data-integration/openflow/about-byoc) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Monitor Openflow using telemetry data](/user-guide/data-integration/openflow/monitor) - [Troubleshoot Openflow](/user-guide/data-integration/openflow/troubleshoot) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) This topic describes the considerations for and steps required to set up an Openflow BYOC deployment with a custom ingress solution managed within your own AWS account. ## Benefits Custom ingress for Openflow BYOC deployments provides your organization with: - Stronger security with network-level restrictions that can limit access to only your VPN or private network. - Full control over the URL and TLS certificate used to access Openflow to meet your security and compliance requirements. ## Considerations With Snowflake managed ingress, Openflow creates the necessary DNS records, public load balancer, and manages the TLS certificate for the Openflow runtimes in your BYOC deployment. When you enable custom ingress, Openflow will no longer automatically manage external DNS records, will not create a public load balancer automatically, and will no longer manage certificates for the Openflow runtimes. You must manage these resources within your own AWS account. ![Openflow Managed Ingress compared with Custom Ingress, highlighting the additional requirements for DNS, load balancers, and certificates.](/static/images/connectivity/openflow-byoc-custom-ingress.svg) ## Configure custom ingress in Snowflake Openflow 1. Enable custom ingress during deployment creation. - During deployment creation, enable **Custom ingress** and specify your preferred fully qualified domain name (FQDN) in the **Hostname** field. - You must be able to manage this DNS record and create a TLS certificate for this FQDN. Do not use a subdomain of `snowflakecomputing.cn`. - You must not include the protocol **https://** or a trailing slash **/** in the FQDN. - For example, if you specify `openflow01.your-domain.org`, you will access a runtime named "My Runtime" at `https://openflow01.your-domain.org/my-runtime/nifi/`. 2. Download the CloudFormation template. This file has all of the settings required for Openflow to run as your custom ingress domain. ## Configure custom ingress in AWS `{deployment-key}` represents the Openflow unique identifier applied to cloud resources created and managed by Openflow for a particular deployment. This is in the `DataPlaneKey` parameter of the CloudFormation template, also available in Openflow through the **View Details** menu option for the deployment. 1. Add the following tag to the private subnets for your Openflow deployment: - Key: **kubernetes.io/role/internal-elb** - Value: `1` 2. If your private subnets are used by other EKS clusters, you must also tag them with the name of the Openflow cluster. This allows Openflow to create a load balancer alongside other load balancers. - Key: **kubernetes.io/cluster/\{deployment-key\}** - Value: `1` 3. Upload the CloudFormation template. Wait approximately 30 minutes for Openflow to create the internal network load balancer. - You can find the internal network load balancer in the AWS Console under **EC2** %ra% **Load Balancers**. - The load balancer will be named `runtime-ingress-{deployment-key}`. 4. Obtain the internal IP address of the Openflow-managed AWS internal network load balancer. - Under **EC2** %ra% **Load Balancers**, navigate to the details page and copy the **DNS name** of the Load Balancer. - Log into your agent EC2 instance (identified as **openflow-agent-\{deployment-key\}**) and run the command `nslookup {openflow-load-balancer-dns-name}`. - Copy the IP addresses of the Openflow-managed AWS internal network load balancer. These are destinations for the target group of the load balancer you will create in a following step. 5. Provision a TLS certificate. - Obtain a TLS certificate for the load balancer that will handle traffic to the Openflow runtime UIs. You can generate a certificate using AWS Certificate Manager (ACM) or import an existing certificate. 6. Create a network load balancer that will route traffic to the Openflow-managed AWS internal network load balancer. 1. In your AWS account, create a Network Load Balancer with the following configuration: - Name: We recommend the naming convention `custom-ingress-external-{deployment-key}`, where `{deployment-key}` is the key of your Openflow deployment. - Type: **Network Load Balancer** - Scheme: **Internal** or **Internet-facing**, depending on your requirements. - VPC: Select the VPC of your deployment - Availability Zones: Select both Availability Zones where your Openflow deployment is running. - Subnets: Select the private subnets of your VPC for an **Internal** Load Balancer, or the public subnets of your VPC for an **Internet-facing** Load Balancer. - Security groups: Select or create a security group that allows traffic on port `443` - Default SSL/TLS server certificate: Import your SSL/TLS certificate - Target group: Create a new target group with the following settings: - Target type: **IP addresses** - Protocol: **TLS** - Port: **443** - VPC: Verify the VPC matches your deployment - Type the IP address of the internal network load balancer created by Openflow (obtained in the previous step) as the target and select **Include as pending below**. 2. Once the load balancer is created, copy the DNS name for the load balancer to use in the next step. 3. For more information on how to create a network load balancer, see Create a Network Load Balancer (https://docs.aws.amazon.com/elasticloadbalancing/latest/network/create-network-load-balancer.html). 7. Create a DNS CNAME record that maps your custom ingress FQDN to the AWS load balancer's DNS name. - For detailed DNS configuration instructions in Route 53, see Create records in Route 53 (https://docs.aws.amazon.com/Route53/latest/DeveloperGuide/resource-record-sets-creating.html). ## Verification 1. The Openflow deployment shows a status of **Active** in the **Deployments** page. 2. Create a runtime in the Openflow deployment. 3. Once the runtime is **Active**, click on the runtime name or use the **View canvas** menu option to access the runtime's UI. 4. Openflow directs you to the runtime with the hostname specified during deployment creation. For example, `https://openflow01.your-domain.org/my-runtime/nifi/`. ## Troubleshooting The following sections provide troubleshooting steps for common issues with custom ingress. If you are still experiencing issues after performing these checks, file a [Snowflake Support](https://docs.snowflake.cn/user-guide/contacting-support) case. ### Load balancer target health check The target group for your network load balancer should list the IP addresses of the Openflow-managed internal network load balancer as targets. All of these targets should show as **Healthy**. If targets are **Unhealthy**, use the following checks to narrow down where traffic is failing. 1. In the AWS console, open **EC2** %ra% **Load Balancers**. 2. Locate the Openflow-managed load balancer that manages ingress to the Kubernetes cluster. This load balancer is named `runtime-ingress-{deployment-key}`. 3. Review the target health for that load balancer under the **Resource map** tab. 4. If the Openflow-managed load balancer is not active or has **Unhealthy** targets: - Traffic may be blocked between the Openflow-managed load balancer and the BYOC cluster, or a service inside the cluster may not be ready. - Generate a diagnostic bundle by running `./diagnostics.sh` from the **openflow-agent-\{deployment-key\}** EC2 instance and attach it to a [Snowflake Support](https://docs.snowflake.cn/user-guide/contacting-support) case. 5. If the Openflow-managed load balancer is active and has healthy targets, check the target health for your load balancer. 6. If your load balancer's targets are **Unhealthy**, the path from your load balancer to the Openflow-managed load balancer is the most likely problem: - **Incorrect or stale IP addresses in your target group.** The Openflow-managed load balancer exposes multiple IP addresses that can change over time. To get the latest values, run `nslookup` with the **DNS name** of the Openflow-managed load balancer. Update your load balancer's targets as necessary. - **Security group rules.** Confirm that inbound rules on the Openflow-managed load balancer's security groups allow TCP `443` from your load balancer. Traffic can fail if your load balancer can't reach the Openflow load balancer on port `443`. ### Browser security blocking Some problems with custom ingress are caused by corporate browser security, firewalls, or web proxies that block or inspect traffic to your custom hostname. Those policies are separate from AWS load balancer configuration. You may find that users can't open the Openflow UI even when AWS load balancers report healthy targets. To verify connectivity through the load balancers to the Openflow services: 1. In the AWS console, open **EC2** %ra% **Load Balancers** to get the DNS name of the load balancer that is serving traffic and the TLS certificate for your custom ingress domain name. - This is **not** the **runtime-ingress-\{deployment-key\}** load balancer. 2. From the **openflow-agent-\{deployment-key\}** EC2 instance, verify connectivity through the load balancers to the Openflow deployment. Run the command: ```bash curl -kv https://{your-load-balancer-dns-name} ``` - If the command outputs the expected certificate information and a successful 404 status code response, you have successfully verified connectivity to your Openflow deployment. - If the command times out or returns an error, create a [Snowflake Support](https://docs.snowflake.cn/user-guide/contacting-support) case and attach a diagnostic bundle generated by running `./diagnostics.sh` from the Openflow Agent instance. 3. From the Openflow Agent instance, you can also verify the DNS CNAME record for your custom ingress FQDN. Run the command: ```bash source ~/.env && nslookup $DOMAIN ``` - If the command returns the IP addresses of the load balancer that is performing TLS termination for your custom ingress domain name, you have successfully verified the DNS CNAME record. - If the command returns no results, the DNS CNAME record is not configured correctly. Check the DNS record for your custom ingress FQDN and ensure it points to your load balancer's DNS name. If the Openflow Agent connected successfully through your load balancer's DNS and you have verified the DNS CNAME record, a security policy or firewall is likely blocking traffic from your browser to the Openflow BYOC deployment. Work with your security team to allowlist your custom ingress FQDN. --- title: Openflow BYOC - Set up encrypted EBS volumes source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/setup-openflow-byoc-encrypted-volumes.md section: Loading & Unloading Data --- # Openflow BYOC - Set up encrypted EBS volumes This feature is not available in the People's Republic of China. Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions). - [About Openflow: BYOC deployments](/user-guide/data-integration/openflow/about-byoc) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Monitor Openflow using telemetry data](/user-guide/data-integration/openflow/monitor) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) This topic describes the steps to set up an Openflow BYOC deployment with encrypted Elastic Block Storage (EBS) volumes using one of the following methods: - [](#label-openflow-byoc-encrypted-ebs-kms-key) - [](#label-openflow-byoc-encrypted-ebs-default-encryption) Both of these solutions provide encrypted EBS volumes that meet the following storage requirements of Openflow BYOC: - Root volume for the Openflow Agent EC2 instance - Root volumes for the EC2 instances in each EKS Cluster Node Group - Persistent volumes for Openflow's runtimes and supporting components - `$AWS_ACCOUNT_ID` represents the AWS Account ID of the account where Openflow is deployed. - `$AWS_REGION` represents the AWS Region of the account, for example `us-west-2`. - `$AWS_KMS_KEY_ARN` represents the Amazon Resource Name (ARN) of the Amazon Key Management Service (AWS KMS) key that Openflow will use for encrypted EBS volumes. - `$DEPLOYMENT_KEY` represents the Openflow unique identifier applied to cloud resources created and managed by Openflow for a particular deployment. This is in the `DataPlaneKey` parameter of the CloudFormation template, also available in Openflow through the **View Details** menu option for the deployment. ## Prerequisites This topic assumes that you have completed the prerequisites for setting up Openflow BYOC. For more information, see [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc). You must also have access to an AWS KMS key that Openflow will use for encrypted EBS volumes. ## Provide a specific AWS KMS Key for Encrypted EBS Volumes When uploading the CloudFormation template for your Openflow BYOC Deployment, you can provide the ARN for the AWS KMS key that Openflow uses for encrypted EBS volumes. Using this configuration, Openflow makes requests for encrypted EBS volumes, ensuring that all SCP policies are satisfied. Snowflake recommends this approach for most customers. This allows you to use different KMS keys for different applications, reducing the risk of a single key being compromised. To ensure that Openflow has the necessary permissions to use this key, perform the following tasks: 1. Ensure that the AWS KMS key grants permissions to the AWS Autoscaling Service Role. The Key Policy must include the following statement: ```json { "Sid": "Allow Autoscaling to use the key", "Effect": "Allow", "Principal": { "AWS": "arn:aws:iam::$AWS_ACCOUNT_ID:role/aws-service-role/autoscaling.amazonaws.com/AWSServiceRoleForAutoScaling" }, "Action": [ "kms:CreateGrant", "kms:Decrypt", "kms:Encrypt", "kms:ReEncrypt*", "kms:GenerateDataKey*", "kms:DescribeKey" ], "Resource": "*" } ``` 2. Enter the ARN of the AWS KMS key in the `EBSKMSKeyArn` parameter of the CloudFormation stack when uploading the template. For example, `arn:aws:kms:$AWS_REGION:$AWS_ACCOUNT_ID:key/1a1a11aa-aa1a-aaa1a-a1a1-000000000000`. Approximately 20 minutes after uploading the CloudFormation template, the Openflow BYOC Deployment creates a new IAM Role with the name `$DEPLOYMENT_KEY-eks-role`. 3. Add the following statement to the KMS key policy to grant permissions for Openflow to use the key: ```json { "Sid": "Allow Openflow Deployment to encrypt EBS volumes", "Effect": "Allow", "Principal": { "AWS": "arn:aws:iam::$AWS_ACCOUNT_ID:role/$DEPLOYMENT_KEY-eks-role" }, "Action": [ "kms:Decrypt", "kms:Encrypt", "kms:ReEncrypt*", "kms:GenerateDataKey*", "kms:CreateGrant", "kms:DescribeKey" ], "Resource": "*" } ``` Openflow automatically detects the new permissions for the KMS key and continues the installation process. The Openflow BYOC deployment will become `Active` after approximately 20 minutes. ## Enable Encrypted EBS Volumes by default for your AWS Account AWS accounts can encrypt new EBS volumes by default by following the AWS EBS encryption by default documentation (https://docs.aws.amazon.com/ebs/latest/userguide/encryption-by-default.html). With this configuration, Openflow makes requests for unencrypted EBS volumes, but the AWS API will return an encrypted EBS volume. The following steps ensure that Openflow has permissions to use the KMS key for these encrypted volumes. Whether you choose to use the AWS managed key `aws/ebs` or your own KMS key, you must attach an IAM Policy to the Openflow IAM Role `$DEPLOYMENT_KEY-eks-role` that grants the necessary permissions to use the key. 1. Create an IAM Policy to allow Openflow to use the KMS key by replacing `$AWS_KMS_KEY_ARN` with the ARN of the KMS key. ```json { "Sid": "Allow Openflow EKS Role to encrypt EBS volumes", "Effect": "Allow", "Action": [ "kms:Decrypt", "kms:Encrypt", "kms:ReEncrypt*", "kms:GenerateDataKey*", "kms:CreateGrant", "kms:DescribeKey" ], "Resource": "$AWS_KMS_KEY_ARN" } ``` 2. Ensure that the AWS KMS key grants permissions to the AWS Autoscaling Service Role. The Key Policy must include the following statement: ```json { "Sid": "Allow Autoscaling to use the key", "Effect": "Allow", "Principal": { "AWS": "arn:aws:iam::$AWS_ACCOUNT_ID:role/aws-service-role/autoscaling.amazonaws.com/AWSServiceRoleForAutoScaling" }, "Action": [ "kms:CreateGrant", "kms:Decrypt", "kms:Encrypt", "kms:ReEncrypt*", "kms:GenerateDataKey*", "kms:DescribeKey" ], "Resource": "*" } ``` 3. When uploading the Openflow BYOC CloudFormation template: - Leave the optional `EBSKMSKeyArn` parameter blank. - Set the `AdditionalEksRolePolicyArns` parameter to the ARN of the new IAM Policy created previously. For example, `arn:aws:iam::$AWS_ACCOUNT_ID:policy/openflow-kms-key-access-policy`. Approximately 20 minutes after uploading the CloudFormation template, the Openflow BYOC Deployment creates a new IAM Role with the name `$DEPLOYMENT_KEY-eks-role`. 4. Add the following statement to the KMS key policy to grant permissions for Openflow to use the key: ```json { "Sid": "Allow Openflow Deployment to encrypt EBS volumes", "Effect": "Allow", "Principal": { "AWS": "arn:aws:iam::$AWS_ACCOUNT_ID:role/$DEPLOYMENT_KEY-eks-role" }, "Action": [ "kms:Decrypt", "kms:Encrypt", "kms:ReEncrypt*", "kms:GenerateDataKey*", "kms:CreateGrant", "kms:DescribeKey" ], "Resource": "*" } ``` Openflow automatically detects the new permissions for the KMS key and continues the installation process. The Openflow BYOC deployment will become `Active` after approximately 20 minutes. --- title: Openflow BYOC cost and scaling considerations source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/cost-byoc.md section: Loading & Unloading Data --- # Openflow BYOC cost and scaling considerations This feature is not available in the People's Republic of China. Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions). - [About Openflow: BYOC deployments](/user-guide/data-integration/openflow/about-byoc) - [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Monitor Openflow using telemetry data](/user-guide/data-integration/openflow/monitor) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) Snowflake Openflow BYOC has cost considerations in multiple areas, including infrastructure, compute, data ingestion and others. Scaling Openflow involves understanding these costs. The following sections describe Openflow BYOC costs in general, and provide a number of examples of scaling Openflow BYOC runtimes and associated costs. ## Openflow BYOC costs When using Openflow, you can incur the following types of costs:
## Openflow BYOC scaling The runtimes and scaling behavior you choose are crucial for managing costs effectively. Openflow supports different runtime types, each with its own scaling characteristics. ### Runtime types and the associated costs The following table illustrates the scaling behavior of various runtimes and their associated costs: | Runtimes | Activity | Snowflake costs | Cloud costs | | ---------------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------- | -------------------------------- | | No runtimes | None | No cost | Compute and storage of Dataplane | | 1 small runtime (1 vCPU)
(min 1 max 2) | Active for 1 hour
Runtime does not scale to 2. | 1 runtime x 1 node x 1 vCPU x 1 hour = 1
Total = 1 vCPU-hour | Compute and storage of Dataplane | | 2 small runtimes (1 vCPU) (min/max=2)
1 large runtime (8 vCPU) (min/max=10) | Small: 2 nodes active for 1 hour
Large: 10 nodes active for 1 hour | 2 runtimes x 2 nodes x 1 vCPU x 1 hour = 4 vCPU
1 runtime x 10 nodes x 8 vCPU x 1 hour = 80 vCPU
Total = 84 vCPU-hours | Compute and storage of Dataplane | | 1 medium (4 vCPU)
(min =1 max=2) | First 20 minutes, 1 node is running
Scales to 2 nodes for the remaining 40 minutes of the hour
Total 1 hour
| 20 minutes = 1/3 hour
1 runtime x 1 node x 4 vCPU x 1/3 hour = 4/3
1 runtime x 2 nodes x 4 vCPU x 2/3 hour = 16/3
Total = 6 2/3 vCPU-hours | Compute and storage of Dataplane | | 1 medium (4 vCPU)
(min/max=2) | First 30 minutes, 2 nodes running
Suspends after first 30 minutes. | 30 minutes = 1/2 hour
1 runtime x 2 nodes x 4 vCPU x 1/2 hour = 4
Total = 4 vCPU-hours | Compute and storage of Dataplane | ### Mapping runtimes to EC2 instance types Choosing a runtime type (t-shirt size) results in the runtime pods being scheduled on the associated EC2 node group \{key\}-sm-group, \{key\}-md-group, or \{key\}-lg-group with resources described in the following table: | Runtime type | vCPUs | Available memory (GB) | EC2 instance type | EC2 node group | EC2 node - CPUs | EC2 node - memory (GB) | | ------------ | ----- | --------------------- | ----------------- | ---------------- | --------------- | ---------------------- | | Small | 1 | 2 | m7i.xlarge | \{key\}-sm-group | 4 | 16 | | Medium | 4 | 10 | m7i.4xlarge | \{key\}-md-group | 16 | 64 | | Large | 8 | 20 | m7i.8xlarge | \{key\}-lg-group | 32 | 128 | The type of runtime that you choose impacts the number of cores (vCPUs) consumed each second. Openflow scales the underlying EC2 node group when additional pods need to be scheduled, based on CPU consumption, and up to the maximum node setting set during runtime creation. EKS node groups are configured with a minimum size of 0 nodes and a maximum of 50 nodes. The desired size is dynamically adjusted depending on the runtime required CPU and memory. Customers are charged by their cloud service provider for the underlying nodes that host their runtime. The underlying EC2 instances are created when the first runtime of a respective size is scheduled. ### Examples for calculating Openflow BYOC runtime consumption
A user requests a BYOC deployment from Openflow and then installs the Openflow agent and deployment
- The user has not created any runtimes. 0 vCPUs are allocated, so there is no Openflow software cost. - The user is charged by their cloud service provider for the provisioned compute and storage of the Openflow BYOC deployment. - Total Openflow consumption = 0 vCPU-hours
A user creates one small runtime with Min Nodes = 1 and Max Nodes = 2. Runtime stays at 1 node for 1 hour.
- 1 small runtime = 1 vCPU - Total Openflow consumption = 1 vCPU-hour
A user creates 2 small runtimes with min/max of 2 nodes each, and one large runtime with min/max of 10 nodes. These runtimes are active for 1 hour
- 2 small runtimes at 2 nodes = 2 runtimes x 2 nodes x 1 vCPU = 4 vCPUs - 1 large runtime at 10 nodes = 1 runtime x 10 nodes x 8 vCPU = 80 vCPUs - Total Openflow consumption = (4 vCPU + 80 vCPU) x 1 hour = 84 vCPU-hours
A user creates 1 medium runtime with 1 node. After 20 minutes, it scales to 2 nodes and remains at 2 nodes for the rest of the hour.
- 1 medium runtime = 4 vCPUs - 20 minutes = 1/3 hour; 40 minutes = 2/3 hour - (1 node x 4 vCPU x 1/3 hour) + (2 nodes x 4 vCPU x 2/3 hour) - 4/3 vCPU-hours + 16/3 vCPU-hours - Total Openflow consumption = 20/3 vCPU-hours, so approximately 6.67 vCPU-hours
A user creates 1 medium runtime with 2 nodes, then suspends it after 30 minutes
- 1 medium runtime = 4 vCPU - 30 minutes = 1/2 hour - Total Openflow consumption = (2 nodes x 4 vCPU x 1/2 hour) = 4 vCPU-hours
--- title: Openflow Connector for Amazon Kinesis Data Streams source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/kinesis/about.md section: Loading & Unloading Data --- # %kinesis% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Set up Openflow Connector for Amazon Kinesis Data Streams](/user-guide/data-integration/openflow/connectors/kinesis/setup) - [Performance tuning of the Openflow Connector for Amazon Kinesis Data Streams](/user-guide/data-integration/openflow/connectors/kinesis/performance-tuning) - [Maintain Openflow Connector for Amazon Kinesis Data Streams](/user-guide/data-integration/openflow/connectors/kinesis/maintenance) - [Troubleshooting the Openflow Connector for Amazon Kinesis Data Streams](/user-guide/data-integration/openflow/connectors/kinesis/troubleshoot) - [Openflow Connector for Kinesis Data Streams: Configuring DLQ handling](/user-guide/data-integration/openflow/connectors/kinesis/configuring-dead-letter-queue-handling) ## About This topic describes the basic concepts of %kinesis%, including its workflow and limitations. You can use Amazon Kinesis Data Streams (https://docs.aws.amazon.com/streams/latest/dev/introduction.html) to collect and process large streams of data records in real time. Producers continually push data to Kinesis Data Streams, and consumers process the data in real time. A Kinesis data stream is a set of shards (https://docs.aws.amazon.com/streams/latest/dev/key-concepts.html#shard). Each shard has a sequence of data records. A data record is the unit of data stored in a Kinesis data stream. Data records are composed of a sequence number, a partition key, and a data blob, which is an immutable sequence of bytes. %kinesis% reads data from Kinesis streams and writes it into Snowflake tables using the [Snowpipe Streaming](/user-guide/snowpipe-streaming/snowpipe-streaming-high-performance-overview) architecture. Use this connector if you're looking to do the following: - Ingest real-time events from Amazon Kinesis into Snowflake for near real-time analytics - Ingest real-time events from Amazon Kinesis into Snowflake-managed Iceberg™ tables - Accelerate your ingestion even more by combining Openflow speed with the Interactive Tables feature - Use Single Message Transforms to enrich or filter data before it lands in Snowflake. ## Limitations - One connector supports only ingestion from a single stream. - Autoscaling is not supported. The number of Openflow runtime min and max nodes should be constant for the runtime where %kinesis% is deployed. - The connector supports routing Kinesis traffic through Snowflake outbound AWS PrivateLink. DynamoDB traffic must use the public endpoint because Amazon DynamoDB doesn't support Private DNS. For more information, see [](#label-kinesis-configure-aws-privatelink). ### Limitations of fault tolerance with the connector Kinesis Streams can be configured with a retention time. If for any reason the %kinesis% is not able to ingest data for more than the retention time, then expired records will not be loaded. ## Using different data types or data manipulation The connector is configured to work with the JSON data type. It can be modified and extended in many ways. See the dedicated sub-pages in the setup section for guidance on making necessary changes, and the following shared streaming customization guides: - [Configuring Avro data type ingestion](/user-guide/data-integration/openflow/connectors/streaming/configuring-avro-data-type-ingestion) - [Configuring Protobuf data type ingestion](/user-guide/data-integration/openflow/connectors/streaming/configuring-protobuf-data-type-ingestion) - [Configuring custom transformations](/user-guide/data-integration/openflow/connectors/streaming/configuring-custom-transformations) - [Configuring Dead Letter Queue (DLQ) handling](/user-guide/data-integration/openflow/connectors/streaming/configuring-dead-letter-queue-handling) and the Kinesis-specific [Kinesis as destination for DLQ messages](configuring-dead-letter-queue-handling) - [Configuring Private Key Authentication](/user-guide/data-integration/openflow/connectors/streaming/configuring-private-key-authentication) ### Supported data types %kinesis% supports the following data types: - **JSON (available by default in the connector)** - [Avro](/user-guide/data-integration/openflow/connectors/streaming/configuring-avro-data-type-ingestion) (extra configuration required) - [Protobuf](/user-guide/data-integration/openflow/connectors/streaming/configuring-protobuf-data-type-ingestion) (extra configuration required) ## Next steps - [Set up Openflow Connector for Amazon Kinesis Data Streams](/user-guide/data-integration/openflow/connectors/kinesis/setup) --- title: Openflow Connector for Kinesis Data Streams: Configuring DLQ handling source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/kinesis/configuring-dead-letter-queue-handling.md section: Loading & Unloading Data --- This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About the connector](about) - [Set up the connector](setup) - [Configuring Dead Letter Queue (DLQ) handling](/user-guide/data-integration/openflow/connectors/streaming/configuring-dead-letter-queue-handling) # Openflow Connector for Kinesis Data Streams: Configuring DLQ handling This topic explains how to configure a **Kinesis stream** as a destination for Dead Letter Queue (DLQ) messages on the **Kinesis high-performance connector**, plus the other Kinesis-specific parts of DLQ handling (the source processor, parse-failure relationship, and credential reuse). DLQ handling is shared between the streaming connectors. Read the general guide first --- [Configuring Dead Letter Queue (DLQ) handling](/user-guide/data-integration/openflow/connectors/streaming/configuring-dead-letter-queue-handling) --- for the common concepts: the failure envelope, the Snowflake-table route, the raw/structured branches, funnels, and DLQ sink failure handling. This page covers only what is specific to Kinesis. You don't have to apply this customization by hand. The **Openflow skill in Snowflake CoCo** can perform it for you --- describe the change you want and it edits the flow following the steps on this page. We recommend using the skill instead of configuring the components manually. ## Connector grounding
## Route the parse failure into the DLQ On a fresh connector the `ConsumeKinesis` `parse.failure` relationship is auto-terminated. Remove the auto-termination and connect `parse.failure` to the **RAW funnel** described in the [common guide](/user-guide/data-integration/openflow/connectors/streaming/configuring-dead-letter-queue-handling). **Capture the error reason.** `ConsumeKinesis` writes a `record.error.message` FlowFile attribute on parse/serde failure. Use `${record.error.message}` for the `error_message` field in the raw/structured branch metadata (the Kafka connector has no equivalent attribute). ## Kinesis stream as destination for DLQ messages Use this route to publish failed records back to a Kinesis stream. **Publish the original failed payload as-is --- there is no envelope and no record wrapping.** Connect the failure sources directly to a `PutKinesisStream` sink; the envelope (`raw_payload` / `structured_payload`) is only for the Snowflake-table route, because a stream consumer wants the original bytes. **Credential reuse:** The DLQ publisher reuses the same `AWSCredentialsProviderControllerService` + **Region** as `ConsumeKinesis` --- that is, the **same AWS account/region**. If your DLQ stream lives in a **different** account or region, configure the publisher with the appropriate credentials/region (and for a fully separate environment, a separate connector). ### Step 1: Create the PutKinesisStream processor 1. Add a `PutKinesisStream` processor to the connector's process group. 2. Set the following properties:
`PutKinesisStream` publishes the entire FlowFile content as a single Kinesis message. If the FlowFile contains multiple records (for example, NDJSON with one record per line), use a `SplitText` processor before `PutKinesisStream` to split the FlowFile into individual FlowFiles, one per line. ### Step 2: Wire the failure sources to the publisher - Connect the failure sources (the `parse.failure` relationship, and any transformation/error relationships) **directly** to this publisher --- no raw/structured branches are built for the stream route. - Route the publisher's `failure`, `invalid` relationships to the [DLQ sink failure handling](/user-guide/data-integration/openflow/connectors/streaming/configuring-dead-letter-queue-handling#label-openflow-streaming-dlq-sink-failure). Use a **bounded** `failure` retry (for example, retry count 3) so transient stream issues recover but persistent failures still reach the parking-lot. Do **not** use an effectively-infinite retry (for example, 9999). ## Snowflake table as destination for DLQ messages Identical to both connectors. See [Route B --- Snowflake table](/user-guide/data-integration/openflow/connectors/streaming/configuring-dead-letter-queue-handling#label-openflow-streaming-dlq-route-b) in the common guide. ## Troubleshooting
For shared symptoms (raw branch, `structured_payload`, grants, parking-lot funnel), see the [common troubleshooting table](/user-guide/data-integration/openflow/connectors/streaming/configuring-dead-letter-queue-handling). --- title: Openflow Connector for MySQL: Data mapping source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/mysql/data-mapping.md section: Loading & Unloading Data --- # %mysql%: Data mapping This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow Connector for MySQL](/user-guide/data-integration/openflow/connectors/mysql/about) - [Set up the Openflow Connector for MySQL](/user-guide/data-integration/openflow/connectors/mysql/setup) This topic describes MySQL data types are mapped to Snowflake data types. ## MySQL to Snowflake data type mapping The following table shows how MySQL data types are mapped to Snowflake data types when replicating data.
For types with default size limits (8 MB / 16 MB) in this table, it is possible to raise these limits. For details, see [Oversized values](/user-guide/data-integration/openflow/connectors/mysql/about#label-mysql-oversized-values). Any MySQL data types not listed in this table are mapped to TEXT by default. --- title: Openflow Connector for MySQL: Iceberg table destinations source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/mysql/iceberg.md section: Loading & Unloading Data --- # Openflow Connector for MySQL: Iceberg table destinations Available to all accounts. - [About Openflow Connector for MySQL](/user-guide/data-integration/openflow/connectors/mysql/about) - [Set up the Openflow Connector for MySQL](/user-guide/data-integration/openflow/connectors/mysql/setup) - [Openflow Connector for MySQL: Data mapping](/user-guide/data-integration/openflow/connectors/mysql/data-mapping) - [Data types for Apache Iceberg™ tables](/user-guide/tables-iceberg-data-types) - [Snowflake storage for Apache Iceberg™ tables](/user-guide/tables-iceberg-internal-storage) - [CREATE EXTERNAL VOLUME](/sql-reference/sql/create-external-volume) The Openflow Connector for MySQL supports writing to Snowflake-managed Apache %iceberg-tm% tables as an opt-in destination format. Iceberg v2 and v3 are both supported. Setting **Table Storage Format** = `ICEBERG` and choosing an **Iceberg Version** are the only connector-level changes required. The external volume, catalog, and serialization policy are inherited from the Snowflake destination database defaults. The Iceberg specification version is set via the **Iceberg Version** connector parameter, which defaults to `3` for both Gen2 (Openflow UI wizard) and Gen1 (parameter context) connectors. Storage can be either [Snowflake storage for Apache %iceberg-tm% tables](/user-guide/tables-iceberg-internal-storage) (`EXTERNAL_VOLUME = 'SNOWFLAKE_MANAGED'`) or an external volume in your cloud storage. When you use Snowflake storage, no external cloud storage or IAM grants are required. Existing connectors using standard tables aren't affected. ## Prerequisites - **Openflow runtime**: An existing runtime to host the connector. - **MySQL source configured for CDC**: Binary logging enabled (`log_bin = ON`, `binlog_format = ROW`, `binlog_row_image = FULL`), a user with `REPLICATION SLAVE` and `REPLICATION CLIENT` privileges, and a sufficiently long `binlog_expire_logs_seconds` for snapshot reconciliation. For details, see [Set up the Openflow Connector for MySQL](/user-guide/data-integration/openflow/connectors/mysql/setup). - **External volume in your cloud storage**: An external volume configured for Iceberg storage, with USAGE granted to the connector's Snowflake role. See [CREATE EXTERNAL VOLUME](/sql-reference/sql/create-external-volume). Not required when using Snowflake storage (`EXTERNAL_VOLUME = 'SNOWFLAKE_MANAGED'`). - **Snowflake destination database**: An existing database configured with Iceberg parameters (next section). ## Step 1: Configure the Snowflake destination database Set the Iceberg defaults on the destination database. The connector reads these defaults at runtime for external volume and serialization policy. The Iceberg specification version is configured per-connector via the **Iceberg Version** parameter (see Step 3), not solely via the database-level `ICEBERG_VERSION_DEFAULT`. ### Option A: Snowflake storage When you use Snowflake storage, Snowflake stores and manages the Iceberg table files for you. No external cloud storage or IAM grants are required. ```sql CREATE DATABASE EXTERNAL_VOLUME = 'SNOWFLAKE_MANAGED' STORAGE_SERIALIZATION_POLICY = ; ``` To configure an existing database: ```sql ALTER DATABASE SET EXTERNAL_VOLUME = 'SNOWFLAKE_MANAGED' STORAGE_SERIALIZATION_POLICY = ; ``` ### Option B: External volume in your cloud storage If you need to keep table files in your own cloud storage, configure the database with your external volume: ```sql CREATE DATABASE EXTERNAL_VOLUME = '' STORAGE_SERIALIZATION_POLICY = ; ``` To configure an existing database: ```sql ALTER DATABASE SET EXTERNAL_VOLUME = '' STORAGE_SERIALIZATION_POLICY = ; ```
`CATALOG = 'SNOWFLAKE'` is set automatically by the connector on each CREATE ICEBERG TABLE statement. Don't set it at the database level. The base location for each table is auto-derived using the [flat layout](/user-guide/tables-iceberg-managing-external-volumes#label-tables-iceberg-snowflake-managed-flat-layout): `STORAGE_BASE_URL/database/schema/table_name.randomId/[data | metadata]/`. No user configuration is needed. If using an external volume in your cloud storage (Option B), grant the connector's Snowflake role USAGE on the external volume: ```sql GRANT USAGE ON EXTERNAL VOLUME TO ROLE ; ``` This step is not required for Snowflake storage. ## Step 2: Set Table Storage Format in the connector's parameter context Set the **Table Storage Format** parameter to `ICEBERG` in the connector's destination parameter context. The default is `STANDARD`. For the full connector creation and configuration workflow, see [Set up the Openflow Connector for MySQL](/user-guide/data-integration/openflow/connectors/mysql/setup). ## Step 3: Set the Iceberg version Set the **Iceberg Version** connector parameter to `2` or `3`. This controls the Iceberg specification version used for type mapping (for example, JSON maps to `variant` on v3 vs `string` on v2) and the `ICEBERG_VERSION=` clause in CREATE ICEBERG TABLE DDL. - **Gen2 (Openflow UI wizard)**: **Iceberg Version** is a required field when **Table Storage Format** = `ICEBERG`, defaulting to `3`. This setting is immutable after the connector configuration is first applied. - **Gen1 (parameter context)**: The **Iceberg Version** parameter defaults to `3`. Review and change to `2` if needed before starting the connector. Do not change this value after ingestion begins. ## Step 4: Start and verify Start the connector as usual. After the initial snapshot completes, verify the destination tables are Iceberg: ```sql -- Confirm the table is Iceberg SELECT GET_DDL('TABLE', '..
No views created. Data is directly queryable from the destination tables.
Legacy parameter Current equivalent
Search Type Removed. The new connector always fetches all issues from discovered projects. Use `Project Keys Filter` to limit ingestion to specific projects.
JQL Query Removed. The new connector doesn't support arbitrary JQL for issue filtering. Use `Project Keys Filter` instead.
Project Names Replaced by `Project Keys Filter`, which accepts project keys (not names or IDs).
Status Category Removed. The new connector fetches all issues regardless of status.
Updated After Removed. The new connector manages incremental state automatically.
Created After Removed. The new connector manages incremental state automatically.
Destination Table Removed. The new connector creates fixed table names per entity (`ISSUE`, `PROJECT`, `COMMENT`, and others) in the configured destination schema.
Fetch All Worklogs Removed. The new connector fetches all worklogs into a separate `WORKLOG` table by default when `WORKLOG` is listed in `Enabled Tables`.
Connection Method Not exposed as a parameter. The new connector uses the `DIRECT` connection method.
Parameter Description
Deletes Fetch Strategy Enables tracking of deleted issues via the Jira audit log. Not available in the legacy connector.
Merge Interval Time interval between journal-to-destination merge operations. Available in both the core flow and the agile flow.
Property Description
End Offset Number of bytes removed at the end of the file.
Remove All Content Remove all content from the FlowFile superseding Start Offset and End Offset properties.
Start Offset Number of bytes removed at the beginning of the file.
Name Description
success Processed flowfiles.
Property Description
Input Compression Strategy The strategy to use for decompressing input FlowFiles
Output Compression Level The compression level for output FlowFiles for supported formats. A lower value results in faster processing but less compression; a value of 0 indicates no (that is, simple archiving) for gzip or minimal for xz-lzma2 compression. Higher levels can mean much larger memory usage such as the case with levels 7-9 for xz-lzma/2 so be careful relative to heap size.
Output Compression Strategy The strategy to use for compressing output FlowFiles
Output Filename Strategy Processing strategy for filename attribute on output FlowFiles
Name Description
failure FlowFiles will be transferred to the failure relationship on compression modification errors
success FlowFiles will be transferred to the success relationship on compression modification success
Name Description
mime.type The appropriate MIME Type is set based on the value of the Compression Format property. If the Compression Format is 'no compression' this attribute is removed as the MIME Type is no longer known.
Display Name API Name Default Value Allowable Values Description
Database User Database User Database user name
Mongo URI * Mongo URI MongoURI, typically of the form: mongodb://host1[:port1][,host2[:port2],...]
Password Password The password for the database user
SSL Context Service SSL Context Service The SSL Context Service used to provide client certificate information for TLS/SSL connections.
Write Concern * Write Concern ACKNOWLEDGED - ACKNOWLEDGED - UNACKNOWLEDGED - FSYNCED - JOURNALED - REPLICA_ACKNOWLEDGED - MAJORITY - W1 - W2 - W3 The write concern to use
Display Name API Name Default Value Allowable Values Description
Schema Access Strategy * Schema Access Strategy infer - Use 'Schema Name' Property - Use 'Schema Text' Property - Infer from Result Specifies how to obtain the schema that is to be used for interpreting the data.
Schema Branch Schema Branch Specifies the name of the branch to use when looking up the schema in the Schema Registry property. If the chosen Schema Registry does not support branching, this value will be ignored.
Schema Name Schema Name $\{schema.name\} Specifies the name of the schema to lookup in the Schema Registry property
Schema Registry Schema Registry Specifies the Controller Service to use for the Schema Registry
Schema Text Schema Text $\{avro.schema\} The text of an Avro-formatted Schema
Schema Version Schema Version Specifies the version of the schema to lookup in the Schema Registry. If not specified then the latest version of the schema will be retrieved.
Mongo Collection Name * mongo-collection-name The name of the collection to use
Mongo Database Name * mongo-db-name The name of the database to use
Client Service * mongo-lookup-client-service A MongoDB controller service to use with this lookup service.
Projection mongo-lookup-projection Specifies a projection for limiting which fields will be returned.
Lookup Value Field mongo-lookup-value-field The field whose value will be returned when the lookup key(s) match a record. If not specified then the entire MongoDB result document minus the _id field will be returned as a record.
Connector Minimum version
MySQL 0.33.0
PostgreSQL 0.39.0
MongoDB 0.17.0
SQL Server 0.27.0
Oracle Embedded License 0.25.0
Oracle Independent License 0.24.0
Name Type Description
application String The fixed value _openflow_
cloud.service.provider String One of _aws_, _snowflake_
container.id String Unique identifier of the container
container.image.name String Fully qualified name of the container image. All Openflow images are hosted by Snowflake repositories. For example, *<account>-openflow-<env>.registry-internal.snowflakecomputing.cn/openflow/openflow/openflow_repo/runtime-server*
container.image.tag String Version of the container image
k8s.container.name String The name of the K8s container. Openflow Runtime containers will start with the "Runtime Key" and end with *-gateway* or *-server*. For example, an Openflow Runtime named "PostgreSQL CDC" with a Runtime Key of postgresql-cdc, so it would have container names of: - postgresql-cdc-gateway - postgresql-cdc-server
k8s.container.restart_count Numeric String The number of times this container has restarted since it was created.
k8s.namespace.name String K8s namespace of the pod or container, starting with _runtime-_ for Openflow Runtimes. Values also include _kube-system_ and _openflow-runtime-infra_.
k8s.node.name String The internal domain name of the EKS node hosting the pod / container, or the EKS node itself. For example, ip-10-12-13-144.us-west-2.compute.internal
k8s.pod.name String The name of the K8s pod. Openflow Runtime pods will start with the "Runtime Key" and end with a numeric identifier for each pod replica. This number can grow up to the "Max Nodes" set for the Runtime, indexed at 0. For example, an Openflow Runtime named "PostgreSQL CDC" with a Runtime Key of postgresql-cdc and 3 nodes would have pod names of: - postgresql-cdc-0 - postgresql-cdc-1 - postgresql-cdc-2
k8s.pod.start_time ISO 8601 Date String Timestamp that the pod was started
k8s.pod.uid UUID String Unique identifier of the pod within the cluster
deployment.version String The Openflow deployment version.
openflow.dataplane.id UUID String The unique identifier of the Openflow Deployment, matching the "ID" shown in the Snowflake Openflow UI through Deployment > View Details.
Name Type Description
name String Provider of the metric. One of: - *runtime* for Openflow Connector metrics - *github.com/open-telemetry/opentelemetry-collector-contrib/receiver/kubeletstatsreceiver* for system-level metrics
Name Type Description
metric Object Contains two fields: - *name* for the unique metric produced, typically using dot-delimited namespaces - *unit* for the value represented by the type, such as byte, nanosecond, and thread The name and unit values vary widely. For the full list, see [Application Metrics](#label-openflow-application-metrics) below.
metric_type String One of: - *gauge* for most Openflow metrics, a snapshot value that can increase or decrease - *sum* for cumulative metrics like pod CPU time and network IO
value_type String The primitive type of the value produced by this metric. One of: - INT - DOUBLE
aggregation_temporality String Optional. Set to cumulative for metrics that are strictly increasing and dependent on previous values, such as pod CPU time and network IO.
is_monotonic Boolean Optional. For cumulative metrics, this is true to show that it is strictly increasing within the time series.
Name Type Description
formattedMessage String The actual log message emitted from the Runtime logger.
level String One of: - ERROR - WARN - INFO - DEBUG - TRACE
loggerName String The fully qualified classname for the logger. Openflow processors will typically use logger names that start with *com.snowflake.openflow.runtime.processors*. This is useful to view logs for a specific processor, controller service, or bundled library.
nanoseconds Integer Nanosecond-level time that this log message was created, starting at milliseconds. For example, a nanosecond value of 111222333 could correspond to a timestamp value of 1749180210111 with the leftmost 3 digits of nanosecond matching the right-most 3 digits of timestamp.
threadName String Name of the thread handling this call. For example, _Timer-Driven Process Thread-7_
throwable JSON Object *null* when there is no exception or stacktrace for this log message. Otherwise, it logs the stacktrace as a JSON string with fields: - *className* - the exception thrown - *message* - any message logged with the exception - *stepArray* - array of method calls for the stack trace, including: - *className* - *fileName* - *lineNumber* - *methodName*
timestamp Integer Time that this log message was created, represented as milliseconds since the UNIX epoch. For example, 1749180210044 indicates that the log was created at 2025-06-05 03:23:30.044 UTC
mdc JSON Object Mapped Diagnostic Context (MDC) providing additional flow-level context for the log entry. Contains the following fields: - *processGroupId* - unique identifier of the process group - *processGroupIdPath* - hierarchical path of process group IDs - *processGroupName* - name of the process group - *processGroupNamePath* - hierarchical path of process group names - *registeredFlowIdentifier* - identifier of the registered flow (present for all versioned flows, including out-of-the-box Openflow connectors) - *registeredFlowVersion* - version of the registered flow (present for all versioned flows, including out-of-the-box Openflow connectors) For example: ```json { "processGroupId": "6dc1d98f-019d-1000-ffff-ffffa3ba8a09", "processGroupIdPath": "/58385a8b-019d-1000-2a52-9ef1c34b0e5f/6dc1d98f-019d-1000-ffff-ffffa3ba8a09", "processGroupName": "latency targets", "processGroupNamePath": "/Openflow/latency targets", "registeredFlowIdentifier": "sqlserver-multidatabase", "registeredFlowVersion": "0.29.0-ebb7a257" } ```
Metric Name Unit Description
connection.input.bytes bytes Size of Items Input
connection.input.count items Count of Items Input
connection.output.bytes bytes Size of Items Output
connection.output.count items Count of Items Output
connection.queued.bytes bytes Size of Items Queued
connection.queued.bytes.max bytes Max Size of Items Queued
connection.queued.count items Count of Items Queued
connection.queued.count.max items Max Count of Items Queued
connection.queued.duration.total milliseconds Total Duration of Queued Items
connection.queued.duration.max milliseconds Max Duration of Queued Items
connection.backpressure.threshold.bytes bytes The maximum size of data in bytes that can be queued in this connection before it applies back pressure.
connection.backpressure.threshold.objects items The configured maximum number of FlowFiles that can be queued in this connection before it applies back pressure.
connection.loadbalance.status.load_balance_not_configured binary, 0 or 1 1 if the connection does not have a configured load balance setting. Otherwise, 0.
connection.loadbalance.status.load_balance_active binary, 0 or 1 1 if the connection is load balancing across the cluster. Otherwise, 0.
connection.loadbalance.status.load_balance_inactive binary, 0 or 1 1 if the connection is not load balancing across the cluster. Otherwise, 0.
Attribute Description
id The unique identifier of the connection
name The user-visible name of the connection
type The fixed value _connection_
source.id The unique identifier of the component that is sending FlowFiles to this connection
source.name The user-visible name of the component that is sending FlowFiles to this connection
destination.id The unique identifier of the component that is receiving FlowFiles from this connection
destination.name The user-visible name of the component that is receiving FlowFiles from this connection
group.id The unique identifier of the Process Group that contains this Connection
Metric Name Unit Description
port.thread.count.active threads Number of Active Threads
port.bytes.received bytes Number of Bytes Received
port.bytes.sent bytes Number of Bytes Sent
port.flowfiles.received flowfiles Number of FlowFiles Received
port.flowfiles.sent flowfiles Number of FlowFiles Sent
port.input.bytes bytes Size of Items Input
port.input.count items Count of Items Input
port.output.bytes bytes Size of Items Output
port.output.count items Count of Items Output
Attribute Description
id The unique identifier of the port
name The user-visible name of the port
type One of _port-input_ or _port-output_
group.id The unique identifier of the Process Group that contains this Port
Metric Name Unit Description
processgroup.thread.count.active threads Number of Active Threads
processgroup.thread.count.stateless threads Number of Stateless Threads
processgroup.thread.count.terminated threads Number of Terminated Threads
processgroup.bytes.read bytes Number of Bytes Read
processgroup.bytes.received bytes Number of Bytes Received
processgroup.bytes.transferred bytes Number of Bytes Transferred
processgroup.bytes.sent bytes Number of Bytes Sent
processgroup.bytes.written bytes Number of Bytes Written
processgroup.flowfiles.received flowfiles Number of FlowFiles Received
processgroup.flowfiles.sent flowfiles Number of FlowFiles Sent
processgroup.flowfiles.transferred flowfiles Number of FlowFiles Transferred
processgroup.input.count items Number of Items Input
processgroup.input.content.size bytes Size of Items Input
processgroup.output.count items Number of Items Output
processgroup.output.content.size bytes Size of Items Output
processgroup.queued.count items Number of Items Queued
processgroup.queued.content.size bytes Size of Items Queued
processgroup.time.processing nanoseconds Time Spent Processing
Attribute Description
id The unique identifier of the Process Group
name The user-visible name of the Process Group
type The fixed value _process-group_
tree.level The depth of the Process Group, relative to the root process group of the flow. Process Groups at the highest level of the flow will have a tree.level of 1
Metric Name Unit Description
processor.thread.count.active thread Number of Active Threads
processor.thread.count.terminated thread Number of Terminated Threads
processor.time.lineage.average nanosecond Average Lineage Duration
processor.invocations invocations Number of Invocations
processor.bytes.read byte Number of Bytes Read
processor.bytes.received byte Number of Bytes Received
processor.bytes.sent byte Number of Bytes Sent
processor.bytes.written byte Number of Bytes Written
processor.flowfiles.received flowfiles Number of FlowFiles Received
processor.flowfiles.removed flowfiles Number of FlowFiles Removed
processor.flowfiles.sent flowfiles Number of FlowFiles Sent
processor.input.count item Number of Items Input
processor.input.content.size bytes Size of Items Input
processor.output.count item Number of Items Output
processor.output.content.size byte Size of Items Output
processor.time.processing nanosecond Time Spent Processing
processor.run.status.running binary, 0 or 1 1 if running; 0 otherwise
processor.run.status.stopped binary, 0 or 1 1 if stopped; 0 otherwise
processor.run.status.validating binary, 0 or 1 1 if validating; 0 otherwise
processor.run.status.invalid binary, 0 or 1 1 if invalid; 0 otherwise
processor.run.status.disabled binary, 0 or 1 1 if disabled; 0 otherwise
processor.counter count Value of the counter
Attribute Description
id The unique identifier of the processor
name The user-visible and user-editable name of the Processor
type The fixed value _processor_
component The immutable class name of the processor.
execution.node Either _ALL_ or _PRIMARY_, depending on how this Processor is configured to run
group.id The unique identifier of the Process Group that contains this Processor
Attribute Description
type The fixed value _counter_
counter The user- or system-generated name of the counter
Metric Name Unit Description
remoteprocessgroup.thread.count.active threads Number of Active Threads
remoteprocessgroup.remote.port.count.active ports Number of Active Remote Ports
remoteprocessgroup.remote.port.count.inactive ports Number of Inactive Remote Ports
remoteprocessgroup.duration.lineage.average nanoseconds Average Lineage Duration
remoteprocessgroup.refresh.age milliseconds Time since last refresh
remoteprocessgroup.received.count items Number of Received Items
remoteprocessgroup.received.content.size bytes Size of Received Items
remoteprocessgroup.sent.count items Number of Sent Items
remoteprocessgroup.sent.content.size bytes Size of Sent Items
remoteprocessgroup.transmission.status.transmitting binary, 0 or 1 1 if the Remote Process Group is transmitting. Otherwise, 0.
remoteprocessgroup.transmission.status.nottransmitting binary, 0 or 1 0 if the Remote Process Group is transmitting. Otherwise, 1.
Attribute Description
id The unique identifier of the remote process group
name The user-visible name of the Remote Process Group
group.id The unique identifier of the Process Group that contains this Remote Process Group
authorization.issue The Authorization used to access the Remote Process Group
target.uri The URI of the Remote Process Group
type The fixed value _remote-process-group_
Metric Name Unit Description
jvm.memory.heap.used bytes The amount of memory currently occupied by objects on the JVM Heap
jvm.memory.heap.committed bytes The amount of memory guaranteed to be available for use by the JVM Heap
jvm.memory.heap.max bytes Maximum amount of memory allocated for the JVM Heap
jvm.memory.heap.init bytes Initial amount of memory allocated for the JVM Heap
jvm.memory.heap.usage percentage JVM Heap Usage
jvm.memory.non-heap.usage percentage JVM Non-Heap Usage
jvm.memory.total.init bytes Initial amount of memory allocated for the JVM
jvm.memory.total.used bytes Current amount of memory used by the JVM
jvm.memory.total.max bytes Maximum amount of memory that can be used by the JVM
jvm.memory.total.committed bytes The amount of memory guaranteed to be available for use by the JVM
jvm.threads.count threads Number of live threads
jvm.threads.deadlocks threads JVM Thread Deadlocks
jvm.threads.daemon.count threads Number of live daemon threads
jvm.uptime seconds Number of seconds the JVM process has been running
jvm.file.descriptor.usage percentage Percentage of available file descriptors currently in use.
jvm.gc.G1-Concurrent-GC.runs runs Total number of times that the G1 Concurrent Garbage Collection has run
jvm.gc.G1-Concurrent-GC.time milliseconds Total amount of time that the G1 Concurrent Garbage Collection has been running
jvm.gc.G1-Young-Generation.runs runs Total number of times that the G1 Young Generation has run
jvm.gc.G1-Young-Generation.time milliseconds Total amount of time that the G1 Young Generation has been running
jvm.gc.G1-Old-Generation.runs runs Total number of times that the G1 Old Generation has run
jvm.gc.G1-Old-Generation.time milliseconds Total amount of time that the G1 Old Generation has been running
Metric Name Unit Description
cores.available cores The number of available cores for the Runtime
cores.load percentage Either the system load average or -1 if it is not available
Attribute Description
id The fixed value _cpu_
name The name of the operating system
architecture The architecture of the operating system
version The version of the operating system
Metric Name Unit Description
storage.free bytes The amount of free storage for a given repository
storage.used bytes The amount of used storage for a given repository
Attribute Description
id The unique identifier of the storage repository
name Same as id and provided for consistency
storage.type One of _flowfile_, _content_, or _provenance_
Metric Initial load Incremental load
`ROWS_ADDED` Records loaded that aren't marked as deleted. Active source records that don't exist in the destination table.
`ROWS_ADDED_DELETED` Records loaded that are already marked as deleted. Source records marked as deleted that don't exist in the destination table.
`ROWS_UPDATED` `0` Active source records that match active records in the destination table.
`ROWS_DELETED` `0` Source records marked as deleted that match active records in the destination table.
`ROWS_RESTORED` `0` Active source records that match records marked as deleted in the destination table.
Property Description
Activity Restored Message The message that will be the content of FlowFiles that are sent to 'activity.restored' relationship
Continually Send Messages If true, will send inactivity indicator continually every Threshold Duration amount of time until activity is restored; if false, will send an indicator only when the flow first becomes inactive
Copy Attributes If true, will copy all flow file attributes from the flow file that resumed activity to the newly created indicator flow file
Inactivity Message The message that will be the content of FlowFiles that are sent to the 'inactive' relationship
Monitoring Scope Specify how to determine activeness of the flow. 'node' means that activeness is examined at individual node separately. It can be useful if DFM expects each node should receive flow files in a distributed manner. With 'cluster', it defines the flow is active while at least one node receives flow files actively. If NiFi is running as standalone mode, this should be set as 'node', if it 's' cluster ', NiFi logs a warning message and act as' node'scope.
Reporting Node Specify which node should send notification flow-files to inactive and activity.restored relationships. With 'all', every node in this cluster send notification flow-files. 'primary' means flow-files will be sent only from a primary node. If NiFi is running as standalone mode, this should be set as 'all', even if it 's' primary ', NiFi act as' all'.
Reset State on Restart When the processor gets started or restarted, if set to true, the initial state will always be active. Otherwise, the last reported flow state will be preserved.
Threshold Duration Determines how much time must elapse before considering the flow to be inactive
Wait for Activity When the processor gets started or restarted, if set to true, only send an inactive indicator if there had been activity beforehand. Otherwise send an inactive indicator even if there had not been activity beforehand.
Scopes Description
LOCAL MonitorActivity stores the last timestamp at each node as state, so that it can examine activity at cluster wide. If 'Copy Attribute' is set to true, then flow file attributes are also persisted. In local scope, it stores last known activity timestamp if the flow is inactive.
CLUSTER MonitorActivity stores the last timestamp at each node as state, so that it can examine activity at cluster wide. If 'Copy Attribute' is set to true, then flow file attributes are also persisted. In local scope, it stores last known activity timestamp if the flow is inactive.
Name Description
activity.restored This relationship is used to transfer an Activity Restored indicator when FlowFiles are routing to 'success' following a period of inactivity
inactive This relationship is used to transfer an Inactivity indicator when no FlowFiles are routed to 'success' for Threshold Duration amount of time
success All incoming FlowFiles are routed to success
Name Description
inactivityStartMillis The time at which Inactivity began, in the form of milliseconds since Epoch
inactivityDurationMillis The number of milliseconds that the inactivity has spanned
Property Description
ADLS Credentials Controller Service used to obtain Azure Credentials.
Conflict Resolution Strategy Indicates what should happen when a file with the same name already exists in the output directory
Destination Directory Name of the Azure Storage Directory where the files will be moved. The Directory Name cannot contain a leading '/'. The root directory can be designated by the empty string value. Non-existing directories will be created. If the original directory structure should be kept, the full directory path needs to be provided after the destination directory. e.g.: destdir/$\{azure.directory\}
Destination Filesystem Name of the Azure Storage File System where the files will be moved.
File Name The filename
Source Directory Name of the Azure Storage Directory from where the move should happen. The Directory Name cannot contain a leading '/'. The root directory can be designated by the empty string value.
Source Filesystem Name of the Azure Storage File System from where the move should happen.
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests. In case of SOCKS, it is not guaranteed that the selected SOCKS Version will be used by the processor.
Name Description
failure Files that could not be written to Azure storage for some reason are transferred to this relationship
success Files that have been successfully written to Azure storage are transferred to this relationship
Name Description
azure.source.filesystem The name of the source Azure File System
azure.source.directory The name of the source Azure Directory
azure.filesystem The name of the Azure File System
azure.directory The name of the Azure Directory
azure.filename The name of the Azure File
azure.primaryUri Primary location for file content
azure.length The length of the Azure File
Property Description
attribute-cache-regex Any attributes whose names match this regex will be stored in the distributed cache to be copied to any FlowFiles released from a corresponding Wait processor. Note that the uuid attribute will not be cached regardless of this value. If blank, no attributes will be cached.
distributed-cache-service The Controller Service that is used to cache release signals in order to release files queued at a corresponding Wait processor
release-signal-id A value, or the results of an Attribute Expression Language statement, which will be evaluated against a FlowFile in order to determine the release signal cache key
signal-buffer-count Specify the maximum number of incoming flow files that can be buffered until signals are notified to cache service. The more buffer can provide the better performance, as it reduces the number of interactions with cache service by grouping signals by signal identifier when multiple incoming flow files share the same signal identifier.
signal-counter-delta A value, or the results of an Attribute Expression Language statement, which will be evaluated against a FlowFile in order to determine the signal counter delta. Specify how much the counter should increase. For example, if multiple signal events are processed at upstream flow in batch oriented way, the number of events processed can be notified with this property at once. Zero (0) has a special meaning, it clears target count back to 0, which is especially useful when used with Wait Releasable FlowFile Count = Zero (0) mode, to provide 'open-close-gate' type of flow control. One (1) can open a corresponding Wait processor, and Zero (0) can negate it as if closing a gate.
signal-counter-name A value, or the results of an Attribute Expression Language statement, which will be evaluated against a FlowFile in order to determine the signal counter name. Signal counter name is useful when a corresponding Wait processor needs to know the number of occurrences of different types of events, such as success or failure, or destination data source names, etc.
Name Description
failure When the cache cannot be reached, or if the Release Signal Identifier evaluates to null or empty, FlowFiles will be routed to this relationship
success All FlowFiles where the release signal has been successfully entered in the cache will be routed to this relationship
Name Description
notified All FlowFiles will have an attribute 'notified'. The value of this attribute is true, is the FlowFile is notified, otherwise false.
Field Description
`apiType` **(Required)** The query endpoint name in the Shopify Admin GraphQL API. This must match the root query field exactly (for example, `orders` for the orders query (https://shopify.dev/docs/api/admin-graphql/2026-04/queries/orders), `products` for the products query (https://shopify.dev/docs/api/admin-graphql/2026-04/queries/products)). Used as the key for lookup and override matching.
`tableName` **(Required)** The Snowflake destination table name.
`gidTypeName` The Shopify GID resource type (for example, `Order`, `Product`). Used for delete cascade and child record routing.
`additionalGidTypeNames` Array of additional GID type names that also map to this object. Use when Shopify returns the same resource under more than one GID type name, so that records are routed to the correct table regardless of which GID type appears in the response.
`graphqlFields` List of GraphQL selection fields. Each entry is a field name, a nested selection (for example, `"totalPriceSet { shopMoney { amount currencyCode } }"`), or an aliased field with arguments (for example, `"tier: metafield(key: \"custom.tier\") { value }"`). Aliases are useful for querying metafields by key.
`requiredQueryArgs` Map of fixed GraphQL argument key-value pairs appended to every query for this object. Use for endpoints that require non-standard arguments that aren't covered by the built-in query parameters (for example, `{"type": "SALES_CHANNEL"}`).
`supportsIncremental` Whether the object supports incremental sync. Default: `true`.
`incrementalField` The field used for watermark-based incremental queries (for example, `updatedAt`, `createdAt`). The field must both exist on the returned type **and** be accepted as a filter by the query root's `query:` argument. A field that exists on the type but isn't supported as a filter causes `GetShopifyIncremental` to fail with `Invalid search field: `. If this happens, set `supportsIncremental` to `false` and `refreshStrategy` to `FULL_PERIODIC` instead.
`refreshStrategy` Controls the sync mode. `INCREMENTAL` (default) uses watermark-based incremental queries. `FULL_PERIODIC` performs a complete re-sync on each run instead. `PARENT_PIGGYBACKED` means this object is extracted from another object's query response and is not queried independently.
`supportsDeletes` Whether the connector should track deletion events for this object. Default: `false`.
`promotedColumns` Array of column definitions that extract values from the JSON payload into dedicated Snowflake columns. For more information, see [Promoted columns](#label-promoted-columns).
`childFields` Array of child connection definitions that are extracted into separate tables. For more information, see [Child fields](#label-child-fields).
`ignoredFields` List of field names to exclude from queries. Matches only on the leading name of each top-level entry in `graphqlFields`. For nested fields inside a sub-selection (for example, a field inside `defaultEmailAddress { ... }`), `ignoredFields` has no effect. Remove the field directly from the sub-selection in `graphqlFields` instead.
`supportsBulk` Whether the object supports bulk queries through the Shopify Bulk Operations API. Default: `true`.
`sortKeys` List of sort key values (from the object's corresponding `SortKeys` enum) used to order results during bulk and incremental queries. For example, `["UPDATED_AT", "ID"]`.
`sortKeyStyle` How sort key values are formatted in queries. `ENUM` (default) uses bare enum values (for example, `UPDATED_AT`). `STRING` uses quoted lowercase strings (for example, `"updated_at"`). Use `STRING` for object types that accept string sort keys, such as metaobjects.
Field Description
`name` The Snowflake column name (uppercase recommended).
`path` A JSONPath expression pointing to the value in the raw record (for example, `$.email`, `$.totalPriceSet.shopMoney.amount`).
`type`

The Snowflake column type. The following values are supported:

Value Snowflake type Notes
`string` `VARCHAR` None
`integer` `NUMBER(38,0)` None
`boolean` `BOOLEAN` None
`float` `FLOAT` None
`money` `NUMBER(38,4)` Converts Shopify amount strings to numeric.
`timestamp` `TIMESTAMP_TZ` ISO-8601 strings.
`date` `DATE` None
`id` `NUMBER(38,0)` Strips the `gid://shopify/*/` prefix and returns the numeric ID.
`gid` `VARCHAR` Stores the full GID string.
`json` `VARIANT` Stores sub-objects as VARIANT.
Field Description
`fieldName` The GraphQL connection field name in the parent object (for example, `lineItems`).
`tableName` The Snowflake table name for the child records.
`gidTypeName` The Shopify GID type for the child (for example, `LineItem`).
`connectionType` `edges` (paginated connection) or `array` (inline array). Default: `edges`.
`pageSize` The `first:` limit applied to this child connection in incremental queries. Default and maximum: `250`.
`graphqlFields` Explicit GraphQL selection set for the child table. If omitted, the connector parses the child's fields from the matching connection entry in the parent's `graphqlFields` list.
`promotedColumns` Array of promoted column definitions for the child table, using the same schema as top-level `promotedColumns`.
Property Description
Model Name The name of the OpenAI Model to use
OpenAI API Key The API Key for interacting with OpenAI
Prompt Text that can be used to guide the model's style or continue a previous audio segment. The text must be in English.
Response Format Specifies which format is desired for the output
Temperature The sampling temperature to use. The value must be a floating-point number between 0.0 and 1.0. A higher value, such as 0.8 will result in more of an interpreted translation, whereas a value of 0.0 will result in a more literal translation.
Name Description
failure FlowFiles that could not be transcribed are routed to this relationship.
success FlowFiles that have been successfully transcribed will be transferred to this relationship.
Cost category Description
Openflow (shown as **Openflow Compute BYOC** on your Snowflake bill) Cost based on the number of virtual CPU cores (vCPU) used by connector runtimes within your "bring your own cloud (BYOC)" environment. You are charged for active runtimes only. The compute used for Openflow management processes is excluded from this specific charge. Credits are billed per-second with a 60-second minimum. For an example of using vCPU and the impacts of scaling, see [](#label-openflow-byoc-scaling-overview). For information on the rate per vCPU per hour, refer to Table 1(g) in the [Snowflake Service Consumption Table](https://www.snowflake.cn/legal-files/CreditConsumptionTable.pdf). Additionally, the [METERING_DAILY_HISTORY](/sql-reference/account-usage/metering_daily_history) and [METERING_HISTORY](/sql-reference/account-usage/metering_history) views in the [Account Usage](/sql-reference/account-usage) schema can provide additional details on Openflow compute costs using queries for *SERVICE_TYPE=OPENFLOW_COMPUTE_BYOC*. See [Exploring compute cost](/user-guide/cost-exploring-compute) for more information on exploring compute costs in Snowflake.
Infrastructure (only for BYOC configuration) For BYOC deployments, you directly pay your cloud provider, for example, AWS, for the underlying infrastructure provisioned in your environment to run Openflow. This primarily includes compute (for runtimes you provision to run the connectors and for managing the runtimes), networking, and storage costs, and appears on your CSP bill. The EC2 compute requirements are illustrated in the following image: ![EC2 compute requirements](/static/images/connectivity/ec2-compute-reqs.png) For information about monitoring costs with AWS resource tags for BYOC deployments, see [BYOC deployment customization and tagging behavior](/user-guide/data-integration/openflow/setup-openflow-byoc#label-openflow-byoc-customization-tagging).
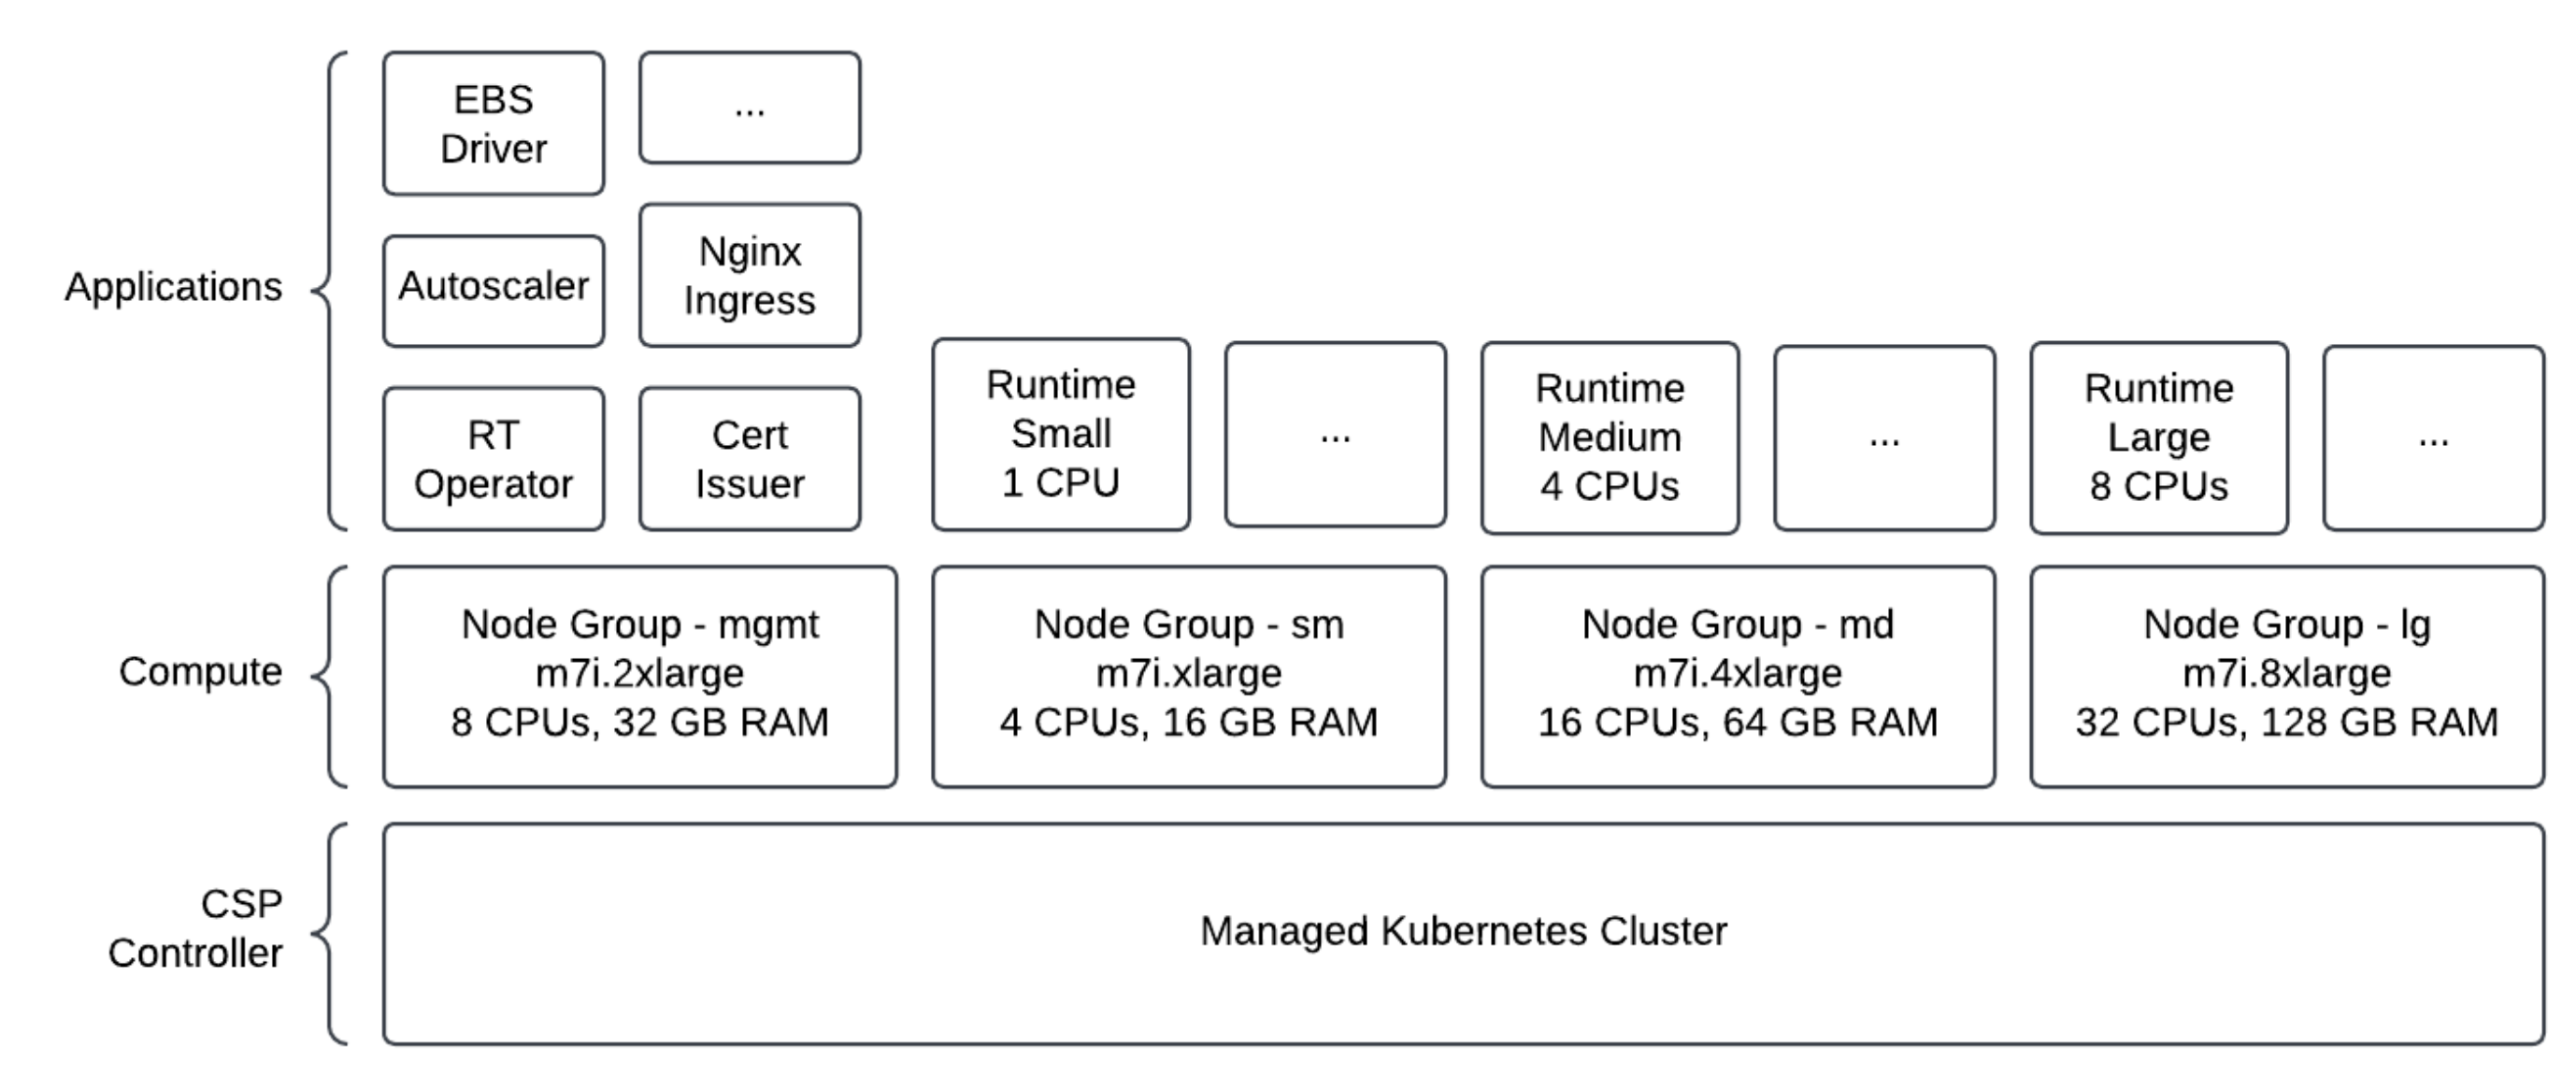
Ingestion Cost for loading data into Snowflake using services such as Snowpipe or Snowpipe Streaming, based on data volume. Appears on your Snowflake bill under respective ingestion services line items. Certain connectors may require a standard Snowflake warehouse, incurring additional warehouse costs. For example, database CDC connectors require a Snowflake warehouse for both initial snapshot and incremental Change Data Capture (CDC). You can schedule [MERGE](/sql-reference/sql/merge) operations to manage the compute cost.
Telemetry Data Ingest Standard Snowflake charges for sending logs and metrics to Openflow deployments and sending runtime logs to your event table within Snowflake. The rate for credits per GB of telemetry data can be found in Table 5 in the [Snowflake Service Consumption Table](https://www.snowflake.cn/legal-files/CreditConsumptionTable.pdf).
Item Kinesis high-performance
Source processor `ConsumeKinesis`
Parse-failure relationship `parse.failure`
Connection / credentials to reuse `AWSCredentialsProviderControllerService` + **Region** + **Stream Name**
Stream-route publisher `PutKinesisStream`
Record reader / writer `JsonTreeReader` / `JsonRecordSetWriter`
Destination processor `PublishSnowpipeStreaming`
Property Value
Stream Name Your DLQ stream name.
AWS Credentials Provider Service The same `AWSCredentialsProviderControllerService` used by `ConsumeKinesis`.
Region The same region as `ConsumeKinesis`.
Symptom Likely cause
DLQ publisher writes to the wrong stream/account `PutKinesisStream` reuses the `AWSCredentialsProviderControllerService` + **Region** of `ConsumeKinesis` --- a different account/region needs the appropriate credentials and region.
MySQL type Snowflake type Notes
DECIMAL / NUMERIC NUMBER The maximum number of digits in DECIMAL format for MySQL is 65. For Snowflake, the maximum is 38. Precision is lost when exceeded.
INT / INTEGER INT
TINYINT / BOOL INT
SMALLINT INT
MEDIUMINT INT
BIGINT INT
YEAR INT
FLOAT FLOAT
DOUBLE FLOAT
VARCHAR TEXT
CHAR TEXT Trailing spaces aren't preserved.
TINYTEXT TEXT
TEXT TEXT
MEDIUMTEXT TEXT
LONGTEXT TEXT Supported by default up to 16 MB.
ENUM TEXT Stored as a string value. For example, for `ENUM('one', 'two')` the possible values are `'one'` and `'two'`.
SET TEXT Stored as a comma-separated string in column declaration order. For example, for `SET('one', 'two')` the possible values are `''`, `'one'`, `'two'`, and `'one,two'`.
BIT TEXT Represented as a hexadecimal string. For example: `'83060c183060c183'`.
DATE DATE
DATETIME TIMESTAMP_NTZ
TIMESTAMP TIMESTAMP_TZ Values are stored in UTC.
TIME TIME
BINARY BINARY
VARBINARY BINARY
TINYBLOB BINARY
BLOB BINARY
MEDIUMBLOB BINARY Supported by default up to 8 MB.
LONGBLOB BINARY Supported by default up to 8 MB.
JSON VARIANT Supported by default up to 16 MB.
Parameter Required Notes
EXTERNAL_VOLUME Yes The external volume for Iceberg file storage.
ICEBERG_VERSION_DEFAULT No `2` or `3`. Legacy fallback for older connector flows where the **Iceberg Version** parameter is unset. New connectors set the version via the connector parameter (Step 3) and do not require this database setting.
STORAGE_SERIALIZATION_POLICY Yes `COMPATIBLE` produces Parquet files readable by external engines. `OPTIMIZED` enables Snowflake-specific query optimizations. Choose based on your data query needs. For more information, see [STORAGE_SERIALIZATION_POLICY](/sql-reference/parameters#storage-serialization-policy).
'); -- Confirm the Iceberg version on the database SHOW PARAMETERS LIKE 'ICEBERG_VERSION_DEFAULT' IN DATABASE ; ``` ## Known limitations - **Tri-Secret Secure accounts and Snowflake storage**: Accounts with Tri-Secret Secure (TSS) enabled may be unable to create new Snowflake-managed Iceberg tables that use [Snowflake storage for Apache %iceberg-tm% tables](/user-guide/tables-iceberg-internal-storage). For details, see [Encryption](/user-guide/tables-iceberg-internal-storage#encryption). - **Incompatible type change.** When the source column type changes to a type that maps to a different Iceberg type, the table is marked as failed and requires a resnapshot. See [Type mapping reference](#type-mapping-reference) for the complete source-to-Iceberg type mapping. - **Parameter change within the same Iceberg type.** The connector doesn't recognize parameter changes within the same Iceberg type (for example, changing `decimal(10,2)` to `decimal(20,2)`). The column retains its current Iceberg type. - **BIGINT to BIGINT UNSIGNED schema evolution not allowed**: Signed `BIGINT` maps to `long` while `BIGINT UNSIGNED` maps to `decimal(20,0)`. Iceberg does not allow promotion from `long` to `decimal`, so this schema change on the source will fail replication. - **Do not change Table Storage Format or Iceberg Version after the connector starts**: The connector's **Table Storage Format** and **Iceberg Version** parameter should not be modified after ingestion begins. Gen2 connectors enforce this by making **Iceberg Version** immutable after first apply. Mixing settings across destination tables is not supported. To switch, follow the steps in [Switching table storage format or Iceberg version](#switching-table-storage-format-or-iceberg-version). ## Type mapping reference The following table shows how MySQL types map to Snowflake standard and Iceberg destination types:
Source types not listed in the table are mapped to TEXT on standard tables and `string` on Iceberg tables. ## Switching table storage format or Iceberg version Switching between Standard and Iceberg, or between Iceberg v2 and v3, requires recreating the connector. Follow these steps: 1. Stop the connector. 2. Delete the process group in Openflow. 3. Manually clean up the destination database (drop the replicated schemas/tables, or use a new database). 4. Reimport the connector with the new **Table Storage Format** and select the target **Iceberg Version** when configuring the connector. This ensures all connector state is correctly cleaned up within Openflow. The new connector performs a fresh snapshot into the destination. ## Upgrading an existing connector to use Iceberg Version pinning Gen2 connector version `2026.7.21` and Gen1 connector version `0.53.0` introduce the **Iceberg Version** parameter. If you are upgrading from an earlier connector version (for example, Gen1 `0.50.0` to `0.53.0` or later), a new **Iceberg Version** field appears that you must configure to match your existing destination tables. 1. Stop the connector. 2. [Upgrade the runtime](/user-guide/data-integration/openflow/manage#label-openflow-upgrading-a-runtime) to version `2026.7.21` or later. 3. [Upgrade the connector](/user-guide/data-integration/openflow/manage#upgrade-a-connector) in place (Gen2: to version `2026.7.21` or later; Gen1: to version `0.53.0` or later). 4. Set the **Iceberg Version** parameter to match your existing destination tables: - **Gen2 (Openflow UI wizard)**: After upgrading, open the connector configuration wizard. The **Destination details** step now includes a required **Iceberg Version** field, defaulting to `3`. If your existing destination tables are Iceberg v2, change it to `2` before applying. This choice is locked after first apply and cannot be changed later. - **Gen1 (parameter context)**: The **Iceberg Version** parameter defaults to `3` after the flow upgrade. If your existing destination tables are Iceberg v2, change it to `2` before starting the connector. 5. Start the connector. Selecting an **Iceberg Version** that doesn't match your existing destination tables can cause type-mapping errors or DDL failures. Always verify the version of your existing tables before choosing a value. ## References - [CREATE EXTERNAL VOLUME](/sql-reference/sql/create-external-volume) - [Data types for Apache Iceberg tables](/user-guide/tables-iceberg-data-types) - [ALTER DATABASE](/sql-reference/sql/alter-database) - [STORAGE_SERIALIZATION_POLICY](/sql-reference/parameters#storage-serialization-policy) - [Set up the Openflow Connector for MySQL](/user-guide/data-integration/openflow/connectors/mysql/setup) --- title: Openflow Connector for MySQL: Maintenance source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/mysql/maintenance.md section: Loading & Unloading Data --- # %mysql%: Maintenance This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Set up the Openflow Connector for MySQL](/user-guide/data-integration/openflow/connectors/mysql/setup) - [Openflow Connector for MySQL: Data mapping](/user-guide/data-integration/openflow/connectors/mysql/data-mapping) This topic describes important maintenance considerations and best practices for maintaining the %mysql% such as reinstalling the connector or setting the starting binary log position for loading. These operations are often used in conjunction with [Incremental replication without snapshots](/user-guide/data-integration/openflow/connectors/mysql/incremental-replication). ## Check the replication status of a table Interim failures, such as connection errors or temporary source unavailability during a high-availability failover, do not prevent table replication. Replicated tables keep their current status and the connector retries on the next polling cycle. However, permanent failures, such as unsupported data types, prevent table replication. To troubleshoot replication issues or verify that a table has been successfully removed from the replication flow, check the Table State Store: 1. In the Openflow runtime canvas, right-click a processor group and choose **Controller Services**. A table listing controller services displays. 2. Locate the row labeled **Table State Store**, click the **More** %sf-vertical-more-button% button on the right side of the row, and then choose **View State**. A list of tables and their current states displays. Type in the search box to filter the list by table name. The possible states are: - **NEW**: The table is scheduled for replication but replication hasn't started. - **SNAPSHOT_REPLICATION**: The connector is copying existing data. This status displays until all records are stored in the destination table. - **INCREMENTAL_REPLICATION**: The connector is actively replicating changes. This status displays after snapshot replication ends and continues to display indefinitely until a table is either removed from replication or replication fails. - **FAILED**: Replication has permanently stopped due to an error. The Openflow runtime canvas doesn't display table status changes — only the current table status. However, table status changes are recorded in logs when they occur. Look for the following log message: ```text Replication state for table .. changed from to ``` If a permanent failure prevents table replication, remove the table from replication. After you address the problem that caused the failure, you can add the table back to replication. For more information, see [Restart table replication](#label-of-mysql-restart-table-replication). ## Restart table replication This procedure re-snapshots the table in place. It requires Runtime Extensions version `2026.5.14.16` or later and connector version `0.49.0` or later. On earlier versions, re-snapshotting a table that already exists in Snowflake fails instead of reloading in place. Upgrade Runtime Extensions first, and then upgrade the connector flow before you use this procedure. A table in a FAILED state (for example, due to a missing primary key or an unsupported schema change) does not restart automatically. If a table enters a FAILED state or you need to restart replication from scratch, use the following procedure to remove and re-add the table to replication. If the failure was caused by an issue in the source table such as a missing primary key, resolve that issue in the source database before continuing. 1. Remove the table from replication, using one of the following methods: - Add the table to the **Re-snapshot Table Exclusions** parameter to temporarily exclude it from replication. This approach is convenient when the table is matched by an **Included Table Regex** that you don't want to change. - In the **Ingestion Parameters** context, either remove the table from **Included Table Names** or modify the **Included Table Regex** so the table is no longer matched. 2. Verify the table has been removed: 1. In the Openflow runtime canvas, right-click a processor group and choose **Controller Services**. 2. In the table listing controller services, locate the **Table State Store** row, click the three vertical dots on the right side of the row, then choose **View State**. You must wait until the table's state is fully removed from this list before proceeding. Don't continue until this configuration change has completed. 3. Wait until all queues in the connector are empty before you re-add the table. When all FlowFiles have been processed, the **Queued** value on the connector's processor group becomes zero. Don't re-add the table while change events that were captured before you removed it are still queued. When you re-add a table, the connector loads the new snapshot in append-only mode, so any leftover change event that merges into the table after the re-snapshot might create duplicate rows in the destination table. 4. Re-add the table by reversing the change you made in the first step: either remove the table from **Re-snapshot Table Exclusions**, or add it back to **Included Table Names** or **Included Table Regex**. You do not need to drop the destination table first. The connector re-snapshots the table in place: it makes a zero-copy [clone](/sql-reference/sql/create-clone) of the current destination table to an archive table named `_ARCHIVE_`, clears the destination table, and then loads the fresh snapshot into the same destination table. Because the destination table object is preserved, dependent objects such as streams remain attached and continue to work. The archive table retains a copy of the destination table's contents from immediately before the reload, as a safeguard. The connector does not read from or write to it again, so you can drop it at any time once the backup is no longer needed, typically after you confirm that the re-snapshot completed and the destination data is correct. 5. Verify the restart: Check the **Table State Store** using the instructions given previously. The state of the table should appear with the status NEW, then transition to SNAPSHOT_REPLICATION, and finally to INCREMENTAL_REPLICATION. ## Increase the oversized value limit By default, the connector replicates individual values up to 16 MB and marks any table that contains a larger value as permanently failed. If your Snowflake account has the `ENABLE_OPENFLOW_CDC_MYSQL_SSV2` parameter set to `true`, the per-value limit can be raised from 16 MB to **128 MB**. The 128 MB limit applies in two ways: it's both the maximum size of a single value and the maximum total size of a row. The connector adds metadata columns to every replicated row (`_SNOWFLAKE_UPDATED_AT`, `_SNOWFLAKE_INSERTED_AT`, `_SNOWFLAKE_DELETED`) that count toward the per-row limit, along with all other columns in the row. As a result, a single value can't reach the full 128 MB in practice when the row includes other data. The increased limit doesn't apply equally to all column types. In Snowflake, the maximum size for `BINARY` is **64 MB** (`BINARY(67108864)`), even when the increased size limits are enabled. Only `VARCHAR`, `VARIANT`, `ARRAY`, and `OBJECT` columns can hold up to 128 MB. ### Check whether the 128 MB limit is available You may not be able to verify the `ENABLE_OPENFLOW_CDC_MYSQL_SSV2` parameter value by querying it. To check if it is enabled, see if the FlowFiles flow through the **Upload Rows via Snowpipe Streaming 2** processor (not through **Upload Rows via Snowpipe Streaming**). ### Configure the processors Update the **Oversized Value Limit** property to `128 MB` on both of the following processors: - **Fetch Table Rows** (in the **Snapshot Load** group) - **Read MySQL CDC Stream** (in the **Incremental Load** group) For each processor: 1. Locate the processor in the flow. On the connector canvas, you can use the search box in the top-right corner to find processors by name. 2. Right-click the processor and select **Configure**. 3. Open the **Properties** tab. 4. Set **Oversized Value Limit** to `128 MB`. 5. Apply the change. For tables that are already being replicated and have destination columns narrower than `VARCHAR(134217728)` or `BINARY(67108864)`, see [](#label-of-mysql-migrate-oversized-value-tables). ### Migrate existing tables The steps in [](#label-of-mysql-increase-oversized-value-limit) raise the limit for newly created destination tables. If a table is already being replicated and its destination column type is **not** `VARCHAR(134217728)` or `BINARY(67108864)`, but you now want to load values larger than the original 16 MB limit, you must manually widen the column type on **both** the journal and destination tables. Before you migrate, check the current destination column type, because it can vary depending on when the snapshot replication was performed. You must stop replication for the affected table before altering its journal or destination tables. Altering these tables while replication is active can corrupt in-flight data. To migrate a table: 1. Stop replication for the affected table by stopping the topmost processors of the **Snapshot Load** and **Incremental Load** groups until all queues are empty. For the equivalent stop procedure, see the substeps of [](#label-mysql-reinstall-connector). 2. Widen the column on both the journal table and the destination table, according to the column type: 1. **VARCHAR columns**: a single `ALTER TABLE ... ALTER COLUMN ... SET DATA TYPE VARCHAR(134217728)` is sufficient on both the journal and destination tables. 2. **BINARY columns**: Snowflake doesn't allow widening `BINARY` in place. You must: 1. Add a new column of type `BINARY(67108864)` on both the journal and destination tables. 2. Copy data from the original column into the new column. 3. Drop the original column and rename the new column to the original name. 3. Restart replication by re-enabling the processors. ### Performance considerations Raising the per-value limit increases the amount of data that the connector loads into memory and moves through the flow, which raises the load on both the runtime and the warehouse. Size the runtime and warehouse accordingly. During both snapshot and incremental replication, the queue in front of the **Upload Rows via Snowpipe Streaming 2** processor can fill with FlowFiles and trigger back pressure, which consumes a large amount of runtime disk space. For larger tables, use a Large runtime to provide additional storage. For guidance on choosing a size, see [Runtime sizing](/user-guide/data-integration/openflow/connectors/cdc-runtime-sizing#label-openflow-cdc-runtime-sizing). #### Snapshot replication During snapshot replication, the product of `fetchSize * rowSize * concurrentQueries` can't exceed the heap size of the NiFi runtime, where: - `fetchSize` is the number of rows fetched per query, set on the **Fetch Table Rows** processor (default: 100). - `rowSize` is the size of a single row being fetched. - `concurrentQueries` is the number of concurrent queries, set on the **Fetch Table Rows** processor (default: 2). This memory requirement applies even when **Oversized Value Strategy** is set to **Set Null**, because the connector must load each oversized value into memory before it can replace the value with `NULL`. If the source database contains many densely packed oversized values, consider excluding the affected column from replication before you start the snapshot. For example, if a column contains 1 GB values, loading even nine rows (~9 GB) can exhaust the heap and cause an out-of-memory error on a Medium runtime. To speed up snapshot replication, you can increase the number of channels that the **Upload Rows via Snowpipe Streaming 2** processor uses. The number of channels is set by the processor's **Channel Group** property, which defaults to `${chunk.index:isEmpty():ifElse('1', ${chunk.index:mod(8)})}`. To increase the number of channels: 1. Locate the **Upload Rows via Snowpipe Streaming 2** processor in the flow. 2. Stop the processor. You must stop the processor before you can change its properties. 3. Right-click the processor and select **Configure**. 4. Open the **Properties** tab. 5. In the **Channel Group** property, increase the value `8` in the expression. For example, change `8` to `16` to double the number of channels. 6. Apply the change. 7. Start the processor. While a snapshot replication is in progress, only increase the number of channels. Decreasing the number of channels during an active snapshot can cause data loss. #### Incremental replication When the source produces frequent changes to rows that contain large values, you might need a Large warehouse. With smaller warehouses, replicating many 8 MB rows can cause an out-of-memory error. By contrast, replicating 128 MB rows with continuous merges completes without warehouse errors, because the connector streams the data file by file through the **Upload Rows via Snowpipe Streaming 2** processor and the merge processes it gradually. Incremental replication is also subject to the MySQL transaction size limitation: a single transaction must fit into a binary log message of no more than 4 GB. For more information, see [Limitations](/user-guide/data-integration/openflow/connectors/mysql/about#limitations). ## Enable error logging on an existing schema When you set the **Error Handling Strategy** parameter to **Log Errors and Continue**, the connector enables error logging automatically only on tables that it creates afterward. Tables that the connector created earlier don't capture rejected rows until you turn on error logging for them. For more information about the error-handling strategies, see [](/user-guide/data-integration/openflow/connectors/mysql/about#label-mysql-error-handling). Because the connector stores journal tables in the same schema as the destination tables, you can turn on error logging for a whole destination schema at once. Run the following stored procedure once per destination schema. Replace `my_database` with your destination database and `my_schema` with the destination schema. The schema name is passed as a quoted identifier (for example, `'"my_schema"'`) so it matches the exact, case-sensitive name that the connector created. For more information about how the connector names destination schemas, see [](/user-guide/data-integration/openflow/connectors/mysql/setup#label-of-mysql-destination-parameters). ```sql USE DATABASE my_database; WITH enable_error_logging AS PROCEDURE (schema_name STRING) RETURNS STRING LANGUAGE SQL AS $$ DECLARE tables RESULTSET; table_count NUMBER DEFAULT 0; BEGIN SHOW TABLES IN SCHEMA IDENTIFIER(:schema_name); -- Assign AFTER SHOW TABLES so LAST_QUERY_ID() refers to that result tables := ( SELECT "database_name", "schema_name", "name" FROM TABLE(RESULT_SCAN(LAST_QUERY_ID())) WHERE "kind" = 'TABLE' ); FOR t IN tables DO -- Double-quote each identifier so names with special characters are handled safely EXECUTE IMMEDIATE 'ALTER TABLE "' || REPLACE(t."database_name", '"', '""') || '".' || '"' || REPLACE(t."schema_name", '"', '""') || '".' || '"' || REPLACE(t."name", '"', '""') || '" ' || 'SET ERROR_LOGGING = TRUE'; table_count := table_count + 1; END FOR; RETURN 'Enabled ERROR_LOGGING on ' || table_count || ' table(s) in schema ' || :schema_name; END; $$ CALL enable_error_logging('"my_schema"'); ``` ### Verify that error logging is enabled To confirm that error logging is enabled on every table in a schema, run the following procedure. It reports how many tables have error logging enabled and how many don't. ```sql USE DATABASE my_database; WITH verify_error_logging AS PROCEDURE (schema_name STRING) RETURNS STRING LANGUAGE SQL AS $$ DECLARE tables RESULTSET; probe RESULTSET; total_tables NUMBER DEFAULT 0; logging_enabled NUMBER DEFAULT 0; disabled_or_invisible NUMBER DEFAULT 0; BEGIN SHOW TABLES IN SCHEMA IDENTIFIER(:schema_name); -- Assign AFTER SHOW TABLES so LAST_QUERY_ID() refers to that result tables := ( SELECT "database_name", "schema_name", "name" FROM TABLE(RESULT_SCAN(LAST_QUERY_ID())) WHERE "kind" = 'TABLE' ); FOR t IN tables DO total_tables := total_tables + 1; -- Probe ERROR_TABLE(): it succeeds only when error logging is enabled and visible BEGIN probe := ( EXECUTE IMMEDIATE 'SELECT 1 FROM ERROR_TABLE(' || '"' || REPLACE(t."database_name", '"', '""') || '".' || '"' || REPLACE(t."schema_name", '"', '""') || '".' || '"' || REPLACE(t."name", '"', '""') || '"' || ') LIMIT 1' ); logging_enabled := logging_enabled + 1; EXCEPTION WHEN STATEMENT_ERROR THEN disabled_or_invisible := disabled_or_invisible + 1; END; END FOR; RETURN 'schema=' || :schema_name || ', total_tables=' || total_tables || ', error_logging_enabled=' || logging_enabled || ', error_logging_disabled_or_not_visible=' || disabled_or_invisible; END; $$ CALL verify_error_logging('"my_schema"'); ``` ## Reclaim journal table storage Journal tables hold every change to a replicated table. The connector never drops them, but it only reads the latest journal for each replicated source table, using append-only streams on top of the journals. To reclaim storage, you can: - Truncate all journal tables at any time. - Drop the journal tables related to source tables that were removed from replication. - Drop all but the latest generation journal tables for actively replicated tables. For example, if your connector is set to actively replicate source table `orders`, and you have earlier removed table `customers` from replication, you may have the following journal tables. In this case you can drop all of them *except* `orders_5678_2`. ```text customers_1234_1 customers_1234_2 orders_5678_1 orders_5678_2 ``` ## Reinstall the connector This section provides instructions on how to reinstall the connector, and continue replicating data for the same tables without having to snapshot them again. It covers situations where the new connector is installed in the same runtime, as well as those where it's moved to a new runtime. For the connector to continue replicating from the same CDC stream position where it stopped before reinstallation, the source database must retain the binary log long enough to cover the time since the prior connector was stopped and the new connector is started. Make sure the `binlog_expire_logs_seconds` parameter of the MySQL server is high enough, and keep the reinstallation time to a minimum. The value of `binlog_expire_logs_seconds` needs to be longer than the expected time to reinstall the connector. Typically 86400s, a day in seconds, is sufficient; however, longer times might be appropriate to ensure time to reinstall. ### Prerequisites Review and note connector parameter context values. If you're reinstalling the connector in the same runtime, you can reuse the existing context. If the new instance is located in a different runtime, you must re-enter all parameters. 1. Finish processing all in-flight FlowFiles in the existing connector, then stop the connector. 1. Sign in to %sf-web-interface-link%. 2. In the navigation menu, select **Ingestion** %raa% **Openflow**. 3. Select **Launch Openflow**. 4. In the **Openflow** pane, select the **Runtimes** tab. 5. Select the runtime containing the connector. 6. Select the connector. 7. Stop the topmost processor **Set Tables for Replication** in the **Snapshot Load** group. 8. Stop the topmost processor **Read MySQL CDC Stream** in the **Incremental Load** group. 9. If you changed the value of the **Merge Task Schedule CRON** parameter, return it to `* * * * * ?`, otherwise queues won't be emptied until the next scheduled run. Wait until all FlowFiles in the connector have been processed, and all queues are empty. When all FlowFiles have been processed, the **Queued** value on the connector's processor group becomes zero. If there are any items left in the original connector's queues, there may be data gaps when the new connector starts. 10. Stop all processors and controller services in the connector. The existing connector can remain in the runtime and doesn't interfere with the new instance, as long as it remains stopped. 2. If you're moving the connector to a new runtime, download the flow definition from the existing connector so that you can recreate the connector with its current state instead of configuring it from scratch. Downloading a flow definition requires Openflow Runtime Server version 2026.6.4.18 or later. 1. Right-click the connector's process group, then select **Download flow definition**. 2. Select both of the following options, then download the flow definition: - **Export with External Services**: includes the controller services that the connector references from parent process groups. - **Export with Components State**: includes component state, such as binary log positions and incremental replication state, so that replication continues from where it left off. 3. Create the connector in the target runtime: - If you downloaded the flow definition, import it into the new runtime. Importing the flow definition preserves the component state captured during the export, so the connector resumes incremental replication from its previous positions. - Otherwise, create a new instance of the connector. If you're using the same runtime as the original connector, you can choose to keep the existing parameter contexts and reuse the settings. 4. If you're installing into a different runtime or you deleted the previous parameter contexts, enter the configuration settings into the new parameter contexts, including the table names and patterns as described in [Set up the Openflow Connector for MySQL](/user-guide/data-integration/openflow/connectors/mysql/setup). A downloaded flow definition doesn't include sensitive values, such as passwords, so you must re-enter them. 5. Navigate to the `MySQL Ingestion Parameters` context, and set the following parameters: - Set the `Ingestion Type` parameter to `incremental`. For more information on the concerns, see [](#label-mysql-incremental-replication). - Set the `Starting Binlog Position` parameter to `Earliest`. For more information and potential concerns, see [](#label-mysql-connector-start-restart-incremental-load-from-earliest-available-binary-log-position). If you imported the flow definition with **Export with Components State** selected, the connector retains its previous binary log positions. In this case, leave `Starting Binlog Position` set to `Latest` to continue replication from where it stopped. 6. Start the new connector. ### Usage notes The new connector uses the existing destination tables that were created by the original connector, but the connector creates new journal tables. ## Specify load from binary log position The %mysql% connector allows you to select the starting position where MySQL binary logs are read. By default, the connector reads from the latest available position. Alternatively, you can choose the earliest position available on the source instance. Choosing to start from the earliest position is common when reinstalling the connector. This allows the new instance to catch up and continue replicating existing tables without having to snapshot each again. Note that switching a running connector from latest to earliest position causes the entire available binary log to be re-read, re-processed, and re-applied to the destination table. While the binary log is being re-read, the columns and data in affected destination tables can become out of sync with their sources until all events have been re-processed and merged. The following parameters that control snapshot loads are available in the `Ingestion Parameters` context:
To determine whether the connector finished re-reading the binary log: 1. Navigate to the Openflow canvas. 2. Open the **Incremental Load** process group. 3. Right-click the topmost processor named **Read MySQL CDC Stream**, then select **View state**. 4. Compare the state entries: - **binlog.position.rewind**: the latest position the processor read before re-reading of the binary log started. - **binlog.position.dml**: the current latest position read by the processor. As long as this value is lower than the rewind value above, the processor is still re-reading the binary log. ### Usage notes - After a running connector is switched to read from the earliest position, and starts running, the process can't be reconfigured or canceled, and will continue until the currently-read position reaches the position from before it started. - Switching to the earliest position on a running connector will, for any tables being re-processed, finish their existing journals, and create new journal tables. - If the binary log contains events from a previous table that was dropped and re-created in the source database, re-reading the stream re-processes all events in the current destination. The connector can't distinguish between a previous and current source table if they share the same name. --- title: Openflow Connector for MySQL: Set up incremental replication without snapshots source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/mysql/incremental-replication.md section: Loading & Unloading Data --- # %mysql%: Set up incremental replication without snapshots This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Set up the Openflow Connector for MySQL](/user-guide/data-integration/openflow/connectors/mysql/setup) - [Openflow Connector for MySQL: Data mapping](/user-guide/data-integration/openflow/connectors/mysql/data-mapping) You can configure the %mysql% connector to immediately replicate incremental changes for newly added tables, bypassing snapshots. Use incremental load to continue replication without snapshotting every table again when you reinstall the connector over previously replicated data. To enable incremental replication in a new connector instance: 1. Set up the connector as described in [Set up the Openflow Connector for MySQL](/user-guide/data-integration/openflow/connectors/mysql/setup). 2. In the `MySQL Ingestion Parameters` context, set the `Ingestion Type` parameter to `incremental`. ## Enable incremental replication without snapshots To enable incremental replication on an existing connector: 1. sign in to %sf-web-interface-link%. 2. in the navigation menu, select **Ingestion** %raa% **Openflow**. 3. In the **Openflow** pane select the **Runtimes** tab. 4. Select the runtime containing the connector. 5. Select the connector. 6. In the `Ingestion Parameters` context, specify `Ingestion Type` = `incremental`. 7. Add new replication tables. These tables immediately switch to their incremental load. To return to replicating tables with the snapshot load, change **Ingestion Type** from `incremental` to `full`. # Usage notes - Changing the value of **Ingestion Type** does not impact any tables that have begun replicating data. Tables currently in the snapshot phase continue until the snapshot load is complete. - While **Ingestion Type** is set to `incremental`, new tables added to the list of replicated tables bypass the snapshot phase. This includes new tables added to the source database that match the `Included Table Regex` parameter. Ensure that the ingestion type is set to `incremental` to bypass the snapshot phase. Connectors should only remain in `incremental` mode as long as required as it bypasses snapshots. Once customer needs for incremental updates have been satisfied the connector should be returned to `full` mode. - For tables that bypass snapshot load, the connector creates a destination table in Snowflake, by executing `CREATE TABLE IF NOT EXISTS`, only if no destination table already exists. Tables going through the snapshot require that no destination table exist. ## Recover a table using incremental-only mode If a table's snapshot completed successfully but incremental replication later failed, you don't need to remove the table and snapshot it again. Instead, you can recover the table by replaying the changes that are still available in the source binary logs (binlog) and merging them onto the existing destination table. Incremental replication can fail for several reasons, for example: - A record in the source database can't be read because it has an incorrect or unsupported format. - A row exceeds the maximum supported size. - A merge operation can't complete. - A transient error persists through so many retries that the table enters the FAILED state. To recover the table without a new snapshot, remove it from replication, switch the connector to incremental-only mode reading from the earliest available position, and add the table back. The connector reads all available changes from the oldest available binary log position, then replays and reapplies them to the destination table. Before you recover the table, address the underlying cause of the failure. Otherwise, the connector encounters the same error again when it replays the changes. For example, raise the per-value limit (see [Increase the oversized value limit](/user-guide/data-integration/openflow/connectors/mysql/maintenance#label-of-mysql-increase-oversized-value-limit)) or fix the problematic record in the source database. To recover the table: 1. Remove the table from replication. In the `Ingestion Parameters` context, remove the table from **Included Table Names**, or modify **Included Table Regex** so the table is no longer matched. Wait until the table's state is fully removed from the **Table State Store** controller service before you continue. Don't drop the destination table. This procedure reuses the existing destination table and replays incremental changes onto it. 2. Stop the connector's process group so that you can change its configuration. On the connector canvas, right-click the connector's process group and select **Stop**. 3. In the `Ingestion Parameters` context, set the `Ingestion Type` parameter to `incremental`. 4. Set the `Starting Binlog Position` parameter to `Earliest`. The connector reads all available changes again from the oldest available binary log position, then replays and reapplies them to the destination table. For more information, see [Specify load from binary log position](/user-guide/data-integration/openflow/connectors/mysql/maintenance#label-mysql-connector-start-restart-incremental-load-from-earliest-available-binary-log-position). Leave `Re-read Tables in State` at its default value, `New`, so that only the table you add back reads from the earliest position. Tables already in replication continue from their last positions. 5. Add the table back to replication by reversing the change you made in step 1. 6. Start the connector's process group. Right-click the connector's process group and select **Start**. 7. Wait until the table returns to incremental replication. In the **Table State Store** controller service state, the table transitions to INCREMENTAL_REPLICATION when recovery completes. 8. Revert the changes you made in steps 3 and 4: set `Ingestion Type` and `Starting Binlog Position` back to their previous values. This procedure recovers only the changes still retained in the source binary logs. If the binary log retention period expired and some changes were purged, the recovered table can have gaps. In that case, you must take a new snapshot to fully resynchronize the table. --- title: Openflow Connector for Oracle: Configure the Oracle database source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/oracle/setup-oracledb.md section: Loading & Unloading Data --- # %oracleofc%: Configure the Oracle database This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). The %oracleofc% is also subject to additional terms of service beyond the standard connector terms of service. For more information, see the [Openflow Connector for Oracle Addendum](https://www.snowflake.cn/en/legal/optional-offerings/offering-specific-terms/openflow-oracle-terms/). - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [About Openflow Connector for Oracle](/user-guide/data-integration/openflow/connectors/oracle/about) - [Openflow Connector for Oracle: Enable and manage commercial terms](/user-guide/data-integration/openflow/connectors/oracle/manage-commercial-terms) - [Set up tasks for the Openflow Connector for Oracle](/user-guide/data-integration/openflow/connectors/oracle/setup-tasks) - [Openflow Connector for Oracle: Set up Snowflake](/user-guide/data-integration/openflow/connectors/oracle/setup-snowflake) This topic describes how to set up the Oracle database for %oracleofc%. Your Oracle database setup depends on your organization's security policies and database architecture. For example, if tables reside in a Container Database (CDB), a Pluggable Database (PDB), multiple PDBs, or a combination. The steps provided in this topic are examples only. Modify them as required for your environment. As an Oracle database administrator, perform the following procedures on your source database: 1. [](#label-set-up-archived-redo-logs-retention-period) 2. [](#label-enable-xstream-and-supplemental-logging) 3. [](#label-create-xstream-administrator-user) 4. [](#label-granting-xstream-administrator-privileges) 5. [](#label-configure-xstream-server-connect-user) 6. [](#label-create-xstream-outbound-server) 7. [](#label-set-xstream-outbound-server-connect-user) 8. [](#label-set-xstream-outbound-server-capture-user) 9. (Optional) [](#label-oracle-standby-setup) 10. (Optional) [](#label-configure-ssl-connections) The steps in this topic are written for a multi-tenant architecture with a Container Database (CDB) and one or more Pluggable Databases (PDB). If your Oracle database uses a single-tenant architecture, see [](#label-setup-xstream-single-tenant). ## Configure the retention period for archived redo logs You must enable the `ARCHIVELOG` mode to ensure that change data is available for replication. If you use AWS RDS for Oracle, you must also configure the retention period for archived redo logs. Determine this period based on the volume of changes in the source database and your storage capacity. To set the retention period, for example to 24 hours, follow the procedures in the following table:
## Enable XStream and supplemental logging XStream is included with Oracle Database and doesn't require any additional software. To enable and configure XStream replication to capture and stream change data, run the following commands: 1. Enable XStream replication: ```sql ALTER SYSTEM SET enable_goldengate_replication=TRUE SCOPE=BOTH; ALTER SYSTEM SET STREAMS_POOL_SIZE = 2560M; ``` Snowflake recommends setting the streams pool size to 2.5 GB. This allocation covers the following: - 1 GB for Capture - 1 GB for Apply - An additional 25% buffer To enable supplemental logging to ensure that the redo logs capture the information required for logical replication, run the following commands: 1. Confirm that the database is in ARCHIVELOG mode as shown in the following example: ```sql SELECT LOG_MODE, FORCE_LOGGING FROM V$DATABASE; ``` Snowflake recommends forcing logging at the database or tablespace level. 2. Set the container to the root container and add supplemental logging to the database: ```sql ALTER SESSION SET CONTAINER = CDB$ROOT; ALTER DATABASE ADD SUPPLEMENTAL LOG DATA (ALL) COLUMNS; ``` Alternatively, you can enable logging only on specific tables as shown in the following example: ```sql ALTER TABLE schema_name.table_name ADD SUPPLEMENTAL LOG DATA (ALL) COLUMNS; ``` ## Create the XStream administrator user An XStream administrator user is required to manage XStream components, including the creation and alteration of outbound servers. You can either create a dedicated user for this purpose or use an existing user, provided that the necessary XStream administration privileges are granted (see the next section). The following example details the setup of a dedicated XStream administrator user in the root container of a CDB. The following example assumes that the database also has a PDB containing tables to be replicated. Connect as SYSDBA or a user with appropriate privileges and run the following commands: ```sql -- Switch to the root container. ALTER SESSION SET CONTAINER = CDB$ROOT; -- Create a tablespace for the XStream administrator user. CREATE TABLESPACE xstream_adm_tbs DATAFILE '/path/to/your/cdb/xstream_adm_tbs.dbf' SIZE 25M REUSE AUTOEXTEND ON MAXSIZE UNLIMITED; -- Switch to the Pluggable Database (PDB) and create a tablespace there. ALTER SESSION SET CONTAINER = YOUR_PDB_NAME; CREATE TABLESPACE xstream_adm_tbs DATAFILE '/path/to/your/pdb/xstream_adm_tbs.dbf' SIZE 25M REUSE AUTOEXTEND ON MAXSIZE UNLIMITED; -- Switch back to the root container to create the common user. ALTER SESSION SET CONTAINER = CDB$ROOT; -- Create the XStream administrator user. -- Note: the 'c##' prefix indicates a common user in a CDB environment, and CONTAINER=ALL grants privileges across all containers. -- Replace "YOUR_XSTREAM_ADMIN_PASSWORD" with a strong, secure password. CREATE USER c##xstreamadmin IDENTIFIED BY "YOUR_XSTREAM_ADMIN_PASSWORD" DEFAULT TABLESPACE xstream_adm_tbs QUOTA UNLIMITED ON xstream_adm_tbs CONTAINER=ALL; ``` ## Grant XStream administrator privileges Connect as SYSDBA or a user with appropriate privileges and grant the required privileges to the XStream administrator user. 1. Grant the CREATE SESSION privilege to the XStream administrator: ```sql GRANT CREATE SESSION TO c##xstreamadmin CONTAINER=ALL; ``` 2. Grant XStream capture privileges using one of the following commands, depending on your Oracle Database version:
## Configure XStream server connect user The Snowflake Openflow Connector uses a dedicated connect user to establish a connection to the XStream Outbound Server and receive change data. This user requires specific privileges to facilitate replication: - **Read from XStream Outbound Server**: The user must be able to access the change data stream from the configured XStream Outbound Server. - **Select from Data Dictionary Views**: The connect user needs SELECT access to various data dictionary views. This can be achieved by granting SELECT_CATALOG_ROLE or SELECT ANY DICTIONARY. If granting SELECT ANY DICTIONARY isn't desired due to company policy, the user specifically needs SELECT access to the following views: - ALL_USERS - ALL_TABLES - ALL_TAB_COLS - ALL_CONS_COLUMNS - ALL_CONSTRAINTS - ALL_INDEXES - ALL_IND_COLUMNS - V$DATABASE If you're replicating data from multiple PDBs, also grant SELECT access to: - V$CONTAINERS - V$PARAMETER - CDB_TABLES - CDB_USERS `ALL_INDEXES` and `ALL_IND_COLUMNS` are required so the connector can detect unique constraints and unique indexes as replication keys when a table has no primary key. For more information on the selection algorithm, see [](#label-oracle-replication-key-selection). - **Select from Source Tables**: The user must have SELECT privileges on all tables that are intended for replication. The following is an example of how to set up such a user in the root container of the CDB. The example assumes that the database also has a PDB containing tables to be replicated. ```sql -- Connect as SYSDBA or a user with appropriate privileges -- Switch to the root container. ALTER SESSION SET CONTAINER = CDB$ROOT; -- Create the connect user. -- Replace "YOUR_CAPTURE_USER_PASSWORD" with a strong, secure password. CREATE USER c##connectuser IDENTIFIED BY "YOUR_CAPTURE_USER_PASSWORD" CONTAINER=ALL; -- Grant necessary privileges to the connect user. -- You can choose to grant access to specific tables -- instead of SELECT ANY TABLE for more granular control, -- for example, GRANT SELECT ON schema.table TO c##connectuser; GRANT CREATE SESSION, SELECT_CATALOG_ROLE, SELECT ANY TABLE TO c##connectuser CONTAINER=ALL; ``` If your database is multi-tenant and the connector is connected to a CDB to replicate data from multiple PDBs, grant the connect user the additional privileges needed to switch between containers and read data dictionary information across all of them: ```sql ALTER USER c##connectuser SET CONTAINER_DATA = ALL CONTAINER = CURRENT; GRANT SET CONTAINER TO c##connectuser CONTAINER=ALL; ``` If you granted SELECT on individual data dictionary views instead of SELECT_CATALOG_ROLE or SELECT ANY DICTIONARY, also grant SELECT on `V$CONTAINERS`, `V$PARAMETER`, `CDB_TABLES`, and `CDB_USERS`. ## Create XStream Outbound Server The XStream Outbound Server captures changes from redo logs for consumption by the Openflow Connector. Define which schemas or tables to replicate. For more information, see DBMS_XSTREAM_ADM.CREATE_OUTBOUND Documentation (https://docs.oracle.com/en/database/oracle/oracle-database/19/arpls/DBMS_XSTREAM_ADM.html#GUID-A602ED86-0F5A-4A27-92A0-55D5ADC0AF0D). Create the outbound server on a writable database: the primary, a logical standby, or a downstream capture database. You can't create it on an Active Data Guard physical standby. For supported standby topologies, see [](/user-guide/data-integration/openflow/connectors/oracle/about#label-oracle-standby-data-guard-support) and [](#label-oracle-standby-setup). Important considerations for replication scope: - If a table is included in the XStream Outbound filtering rules command, it won't be replicated. - A table or schema included here must also be defined in the connector parameters for it to be replicated. You can include an entire schema in the server filtering rules and later, in the connector parameters, specify only certain tables within that schema for replication. The XStream Outbound Server can only be created from the root container. However, starting with Oracle Database version 23ai, it can also be created on the PDB level. To avoid a significant hit to your CPU and network, and to prevent your queues from being filled with irrelevant data, it's essential to use a granular approach. The best way to do this is with the DBMS_XSTREAM_ADM.ADD_TABLE_RULES procedure, which lets you choose only the specific tables you need. The following examples show how to set up the XStream Outbound Server based on different replication needs. In practice, when setting up your XStream Outbound Server on your production environment, you should be selective about what changes you capture. Capturing everything can have serious consequences for your database's performance and resource usage. For information on how to configure XStream Outbound Server, see Configuring XStream Out (https://docs.oracle.com/en/database/oracle/oracle-database/19/xstrm/configuring-xstream-out.html#GUID-A1C8430E-565B-4F66-8E00-495F283AAAFB). **Example 1:** Capture all tables from all schemas in the root container and all PDBs ```sql -- Connect as a user with XStream admin privileges to the root container. -- Ensure serveroutput is enabled to see messages from the PL/SQL block. SET SERVEROUTPUT ON; DECLARE tables DBMS_UTILITY.UNCL_ARRAY; schemas DBMS_UTILITY.UNCL_ARRAY; BEGIN -- To replicate all tables in all schemas across all containers, set both to NULL. tables(1) := NULL; schemas(1) := NULL; DBMS_XSTREAM_ADM.CREATE_OUTBOUND( server_name => 'XOUT1', table_names => tables, schema_names => schemas, include_ddl => TRUE ); DBMS_OUTPUT.PUT_LINE('XStream Outbound Server created.'); EXCEPTION WHEN OTHERS THEN DBMS_OUTPUT.PUT_LINE('Error creating XStream Outbound Server: ' || SQLERRM); RAISE; END; / ``` **Example 2:** Capture all tables from a single schema in a Pluggable Database (PDB) ```sql -- Connect as a user with XStream admin privileges to the root container. -- Ensure serveroutput is enabled to see messages from the PL/SQL block. SET SERVEROUTPUT ON; DECLARE tables DBMS_UTILITY.UNCL_ARRAY; schemas DBMS_UTILITY.UNCL_ARRAY; BEGIN -- To replicate all tables in a schema in the single PDB, set source_container_name. tables(1) := NULL; schemas(1) := 'schema_name'; DBMS_XSTREAM_ADM.CREATE_OUTBOUND( server_name => 'XOUT1', table_names => tables, schema_names => schemas, include_ddl => TRUE, source_container_name => 'YOUR_PDB_NAME' ); DBMS_OUTPUT.PUT_LINE('XStream Outbound Server created.'); EXCEPTION WHEN OTHERS THEN DBMS_OUTPUT.PUT_LINE('Error creating XStream Outbound Server: ' || SQLERRM); RAISE; END; / ``` ## Set up the XStream Outbound Server Connect User Set the connect user on the XStream Outbound Server. This ensures that the previously created connect user is associated with the XStream Outbound Server (XOUT1), allowing it to receive change data. The following example assumes that the connect user is c##connectuser. ```sql BEGIN DBMS_XSTREAM_ADM.ALTER_OUTBOUND( server_name => 'XOUT1', connect_user => 'c##connectuser'); END; / ``` ## Set up the XStream Outbound Server Capture User If you want the data to be captured by the same user that created the server (the administrator), skip this section. If you configured a separate capture user, configure the XStream Outbound Server to run as this user. This ensures that the dedicated capture user is associated with the XStream Outbound Server (XOUT1), allowing that user to capture change data. ```sql BEGIN DBMS_XSTREAM_ADM.ALTER_OUTBOUND( server_name => 'XOUT1', capture_user => 'yourcaptureuser'); END; / ``` ## Set up XStream for single-tenant databases The default architecture for Oracle 12c and later is a multi-tenant architecture with a Container Database (CDB) and one or more Pluggable Databases (PDB). Oracle 11g uses a single-tenant (non-CDB) architecture. If your Oracle database uses a single-tenant architecture, note the following differences in setting up XStream: - Do not use `ALTER SESSION SET CONTAINER` commands. In a single-tenant database, there is only one instance, so container switching doesn't apply. - Create only one `xstream_adm_tbs` tablespace. Do not create a second tablespace in a PDB. - Do not use the `C##` prefix on user names. For example, create `xstreamadmin` instead of `c##xstreamadmin` and `connectuser` instead of `c##connectuser`. The `C##` prefix is required only in multi-tenant environments. - Do not include `CONTAINER=ALL` or `container => 'ALL'` in any commands. These clauses grant privileges across multiple containers and don't apply in a single-tenant database. ## Data Guard or standby capture (optional) By default, the procedures in this topic create the XStream outbound server on the primary (source) database. If you want to keep replication load off the primary, review [](/user-guide/data-integration/openflow/connectors/oracle/about#label-oracle-standby-data-guard-support) and choose a supported topology before you create the outbound server. ### Logical standby requirements On a logical standby, create the XStream outbound server and connect the connector to that standby the same way you would for a primary. Before you create the outbound server or start the connector, set Database Guard to `STANDBY`. Logical standbys default to Database Guard `ALL`, which blocks the XStream client from reading the outbound server and raises `ORA-16224: Database Guard is enabled`. 1. Check the current guard status: ```sql SELECT guard_status FROM v$database; ``` 2. If the result is `ALL`, set Database Guard to `STANDBY`: ```sql ALTER DATABASE GUARD STANDBY; ``` Then complete the XStream setup procedures in this topic on the logical standby, and point the connector's Oracle connection URL and XStream Out Server URL at that standby. ### Active Data Guard requirements for snapshot load You can run the connector's snapshot load against an Active Data Guard physical standby to avoid reading application tables on the primary. Because the standby is read-only: - Set **Snapshot Fetching Strategy** to `SEQUENTIAL_BY_PRIMARY_KEY` in the connector parameters. `CONCURRENT_BY_ROWID` requires creating a parallel task, which isn't allowed on a read-only standby. - Don't create the XStream outbound server on the Active Data Guard standby. For CDC, create it on the primary, a logical standby, or a downstream capture database instead. Point the connector's Oracle connection URL at the Active Data Guard standby for snapshot reads. Point the XStream Out Server URL at the writable database that hosts the outbound server (for example, the primary or a downstream capture database). ### Downstream capture for CDC To run CDC off the primary, configure Oracle downstream capture so that a separate database receives redo from the primary, then create the XStream outbound server on that downstream database by using the procedures in this topic. Downstream capture provides redo only. It can't serve snapshot queries. If you also need an initial snapshot without reading the primary, combine Active Data Guard for the snapshot with downstream capture for CDC, or use a logical standby for both stages. For Oracle's downstream capture concepts and setup, see XStream Out Concepts (https://docs.oracle.com/en/database/oracle/oracle-database/19/xstrm/xstream-out-concepts.html) in the Oracle documentation. ## Configure SSL connections (optional) The %oracleofc% supports encrypted SSL connections to the Oracle database using the TCPS (TCP with SSL) protocol. When SSL is enabled, both the database connection and the XStream connection use encrypted communication. To use SSL, you must: 1. [](#label-enable-tcps-on-oracle-database) 2. [](#label-create-client-wallet) ### Enable TCPS on the Oracle database You must configure the Oracle database to accept connections using the TCPS protocol. Follow the procedure for your database environment. #### On-premises / OCI 1. Create an SSL server wallet with the server certificate. 2. Configure the `listener.ora` to include a TCPS endpoint (default port 2484). 3. Configure the `sqlnet.ora` to reference the server wallet. 4. Restart the listener. For more information, see Configuring Transport Layer Security Encryption (https://docs.oracle.com/en/database/oracle/oracle-database/23/dbseg/configuring-transport-layer-security-encryption.html). #### AWS RDS (Standard) 1. Add the Oracle SSL option to the option group associated with the DB instance. 2. Specify the SSL port (for example, 2484). For more information, see Oracle Secure Sockets Layer (https://docs.aws.amazon.com/AmazonRDS/latest/UserGuide/Appendix.Oracle.Options.SSL.html). ### Create a client wallet After TCPS is enabled on the database, create an Oracle auto-login wallet (`cwallet.sso`) containing the server's trusted certificate. This wallet is provided to the connector so that it can verify the server during the SSL handshake. 1. Export the server certificate from the Oracle database server as a PEM file. 2. Use the Oracle `orapki` utility to create a client wallet and import the server certificate: ```bash orapki wallet create -wallet /path/to/client/wallet -pwd -auto_login orapki wallet add -wallet /path/to/client/wallet -pwd \ -trusted_cert -cert /path/to/server-cert.pem ``` 3. Copy the generated `cwallet.sso` file to a location accessible by the Openflow runtime. For AWS RDS, download the root certificate from AWS instead of exporting it from the database server. For more information, see Connecting to an RDS for Oracle DB instance using SSL (https://docs.aws.amazon.com/AmazonRDS/latest/UserGuide/Appendix.Oracle.Options.SSL.Connecting.html). For more information, see Using the orapki Utility to Manage PKI Elements (https://docs.oracle.com/en/database/oracle/oracle-database/23/dbseg/using-the-orapki-utility-to-manage-pki-elements.html). ## Next steps [Configure the connector](/user-guide/data-integration/openflow/connectors/oracle/setup-connector). --- title: Openflow Connector for Oracle: Data mapping source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/oracle/data-mapping.md section: Loading & Unloading Data --- # %oracleofc%: Data mapping This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). The %oracleofc% is also subject to additional terms of service beyond the standard connector terms of service. For more information, see the [Openflow Connector for Oracle Addendum](https://www.snowflake.cn/en/legal/optional-offerings/offering-specific-terms/openflow-oracle-terms/). - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [About Openflow Connector for Oracle](/user-guide/data-integration/openflow/connectors/oracle/about) - [Openflow Connector for Oracle: Enable and manage commercial terms](/user-guide/data-integration/openflow/connectors/oracle/manage-commercial-terms) - [Set up tasks for the Openflow Connector for Oracle](/user-guide/data-integration/openflow/connectors/oracle/setup-tasks) This topic describes how Oracle data types are mapped to Snowflake data types when replicating data. ## Oracle to Snowflake data type mapping The following table shows how Oracle data types are mapped to Snowflake data types when replicating data.
For types with default size limits (8 MB / 16 MB) in this table, it is possible to raise these limits. For details, see [Oversized values](/user-guide/data-integration/openflow/connectors/oracle/about#label-oracle-oversized-values). Any Oracle data types not listed in this table are mapped to TEXT by default. ## Next steps Review [Set up tasks for the Openflow Connector for Oracle](/user-guide/data-integration/openflow/connectors/oracle/setup-tasks) to set up the connector. --- title: Openflow Connector for Oracle: Enable and manage commercial terms source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/oracle/manage-commercial-terms.md section: Loading & Unloading Data --- # %oracleofc%: Enable and manage commercial terms This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). The %oracleofc% is also subject to additional terms of service beyond the standard connector terms of service. For more information, see the [Openflow Connector for Oracle Addendum](https://www.snowflake.cn/en/legal/optional-offerings/offering-specific-terms/openflow-oracle-terms/). - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [About Openflow Connector for Oracle](/user-guide/data-integration/openflow/connectors/oracle/about) - [Set up tasks for the Openflow Connector for Oracle](/user-guide/data-integration/openflow/connectors/oracle/setup-tasks) - [Install and configure the Openflow Connector for Oracle](/user-guide/data-integration/openflow/connectors/oracle/setup-connector) - [Openflow Connector for Oracle: Maintenance](/user-guide/data-integration/openflow/connectors/oracle/maintenance) This topic describes how to enable the %oracleofc% in the list of available connectors and manage the licensing lifecycle. This task must be performed by the organization administrator (ORGADMIN). Setting up the %oracleofc% is a two-stage process. First, enable Oracle XStream services to make the connector available for installation. Then, finalize the license configuration after the connector detects your source database inventory. ## Part 1: Enable service (pre-installation) By default, the %oracleofc% isn't displayed in the list of available connectors. You must accept the [Openflow Connector for Oracle Addendum](https://www.snowflake.cn/en/legal/optional-offerings/offering-specific-terms/openflow-oracle-terms/) terms to make it available for installation. This is required for all license models. 1. Sign in to %sf-web-interface-link%. 2. In the navigation menu, select **Admin** %raa% **Terms**. 3. Locate the item **Oracle Connector Terms** in the list. 4. Select **Review & Enable**. After you complete these steps, the following changes take effect: - The %oracleofc% listing becomes visible in the list of available connectors. - A new **Openflow for Oracle** tab appears in the **Admin** %raa% **Terms** page. ## Part 2: License setup and lifecycle Complete the steps for the license model you selected during configuration: - [Option A: Embedded license for 36-month commitment (Snowflake-provided)](#label-oracle-embedded-license-setup-36) - [Option B: Embedded license for 12-month commitment (Snowflake-provided)](#label-oracle-embedded-license-setup-12) - [Option C: Independent license / BYOL](#label-oracle-byol-license-setup) ### Option A: Embedded license for 36-month commitment (Snowflake-provided) For this licensing model, you must activate the trial to enable the connector. Even if you install the connector, data replication doesn't start until this step is complete. #### Step 1: Start the trial (prerequisite) To start the trial: 1. Sign in to %sf-web-interface-link%. 2. In the navigation menu, select **Admin** %raa% **Terms**. 3. Select the **Openflow for Oracle** tab. 4. Locate the **Trial Status** card (status: "Ready to Activate"). 5. Select **Start Trial**. 6. Accept the terms to start the 60-day trial period. This action enables the captureChangeOracle processor, allowing it to connect to your database. #### Step 2: Configure connector After starting the trial, install and configure the connector. For more information, see [Configure the connector](/user-guide/data-integration/openflow/connectors/oracle/setup-connector). After the connector successfully connects to the source database, a subscription is automatically created and displayed in the **Openflow for Oracle** dashboard. #### Step 3: Verify inventory 1. Sign in to %sf-web-interface-link%. 2. In the navigation menu, select **Admin** %raa% **Terms**. 3. Select the **Openflow for Oracle** tab. 4. Review the **Subscription Inventory** section. 5. Verify that the CPU core count matches your physical source database hardware. 6. If the core count is incorrect, update the runtime configuration. #### Step 4: Lifecycle management For more information about the licensing models and terms, see [Licensing models and critical constraints](#label-oracle-licensing-models). The following table describes the actions available at each stage of the embedded license lifecycle.
### Option B: Embedded license for 12-month commitment (Snowflake-provided) For this licensing model, you must activate the trial to enable the connector. Even if you install the connector, data replication doesn't start until this step is complete. #### Step 1: Start the trial (prerequisite) To start the trial: 1. Sign in to %sf-web-interface-link%. 2. In the navigation menu, select **Admin** %raa% **Terms**. 3. Select the **Openflow for Oracle** tab. 4. Locate the **Trial Status** card (status: "Ready to Activate"). 5. Select **Start Trial**. 6. Accept the terms to start the 60-day trial period. This action enables the captureChangeOracle processor, allowing it to connect to your database. #### Step 2: Configure connector After starting the trial, install and configure the connector. For more information, see [Configure the connector](/user-guide/data-integration/openflow/connectors/oracle/setup-connector). After the connector successfully connects to the source database, a subscription is automatically created and displayed in the **Openflow for Oracle** dashboard. #### Step 3: Verify inventory 1. Sign in to %sf-web-interface-link%. 2. In the navigation menu, select **Admin** %raa% **Terms**. 3. Select the **Openflow for Oracle** tab. 4. Review the **Subscription Inventory** section. 5. Verify that the CPU core count matches your physical source database hardware. 6. If the core count is incorrect, update the runtime configuration. #### Step 4: Lifecycle management For more information about the licensing models and terms, see [Licensing models and critical constraints](#label-oracle-licensing-models). The following table describes the actions available at each stage of the embedded license lifecycle.
### Option C: Independent license / BYOL If you are using the independent license (Bring Your Own License), no prior trial activation is required. #### Step 1: Configure the connector To set up the connector with the independent/BYOL license, follow the steps in [Configure the connector](/user-guide/data-integration/openflow/connectors/oracle/setup-connector). #### Step 2: Verify inventory (recommended) Verify that Snowflake has correctly identified your database inventory. 1. Sign in to %sf-web-interface-link%. 2. In the navigation menu, select **Admin** %raa% **Terms**. 3. Select the **Openflow for Oracle** tab. 4. Review the database inventory details. The **Start Trial** button doesn't appear for this license model, and the Embedded License commitment-period rules don't apply. You are responsible for maintaining a valid Oracle license that includes XStream entitlements. --- title: Openflow Connector for Oracle: Iceberg table destinations source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/oracle/iceberg.md section: Loading & Unloading Data --- # Openflow Connector for Oracle: Iceberg table destinations Available to all accounts. - [About Openflow Connector for Oracle](/user-guide/data-integration/openflow/connectors/oracle/about) - [Set up tasks for the Openflow Connector for Oracle](/user-guide/data-integration/openflow/connectors/oracle/setup-tasks) - [Openflow Connector for Oracle: Data mapping](/user-guide/data-integration/openflow/connectors/oracle/data-mapping) - [Data types for Apache Iceberg™ tables](/user-guide/tables-iceberg-data-types) - [Snowflake storage for Apache Iceberg™ tables](/user-guide/tables-iceberg-internal-storage) - [CREATE EXTERNAL VOLUME](/sql-reference/sql/create-external-volume) The Openflow Connector for Oracle (multi-database) supports writing to Snowflake-managed Apache %iceberg-tm% tables as an opt-in destination format. Iceberg v2 and v3 are both supported. Setting **Table Storage Format** = `ICEBERG` and choosing an **Iceberg Version** are the only connector-level changes required. The external volume, catalog, and serialization policy are inherited from the Snowflake destination database defaults. The Iceberg specification version is set via the **Iceberg Version** connector parameter, which defaults to `3`. Storage can be either [Snowflake storage for Apache %iceberg-tm% tables](/user-guide/tables-iceberg-internal-storage) (`EXTERNAL_VOLUME = 'SNOWFLAKE_MANAGED'`) or an external volume in your cloud storage. When you use Snowflake storage, no external cloud storage or IAM grants are required. Existing connectors using standard tables aren't affected. ## Prerequisites - **Openflow runtime**: An existing runtime to host the connector. - **Oracle source configured for CDC**: Archive logging enabled (`ARCHIVELOG` mode), supplemental logging configured, and a LogMiner or XStream user with the required privileges. For details, see [Set up the Openflow Connector for Oracle](/user-guide/data-integration/openflow/connectors/oracle/setup-tasks). - **Snowpipe Streaming v2**: The Oracle connector must have Snowpipe Streaming v2 based writes enabled. This is required for Iceberg table destinations. - **External volume in your cloud storage**: An external volume configured for Iceberg storage, with USAGE granted to the connector's Snowflake role. See [CREATE EXTERNAL VOLUME](/sql-reference/sql/create-external-volume). Not required when using Snowflake storage (`EXTERNAL_VOLUME = 'SNOWFLAKE_MANAGED'`). - **Snowflake destination database**: An existing database configured with Iceberg parameters (next section). ## Step 1: Configure the Snowflake destination database Set the Iceberg defaults on the destination database. The connector reads these defaults at runtime for external volume and serialization policy. The Iceberg specification version is configured per-connector via the **Iceberg Version** parameter (see Step 3), not solely via the database-level `ICEBERG_VERSION_DEFAULT`. ### Option A: Snowflake storage When you use Snowflake storage, Snowflake stores and manages the Iceberg table files for you. No external cloud storage or IAM grants are required. ```sql CREATE DATABASE EXTERNAL_VOLUME = 'SNOWFLAKE_MANAGED' STORAGE_SERIALIZATION_POLICY = ; ``` To configure an existing database: ```sql ALTER DATABASE SET EXTERNAL_VOLUME = 'SNOWFLAKE_MANAGED' STORAGE_SERIALIZATION_POLICY = ; ``` ### Option B: External volume in your cloud storage If you need to keep table files in your own cloud storage, configure the database with your external volume: ```sql CREATE DATABASE EXTERNAL_VOLUME = '' STORAGE_SERIALIZATION_POLICY = ; ``` To configure an existing database: ```sql ALTER DATABASE SET EXTERNAL_VOLUME = '' STORAGE_SERIALIZATION_POLICY = ; ```
`CATALOG = 'SNOWFLAKE'` is set automatically by the connector on each CREATE ICEBERG TABLE statement. Don't set it at the database level. The base location for each table is auto-derived using the [flat layout](/user-guide/tables-iceberg-managing-external-volumes#label-tables-iceberg-snowflake-managed-flat-layout): `STORAGE_BASE_URL/database/schema/table_name.randomId/[data | metadata]/`. No user configuration is needed. If using an external volume in your cloud storage (Option B), grant the connector's Snowflake role USAGE on the external volume: ```sql GRANT USAGE ON EXTERNAL VOLUME TO ROLE ; ``` This step is not required for Snowflake storage. ## Step 2: Set Table Storage Format in the connector's parameter context Set the **Table Storage Format** parameter to `ICEBERG` in the connector's destination parameter context. The default is `STANDARD`. For the full connector creation and configuration workflow, see [Set up the Openflow Connector for Oracle](/user-guide/data-integration/openflow/connectors/oracle/setup-tasks). ## Step 3: Set the Iceberg version Set the **Iceberg Version** connector parameter to `2` or `3`. This controls the Iceberg specification version used for type mapping (for example, JSON maps to `variant` on v3 versus `string` on v2) and the `ICEBERG_VERSION=` clause in CREATE ICEBERG TABLE DDL. The **Iceberg Version** parameter defaults to `3`. Review and change to `2` if needed before starting the connector. Do not change this value after ingestion begins. ## Step 4: Start and verify Start the connector as usual. After the initial snapshot completes, verify the destination tables are Iceberg: ```sql -- Confirm the table is Iceberg SELECT GET_DDL('TABLE', '..
MySQL type Snowflake (Standard) Iceberg v3 Iceberg v2
TINYINT / SMALLINT / MEDIUMINT (signed or unsigned) INT `long` `long`
INT (signed) INT `long` `long`
INT UNSIGNED INT `long` `long`
BIGINT (signed) INT `long` `long`
BIGINT UNSIGNED INT `decimal(20,0)` `decimal(20,0)`
YEAR INT `long` `long`
FLOAT (signed/unsigned) FLOAT `double` `double`
DOUBLE (signed/unsigned) FLOAT `double` `double`
DECIMAL(P,S) (P ≤ 38) NUMBER(P,S) `decimal(P,S)` `decimal(P,S)`
DECIMAL(P,S) (P > 38) TEXT `string` `string`
BOOLEAN / BOOL INT `long` `long`
DATE DATE `date` `date`
TIME TIME `time` `time`
DATETIME TIMESTAMP_NTZ `timestamp` `timestamp`
TIMESTAMP TIMESTAMP_TZ `timestamptz` `timestamptz`
CHAR / VARCHAR / TEXT / TINYTEXT / MEDIUMTEXT / LONGTEXT TEXT `string` `string`
ENUM / SET TEXT `string` `string`
BIT TEXT `string` `string`
BINARY / VARBINARY / BLOB / TINYBLOB / MEDIUMBLOB / LONGBLOB BINARY `binary` `binary`
JSON VARIANT `variant` `string`
GEOMETRY family TEXT `string` `string`
Parameter Description
Starting Binlog Position - `Latest` (default): CDC stream reading starts at the latest available position and continues from there. - `Earliest`: Switches the incremental load to start, or restart reading from the earliest available binary log position.
Re-read Tables in State - `New` (default): While re-reading the binary log, only those events will be processed from new tables added to replication after the re-reading started. Other events are discarded until the connector reaches the position just before re-reading started. - `Any active`: Re-read and re-process events from any table currently in replication.
Database version Procedure
AWS RDS (Standard) Run the following:
```sql begin rdsadmin.rdsadmin_util.set_configuration( name => 'archivelog retention hours', value => '24'); end; / commit; ```
For more information, see Retaining archived redo logs (https://docs.aws.amazon.com/AmazonRDS/latest/UserGuide/Appendix.Oracle.CommonDBATasks.RetainRedoLogs.html).
AWS RDS Custom 1. Create a text file named `/opt/aws/rdscustomagent/config/redo_logs_custom_configuration.json`. 2. Add a JSON object to this file in the following format: `{"archivedLogRetentionHours" : "24"}`. For more information, see Restoring an RDS Custom for Oracle instance (https://docs.aws.amazon.com/AmazonRDS/latest/UserGuide/custom-backup.pitr.html).
Database version Command
Oracle Database 21c and earlier Run the following: ```sql BEGIN DBMS_XSTREAM_AUTH.GRANT_ADMIN_PRIVILEGE( grantee => 'c##xstreamadmin', privilege_type => 'CAPTURE', grant_select_privileges => TRUE, container => 'ALL'); END; / ```
Oracle Database 23c and later Oracle Database 23c introduced a dedicated `XSTREAM_CAPTURE` system privilege. Run the following: ```sql GRANT XSTREAM_CAPTURE TO c##xstreamadmin CONTAINER=ALL; ```
Oracle type Snowflake type Notes
NUMBER NUMBER If precision is undefined, mapped to NUMBER(38, 19). If precision or scale exceeds Snowflake limitations (precision > 38 or scale > 37), the value is stored as TEXT.
FLOAT FLOAT
BINARY_FLOAT FLOAT
BINARY_DOUBLE FLOAT
CHAR TEXT
VARCHAR2 TEXT
NCHAR TEXT
NVARCHAR2 TEXT
CLOB TEXT Supported by default up to 16 MB.
NCLOB TEXT Supported by default up to 16 MB.
LONG TEXT Supported by default up to 16 MB.
DATE TIMESTAMP_NTZ
TIMESTAMP TIMESTAMP_NTZ
TIMESTAMP WITH TIME ZONE TIMESTAMP_TZ
TIMESTAMP WITH LOCAL TIME ZONE TIMESTAMP_LTZ
INTERVAL TEXT
INTERVAL YEAR TO MONTH TEXT
INTERVAL DAY TO SECOND TEXT
RAW BINARY
LONG RAW BINARY Supported by default up to 8 MB.
BLOB BINARY Supported by default up to 8 MB.
BOOLEAN BOOLEAN
JSON VARIANT Supported by default up to 16 MB.
XMLTYPE TEXT Supported by default up to 16 MB.
Stage Action Result
Trial period (Day 1 to 60) Select **Cancel Trial** in the **Openflow for Oracle** dashboard before Day 60. Oracle XStream services stop. No charges are incurred.
36-month commitment (Day 61+) No action required. If the trial isn't canceled, the non-cancelable 36-month term begins automatically on Day 61. The license can't be canceled during this period. If your Snowflake agreement is terminated, the full remaining balance is due immediately.
Post-term S&M renewal (after month 36) The license fee drops to $0. The Support & Maintenance (S&M) fee auto-renews in 12-month increments, billed monthly. You may opt out of S&M renewal in the **Openflow for Oracle** dashboard. If you opt out and S&M coverage expires, the connector is permanently locked. To resume, you must purchase a new Embedded License, which resets the 36-month commitment.
Stage Action Result
Trial period (Day 1 to 60) Select **Cancel Trial** in the **Openflow for Oracle** dashboard before Day 60. Oracle XStream services stop. No charges are incurred.
12-month commitment (Day 61+) No action required. If the trial isn't canceled, the non-cancelable 12-month term begins automatically on Day 61, with license fees paid upfront in full. The license can't be canceled during this period. If your Snowflake agreement is terminated, the full remaining balance is due immediately.
Post-term S&M renewal (after month 12) The license fee drops to $0. The Support & Maintenance (S&M) fee auto-renews in 12-month increments, billed annually. You may opt out of S&M renewal in the **Openflow for Oracle** dashboard. If you opt out and S&M coverage expires, the connector is permanently locked. To resume, you must purchase a new Embedded License, which resets the 12-month commitment.
Parameter Required Notes
EXTERNAL_VOLUME Yes The external volume for Iceberg file storage.
ICEBERG_VERSION_DEFAULT No `2` or `3`. Legacy fallback for older connector flows where the **Iceberg Version** parameter is unset. New connectors set the version via the connector parameter (Step 3) and do not require this database setting.
STORAGE_SERIALIZATION_POLICY Yes `COMPATIBLE` produces Parquet files readable by external engines. `OPTIMIZED` enables Snowflake-specific query optimizations. Choose based on your data query needs. For more information, see [STORAGE_SERIALIZATION_POLICY](/sql-reference/parameters#storage-serialization-policy).
'); -- Confirm the Iceberg version on the database SHOW PARAMETERS LIKE 'ICEBERG_VERSION_DEFAULT' IN DATABASE ; ``` ## Known limitations - **Tri-Secret Secure accounts and Snowflake storage**: Accounts with Tri-Secret Secure (TSS) enabled may be unable to create new Snowflake-managed Iceberg tables that use [Snowflake storage for Apache %iceberg-tm% tables](/user-guide/tables-iceberg-internal-storage). For details, see [Encryption](/user-guide/tables-iceberg-internal-storage#encryption). - **Incompatible type change:** When the source column type changes to a type that maps to a different Iceberg type, the table is marked as failed and requires a resnapshot. See [Type mapping reference](#type-mapping-reference) for the complete source-to-Iceberg type mapping. - **Parameter change within the same Iceberg type:** The connector doesn't recognize parameter changes within the same Iceberg type (for example, changing `decimal(10,2)` to `decimal(20,2)`). The column retains its current Iceberg type. - **Nanosecond timestamp range restriction on v3**: When a TIMESTAMP(7..9) column maps to `timestamp_ns` or `timestamptz_ns` on v3, the representable date range narrows to 1677-09-21 through 2262-04-11. Values outside this range are rejected at insert time. - **TIMESTAMP WITH TIME ZONE offset collapsed to UTC**: Iceberg has no offset-preserving timestamp type. The original timezone offset or region name is lost; only the UTC instant is stored. - **Source TIMESTAMP precision widening not supported on v3**: If a source column's precision increases (for example, TIMESTAMP(6) altered to TIMESTAMP(7)), the Iceberg column type cannot be promoted from `timestamp` to `timestamp_ns`. The connector was created based on the original precision. - **Do not change Table Storage Format or Iceberg Version after the connector starts**: The connector's **Table Storage Format** and **Iceberg Version** parameter should not be modified after ingestion begins. Mixing settings across destination tables is not supported. To switch, follow the steps in [Switching table storage format or Iceberg version](#switching-table-storage-format-or-iceberg-version). ## Type mapping reference The following table shows how Oracle types map to Snowflake standard and Iceberg destination types:
Source types not listed in the table are mapped to TEXT on standard tables and `string` on Iceberg tables. ## Switching table storage format or Iceberg version Switching between Standard and Iceberg, or between Iceberg v2 and v3, requires recreating the connector. Follow these steps: 1. Stop the connector. 2. Delete the process group in Openflow. 3. Manually clean up the destination database (drop the replicated schemas/tables, or use a new database). 4. Reimport the connector with the new **Table Storage Format** and select the target **Iceberg Version** when configuring the connector. This ensures all connector state is correctly cleaned up within Openflow. The new connector performs a fresh snapshot into the destination. ## Upgrading an existing connector to use Iceberg Version pinning Connector version `0.42.0` (embedded license) / `0.41.0` (independent license) introduces the **Iceberg Version** parameter. If you are upgrading from an earlier connector version, a new **Iceberg Version** field appears that you must configure to match your existing destination tables. 1. Stop the connector. 2. [Upgrade the runtime](/user-guide/data-integration/openflow/manage#label-openflow-upgrading-a-runtime) to version `2026.7.21` or later. 3. [Upgrade the connector](/user-guide/data-integration/openflow/manage#upgrade-a-connector) in place to the version listed above or later. 4. The **Iceberg Version** parameter defaults to `3` after the flow upgrade. Review and change to `2` if your existing destination tables are Iceberg v2 before starting the connector. 5. Start the connector. Selecting an **Iceberg Version** that doesn't match your existing destination tables can cause type-mapping errors or DDL failures. Always verify the version of your existing tables before choosing a value. ## References - [CREATE EXTERNAL VOLUME](/sql-reference/sql/create-external-volume) - [Data types for Apache Iceberg tables](/user-guide/tables-iceberg-data-types) - [ALTER DATABASE](/sql-reference/sql/alter-database) - [STORAGE_SERIALIZATION_POLICY](/sql-reference/parameters#storage-serialization-policy) - [Set up the Openflow Connector for Oracle](/user-guide/data-integration/openflow/connectors/oracle/setup-tasks) --- title: Openflow Connector for Oracle: Maintenance source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/oracle/maintenance.md section: Loading & Unloading Data --- # %oracleofc%: Maintenance This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). The %oracleofc% is also subject to additional terms of service beyond the standard connector terms of service. For more information, see the [Openflow Connector for Oracle Addendum](https://www.snowflake.cn/en/legal/optional-offerings/offering-specific-terms/openflow-oracle-terms/). - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [About Openflow Connector for Oracle](/user-guide/data-integration/openflow/connectors/oracle/about) - [Openflow Connector for Oracle: Enable and manage commercial terms](/user-guide/data-integration/openflow/connectors/oracle/manage-commercial-terms) - [Openflow Connector for Oracle: Set up incremental replication without snapshots](/user-guide/data-integration/openflow/connectors/oracle/incremental-replication) This topic describes maintenance tasks for the %oracleofc%, such as reinstalling the connector or setting the starting redo log position. These operations are often used in conjunction with [Incremental replication without snapshots](/user-guide/data-integration/openflow/connectors/oracle/incremental-replication). ## Check the replication status of a table Interim failures, such as connection errors or temporary source unavailability during a high-availability failover, do not prevent table replication. Replicated tables keep their current status and the connector retries on the next polling cycle. However, permanent failures, such as unsupported data types, prevent table replication. To troubleshoot replication issues or verify that a table has been successfully removed from the replication flow, check the Table State Store: 1. In the Openflow runtime canvas, right-click a processor group and choose **Controller Services**. A table listing controller services displays. 2. Locate the row labeled **Table State Store**, click the **More** %sf-vertical-more-button% button on the right side of the row, and then choose **View State**. A list of tables and their current states displays. Type in the search box to filter the list by table name. The possible states are: - **NEW**: The table is scheduled for replication but replication hasn't started. - **SNAPSHOT_REPLICATION**: The connector is copying existing data. This status displays until all records are stored in the destination table. - **INCREMENTAL_REPLICATION**: The connector is actively replicating changes. This status displays after snapshot replication ends and continues to display indefinitely until a table is either removed from replication or replication fails. - **FAILED**: Replication has permanently stopped due to an error. The Openflow runtime canvas doesn't display table status changes — only the current table status. However, table status changes are recorded in logs when they occur. Look for the following log message: ```text Replication state for table .. changed from to ``` If a permanent failure prevents table replication, remove the table from replication. After you address the problem that caused the failure, you can add the table back to replication. For more information, see [Restart table replication](#label-of-oracle-restart-table-replication). ## Increase the oversized value limit By default, the connector replicates individual values up to 16 MB and marks any table that contains a larger value as permanently failed. If your Snowflake account has the `ENABLE_OPENFLOW_CDC_ORACLE_SSV2` parameter set to `true`, the per-value limit can be raised from 16 MB to **128 MB**. The 128 MB limit applies in two ways: it's both the maximum size of a single value and the maximum total size of a row. The connector adds metadata columns to every replicated row (`_SNOWFLAKE_UPDATED_AT`, `_SNOWFLAKE_INSERTED_AT`, `_SNOWFLAKE_DELETED`) that count toward the per-row limit, along with all other columns in the row. As a result, a single value can't reach the full 128 MB in practice when the row includes other data. The increased limit doesn't apply equally to all column types. In Snowflake, the maximum size for `BINARY` is **64 MB** (`BINARY(67108864)`), even when the increased size limits are enabled. Only `VARCHAR`, `VARIANT`, `ARRAY` and `OBJECT` columns can hold up to 128 MB. ### Check whether the 128 MB limit is available You may not be able to verify the `ENABLE_OPENFLOW_CDC_ORACLE_SSV2` parameter value by querying it. To check if it is enabled, see if the FlowFiles flow through **Upload Rows via Snowpipe Streaming 2** processor (not through **Upload Rows via Snowpipe Streaming**). ### Configure the processors Update the **Oversized Value Limit** property to `128 MB` on the following processors: - **Fetch Rows by ROWID Range** (in the **Snapshot Load** group) — used when **Snapshot Fetching Strategy** is `CONCURRENT_BY_ROWID` - **Fetch Table Rows** (in the **Snapshot Load** group) — used when **Snapshot Fetching Strategy** is `SEQUENTIAL_BY_PRIMARY_KEY` - **Read Oracle CDC Stream** (in the **Incremental Load** group) For each processor: 1. Locate the processor in the flow. On the connector canvas, you can use the search box in the top-right corner to find processors by name. 2. Right-click the processor and select **Configure**. 3. Open the **Properties** tab. 4. Set **Oversized Value Limit** to `128 MB`. 5. Apply the change. For tables that are already being replicated and have destination columns narrower than `VARCHAR(134217728)` or `BINARY(67108864)`, see [](#label-of-oracle-migrate-oversized-value-tables). ### Migrate existing tables The steps in [](#label-of-oracle-increase-oversized-value-limit) raise the limit for newly created destination tables. If a table is already being replicated and its destination column type is **not** `VARCHAR(134217728)` or `BINARY(67108864)`, but you now want to load values larger than the original 16 MB limit, you must manually widen the column type on **both** the journal and destination tables. Before you migrate, check the current destination column type, because it can vary depending on when the snapshot replication was performed. You must stop replication for the affected table before altering its journal or destination tables. Altering these tables while replication is active can corrupt in-flight data. To migrate a table: 1. Stop replication for the affected table by stopping the topmost processors of the **Snapshot Load** and **Incremental Load** groups until all queues are empty. For the equivalent stop procedure, see the substeps in [](#label-oracle-reinstall-connector). 2. Widen the column on both the journal table and the destination table, according to the column type: 1. For **VARCHAR** columns, run `ALTER TABLE ... ALTER COLUMN ... SET DATA TYPE VARCHAR(134217728)` on the journal table and on the destination table (one statement per table). 2. For **BINARY** columns, Snowflake doesn't allow widening `BINARY` in place, so do the following on both the journal and destination tables: 1. Add a new column of type `BINARY(67108864)`. 2. Copy data from the original column into the new column. 3. Drop the original column and rename the new column to the original name. 3. Restart replication by re-enabling the processors. ### Performance considerations Raising the per-value limit increases the amount of data that the connector loads into memory and moves through the flow, which raises the load on both the runtime and the warehouse. Size the runtime and warehouse accordingly. When **Oversized Value Strategy** is set to **Set Null**, the connector still loads each oversized value into memory before it can replace it with `NULL`. If your tables contain multi-gigabyte LOB columns, exclude those columns from replication. During both snapshot and incremental replication, the queue in front of the **Upload Rows via Snowpipe Streaming 2** processor can fill with FlowFiles and trigger back pressure, which consumes a large amount of runtime disk space. For larger tables, use a Large runtime to provide additional storage. For guidance on choosing a size, see [Runtime sizing](/user-guide/data-integration/openflow/connectors/oracle/setup-connector#label-oracle-runtime-sizing). #### Snapshot replication Large LOB values can substantially increase snapshot runtime memory and disk use, because **Fetch Rows by ROWID Range** reads full row payloads (including LOBs) into the runtime before emitting FlowFiles. The **Split Table into Chunks** processor sizes ROWID ranges from table heap blocks. Because LOBs are stored in separate segments, their size is not included in that calculation. When non-LOB column data is small compared with LOB payloads, a single chunk can still require **Fetch Rows by ROWID Range** to read multi-gigabytes of data. Output FlowFiles for that chunk are not passed downstream until the JDBC fetch for the entire ROWID range completes, so later processors may not receive data for a long time. #### Incremental replication When the source produces frequent changes to rows that contain large values, you might need a Large warehouse. High-frequency merges of many moderately large rows (for example, many 8 MB values) can require a large single merge operation, and smaller warehouses can run out of memory. By contrast, fewer very large rows (for example, 128 MB values) are streamed file by file through the **Upload Rows via Snowpipe Streaming 2** processor, and each file is merged incrementally, which typically completes without warehouse errors even on smaller warehouses. During incremental CDC, **Read Oracle CDC Stream** materializes each changed row in memory before it is processed. This applies even when **Oversized Value Strategy** is set to **Set Null**: the connector must load the full row, including all LOB columns, before it can replace oversized values with `NULL`. If a single row contains multiple multi-gigabyte LOB columns, the total in-memory size can exceed the runtime heap and cause an out-of-memory error. Exclude such columns from replication before you rely on incremental CDC. ## Enable error logging on an existing schema When you set the **Error Handling Strategy** parameter to **Log Errors and Continue**, the connector enables error logging automatically only on tables that it creates afterward. Tables that the connector created earlier don't capture rejected rows until you turn on error logging for them. For more information about the error-handling strategies, see [](/user-guide/data-integration/openflow/connectors/oracle/about#label-oracle-error-handling). Because the connector stores journal tables in the same schema as the destination tables, you can turn on error logging for a whole destination schema at once. Run the following stored procedure once per destination schema. Replace `my_database` with your destination database and `my_schema` with the destination schema. The schema name is passed as a quoted identifier (for example, `'"my_schema"'`) so it matches the exact, case-sensitive name that the connector created. For more information about how the connector names destination schemas, see [](/user-guide/data-integration/openflow/connectors/oracle/setup-connector#label-oracle-snowflake-destination-parameters). ```sql USE DATABASE my_database; WITH enable_error_logging AS PROCEDURE (schema_name STRING) RETURNS STRING LANGUAGE SQL AS $$ DECLARE tables RESULTSET; table_count NUMBER DEFAULT 0; BEGIN SHOW TABLES IN SCHEMA IDENTIFIER(:schema_name); -- Assign AFTER SHOW TABLES so LAST_QUERY_ID() refers to that result tables := ( SELECT "database_name", "schema_name", "name" FROM TABLE(RESULT_SCAN(LAST_QUERY_ID())) WHERE "kind" = 'TABLE' ); FOR t IN tables DO -- Double-quote each identifier so names with special characters are handled safely EXECUTE IMMEDIATE 'ALTER TABLE "' || REPLACE(t."database_name", '"', '""') || '".' || '"' || REPLACE(t."schema_name", '"', '""') || '".' || '"' || REPLACE(t."name", '"', '""') || '" ' || 'SET ERROR_LOGGING = TRUE'; table_count := table_count + 1; END FOR; RETURN 'Enabled ERROR_LOGGING on ' || table_count || ' table(s) in schema ' || :schema_name; END; $$ CALL enable_error_logging('"my_schema"'); ``` ### Verify that error logging is enabled To confirm that error logging is enabled on every table in a schema, run the following procedure. It reports how many tables have error logging enabled and how many don't. ```sql USE DATABASE my_database; WITH verify_error_logging AS PROCEDURE (schema_name STRING) RETURNS STRING LANGUAGE SQL AS $$ DECLARE tables RESULTSET; probe RESULTSET; total_tables NUMBER DEFAULT 0; logging_enabled NUMBER DEFAULT 0; disabled_or_invisible NUMBER DEFAULT 0; BEGIN SHOW TABLES IN SCHEMA IDENTIFIER(:schema_name); -- Assign AFTER SHOW TABLES so LAST_QUERY_ID() refers to that result tables := ( SELECT "database_name", "schema_name", "name" FROM TABLE(RESULT_SCAN(LAST_QUERY_ID())) WHERE "kind" = 'TABLE' ); FOR t IN tables DO total_tables := total_tables + 1; -- Probe ERROR_TABLE(): it succeeds only when error logging is enabled and visible BEGIN probe := ( EXECUTE IMMEDIATE 'SELECT 1 FROM ERROR_TABLE(' || '"' || REPLACE(t."database_name", '"', '""') || '".' || '"' || REPLACE(t."schema_name", '"', '""') || '".' || '"' || REPLACE(t."name", '"', '""') || '"' || ') LIMIT 1' ); logging_enabled := logging_enabled + 1; EXCEPTION WHEN STATEMENT_ERROR THEN disabled_or_invisible := disabled_or_invisible + 1; END; END FOR; RETURN 'schema=' || :schema_name || ', total_tables=' || total_tables || ', error_logging_enabled=' || logging_enabled || ', error_logging_disabled_or_not_visible=' || disabled_or_invisible; END; $$ CALL verify_error_logging('"my_schema"'); ``` ## Reinstall the connector This section provides instructions on how to reinstall the connector, and continue replicating data for the same tables without having to snapshot them again. It covers situations where the new connector is installed in the same runtime, as well as moved to a new runtime. For the connector to continue replicating from the same CDC stream position where it stopped before reinstallation, the source database must retain the archived redo logs long enough to cover the time after the prior connector was stopped and before the new connector is started. Ensure the archived redo log retention period of the Oracle database is high enough, and keep the reinstallation time to a minimum. Typically a retention period of 24 hours is sufficient; however, longer times might be appropriate to ensure time to reinstall. For more information on configuring archived redo log retention, see [Openflow Connector for Oracle: Configure the Oracle database](/user-guide/data-integration/openflow/connectors/oracle/setup-oracledb). ### Prerequisites Review and note connector parameter context values. If you're reinstalling the connector in the same runtime, you can reuse the existing context. If the new instance is located in a different runtime, you must re-enter all parameters. 1. Finish processing all in-flight FlowFiles in the existing connector, then stop the connector. 1. Sign in to %sf-web-interface-link%. 2. In the navigation menu, select **Ingestion** %raa% **Openflow**. 3. Select **Launch Openflow**. 4. In the **Openflow** pane select the **Runtimes** tab. 5. Select the runtime containing the connector. 6. Select the connector. 7. Stop the topmost processor **Set Tables for Replication** in the **Snapshot Load** group. 8. Stop the topmost processor **Read Oracle CDC Stream** in the **Incremental Load** group. 9. If you changed the value of the **Merge Task Schedule CRON** parameter, return it to `* * * * * ?`. Otherwise, queues won't be emptied until the next scheduled run. Wait until all FlowFiles in the connector have been processed, and all queues are empty. When all FlowFiles have been processed, the **Queued** value on the connector's processor group becomes zero. If any items remain in the original connector's queues, data gaps might occur when the new connector starts. 10. Stop all processors and controller services in the connector. The existing connector can remain in the runtime and doesn't interfere with the new instance, as long as it remains stopped. 2. If you're moving the connector to a new runtime, download the flow definition from the existing connector so that you can recreate the connector with its current state instead of configuring it from scratch. Downloading a flow definition requires Openflow Runtime Server version 2026.6.4.18 or later. 1. Right-click the connector's process group, then select **Download flow definition**. 2. Select both of the following options, then download the flow definition: - **Export with External Services**: includes the controller services that the connector references from parent process groups. - **Export with Components State**: includes component state, such as redo log positions and incremental replication state, so that replication continues from where it left off. 3. Create the connector in the target runtime: - If you downloaded the flow definition, import it into the new runtime. Importing the flow definition preserves the component state captured during the export, so the connector resumes incremental replication from its previous positions. - Otherwise, create a new instance of the connector. If you're using the same runtime as the original connector, you can choose to keep the existing parameter contexts and reuse the settings. 4. If you're installing into a different runtime or you deleted the previous parameter contexts, enter the configuration settings into the new parameter contexts, including the table names and patterns as described in [Install and configure the Openflow Connector for Oracle](/user-guide/data-integration/openflow/connectors/oracle/setup-connector). A downloaded flow definition doesn't include sensitive values (such as passwords) or uploaded files (such as the Oracle auto-login wallet file), so you must re-enter and re-upload them. 5. Navigate to the `Oracle Ingestion Parameters` context, and set the following parameters: - Set the `Ingestion Type` parameter to `incremental`. For more information on the concerns, see [](#label-oracle-incremental-replication). - Set the `Starting XStream Position` parameter to `Earliest`. For more information and potential concerns, see [](#label-oracle-alter-xstream-outbound-server). If you imported the flow definition with **Export with Components State** selected, the connector retains its previous redo log positions. In this case, leave `Starting XStream Position` set to `Latest` to continue replication from where it stopped. 6. Start the new connector. ### Usage notes The new connector uses the existing destination tables that were created by the original connector, but the connector creates new journal tables. ## Alter XStream outbound server The connector regularly updates the XStream server with the latest SCN position it processed. If the connector is reinstalled and connects to the same XStream outbound server, it will resume reading from the SCN position where it left off. This SCN number can be checked with: ```sql SELECT PROCESSED_LOW_SCN FROM DBA_XSTREAM_OUTBOUND_PROGRESS WHERE SERVER_NAME = 'XOUT1'; ``` If you want to re-read data from an earlier position, you must first change the start SCN of the XStream server: ```sql BEGIN DBMS_XSTREAM_ADM.ALTER_OUTBOUND( server_name => 'XOUT1', start_scn => ); END; / ``` The value of `` must be a valid SCN within the range of available redo logs. The lowest SCN that the start position can be reset to can be checked with: ```sql SELECT REQUIRED_CHECKPOINT_SCN FROM DBA_CAPTURE WHERE CLIENT_NAME = 'XOUT1'; ``` This is the lowest SCN for which the capture process requires redo information. ## Specify load from XStream position The %oracleofc% connector allows you to select the starting position where Oracle redo logs are read. By default the connector reads from the latest available position. Alternatively, you can choose the earliest position available on the source instance. Choosing to start from the earliest position is common when reinstalling the connector. This allows the new instance to catch up and continue replicating existing tables without having to snapshot each again. Switching a running connector from latest to earliest position causes all available redo logs to be re-read, re-processed, and re-applied to the destination table. While the redo logs are being re-read, the columns and data in affected destination tables can become out of sync with their sources until all events have been re-processed and merged. The following parameters are available in the `Ingestion Parameters` context:
To determine whether the connector finished re-reading the redo logs: 1. Navigate to the Openflow canvas. 2. Open the **Incremental Load** process group. 3. Right-click the topmost processor named **Read Oracle CDC Stream**, then select **View state**. 4. Compare the state entries: - **lcr.position.rewind**: the latest position the processor read before re-reading of the redo logs started. - **lcr.position.last**: the current latest position read by the processor. As long as this value is lower than the rewind value above, the processor is still re-reading the redo logs. ### Usage notes - After a running connector is switched to read from the earliest position, and starts running, the process can't be reconfigured or cancelled, and continues until the currently-read position reaches the position from before it started. - Switching to the earliest position on a running connector will, for any tables being re-processed, finish their existing journals, and create new journal tables. - If the redo log contains events from a previous table that was dropped and re-created in the source database, re-reading the stream re-processes all events in the current destination. The connector can't distinguish between a previous and current source table if they share the same name. Schema changes (such as ALTER TABLE statements that add or drop columns) aren't supported while re-reading the redo logs from the earliest position. If any table's schema was altered between the earliest available SCN and the current position, that table should be removed from replication and re-added with a fresh snapshot instead. --- title: Openflow Connector for Oracle: Set up incremental replication without snapshots source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/oracle/incremental-replication.md section: Loading & Unloading Data --- # %oracleofc%: Set up incremental replication without snapshots This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). The %oracleofc% is also subject to additional terms of service beyond the standard connector terms of service. For more information, see the [Openflow Connector for Oracle Addendum](https://www.snowflake.cn/en/legal/optional-offerings/offering-specific-terms/openflow-oracle-terms/). - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [About Openflow Connector for Oracle](/user-guide/data-integration/openflow/connectors/oracle/about) - [Openflow Connector for Oracle: Enable and manage commercial terms](/user-guide/data-integration/openflow/connectors/oracle/manage-commercial-terms) - [Install and configure the Openflow Connector for Oracle](/user-guide/data-integration/openflow/connectors/oracle/setup-connector) - [Openflow Connector for Oracle: Maintenance](/user-guide/data-integration/openflow/connectors/oracle/maintenance) This topic describes how to configure the %oracleofc% connector to start replicating incremental changes for newly added tables immediately, bypassing snapshots. This configuration is useful when you reinstall the connector over previously replicated data and want to continue replication without snapshotting every table again. You can enable incremental replication on either a new or an existing connector instance. ## Enable incremental replication without snapshots on a new connector To enable incremental replication on a new connector instance: 1. Set up the connector as described in [Install and configure the Openflow Connector for Oracle](/user-guide/data-integration/openflow/connectors/oracle/setup-connector). 2. In the `Oracle Ingestion Parameters` context, set the `Ingestion Type` parameter to `incremental`. ## Enable incremental replication without snapshots on an existing connector To enable incremental replication on an existing connector: 1. sign in to %sf-web-interface-link%. 2. in the navigation menu, select **Ingestion** %raa% **Openflow**. 3. In the **Openflow** pane select the **Runtimes** tab. 4. Select the runtime containing the connector. 5. Select the connector. 6. In the `Ingestion Parameters` context, specify `Ingestion Type` = `incremental`. 7. Add new replication tables. These tables immediately switch to their incremental load. To return to replicating tables with the snapshot load, change **Ingestion Type** from `incremental` to `full`. # Usage notes - Changing the value of **Ingestion Type** does not impact any tables that have begun replicating data. Tables currently in the snapshot phase continue until the snapshot load is complete. - While **Ingestion Type** is set to `incremental`, new tables added to the list of replicated tables bypass the snapshot phase. This includes new tables added to the source database that match the `Included Table Regex` parameter. Ensure that the ingestion type is set to `incremental` to bypass the snapshot phase. Connectors should only remain in `incremental` mode as long as required as it bypasses snapshots. Once customer needs for incremental updates have been satisfied the connector should be returned to `full` mode. - For tables that bypass snapshot load, the connector creates a destination table in Snowflake, by executing `CREATE TABLE IF NOT EXISTS`, only if no destination table already exists. Tables going through the snapshot require that no destination table exist. ## Recover a table using incremental-only mode If a table's snapshot completed successfully but incremental replication later failed, you don't need to remove the table and snapshot it again. Instead, you can recover the table by replaying the changes that are still available in the source redo logs through XStream and merging them onto the existing destination table. Incremental replication can fail for several reasons, for example: - A record in the source database can't be read because it has an incorrect or unsupported format. - A row exceeds the maximum supported size. - A merge operation can't complete. - A transient error persists through so many retries that the table enters the FAILED state. To recover the table without a new snapshot, remove it from replication, switch the connector to incremental-only mode reading from the earliest available position, and add the table back. The connector reads all available changes from the oldest available XStream position, then replays and reapplies them to the destination table. Before you recover the table, address the underlying cause of the failure. Otherwise, the connector encounters the same error again when it replays the changes. For example, raise the per-value limit (see [Increase the oversized value limit](/user-guide/data-integration/openflow/connectors/oracle/maintenance#label-of-oracle-increase-oversized-value-limit)) or fix the problematic record in the source database. To recover the table: 1. Remove the table from replication. In the `Ingestion Parameters` context, remove the table from **Included Table Names**, or modify **Included Table Regex** so the table is no longer matched. Wait until the table's state is fully removed from the **Table State Store** controller service before you continue. Don't drop the destination table. This procedure reuses the existing destination table and replays incremental changes onto it. 2. Stop the connector's process group so that you can change its configuration. On the connector canvas, right-click the connector's process group and select **Stop**. 3. In the `Ingestion Parameters` context, set the `Ingestion Type` parameter to `incremental`. 4. Set the `Starting XStream Position` parameter to `Earliest`. The connector reads all available changes again from the oldest available XStream position, then replays and reapplies them to the destination table. For more information, see the "Specify load from XStream position" section in [Openflow Connector for Oracle: Maintenance](/user-guide/data-integration/openflow/connectors/oracle/maintenance). Leave `Re-read Tables in State` at its default value, `New`, so that only the table you add back reads from the earliest position. Tables already in replication continue from their last positions. 5. Add the table back to replication by reversing the change you made in step 1. 6. Start the connector's process group. Right-click the connector's process group and select **Start**. 7. Wait until the table returns to incremental replication. In the **Table State Store** controller service state, the table transitions to INCREMENTAL_REPLICATION when recovery completes. 8. Revert the changes you made in steps 3 and 4: set `Ingestion Type` and `Starting XStream Position` back to their previous values. This procedure recovers only the changes still available in the source redo logs. If the required redo information is no longer retained on the source, the recovered table can have gaps. In that case, you must take a new snapshot to fully resynchronize the table. --- title: Openflow Connector for Oracle: Set up Snowflake source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/oracle/setup-snowflake.md section: Loading & Unloading Data --- # %oracleofc%: Set up Snowflake This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). The %oracleofc% is also subject to additional terms of service beyond the standard connector terms of service. For more information, see the [Openflow Connector for Oracle Addendum](https://www.snowflake.cn/en/legal/optional-offerings/offering-specific-terms/openflow-oracle-terms/). - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [About Openflow Connector for Oracle](/user-guide/data-integration/openflow/connectors/oracle/about) - [Openflow Connector for Oracle: Enable and manage commercial terms](/user-guide/data-integration/openflow/connectors/oracle/manage-commercial-terms) - [Openflow Connector for Oracle: Configure the Oracle database](/user-guide/data-integration/openflow/connectors/oracle/setup-oracledb) - [Install and configure the Openflow Connector for Oracle](/user-guide/data-integration/openflow/connectors/oracle/setup-connector) This topic describes how to set up your Snowflake environment for the %oracleofc%. As a Snowflake administrator, perform the following tasks: 1. Create a destination database in Snowflake to store the replicated data: ```sql CREATE DATABASE ; ``` 2. Create a Snowflake [service user](#label-user-type-property): ```sql CREATE USER TYPE = SERVICE COMMENT='Service user for automated access of Openflow'; ``` 3. Create a Snowflake role for the connector and grant the required privileges: ```sql CREATE ROLE ; GRANT ROLE TO USER ; GRANT USAGE ON DATABASE TO ROLE ; GRANT CREATE SCHEMA ON DATABASE TO ROLE ; ``` Use this role to manage the connector's access to the Snowflake database. To create objects in the destination database, you must grant the [USAGE and CREATE SCHEMA privileges](#label-database-privileges) on the database to the role used to manage access. 4. Create a Snowflake warehouse for the connector and grant the required privileges: ```sql CREATE WAREHOUSE WITH WAREHOUSE_SIZE = 'XSMALL' AUTO_SUSPEND = 300 AUTO_RESUME = TRUE; GRANT USAGE, OPERATE ON WAREHOUSE TO ROLE ; ``` Snowflake recommends starting with a XSMALL warehouse size, then experimenting with size depending on the number of tables being replicated and the amount of data transferred. Large numbers of tables typically scale better with multi-cluster warehouses, rather than a larger warehouse size. For more information, see [multi-cluster warehouses](/user-guide/warehouses-multicluster). 5. Set up the public and private keys for key pair authentication: 1. Create a pair of secure keys (public and private). 2. Store the private key for the user in a file to supply to the connector's configuration. 3. Assign the public key to the Snowflake service user: ```sql ALTER USER SET RSA_PUBLIC_KEY = 'thekey'; ``` For more information, see [Key-pair authentication and key-pair rotation](/user-guide/key-pair-auth). ## Next steps [Configure the connector](/user-guide/data-integration/openflow/connectors/oracle/setup-connector). --- title: Openflow Connector for PostgreSQL Maintenance source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/postgres/maintenance.md section: Loading & Unloading Data --- # %postgresql% Maintenance This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Set up the Openflow Connector for PostgreSQL](/user-guide/data-integration/openflow/connectors/postgres/setup) - [Openflow Connector for PostgreSQL: Data mapping](/user-guide/data-integration/openflow/connectors/postgres/data-mapping) This topic describes important maintenance considerations and best practices for maintaining the %postgresql% when making changes to the source PostgreSQL database. In addition, this topic describes how to restart table replication and reinstall the connector. ## Check the replication status of a table Interim failures, such as connection errors or temporary source unavailability during a high-availability failover, do not prevent table replication. Replicated tables keep their current status and the connector retries on the next polling cycle. However, permanent failures, such as unsupported data types, prevent table replication. To troubleshoot replication issues or verify that a table has been successfully removed from the replication flow, check the Table State Store: 1. In the Openflow runtime canvas, right-click a processor group and choose **Controller Services**. A table listing controller services displays. 2. Locate the row labeled **Table State Store**, click the **More** %sf-vertical-more-button% button on the right side of the row, and then choose **View State**. A list of tables and their current states displays. Type in the search box to filter the list by table name. The possible states are: - **NEW**: The table is scheduled for replication but replication hasn't started. - **SNAPSHOT_REPLICATION**: The connector is copying existing data. This status displays until all records are stored in the destination table. - **INCREMENTAL_REPLICATION**: The connector is actively replicating changes. This status displays after snapshot replication ends and continues to display indefinitely until a table is either removed from replication or replication fails. - **FAILED**: Replication has permanently stopped due to an error. The Openflow runtime canvas doesn't display table status changes — only the current table status. However, table status changes are recorded in logs when they occur. Look for the following log message: ```text Replication state for table .. changed from to ``` If a permanent failure prevents table replication, remove the table from replication. After you address the problem that caused the failure, you can add the table back to replication. For more information, see [Restart table replication](#label-of-postgres-restart-table-replication). ## Restart table replication This procedure re-snapshots the table in place. It requires Runtime Extensions version `2026.6.18.9` or later and connector version `0.55.0` or later. On earlier versions, re-snapshotting a table that already exists in Snowflake fails instead of reloading in place. Upgrade Runtime Extensions first, and then upgrade the connector flow before you use this procedure. A table in a FAILED state (for example, due to a missing primary key or an unsupported schema change) does not restart automatically. If a table enters a FAILED state or you need to restart replication from scratch, use the following procedure to remove and re-add the table to replication. If the failure was caused by an issue in the source table such as a missing primary key, resolve that issue in the source database before continuing. 1. Remove the table from replication, using one of the following methods: - Add the table to the **Re-snapshot Table Exclusions** parameter to temporarily exclude it from replication. This approach is convenient when the table is matched by an **Included Table Regex** that you don't want to change. - In the **Ingestion Parameters** context, either remove the table from **Included Table Names** or modify the **Included Table Regex** so the table is no longer matched. 2. Verify the table has been removed: 1. In the Openflow runtime canvas, right-click a processor group and choose **Controller Services**. 2. In the table listing controller services, locate the **Table State Store** row, click the three vertical dots on the right side of the row, then choose **View State**. You must wait until the table's state is fully removed from this list before proceeding. Don't continue until this configuration change has completed. 3. Wait until all queues in the connector are empty before you re-add the table. When all FlowFiles have been processed, the **Queued** value on the connector's processor group becomes zero. Don't re-add the table while change events that were captured before you removed it are still queued. When you re-add a table, the connector loads the new snapshot in append-only mode, so any leftover change event that merges into the table after the re-snapshot might create duplicate rows in the destination table. 4. Re-add the table by reversing the change you made in the first step: either remove the table from **Re-snapshot Table Exclusions**, or add it back to **Included Table Names** or **Included Table Regex**. You do not need to drop the destination table first. The connector re-snapshots the table in place: it makes a zero-copy [clone](/sql-reference/sql/create-clone) of the current destination table to an archive table named `_ARCHIVE_`, clears the destination table, and then loads the fresh snapshot into the same destination table. Because the destination table object is preserved, dependent objects such as streams remain attached and continue to work. The archive table retains a copy of the destination table's contents from immediately before the reload, as a safeguard. The connector does not read from or write to it again, so you can drop it at any time once the backup is no longer needed, typically after you confirm that the re-snapshot completed and the destination data is correct. 5. Verify the restart: Check the **Table State Store** using the instructions given previously. The state of the table should appear with the status NEW, then transition to SNAPSHOT_REPLICATION, and finally to INCREMENTAL_REPLICATION. ## Increase the oversized value limit By default, the connector replicates individual values up to 16 MB and marks any table that contains a larger value as permanently failed. If your Snowflake account has the `ENABLE_OPENFLOW_CDC_POSTGRES_SSV2` parameter set to `true`, the per-value limit can be raised from 16 MB to **128 MB**. The 128 MB limit applies in two ways: it's both the maximum size of a single value and the maximum total size of a row. The connector adds metadata columns to every replicated row (`_SNOWFLAKE_UPDATED_AT`, `_SNOWFLAKE_INSERTED_AT`, `_SNOWFLAKE_DELETED`) that count toward the per-row limit, along with all other columns in the row. As a result, a single value can't reach the full 128 MB in practice when the row includes other data. The increased limit doesn't apply equally to all column types. In Snowflake, the maximum size for `BINARY` is **64 MB** (`BINARY(67108864)`), even when the increased size limits are enabled. Only `VARCHAR`, `VARIANT`, `ARRAY` and `OBJECT` columns can hold up to 128 MB. ### Check whether the 128 MB limit is available You may not be able to verify the `ENABLE_OPENFLOW_CDC_POSTGRES_SSV2` parameter value by querying it. To check if it is enabled, see if the FlowFiles flow through **Upload Rows via Snowpipe Streaming 2** processor (not through **Upload Rows via Snowpipe Streaming**). ### Configure the processors Update the **Oversized Value Limit** property to `128 MB` on both of the following processors: - **Fetch Table Rows** (in the **Snapshot Load** group) - **Read PostgreSQL CDC Stream** (in the **Incremental Load** group) For each processor: 1. Locate the processor in the flow. On the connector canvas, you can use the search box in the top-right corner to find processors by name. 2. Right-click the processor and select **Configure**. 3. Open the **Properties** tab. 4. Set **Oversized Value Limit** to `128 MB`. 5. Apply the change. For tables that are already being replicated and have destination columns narrower than `VARCHAR(134217728)` or `BINARY(67108864)`, see [](#label-of-postgres-migrate-oversized-value-tables). ### Migrate existing tables The steps in [](#label-of-postgres-increase-oversized-value-limit) raise the limit for newly created destination tables. If a table is already being replicated and its destination column type is **not** `VARCHAR(134217728)` or `BINARY(67108864)`, but you now want to load values larger than the original 16 MB limit, you must manually widen the column type on **both** the journal and destination tables. Before you migrate, check the current destination column type, because it can vary depending on when the snapshot replication was performed. You must stop replication for the affected table before altering its journal or destination tables. Altering these tables while replication is active can corrupt in-flight data. To migrate a table: 1. Stop replication for the affected table by stopping the topmost processors of the **Snapshot Load** and **Incremental Load** groups until all queues are empty. For the equivalent stop procedure, see the substeps in [](#label-postgres-reinstall-connector). 2. Widen the column on both the journal table and the destination table, according to the column type: 1. For **VARCHAR** columns, run a single `ALTER TABLE ... ALTER COLUMN ... SET DATA TYPE VARCHAR(134217728)` on both the journal and destination tables. 2. For **BINARY** columns, Snowflake doesn't allow widening `BINARY` in place, so do the following on both the journal and destination tables: 1. Add a new column of type `BINARY(67108864)`. 2. Copy data from the original column into the new column. 3. Drop the original column and rename the new column to the original name. 3. Restart replication by re-enabling the processors. ### Performance considerations Raising the per-value limit increases the amount of data that the connector loads into memory and moves through the flow, which raises the load on both the runtime and the warehouse. Size the runtime and warehouse accordingly. During both snapshot and incremental replication, the queue in front of the **Upload Rows via Snowpipe Streaming 2** processor can fill with FlowFiles and trigger back pressure, which consumes a large amount of runtime disk space. For larger tables, use a Large runtime to provide additional storage. For guidance on choosing a size, see [Runtime sizing](/user-guide/data-integration/openflow/connectors/cdc-runtime-sizing#label-openflow-cdc-runtime-sizing). #### Snapshot replication During snapshot replication, the product of `fetchSize * rowSize * concurrentQueries` can't exceed the heap size of the NiFi runtime, where: - `fetchSize` is the number of rows fetched per query, set on the **Fetch Table Rows** processor (default: 100). - `rowSize` is the size of a single row being fetched. - `concurrentQueries` is the number of concurrent queries, set on the **Fetch Table Rows** processor (default: 2). This memory requirement applies even when **Oversized Value Strategy** is set to **Set Null**, because the connector must load each oversized value into memory before it can replace the value with `NULL`. If the source database contains many densely packed oversized values, consider excluding the affected column from replication before you start the snapshot. For example, if a column contains 1 GB values, loading even nine rows (~9 GB) can exhaust the heap and cause an out-of-memory error on a Medium runtime. To speed up snapshot replication, you can increase the number of channels that the **Upload Rows via Snowpipe Streaming 2** processor uses. The number of channels is set by the processor's **Channel Group** property, which defaults to `${chunk.index:isEmpty():ifElse('1', ${chunk.index:mod(8)})}`. To increase the number of channels: 1. Locate the **Upload Rows via Snowpipe Streaming 2** processor in the flow. 2. Stop the processor. You must stop the processor before you can change its properties. 3. Right-click the processor and select **Configure**. 4. Open the **Properties** tab. 5. In the **Channel Group** property, increase the value `8` in the expression. For example, change `8` to `16` to double the number of channels. 6. Apply the change. 7. Start the processor. While a snapshot replication is in progress, only increase the number of channels. Decreasing the number of channels during an active snapshot can cause data loss. #### Incremental replication When the source produces frequent changes to rows that contain large values, you might need a Large warehouse. With smaller warehouses, replicating many 8 MB rows can cause an out-of-memory error. By contrast, replicating 128 MB rows with continuous merges completes without warehouse errors, because the connector streams the data file by file through the **Upload Rows via Snowpipe Streaming 2** processor and the merge processes it gradually. ## Enable error logging on an existing schema When you set the **Error Handling Strategy** parameter to **Log Errors and Continue**, the connector enables error logging automatically only on tables that it creates afterward. Tables that the connector created earlier don't capture rejected rows until you turn on error logging for them. For more information about the error-handling strategies, see [](/user-guide/data-integration/openflow/connectors/postgres/about#label-postgres-error-handling). Because the connector stores journal tables in the same schema as the destination tables, you can turn on error logging for a whole destination schema at once. Run the following stored procedure once per destination schema. Replace `my_database` with your destination database and `my_schema` with the destination schema. The schema name is passed as a quoted identifier (for example, `'"my_schema"'`) so it matches the exact, case-sensitive name that the connector created. For more information about how the connector names destination schemas, see [](/user-guide/data-integration/openflow/connectors/postgres/setup#label-of-postgres-destination-parameters). ```sql USE DATABASE my_database; WITH enable_error_logging AS PROCEDURE (schema_name STRING) RETURNS STRING LANGUAGE SQL AS $$ DECLARE tables RESULTSET; table_count NUMBER DEFAULT 0; BEGIN SHOW TABLES IN SCHEMA IDENTIFIER(:schema_name); -- Assign AFTER SHOW TABLES so LAST_QUERY_ID() refers to that result tables := ( SELECT "database_name", "schema_name", "name" FROM TABLE(RESULT_SCAN(LAST_QUERY_ID())) WHERE "kind" = 'TABLE' ); FOR t IN tables DO -- Double-quote each identifier so names with special characters are handled safely EXECUTE IMMEDIATE 'ALTER TABLE "' || REPLACE(t."database_name", '"', '""') || '".' || '"' || REPLACE(t."schema_name", '"', '""') || '".' || '"' || REPLACE(t."name", '"', '""') || '" ' || 'SET ERROR_LOGGING = TRUE'; table_count := table_count + 1; END FOR; RETURN 'Enabled ERROR_LOGGING on ' || table_count || ' table(s) in schema ' || :schema_name; END; $$ CALL enable_error_logging('"my_schema"'); ``` ### Verify that error logging is enabled To confirm that error logging is enabled on every table in a schema, run the following procedure. It reports how many tables have error logging enabled and how many don't. ```sql USE DATABASE my_database; WITH verify_error_logging AS PROCEDURE (schema_name STRING) RETURNS STRING LANGUAGE SQL AS $$ DECLARE tables RESULTSET; probe RESULTSET; total_tables NUMBER DEFAULT 0; logging_enabled NUMBER DEFAULT 0; disabled_or_invisible NUMBER DEFAULT 0; BEGIN SHOW TABLES IN SCHEMA IDENTIFIER(:schema_name); -- Assign AFTER SHOW TABLES so LAST_QUERY_ID() refers to that result tables := ( SELECT "database_name", "schema_name", "name" FROM TABLE(RESULT_SCAN(LAST_QUERY_ID())) WHERE "kind" = 'TABLE' ); FOR t IN tables DO total_tables := total_tables + 1; -- Probe ERROR_TABLE(): it succeeds only when error logging is enabled and visible BEGIN probe := ( EXECUTE IMMEDIATE 'SELECT 1 FROM ERROR_TABLE(' || '"' || REPLACE(t."database_name", '"', '""') || '".' || '"' || REPLACE(t."schema_name", '"', '""') || '".' || '"' || REPLACE(t."name", '"', '""') || '"' || ') LIMIT 1' ); logging_enabled := logging_enabled + 1; EXCEPTION WHEN STATEMENT_ERROR THEN disabled_or_invisible := disabled_or_invisible + 1; END; END FOR; RETURN 'schema=' || :schema_name || ', total_tables=' || total_tables || ', error_logging_enabled=' || logging_enabled || ', error_logging_disabled_or_not_visible=' || disabled_or_invisible; END; $$ CALL verify_error_logging('"my_schema"'); ``` ## Upgrading PostgreSQL Upgrading the connector requires a different approach depending on whether PostgreSQL is being upgraded to the next minor or major version. Minor version upgrades - Are data-safe. - Require no special treatment. - Require stopping the connector for the duration of the upgrade to avoid reporting connectivity issues. - Continue replicating, after the upgrade, with no data loss. Major version upgrades - Require the PostgreSQL server to drop replication slots, including any used by the connector. - Cannot preserve or migrate replication slots to the new version. See also [](#label-postgres-upgrade-note). - Require restarting replication of all tables from the snapshot phase, unless you can stop all writes to the source database for the duration of the upgrade. In that case, you can keep the replicated data and resume with incremental replication only. For more information, see [](#label-postgres-upgrade-incremental-only). To perform a minor version upgrade, do the following: 1. Stop the connector, including all Processors and Controller Services. 2. Upgrade PostgreSQL. 3. Restart the connector. To perform a major version upgrade, do the following: 1. Remove all tables from replication in the connector by clearing the **Included Table Names** and **Included Table Regex** parameters. 2. Wait until all queues in the connector are empty, so that every captured change is merged into the destination tables. 3. Stop the connector, including all Processors and Controller Services. 4. Open the **Incremental Load** group in the connector. 5. Clear the state of the CDC processor: 1. Open the **Incremental Load** group in the connector. 2. Right-click the top Processor in the group, **Read PostgreSQL CDC Stream**, and select **View state**. 3. Click **Clear state**. 4. Click **Close**. 6. Upgrade PostgreSQL. 7. Restart the connector. A new replication slot will be created. 8. Re-add all tables to the **Included Table Names** or **Included Table Regex** parameters. You don't need to drop or rename the destination tables before you re-add the tables. The connector re-snapshots each table in place, which preserves the destination table object along with dependent objects such as streams. Before it loads the fresh snapshot, the connector saves a copy of the previous contents in an archive table named `_ARCHIVE_`, which you can drop once you've confirmed that the re-snapshot completed. For more information, see [](#label-of-postgres-restart-table-replication). ### Upgrade without re-snapshotting tables When an upgrade drops the replication slot, you can avoid re-snapshotting every table if you can stop all writes to the source database while you upgrade. This applies to major version upgrades and to any upgrade to PostgreSQL 17.0 from version 16 or earlier. The connector keeps the data it already replicated and continues with incremental replication only. No writes of any kind, whether DML or DDL, can reach the replicated database from the moment you stop the connector until all tables are back in incremental replication. The new replication slot starts at the current write-ahead log position, so any change made during that window is lost and there's no way to recover it without a new snapshot. To upgrade without re-snapshotting tables, do the following: 1. Remove all tables from replication in the connector by clearing the **Included Table Names** and **Included Table Regex** parameters. 2. Wait until all queues in the connector are empty, so that every captured change is merged into the destination tables. 3. Stop the connector, including all Processors and Controller Services. 4. Stop all writes to the source database, and keep them stopped for the rest of this procedure. 5. Clear the state of the CDC processor: 1. Open the **Incremental Load** group in the connector. 2. Right-click the top Processor in the group, **Read PostgreSQL CDC Stream**, and select **View state**. 3. Click **Clear state**. 4. Click **Close**. 6. Upgrade PostgreSQL. 7. In the `PostgreSQL Ingestion Parameters` context, set the `Ingestion Type` parameter to `incremental`. For more information, see [Openflow Connector for PostgreSQL: Set up incremental replication without snapshots](/user-guide/data-integration/openflow/connectors/postgres/incremental-replication). 8. Restart the connector. A new replication slot is created. 9. Re-add all tables to the **Included Table Names** or **Included Table Regex** parameters. The tables bypass the snapshot phase and replicate incrementally into the existing destination tables. 10. Confirm that every table reaches the status INCREMENTAL_REPLICATION in the **Table State Store** controller service. For instructions on viewing table state, see [](#label-of-postgres-check-table-replication-status). 11. Resume writes to the source database. 12. Set the `Ingestion Type` parameter back to `full`, so that tables you add later still get a snapshot. ### PostgreSQL 17 and later versions upgrades PostgreSQL 17 improved upgrading such that it no longer requires dropping replication slots when upgrading to later versions such as 17.1 %ra% 18.0. Upgrading to PostgreSQL 17.0 or later from prior versions (16 and earlier) drops replication slots and should be treated as a major upgrade. Future versions of PostgreSQL may also improve the upgrade process further. If the connector is using failover slot support, ensure the slot is caught up and not conflicting before starting the upgrade. See [Additional step when running pg_upgrade](/user-guide/data-integration/openflow/connectors/postgres/failover#label-postgres-failover-pg-upgrade). ## Reclaim journal table storage Journal tables hold every change to a replicated table. The connector never drops them, but it only reads the latest journal for each replicated source table, using append-only streams on top of the journals. To reclaim storage, you can: - Truncate all journal tables at any time. - Drop the journal tables related to source tables that were removed from replication. - Drop all but the latest generation journal tables for actively replicated tables. For example, if your connector is set to actively replicate source table `orders`, and you have earlier removed table `customers` from replication, you may have the following journal tables. In this case you can drop all of them *except* `orders_5678_2`. ```text customers_1234_1 customers_1234_2 orders_5678_1 orders_5678_2 ``` ## Stop or delete the connector When stopping or removing the connector, you have to consider the replication slot (https://www.postgresql.org/docs/current/warm-standby.html#STREAMING-REPLICATION-SLOTS) that the connector uses. The connector creates its own replication slot with a name starting with `snowflake_connector_` followed by a random suffix. As the connector reads the replication stream, it advances the slot, so that PostgreSQL can trim its WAL log and free up disk space. When the connector is paused, the slot isn't advanced, and changes to the source database keep increasing the WAL log size. You should not keep the connector paused for extended periods of time, especially on high-traffic databases. When the connector is removed, whether by dropping it with `DROP OPENFLOW CONNECTOR` (gen 2), deleting it from the Openflow canvas, or any other means, such as deleting the whole Openflow instance, the replication slot remains in place, and must be dropped manually. If you have multiple connector instances replicating from the same PostgreSQL database, each instance will create its own uniquely named replication slot. When dropping a replication slot manually, make sure it's the right one. You can see which replication slot is used by a given connector instance by checking the state of the `CaptureChangePostgreSQL` processor. ## Reinstall the connector This section describes how to reinstall the connector. It covers situations where the new connector is installed in the same runtime, or where it is moved to a new runtime. Reinstall is often used in conjunction with [Incremental replication without snapshots](/user-guide/data-integration/openflow/connectors/postgres/incremental-replication). For the connector to be able to continue replicating from the same CDC stream position where it stopped before reinstallation, the source database must retain the WAL long enough to cover the time between when the old connector stops and the new connector starts. Ensure the `max_wal_size` parameter of the PostgreSQL server is high enough, depending on your traffic, and keep the reinstallation time to a minimum. ### Prerequisites Review and note connector parameter context values. If you're reinstalling the connector in the same runtime, you can reuse the existing context. If the new instance will be located in a different runtime, you will have to re-enter all parameters. To reinstall the connector: 1. Finish processing all in-flight FlowFiles in the existing connector, and then stop the connector. 1. Sign in to %sf-web-interface-link%. 2. In the navigation menu, select **Ingestion** %raa% **Openflow**. 3. Select **Launch Openflow**. 4. In the **Openflow** pane select the **Runtimes** tab. 5. Select the runtime containing the connector. 6. Select the connector. 7. Stop the topmost processor **Set Tables for Replication** in the **Snapshot Load** group. 8. Stop the topmost processor **Read PostgreSQL CDC Stream** in the **Incremental Load** group. 9. If you changed the value of the **Merge Task Schedule CRON** parameter, return it to `* * * * * ?`. Otherwise, queues won't be emptied until the next scheduled run. Wait until all FlowFiles in the connector have been processed, and all queues are empty. When all FlowFiles have been processed, the **Queued** value on the connector's processor group becomes zero. If there are any items left in the original connector's queues, there may be data gaps when the new connector starts. 10. Stop all Processors and Controller Services in the connector. 2. Find and copy the name of the replication slot used by the original connector, by viewing the state of the topmost processor in the `Incremental Load` group with name `Read PostgreSQL CDC Stream`. The replication slot name is stored under the key `replication.slot.name`. Copy the value of the key to a text editor. 3. Create a new instance of the connector. If you're using the same runtime as the original connector, you can choose to keep the existing parameter contexts, and reuse the settings. The existing connector can remain in the runtime and doesn't interfere with the new instance, as long as it remains stopped. 4. If you're installing into a different runtime, or you deleted the previous parameter contexts, enter all the configuration settings into the new parameter contexts, including the table names and patterns as described in [Set up the Openflow Connector for PostgreSQL](/user-guide/data-integration/openflow/connectors/postgres/setup). 5. Open the `PostgreSQL Ingestion Parameters` context, and set `Ingestion Type` parameter to `incremental`. For more information, see [](#label-postgres-incremental-replication). 6. Open the `PostgreSQL Source Parameters` context, and set the `Replication Slot Name` parameter to the value you copied earlier. 7. Start the new connector. ### Usage notes The new connector will use the same existing destination tables that were created by the original connector, but will create new journal tables. --- title: Openflow Connector for PostgreSQL: Data mapping source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/postgres/data-mapping.md section: Loading & Unloading Data --- # %postgresql%: Data mapping This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow Connector for PostgreSQL](/user-guide/data-integration/openflow/connectors/postgres/about) - [Set up the Openflow Connector for PostgreSQL](/user-guide/data-integration/openflow/connectors/postgres/setup) This topic describes how PostgreSQL data types are mapped to Snowflake data types. ## PostgreSQL to Snowflake data type mapping The following table shows how PostgreSQL data types are mapped to Snowflake data types when replicating data.
For types with default size limits (8 MB / 16 MB) in this table, it is possible to raise these limits. For details, see [Oversized values](/user-guide/data-integration/openflow/connectors/postgres/about#label-postgres-oversized-values). Any PostgreSQL data types not listed in this table are mapped to TEXT by default. --- title: Openflow Connector for PostgreSQL: Iceberg table destinations source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/postgres/iceberg.md section: Loading & Unloading Data --- # Openflow Connector for PostgreSQL: Iceberg table destinations Available to all accounts. - [About Openflow Connector for PostgreSQL](/user-guide/data-integration/openflow/connectors/postgres/about) - [Set up the Openflow Connector for PostgreSQL](/user-guide/data-integration/openflow/connectors/postgres/setup) - [Openflow Connector for PostgreSQL: Data mapping](/user-guide/data-integration/openflow/connectors/postgres/data-mapping) - [Data types for Apache Iceberg™ tables](/user-guide/tables-iceberg-data-types) - [Snowflake storage for Apache Iceberg™ tables](/user-guide/tables-iceberg-internal-storage) - [CREATE EXTERNAL VOLUME](/sql-reference/sql/create-external-volume) The Openflow Connector for PostgreSQL supports writing to Snowflake-managed Apache %iceberg-tm% tables as an opt-in destination format. Iceberg v2 and v3 are both supported. Setting **Table Storage Format** = `ICEBERG` and choosing an **Iceberg Version** are the only connector-level changes required. The external volume, catalog, and serialization policy are inherited from the Snowflake destination database defaults. The Iceberg specification version is set via the **Iceberg Version** connector parameter, which defaults to `3` for both Gen2 (Openflow UI wizard) and Gen1 (parameter context) connectors. Storage can be either [Snowflake storage for Apache %iceberg-tm% tables](/user-guide/tables-iceberg-internal-storage) (`EXTERNAL_VOLUME = 'SNOWFLAKE_MANAGED'`) or an external volume in your cloud storage. When you use Snowflake storage, no external cloud storage or IAM grants are required. Existing connectors using standard tables aren't affected. ## Prerequisites - **Openflow runtime**: An existing runtime to host the connector. - **PostgreSQL source configured for CDC**: Logical replication enabled (`wal_level = logical`), a publication created, and a user with replication privileges. For details, see [Set up the Openflow Connector for PostgreSQL](/user-guide/data-integration/openflow/connectors/postgres/setup). - **External volume in your cloud storage**: An external volume configured for Iceberg storage, with USAGE granted to the connector's Snowflake role. See [CREATE EXTERNAL VOLUME](/sql-reference/sql/create-external-volume). Not required when using Snowflake storage (`EXTERNAL_VOLUME = 'SNOWFLAKE_MANAGED'`). - **Snowflake destination database**: An existing database configured with Iceberg parameters (next section). ## Step 1: Configure the Snowflake destination database Set the Iceberg defaults on the destination database. The connector reads these defaults at runtime for external volume and serialization policy. The Iceberg specification version is configured per-connector via the **Iceberg Version** parameter (see Step 3), not solely via the database-level `ICEBERG_VERSION_DEFAULT`. ### Option A: Snowflake storage When you use Snowflake storage, Snowflake stores and manages the Iceberg table files for you. No external cloud storage or IAM grants are required. ```sql CREATE DATABASE EXTERNAL_VOLUME = 'SNOWFLAKE_MANAGED' STORAGE_SERIALIZATION_POLICY = ; ``` To configure an existing database: ```sql ALTER DATABASE SET EXTERNAL_VOLUME = 'SNOWFLAKE_MANAGED' STORAGE_SERIALIZATION_POLICY = ; ``` ### Option B: External volume in your cloud storage If you need to keep table files in your own cloud storage, configure the database with your external volume: ```sql CREATE DATABASE EXTERNAL_VOLUME = '' STORAGE_SERIALIZATION_POLICY = ; ``` To configure an existing database: ```sql ALTER DATABASE SET EXTERNAL_VOLUME = '' STORAGE_SERIALIZATION_POLICY = ; ```
`CATALOG = 'SNOWFLAKE'` is set automatically by the connector on each CREATE ICEBERG TABLE statement. Don't set it at the database level. The base location for each table is auto-derived using the [flat layout](/user-guide/tables-iceberg-managing-external-volumes#label-tables-iceberg-snowflake-managed-flat-layout): `STORAGE_BASE_URL/database/schema/table_name.randomId/[data | metadata]/`. No user configuration is needed. If using an external volume in your cloud storage (Option B), grant the connector's Snowflake role USAGE on the external volume: ```sql GRANT USAGE ON EXTERNAL VOLUME TO ROLE ; ``` This step is not required for Snowflake storage. ## Step 2: Set Table Storage Format in the connector's parameter context Set the **Table Storage Format** parameter to `ICEBERG` in the connector's destination parameter context. The default is `STANDARD`. For the full connector creation and configuration workflow, see [Set up the Openflow Connector for PostgreSQL](/user-guide/data-integration/openflow/connectors/postgres/setup). ## Step 3: Set the Iceberg version Set the **Iceberg Version** connector parameter to `2` or `3`. This controls the Iceberg specification version used for type mapping (for example, JSON/JSONB maps to `variant` on v3 versus `string` on v2) and the `ICEBERG_VERSION=` clause in CREATE ICEBERG TABLE DDL. - **Gen2 (Openflow UI wizard)**: **Iceberg Version** is a required field when **Table Storage Format** = `ICEBERG`, defaulting to `3`. This setting is immutable after the connector configuration is first applied. - **Gen1 (parameter context)**: The **Iceberg Version** parameter defaults to `3`. Review and change to `2` if needed before starting the connector. Do not change this value after ingestion begins. ## Step 4: Start and verify Start the connector as usual. After the initial snapshot completes, verify the destination tables are Iceberg: ```sql -- Confirm the table is Iceberg SELECT GET_DDL('TABLE', '..
Oracle type Snowflake (Standard) Iceberg v3 Iceberg v2
NUMBER(P,S) (P ≤ 38) NUMBER(P,S) `decimal(P,S)` `decimal(P,S)`
NUMBER (no precision) NUMBER(38,19) `decimal(38,19)` `decimal(38,19)`
INTEGER / SMALLINT / INT NUMBER(38,0) `decimal(38,0)` `decimal(38,0)`
FLOAT(P) FLOAT `double` `double`
BINARY_FLOAT FLOAT `double` `double`
BINARY_DOUBLE FLOAT `double` `double`
BOOLEAN (Oracle 23ai+) BOOLEAN `boolean` `boolean`
DATE TIMESTAMP_NTZ `timestamp` `timestamp`
TIMESTAMP(0..6) TIMESTAMP_NTZ `timestamp` `timestamp`
TIMESTAMP(7..9) TIMESTAMP_NTZ `timestamp_ns` `timestamp` (truncated)
TIMESTAMP(0..6) WITH TIME ZONE TIMESTAMP_TZ `timestamptz` `timestamptz`
TIMESTAMP(7..9) WITH TIME ZONE TIMESTAMP_TZ `timestamptz_ns` `timestamptz` (truncated)
TIMESTAMP WITH LOCAL TIME ZONE (0..6) TIMESTAMP_LTZ `timestamptz` `timestamptz`
TIMESTAMP WITH LOCAL TIME ZONE (7..9) TIMESTAMP_LTZ `timestamptz_ns` `timestamptz` (truncated)
INTERVAL YEAR TO MONTH TEXT `string` `string`
INTERVAL DAY TO SECOND TEXT `string` `string`
CHAR / NCHAR / VARCHAR2 / NVARCHAR2 TEXT `string` `string`
CLOB / NCLOB / LONG TEXT `string` `string`
RAW BINARY `binary` `binary`
BLOB / LONG RAW BINARY `binary` `binary`
JSON (Oracle 21c+) VARIANT `variant` `string`
XMLTYPE TEXT `string` `string`
ROWID / UROWID TEXT `string` `string`
Parameter Description
Starting XStream Position - `Latest` (default): CDC stream reading starts at the latest available position and continues from there. - `Earliest`: Switches the incremental load to start, or restart reading from the earliest available XStream position.
Re-read Tables in State - `New` (default): While re-reading the redo logs, only those LCRs (Logical Change Records) will be processed from new tables added to replication after the re-reading started. Other LCRs are discarded until the connector reaches the position just before re-reading started. - `Any active`: Re-read and re-process events from any table currently in replication.
PostgreSQL type Snowflake type Notes
SMALLINT / INT2 INT
INTEGER / INT / INT4 INT
BIGINT / INT8 INT
SMALLSERIAL / SERIAL2 INT
SERIAL / SERIAL4 INT
BIGSERIAL / SERIAL8 INT
NUMERIC / DECIMAL NUMBER Scale and precision are preserved within Snowflake limitations. Negative scale is converted to scale 0 with adjusted precision.
REAL / FLOAT4 FLOAT
DOUBLE PRECISION / FLOAT8 FLOAT
MONEY FLOAT
BOOLEAN / BOOL BOOLEAN
CHARACTER / CHAR / BPCHAR TEXT
CHARACTER VARYING / VARCHAR TEXT Supported by default up to 16 MB.
TEXT TEXT Supported by default up to 16 MB.
BYTEA BINARY Supported by default up to 8 MB.
DATE DATE
TIME / TIME WITHOUT TIME ZONE TIME
TIME WITH TIME ZONE / TIMETZ TIMESTAMP_TZ
TIMESTAMP / TIMESTAMP WITHOUT TIME ZONE TIMESTAMP_NTZ
TIMESTAMP WITH TIME ZONE / TIMESTAMPTZ TIMESTAMP_LTZ
INTERVAL TEXT
JSON VARIANT Supported by default up to 16 MB.
JSONB VARIANT Supported by default up to 16 MB.
UUID TEXT
XML TEXT Supported by default up to 16 MB.
BIT TEXT
BIT VARYING / VARBIT TEXT
POINT TEXT
LINE TEXT
LSEG TEXT
BOX TEXT
PATH TEXT
POLYGON TEXT
CIRCLE TEXT
CIDR TEXT
INET TEXT
MACADDR TEXT
MACADDR8 TEXT
TSVECTOR TEXT
TSQUERY TEXT
PG_LSN TEXT
Parameter Required Notes
EXTERNAL_VOLUME Yes The external volume for Iceberg file storage.
ICEBERG_VERSION_DEFAULT No `2` or `3`. Legacy fallback for older connector flows where the **Iceberg Version** parameter is unset. New connectors set the version via the connector parameter (Step 3) and do not require this database setting.
STORAGE_SERIALIZATION_POLICY Yes `COMPATIBLE` produces Parquet files readable by external engines. `OPTIMIZED` enables Snowflake-specific query optimizations. Choose based on your data query needs. For more information, see [STORAGE_SERIALIZATION_POLICY](/sql-reference/parameters#storage-serialization-policy).
'); -- Confirm the Iceberg version on the database SHOW PARAMETERS LIKE 'ICEBERG_VERSION_DEFAULT' IN DATABASE ; ``` ## Known limitations - **Tri-Secret Secure accounts and Snowflake storage**: Accounts with Tri-Secret Secure (TSS) enabled may be unable to create new Snowflake-managed Iceberg tables that use [Snowflake storage for Apache %iceberg-tm% tables](/user-guide/tables-iceberg-internal-storage). For details, see [Encryption](/user-guide/tables-iceberg-internal-storage#encryption). - **Incompatible type change:** When the source column type changes to a type that maps to a different Iceberg type, the table is marked as failed and requires a resnapshot. See [Type mapping reference](#type-mapping-reference) for the complete source-to-Iceberg type mapping. - **Parameter change within the same Iceberg type:** The connector doesn't recognize parameter changes within the same Iceberg type (for example, changing `decimal(10,2)` to `decimal(20,2)`). The column retains its current Iceberg type. - **TIMETZ offset not preserved**: Iceberg `timestamptz` stores only the UTC instant. PostgreSQL TIMETZ values lose the original timezone offset when written to Iceberg tables. - **Do not change Table Storage Format or Iceberg Version after the connector starts**: The connector's **Table Storage Format** and **Iceberg Version** parameter should not be modified after ingestion begins. Gen2 connectors enforce this by making **Iceberg Version** immutable after first apply. Mixing settings across destination tables is not supported. To switch, follow the steps in [Switching table storage format or Iceberg version](#switching-table-storage-format-or-iceberg-version). ## Type mapping reference The following table shows how PostgreSQL types map to Snowflake standard and Iceberg destination types:
Source types not listed in the table are mapped to TEXT on standard tables and `string` on Iceberg tables. ## Switching table storage format or Iceberg version Switching between Standard and Iceberg, or between Iceberg v2 and v3, requires recreating the connector. Follow these steps: 1. Stop the connector. 2. Delete the process group in Openflow. 3. Manually clean up the destination database (drop the replicated schemas/tables, or use a new database). 4. Reimport the connector with the new **Table Storage Format** and select the target **Iceberg Version** when configuring the connector. This ensures all connector state is correctly cleaned up within Openflow. The new connector performs a fresh snapshot into the destination. ## Upgrading an existing connector to use Iceberg Version pinning Gen2 connector version `2026.7.21` and Gen1 connector version `0.60.0` introduce the **Iceberg Version** parameter. If you are upgrading from an earlier connector version (for example, Gen1 `0.56.0` to `0.60.0` or later), a new **Iceberg Version** field appears that you must configure to match your existing destination tables. 1. Stop the connector. 2. [Upgrade the runtime](/user-guide/data-integration/openflow/manage#label-openflow-upgrading-a-runtime) to version `2026.7.21` or later. 3. [Upgrade the connector](/user-guide/data-integration/openflow/manage#upgrade-a-connector) in place (Gen2: to version `2026.7.21` or later; Gen1: to version `0.60.0` or later). 4. Set the **Iceberg Version** parameter to match your existing destination tables: - **Gen2 (Openflow UI wizard)**: After upgrading, open the connector configuration wizard. The **Destination details** step now includes a required **Iceberg Version** field, defaulting to `3`. If your existing destination tables are Iceberg v2, change it to `2` before applying. This choice is locked after first apply and cannot be changed later. - **Gen1 (parameter context)**: The **Iceberg Version** parameter defaults to `3` after the flow upgrade. If your existing destination tables are Iceberg v2, change it to `2` before starting the connector. 5. Start the connector. Selecting an **Iceberg Version** that doesn't match your existing destination tables can cause type-mapping errors or DDL failures. Always verify the version of your existing tables before choosing a value. ## References - [CREATE EXTERNAL VOLUME](/sql-reference/sql/create-external-volume) - [Data types for Apache Iceberg tables](/user-guide/tables-iceberg-data-types) - [ALTER DATABASE](/sql-reference/sql/alter-database) - [STORAGE_SERIALIZATION_POLICY](/sql-reference/parameters#storage-serialization-policy) - [Set up the Openflow Connector for PostgreSQL](/user-guide/data-integration/openflow/connectors/postgres/setup) --- title: Openflow Connector for PostgreSQL: PostgreSQL 17+ failover slot support source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/postgres/failover.md section: Loading & Unloading Data --- # %postgresql%: PostgreSQL 17+ failover slot support This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow Connector for PostgreSQL](/user-guide/data-integration/openflow/connectors/postgres/about) - [Set up the Openflow Connector for PostgreSQL](/user-guide/data-integration/openflow/connectors/postgres/setup) - [Openflow Connector for PostgreSQL Maintenance](/user-guide/data-integration/openflow/connectors/postgres/maintenance) Requires runtime-extensions 2026.7.16.14 or later. Applies to PostgreSQL 17 and later only. On PostgreSQL 17 and later, the connector creates its logical replication slot with `failover=true`. The slot is synchronized to standbys by PostgreSQL and survives: - A primary failover: replication resumes from the new primary. - A major-version upgrade through `pg_upgrade` (for example, 17 → 18), provided the slot is caught up and not conflicting or invalidated at upgrade time. The connector must be pointed at the primary to get failover protection. PostgreSQL does not allow `failover=true` on slots created against a standby. If the JDBC URL resolves to a read replica, the slot on that node will not have failover protection. Version is auto-detected. No new connector property is required. ## Limitations - PostgreSQL 16 and earlier versions are unchanged. Failover protection is not available on those versions as this is a native PostgreSQL feature that does not exist before PostgreSQL 17. - Upgrading the connector alone does not retrofit failover onto an existing slot. The connector only sets `failover=true` at slot creation time. To gain failover protection on an existing deployment, see [Retrofit failover protection on an existing deployment](#label-retrofit-failover-protection-on-an-existing-deployment). - Delivery is at-least-once across a failover. The connector de-duplicates on reconnect. - The connector does not validate the PostgreSQL configuration described in this topic. If it is missing, `failover=true` is inert and the slot will not survive a failover. ## Required PostgreSQL configuration The following configuration must be set by the user. The connector can't set these. - Point the JDBC URL at the primary's writer endpoint so the connector reconnects to the new primary after a failover. To confirm the connector is connected to the primary, run the following against the connected database. The result must be `false` (false = primary, true = standby): ```sql SELECT pg_is_in_recovery(); ``` - On the primary, set `synchronized_standby_slots` to list the physical replication slot names of the failover-candidate standbys. Without it, the failover slot may advance faster than the standby receives WAL: ```ini synchronized_standby_slots = '' ``` - On each failover-candidate standby, set the following: - `wal_level = logical` (already required on the primary): set this on standbys so it takes effect on promotion. - `sync_replication_slots = on` - `hot_standby_feedback = on` - `primary_conninfo` must include `dbname=` (PostgreSQL 17 requirement). - `primary_slot_name` must reference a physical slot listed in `synchronized_standby_slots` on the primary. ## Retrofit failover protection on an existing deployment To gain failover protection on an existing deployment, there are two paths available: with re-snapshot or without re-snapshot. Follow the procedure for the path you choose. ### Retrofit failover protection without re-snapshotting Process all existing FlowFiles in the existing connector before you start the new one. The existing connector should have no FlowFiles in queue and should have all processors stopped. Any writes between stopping the existing connector and starting the new connector will not be delivered to Snowflake. Once a slot is dropped, PostgreSQL can't replay old WAL. If you can't guarantee a write-free window, use [Retrofit failover protection with re-snapshot](#label-retrofit-with-re-snapshot) instead. Do not add new tables while the connector is in incremental mode. New tables will not be snapshotted. 1. Ensure the connector is fully caught up before proceeding. The `confirmed_flush_lsn` should match `pg_current_wal_lsn()`: ```sql SELECT slot_name, confirmed_flush_lsn, pg_current_wal_lsn() FROM pg_replication_slots; ``` 2. Pause writes on the source tables by running the following against your PostgreSQL source database. Replace `` and `` with your values: ```sql REVOKE INSERT, UPDATE, DELETE ON ALL TABLES IN SCHEMA FROM ; ``` 3. Wait until all queues in the connector are empty. 4. Stop the connector and disable all Controller Services. 5. Drop the replication slot. The slot name is in the `CaptureChangePostgreSQL` processor state under `replication.slot.name`, or in `pg_replication_slots`: ```sql SELECT pg_drop_replication_slot(''); ``` 6. In the parameter context, set **Ingestion Type** to `incremental`. To set this, go to **Ingestion Parameters** → **Ingestion Type** → edit the value to `incremental`. 7. Install a new connector. In the top menu, drag down **Import from registry**. Select **postgresql** from **Flow**, select **Keep existing Parameter contexts** to reuse the same parameter context as the existing connector, then click **Import**. 8. Start the connector fully, including all Processors and Controller Services. 9. Verify the new slot was created with `failover=true` by running the following against your PostgreSQL source database: ```sql SELECT slot_name, failover FROM pg_replication_slots; ``` 10. Resume writes: ```sql GRANT INSERT, UPDATE, DELETE ON ALL TABLES IN SCHEMA TO ; ``` 11. Optionally, delete the existing connector to prevent accidentally resuming it. Once all existing tables are in **Incremental Replication**, change **Ingestion Type** from `incremental` to `full`. To verify, in Snowsight go to **Ingestion** → **Openflow** → **Connector Observability**, select your connector, and confirm all tables show **Incremental Replication** in the **Replication Phase** column. ### Retrofit failover protection with re-snapshot Individual change events that occur on the source between dropping the slot and completing the re-snapshot are not delivered as CDC events. They are absorbed into the snapshot's final row values. 1. In the connector, remove all tables from replication by clearing the **Included Table Names** and **Included Table Regex** parameters. 2. Wait until all queues in the connector are empty. 3. Stop the connector, including all Processors and Controller Services. 4. Drop the replication slot. The slot name is in the `CaptureChangePostgreSQL` processor state under `replication.slot.name`, or in `pg_replication_slots`: ```sql SELECT pg_drop_replication_slot(''); ``` 5. Install a new connector. In the top menu, drag down **Import from registry**. Select **postgresql** from **Flow**, select **Keep existing Parameter contexts** to reuse the same parameter context as the existing connector, then click **Import**. 6. Re-add tables to **Included Table Names**. 7. Start the new connector fully, including all Processors and Controller Services. The connector creates a new replication slot with `failover=true` and snapshots the tables fresh. Verify the new slot has `failover=true`: ```sql SELECT slot_name, failover FROM pg_replication_slots; ``` ## Additional step when running pg_upgrade This step is only needed during a major-version upgrade. It is not part of the general setup. Ensure the connector is caught up and the slot is not conflicting or invalidated before starting `pg_upgrade`: ```sql SELECT slot_name, conflicting, invalidation_reason FROM pg_replication_slots; ``` --- title: Openflow Connector for PostgreSQL: Set up incremental replication without snapshots source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/postgres/incremental-replication.md section: Loading & Unloading Data --- # %postgresql%: Set up incremental replication without snapshots This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Set up the Openflow Connector for PostgreSQL](/user-guide/data-integration/openflow/connectors/postgres/setup) - [Openflow Connector for PostgreSQL: Data mapping](/user-guide/data-integration/openflow/connectors/postgres/data-mapping) You can configure the %postgresql% connector to immediately replicate incremental changes for newly added tables, bypassing snapshots. Use incremental load to continue replication without snapshotting every table again when you reinstall the connector over previously replicated data. To enable incremental replication in a new connector instance: 1. Set up the connector as described in [Set up the Openflow Connector for PostgreSQL](/user-guide/data-integration/openflow/connectors/postgres/setup). 2. In the `PostgreSQL Ingestion Parameters` context, set the `Ingestion Type` parameter to `incremental`. ## Enable incremental replication without snapshots To enable incremental replication on an existing connector: 1. sign in to %sf-web-interface-link%. 2. in the navigation menu, select **Ingestion** %raa% **Openflow**. 3. In the **Openflow** pane select the **Runtimes** tab. 4. Select the runtime containing the connector. 5. Select the connector. 6. In the `Ingestion Parameters` context, specify `Ingestion Type` = `incremental`. 7. Add new replication tables. These tables immediately switch to their incremental load. To return to replicating tables with the snapshot load, change **Ingestion Type** from `incremental` to `full`. # Usage notes - Changing the value of **Ingestion Type** does not impact any tables that have begun replicating data. Tables currently in the snapshot phase continue until the snapshot load is complete. - While **Ingestion Type** is set to `incremental`, new tables added to the list of replicated tables bypass the snapshot phase. This includes new tables added to the source database that match the `Included Table Regex` parameter. Ensure that the ingestion type is set to `incremental` to bypass the snapshot phase. Connectors should only remain in `incremental` mode as long as required as it bypasses snapshots. Once customer needs for incremental updates have been satisfied the connector should be returned to `full` mode. - For tables that bypass snapshot load, the connector creates a destination table in Snowflake, by executing `CREATE TABLE IF NOT EXISTS`, only if no destination table already exists. Tables going through the snapshot require that no destination table exist. --- title: Openflow Connector for Salesforce Bulk API: Configure the connector source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/configure-connector.md section: Loading & Unloading Data --- # %salesforcebulkapiof%: Configure the connector This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About the Openflow Connector for Salesforce Bulk API](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/about) - [Openflow Connector for Salesforce Bulk API: Set up Snowflake](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/setup-snowflake) - [Openflow Connector for Salesforce Bulk API: Set up Salesforce](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/setup-salesforce) - [Openflow Connector for Salesforce Bulk API: Iceberg table destinations](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/iceberg) - [Openflow Connector for Salesforce Bulk API: Salesforce formula fields](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/formula-fields) - [Monitor the Openflow Connector for Salesforce Bulk API](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/monitor) - [Troubleshooting the Openflow Connector for Salesforce Bulk API](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/troubleshoot) This topic describes the steps to configure the %salesforcebulkapiof%. ## Install the connector Follow these steps to install the %salesforcebulkapiof% in an Openflow runtime: 1. Navigate to the Openflow **Overview** page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find **Openflow connector for Salesforce Bulk API** and select **Install**. 3. In the **Select runtime** dialog, select your runtime from the **Available runtimes** drop-down. The Openflow canvas appears with the connector process group added to it. ## Configure the connector To configure the connector, perform the following steps: 1. Right-click on the imported process group and select **Parameters**. 2. Populate the required parameter values as described in the table below.
## Verify the Salesforce connection Before enabling and starting the connector, Snowflake recommends verifying that the Salesforce authentication is properly configured. The **Verification** feature on controller services lets you test the connection without starting the full connector flow. The **JWT Bearer OAuth2 Access Token Provider** controller service depends on two other controller services that must be enabled first: the **Salesforce Private Key Service** and the **Web Client Service Provider**. 1. Double-click the connector process group to open it. 2. Right-click on an empty area of the canvas and select **Controller Services**. 3. Enable the **Salesforce Private Key Service** and the **Web Client Service Provider** services. 4. Locate the **JWT Bearer OAuth2 Access Token Provider** service in the list. 5. Click the **Verification** button for the service. A dialog opens where you can provide property overrides. You can ignore this and click **Verify** directly. 6. If everything is configured properly, the **Acquire token** step shows a green checkmark indicating success. This confirms the connector can authenticate with Salesforce and obtain an access token. You can proceed to the next step to run the connector. 7. If verification fails, review the error message and check the following: - The **OAuth2 Client ID** parameter matches the **Consumer Key** from the external client app in Salesforce. - The private key corresponds to the certificate uploaded to the external client app. - The **OAuth2 Subject** user is authorized for the external client app (see [](#salesforce-approve-client-app)). - The **OAuth2 Token Endpoint URL** uses the correct Salesforce instance hostname. - The **OAuth2 Audience** is set to the correct value: `https://login.salesforce.com` for production or `https://test.salesforce.com` for sandboxes. For detailed troubleshooting, see [Troubleshooting the Openflow Connector for Salesforce Bulk API](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/troubleshoot). ## Run the connector Follow these steps to start the connector and begin replicating data from Salesforce to Snowflake: 1. Right-click on an empty area in the canvas and select **Enable all Controller Services**. 2. Right-click on the connector process group and select **Start**. ## Manage object replication After the connector has been started and objects have been replicated, you can add new objects or remove existing objects from replication. ### Add new objects to replication To add a new object to replication, update the **Filter** parameter (or **Special Objects Filter** parameter, if applicable) with the new object names. You do not need to stop the connector. The new object is replicated at the next scheduled execution. For example, if the current **Filter** value is `Account, Opportunity` and you want to add the `Contact` object, change the value to `Account, Opportunity, Contact`. ### Remove objects from replication Removing an object from replication requires stopping the connector and cleaning up both the connector state and the destination table in Snowflake: 1. Stop all processors in the flow by right-clicking on the connector process group and selecting **Stop**. 2. Ensure that no in-flight FlowFiles are being processed. 3. Right-click on the canvas and select **Parameters**, then remove the object name from the **Filter** parameter (or the **Special Objects Filter** parameter, if applicable). 4. Right-click on the canvas and select **Disable all controller services**. 5. Go to **Controller services** and open the state of the controller service named **Salesforce Bulk Jobs State**. 6. Select the trash icon next to the object type you removed to delete its state entry. 7. Right-click on the canvas and select **Enable all controller services**, then start all processors to resume the connector. 8. If applicable, drop the corresponding table from the Snowflake destination database to clean up the previously replicated data. For example: ```sql DROP TABLE ..; ``` ## Configure blob field ingestion The Salesforce Bulk API 2.0 does not support binary (base64-encoded) fields. The connector handles these fields through a dedicated Non-Bulk API path that uses the Salesforce REST Query API. Objects with blob fields must be listed in the **Special Objects Filter** parameter so they are routed to this path. To enable blob field ingestion, set **Enable Capture Blob Fields** to `true` in the connector parameters. ## Next steps - To monitor replication activity and merge metrics, see [Monitor the Openflow Connector for Salesforce Bulk API](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/monitor). - To diagnose connector issues, see [Troubleshooting the Openflow Connector for Salesforce Bulk API](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/troubleshoot). --- title: Openflow Connector for Salesforce Bulk API: Iceberg table destinations source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/iceberg.md section: Loading & Unloading Data --- # %salesforcebulkapiof%: Iceberg table destinations Available to all accounts. - [About the Openflow Connector for Salesforce Bulk API](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/about) - [Openflow Connector for Salesforce Bulk API: Set up Snowflake](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/setup-snowflake) - [Openflow Connector for Salesforce Bulk API: Configure the connector](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/configure-connector) - [Openflow Connector for Salesforce Bulk API: Salesforce formula fields](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/formula-fields) - [Snowflake storage for Apache Iceberg™ tables](/user-guide/tables-iceberg-internal-storage) - [CREATE EXTERNAL VOLUME](/sql-reference/sql/create-external-volume) The %salesforcebulkapiof% supports writing to Snowflake-managed Apache %iceberg-tm% tables as an opt-in destination format. The connector supports Iceberg v2 and v3. Existing connectors that write to standard Snowflake tables aren't affected. To use Iceberg table destinations, configure the Snowflake destination database with Iceberg defaults, then set the connector's **Table Storage Format** parameter to `ICEBERG` and choose an **Iceberg Version** before the connector creates destination tables. ## Prerequisites Before you begin: - Complete the steps in [Openflow Connector for Salesforce Bulk API: Set up Snowflake](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/setup-snowflake). - Choose either Snowflake storage or an external volume in your cloud storage for the Iceberg table files. ## Configure the destination database Configure the destination database with Iceberg defaults before starting the connector. The connector reads the database defaults for the external volume and storage serialization policy when it creates Iceberg tables. ### Option A: Snowflake storage To use [Snowflake storage for Apache %iceberg-tm% tables](/user-guide/tables-iceberg-internal-storage), configure the database with `EXTERNAL_VOLUME = 'SNOWFLAKE_MANAGED'`: ```sql ALTER DATABASE SET EXTERNAL_VOLUME = 'SNOWFLAKE_MANAGED' STORAGE_SERIALIZATION_POLICY = ; ``` With Snowflake storage, Snowflake stores and manages the Iceberg table files. You don't need to configure external cloud storage or grant access to an external volume. ### Option B: External volume in your cloud storage To store the Iceberg table files in your cloud storage, configure the database with the external volume: ```sql ALTER DATABASE SET EXTERNAL_VOLUME = '' STORAGE_SERIALIZATION_POLICY = ; ``` `COMPATIBLE` produces Parquet files readable by external engines. `OPTIMIZED` enables Snowflake-specific query optimizations. Choose based on your data query needs. For more information, see [STORAGE_SERIALIZATION_POLICY](/sql-reference/parameters#storage-serialization-policy). Grant the connector role `USAGE` on the external volume: ```sql GRANT USAGE ON EXTERNAL VOLUME TO ROLE ; ``` This grant isn't required when you use Snowflake storage (`EXTERNAL_VOLUME = 'SNOWFLAKE_MANAGED'`). `CATALOG = 'SNOWFLAKE'` is set automatically by the connector when it creates Iceberg tables. Don't set it at the database level. ## Configure the connector Set the following destination parameters before the connector creates destination tables: - **Table Storage Format**: Set to `ICEBERG`. The default is `STANDARD`. - **Iceberg Version**: Set to `2` or `3`. The default is `3`. Don't change **Table Storage Format** or **Iceberg Version** after ingestion begins. To switch between standard and Iceberg destinations, or between Iceberg v2 and v3, recreate the connector and perform a fresh load into new destination tables. For the full connector configuration workflow, see [Openflow Connector for Salesforce Bulk API: Configure the connector](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/configure-connector). ## Verify Iceberg table creation After the initial load completes, verify that the destination tables were created as Iceberg tables: ```sql SELECT GET_DDL('TABLE', '..'); ``` The returned DDL should include `ICEBERG TABLE`. You can also verify the database-level Iceberg defaults: ```sql SHOW PARAMETERS LIKE 'EXTERNAL_VOLUME' IN DATABASE ; SHOW PARAMETERS LIKE 'STORAGE_SERIALIZATION_POLICY' IN DATABASE ; ``` ## Limitations and behavior - **Tri-Secret Secure accounts and Snowflake storage**: Accounts with Tri-Secret Secure (TSS) enabled may be unable to create new Snowflake-managed Iceberg tables that use [Snowflake storage for Apache %iceberg-tm% tables](/user-guide/tables-iceberg-internal-storage). For details, see [Encryption](/user-guide/tables-iceberg-internal-storage#encryption). - **Collation isn't supported on Iceberg tables**: When **Table Storage Format** is set to `ICEBERG`, the connector doesn't include `DEFAULT_DDL_COLLATION` in table creation parameters. - **Salesforce time fields use microsecond precision**: Salesforce fields of type `time` are created as `TIME(6)` on Iceberg tables. - **Formula views can be created over Iceberg tables**: When **Enable Views Creation** is set to `true`, the connector can create formula views over Iceberg base tables. The formula field limitations described in [Openflow Connector for Salesforce Bulk API: Salesforce formula fields](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/formula-fields) still apply. - **Hard deletes aren't supported**: The connector still represents deleted Salesforce records with the `isDeleted` column rather than hard-deleting rows from the destination table. --- title: Openflow Connector for Salesforce Bulk API: Salesforce formula fields source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/formula-fields.md section: Loading & Unloading Data --- # %salesforcebulkapiof%: Salesforce formula fields This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About the Openflow Connector for Salesforce Bulk API](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/about) - [Openflow Connector for Salesforce Bulk API: Configure the connector](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/configure-connector) This topic describes how the %salesforcebulkapiof% translates Salesforce formula fields into Snowflake SQL views, including supported functions and limitations. ## How formula views work When **Enable Views Creation** is set to `true`, the connector performs the following for each object that has formula fields: 1. Retrieves the formula expressions from the Salesforce object metadata via the Describe API. 2. Parses each formula expression and translates it into equivalent Snowflake SQL. 3. Generates a `CREATE OR REPLACE VIEW` statement that combines non-formula columns from the base table with the translated formula expressions as computed columns. 4. Runs the DDL against Snowflake to create or update the view. The resulting view is named `_FORMULA_VW`. For example, the `Account` object produces a view named `ACCOUNT_FORMULA_VW`. You can query this view to obtain formula field values alongside the replicated data. The view is automatically updated whenever the connector detects schema changes in the source object, ensuring that formula definitions stay in sync with Salesforce. ## Cross-object formula fields Salesforce formulas can reference fields from related objects using relationship traversal (for example, `Account.Owner.Name`). The connector supports these cross-object references by generating `LEFT JOIN` clauses in the view definition. Each relationship traversal produces a join to the corresponding related table in Snowflake. For cross-object formulas to work correctly, the related objects must also be replicated by the connector. If a related object is not being synced, the formula columns that reference it are replaced with a typed `NULL` in the view. The remaining formula columns continue to compute normally. The affected columns have a `LOOKUP_NOT_SYNCED` comment. Once the referenced objects are added to replication and synced, the view is automatically rebuilt on the next connector run. ## Chained formula fields Formula fields that reference other formula fields (chained formulas) are supported. The connector resolves the dependency graph before SQL generation and expands each referenced formula field's expression into the referencing formula's AST. Multi-hop chains are fully expanded. If a dependency cannot be translated, the dependent field also returns `NULL` and the column comment indicates `FORMULA_CHAIN_NOT_SUPPORTED`. ## Formula view column comments Each formula column in the generated view includes a SQL `COMMENT` annotation: - For successfully translated formulas, the comment contains the original Salesforce formula expression. - For formulas that could not be translated, the comment contains the failure reason code followed by the original Salesforce formula expression, separated by a colon (for example, `FUNCTION_NOT_SUPPORTED: IMAGE(url, 'alt')`). You can inspect these comments by running `DESCRIBE VIEW ` in Snowflake. ## Supported formula functions The following Salesforce formula functions are translated into equivalent Snowflake SQL:
In addition to functions, the following operators are supported: - Arithmetic: `+`, `-`, `*`, `/`, `^` (exponentiation, translated to `POWER`) - Comparison: `=`, `==`, `!=`, `<>`, `<`, `<=`, `>`, `>=` - Logical: `AND`, `OR`, `&&`, `||` - String concatenation: `&` (translated to `||` with `COALESCE` null handling) - Unary: `-` (negation), `NOT` ## Unsupported formula constructs The following formula constructs are not yet supported. Support for additional functions and constructs will be added in future releases. When a formula uses any of these, the corresponding column in the view returns `NULL` and the column comment indicates the failure reason.
--- title: Openflow Connector for Salesforce Bulk API: Set up Salesforce source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/setup-salesforce.md section: Loading & Unloading Data --- # %salesforcebulkapiof%: Set up Salesforce This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About the Openflow Connector for Salesforce Bulk API](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/about) - [Openflow Connector for Salesforce Bulk API: Set up Snowflake](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/setup-snowflake) - [Openflow Connector for Salesforce Bulk API: Configure the connector](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/configure-connector) This topic describes the steps to set up Salesforce for the %salesforcebulkapiof%. The connector authenticates with Salesforce using the OAuth 2.0 JWT Bearer Flow. This requires creating a certificate key pair, configuring an external client app in Salesforce, and authorizing a user to use the app. Salesforce has deprecated Connected Apps in favor of External Client Apps. If you have an existing Connected App, Snowflake recommends creating a new External Client App instead. ## Create certificates You need a private key and public certificate to configure the external client app in Salesforce. The private key is used by the connector to sign JWT tokens, and the public certificate is uploaded to the external client app in Salesforce so that Salesforce can verify the signature. 1. Generate the private key. You are asked for a password to secure the private key. ```bash openssl genpkey -algorithm RSA -out private.key -aes256 ``` Record the password. You need it when configuring the connector parameters in Snowflake. 2. Create a self-signed certificate from the private key. ```bash openssl req -new -x509 -key private.key -out public.crt -days 365 ``` You can also generate a Certificate Signing Request (CSR) to have a certificate signed by your company CA. You are responsible for safeguarding and rotating the public key and private key files used for key-pair authentication according to the security policies of your organization. ## Create an external client app in Salesforce Create an external client app in Salesforce with JWT Bearer Flow. The connector requires this specific OAuth flow to authenticate. Using a different OAuth flow (such as Authorization Code Flow) causes `invalid_grant` errors. 1. Log in to Salesforce as an administrator. 2. Go to **Setup** %ra% **Apps** %ra% **App Manager**, and then select **New External Client App**. 3. Fill in the required fields: - **External Client App Name**: For example, `Openflow connector for Salesforce Bulk API`. - **Contact Email**: For example, `salesforceadmin@mycompany.com`. 4. In the **API (Enable OAuth Settings)** section, select the **Enable OAuth** checkbox. 5. Provide a valid **Callback URL** (for example, `https://www.google.com/`). The callback URL is required by Salesforce, but it is not used by the JWT Bearer Flow. You can provide any valid URL. 6. Provide the desired **OAuth Scopes** for the application. The following scopes are required for the connector to operate properly: - Manage user data via APIs (`api`) - Perform requests at any time (`refresh_token`, `offline_access`) 7. In **Flow Enablement**, select the **Enable JWT Bearer Flow** checkbox and upload the `public.crt` file created in the previous step. You must select **Enable JWT Bearer Flow** specifically. Do not enable other flows unless you have a specific reason to do so. The certificate you upload here must correspond to the private key (`private.key`) that you configure in the connector parameters. 8. Click **Create** to complete the application creation process. 9. Go to the **Settings** tab, expand the **OAuth Settings** section, and click **Consumer Key and Secret** to retrieve the credentials of your application. 10. Record the values for the **Consumer Key** and the **Consumer Secret** for use when configuring the connector in Snowflake. The **Consumer Key** is used as the **OAuth2 Client ID** parameter in the connector configuration. ## Approve the client app for a user The connector interacts with Salesforce APIs on behalf of a specific user (the OAuth2 Subject configured in the connector parameters). You must authorize this user to use the external client app by assigning the appropriate profiles or permission sets. If this step is not completed, the connector receives a permission error when attempting to authenticate, even if the JWT Bearer Flow is configured correctly. 1. Go to the **Policies** tab of the client application. 2. Click **Edit**. 3. Expand the **OAuth Policies** section and change **Permitted Users** to **Admin approved users are pre-authorized**. 4. Expand the **App Policies** section and select the profiles or permission sets that are assigned to the Salesforce user you want the connector to use. For example, if the user has the `System Administrator` profile, select that profile. The user specified as the **OAuth2 Subject** in the connector configuration must belong to at least one of the profiles or permission sets selected here. If the user is not authorized, you receive a permission error when verifying or running the connector. 5. Click **Save**. ## Verify credentials match Before proceeding to the Snowflake setup, confirm that the following credentials all belong to the same external client app and key pair: - The **Consumer Key** (Client ID) was retrieved from the external client app you just created. - The **private key** (`private.key`) corresponds to the **certificate** (`public.crt`) uploaded to the same external client app. - The **OAuth2 Subject** (user) is authorized for this external client app through the profile or permission set assignment. If you have created multiple external client apps or experimented with different configurations, mixing credentials from different apps or key pairs is a common source of `invalid_grant` errors. When in doubt, create a new external client app with a fresh certificate and key pair. ## Next steps Perform the Snowflake setup tasks: [Openflow Connector for Salesforce Bulk API: Set up Snowflake](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/setup-snowflake) --- title: Openflow Connector for Salesforce Bulk API: Set up Snowflake source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/setup-snowflake.md section: Loading & Unloading Data --- # %salesforcebulkapiof%: Set up Snowflake This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About the Openflow Connector for Salesforce Bulk API](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/about) - [Openflow Connector for Salesforce Bulk API: Set up Salesforce](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/setup-salesforce) - [Openflow Connector for Salesforce Bulk API: Configure the connector](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/configure-connector) - [Openflow Connector for Salesforce Bulk API: Iceberg table destinations](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/iceberg) This topic describes the steps to set up Snowflake for the %salesforcebulkapiof%. ## Prerequisites Before you begin, ensure you have completed the following: - Install Openflow (either BYOC or SPCS). For more information, see [About Openflow](/user-guide/data-integration/openflow/about). - Create an Openflow deployment. For more information, see [Set up Openflow - Snowflake Deployment: Create deployment](/user-guide/data-integration/openflow/setup-openflow-spcs-deployment) or [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc). - Create an Openflow runtime. For more information, see [Set up Openflow - Snowflake Deployment: Create runtime](/user-guide/data-integration/openflow/setup-openflow-spcs-create-runtime) or [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc). - Review the known limitations of the connector in [About the Openflow Connector for Salesforce Bulk API](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/about). ## Create a key pair Create a key pair that will be used by the service account user in the connector to interact with the database. This step is only required if you are deploying the connector in Openflow BYOC. It is NOT needed when deploying the connector in Openflow SPCS. 1. Generate a private key. The example below shows how to generate an unencrypted private key. ```bash openssl genrsa 2048 | openssl pkcs8 -topk8 -inform PEM -out rsa_key.p8 -nocrypt ``` The content of the `rsa_key.p8` file will look like this: ```text -----BEGIN PRIVATE KEY----- MIIE6T... -----END PRIVATE KEY----- ``` 2. Generate the public key by referencing the private key. ```bash openssl rsa -in rsa_key.p8 -pubout -out rsa_key.pub ``` The content of the `rsa_key.pub` file will look like this: ```text -----BEGIN PUBLIC KEY----- MIIBIjANBgkqh... -----END PUBLIC KEY----- ``` Copy the contents of this file (without the `-----BEGIN PUBLIC KEY-----` and `-----END PUBLIC KEY-----` headers) to use when creating the user in the next section. ## Create objects and grant privileges Create a service account, role, database, schema, and warehouse for the connector, and grant the appropriate permissions. 1. Use a role with `ACCOUNTADMIN` privileges to set the role: ```sql USE ROLE ACCOUNTADMIN; ``` 2. Create the destination Snowflake database, if it does not exist: ```sql CREATE DATABASE IF NOT EXISTS ; ``` 3. Create the destination schema in the database, if it does not exist: ```sql CREATE SCHEMA IF NOT EXISTS .; ``` 4. Create the role used by the Openflow connector: ```sql CREATE ROLE IF NOT EXISTS ; ``` 5. Grant the privileges to the role to use the database: ```sql GRANT USAGE ON DATABASE TO ROLE ; GRANT USAGE ON SCHEMA . TO ROLE ; GRANT CREATE TABLE, CREATE PIPE ON SCHEMA . TO ROLE ; ``` 6. Create a warehouse for the connector (or use an existing one) and grant usage privileges to the connector role: ```sql -- Create a warehouse (skip if you wish to use an existing warehouse) CREATE OR REPLACE WAREHOUSE MY_WAREHOUSE WITH WAREHOUSE_SIZE = 'SMALL' AUTO_SUSPEND = 300 AUTO_RESUME = TRUE; GRANT USAGE, OPERATE ON WAREHOUSE MY_WAREHOUSE TO ROLE ; ``` 7. Create the service user and assign the role and public key: ```sql -- Create a service user that the connector will use to interact with Snowflake -- Set default role to -- Assign the public key generated with openssl in the previous step (only for BYOC) CREATE OR REPLACE USER TYPE = SERVICE DEFAULT_ROLE = RSA_PUBLIC_KEY = ''; -- Grant the role to the user GRANT ROLE TO USER ; ``` ## Create a network rule (Openflow Snowflake Deployment only) If you are deploying the connector in a runtime that is in an Openflow Snowflake Deployment, you must create a network rule and external access integration and set them on the runtime. ```sql USE ROLE SECURITYADMIN; CREATE NETWORK RULE MY_OPENFLOW_SALESFORCE_NETWORK_RULE TYPE = HOST_PORT MODE = EGRESS VALUE_LIST = (':443'); CREATE EXTERNAL ACCESS INTEGRATION MY_OPENFLOW_SALESFORCE_EAI ALLOWED_NETWORK_RULES = (MY_OPENFLOW_SALESFORCE_NETWORK_RULE) ENABLED = TRUE COMMENT = 'External Access Integration to connect to Salesforce'; GRANT USAGE ON INTEGRATION MY_OPENFLOW_SALESFORCE_EAI TO ROLE OPENFLOW__EXECUTE_AS_RL; ``` ## Next steps Configure the connector in Openflow: [Openflow Connector for Salesforce Bulk API: Configure the connector](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/configure-connector) To use Iceberg tables as the destination, see [Openflow Connector for Salesforce Bulk API: Iceberg table destinations](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/iceberg). --- title: Openflow Connector for SQL Server (CDC): Maintenance source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/sql-server-cdc/maintenance.md section: Loading & Unloading Data --- # %sqlservercdc%: Maintenance This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Set up the Openflow Connector for SQL Server (CDC)](/user-guide/data-integration/openflow/connectors/sql-server-cdc/setup) - [Openflow connectors for SQL Server: Data mapping](/user-guide/data-integration/openflow/connectors/sql-server/data-mapping) This topic describes maintenance considerations and best practices for the %sqlservercdc%, such as reinstalling the connector. These operations are often used in conjunction with [Incremental replication without snapshots](/user-guide/data-integration/openflow/connectors/sql-server-cdc/incremental-replication). ## Check the replication status of a table Interim failures, such as connection errors or temporary source unavailability during a high-availability failover, do not prevent table replication. Replicated tables keep their current status and the connector retries on the next polling cycle. However, permanent failures, such as unsupported data types, prevent table replication. To troubleshoot replication issues or verify that a table has been successfully removed from the replication flow, check the Table State Store: 1. In the Openflow runtime canvas, right-click a processor group and choose **Controller Services**. A table listing controller services displays. 2. Locate the row labeled **Table State Store**, click the **More** %sf-vertical-more-button% button on the right side of the row, and then choose **View State**. A list of tables and their current states displays. Type in the search box to filter the list by table name. The possible states are: - **NEW**: The table is scheduled for replication but replication hasn't started. - **SNAPSHOT_REPLICATION**: The connector is copying existing data. This status displays until all records are stored in the destination table. - **INCREMENTAL_REPLICATION**: The connector is actively replicating changes. This status displays after snapshot replication ends and continues to display indefinitely until a table is either removed from replication or replication fails. - **FAILED**: Replication has permanently stopped due to an error. The Openflow runtime canvas doesn't display table status changes — only the current table status. However, table status changes are recorded in logs when they occur. Look for the following log message: ```text Replication state for table .. changed from to ``` If a permanent failure prevents table replication, remove the table from replication. After you address the problem that caused the failure, you can add the table back to replication. For more information, see [Restart table replication](#label-of-sql-server-cdc-restart-table-replication). ## Restart table replication This procedure re-snapshots the table in place. It requires connector version `0.50.0` or later, and runtime-extensions `2026.9.3.12` or later. On earlier versions, re-snapshotting a table that already exists in Snowflake fails instead of reloading in place. Upgrade the connector before you use this procedure. A table in a FAILED state (for example, due to a missing primary key or an unsupported schema change) does not restart automatically. If a table enters a FAILED state or you need to restart replication from scratch, use the following procedure to remove and re-add the table to replication. If the failure was caused by an issue in the source table such as a missing primary key, resolve that issue in the source database before continuing. 1. Remove the table from replication, using one of the following methods: - Add the table to the **Re-snapshot Table Exclusions** parameter to temporarily exclude it from replication. This approach is convenient when the table is matched by an **Included Table Regex** that you don't want to change. - In the **Ingestion Parameters** context, either remove the table from **Included Table Names** or modify the **Included Table Regex** so the table is no longer matched. 2. Verify the table has been removed: 1. In the Openflow runtime canvas, right-click a processor group and choose **Controller Services**. 2. In the table listing controller services, locate the **Table State Store** row, click the three vertical dots on the right side of the row, then choose **View State**. You must wait until the table's state is fully removed from this list before proceeding. Don't continue until this configuration change has completed. 3. Wait until all queues in the connector are empty before you re-add the table. When all FlowFiles have been processed, the **Queued** value on the connector's processor group becomes zero. Don't re-add the table while change events that were captured before you removed it are still queued. When you re-add a table, the connector loads the new snapshot in append-only mode, so any leftover change event that merges into the table after the re-snapshot might create duplicate rows in the destination table. 4. Re-add the table by reversing the change you made in the first step: either remove the table from **Re-snapshot Table Exclusions**, or add it back to **Included Table Names** or **Included Table Regex**. You do not need to drop the destination table first. The connector re-snapshots the table in place: it makes a zero-copy [clone](/sql-reference/sql/create-clone) of the current destination table to an archive table named `_ARCHIVE_`, clears the destination table, and then loads the fresh snapshot into the same destination table. Because the destination table object is preserved, dependent objects such as streams remain attached and continue to work. The archive table retains a copy of the destination table's contents from immediately before the reload, as a safeguard. The connector does not read from or write to it again, so you can drop it at any time once the backup is no longer needed, typically after you confirm that the re-snapshot completed and the destination data is correct. 5. Verify the restart: Check the **Table State Store** using the instructions given previously. The state of the table should appear with the status NEW, then transition to SNAPSHOT_REPLICATION, and finally to INCREMENTAL_REPLICATION. ## Increase the oversized value limit By default, the connector replicates individual values up to 16 MB and marks any table that contains a larger value as permanently failed. If your Snowflake account has the `ENABLE_OPENFLOW_CDC_BASED_SQLSERVER_SSV2` parameter set to `true`, the per-value limit can be raised from 16 MB to **128 MB**. If replicated tables contain LOB values larger than 64 KB, SQL Server CDC requires the `max text repl size` setting to be raised on the source instance. This applies on every platform and even at the connector's default 16 MB per-value limit. For configuration steps by platform, see [Raise max text repl size for large LOB columns](/user-guide/data-integration/openflow/connectors/sql-server-cdc/setup#label-sql-server-cdc-max-text-repl-size). The 128 MB limit applies in two ways: it's both the maximum size of a single value and the maximum total size of a row. The connector adds metadata columns to every replicated row (`_SNOWFLAKE_UPDATED_AT`, `_SNOWFLAKE_INSERTED_AT`, `_SNOWFLAKE_DELETED`) that count toward the per-row limit, along with all other columns in the row. As a result, a single value can't reach the full 128 MB in practice when the row includes other data. The increased limit doesn't apply equally to all column types. In Snowflake, the maximum size for `BINARY` is **64 MB** (`BINARY(67108864)`), even when the increased size limits are enabled. Only `VARCHAR`, `VARIANT`, `ARRAY` and `OBJECT` columns can hold up to 128 MB. ### Check whether the 128 MB limit is available You may not be able to verify the `ENABLE_OPENFLOW_CDC_BASED_SQLSERVER_SSV2` parameter value by querying it. To check if it is enabled, see if the FlowFiles flow through **Upload Rows via Snowpipe Streaming 2** processor (not through **Upload Rows via Snowpipe Streaming**). ### Configure the processors Update the **Oversized Value Limit** property to `128 MB` on the following processors: - **Fetch Table Rows** (in the **Snapshot Load** group) — used for non-partitioned tables - **MultiDatabaseFetchTableSnapshot** (in the **Snapshot Load** group) — used for partitioned tables - **MultiDatabaseCaptureChangeCdcSqlServer** (in the **Incremental Load** group) For each processor: 1. Locate the processor in the flow. On the connector canvas, you can use the search box in the top-right corner to find processors by name. 2. Right-click the processor and select **Configure**. 3. Open the **Properties** tab. 4. Set **Oversized Value Limit** to `128 MB`. 5. Apply the change. For tables that are already being replicated and have destination columns narrower than `VARCHAR(134217728)` or `BINARY(67108864)`, see [](#label-of-sql-server-cdc-migrate-oversized-value-tables). ### Migrate existing tables The steps in [](#label-of-sql-server-cdc-increase-oversized-value-limit) raise the limit for newly created destination tables. If a table is already being replicated and its destination column type is **not** `VARCHAR(134217728)` or `BINARY(67108864)`, but you now want to load values larger than the original 16 MB limit, you must manually widen the column type on **both** the journal and destination tables. Before you migrate, check the current destination column type, because it can vary depending on when the snapshot replication was performed. You must stop replication for the affected table before altering its journal or destination tables. Altering these tables while replication is active can corrupt in-flight data. To migrate a table: 1. Stop replication for the affected table by stopping the topmost processors of the **Snapshot Load** and **Incremental Load** groups until all queues are empty. For the equivalent stop procedure, see the substeps in [](#label-sql-server-cdc-reinstall-connector). 2. Widen the column on both the journal table and the destination table, according to the column type: 1. For **VARCHAR** columns, run `ALTER TABLE ... ALTER COLUMN ... SET DATA TYPE VARCHAR(134217728)` on the journal table and on the destination table (one statement per table). 2. For **BINARY** columns, Snowflake doesn't allow widening `BINARY` in place, so do the following on both the journal and destination tables: 1. Add a new column of type `BINARY(67108864)`. 2. Copy data from the original column into the new column. 3. Drop the original column and rename the new column to the original name. 3. Restart replication by re-enabling the processors. ### Performance considerations Raising the per-value limit increases the amount of data that the connector loads into memory and moves through the flow, which raises the load on both the runtime and the warehouse. Size the runtime and warehouse accordingly. When **Oversized Value Strategy** is set to **Set Null**, the connector still loads each oversized value into memory before it can replace it with `NULL`. If your tables contain multi-gigabyte LOB columns, exclude those columns from replication. During both snapshot and incremental replication, the queue in front of the **Upload Rows via Snowpipe Streaming 2** processor can fill with FlowFiles and trigger back pressure, which consumes a large amount of runtime disk space. For larger tables, use a Large runtime to provide additional storage. For guidance on choosing a size, see [Runtime sizing](/user-guide/data-integration/openflow/connectors/sql-server-cdc/setup#label-sql-server-cdc-runtime-sizing). #### Snapshot replication To speed up snapshot replication, you can increase the number of channels that the **Upload Rows via Snowpipe Streaming 2** processor uses. The number of channels is set by the processor's **Channel Group** property, which defaults to `${chunk.index:isEmpty():ifElse('1', ${chunk.index:mod(8)})}`. To increase the number of channels: 1. Locate the **Upload Rows via Snowpipe Streaming 2** processor in the flow. 2. Stop the processor. You must stop the processor before you can change its properties. 3. Right-click the processor and select **Configure**. 4. Open the **Properties** tab. 5. In the **Channel Group** property, increase the value `8` in the expression. For example, change `8` to `16` to double the number of channels. 6. Apply the change. 7. Start the processor. While a snapshot replication is in progress, only increase the number of channels. Decreasing the number of channels during an active snapshot can cause data loss. #### Incremental replication During incremental replication, the connector reads from SQL Server CDC change tables, not directly from the source table. The CDC capture job (`cdc._capture`) moves changes from the transaction log into those tables in batches. For rows with large LOB values (for example, 64 MB `VARCHAR(MAX)` columns), this capture job can become slow, especially when changes are frequent. The connector can only consume data after the capture job has written it to the change tables. As a result, NiFi queues may fill in waves rather than steadily: FlowFiles arrive in batches when CDC data becomes available, then queues may drain while the capture job processes the next batch. Temporary gaps in queue activity don't necessarily indicate connector failure; they often reflect source-side CDC capture lag. When the source produces frequent changes to rows that contain large values, you might need a Large warehouse. High-frequency merges of many moderately large rows (for example, many 8 MB values) can require a large single merge operation, and smaller warehouses can run out of memory. By contrast, fewer very large rows (for example, 128 MB values) are streamed file by file through the **Upload Rows via Snowpipe Streaming 2** processor, and each file is merged incrementally, which typically completes without warehouse errors even on smaller warehouses. ## Reinstall the connector This section provides instructions on how to reinstall the connector, and continue replicating data for the same tables without having to snapshot them again. It covers situations where the new connector is installed in the same runtime, as well as moved to a new runtime. ### Prerequisites Review and note connector parameter context values. If you reinstall the connector in the same runtime, you can reuse the existing context. If the new instance is located in a different runtime, you must re-enter all parameters. 1. Finish processing all in-flight FlowFiles in the existing connector, then stop the connector. 1. Sign in to %sf-web-interface-link%. 2. In the navigation menu, select **Ingestion** %raa% **Openflow**. 3. Select **Launch Openflow**. 4. In the **Openflow** pane select the **Runtimes** tab. 5. Select the runtime containing the connector. 6. Select the connector. 7. Stop the topmost processor **Set Tables for Replication** in the **Snapshot Load** group. 8. Stop the **MultiDatabaseCaptureChangeCdcSqlServer** processor in the **Incremental Load** group. 9. If you changed the value of the **Merge Task Schedule CRON** parameter, return it to `* * * * * ?`, otherwise queues won't be emptied until the next scheduled run. Wait until all FlowFiles in the connector have been processed, and all queues are empty. When all FlowFiles have been processed, the **Queued** value on the connector's processor group becomes zero. If there are any items left in the original connector's queues, there may be data gaps when the new connector starts. 10. Stop all processors and controller services in the connector. The existing connector can remain in the runtime and doesn't interfere with the new instance, as long as it remains stopped. 2. If you're moving the connector to a new runtime, download the flow definition from the existing connector so that you can recreate the connector with its current state instead of configuring it from scratch. Downloading a flow definition requires Openflow Runtime Server version 2026.6.4.18 or later. 1. Right-click the connector's process group, then select **Download flow definition**. 2. Select both of the following options, then download the flow definition: - **Export with External Services**: includes the controller services that the connector references from parent process groups. - **Export with Components State**: includes component state, such as CDC positions and incremental replication state, so that replication continues from where it left off. 3. Create the connector in the target runtime: - If you downloaded the flow definition, import it into the new runtime. Importing the flow definition preserves the component state captured during the export, so the connector resumes incremental replication from its previous positions. - Otherwise, create a new instance of the connector. If you use the same runtime as the original connector, you can choose to keep the existing parameter contexts and reuse the settings. 4. If you install into a different runtime or you deleted the previous parameter contexts, enter the configuration settings into the new parameter contexts, including the table names and patterns as described in [Set up the Openflow Connector for SQL Server (CDC)](/user-guide/data-integration/openflow/connectors/sql-server-cdc/setup). A downloaded flow definition doesn't include sensitive values, such as passwords, so you must re-enter them. 5. Navigate to the `SQLServer Ingestion Parameters` context, and set the following parameters: - Set the `Ingestion Type` parameter to `incremental`. For information, see [](#label-sql-server-cdc-incremental-replication). - Set the `Starting CDC Position` parameter to `Earliest`. For information, see [](#label-sql-server-cdc-connector-start-restart-incremental-load-from-earliest-available-position). If you imported the flow definition with **Export with Components State** selected, the connector retains its previous CDC positions. In this case, leave `Starting CDC Position` set to `Latest` to continue replication from where it stopped. 6. Start the new connector. ### Usage notes The new connector uses the existing destination tables created by the original connector, but creates new journal tables. ## Specify load from CDC position The %sqlservercdc% connector lets you select the starting position where CDC change tables are read. By default, the connector reads from the latest available position. Alternatively, you can choose the earliest position available on the source instance. Choosing to start from the earliest position is common when reinstalling the connector. This allows the new instance to catch up and continue replicating existing tables without having to snapshot each again. Switching a running connector from latest to earliest position causes the contents of CDC change tables to be re-read, re-processed, and re-applied to the destination table. While the CDC change tables are being re-read, the data in affected destination tables can become out of sync with their sources until all events have been re-processed and merged. The following parameters are available in the `Ingestion Parameters` context:
To determine whether the connector finished re-reading the CDC change tables: 1. Navigate to the Openflow canvas. 2. Open the **Incremental Load** process group. 3. Right-click the **MultiDatabaseCaptureChangeCdcSqlServer** processor, then select **View state**. 4. Check the state entries for every table with keys starting with `position.`. If a value is `0/0/0`, then the connector has not yet finished re-reading the changes for this table. ### Usage notes - After you switch a running connector to read from the earliest positions and start it, you can't reconfigure or cancel the process, and it will continue until the currently-read positions reach the latest values. - Switching to the earliest position on a running connector will, for any tables being re-processed, finish their existing journals, and create new journal tables. --- title: Openflow Connector for SQL Server (CDC): Set up incremental replication without snapshots source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/sql-server-cdc/incremental-replication.md section: Loading & Unloading Data --- # %sqlservercdc%: Set up incremental replication without snapshots This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Set up the Openflow Connector for SQL Server (CDC)](/user-guide/data-integration/openflow/connectors/sql-server-cdc/setup) - [Openflow connectors for SQL Server: Data mapping](/user-guide/data-integration/openflow/connectors/sql-server/data-mapping) You can configure the %sqlservercdc% connector to immediately replicate incremental changes for newly added tables, bypassing snapshots. Use incremental load to continue replication without snapshotting every table again when you reinstall the connector over previously replicated data. To enable incremental replication in a new connector instance: 1. Set up the connector as described in [Set up the Openflow Connector for SQL Server (CDC)](/user-guide/data-integration/openflow/connectors/sql-server-cdc/setup). 2. In the `SQLServer Ingestion Parameters` context, set the `Ingestion Type` parameter to `incremental`. ## Enable incremental replication without snapshots To enable incremental replication on an existing connector: 1. sign in to %sf-web-interface-link%. 2. in the navigation menu, select **Ingestion** %raa% **Openflow**. 3. In the **Openflow** pane select the **Runtimes** tab. 4. Select the runtime containing the connector. 5. Select the connector. 6. In the `Ingestion Parameters` context, specify `Ingestion Type` = `incremental`. 7. Add new replication tables. These tables immediately switch to their incremental load. To return to replicating tables with the snapshot load, change **Ingestion Type** from `incremental` to `full`. # Usage notes - Changing the value of **Ingestion Type** does not impact any tables that have begun replicating data. Tables currently in the snapshot phase continue until the snapshot load is complete. - While **Ingestion Type** is set to `incremental`, new tables added to the list of replicated tables bypass the snapshot phase. This includes new tables added to the source database that match the `Included Table Regex` parameter. Ensure that the ingestion type is set to `incremental` to bypass the snapshot phase. Connectors should only remain in `incremental` mode as long as required as it bypasses snapshots. Once customer needs for incremental updates have been satisfied the connector should be returned to `full` mode. - For tables that bypass snapshot load, the connector creates a destination table in Snowflake, by executing `CREATE TABLE IF NOT EXISTS`, only if no destination table already exists. Tables going through the snapshot require that no destination table exist. ## Recover a table using incremental-only mode If a table's snapshot completed successfully but incremental replication later failed, you don't need to remove the table and snapshot it again. Instead, you can recover the table by replaying the changes that are still available in the source CDC change tables and merging them onto the existing destination table. Incremental replication can fail for several reasons, for example: - A record in the source database can't be read because it has an incorrect or unsupported format. - A row exceeds the maximum supported size. - A merge operation can't complete. - A transient error persists through so many retries that the table enters the FAILED state. To recover the table without a new snapshot, remove it from replication, switch the connector to incremental-only mode reading from the earliest available position, and add the table back. The connector reads all available changes from the oldest available CDC position, then replays and reapplies them to the destination table. Before you recover the table, address the underlying cause of the failure. Otherwise, the connector encounters the same error again when it replays the changes. For example, raise the per-value limit (see [Increase the oversized value limit](/user-guide/data-integration/openflow/connectors/sql-server-cdc/maintenance#label-of-sql-server-cdc-increase-oversized-value-limit)) or fix the problematic record in the source database. To recover the table: 1. Remove the table from replication. In the `Ingestion Parameters` context, remove the table from **Included Table Names**, or modify **Included Table Regex** so the table is no longer matched. Wait until the table's state is fully removed from the **Table State Store** controller service before you continue. Don't drop the destination table. This procedure reuses the existing destination table and replays incremental changes onto it. 2. Stop the connector's process group so that you can change its configuration. On the connector canvas, right-click the connector's process group and select **Stop**. 3. In the `Ingestion Parameters` context, set the `Ingestion Type` parameter to `incremental`. 4. Set the `Starting CDC Position` parameter to `Earliest`. The connector reads all available changes again from the oldest available CDC position, then replays and reapplies them to the destination table. For more information, see [Specify load from CDC position](/user-guide/data-integration/openflow/connectors/sql-server-cdc/maintenance#label-sql-server-cdc-connector-start-restart-incremental-load-from-earliest-available-position). Leave `Re-read Tables in State` at its default value, `New`, so that only the table you add back reads from the earliest position. Tables already in replication continue from their last positions. 5. Add the table back to replication by reversing the change you made in step 1. 6. Start the connector's process group. Right-click the connector's process group and select **Start**. 7. Wait until the table returns to incremental replication. In the **Table State Store** controller service state, the table transitions to INCREMENTAL_REPLICATION when recovery completes. 8. Revert the changes you made in steps 3 and 4: set `Ingestion Type` and `Starting CDC Position` back to their previous values. This procedure recovers only the changes still retained in the source CDC change tables. If the CDC retention period expired and some changes were purged, the recovered table can have gaps. In that case, you must take a new snapshot to fully resynchronize the table. --- title: Openflow Connector for SQL Server: Iceberg table destinations source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/sql-server/iceberg.md section: Loading & Unloading Data --- # Openflow Connector for SQL Server: Iceberg table destinations Available to all accounts. - [About Openflow Connector for SQL Server](/user-guide/data-integration/openflow/connectors/sql-server/about) - [Set up the Openflow Connector for SQL Server](/user-guide/data-integration/openflow/connectors/sql-server/setup) - [Openflow connectors for SQL Server: Data mapping](/user-guide/data-integration/openflow/connectors/sql-server/data-mapping) - [About Openflow Connector for SQL Server (CDC)](/user-guide/data-integration/openflow/connectors/sql-server-cdc/about) - [Data types for Apache Iceberg™ tables](/user-guide/tables-iceberg-data-types) - [Snowflake storage for Apache Iceberg™ tables](/user-guide/tables-iceberg-internal-storage) - [CREATE EXTERNAL VOLUME](/sql-reference/sql/create-external-volume) The Openflow multi-database connectors for SQL Server support writing to Snowflake-managed Apache %iceberg-tm% tables as an opt-in destination format. Iceberg v2 and v3 are both supported. Setting **Table Storage Format** = `ICEBERG` and choosing an **Iceberg Version** are the only connector-level changes required. The external volume, catalog, and serialization policy are inherited from the Snowflake destination database defaults. The Iceberg specification version is set via the **Iceberg Version** connector parameter, which defaults to `3`. Storage can be either [Snowflake storage for Apache %iceberg-tm% tables](/user-guide/tables-iceberg-internal-storage) (`EXTERNAL_VOLUME = 'SNOWFLAKE_MANAGED'`) or an external volume in your cloud storage. When you use Snowflake storage, no external cloud storage or IAM grants are required. Existing connectors using standard tables aren't affected. ## Prerequisites - **Openflow runtime**: An existing runtime to host the connector. - **SQL Server source configured for CDC or Change Tracking**: - For CDC: Enable CDC on the database and each replicated table. - For Change Tracking: Enable change tracking on the database and each replicated table with a primary key. - For details, see [Set up the Openflow Connector for SQL Server](/user-guide/data-integration/openflow/connectors/sql-server/setup) or [Set up the SQL Server CDC connector](/user-guide/data-integration/openflow/connectors/sql-server-cdc/setup). - **External volume in your cloud storage**: An external volume configured for Iceberg storage, with USAGE granted to the connector's Snowflake role. See [CREATE EXTERNAL VOLUME](/sql-reference/sql/create-external-volume). Not required when using Snowflake storage (`EXTERNAL_VOLUME = 'SNOWFLAKE_MANAGED'`). - **Snowflake destination database**: An existing database configured with Iceberg parameters (next section). ## Step 1: Configure the Snowflake destination database Set the Iceberg defaults on the destination database. The connector reads these defaults at runtime for external volume and serialization policy. The Iceberg specification version is configured per-connector via the **Iceberg Version** parameter (see Step 3), not solely via the database-level `ICEBERG_VERSION_DEFAULT`. ### Option A: Snowflake storage When you use Snowflake storage, Snowflake stores and manages the Iceberg table files for you. No external cloud storage or IAM grants are required. ```sql CREATE DATABASE EXTERNAL_VOLUME = 'SNOWFLAKE_MANAGED' STORAGE_SERIALIZATION_POLICY = ; ``` To configure an existing database: ```sql ALTER DATABASE SET EXTERNAL_VOLUME = 'SNOWFLAKE_MANAGED' STORAGE_SERIALIZATION_POLICY = ; ``` ### Option B: External volume in your cloud storage If you need to keep table files in your own cloud storage, configure the database with your external volume: ```sql CREATE DATABASE EXTERNAL_VOLUME = '' STORAGE_SERIALIZATION_POLICY = ; ``` To configure an existing database: ```sql ALTER DATABASE SET EXTERNAL_VOLUME = '' STORAGE_SERIALIZATION_POLICY = ; ```
`CATALOG = 'SNOWFLAKE'` is set automatically by the connector on each CREATE ICEBERG TABLE statement. Don't set it at the database level. The base location for each table is auto-derived using the [flat layout](/user-guide/tables-iceberg-managing-external-volumes#label-tables-iceberg-snowflake-managed-flat-layout): `STORAGE_BASE_URL/database/schema/table_name.randomId/[data | metadata]/`. No user configuration is needed. If using an external volume in your cloud storage (Option B), grant the connector's Snowflake role USAGE on the external volume: ```sql GRANT USAGE ON EXTERNAL VOLUME TO ROLE ; ``` This step is not required for Snowflake storage. ## Step 2: Set Table Storage Format in the connector's parameter context Set the **Table Storage Format** parameter to `ICEBERG` in the connector's destination parameter context. The default is `STANDARD`. For the full connector creation and configuration workflow, see [Set up the Openflow Connector for SQL Server](/user-guide/data-integration/openflow/connectors/sql-server/setup) or [Set up the SQL Server CDC connector](/user-guide/data-integration/openflow/connectors/sql-server-cdc/setup). ## Step 3: Set the Iceberg version Set the **Iceberg Version** connector parameter to `2` or `3`. This controls the Iceberg specification version used for type mapping (for example, JSON maps to `variant` on v3 vs `string` on v2) and the `ICEBERG_VERSION=` clause in CREATE ICEBERG TABLE DDL. The **Iceberg Version** parameter defaults to `3`. Review and change to `2` if needed before starting the connector. Do not change this value after ingestion begins. ## Step 4: Start and verify Start the connector as usual. After the initial snapshot completes, verify the destination tables are Iceberg: ```sql -- Confirm the table is Iceberg SELECT GET_DDL('TABLE', '..
PostgreSQL type Snowflake (Standard) Iceberg v3 Iceberg v2
SMALLINT / INTEGER INT `long` `long`
BIGINT INT `long` `long`
REAL FLOAT `double` `double`
DOUBLE PRECISION FLOAT `double` `double`
NUMERIC(P,S) NUMBER(P,S) `decimal(P,S)` `decimal(P,S)`
BOOLEAN BOOLEAN `boolean` `boolean`
DATE DATE `date` `date`
TIME TIME `time` `time`
TIMESTAMP TIMESTAMP_NTZ `timestamp` `timestamp`
TIMESTAMPTZ TIMESTAMP_LTZ `timestamptz` `timestamptz`
TIMETZ TIMESTAMP_TZ `timestamptz` `timestamptz`
TEXT / VARCHAR / CHAR TEXT `string` `string`
BYTEA BINARY `binary` `binary`
JSON / JSONB VARIANT `variant` `string`
UUID TEXT `string` `string`
Parameter Description
Column Removal Strategy Defines the strategy to adopt when a column should be removed in the destination table based on the latest received schema. Three possible values: `Drop Column`, `Rename Column`, `Ignore Column`. - `Drop Column`: Drop the column from the Snowflake table. - `Rename Column`: Rename the column in the Snowflake table. - `Ignore Column`: Ignore the column, leaving it as is in the Snowflake table.
Connected App Key The private key used for JWT Bearer Flow authentication with Salesforce. Copy-paste the content of the `private.key` file generated during the [Salesforce setup](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/setup-salesforce). This private key must correspond to the public certificate (`public.crt`) uploaded to the external client app in Salesforce. You can also use the next parameter to upload the private key file instead.
Connected App Key File Upload the `private.key` file by selecting the **Reference asset** checkbox, then upload the file as an asset and select the asset as the value for the parameter. This is an alternative to pasting the key content in the **Connected App Key** parameter.
Connected App Key Password Password set on the private key file during the [Salesforce setup](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/setup-salesforce) steps.
Destination Database Name of the database in Snowflake where the Salesforce data will be replicated. The database must exist before starting the connector.
Destination Schema Name of the schema, in the database above, into which the connector will create tables for the Salesforce data to be added. The schema must exist before starting the connector.
Enable Capture Blob Fields If set to `true`, fields of type `base64` (binary fields such as `Attachment.Body` and `ContentVersion.VersionData`) are fetched by the connector. The objects that contain blob fields must be listed in the **Special Objects Filter** parameter (Non-Bulk API path). Default: `false`. See [Configure blob field ingestion](#blob-fields) for details.
Enable Journal Tables If set to `true`, a `JOURNAL_` table is created for each synced object that has a `SystemModstamp` or `LastModifiedDate` field. All changes are appended to the journal table, providing a full history of modifications. This is in addition to the main table that contains the merged data for the object. If a full reload occurs for a given object type, its journal table is also recreated. Default: `false`.
Enable Merge Metrics If set to `true`, the connector runs an additional query to count records that are added, updated, deleted, or restored during replication. The additional query uses the **Snowflake Warehouse** and applies only to objects that include the `IsDeleted` field. The connector writes the counts to logs in the event table. Default: `false`. See [Monitor the Openflow Connector for Salesforce Bulk API](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/monitor).
Enable Views Creation If set to `true`, a view named `_FORMULA_VW` is created for each synced object that contains formula fields. The view translates supported Salesforce formula expressions into Snowflake SQL, allowing you to query formula results directly without replicating formula field values from Salesforce. See [](#salesforce-formula-fields) for details. Default: `false`.
Filter Comma-separated list of objects to replicate from Salesforce, or regular expression to apply against all existing objects. The filter is case-insensitive, meaning that a filter set to `account` would match the object type `Account`. Example: `Account, Opportunity, Contact`. If left empty, all objects will be replicated. This is not recommended as there are usually thousands of objects in a Salesforce instance.
Incremental Offload Whether the processor should perform incremental offload. If `true`, the processor will only fetch the records that have been modified since the last query job submission by using a `WHERE` clause on the appropriate timestamp field. If `false`, all records will be fetched at every execution of the connector.
Initial Load Chunking If set to a value other than `NONE`, the initial data load will be split into multiple jobs based on this interval. On the first run for an object, the connector will query Salesforce to find the oldest record and use that as the starting point. Each subsequent job will query the next time chunk until caught up to the current time. Set to one of: `NONE`, `MONTHLY`, `QUARTERLY`, `YEARLY`. This is useful for large datasets where loading all historical data in a single query may time out, exceed API limits, or exceed the storage size of the content repository of the runtime. After catching up, the processor continues with normal incremental offload behavior.
Iceberg Version Only applicable when **Table Storage Format** is set to `ICEBERG` (preview). Specifies the Iceberg version for the destination Iceberg table. Supported values are `2` and `3`. Default: `3`. Don't change this value after ingestion begins. For setup instructions, see [Openflow Connector for Salesforce Bulk API: Iceberg table destinations](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/iceberg).
OAuth2 Audience Audience to set in the JWT token. Set to `https://login.salesforce.com` for production environments or `https://test.salesforce.com` for sandboxes and test environments.
OAuth2 Client ID Should be set to the **Consumer Key** value retrieved during the Salesforce Setup steps.
OAuth2 Subject Should be set to the username of an admin-approved user on whose behalf the application interacts with Salesforce APIs.
OAuth2 Token Endpoint URL Endpoint to negotiate tokens via the JWT Bearer Flow. Example: `https://myCompany.my.salesforce.com/services/oauth2/token`.
Object Fields Filter JSON A JSON specifying which fields and field patterns should be included or excluded, per Salesforce object. Takes the form of an array with one item per object. Example 1: This will include all fields that end with 'name' in the 'Account' Salesforce object: `[ {"objectType":"Account", "includedPattern":".*name"} ]` Example 2: This will include the fields Id, Name, and Revenue in the 'Account' Salesforce object: `[ {"objectType":"Account", "included": ["Id", "Name", "Revenue"]} ]` `excluded` and `excludedPattern` are also available for configuring the filters.
Object Identifier Resolution Determines whether schema/table/column names are treated as case-sensitive or case-insensitive. One of: `CASE_INSENSITIVE` / `CASE_SENSITIVE`. Changing this parameter value will require clearing the state and doing a full reload of all objects.
Removed Column Name Suffix Suffix added to the column name when the parameter **Column Removal Strategy** is set to `Rename Column`. Default: `__deleted`.
Run Schedule Frequency at which the connector will check for updates in Salesforce for configured objects via the **Filter** parameter. Default: `15 minutes`.
Salesforce Instance Hostname of the Salesforce instance including the domain name. Do not include the protocol prefix (`https://`). For example, use `myCompany.my.salesforce.com`.
Snowflake Account Identifier Snowflake account name formatted as `[organization-name]-[account-name]` where data will be persisted. Example: `PM-CONNECTORS`.
Snowflake Username The name of the service user that the connector uses to connect to Snowflake. The service user is required only when using the `KEY_PAIR` authentication strategy (Openflow BYOC only).
Snowflake Private Key The RSA Private Key that the connector uses for authentication to Snowflake, formatted according to PKCS8 standards and including standard PEM headers and footers. The header line starts with `-----BEGIN PRIVATE`. This is required only when using the `KEY_PAIR` authentication strategy (Openflow BYOC only). You may also use the next parameter to upload the private key to the Openflow runtime instead.
Snowflake Private Key File The file containing the RSA Private Key that the connector uses for authentication to Snowflake, formatted according to PKCS8 standards and including standard PEM headers and footers. The header line starts with `-----BEGIN PRIVATE`. Required only when using the `KEY_PAIR` authentication strategy (Openflow BYOC only). Select the **Reference asset** checkbox to upload the private key file and store it securely in the Openflow runtime.
Snowflake Private Key Password The password associated with the Snowflake Private Key File (if encrypted). This is required only when using the `KEY_PAIR` authentication strategy (Openflow BYOC only).
Snowflake Role Name of the execute-as role used during query execution. When using `SNOWFLAKE_MANAGED`, this is the execute-as role for Openflow runtimes. When using `KEY_PAIR` (Openflow BYOC only), this is the role assigned to the specified Snowflake username.
Snowflake Authentication Strategy Authentication strategy for the connector to connect to Snowflake. Using `SNOWFLAKE_MANAGED` (default) uses the Snowflake managed token associated with the runtime's execute-as role. If using Openflow BYOC, you can also use `KEY_PAIR` to specify a specific user and role via a custom Key Pair.
Snowflake Warehouse The Snowflake warehouse used to run queries.
Special Objects Filter Comma-separated list of objects to offload from Salesforce (using direct API access), or regular expression to apply against all existing objects. The filter is case-insensitive, meaning that a filter set to `account` would match the object type `Account`. This filter should only be used for objects that are **not** supported by the Salesforce Bulk API, such as knowledge data. This parameter should not overlap with the parameter **Filter**. Example: `Knowledge.*`
Table Storage Format The storage format of the destination Snowflake table. Use `STANDARD` for standard Snowflake tables. The `ICEBERG` option, which writes to Apache Iceberg tables, is a preview feature. Default: `STANDARD`. Don't change this value after ingestion begins. For setup instructions, see [Openflow Connector for Salesforce Bulk API: Iceberg table destinations](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/iceberg).
Category Salesforce function Snowflake equivalent
Logical `IF` `CASE WHEN ... THEN ... ELSE ... END`
Logical `CASE` `CASE ... WHEN ... THEN ... ELSE ... END`
Logical `AND` / `OR` / `NOT` `AND` / `OR` / `NOT`
Null handling `ISBLANK` `(expr IS NULL OR TO_VARCHAR(expr) = '')`; returns `FALSE` for boolean fields
Null handling `ISNULL` `expr IS NULL`
Null handling `NULLVALUE` `COALESCE`
Null handling `BLANKVALUE` `CASE WHEN expr IS NULL OR TO_VARCHAR(expr) = '' THEN default ELSE expr END`
Text `LEFT` `LEFT`
Text `RIGHT` `RIGHT`
Text `MID` `SUBSTR`
Text `LEN` `LENGTH`
Text `SUBSTITUTE` `REPLACE`
Text `TRIM` `TRIM`
Text `UPPER` `UPPER`
Text `LOWER` `LOWER`
Text `CONTAINS` `CONTAINS`
Text `BEGINS` `STARTSWITH`
Text `FIND` `CHARINDEX`
Text `LPAD` `LPAD`
Text `RPAD` `RPAD`
Text `BR` Newline character literal
Conversion `TEXT` `CAST(... AS STRING)`
Conversion `VALUE` `TRY_CAST(... AS NUMBER)`
Math `ABS` `ABS`
Math `ROUND` `ROUND`
Math `CEILING` `CEIL`
Math `FLOOR` `FLOOR`
Math `MOD` `MOD`
Math `SQRT` `SQRT`
Math `MAX` `GREATEST`
Math `MIN` `LEAST`
Math `LOG` `LOG(10, ...)`
Math `EXP` `EXP`
Math `LN` `LN`
Date and time `NOW` `CURRENT_TIMESTAMP()`
Date and time `TODAY` `CURRENT_DATE()`
Date and time `YEAR` `YEAR`
Date and time `MONTH` `MONTH`
Date and time `DAY` `DAY`
Date and time `DATEVALUE` `TO_DATE`
Date and time `DATETIMEVALUE` `TO_TIMESTAMP`
Date and time `ADDMONTHS` `DATEADD(MONTH, ...)`
Picklist `ISPICKVAL` `COALESCE(field, '') = COALESCE(value, '')`
Failure reason Description
`FUNCTION_NOT_SUPPORTED` The formula uses a function that has no Snowflake equivalent or that is specific to the Salesforce UI. This includes: `IMAGE`, `HYPERLINK`, `URLFOR`, `HTMLENCODE`, `JSENCODE`, `LINKTO`, `GEOLOCATION`, `DISTANCE`, `VLOOKUP`, `REGEX`, `PREDICT`, `GETSESSIONID`, `GETRECORDIDS`, `REQUIRESCRIPT`, `ISCHANGED`, `ISNEW`, `ISCLONE`, `PRIORVALUE`.
`GLOBAL_VARIABLE_NOT_SUPPORTED` The formula references a Salesforce global variable such as `$User.Name`, `$Organization.Name`, or `$Profile.Name`. These variables have no equivalent in Snowflake.
`FORMULA_CHAIN_NOT_SUPPORTED` A formula field in the chain could not be translated. When a formula field references another formula field (a chained formula), the connector expands the dependency before translation. If the dependency itself fails to translate, the referencing formula also fails with this reason code. This can also occur for cyclic formula references, which are not allowed by Salesforce.
`ROLLUP_NOT_SUPPORTED` The field is a rollup summary field rather than a formula field. Rollup summaries aggregate data from child records and cannot be expressed as a simple SQL view.
`LOOKUP_NOT_SYNCED` The formula references a relationship that cannot be resolved from the Salesforce object metadata. This typically occurs when the relationship name in the formula does not match any known relationship on the object.
`ID_FORMAT_MISMATCH` The formula contains a hardcoded 15-character Salesforce ID. Salesforce uses 15-character IDs internally, but the Bulk API returns 18-character IDs. Formulas with hardcoded 15-character IDs cannot be reliably translated.
`COMPOUND_FIELD_REFERENCE` The formula references a compound field (such as `MailingAddress`) that is not stored as a single column in Snowflake.
`PARSE_ERROR` The formula expression could not be parsed. This might indicate a syntax that the connector does not yet recognize.
`UNSUPPORTED_SYNTAX` The formula uses a syntax construct that is recognized but cannot be translated (for example, an `IF` function with fewer than three arguments).
Parameter Description
Starting CDC Position - `Latest` (default): CDC change table reading starts at the latest available position and continues from there. - `Earliest`: Switches the incremental load to start, or restart reading from the earliest available CDC change table positions.
Re-read Tables in State - `New` (default): Only new tables, added after the starting position was switched to `Earliest`, will have their CDC change tables read from the earliest available positions. Tables that started replication before the configuration change will continue reading from their last positions. - `Any active`: Re-read and re-process changes from any table currently in replication.
Parameter Required Notes
EXTERNAL_VOLUME Yes The external volume for Iceberg file storage.
ICEBERG_VERSION_DEFAULT No `2` or `3`. Legacy fallback for older connector flows where the **Iceberg Version** parameter is unset. New connectors set the version via the connector parameter (Step 3) and do not require this database setting.
STORAGE_SERIALIZATION_POLICY Yes `COMPATIBLE` produces Parquet files readable by external engines. `OPTIMIZED` enables Snowflake-specific query optimizations. Choose based on your data query needs. For more information, see [STORAGE_SERIALIZATION_POLICY](/sql-reference/parameters#storage-serialization-policy).
'); -- Confirm the Iceberg version on the database SHOW PARAMETERS LIKE 'ICEBERG_VERSION_DEFAULT' IN DATABASE ; ``` ## Known limitations - **Tri-Secret Secure accounts and Snowflake storage**: Accounts with Tri-Secret Secure (TSS) enabled may be unable to create new Snowflake-managed Iceberg tables that use [Snowflake storage for Apache %iceberg-tm% tables](/user-guide/tables-iceberg-internal-storage). For details, see [Encryption](/user-guide/tables-iceberg-internal-storage#encryption). - **Incompatible type change.** When the source column type changes to a type that maps to a different Iceberg type, the table is marked as failed and requires a resnapshot. See [Type mapping reference](#type-mapping-reference) for the complete source-to-Iceberg type mapping. - **Parameter change within the same Iceberg type.** The connector doesn't recognize parameter changes within the same Iceberg type (for example, changing `decimal(10,2)` to `decimal(20,2)`). The column retains its current Iceberg type. - **Nanosecond timestamp range restriction on v3**: When DATETIME2(7) or DATETIMEOFFSET(7) maps to `timestamp_ns` or `timestamptz_ns` on v3, the representable date range narrows to 1677-09-21 through 2262-04-11. Values outside this range are rejected at insert time. - **DATETIMEOFFSET offset collapsed to UTC**: Iceberg has no offset-preserving timestamp type. The original timezone offset is lost; only the UTC instant is stored. - **Source timestamp precision widening not supported on v3**: If a source column's precision increases (for example, DATETIME2(6) altered to DATETIME2(7)), the Iceberg column type cannot be promoted from `timestamp` to `timestamp_ns`. The connector was created based on the original precision. - **Do not change Table Storage Format or Iceberg Version after the connector starts**: The connector's **Table Storage Format** and **Iceberg Version** parameter should not be modified after ingestion begins. Mixing settings across destination tables is not supported. To switch, follow the steps in [Switching table storage format or Iceberg version](#switching-table-storage-format-or-iceberg-version). ## Type mapping reference The following table shows how SQL Server types map to Snowflake standard and Iceberg destination types:
Source types not listed in the table are mapped to TEXT on standard tables and `string` on Iceberg tables. ## Switching table storage format or Iceberg version Switching between Standard and Iceberg, or between Iceberg v2 and v3, requires recreating the connector. Follow these steps: 1. Stop the connector. 2. Delete the process group in Openflow. 3. Manually clean up the destination database (drop the replicated schemas/tables, or use a new database). 4. Reimport the connector with the new **Table Storage Format** and select the target **Iceberg Version** when configuring the connector. This ensures all connector state is correctly cleaned up within Openflow. The new connector performs a fresh snapshot into the destination. ## Upgrading an existing connector to use Iceberg Version pinning Connector version `0.45.0` (multi-database) / `0.44.0` (CDC) introduces the **Iceberg Version** parameter. If you are upgrading from an earlier connector version, a new **Iceberg Version** field appears that you must configure to match your existing destination tables. 1. Stop the connector. 2. [Upgrade the runtime](/user-guide/data-integration/openflow/manage#label-openflow-upgrading-a-runtime) to version `2026.7.21` or later. 3. [Upgrade the connector](/user-guide/data-integration/openflow/manage#upgrade-a-connector) in place to the version listed above or later. 4. The **Iceberg Version** parameter defaults to `3` after the flow upgrade. Review and change to `2` if your existing destination tables are Iceberg v2 before starting the connector. 5. Start the connector. Selecting an **Iceberg Version** that doesn't match your existing destination tables can cause type-mapping errors or DDL failures. Always verify the version of your existing tables before choosing a value. ## References - [CREATE EXTERNAL VOLUME](/sql-reference/sql/create-external-volume) - [Data types for Apache Iceberg tables](/user-guide/tables-iceberg-data-types) - [ALTER DATABASE](/sql-reference/sql/alter-database) - [STORAGE_SERIALIZATION_POLICY](/sql-reference/parameters#storage-serialization-policy) - [Set up the Openflow Connector for SQL Server](/user-guide/data-integration/openflow/connectors/sql-server/setup) - [Set up the SQL Server CDC connector](/user-guide/data-integration/openflow/connectors/sql-server-cdc/setup) --- title: Openflow Connector for SQL Server: Maintenance source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/sql-server/maintenance.md section: Loading & Unloading Data --- # %sqlserver%: Maintenance This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Set up the Openflow Connector for SQL Server](/user-guide/data-integration/openflow/connectors/sql-server/setup) - [Openflow connectors for SQL Server: Data mapping](/user-guide/data-integration/openflow/connectors/sql-server/data-mapping) This topic describes maintenance considerations and best practices for the %sqlserver%, such as reinstalling the connector or setting the change tracking starting position. These operations are often used in conjunction with [Incremental replication without snapshots](/user-guide/data-integration/openflow/connectors/sql-server/incremental-replication). ## Check the replication status of a table Interim failures, such as connection errors or temporary source unavailability during a high-availability failover, do not prevent table replication. Replicated tables keep their current status and the connector retries on the next polling cycle. However, permanent failures, such as unsupported data types, prevent table replication. To troubleshoot replication issues or verify that a table has been successfully removed from the replication flow, check the Table State Store: 1. In the Openflow runtime canvas, right-click a processor group and choose **Controller Services**. A table listing controller services displays. 2. Locate the row labeled **Table State Store**, click the **More** %sf-vertical-more-button% button on the right side of the row, and then choose **View State**. A list of tables and their current states displays. Type in the search box to filter the list by table name. The possible states are: - **NEW**: The table is scheduled for replication but replication hasn't started. - **SNAPSHOT_REPLICATION**: The connector is copying existing data. This status displays until all records are stored in the destination table. - **INCREMENTAL_REPLICATION**: The connector is actively replicating changes. This status displays after snapshot replication ends and continues to display indefinitely until a table is either removed from replication or replication fails. - **FAILED**: Replication has permanently stopped due to an error. The Openflow runtime canvas doesn't display table status changes — only the current table status. However, table status changes are recorded in logs when they occur. Look for the following log message: ```text Replication state for table .. changed from to ``` If a permanent failure prevents table replication, remove the table from replication. After you address the problem that caused the failure, you can add the table back to replication. For more information, see [Restart table replication](#label-of-sql-server-restart-table-replication). ## Restart table replication This procedure re-snapshots the table in place. It requires connector version `0.53.0` or later, and runtime-extensions `2026.9.3.12` or later. On earlier versions, re-snapshotting a table that already exists in Snowflake fails instead of reloading in place. Upgrade the connector before you use this procedure. A table in a FAILED state (for example, due to a missing primary key or an unsupported schema change) does not restart automatically. If a table enters a FAILED state or you need to restart replication from scratch, use the following procedure to remove and re-add the table to replication. If the failure was caused by an issue in the source table such as a missing primary key, resolve that issue in the source database before continuing. 1. Remove the table from replication, using one of the following methods: - Add the table to the **Re-snapshot Table Exclusions** parameter to temporarily exclude it from replication. This approach is convenient when the table is matched by an **Included Table Regex** that you don't want to change. - In the **Ingestion Parameters** context, either remove the table from **Included Table Names** or modify the **Included Table Regex** so the table is no longer matched. 2. Verify the table has been removed: 1. In the Openflow runtime canvas, right-click a processor group and choose **Controller Services**. 2. In the table listing controller services, locate the **Table State Store** row, click the three vertical dots on the right side of the row, then choose **View State**. You must wait until the table's state is fully removed from this list before proceeding. Don't continue until this configuration change has completed. 3. Wait until all queues in the connector are empty before you re-add the table. When all FlowFiles have been processed, the **Queued** value on the connector's processor group becomes zero. Don't re-add the table while change events that were captured before you removed it are still queued. When you re-add a table, the connector loads the new snapshot in append-only mode, so any leftover change event that merges into the table after the re-snapshot might create duplicate rows in the destination table. 4. Re-add the table by reversing the change you made in the first step: either remove the table from **Re-snapshot Table Exclusions**, or add it back to **Included Table Names** or **Included Table Regex**. You do not need to drop the destination table first. The connector re-snapshots the table in place: it makes a zero-copy [clone](/sql-reference/sql/create-clone) of the current destination table to an archive table named `_ARCHIVE_`, clears the destination table, and then loads the fresh snapshot into the same destination table. Because the destination table object is preserved, dependent objects such as streams remain attached and continue to work. The archive table retains a copy of the destination table's contents from immediately before the reload, as a safeguard. The connector does not read from or write to it again, so you can drop it at any time once the backup is no longer needed, typically after you confirm that the re-snapshot completed and the destination data is correct. 5. Verify the restart: Check the **Table State Store** using the instructions given previously. The state of the table should appear with the status NEW, then transition to SNAPSHOT_REPLICATION, and finally to INCREMENTAL_REPLICATION. ## Increase the oversized value limit By default, the connector replicates individual values up to 16 MB and marks any table that contains a larger value as permanently failed. If your Snowflake account has the `ENABLE_OPENFLOW_CDC_SQLSERVER_SSV2` parameter set to `true`, the per-value limit can be raised from 16 MB to **128 MB**. The 128 MB limit applies in two ways: it's both the maximum size of a single value and the maximum total size of a row. The connector adds metadata columns to every replicated row (`_SNOWFLAKE_UPDATED_AT`, `_SNOWFLAKE_INSERTED_AT`, `_SNOWFLAKE_DELETED`) that count toward the per-row limit, along with all other columns in the row. As a result, a single value can't reach the full 128 MB in practice when the row includes other data. The increased limit doesn't apply equally to all column types. In Snowflake, the maximum size for `BINARY` is **64 MB** (`BINARY(67108864)`), even when the increased size limits are enabled. Only `VARCHAR`, `VARIANT`, `ARRAY`, and `OBJECT` columns can hold up to 128 MB. ### Check whether the 128 MB limit is available You may not be able to verify the `ENABLE_OPENFLOW_CDC_SQLSERVER_SSV2` parameter value by querying it. To check if it is enabled, see if the FlowFiles flow through the **Upload Rows via Snowpipe Streaming 2** processor (not through **Upload Rows via Snowpipe Streaming**). ### Configure the processors Update the **Oversized Value Limit** property to `128 MB` on the following processors: - **Fetch Table Rows** (in the **Snapshot Load** group): used for non-partitioned tables - **MultiDatabaseFetchTableSnapshot** (in the **Snapshot Load** group): used for partitioned tables - **Read SQLServer Change Tracking tables** (in the **Incremental Load** group) For each processor: 1. Locate the processor in the flow. On the connector canvas, you can use the search box in the top-right corner to find processors by name. 2. Right-click the processor and select **Configure**. 3. Open the **Properties** tab. 4. Set **Oversized Value Limit** to `128 MB`. 5. Apply the change. For tables that are already being replicated and have destination columns narrower than `VARCHAR(134217728)` or `BINARY(67108864)`, see [](#label-of-sql-server-migrate-oversized-value-tables). ### Migrate existing tables The steps in [](#label-of-sql-server-increase-oversized-value-limit) raise the limit for newly created destination tables. If a table is already being replicated and its destination column type is **not** `VARCHAR(134217728)` or `BINARY(67108864)`, but you now want to load values larger than the original 16 MB limit, you must manually widen the column type on **both** the journal and destination tables. Before you migrate, check the current destination column type, because it can vary depending on when the snapshot replication was performed. You must stop replication for the affected table before altering its journal or destination tables. Altering these tables while replication is active can corrupt in-flight data. To migrate a table: 1. Stop replication for the affected table by stopping the topmost processors of the **Snapshot Load** and **Incremental Load** groups until all queues are empty. For the equivalent stop procedure, see the substeps in [](#label-sql-server-reinstall-connector). 2. Widen the column on both the journal table and the destination table, according to the column type: 1. For **VARCHAR** columns, run `ALTER TABLE ... ALTER COLUMN ... SET DATA TYPE VARCHAR(134217728)` on the journal table and on the destination table (one statement per table). 2. For **BINARY** columns, Snowflake doesn't allow widening `BINARY` in place, so do the following on both the journal and destination tables: 1. Add a new column of type `BINARY(67108864)`. 2. Copy data from the original column into the new column. 3. Drop the original column and rename the new column to the original name. 3. Restart replication by re-enabling the processors. ### Performance considerations Raising the per-value limit increases the amount of data that the connector loads into memory and moves through the flow, which raises the load on both the runtime and the warehouse. Size the runtime and warehouse accordingly. When **Oversized Value Strategy** is set to **Set Null**, the connector still loads each oversized value into memory before it can replace it with `NULL`. If your tables contain multi-gigabyte LOB columns, exclude those columns from replication. During both snapshot and incremental replication, the queue in front of the **Upload Rows via Snowpipe Streaming 2** processor can fill with FlowFiles and trigger back pressure, which consumes a large amount of runtime disk space. For larger tables, use a Large runtime to provide additional storage. For guidance on choosing a size, see [Runtime sizing](/user-guide/data-integration/openflow/connectors/sql-server/setup#label-sql-server-runtime-sizing). #### Snapshot replication To speed up snapshot replication, you can increase the number of channels that the **Upload Rows via Snowpipe Streaming 2** processor uses. The number of channels is set by the processor's **Channel Group** property, which defaults to `${chunk.index:isEmpty():ifElse('1', ${chunk.index:mod(8)})}`. To increase the number of channels: 1. Locate the **Upload Rows via Snowpipe Streaming 2** processor in the flow. 2. Stop the processor. You must stop the processor before you can change its properties. 3. Right-click the processor and select **Configure**. 4. Open the **Properties** tab. 5. In the **Channel Group** property, increase the value `8` in the expression. For example, change `8` to `16` to double the number of channels. 6. Apply the change. 7. Start the processor. While a snapshot replication is in progress, only increase the number of channels. Decreasing the number of channels during an active snapshot can cause data loss. #### Incremental replication When the source produces frequent changes to rows that contain large values, you might need a Large warehouse. High-frequency merges of many moderately large rows (for example, many 8 MB values) can require a large single merge operation, and smaller warehouses can run out of memory. By contrast, fewer very large rows (for example, 128 MB values) are streamed file by file through the **Upload Rows via Snowpipe Streaming 2** processor, and each file is merged incrementally, which typically completes without warehouse errors even on smaller warehouses. ## Enable error logging on an existing schema When you set the **Error Handling Strategy** parameter to **Log Errors and Continue**, the connector enables error logging automatically only on tables that it creates afterward. Tables that the connector created earlier don't capture rejected rows until you turn on error logging for them. For more information about the error-handling strategies, see [](/user-guide/data-integration/openflow/connectors/sql-server/about#label-sql-server-error-handling). Because the connector stores journal tables in the same schema as the destination tables, you can turn on error logging for a whole destination schema at once. Run the following stored procedure once per destination schema. Replace `my_database` with your destination database and `my_schema` with the destination schema. The schema name is passed as a quoted identifier (for example, `'"my_schema"'`) so it matches the exact, case-sensitive name that the connector created. For more information about how the connector names destination schemas, see [](/user-guide/data-integration/openflow/connectors/sql-server/setup#label-of-sqlserver-destination-parameters). ```sql USE DATABASE my_database; WITH enable_error_logging AS PROCEDURE (schema_name STRING) RETURNS STRING LANGUAGE SQL AS $$ DECLARE tables RESULTSET; table_count NUMBER DEFAULT 0; BEGIN SHOW TABLES IN SCHEMA IDENTIFIER(:schema_name); -- Assign AFTER SHOW TABLES so LAST_QUERY_ID() refers to that result tables := ( SELECT "database_name", "schema_name", "name" FROM TABLE(RESULT_SCAN(LAST_QUERY_ID())) WHERE "kind" = 'TABLE' ); FOR t IN tables DO -- Double-quote each identifier so names with special characters are handled safely EXECUTE IMMEDIATE 'ALTER TABLE "' || REPLACE(t."database_name", '"', '""') || '".' || '"' || REPLACE(t."schema_name", '"', '""') || '".' || '"' || REPLACE(t."name", '"', '""') || '" ' || 'SET ERROR_LOGGING = TRUE'; table_count := table_count + 1; END FOR; RETURN 'Enabled ERROR_LOGGING on ' || table_count || ' table(s) in schema ' || :schema_name; END; $$ CALL enable_error_logging('"my_schema"'); ``` ### Verify that error logging is enabled To confirm that error logging is enabled on every table in a schema, run the following procedure. It reports how many tables have error logging enabled and how many don't. ```sql USE DATABASE my_database; WITH verify_error_logging AS PROCEDURE (schema_name STRING) RETURNS STRING LANGUAGE SQL AS $$ DECLARE tables RESULTSET; probe RESULTSET; total_tables NUMBER DEFAULT 0; logging_enabled NUMBER DEFAULT 0; disabled_or_invisible NUMBER DEFAULT 0; BEGIN SHOW TABLES IN SCHEMA IDENTIFIER(:schema_name); -- Assign AFTER SHOW TABLES so LAST_QUERY_ID() refers to that result tables := ( SELECT "database_name", "schema_name", "name" FROM TABLE(RESULT_SCAN(LAST_QUERY_ID())) WHERE "kind" = 'TABLE' ); FOR t IN tables DO total_tables := total_tables + 1; -- Probe ERROR_TABLE(): it succeeds only when error logging is enabled and visible BEGIN probe := ( EXECUTE IMMEDIATE 'SELECT 1 FROM ERROR_TABLE(' || '"' || REPLACE(t."database_name", '"', '""') || '".' || '"' || REPLACE(t."schema_name", '"', '""') || '".' || '"' || REPLACE(t."name", '"', '""') || '"' || ') LIMIT 1' ); logging_enabled := logging_enabled + 1; EXCEPTION WHEN STATEMENT_ERROR THEN disabled_or_invisible := disabled_or_invisible + 1; END; END FOR; RETURN 'schema=' || :schema_name || ', total_tables=' || total_tables || ', error_logging_enabled=' || logging_enabled || ', error_logging_disabled_or_not_visible=' || disabled_or_invisible; END; $$ CALL verify_error_logging('"my_schema"'); ``` ## Reinstall the connector This section provides instructions on how to reinstall the connector, and continue replicating data for the same tables without having to snapshot them again. It covers situations where the new connector is installed in the same runtime, as well as when it's moved to a new runtime. ### Prerequisites Review and note connector parameter context values. If you reinstall the connector in the same runtime, you can reuse the existing context. If the new instance is located in a different runtime, you must re-enter all parameters. 1. Finish processing all in-flight FlowFiles in the existing connector, then stop the connector. 1. Sign in to %sf-web-interface-link%. 2. In the navigation menu, select **Ingestion** %raa% **Openflow**. 3. Select **Launch Openflow**. 4. In the **Openflow** pane select the **Runtimes** tab. 5. Select the runtime containing the connector. 6. Select the connector. 7. Stop the topmost processor **Set Tables for Replication** in the **Snapshot Load** group. 8. Stop the topmost processor **Read SQLServer Change Tracking tables** in the **Incremental Load** group. 9. If you changed the value of the **Merge Task Schedule CRON** parameter, return it to `* * * * * ?`; otherwise, queues won't be emptied until the next scheduled run. Wait until all FlowFiles in the connector have been processed, and all queues are empty. When all FlowFiles have been processed, the **Queued** value on the connector's processor group becomes zero. If there are any items left in the original connector's queues, there may be data gaps when the new connector starts. 10. Stop all processors and controller services in the connector. The existing connector can remain in the runtime and doesn't interfere with the new instance, as long as it remains stopped. 2. If you're moving the connector to a new runtime, download the flow definition from the existing connector so that you can recreate the connector with its current state instead of configuring it from scratch. Downloading a flow definition requires Openflow Runtime Server version 2026.6.4.18 or later. 1. Right-click the connector's process group, then select **Download flow definition**. 2. Select both of the following options, then download the flow definition: - **Export with External Services**: includes the controller services that the connector references from parent process groups. - **Export with Components State**: includes component state, such as change tracking positions and incremental replication state, so that replication continues from where it left off. 3. Create the connector in the target runtime: - If you downloaded the flow definition, import it into the new runtime. Importing the flow definition preserves the component state captured during the export, so the connector resumes incremental replication from its previous positions. - Otherwise, create a new instance of the connector. If you use the same runtime as the original connector, you can choose to keep the existing parameter contexts and reuse the settings. 4. If you install into a different runtime or you deleted the previous parameter contexts, enter the configuration settings into the new parameter contexts, including the table names and patterns as described in [Set up the Openflow Connector for SQL Server](/user-guide/data-integration/openflow/connectors/sql-server/setup). A downloaded flow definition doesn't include sensitive values (such as passwords) or uploaded files (such as the Microsoft JDBC driver), so you must re-enter and re-upload them. 5. Navigate to the `SQLServer Ingestion Parameters` context, and set the following parameters: - Set the `Ingestion Type` parameter to `incremental`. For information, see [](#label-sql-server-incremental-replication). - Set the `Starting Change Tracking Position` parameter to `Earliest`. For information, see [](#label-sql-server-connector-start-restart-incremental-load-from-earliest-available-change-tracking-position). If you imported the flow definition with **Export with Components State** selected, the connector retains its previous change tracking positions. In this case, leave `Starting Change Tracking Position` set to `Latest` to continue replication from where it stopped. 6. Start the new connector. ### Usage notes The new connector uses the existing destination tables created by the original connector, but creates new journal tables. ## Specify load from change tracking table position The %sqlserver% connector lets you select the starting position where change tracking tables are read. By default, the connector reads from the latest available position. Alternatively, you can choose the earliest position available on the source instance. Choosing to start from the earliest position is common when reinstalling the connector. This allows the new instance to catch up and continue replicating existing tables without having to snapshot each again. Switching a running connector from latest to earliest position causes the contents of change tracking tables to be re-read, re-processed, and re-applied to the destination table. While the change tracking tables are being re-read, the data in affected destination tables can become out of sync with their sources until all events have been re-processed and merged. The following parameters are available in the `Ingestion Parameters` context:
To determine whether the connector finished re-reading the change tracking tables: 1. Navigate to the Openflow canvas. 2. Open the **Incremental Load** process group. 3. Right-click the topmost processor named **Read SQLServer Change Tracking tables**, then select **View state**. 4. Check the state entries for every table with keys starting with `position.`. If a value is `0/0` then the connector has not yet finished re-reading the changes for this table. ### Usage notes - After you switch a running connector to read from the earliest positions and start it, you can't reconfigure or cancel the process, and it will continue until the currently read positions reach the latest values. - Switching to the earliest position on a running connector will, for any tables being re-processed, finish their existing journals, and create new journal tables. --- title: Openflow Connector for SQL Server: Set up incremental replication without snapshots source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/sql-server/incremental-replication.md section: Loading & Unloading Data --- # %sqlserver%: Set up incremental replication without snapshots This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Set up the Openflow Connector for SQL Server](/user-guide/data-integration/openflow/connectors/sql-server/setup) - [Openflow connectors for SQL Server: Data mapping](/user-guide/data-integration/openflow/connectors/sql-server/data-mapping) You can configure the %sqlserver% connector to immediately replicate incremental changes for newly added tables, bypassing snapshots. Use incremental load to continue replication without snapshotting every table again when you reinstall the connector over previously replicated data. To enable incremental replication in a new connector instance: 1. Set up the connector as described in [Set up the Openflow Connector for SQL Server](/user-guide/data-integration/openflow/connectors/sql-server/setup). 2. In the `SQLServer Ingestion Parameters` context, set the `Ingestion Type` parameter to `incremental`. ## Enable incremental replication without snapshots To enable incremental replication on an existing connector: 1. sign in to %sf-web-interface-link%. 2. in the navigation menu, select **Ingestion** %raa% **Openflow**. 3. In the **Openflow** pane select the **Runtimes** tab. 4. Select the runtime containing the connector. 5. Select the connector. 6. In the `Ingestion Parameters` context, specify `Ingestion Type` = `incremental`. 7. Add new replication tables. These tables immediately switch to their incremental load. To return to replicating tables with the snapshot load, change **Ingestion Type** from `incremental` to `full`. # Usage notes - Changing the value of **Ingestion Type** does not impact any tables that have begun replicating data. Tables currently in the snapshot phase continue until the snapshot load is complete. - While **Ingestion Type** is set to `incremental`, new tables added to the list of replicated tables bypass the snapshot phase. This includes new tables added to the source database that match the `Included Table Regex` parameter. Ensure that the ingestion type is set to `incremental` to bypass the snapshot phase. Connectors should only remain in `incremental` mode as long as required as it bypasses snapshots. Once customer needs for incremental updates have been satisfied the connector should be returned to `full` mode. - For tables that bypass snapshot load, the connector creates a destination table in Snowflake, by executing `CREATE TABLE IF NOT EXISTS`, only if no destination table already exists. Tables going through the snapshot require that no destination table exist. ## Recover a table using incremental-only mode If a table's snapshot completed successfully but incremental replication later failed, you don't need to remove the table and snapshot it again. Instead, you can recover the table by replaying the changes that are still available in the source change tracking tables and merging them onto the existing destination table. Incremental replication can fail for several reasons, for example: - A record in the source database can't be read because it has an incorrect or unsupported format. - A row exceeds the maximum supported size. - A merge operation can't complete. - A transient error persists through so many retries that the table enters the FAILED state. To recover the table without a new snapshot, remove it from replication, switch the connector to incremental-only mode reading from the earliest available position, and add the table back. The connector reads all available changes from the oldest available change tracking position, then replays and reapplies them to the destination table. Before you recover the table, address the underlying cause of the failure. Otherwise, the connector encounters the same error again when it replays the changes. For example, raise the per-value limit (see [Increase the oversized value limit](/user-guide/data-integration/openflow/connectors/sql-server/maintenance#label-of-sql-server-increase-oversized-value-limit)) or fix the problematic record in the source database. To recover the table: 1. Remove the table from replication. In the `Ingestion Parameters` context, remove the table from **Included Table Names**, or modify **Included Table Regex** so the table is no longer matched. Wait until the table's state is fully removed from the **Table State Store** controller service before you continue. Don't drop the destination table. This procedure reuses the existing destination table and replays incremental changes onto it. 2. Stop the connector's process group so that you can change its configuration. On the connector canvas, right-click the connector's process group and select **Stop**. 3. In the `Ingestion Parameters` context, set the `Ingestion Type` parameter to `incremental`. 4. Set the `Starting Change Tracking Position` parameter to `Earliest`. The connector reads all available changes again from the oldest available change tracking position, then replays and reapplies them to the destination table. For more information, see [Specify load from change tracking table position](/user-guide/data-integration/openflow/connectors/sql-server/maintenance#label-sql-server-connector-start-restart-incremental-load-from-earliest-available-change-tracking-position). Leave `Re-read Tables in State` at its default value, `New`, so that only the table you add back reads from the earliest position. Tables already in replication continue from their last positions. 5. Add the table back to replication by reversing the change you made in step 1. 6. Start the connector's process group. Right-click the connector's process group and select **Start**. 7. Wait until the table returns to incremental replication. In the **Table State Store** controller service state, the table transitions to INCREMENTAL_REPLICATION when recovery completes. 8. Revert the changes you made in steps 3 and 4: set `Ingestion Type` and `Starting Change Tracking Position` back to their previous values. This procedure recovers only the changes still retained in the source change tracking tables. If the change tracking retention period expired and some changes were purged, the recovered table can have gaps. In that case, you must take a new snapshot to fully resynchronize the table. --- title: Openflow connectors source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/about-openflow-connectors.md section: Loading & Unloading Data --- # Openflow connectors This feature is not available in the People's Republic of China. Openflow is available to all accounts in AWS [](#label-na-general-regions). The connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) - [Set up Openflow - Snowflake Deployment - Task overview](/user-guide/data-integration/openflow/setup-openflow-spcs) - [Manage Openflow](/user-guide/data-integration/openflow/manage) Openflow connectors are curated, versioned Apache NiFi flow definitions built using open-source and proprietary NiFi components. These connectors follow a strict set of design patterns to ensure performance, fault-tolerance, and ease of configuration. Review the details of the following connectors available in Openflow:
--- title: Openflow connectors for SQL Server: Data mapping source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/sql-server/data-mapping.md section: Loading & Unloading Data --- # Openflow connectors for SQL Server: Data mapping This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [About Openflow Connector for SQL Server](/user-guide/data-integration/openflow/connectors/sql-server/about) - [About Openflow Connector for SQL Server (CDC)](/user-guide/data-integration/openflow/connectors/sql-server-cdc/about) This topic describes how SQL Server data types are mapped to Snowflake data types. The mapping is the same for the %sqlserver% and the %sqlservercdc%. ## SQL Server to Snowflake data type mapping The following table shows how SQL Server data types are mapped to Snowflake data types when replicating data.
For types with default size limits (8 MB / 16 MB) in this table, it is possible to raise these limits. For details of the %sqlservercdc%, see [Oversized values](/user-guide/data-integration/openflow/connectors/sql-server-cdc/about#label-sql-server-cdc-oversized-values) and for %sqlserver%, see [Oversized values](/user-guide/data-integration/openflow/connectors/sql-server/about#label-sql-server-oversized-values). Any SQL Server data types not listed in this table are mapped to TEXT by default. --- title: Openflow gen 1 and gen 2 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/gen2/openflow-generations.md section: Loading & Unloading Data --- # Openflow gen 1 and gen 2 Available to all accounts. - [Second generation Openflow objects and interfaces](/user-guide/data-integration/openflow/gen2/index) - [About Openflow](/user-guide/data-integration/openflow/about) - [Configure a connector with the setup wizard](/user-guide/data-integration/openflow/gen2/setup-connector-wizard) Enabled accounts can use gen 1 and gen 2 Openflow resources: - **First generation (gen 1)** — The current generally available Openflow model. Deployments and runtimes are created with `CREATE OPENFLOW DATA PLANE INTEGRATION` and `CREATE OPENFLOW RUNTIME INTEGRATION` (UI or SQL). Connectors are Apache NiFi process groups installed from the connector catalog with **Install** (Openflow UI) and configured on the runtime canvas. - **Second generation (gen 2)** — Deployments, runtimes, and connectors are first-class Snowflake objects created with SQL commands (`CREATE OPENFLOW DEPLOYMENT`, `CREATE OPENFLOW RUNTIME`, `CREATE OPENFLOW CONNECTOR`) or by installing from the connector catalog in the Openflow UI. Gen 2 connectors are [File Based Entities (FBEs)](/user-guide/data-integration/openflow/gen2/connector-versioning) with versioned configuration and can use the setup wizard. Any newly created Openflow deployment is gen 2. Existing gen 1 deployments stay gen 1 until you migrate them, and new runtimes on a gen 1 deployment are gen 1. Gen 2 runtimes support both gen 1 and gen 2 connectors — you do not need to wait for a gen 2 version of a connector to use it on a gen 2 runtime. This topic explains how gen 1 and gen 2 differ and which documentation to follow for each. ## Overview Gen 1 and gen 2 resources share the same Openflow platform concepts—BYOC and %OFSFSPCS% deployment types, NiFi-based data movement, and Snowflake as a destination—but they differ in how objects are created, secured, and managed. Gen 2 is the long-term Openflow management model: SQL-accessible objects, granular privileges, and connectors with committed configuration versions. During the preview, gen 1 resources you already have continue to work unchanged. New gen 2 resources are created separately and follow Gen 2 lifecycle rules. ## Why migrate to gen 2? **Manage everything with SQL** Gen 2 deployments, runtimes, and connectors are first-class Snowflake objects. Create, configure, start, stop, and remove them with SQL commands (`CREATE OPENFLOW DEPLOYMENT`, `ALTER OPENFLOW CONNECTOR ... START`, and so on) or the Openflow UI. Because these are standard SQL operations, you can programmatically schedule runtime suspends during off-hours to reduce total cost of ownership. **CI/CD and infrastructure as code** Gen 2 connectors store configuration as versioned files ([File Based Entities](/user-guide/data-integration/openflow/gen2/connector-versioning)). Draft changes, commit them, and roll back to a previous version. Reuse validated configs across environments through Git workflows, promote configurations from dev to production without click-ops, and integrate connector management into CI/CD pipelines. Gen 2 objects are also supported by the Snowflake Terraform provider for infrastructure-as-code workflows. **Setup wizard for guided installation** Gen 2 connectors can be installed through a step-by-step setup wizard that validates connectivity and configuration before starting. Gen 1 connector installation requires manual configuration of processors, controller services, and parameter contexts on the canvas. **Granular access control** Gen 2 runtimes and connectors are schema-scoped objects with standard Snowflake RBAC. Control who can see deployments, operate runtimes, or manage connectors using `GRANT USAGE` and `GRANT OPERATE`. **To get started:** Migration from gen 1 to gen 2 is available in Private Preview. Contact your Snowflake account representative to be included. ## Comparison by resource type ### Deployments
**Snowflake deployment limit:** Each account supports up to three Snowflake Openflow deployments. Gen 1 and gen 2 deployments share this limit; `CREATE OPENFLOW DEPLOYMENT WITH DEPLOYMENT_TYPE = SNOWFLAKE` fails when the account already has three Snowflake deployments, regardless of generation. ### Runtimes
### Connectors
## Authorization differences ### USAGE on a deployment does not grant visibility on runtimes In gen 1, users with `USAGE` on a deployment can see its runtimes. In gen 2, `USAGE` on a deployment does **not** grant access to runtimes in that deployment. To access or manage a runtime, the user must have `USAGE`, `OPERATE`, or `MONITOR` granted **directly on the runtime**, and `USAGE` on the runtime's database and schema. ### Users must have a privilege on a deployment to see it In gen 1, all users can see all deployments in the account. In gen 2, a user must hold a role with a qualifying privilege on the deployment to see it in listings. If secondary roles are enabled, secondary roles are considered when determining deployment visibility. ### Runtime object privileges Gen 1 runtimes are represented by account-level `OPENFLOW RUNTIME INTEGRATION` objects. Required privileges on that integration object are `USAGE`, `OPERATE`, or `MONITOR`. Gen 2 runtimes are schema-level objects. Required privileges are: - `USAGE`, `OPERATE`, or `MONITOR` on the runtime object itself, **and** - `USAGE` on the runtime's database and schema ### Connector privileges Most connector operations derive privileges from the parent runtime. If you have `USAGE` on the runtime, you can start, stop, configure, and terminate connectors in that runtime. `OWNERSHIP` on the connector object itself is required for metadata changes, rename, and `DROP`. ### Transferring OWNERSHIP `GRANT OWNERSHIP` on gen 2 Openflow deployments, runtimes, or connectors can break underlying functionality today (for example, deployment agent credentials or runtime control-plane bindings). The command is accepted in SQL, but **avoid transferring ownership** until an upcoming update addresses this behavior. ## Behavior differences ### Runtime deletion workflow Before you delete a runtime in either generation, stop the connectors in that runtime. Gen 1 runtimes follow this workflow: ``` ACTIVE → (stop connectors) → (suspend) → SUSPENDED → (delete from UI) → removed ``` Gen 2 runtimes follow this workflow: ``` ACTIVE → (stop connectors) → (suspend) → SUSPENDED → (terminate) → TERMINATED → (drop) → removed ``` `ALTER OPENFLOW RUNTIME ... TERMINATE` drains in-flight connector data before removal. Use `TERMINATE FORCE` to purge queues instead of draining when you accept possible data loss. From the UI: 1. Stop connectors in the runtime. 2. Select **Launch Openflow**, open the **Runtimes** tab, and open the runtime **menu**. 3. Select **Suspend**. 4. From the same menu, select **Delete** (terminates the runtime). 5. From the same menu, select **Drop**. From SQL: ```sql ALTER OPENFLOW RUNTIME my_db.my_schema.my_runtime SUSPEND; SELECT SYSTEM$WAIT_FOR_STABLE_OPENFLOW_RUNTIMES(600, 'my_db.my_schema.my_runtime'); ALTER OPENFLOW RUNTIME my_db.my_schema.my_runtime TERMINATE; SELECT SYSTEM$WAIT_FOR_STABLE_OPENFLOW_RUNTIMES(600, 'my_db.my_schema.my_runtime'); DROP OPENFLOW RUNTIME my_db.my_schema.my_runtime; ``` In UI-driven workflows, wait for each step to finish before starting the next. In scripts, call `SYSTEM$WAIT_FOR_STABLE_OPENFLOW_*` after asynchronous `ALTER` commands. See [SYSTEM$WAIT_FOR_STABLE_OPENFLOW_DEPLOYMENTS](/sql-reference/functions/system_wait_for_stable_openflow_deployments), [SYSTEM$WAIT_FOR_STABLE_OPENFLOW_RUNTIMES](/sql-reference/functions/system_wait_for_stable_openflow_runtimes), [SYSTEM$WAIT_FOR_STABLE_OPENFLOW_CONNECTORS](/sql-reference/functions/system_wait_for_stable_openflow_connectors). ### Connector deletion workflow **gen 1** connectors are NiFi process groups on the runtime canvas. They are not `OPENFLOW CONNECTOR` objects and cannot be removed with `ALTER OPENFLOW CONNECTOR` or `DROP OPENFLOW CONNECTOR`. Stop ingestion and remove the process group using connector-specific steps on the canvas and in that connector's public setup or maintenance topic. **gen 2** connectors are first-class Snowflake objects removed with **stop** → **terminate** → **drop**. Use **Start** / **Stop** on **Installed Connectors** or `ALTER OPENFLOW CONNECTOR ... START|STOP` for day-to-day control; use **Delete** / **Drop** or `TERMINATE` / `DROP OPENFLOW CONNECTOR` for removal. UI **Delete** maps to `TERMINATE`; UI **Drop** maps to `DROP OPENFLOW CONNECTOR`. **`TERMINATE`** drains in-flight data before removal. For full UI and SQL removal steps, wait functions, and cleanup guidance, see [Manage the gen 2 Openflow connector lifecycle](/user-guide/data-integration/openflow/gen2/manage-connector-lifecycle). ### Gen 2 connector configuration Gen 1 connectors are configured on the runtime canvas: parameter contexts, controller services, and processors, following that connector's public setup documentation. Gen 2 connectors use versioned configuration (see [gen 2 connector configuration and versioning](/user-guide/data-integration/openflow/gen2/connector-versioning)). A connector in **Draft** state must be committed before it can start. The UI shows **Edits not applied** when a live version exists alongside a committed default version. For gen 2 connectors, the runtime canvas is read-only for configuration. Use **Installed Connectors** %raa% **Edit**, the setup wizard, or SQL/API commands to change settings. ## How to identify gen 1 and gen 2 resources Use the following checks when you are unsure whether a resource is gen 1 or gen 2. ### In the Openflow UI The fastest check is the **gen 2** label in Openflow: - **Deployments** and **runtimes** — gen 2 resources show a **gen 2** tag in the Openflow UI. Gen 1 resources do not. ### Deployments and runtimes in SQL Gen 1 and gen 2 objects use different `SHOW` commands. These are Openflow-specific listings—not the generic `SHOW INTEGRATIONS` command. **gen 2 deployments** — Listed by `SHOW OPENFLOW DEPLOYMENTS`. You must hold a qualifying privilege on the deployment to see it. **gen 1 deployments** — Listed by `SHOW OPENFLOW DATA PLANE INTEGRATIONS`. They do not appear in `SHOW OPENFLOW DEPLOYMENTS`. **gen 2 runtimes** — Listed by `SHOW OPENFLOW RUNTIMES IN ACCOUNT`. Each row includes `database_name` and `schema_name` columns; the fully qualified name is `..`. **gen 1 runtimes** — Listed by `SHOW OPENFLOW RUNTIME INTEGRATIONS`. Runtime names are not schema-qualified and do not appear in `SHOW OPENFLOW RUNTIMES`. If `SHOW OPENFLOW DEPLOYMENTS` returns a SQL error (not an empty result), the account does not support gen 2 SQL objects. Use the gen 1 `SHOW OPENFLOW ... INTEGRATIONS` commands and the public gen 1 documentation instead. ### Connectors Gen 2 connectors are first-class Snowflake objects. Gen 1 connectors are NiFi process groups on the runtime canvas only—they are not separate Snowflake objects. **You have a gen 2 connector if any of the following is true:** - The connector shows a **gen 2** label in the catalog or on **Installed Connectors**. - The connector appears on the **Installed Connectors** tab for its runtime. - `SHOW OPENFLOW CONNECTORS` or `DESCRIBE OPENFLOW CONNECTOR` returns the connector (when you have access). **You have a gen 1 connector if any of the following is true:** - The connector is visible on the runtime canvas but does **not** appear on **Installed Connectors**. - The connector was installed on the canvas (for example, **Install** from the catalog on a gen 1 runtime, or **Import from Registry** on a gen 2 runtime—see [Gen 1 and gen 2 coexistence](#label-openflow-generations-coexistence)). **Using SQL to tell gen 1 from gen 2** - If `SHOW OPENFLOW CONNECTORS` or `DESCRIBE OPENFLOW CONNECTOR` returns the connector, it is gen 2 (when you have the required privileges). - If those commands return no row, the connector might be gen 1 **or** you might lack `USAGE` on the parent runtime (or another required privilege). Use the UI checks above—especially whether the connector appears on **Installed Connectors**—before assuming it is gen 1. If you see a process group on the canvas that is missing from **Installed Connectors** and you have confirmed you have access to the runtime, treat it as gen 1 and follow that connector's public setup documentation. ## Coexistence Gen 1 and gen 2 resources can exist in the same account, with these rules: - **New deployments after account enablement** — Once your account is enabled for gen 2, you can only create new gen 2 deployments. `CREATE OPENFLOW DATA PLANE INTEGRATION` is no longer available for any deployment type (BYOC or Snowflake). Existing gen 1 deployments continue to work unchanged and can be migrated. Migration from gen 1 to gen 2 is available in Private Preview; contact your Snowflake account representative to be included. - **Gen 2 runtimes** — Support both gen 1 and gen 2 connectors; both types can coexist on the same runtime. Install gen 2 connectors from the connector catalog in the Openflow UI (using the setup wizard). If a gen 2 catalog entry isn't available for your source yet, or if you prefer the gen 1 connector, install it from the connector catalog — it runs on the same gen 2 runtime and follows that connector's public setup documentation. - **Gen 1 runtimes** — Support gen 1 connectors only. Don't install gen 2 connectors on a gen 1 runtime. - **Snowflake deployment limit** — Each account supports up to three Snowflake Openflow deployments. Gen 1 and gen 2 deployments share this limit; `CREATE OPENFLOW DEPLOYMENT WITH DEPLOYMENT_TYPE = SNOWFLAKE` fails when the account already has three Snowflake deployments, regardless of generation. - **Shared source setup** — Source preparation (database permissions, network access, secrets) often follows the same public connector setup documentation for gen 1 and gen 2. Gen 2 topics link to those instructions where applicable. Migration from gen 1 to gen 2 is available in Private Preview. Contact your Snowflake account representative to be included. ## Which documentation to follow Use this decision guide to choose the right topic:
--- title: Openflow security source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/security/index.md section: Loading & Unloading Data --- # Openflow security This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions). - [About Openflow](/user-guide/data-integration/openflow/about) - [Workload identity federation for Snowflake workloads that access external services](/user-guide/workload-identity-federation-outbound) This section describes how Openflow runtimes securely authenticate to external systems. ## Topics - [Use Workload Identity Federation with Openflow](/user-guide/data-integration/openflow/security/workload-identity-federation) --- title: Openflow Snowflake Deployment cost and scaling considerations source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/cost-spcs.md section: Loading & Unloading Data --- # Openflow Snowflake Deployment cost and scaling considerations This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). - [About Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/about-spcs) - [Set up Openflow - Snowflake Deployment - Task overview](/user-guide/data-integration/openflow/setup-openflow-spcs) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Monitor Openflow using telemetry data](/user-guide/data-integration/openflow/monitor) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) When running %ofsfspcs% you must be aware of the cost considerations associated with multiple Snowflake components, including, but not limited to, the following cost categories: - Compute pool costs - Snowpark Container Services infrastructure - Data Ingestion - Telemetry Data Ingestion - Other costs not explicitly mentioned in this topic Using and scaling Openflow involves understanding these costs. The following sections describe Openflow costs in general, and provide a number of examples of scaling Openflow runtimes and associated costs. ## %ofsfspcs% costs When using %ofsfspcs%, you can incur costs from multiple Snowflake components that Openflow uses. These cost categories are described in the following sections. However, your actual costs may vary based on your specific environment. See [](#label-openflow-spcs-consumption-examples) for examples of different cost consumption scenarios. ### Openflow compute pool costs This cost category is shown as **Openflow Compute Snowflake** on your Snowflake bill. The total costs for running Openflow are based on the number and types of instances used by [Snowpark Container Service compute pools](/developer-guide/snowpark-container-services/working-with-compute-pool) in your Snowflake account. Openflow uses compute pools for two different purposes: - Openflow Management Services Openflow Management Services run as part of an Openflow deployment. They use a compute pool to manage the Openflow deployment. This compute pool begins running as soon as you create a deployment. It continues to run as long as the deployment is active. The compute pool associated with the Openflow Management Services continues to run and incurs costs, even if there are no runtimes running. - Openflow runtimes Openflow uses compute pools to run the Openflow runtimes. The number of compute pools required and the number of nodes within each compute pool are scaled based on the number of runtimes that are currently running. When all runtimes associated with a compute pool are stopped, the compute pool associated with the runtimes is scaled down to 0 nodes. No costs are incurred for a runtime compute pool when it is not in use. Credits are billed per-second with a 5-minute minimum. For information on the rate per Snowpark Container Services Compute Instance Family per hour, refer to Table 1(d) in the [Snowflake Service Consumption Table](https://www.snowflake.cn/legal-files/CreditConsumptionTable.pdf). The following views in the [Account Usage](/sql-reference/account-usage) schema provide additional details on Openflow compute costs: - [METERING_DAILY_HISTORY](/sql-reference/account-usage/metering_daily_history) - [METERING_HISTORY](/sql-reference/account-usage/metering_history) Compute pool costs related to Openflow appear under *SERVICE_TYPE* as *OPENFLOW_COMPUTE_SNOWFLAKE*. In these rows, *NAME* returns the name of the compute pool that incurred the cost, which lets you separate Openflow Management Services costs from runtime costs. The [OPENFLOW_USAGE_HISTORY](/sql-reference/account-usage/openflow_usage_history) view currently does not contain records for the *OPENFLOW_COMPUTE_SNOWFLAKE* service type. That view covers Openflow BYOC deployments only. As a result, per-runtime cost attribution isn't available for Openflow Snowflake Deployments. For more information on compute costs in Snowflake, see [Exploring compute cost](/user-guide/cost-exploring-compute). ### Snowpark Container Services infrastructure costs In addition to compute pool costs, there are costs associated with additional Snowpark Container Services infrastructure, including storage and data transfer. For additional information, see [Snowpark Container Services costs](/developer-guide/snowpark-container-services/accounts-orgs-usage-views). ### Data ingestion costs Costs are incurred when loading data into Snowflake using services such as Snowpipe or Snowpipe Streaming. These costs are based on the volume of data ingested. These costs appear on your Snowflake bill under their respective ingestion services line items. Additionally, some connectors may require a warehouse and will incur warehouse costs. For example, database CDC connectors require a warehouse for both the initial snapshots and ongoing incremental Change Data Capture (CDC). ### Telemetry data ingestion costs When using an event table to store telemetry data for Openflow, Snowflake charges for sending logs and metrics to Openflow deployments. There are also charges for sending runtime telemetry data to your event table within Snowflake. The rate for credits per GB of telemetry data is specified in Table 5 in the [Snowflake Service Consumption Table](https://www.snowflake.cn/legal-files/CreditConsumptionTable.pdf). This item is referred to as Telemetry Data Ingest. ## Reducing Openflow credit consumption If you have runtimes that are not actively in use, you can suspend them to reduce costs. Suspending a runtime stops credit consumption for the associated runtime compute pool. When a runtime is suspended, its compute pool scales down to 0 nodes and no longer incurs charges. ## %ofsfspcs% costs associated with runtimes and scaling behavior How you choose to configure and scale runtimes is important for managing costs effectively. Openflow supports different runtime types, each with its own scaling characteristics and associated costs. ### Mapping runtimes to Snowflake compute pools The runtime type you choose determines the runtime pods that are scheduled on the associated compute pool. Using a larger runtime type will result in a larger compute pool being used, which will incur higher costs. The runtime sizes and their scaling behavior are described in the following table: | Runtime type | vCPUs | Available memory (GB) | Snowflake Compute Pool instance family | Snowflake Compute Pool | Instance Family - vCPUs | Instance Family - memory (GB) | | ------------ | ----- | --------------------- | -------------------------------------- | -------------------------- | ----------------------- | ----------------------------- | | Small | 1 | 2 | CPU_X64_S | INTERNAL_OPENFLOW_0_SMALL | 4 | 16 | | Medium | 4 | 10 | CPU_X64_SL | INTERNAL_OPENFLOW_0_MEDIUM | 16 | 64 | | Large | 8 | 20 | CPU_X64_L | INTERNAL_OPENFLOW_0_LARGE | 32 | 128 | Openflow scales the underlying Snowflake Compute Pools when additional compute pool nodes need to be scheduled, based on CPU consumption, and up to the maximum node setting set during runtime creation. Compute pools are configured with a minimum size of 0 nodes and a maximum of 50 nodes. The required size is dynamically adjusted depending on the CPU and memory requirements of the runtimes. If there are no resource demands, for example, if the runtime is not running, a compute pool scales down to 0 nodes after 600 seconds (10 minutes). ### Examples for calculating %ofsfspcs% consumption
You created an Openflow Snowflake Deployment and have not created any runtimes.
- The Openflow_Control_Pool_0 Compute Pool is running with one CPU_X64_S instance - Total Openflow consumption = 1 CPU_X64_S instance-hour
You created one small runtime with Min Nodes = 1 and Max Nodes = 2. Runtime stays at 1 node for 1 hour.
- The Openflow_Control_Pool_0 Compute Pool is running with 1 CPU_X64_S instance - The INTERNAL_OPENFLOW_0_SMALL Compute Pool is running with 1 CPU_X64_S instance - Total Openflow consumption = 2 CPU_X64_S instance-hours
You created two small runtimes with min/max of two nodes each, and one large runtime with min/max of 10 nodes. These Runtimes are active for one hour.
- The Openflow_Control_Pool_0 Compute Pool is running with 1 CPU_X64_S instance - Two small runtimes at two nodes = INTERNAL_OPENFLOW_0_SMALL Compute Pool is running with 2 CPU_X64_S instances = 2 CPU_X64_S instance-hours - One large runtime at 10 nodes = INTERNAL_OPENFLOW_0_LARGE Compute Pool is running with 4 CPU_X64_L instances = 4 CPU_X64_L instance-hours - Total Openflow consumption = 3 CPU_X64_S instance-hours + 4 CPU_X64_L instance-hours
You created one medium runtime with one node. After 20 minutes, it scales to two nodes. After 20 minutes, it scales back down to one node and runs for another 20 minutes.
- The Openflow_Control_Pool_0 Compute Pool is running with 1 CPU_X64_S instance - One medium runtime scaling up to two nodes = INTERNAL_OPENFLOW_0_MEDIUM Compute Pool is running with 1 CPU_X64_SL instance = 1 CPU_X64_SL instance-hour - Total Openflow consumption = 1 CPU_X64_S instance-hour + 1 CPU_X64_SL instance-hour
You created one medium runtime with two nodes, then suspended it after 30 minutes.
- The Openflow_Control_Pool_0 Compute Pool is running with 1 CPU_X64_S instance - One medium runtime at one node = INTERNAL_OPENFLOW_0_MEDIUM Compute Pool is running with 1 CPU_X64_SL instance - 30 minutes = 1/2 hour - Total Openflow consumption = 1 CPU_X64_S instance-hour + 1/2 CPU_X64_SL instance-hour
--- title: PackageFlowFile 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/packageflowfile.md section: Loading & Unloading Data --- # PackageFlowFile 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description This processor will package FlowFile attributes and content into an output FlowFile that can be exported from NiFi and imported back into NiFi, preserving the original attributes and content. ## Tags attributes, flowfile, flowfile-stream, flowfile-stream-v3, package ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## Use Cases Involving Other Components | Send FlowFile content and attributes from one NiFi instance to another NiFi instance. | | ------------------------------------------------------------------------------------- | | Export FlowFile content and attributes from NiFi to external storage and reimport. | ## See also - [org.apache.nifi.processors.standard.MergeContent](/user-guide/data-integration/openflow/processors/mergecontent) - [org.apache.nifi.processors.standard.UnpackContent](/user-guide/data-integration/openflow/processors/unpackcontent) --- title: PaginatedJsonQueryElasticsearch 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/paginatedjsonqueryelasticsearch.md section: Loading & Unloading Data --- # PaginatedJsonQueryElasticsearch 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-elasticsearch-restapi-nar ## Description A processor that allows the user to run a paginated query (with aggregations) written with the Elasticsearch JSON DSL. It will use the flowfile's content for the query unless the QUERY attribute is populated. Search After/Point in Time queries must include a valid "sort" field. ## Tags elasticsearch, elasticsearch7, elasticsearch8, elasticsearch9, json, page, query, read, scroll ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.elasticsearch.ConsumeElasticsearch](/user-guide/data-integration/openflow/processors/consumeelasticsearch) - [org.apache.nifi.processors.elasticsearch.JsonQueryElasticsearch](/user-guide/data-integration/openflow/processors/jsonqueryelasticsearch) - [org.apache.nifi.processors.elasticsearch.SearchElasticsearch](/user-guide/data-integration/openflow/processors/searchelasticsearch) --- title: ParquetIcebergWriter source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/parqueticebergwriter.md section: Loading & Unloading Data --- # ParquetIcebergWriter This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides record serialization for Apache Iceberg using Apache Parquet formatting ## Tags iceberg, openflow, parquet, record ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: ParseEvtx 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/parseevtx.md section: Loading & Unloading Data --- # ParseEvtx 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-evtx-nar ## Description Parses the contents of a Windows Event Log file (evtx) and writes the resulting XML to the FlowFile ## Tags event, evtx, file, logs, message, windows ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: ParseExcelCellReference 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/parseexcelcellreference.md section: Loading & Unloading Data --- # ParseExcelCellReference 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-office-nar ## Description Processor responsible for parsing Excel cell reference formula. ## Tags cell, excel, parse, spreadsheet, xls, xlsx ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: ParseSyslog 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/parsesyslog.md section: Loading & Unloading Data --- # ParseSyslog 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Attempts to parse the contents of a Syslog message in accordance to RFC5424 and RFC3164 formats and adds attributes to the FlowFile for each of the parts of the Syslog message. Note: Be mindful that RFC3164 is informational and a wide range of different implementations are present in the wild. If messages fail parsing, considering using RFC5424 or using a generic parsing processors such as ExtractGrok. ## Tags attributes, event, logs, message, syslog, system ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.standard.ListenSyslog](/user-guide/data-integration/openflow/processors/listensyslog) - [org.apache.nifi.processors.standard.PutSyslog](/user-guide/data-integration/openflow/processors/putsyslog) --- title: ParseSyslog5424 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/parsesyslog5424.md section: Loading & Unloading Data --- # ParseSyslog5424 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Attempts to parse the contents of a well formed Syslog message in accordance to RFC5424 format and adds attributes to the FlowFile for each of the parts of the Syslog message, including Structured Data. Structured Data will be written to attributes as one attribute per item id + parameter see https://tools.ietf.org/html/rfc5424.Note (https://tools.ietf.org/html/rfc5424.Note): ParseSyslog5424 follows the specification more closely than ParseSyslog. If your Syslog producer does not follow the spec closely, with regards to using '-' for missing header entries for example, those logs will fail with this parser, where they would not fail with ParseSyslog. ## Tags attributes, event, logs, message, syslog, syslog5424, system ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.standard.ListenSyslog](/user-guide/data-integration/openflow/processors/listensyslog) - [org.apache.nifi.processors.standard.ParseSyslog](/user-guide/data-integration/openflow/processors/parsesyslog) - [org.apache.nifi.processors.standard.PutSyslog](/user-guide/data-integration/openflow/processors/putsyslog) --- title: PartitionRecord 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/partitionrecord.md section: Loading & Unloading Data --- # PartitionRecord 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Splits, or partitions, record-oriented data based on the configured fields in the data. One or more properties must be added. The name of the property is the name of an attribute to add. The value of the property is a RecordPath to evaluate against each Record. Two records will go to the same outbound FlowFile only if they have the same value for each of the given RecordPaths. Because we know that all records in a given output FlowFile have the same value for the fields that are specified by the RecordPath, an attribute is added for each field. See Additional Details on the Usage page for more information and examples. ## Tags bin, group, organize, partition, record, recordpath, rpath, segment, split ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## Use cases | Separate records into separate FlowFiles so that all of the records in a FlowFile have the same value for a given field or set of fields. | | ----------------------------------------------------------------------------------------------------------------------------------------- | | Separate records based on whether or not they adhere to a specific criteria | ## See also - [org.apache.nifi.processors.standard.ConvertRecord](/user-guide/data-integration/openflow/processors/convertrecord) - [org.apache.nifi.processors.standard.QueryRecord](/user-guide/data-integration/openflow/processors/queryrecord) - [org.apache.nifi.processors.standard.SplitRecord](/user-guide/data-integration/openflow/processors/splitrecord) - [org.apache.nifi.processors.standard.UpdateRecord](/user-guide/data-integration/openflow/processors/updaterecord) --- title: PEMEncodedSSLContextProvider source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/pemencodedsslcontextprovider.md section: Loading & Unloading Data --- # PEMEncodedSSLContextProvider This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description SSLContext Provider configurable using PEM Private Key and Certificate files. Supports PKCS1 and PKCS8 encoding for Private Keys as well as X.509 encoding for Certificates. ## Tags Certificate, ECDSA, Ed25519, Key, PEM, PKCS1, PKCS8, RSA, SSL, TLS, X.509 ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: Performance tuning of the Openflow Connector for Amazon Kinesis Data Streams source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/kinesis/performance-tuning.md section: Loading & Unloading Data --- # Performance tuning of the %kinesis% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Openflow Connector for Amazon Kinesis Data Streams](/user-guide/data-integration/openflow/connectors/kinesis/about) - [Set up Openflow Connector for Amazon Kinesis Data Streams](/user-guide/data-integration/openflow/connectors/kinesis/setup) - [Maintain Openflow Connector for Amazon Kinesis Data Streams](/user-guide/data-integration/openflow/connectors/kinesis/maintenance) - [Troubleshooting the Openflow Connector for Amazon Kinesis Data Streams](/user-guide/data-integration/openflow/connectors/kinesis/troubleshoot) When configuring the Openflow Connector for Kinesis for optimal performance, consider the following key factors that impact ingestion throughput and latency. ## Flowfile size For optimal performance, flowfiles should be in the range 1-10 MB rather than containing individual small messages. Larger flowfiles reduce processing overhead and improve throughput by minimizing the number of individual file operations. Default settings should yield flowfiles in an acceptable size range. Small flowfiles are expected when throughput is low. If you observe small flowfiles with high throughput, contact [Snowflake Support](/user-guide/contacting-support) for assistance. ## Network and infrastructure ### Network latency Lower latency between Kinesis and Openflow improves overall performance. It's highly advised that your Kinesis stream and Openflow are located in the same cloud service provider (CSP) region. ### Node size recommendations The following table provides configuration recommendations based on expected workload characteristics. Throughput values are relative and depend heavily on the source system configuration, topic and stream sizes, data format, and other factors.
## Performance optimization best practices ### Tuning Max Records Per Request When the ConsumeKinesis processor uses the **SHARED_THROUGHPUT** consumer type, the **Max Records Per Request** property controls the maximum number of records that the processor retrieves from Kinesis in a single request. If ingestion throughput is low and you don't see an obvious bottleneck in Openflow, Snowflake, or the network, this value might be too low for your workload. For most workloads, start by setting **Max Records Per Request** so that each request retrieves about 1 MB of data. Estimate the value by dividing 1 MB by your average Kinesis record size. The following table shows example starting values for common average record sizes:
After changing the value, monitor consumer lag, throughput, and runtime resource usage. Increase the value gradually if Kinesis consumption remains the bottleneck. ### Adjusting processor concurrent tasks To optimize processor performance, you can adjust the number of concurrent tasks for both ConsumeKinesis and PublishSnowpipeStreaming processors. Concurrent tasks allow processors to run multiple threads simultaneously, improving throughput for high-volume scenarios. To adjust concurrent tasks for a processor, perform the following tasks: 1. Right-click on the processor in the Openflow canvas. 2. Select **Configure** from the context menu. 3. Navigate to the **Scheduling** tab. 4. In the **Concurrent tasks** field, enter the preferred number of concurrent tasks. 5. Select **Apply** to save the configuration. #### Recommended concurrent task settings
#### Important considerations - **Memory usage**: Each concurrent task consumes additional memory. Monitor JVM heap usage when increasing concurrent tasks. - **Start conservatively**: Begin with lower values and gradually increase while monitoring performance metrics. ## Troubleshoot common performance bottlenecks ### High consumer lag or Snowflake ingestion bottlenecks If Kinesis consumer lag is increasing or Snowflake ingestion is slow, then perform the following tasks: 1. Verify network connectivity and bandwidth between Openflow and Kinesis. 2. Observe if the queue in front of the PublishSnowpipeStreaming processor increases. 1. If yes, consider adding more concurrent tasks for the PublishSnowpipeStreaming processor in the range limitations provided in [Adjusting processor concurrent tasks](#adjusting-processor-concurrent-tasks). 2. If not, consider adding more concurrent tasks for the ConsumeKinesis processor in the range limitations provided in [Adjusting processor concurrent tasks](#adjusting-processor-concurrent-tasks). 3. Consider using a bigger node type. 4. Consider increasing the number of nodes for the runtime. This can be done by stopping the connectors in the runtime. Changing node min and max size numbers and starting the connectors again.. ### Memory pressure If experiencing memory-related issues: 1. Reduce the batch sizes to lower the memory footprint. This can be done by changing the File Fragment Size and File Fragment Count parameters in the PublishSnowpipeStreaming processor. 2. Reduce the number of concurrent tasks for the ConsumeKinesis processor. 3. Consider using a bigger node type. ### Network latency issues If experiencing high latency: 1. Verify network configuration between Openflow and external systems. 2. Consider deploying Openflow in the same region as your Kinesis stream. 3. If working with low throughput, consider lowering the Client Lag settings in the PublishSnowpipeStreaming processor and Max Uncommitted Time in the ConsumeKinesis processor. --- title: Performance Tuning of the Openflow Connector for Kafka source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/kafka/performance-tuning.md section: Loading & Unloading Data --- # Performance Tuning of the Openflow Connector for Kafka This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) This topic provides guidance for optimizing the performance of the [Snowflake Openflow Connector for Kafka](/user-guide/data-integration/openflow/connectors/kafka/about) to achieve optimal throughput and minimize latency when ingesting data into Snowflake. ## Performance considerations When configuring the Openflow Connector for Kafka for optimal performance, consider the following key factors that impact ingestion throughput and latency: ### Kafka configuration #### Partition count More partitions allow for higher parallelism but require careful coordination with consumer configuration. Excessive partitions can cause several issues: increased memory usage, slower leader elections during failures, and significant metadata management overhead on brokers. #### Compression Message compression can reduce network bandwidth but increases CPU overhead. ### Flowfile optimization #### Flowfile size For optimal performance, flowfiles should be in the range 1-10 MB rather than containing individual small messages. Larger flowfiles reduce processing overhead and improve throughput by minimizing the number of individual file operations. Default settings should yield flowfiles in an acceptable size range. Small flowfiles are expected when throughput is low. If you observe small flowfiles with high throughput, contact [Snowflake Support](/user-guide/contacting-support) for assistance. ### Network and infrastructure #### Network latency Lower latency between Kafka brokers and Openflow improves overall performance. Snowflake recommends deploying Kafka brokers and Openflow in the same CSP region. #### Node size recommendations The following table provides configuration recommendations based on expected workload characteristics:
### Performance optimization best practices #### Adjusting processor concurrent tasks To optimize processor performance, you can adjust the number of concurrent tasks for both [ConsumeKafka](/user-guide/data-integration/openflow/processors/consumekafka) and PublishSnowpipeStreaming processors. Concurrent tasks allow processors to run multiple threads simultaneously, improving throughput for high-volume scenarios. To adjust concurrent tasks for a processor, perform the following tasks: 1. Right-click on the processor in the Openflow canvas. 2. Select Configure from the context menu. 3. Navigate to the Scheduling tab. 4. In the Concurrent tasks field, enter the preferred number of concurrent tasks. 5. Select Apply to save the configuration. #### Recommended concurrent task settings The following table provides recommended concurrent task settings for different node sizes:
#### Important considerations
Memory usage
Each concurrent task consumes additional memory. Monitor JVM heap usage when increasing concurrent tasks.
Kafka partitions
For ConsumeKafka, the number of concurrent tasks multiplied by the number of runtime nodes should not exceed the number of total Kafka partitions from all topics.
Start conservatively
Begin with lower values and gradually increase while monitoring performance metrics.
#### Troubleshooting performance issues: Common performance bottlenecks ##### High consumer lag or Snowflake ingestion bottlenecks If Kafka consumer lag is increasing or Snowflake ingestion is slow, then perform the following tasks: 1. Verify network connectivity and bandwidth between Openflow and Kafka brokers. 2. Observe if the queue in front of the PublishSnowpipeStreaming processor increases. 1. If yes, consider adding more concurrent tasks for the PublishSnowpipeStreaming processor in the range limitations provided in [](#label-openflow-kafka-adjust-concurrent-tasks). 2. If not, consider adding more concurrent tasks for the ConsumeKafka processor in the range limitations provided in [](#label-openflow-kafka-adjust-concurrent-tasks). 3. Consider using a bigger node type. 4. Consider increasing the max number of nodes for the runtime. ##### Memory pressure If experiencing memory-related issues: 1. Reduce the batch sizes to lower the memory footprint. 2. Reduce the number of concurrent tasks for the ConsumeKafka processor. 3. Consider upgrading to a bigger node type. ##### Network latency issues If experiencing high latency: 1. Verify network configuration between Openflow and external systems. 2. Consider deploying Openflow closer to your Kafka cluster. 3. If working with low throughput, consider lowering the Client Lag settings in the PublishSnowpipeStreaming processor and Max Uncommitted Time in the ConsumeKafka processor. --- title: PerformSnowflakeCortexOCR 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/performsnowflakecortexocr.md section: Loading & Unloading Data --- # PerformSnowflakeCortexOCR 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-snowflake-processors-nar ## Description Performs Optical Character Recognition (OCR) on PDF documents using Snowflake Cortex ML functions. Documents must be staged in a Snowflake internal stage with server-side encryption enabled. The processor extracts text content from PDFs and can output the results either as FlowFile content or as an attribute. ## Tags ai, cortex, document, ml, ocr, openflow, pdf, snowflake ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [com.snowflake.openflow.runtime.processors.snowflake.PutSnowflakeInternalStageFile](/user-guide/data-integration/openflow/processors/putsnowflakeinternalstagefile) --- title: PickTablesForReplication 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/picktablesforreplication.md section: Loading & Unloading Data --- # PickTablesForReplication 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-database-cdc-processors-nar ## Description Accepts a list of fully qualified table names and determines if a table: - is new (is not replicated, but was added in the source) - is existing (is replicated and exists in the source) - is stale (is replicated but no longer exists in the source) Configuration is passed as a FlowFile attribute. Processor generates a separate FlowFile for each source table. ## Tags snowflake, state, table ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: PolarisIcebergCatalog source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/polarisicebergcatalog.md section: Loading & Unloading Data --- # PolarisIcebergCatalog This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides Apache Iceberg integration with Apache Polaris Catalog access over REST HTTP ## Tags catalog, iceberg, openflow, polaris ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: PromptAnthropicAI 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/promptanthropicai.md section: Loading & Unloading Data --- # PromptAnthropicAI 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-anthropic-nar ## Description Sends a prompt to Anthropic, writing the response either as a FlowFile attribute or to the contents of the incoming FlowFile. The prompt may consist of pure text interaction or may include an image. Use dynamic properties to enable beta features in the Anthropic endpoint. ## Tags ai, anthropic, chat, image, openflow, prompt, text ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: PromptAzureOpenAI 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/promptazureopenai.md section: Loading & Unloading Data --- # PromptAzureOpenAI 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-openai-nar ## Description Sends a prompt to Azure's OpenAI service, writing the response either as a FlowFile attribute or to the contents of the incoming FlowFile. The prompt may consist of pure text interaction or may include images. In the case of images, a URL may be provided, or the contents of the FlowFile may be used, depending on the provided configuration ## Tags ai, azure, chat, image, openai, openflow, prompt, text ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [com.snowflake.openflow.runtime.processors.openai.CreateAzureOpenAiEmbeddings](/user-guide/data-integration/openflow/processors/createazureopenaiembeddings) - [com.snowflake.openflow.runtime.processors.openai.PromptOpenAI](/user-guide/data-integration/openflow/processors/promptopenai) --- title: PromptLLM 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/promptllm.md section: Loading & Unloading Data --- # PromptLLM 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-llm-processors-nar ## Description This processor sends a user defined prompt to a Large Language Model (LLM) to respond. ## Tags ai, llm, openflow, prompt, text processing ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: PromptOpenAI 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/promptopenai.md section: Loading & Unloading Data --- # PromptOpenAI 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-openai-nar ## Description Sends a prompt to OpenAI, writing the response either as a FlowFile attribute or to the contents of the incoming FlowFile. The prompt may consist of pure text interaction or may include images. In the case of images, a URL may be provided, or the contents of the FlowFile may be used, depending on the provided configuration ## Tags ai, chat, image, openai, openflow, prompt, text ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [com.snowflake.openflow.runtime.processors.openai.CreateOpenAiEmbeddings](/user-guide/data-integration/openflow/processors/createopenaiembeddings) - [com.snowflake.openflow.runtime.processors.openai.PromptAzureOpenAI](/user-guide/data-integration/openflow/processors/promptazureopenai) --- title: PromptSnowflakeCortex 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/promptsnowflakecortex.md section: Loading & Unloading Data --- # PromptSnowflakeCortex 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-snowflake-processors-nar ## Description Sends a prompt to Snowflake Cortex, writing the response either as a FlowFile attribute or to the contents of the incoming FlowFile. The prompt may consist of pure text interaction only. ## Tags ai, chat, cortex, openflow, prompt, snowflake, text ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: PromptVertexAI 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/promptvertexai.md section: Loading & Unloading Data --- # PromptVertexAI 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-vertexai-nar ## Description Sends a prompt to VertexAI, writing the response either as a FlowFile attribute or to the contents of the incoming FlowFile. The prompt may consist of pure text interaction or may include multimedia. ## Tags ai, chat, cloud, gcp, google, image, openflow, pdf, prompt, text, video ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: PropertiesFileLookupService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/propertiesfilelookupservice.md section: Loading & Unloading Data --- # PropertiesFileLookupService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description A reloadable properties file-based lookup service ## Tags cache, enrich, join, key, lookup, properties, reloadable, value ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted ## Restrictions
## System Resource Considerations This component does not specify system resource considerations. --- title: ProtobufReader source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/protobufreader.md section: Loading & Unloading Data --- # ProtobufReader This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Parses a Protocol Buffers message from binary format. ## Tags parser, protobuf, reader, record ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: Publish Data from Snowflake to SAP® BDC Connect for Snowflake source: https://docs.snowflake.cn/en/user-guide/data-integration/zero-copy/sap-sql/publish-data.md section: Loading & Unloading Data --- # Publish data from Snowflake to %sapbdc% - [Set Up SAP® BDC Connect for Snowflake Zerocopy Connector](/user-guide/data-integration/zero-copy/sap-sql/setup) - [Explore Data Products from SAP® BDC Connect for Snowflake](/user-guide/data-integration/zero-copy/sap-sql/explore-data-products) - [SAP® BDC Connect for Snowflake Zerocopy Connector — Security and Privileges](/user-guide/data-integration/zero-copy/sap-sql/security) The [`manage-zerocopy-sapbdc`](/user-guide/cortex-code/bundled-skills#label-bundled-skill-manage-zerocopy-sapbdc) skill manages the end-to-end lifecycle of the SAP and Snowflake Zero-Copy Integration and connector: creating connectors, consuming data products from SAP® BDC, publishing Snowflake data to SAP® BDC, analyzing shared data, and troubleshooting issues, all through a conversational, step-by-step workflow. This skill is now bundled with Cortex Code (CoCo), and you can use it to automate the steps in this topic. This topic describes how to publish Snowflake data back to %sapbdc% by creating a share, granting access to databases, schemas, and tables, and associating the share with a Zerocopy Connector. The connector must be in `CONNECTED` state and have `SHARE_BACK` enabled before associating a share. See [Set Up SAP® BDC Connect for Snowflake Zerocopy Connector](/user-guide/data-integration/zero-copy/sap-sql/setup) for details. ## Enable share back Before publishing data to %sapbdc%, enable share back on the connector: ```sql ALTER ZEROCOPY CONNECTOR IF EXISTS my_db.my_schema.my_sap_connector SET SHARE_BACK = TRUE; ``` The role used to create the share must have the `CREATE SHARE` privilege on the account. For the full list of required privileges, see [SAP® BDC Connect for Snowflake Zerocopy Connector — Security and Privileges](/user-guide/data-integration/zero-copy/sap-sql/security). ## Grant access to Snowflake objects To publish Snowflake data to %sapbdc%, you first create a Snowflake share and grant access to the databases, schemas, and tables you want to publish. For more information about creating and managing shares, see [CREATE SHARE](/sql-reference/sql/create-share). - The tables must be Iceberg V3 tables. When you create a table, set `ICEBERG_VERSION = 3`, or set `ICEBERG_VERSION_DEFAULT = 3` at the database or schema level. For more information, see [](#label-iceberg-version) and [](#label-iceberg-version-default). - The tables must use Snowflake as the Iceberg catalog ([Snowflake-managed Iceberg tables](#label-tables-iceberg-snowflake-as-catalog)). When you create a table, set `CATALOG = 'SNOWFLAKE'`. For more information, see [CREATE ICEBERG TABLE (Snowflake as the Iceberg catalog)](/sql-reference/sql/create-iceberg-table-snowflake). - The tables must use Snowflake storage, which is the default when you use Snowflake as the catalog. For more information, see [Snowflake storage for Apache Iceberg™ tables](/user-guide/tables-iceberg-internal-storage). - The tables must have copy-on-write enabled. When you create a table, set `ICEBERG_MERGE_ON_READ_BEHAVIOR = 'DISABLED'`. For more information, see [](#label-tables-iceberg-row-level-deletes). - The tables must use a compatible storage serialization policy so that %sapbdc% can consume the published data. When you create a table, set `STORAGE_SERIALIZATION_POLICY = 'COMPATIBLE'`. For more information, see [](#label-storage-serialization-policy). - Each shared data product should map to a single dedicated database. For more information about direct shares, see [About Secure Data Sharing](/user-guide/data-sharing-intro). Alternatively, you can set these properties at the database or schema level so that all tables automatically inherit them. Snowflake recommends setting the required Iceberg configuration at the database level so that all tables in the database automatically inherit the correct settings. Use [CREATE DATABASE](/sql-reference/sql/create-database) for a new database or [ALTER DATABASE](/sql-reference/sql/alter-database) to update an existing one: ```sql -- New database CREATE DATABASE my_publish_db ICEBERG_VERSION_DEFAULT = 3 CATALOG = 'SNOWFLAKE' ICEBERG_MERGE_ON_READ_BEHAVIOR = 'DISABLED' STORAGE_SERIALIZATION_POLICY = 'COMPATIBLE'; -- Existing database ALTER DATABASE my_publish_db SET ICEBERG_VERSION_DEFAULT = 3 CATALOG = 'SNOWFLAKE' ICEBERG_MERGE_ON_READ_BEHAVIOR = 'DISABLED' STORAGE_SERIALIZATION_POLICY = 'COMPATIBLE'; ``` If you prefer to set these properties at the table level instead, specify them explicitly when creating each table: ```sql CREATE ICEBERG TABLE my_publish_db.my_schema.my_table ( id STRING PRIMARY KEY, name STRING, value NUMBER(38,0) ) ICEBERG_VERSION = 3 CATALOG = 'SNOWFLAKE' ICEBERG_MERGE_ON_READ_BEHAVIOR = 'DISABLED' STORAGE_SERIALIZATION_POLICY = 'COMPATIBLE'; ``` You must define a primary key on each Iceberg table that you publish to %sapbdc%. In the preceding example, `id` is the primary key. Mark the same column as the key (`"key": true`) in the CSN document when you publish the data product. ### Create a share To create a share, the role must have the `CREATE SHARE` privilege on the account. For the full list of required privileges, see [SAP® BDC Connect for Snowflake Zerocopy Connector — Security and Privileges](/user-guide/data-integration/zero-copy/sap-sql/security). Create a share using [CREATE SHARE](/sql-reference/sql/create-share): ```sql CREATE SHARE IF NOT EXISTS my_share; ``` ### Grant access to the share Grant `USAGE` on the database: ```sql GRANT USAGE ON DATABASE my_publish_db TO SHARE my_share; ``` Grant `USAGE` on the schema: ```sql GRANT USAGE ON SCHEMA my_publish_db.my_schema TO SHARE my_share; ``` Grant `SELECT` on a specific table: ```sql GRANT SELECT ON TABLE my_publish_db.my_schema.my_table TO SHARE my_share; ``` ### Associate the share with the connector After granting access, associate the share with the Zerocopy Connector: ```sql ALTER ZEROCOPY CONNECTOR my_db.my_schema.my_sap_connector ADD SHARE my_share; ``` To view the shares associated with a Zerocopy Connector, use `DESC ZEROCOPY CONNECTOR`: ```sql DESC ZEROCOPY CONNECTOR my_db.my_schema.my_sap_connector; ``` ## Revoke access To disassociate a share from the Zerocopy Connector: ```sql ALTER ZEROCOPY CONNECTOR my_db.my_schema.my_sap_connector REMOVE SHARE my_share; ``` To revoke access to a previously granted object from the share: ```sql REVOKE USAGE ON DATABASE my_publish_db FROM SHARE my_share; REVOKE USAGE ON SCHEMA my_publish_db.my_schema FROM SHARE my_share; REVOKE SELECT ON TABLE my_publish_db.my_schema.my_table FROM SHARE my_share; ``` ## Publish a data product to %sapbdc% After granting access to Snowflake objects, publish the data product to SAP® BDC by calling the `SYSTEM$SAP_PUBLISH_DATA_PRODUCT` function. This makes the data product discoverable and accessible from the SAP® BDC side. The `OPERATE` privilege on the connector is required to call `SYSTEM$SAP_PUBLISH_DATA_PRODUCT`. ```sql SELECT SYSTEM$SAP_PUBLISH_DATA_PRODUCT( '', '', '', '' ); ``` For example: ```sql SELECT SYSTEM$SAP_PUBLISH_DATA_PRODUCT( 'my_db.my_schema.my_sap_connector', 'my_share', '{ "title": "Airline Data Product", "shortDescription": "Airline dimension data from Snowflake.", "description": "Contains airline identifiers and attributes published from Snowflake to SAP BDC." }', '{ "csnInteropEffective": "1.0", "$version": "2.0", "i18n": {}, "meta": { "creator": "Snowflake CSN Interop Generator - Minimal", "flavor": "inferred" }, "definitions": { "MY_SCHEMA": { "kind": "context" }, "MY_SCHEMA.MY_TABLE": { "kind": "entity", "elements": { "ID": { "type": "cds.String", "key": true, "notNull": true }, "NAME": { "type": "cds.String" }, "VALUE": { "type": "cds.Decimal", "precision": 38, "scale": 0 } } } } }' ); ```
If the function fails to resolve `connector_name` or `snowflake_share_name`, verify that the names use the correct case. Snowflake identifiers are case-sensitive when quoted. For more information, see [Identifier requirements](/sql-reference/identifiers-syntax). --- title: PublishAMQP 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/publishamqp.md section: Loading & Unloading Data --- # PublishAMQP 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-amqp-nar ## Description Creates an AMQP Message from the contents of a FlowFile and sends the message to an AMQP Exchange. In a typical AMQP exchange model, the message that is sent to the AMQP Exchange will be routed based on the 'Routing Key' to its final destination in the queue (the binding). If due to some misconfiguration the binding between the Exchange, Routing Key and Queue is not set up, the message will have no final destination and will return (i.e., the data will not make it to the queue). If that happens you will see a log in both app-log and bulletin stating to that effect, and the FlowFile will be routed to the 'failure' relationship. ## Tags amqp, message, publish, put, rabbit, send ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: PublishChangeDataSnowpipeStreaming 2026.4.28.15 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/publishchangedatasnowpipestreaming.md section: Loading & Unloading Data --- # PublishChangeDataSnowpipeStreaming 2026.4.28.15 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-snowpipe-streaming-2-processors-nar ## Description Publishes change data records formatted as Newline Delimited JSON to Snowflake Database Pipes using Snowpipe Streaming High Availability. The processor supports **Concurrency Group** serialization so FlowFiles that share the same group are not processed against the channel concurrently. After data is transferred, the processor waits for the streaming channel to report committed offset tokens (according to **Offset Tracking Resolution** and **Offset Tracking Timeout**) before routing FlowFiles to **success**, **invalid**, or **failure**. It can run when the incoming connection has no FlowFiles so that pending batches finish polling. ## Tags CDC, Change Data Capture, NDJSON, Snowflake, Snowpipe Streaming ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: PublishGCPubSub 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/publishgcpubsub.md section: Loading & Unloading Data --- # PublishGCPubSub 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-gcp-nar ## Description Publishes the content of the incoming flowfile to the configured Google Cloud PubSub topic. The processor supports dynamic properties. If any dynamic properties are present, they will be sent along with the message in the form of 'attributes'. ## Tags gcp, google, google-cloud, message, publish, pubsub ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.gcp.pubsub.ConsumeGCPubSub](/user-guide/data-integration/openflow/processors/consumegcpubsub) --- title: PublishJMS 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/publishjms.md section: Loading & Unloading Data --- # PublishJMS 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-jms-processors-nar ## Description Creates a JMS Message from the contents of a FlowFile and sends it to a JMS Destination (queue or topic) as JMS BytesMessage or TextMessage. FlowFile attributes will be added as JMS headers and/or properties to the outgoing JMS message. ## Tags jms, message, publish, put, send ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Restrictions
## Relationships
## See also - [org.apache.nifi.jms.processors.ConsumeJMS](/user-guide/data-integration/openflow/processors/consumejms) --- title: PublishKafka 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/publishkafka.md section: Loading & Unloading Data --- # PublishKafka 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-kafka-nar ## Description Sends the contents of a FlowFile as either a message or as individual records to Apache Kafka using the Kafka Producer API. The messages to send may be individual FlowFiles, may be delimited using a user-specified delimiter (such as a new-line), or may be record-oriented data that can be read by the configured Record Reader. The complementary NiFi processor for fetching messages is ConsumeKafka. ## Tags apache, avro, csv, json, kafka, logs, message, openflow, pubsub, put, record, send ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [com.snowflake.openflow.runtime.processors.kafka.ConsumeKafka](/user-guide/data-integration/openflow/processors/consumekafka) --- title: PublishMQTT 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/publishmqtt.md section: Loading & Unloading Data --- # PublishMQTT 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-mqtt-nar ## Description Publishes a message to an MQTT topic ## Tags IOT, MQTT, publish ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [org.apache.nifi.processors.mqtt.ConsumeMQTT](/user-guide/data-integration/openflow/processors/consumemqtt) --- title: PublishSlack 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/publishslack.md section: Loading & Unloading Data --- # PublishSlack 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-slack-nar ## Description Posts a message to the specified Slack channel. The content of the message can be either a user-defined message that makes use of Expression Language or the contents of the FlowFile can be sent as the message. If sending a user-defined message, the contents of the FlowFile may also be optionally uploaded as a file attachment. ## Tags chat.postMessage, conversation, publish, send, slack, social media, team, text, unstructured, upload, write ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## Use cases | Send specific text as a message to Slack, optionally including the FlowFile's contents as an attached file. | | ----------------------------------------------------------------------------------------------------------- | | Send the contents of the FlowFile as a message to Slack. | ## Use Cases Involving Other Components | Respond to a Slack message in a thread. | | --------------------------------------- | ## See also - [org.apache.nifi.processors.slack.ConsumeSlack](/user-guide/data-integration/openflow/processors/consumeslack) - [org.apache.nifi.processors.slack.ListenSlack](/user-guide/data-integration/openflow/processors/listenslack) --- title: PublishSnowpipeStreaming 2026.4.28.15 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/publishsnowpipestreaming.md section: Loading & Unloading Data --- # PublishSnowpipeStreaming 2026.4.28.15 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-snowpipe-streaming-2-processors-nar ## Description Publishes records formatted as Newline Delimited JSON to Snowflake Database Pipes using Snowpipe Streaming High Availability. After data is transferred, the processor waits for the streaming channel to report committed offset tokens (according to **Offset Tracking Resolution** and **Offset Tracking Timeout**) before routing FlowFiles to **success**, **invalid**, or **failure**. It can run when the incoming connection has no FlowFiles so that pending batches finish polling. ## Tags NDJSON, Snowflake, Snowpipe Streaming ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: PutAzureBlobStorage_v12 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putazureblobstorage_v12.md section: Loading & Unloading Data --- # PutAzureBlobStorage_v12 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-azure-nar ## Description Puts content into a blob on Azure Blob Storage. The processor uses Azure Blob Storage client library v12. ## Tags azure, blob, cloud, microsoft, storage ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.azure.storage.CopyAzureBlobStorage_v12](/user-guide/data-integration/openflow/processors/copyazureblobstorage_v12) - [org.apache.nifi.processors.azure.storage.DeleteAzureBlobStorage_v12](/user-guide/data-integration/openflow/processors/deleteazureblobstorage_v12) - [org.apache.nifi.processors.azure.storage.FetchAzureBlobStorage_v12](/user-guide/data-integration/openflow/processors/fetchazureblobstorage_v12) - [org.apache.nifi.processors.azure.storage.ListAzureBlobStorage_v12](/user-guide/data-integration/openflow/processors/listazureblobstorage_v12) --- title: PutAzureCosmosDBRecord 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putazurecosmosdbrecord.md section: Loading & Unloading Data --- # PutAzureCosmosDBRecord 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-azure-nar ## Description This processor is a record-aware processor for inserting data into Cosmos DB with Core SQL API. It uses a configured record reader and schema to read an incoming record set from the body of a Flowfile and then inserts those records into a configured Cosmos DB Container. ## Tags azure, cosmos, insert, put, record ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: PutAzureDataExplorer 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putazuredataexplorer.md section: Loading & Unloading Data --- # PutAzureDataExplorer 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-azure-nar ## Description Acts as an Azure Data Explorer sink which sends FlowFiles to the provided endpoint. Data can be sent through queued ingestion or streaming ingestion to the Azure Data Explorer cluster. ## Tags ADX, Azure, Data, Explorer, Kusto ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: PutAzureDataLakeStorage 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putazuredatalakestorage.md section: Loading & Unloading Data --- # PutAzureDataLakeStorage 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-azure-nar ## Description Writes the contents of a FlowFile as a file on Azure Data Lake Storage Gen 2 ## Tags adlsgen2, azure, cloud, datalake, microsoft, storage ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.azure.storage.DeleteAzureDataLakeStorage](/user-guide/data-integration/openflow/processors/deleteazuredatalakestorage) - [org.apache.nifi.processors.azure.storage.FetchAzureDataLakeStorage](/user-guide/data-integration/openflow/processors/fetchazuredatalakestorage) - [org.apache.nifi.processors.azure.storage.ListAzureDataLakeStorage](/user-guide/data-integration/openflow/processors/listazuredatalakestorage) --- title: PutAzureEventHub 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putazureeventhub.md section: Loading & Unloading Data --- # PutAzureEventHub 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-azure-nar ## Description Send FlowFile contents to Azure Event Hubs ## Tags azure, cloud, eventhub, events, microsoft, streaming, streams ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: PutAzureQueueStorage_v12 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putazurequeuestorage_v12.md section: Loading & Unloading Data --- # PutAzureQueueStorage_v12 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-azure-nar ## Description Writes the content of the incoming FlowFiles to the configured Azure Queue Storage. ## Tags azure, cloud, enqueue, microsoft, queue, storage ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [org.apache.nifi.processors.azure.storage.queue.GetAzureQueueStorage_v12](/user-guide/data-integration/openflow/processors/getazurequeuestorage_v12) --- title: PutBigQuery 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putbigquery.md section: Loading & Unloading Data --- # PutBigQuery 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-gcp-nar ## Description Writes the contents of a FlowFile to a Google BigQuery table. The processor is record based so the schema that is used is driven by the RecordReader. Attributes that are not matched to the target schema are skipped. Exactly once delivery semantics are achieved via stream offsets. ## Tags bigquery, bq, google, google cloud ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: PutBoxFile 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putboxfile.md section: Loading & Unloading Data --- # PutBoxFile 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-box-nar ## Description Puts content to a Box folder. ## Tags box, put, storage ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.box.FetchBoxFile](/user-guide/data-integration/openflow/processors/fetchboxfile) - [org.apache.nifi.processors.box.ListBoxFile](/user-guide/data-integration/openflow/processors/listboxfile) --- title: PutCloudWatchMetric 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putcloudwatchmetric.md section: Loading & Unloading Data --- # PutCloudWatchMetric 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-aws-nar ## Description Publishes metrics to Amazon CloudWatch. Metric can be either a single value, or a StatisticSet comprised of minimum, maximum, sum and sample count. ## Tags amazon, aws, cloudwatch, metrics, publish, put ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: PutDatabaseRecord 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putdatabaserecord.md section: Loading & Unloading Data --- # PutDatabaseRecord 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description The PutDatabaseRecord processor uses a specified RecordReader to input (possibly multiple) records from an incoming flow file. These records are translated to SQL statements and executed as a single transaction. If any errors occur, the flow file is routed to failure or retry, and if the records are transmitted successfully, the incoming flow file is routed to success. The type of statement executed by the processor is specified via the Statement Type property, which accepts some hard-coded values such as INSERT, UPDATE, and DELETE, as well as 'Use statement.type Attribute', which causes the processor to get the statement type from a flow file attribute. IMPORTANT: If the Statement Type is UPDATE, then the incoming records must not alter the value(s) of the primary keys (or user-specified Update Keys). If such records are encountered, the UPDATE statement issued to the database may do nothing (if no existing records with the new primary key values are found), or could inadvertently corrupt the existing data (by changing records for which the new values of the primary keys exist). ## Tags database, delete, insert, jdbc, put, record, sql, update ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## Use cases | Insert records into a database | | ------------------------------ | --- title: PutDatabricksSQL 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putdatabrickssql.md section: Loading & Unloading Data --- # PutDatabricksSQL 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-databricks-processors-nar ## Description Submit a SQL Execution using Databricks REST API then write the JSON response to FlowFile Content. For high performance SELECT or INSERT queries use ExecuteSQL instead. ## Tags databricks, openflow, sql ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: PutDBFSFile 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putdbfsfile.md section: Loading & Unloading Data --- # PutDBFSFile 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-databricks-processors-nar ## Description Write FlowFile content to DBFS. ## Tags databricks, dbfs, openflow ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: PutDistributedMapCache 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putdistributedmapcache.md section: Loading & Unloading Data --- # PutDistributedMapCache 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Gets the content of a FlowFile and puts it to a distributed map cache, using a cache key computed from FlowFile attributes. If the cache already contains the entry and the cache update strategy is 'keep original' the entry is not replaced.' ## Tags cache, distributed, map, put ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.standard.FetchDistributedMapCache](/user-guide/data-integration/openflow/processors/fetchdistributedmapcache) --- title: PutDropbox 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putdropbox.md section: Loading & Unloading Data --- # PutDropbox 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-dropbox-processors-nar ## Description Puts content to a Dropbox folder. ## Tags dropbox, put, storage ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.dropbox.FetchDropbox](/user-guide/data-integration/openflow/processors/fetchdropbox) - [org.apache.nifi.processors.dropbox.ListDropbox](/user-guide/data-integration/openflow/processors/listdropbox) --- title: PutDynamoDB 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putdynamodb.md section: Loading & Unloading Data --- # PutDynamoDB 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-aws-nar ## Description Puts a document from DynamoDB based on hash and range key. The table can have either hash and range or hash key alone. Currently the keys supported are string and number and value can be json document. In case of hash and range keys both key are required for the operation. The FlowFile content must be JSON. FlowFile content is mapped to the specified Json Document attribute in the DynamoDB item. ## Tags AWS, Amazon, DynamoDB, Insert, Put ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.aws.dynamodb.DeleteDynamoDB](/user-guide/data-integration/openflow/processors/deletedynamodb) - [org.apache.nifi.processors.aws.dynamodb.GetDynamoDB](/user-guide/data-integration/openflow/processors/getdynamodb) - [org.apache.nifi.processors.aws.dynamodb.PutDynamoDBRecord](/user-guide/data-integration/openflow/processors/putdynamodbrecord) --- title: PutDynamoDBRecord 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putdynamodbrecord.md section: Loading & Unloading Data --- # PutDynamoDBRecord 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-aws-nar ## Description Inserts items into DynamoDB based on record-oriented data. The record fields are mapped into DynamoDB item fields, including partition and sort keys if set. Depending on the number of records the processor might execute the insert in multiple chunks in order to overcome DynamoDB's limitation on batch writing. This might result partially processed FlowFiles in which case the FlowFile will be transferred to the "unprocessed" relationship with the necessary attribute to retry later without duplicating the already executed inserts. ## Tags AWS, Amazon, DynamoDB, Insert, Put, Record ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.aws.dynamodb.DeleteDynamoDB](/user-guide/data-integration/openflow/processors/deletedynamodb) - [org.apache.nifi.processors.aws.dynamodb.GetDynamoDB](/user-guide/data-integration/openflow/processors/getdynamodb) - [org.apache.nifi.processors.aws.dynamodb.PutDynamoDB](/user-guide/data-integration/openflow/processors/putdynamodb) --- title: PutElasticsearchJson 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putelasticsearchjson.md section: Loading & Unloading Data --- # PutElasticsearchJson 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-elasticsearch-restapi-nar ## Description An Elasticsearch put processor that uses the official Elastic REST client libraries. Each FlowFile is treated as a document to be sent to the Elasticsearch _bulk API. Multiple FlowFiles can be batched together into each Request sent to Elasticsearch. ## Tags elasticsearch, elasticsearch7, elasticsearch8, elasticsearch9, index, json, put ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.elasticsearch.PutElasticsearchRecord](/user-guide/data-integration/openflow/processors/putelasticsearchrecord) --- title: PutElasticsearchRecord 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putelasticsearchrecord.md section: Loading & Unloading Data --- # PutElasticsearchRecord 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-elasticsearch-restapi-nar ## Description A record-aware Elasticsearch put processor that uses the official Elastic REST client libraries. Each Record within the FlowFile is converted into a document to be sent to the Elasticsearch _bulk APi. Multiple documents can be batched into each Request sent to Elasticsearch. Each document's Bulk operation can be configured using Record Path expressions. ## Tags elasticsearch, elasticsearch7, elasticsearch8, elasticsearch9, index, json, put, record ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.elasticsearch.PutElasticsearchJson](/user-guide/data-integration/openflow/processors/putelasticsearchjson) --- title: PutEmail 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putemail.md section: Loading & Unloading Data --- # PutEmail 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Sends an e-mail to configured recipients for each incoming FlowFile ## Tags email, notify, put, smtp ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties true ## Properties
## Relationships
--- title: PutFile 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putfile.md section: Loading & Unloading Data --- # PutFile 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Writes the contents of a FlowFile to the local file system ## Tags archive, copy, files, filesystem, local, put ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Restrictions
## Relationships
## See also - [org.apache.nifi.processors.standard.FetchFile](/user-guide/data-integration/openflow/processors/fetchfile) - [org.apache.nifi.processors.standard.GetFile](/user-guide/data-integration/openflow/processors/getfile) --- title: PutFTP 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putftp.md section: Loading & Unloading Data --- # PutFTP 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Sends FlowFiles to an FTP Server ## Tags archive, copy, egress, files, ftp, put, remote ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [org.apache.nifi.processors.standard.GetFTP](/user-guide/data-integration/openflow/processors/getftp) --- title: PutGCSObject 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putgcsobject.md section: Loading & Unloading Data --- # PutGCSObject 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-gcp-nar ## Description Writes the contents of a FlowFile as an object in a Google Cloud Storage. ## Tags archive, gcs, google, google cloud, put ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.gcp.storage.DeleteGCSObject](/user-guide/data-integration/openflow/processors/deletegcsobject) - [org.apache.nifi.processors.gcp.storage.FetchGCSObject](/user-guide/data-integration/openflow/processors/fetchgcsobject) - [org.apache.nifi.processors.gcp.storage.ListGCSBucket](/user-guide/data-integration/openflow/processors/listgcsbucket) --- title: PutGoogleDrive 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putgoogledrive.md section: Loading & Unloading Data --- # PutGoogleDrive 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-gcp-nar ## Description Writes the contents of a FlowFile as a file in Google Drive. ## Tags drive, google, put, storage ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.gcp.drive.FetchGoogleDrive](/user-guide/data-integration/openflow/processors/fetchgoogledrive) - [org.apache.nifi.processors.gcp.drive.ListGoogleDrive](/user-guide/data-integration/openflow/processors/listgoogledrive) --- title: PutGridFS 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putgridfs.md section: Loading & Unloading Data --- # PutGridFS 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-mongodb-nar ## Description Writes a file to a GridFS bucket. ## Tags file, gridfs, mongo, put, store ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: PutHubSpot 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/puthubspot.md section: Loading & Unloading Data --- # PutHubSpot 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-hubspot-processors-nar ## Description Upsert a HubSpot object. ## Tags Preview, hubspot ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [com.snowflake.openflow.runtime.processors.hubspot.GetHubSpotObject](/user-guide/data-integration/openflow/processors/gethubspotobject) - [com.snowflake.openflow.runtime.processors.hubspot.GetHubSpotSchema](/user-guide/data-integration/openflow/processors/gethubspotschema) - [com.snowflake.openflow.runtime.processors.hubspot.ListArchivedHubSpotData](/user-guide/data-integration/openflow/processors/listarchivedhubspotdata) - [com.snowflake.openflow.runtime.processors.hubspot.ListHubSpotObjects](/user-guide/data-integration/openflow/processors/listhubspotobjects) --- title: PutIcebergTable 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/puticebergtable.md section: Loading & Unloading Data --- # PutIcebergTable 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-iceberg-processors-nar ## Description Store records in Iceberg using configurable Catalog for managing namespaces and tables. ## Tags analytics, iceberg, openflow, parquet, polaris, s3 ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: PutKinesisFirehose 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putkinesisfirehose.md section: Loading & Unloading Data --- # PutKinesisFirehose 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-aws-nar ## Description Sends the contents to a specified Amazon Kinesis Firehose. In order to send data to firehose, the firehose delivery stream name has to be specified. ## Tags amazon, aws, firehose, kinesis, put, stream ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: PutKinesisStream 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putkinesisstream.md section: Loading & Unloading Data --- # PutKinesisStream 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-aws-nar ## Description Sends the contents to a specified Amazon Kinesis. In order to send data to Kinesis, the stream name has to be specified. ## Tags amazon, aws, kinesis, put, stream ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.aws.kinesis.stream.ConsumeKinesisStream](/user-guide/data-integration/openflow/processors/consumekinesisstream) --- title: PutLambda 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putlambda.md section: Loading & Unloading Data --- # PutLambda 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-aws-nar ## Description Sends the contents to a specified Amazon Lambda Function. The AWS credentials used for authentication must have permissions execute the Lambda function (lambda:InvokeFunction).The FlowFile content must be JSON. ## Tags amazon, aws, lambda, put ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: PutMongo 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putmongo.md section: Loading & Unloading Data --- # PutMongo 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-mongodb-nar ## Description Writes the contents of a FlowFile to MongoDB ## Tags insert, mongodb, put, update, write ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: PutMongoBulkOperations 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putmongobulkoperations.md section: Loading & Unloading Data --- # PutMongoBulkOperations 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-mongodb-nar ## Description Writes the contents of a FlowFile to MongoDB as bulk-update ## Tags bulk, insert, mongodb, put, update, write ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: PutMongoRecord 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putmongorecord.md section: Loading & Unloading Data --- # PutMongoRecord 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-mongodb-nar ## Description This processor is a record-aware processor for inserting/upserting data into MongoDB. It uses a configured record reader and schema to read an incoming record set from the body of a flowfile and then inserts/upserts batches of those records into a configured MongoDB collection. This processor does not support deletes. The number of documents to insert/upsert at a time is controlled by the "Batch Size" configuration property. This value should be set to a reasonable size to ensure that MongoDB is not overloaded with too many operations at once. ## Tags insert, mongodb, put, record, update, upsert ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: PutRecord 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putrecord.md section: Loading & Unloading Data --- # PutRecord 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description The PutRecord processor uses a specified RecordReader to input (possibly multiple) records from an incoming flow file, and sends them to a destination specified by a Record Destination Service (i.e. record sink). ## Tags put, record, sink ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: PutRedisHashRecord 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putredishashrecord.md section: Loading & Unloading Data --- # PutRedisHashRecord 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-redis-nar ## Description Puts record field data into Redis using a specified hash value, which is determined by a RecordPath to a field in each record containing the hash value. The record fields and values are stored as key/value pairs associated by the hash value. NOTE: Neither the evaluated hash value nor any of the field values can be null. If the hash value is null, the FlowFile will be routed to failure. For each of the field values, if the value is null that field will be not set in Redis. ## Tags hash, put, record, redis ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: PutS3Object 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/puts3object.md section: Loading & Unloading Data --- # PutS3Object 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-aws-nar ## Description Writes the contents of a FlowFile as an S3 Object to an Amazon S3 Bucket. ## Tags AWS, Amazon, Archive, Put, S3 ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.aws.s3.CopyS3Object](/user-guide/data-integration/openflow/processors/copys3object) - [org.apache.nifi.processors.aws.s3.DeleteS3Object](/user-guide/data-integration/openflow/processors/deletes3object) - [org.apache.nifi.processors.aws.s3.FetchS3Object](/user-guide/data-integration/openflow/processors/fetchs3object) - [org.apache.nifi.processors.aws.s3.GetS3ObjectMetadata](/user-guide/data-integration/openflow/processors/gets3objectmetadata) - [org.apache.nifi.processors.aws.s3.GetS3ObjectTags](/user-guide/data-integration/openflow/processors/gets3objecttags) - [org.apache.nifi.processors.aws.s3.ListS3](/user-guide/data-integration/openflow/processors/lists3) - [org.apache.nifi.processors.aws.s3.TagS3Object](/user-guide/data-integration/openflow/processors/tags3object) --- title: PutSalesforceObject 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putsalesforceobject.md section: Loading & Unloading Data --- # PutSalesforceObject 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-salesforce-nar ## Description Creates new records for the specified Salesforce sObject. The type of the Salesforce object must be set in the input flowfile 's' objectType' attribute. This processor cannot update existing records. ## Tags put, salesforce, sobject ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.salesforce.QuerySalesforceObject](/user-guide/data-integration/openflow/processors/querysalesforceobject) --- title: PutSFTP 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putsftp.md section: Loading & Unloading Data --- # PutSFTP 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Sends FlowFiles to an SFTP Server ## Tags archive, copy, egress, files, put, remote, sftp ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [org.apache.nifi.processors.standard.GetSFTP](/user-guide/data-integration/openflow/processors/getsftp) --- title: PutSmbFile 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putsmbfile.md section: Loading & Unloading Data --- # PutSmbFile 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-smb-nar ## Description Writes the contents of a FlowFile to a samba network location. Use this processor instead of a cifs mounts if share access control is important. Configure the Hostname, Share and Directory accordingly: \[Hostname][Share][pathtoDirectory] ## Tags samba, smb, cifs, files, put ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [org.apache.nifi.processors.smb.FetchSmb](/user-guide/data-integration/openflow/processors/fetchsmb) - [org.apache.nifi.processors.smb.GetSmbFile](/user-guide/data-integration/openflow/processors/getsmbfile) - [org.apache.nifi.processors.smb.ListSmb](/user-guide/data-integration/openflow/processors/listsmb) --- title: PutSnowflakeInternalStageFile 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putsnowflakeinternalstagefile.md section: Loading & Unloading Data --- # PutSnowflakeInternalStageFile 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-snowflake-processors-nar ## Description Puts files into a Snowflake internal stage. The internal stage must be created in the Snowflake account beforehand. ## Tags connection, database, jdbc, openflow, snowflake, snowpipe ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: PutSnowpipeStreaming 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putsnowpipestreaming.md section: Loading & Unloading Data --- # PutSnowpipeStreaming 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-snowpipe-processors-nar ## Description Streams records into a Snowflake table. The table must be created in the Snowflake account beforehand. ## Tags connection, database, jdbc, openflow, snowflake, snowpipe streaming ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Use cases | Write record-oriented data to a Snowflake table as fast as possible, accepting the possible of occasional duplicates. | | --------------------------------------------------------------------------------------------------------------------- | --- title: PutSNS 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putsns.md section: Loading & Unloading Data --- # PutSNS 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-aws-nar ## Description Sends the content of a FlowFile as a notification to the Amazon Simple Notification Service ## Tags amazon, aws, publish, pubsub, put, sns, topic ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [org.apache.nifi.processors.aws.sqs.GetSQS](/user-guide/data-integration/openflow/processors/getsqs) - [org.apache.nifi.processors.aws.sqs.PutSQS](/user-guide/data-integration/openflow/processors/putsqs) --- title: PutSplunk 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putsplunk.md section: Loading & Unloading Data --- # PutSplunk 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-splunk-nar ## Description Sends logs to Splunk Enterprise over TCP, TCP + TLS/SSL, or UDP. If a Message Delimiter is provided, then this processor will read messages from the incoming FlowFile based on the delimiter, and send each message to Splunk. If a Message Delimiter is not provided then the content of the FlowFile will be sent directly to Splunk as if it were a single message. ## Tags logs, splunk, tcp, udp ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: PutSplunkHTTP 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putsplunkhttp.md section: Loading & Unloading Data --- # PutSplunkHTTP 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-splunk-nar ## Description Sends flow file content to the specified Splunk server over HTTP or HTTPS. Supports HEC Index Acknowledgement. ## Tags http, logs, splunk ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.splunk.QuerySplunkIndexingStatus](/user-guide/data-integration/openflow/processors/querysplunkindexingstatus) --- title: PutSQL 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putsql.md section: Loading & Unloading Data --- # PutSQL 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Executes a SQL UPDATE or INSERT command. The content of an incoming FlowFile is expected to be the SQL command to execute. The SQL command may use the ? to escape parameters. In this case, the parameters to use must exist as FlowFile attributes with the naming convention sql.args. N.type and sql.args. N.value, where N is a positive integer. The sql.args. N.type is expected to be a number indicating the JDBC Type. The content of the FlowFile is expected to be in UTF-8 format. ## Tags database, insert, put, rdbms, relational, sql, update ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: PutSQS 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putsqs.md section: Loading & Unloading Data --- # PutSQS 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-aws-nar ## Description Publishes a message to an Amazon Simple Queuing Service Queue ## Tags AWS, Amazon, Publish, Put, Queue, SQS ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [org.apache.nifi.processors.aws.sqs.DeleteSQS](/user-guide/data-integration/openflow/processors/deletesqs) - [org.apache.nifi.processors.aws.sqs.GetSQS](/user-guide/data-integration/openflow/processors/getsqs) --- title: PutSyslog 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putsyslog.md section: Loading & Unloading Data --- # PutSyslog 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Sends Syslog messages to a given host and port over TCP or UDP. Messages are constructed from the "Message ___" properties of the processor which can use expression language to generate messages from incoming FlowFiles. The properties are used to construct messages of the form: (<PRIORITY>)(VERSION )(TIMESTAMP) (HOSTNAME) (BODY) where version is optional. The constructed messages are checked against regular expressions for RFC5424 and RFC3164 formatted messages. The timestamp can be an RFC5424 timestamp with a format of "yyyy-MM-dd 'T'HH:mm:ss. S 'Z'" or "yyyy-MM-dd 'T'HH:mm:ss. S+hh:mm", or it can be an RFC3164 timestamp with a format of "MMM d HH:mm:ss". If a message is constructed that does not form a valid Syslog message according to the above description, then it is routed to the invalid relationship. Valid messages are sent to the Syslog server and successes are routed to the success relationship, failures routed to the failure relationship. ## Tags logs, put, syslog, tcp, udp ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [org.apache.nifi.processors.standard.ListenSyslog](/user-guide/data-integration/openflow/processors/listensyslog) - [org.apache.nifi.processors.standard.ParseSyslog](/user-guide/data-integration/openflow/processors/parsesyslog) --- title: PutTCP 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/puttcp.md section: Loading & Unloading Data --- # PutTCP 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Sends serialized FlowFiles or Records over TCP to a configurable destination with optional support for TLS ## Tags egress, put, remote, tcp ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.standard.ListenTCP](/user-guide/data-integration/openflow/processors/listentcp) - [org.apache.nifi.processors.standard.PutUDP](/user-guide/data-integration/openflow/processors/putudp) --- title: PutUDP 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putudp.md section: Loading & Unloading Data --- # PutUDP 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description The PutUDP processor receives a FlowFile and packages the FlowFile content into a single UDP datagram packet which is then transmitted to the configured UDP server. The user must ensure that the FlowFile content being fed to this processor is not larger than the maximum size for the underlying UDP transport. The maximum transport size will vary based on the platform setup but is generally just under 64KB. FlowFiles will be marked as failed if their content is larger than the maximum transport size. ## Tags egress, put, remote, udp ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [org.apache.nifi.processors.standard.ListenUDP](/user-guide/data-integration/openflow/processors/listenudp) - [org.apache.nifi.processors.standard.PutTCP](/user-guide/data-integration/openflow/processors/puttcp) --- title: PutUnityCatalogFile 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putunitycatalogfile.md section: Loading & Unloading Data --- # PutUnityCatalogFile 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-databricks-processors-nar ## Description Write FlowFile content with max size of 5 GiB to Unity Catalog. ## Tags databricks, openflow, unity catalog ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: PutVectaraDocument 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putvectaradocument.md section: Loading & Unloading Data --- # PutVectaraDocument 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-vectara-processors-nar ## Description Generate and upload a JSON document to Vectara's upload endpoint. The input text can be JSON Object, JSON Array, or JSONL format. ## Tags ai, llm, openflow, rag, vectara ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Use Cases Involving Other Components | Publish a PDF file to a Vectara corpus. | | --------------------------------------- | ## See also - [com.snowflake.openflow.runtime.processors.vectara.PutVectaraFile](/user-guide/data-integration/openflow/processors/putvectarafile) --- title: PutVectaraFile 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putvectarafile.md section: Loading & Unloading Data --- # PutVectaraFile 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-vectara-processors-nar ## Description Upload a FlowFile content to Vectara's index endpoint. Document filter attributes and metadata attributes can be set by referencing FlowFile attributes. ## Tags ai, llm, openflow, rag, vectara ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [com.snowflake.openflow.runtime.processors.vectara.PutVectaraDocument](/user-guide/data-integration/openflow/processors/putvectaradocument) --- title: PutWebSocket 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putwebsocket.md section: Loading & Unloading Data --- # PutWebSocket 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-websocket-processors-nar ## Description Sends messages to a WebSocket remote endpoint using a WebSocket session that is established by either ListenWebSocket or ConnectWebSocket. ## Tags WebSocket, publish, send ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: PutZendeskTicket 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/putzendeskticket.md section: Loading & Unloading Data --- # PutZendeskTicket 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-zendesk-nar ## Description Create Zendesk tickets using the Zendesk API. ## Tags zendesk, ticket ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: QueryAzureDataExplorer 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/queryazuredataexplorer.md section: Loading & Unloading Data --- # QueryAzureDataExplorer 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-azure-nar ## Description Query Azure Data Explorer and stream JSON results to output FlowFiles ## Tags ADX, Azure, Data, Explorer, Kusto ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: QueryDatabaseTable 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/querydatabasetable.md section: Loading & Unloading Data --- # QueryDatabaseTable 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Generates a SQL select query, or uses a provided statement, and executes it to fetch all rows whose values in the specified Maximum Value column(s) are larger than the previously-seen maxima. Query result will be converted to Avro format. Expression Language is supported for several properties, but no incoming connections are permitted. The Environment/System properties may be used to provide values for any property containing Expression Language. If it is desired to leverage flow file attributes to perform these queries, the GenerateTableFetch and/or ExecuteSQL processors can be used for this purpose. Streaming is used so arbitrarily large result sets are supported. This processor can be scheduled to run on a timer or cron expression, using the standard scheduling methods. This processor is intended to be run on the Primary Node only. FlowFile attribute 'querydbtable.row.count' indicates how many rows were selected. ## Tags database, jdbc, query, select, sql ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.standard.ExecuteSQL](/user-guide/data-integration/openflow/processors/executesql) - [org.apache.nifi.processors.standard.GenerateTableFetch](/user-guide/data-integration/openflow/processors/generatetablefetch) --- title: QueryDatabaseTableRecord 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/querydatabasetablerecord.md section: Loading & Unloading Data --- # QueryDatabaseTableRecord 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Generates a SQL select query, or uses a provided statement, and executes it to fetch all rows whose values in the specified Maximum Value column(s) are larger than the previously-seen maxima. Query result will be converted to the format specified by the record writer. Expression Language is supported for several properties, but no incoming connections are permitted. The Environment/System properties may be used to provide values for any property containing Expression Language. If it is desired to leverage flow file attributes to perform these queries, the GenerateTableFetch and/or ExecuteSQL processors can be used for this purpose. Streaming is used so arbitrarily large result sets are supported. This processor can be scheduled to run on a timer or cron expression, using the standard scheduling methods. This processor is intended to be run on the Primary Node only. FlowFile attribute 'querydbtable.row.count' indicates how many rows were selected. ## Tags database, jdbc, query, record, select, sql ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
## Use cases | Retrieve all rows from a database table. | | -------------------------------------------------------------------------------------------------------------- | | Perform an incremental load of a single database table, fetching only new rows as they are added to the table. | ## Use Cases Involving Other Components | Perform an incremental load of multiple database tables, fetching only new rows as they are added to the tables. | | ---------------------------------------------------------------------------------------------------------------- | ## See also - [org.apache.nifi.processors.standard.ExecuteSQL](/user-guide/data-integration/openflow/processors/executesql) - [org.apache.nifi.processors.standard.GenerateTableFetch](/user-guide/data-integration/openflow/processors/generatetablefetch) --- title: QueryMilvus 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/querymilvus.md section: Loading & Unloading Data --- # QueryMilvus 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-milvus-processors-nar ## Description Queries a given collection in a Milvus database using vectors. Results of query are added to current record under the results record path for each vector searched. ## Tags chatbot, embeddings, gen ai, genai, generative ai, llm, metadata, milvus, openflow, publish, query, search, text, vector ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [com.snowflake.openflow.runtime.processors.milvus.UpsertMilvus](/user-guide/data-integration/openflow/processors/upsertmilvus) --- title: QueryPinecone 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/querypinecone.md section: Loading & Unloading Data --- # QueryPinecone 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-pinecone-nar ## Description Queries Pinecone for vectors that are similar to the input vector, or retrieves a vector by ID. ## Tags chatbot, gen ai, generative ai, llm, openflow, pinecone, query, similarity, vector ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Use Cases Involving Other Components | Query Pinecone for vectors that are similar to some input text | | -------------------------------------------------------------- | --- title: QueryRecord 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/queryrecord.md section: Loading & Unloading Data --- # QueryRecord 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Evaluates one or more SQL queries against the contents of a FlowFile. The result of the SQL query then becomes the content of the output FlowFile. This can be used, for example, for field-specific filtering, transformation, and row-level filtering. Columns can be renamed, simple calculations and aggregations performed, etc. The Processor is configured with a Record Reader Controller Service and a Record Writer service so as to allow flexibility in incoming and outgoing data formats. The Processor must be configured with at least one user-defined property. The name of the Property is the Relationship to route data to, and the value of the Property is a SQL SELECT statement that is used to specify how input data should be transformed/filtered. The SQL statement must be valid ANSI SQL and is powered by Apache Calcite. If the transformation fails, the original FlowFile is routed to the 'failure' relationship. Otherwise, the data selected will be routed to the associated relationship. If the Record Writer chooses to inherit the schema from the Record, it is important to note that the schema that is inherited will be from the ResultSet, rather than the input Record. This allows a single instance of the QueryRecord processor to have multiple queries, each of which returns a different set of columns and aggregations. As a result, though, the schema that is derived will have no schema name, so it is important that the configured Record Writer not attempt to write the Schema Name as an attribute if inheriting the Schema from the Record. See the Processor Usage documentation for more information. ## Tags aggregate, avro, calcite, csv, etl, filter, json, logs, modify, query, record, route, select, sql, text, transform, update ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## Use cases | Filter out records based on the values of the records' fields | | ---------------------------------------------------------------------------------------- | | Keep only specific records | | Keep only specific fields in a a Record, where the names of the fields to keep are known | | Route record-oriented data for processing based on its contents | --- title: QuerySalesforceObject 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/querysalesforceobject.md section: Loading & Unloading Data --- # QuerySalesforceObject 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-salesforce-nar ## Description Retrieves records from a Salesforce sObject. Users can add arbitrary filter conditions by setting the 'Custom WHERE Condition' property. The processor can also run a custom query, although record processing is not supported in that case. Supports incremental retrieval: users can define a field in the 'Age Field' property that will be used to determine when the record was created. When this property is set the processor will retrieve new records. Incremental loading and record-based processing are only supported in property-based queries. It 's also possible to define an initial cutoff value for the age, filtering out all older records even for the first run. In case of'Property Based Query 'this processor should run on the Primary Node only. FlowFile attribute' record.count 'indicates how many records were retrieved and written to the output. The processor can accept an optional input FlowFile and reference the FlowFile attributes in the query. When'Include Deleted Records 'is true, the processor will include deleted records (soft-deletes) in the results by using the' queryAll 'API. The'IsDeleted' field will be automatically included in the results when querying deleted records. ## Tags query, salesforce, sobject, soql ## Input Requirement ALLOWED ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.salesforce.PutSalesforceObject](/user-guide/data-integration/openflow/processors/putsalesforceobject) --- title: QuerySplunkIndexingStatus 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/querysplunkindexingstatus.md section: Loading & Unloading Data --- # QuerySplunkIndexingStatus 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-splunk-nar ## Description Queries Splunk server in order to acquire the status of indexing acknowledgement. ## Tags acknowledgement, http, logs, splunk ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [org.apache.nifi.processors.splunk.PutSplunkHTTP](/user-guide/data-integration/openflow/processors/putsplunkhttp) --- title: Quickstart: gen 2 Openflow source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/gen2/quickstart.md section: Loading & Unloading Data --- # Quickstart: gen 2 Openflow Available to all accounts. Gen 2 Openflow is available on AWS and Azure. GCP support isn't available yet. - [Second generation Openflow objects and interfaces](/user-guide/data-integration/openflow/gen2/index) - [Openflow gen 1 and gen 2](/user-guide/data-integration/openflow/gen2/openflow-generations) - [Configure a connector with the setup wizard](/user-guide/data-integration/openflow/gen2/setup-connector-wizard) - [About Openflow](/user-guide/data-integration/openflow/about) This topic walks through what's needed to get your first gen 2 connector up and running. For background on how gen 2 Openflow differs from gen 1, see [Openflow gen 1 and gen 2](/user-guide/data-integration/openflow/gen2/openflow-generations). **If you already have gen 1 deployments and runtimes** that you want to bring into gen 2, follow the migration path instead of creating new resources here. Migration from gen 1 to gen 2 is available in Private Preview; contact your Snowflake account representative to be included. Return to this quickstart to set up privileges if you haven't done that yet (the privilege grants in [Set up privileges](#label-openflow-gen2-quickstart-privileges) apply regardless of how you create your gen 2 resources). ## Before you begin Complete the standard Openflow prerequisites described in [About Openflow](/user-guide/data-integration/openflow/about)—role configuration, terms of service, and deployment-type planning (BYOC or %OFSFSPCS%). Gen 2 uses different account- and schema-level privileges than gen 1. If you previously set up Openflow using the public guides, see [Openflow gen 1 and gen 2](/user-guide/data-integration/openflow/gen2/openflow-generations) for how the privilege model differs. ## Set up privileges An account administrator grants privileges; an Openflow administrator role creates the database, schema, and gen 2 objects. ### Grant privileges (account administrator) ```sql USE ROLE ACCOUNTADMIN; CREATE ROLE IF NOT EXISTS openflow_admin; GRANT ROLE openflow_admin TO ROLE ACCOUNTADMIN; GRANT CREATE OPENFLOW DEPLOYMENT ON ACCOUNT TO ROLE openflow_admin; GRANT CREATE DATABASE ON ACCOUNT TO ROLE openflow_admin; GRANT CREATE INTEGRATION ON ACCOUNT TO ROLE openflow_admin; -- Snowflake deployments only GRANT CREATE COMPUTE POOL ON ACCOUNT TO ROLE openflow_admin; ``` ### Create database and schema (Openflow administrator) Create a database and schema to **house gen 2 Openflow objects**—runtimes and connectors are schema-level objects stored here. This is your Openflow **control schema**, not the database where connectors load data. Grant the execute-as role access to destination databases separately (see [Create an execute-as role](#label-openflow-gen2-quickstart-execute-as-role)). ```sql USE ROLE openflow_admin; CREATE DATABASE IF NOT EXISTS openflow_db; CREATE SCHEMA IF NOT EXISTS openflow_db.openflow_schema; GRANT CREATE OPENFLOW RUNTIME ON SCHEMA openflow_db.openflow_schema TO ROLE openflow_admin; GRANT CREATE OPENFLOW CONNECTOR ON SCHEMA openflow_db.openflow_schema TO ROLE openflow_admin; ``` Runtimes are schema-level objects. To run SQL against a runtime, users need `USAGE`, `OPERATE`, or `MONITOR` on the runtime and `USAGE` on its database and schema. You can use a simple name when the session database and schema are set—the same name resolution rules as other schema-level objects apply, including in wait functions. ## Create a gen 2 deployment Create a gen 2 deployment object with SQL or the Openflow UI. Gen 2 uses `CREATE OPENFLOW DEPLOYMENT`—not the gen 1 `CREATE OPENFLOW DATA PLANE INTEGRATION`. For SQL parameters (`DEPLOYMENT_TYPE`, `VPC_TYPE`, `USE_PRIVATE_LINK`, `EVENT_TABLE`, and so on), see [CREATE OPENFLOW DEPLOYMENT](/sql-reference/sql/create-openflow-deployment). **PrivateLink:** If your organization requires private connectivity to Snowflake or the Openflow UI—not just to your data source—plan PrivateLink before you run `CREATE OPENFLOW DEPLOYMENT`. Enable PrivateLink for your account first (see [AWS PrivateLink and Snowflake](/user-guide/admin-security-privatelink)). Set `USE_PRIVATE_LINK = TRUE` in your `CREATE` statement (see [CREATE OPENFLOW DEPLOYMENT](/sql-reference/sql/create-openflow-deployment)). These flags are chosen at deployment creation; you cannot change them later with `ALTER OPENFLOW DEPLOYMENT`. - **BYOC:** Complete AWS PrivateLink setup (VPC endpoint, DNS, security groups) **before** you apply the CloudFormation template—if you deploy without it configured, you typically must create a new deployment rather than retrofit. Also set `USE_USER_AUTH_OVER_PRIVATELINK = TRUE` only if users access %sf-web-interface% or Openflow through a PrivateLink URL; leave it `FALSE` if they use public URLs (deployment traffic still uses PrivateLink when `USE_PRIVATE_LINK` is enabled). See [](/user-guide/data-integration/openflow/setup-openflow-byoc#label-setup-private-link). - **Snowflake deployments:** Enable PrivateLink when creating the deployment and configure PrivateLink access to the Runtime UI. The user-auth-over-PrivateLink setting does not apply here. See [Set up PrivateLink UI access in Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/setup-openflow-spcs-configure-pr-ui). Example (BYOC): ```sql USE ROLE openflow_admin; CREATE OPENFLOW DEPLOYMENT my_deployment DEPLOYMENT_TYPE = BYOC VPC_TYPE = 'MANAGED' -- USE_PRIVATE_LINK = TRUE, -- USE_USER_AUTH_OVER_PRIVATELINK = FALSE, -- BYOC only; see PrivateLink note above DISPLAY_NAME = 'My gen 2 Deployment'; ``` Example (Snowflake deployment): ```sql CREATE OPENFLOW DEPLOYMENT my_snowflake_deployment DEPLOYMENT_TYPE = SNOWFLAKE -- USE_PRIVATE_LINK = TRUE, -- see PrivateLink note above DISPLAY_NAME = 'My gen 2 Snowflake Deployment'; ``` Each account supports up to three Snowflake Openflow deployments. Gen 1 and gen 2 deployments share this limit; `CREATE OPENFLOW DEPLOYMENT WITH DEPLOYMENT_TYPE = SNOWFLAKE` fails when the account already has three Snowflake deployments, regardless of generation. Next, complete cloud infrastructure setup—the networking and installation steps match the public Openflow guides; only the Snowflake object you create first is different: - **BYOC:** CloudFormation template, installation script, and VPC setup. See [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc). - **Snowflake deployments:** Core Snowflake and deployment prerequisites. See [Set up Openflow - Snowflake Deployment - Task overview](/user-guide/data-integration/openflow/setup-openflow-spcs). ## Create a gen 2 runtime Create a runtime inside your gen 2 deployment. Use the database and schema you created in [Set up privileges](#label-openflow-gen2-quickstart-privileges). ### Create an execute-as role `EXECUTE_AS_ROLE` is the Snowflake role that connectors use when reading from and writing to Snowflake during connector execution. Snowflake access follows that role's grants—not your session role and not privileges on the runtime's home schema. Grant the control schema and other connector-specific objects before you create the runtime (destination database grants are in [Before you install a connector](#label-openflow-gen2-quickstart-connector-prereqs)). ```sql USE ROLE ACCOUNTADMIN; CREATE ROLE IF NOT EXISTS openflow_execute_as_rl; GRANT ROLE openflow_execute_as_rl TO ROLE openflow_admin; -- Control schema: required if secrets, stages, or other connector-referenced objects live here GRANT USAGE ON DATABASE openflow_db TO ROLE openflow_execute_as_rl; GRANT USAGE ON SCHEMA openflow_db.openflow_schema TO ROLE openflow_execute_as_rl; ``` Grant **READ** on any [Snowflake secrets](/sql-reference/sql/create-secret) the connector references (often in the control schema), plus **USAGE** on the secret's database and schema. See [Configure a gen 2 connector with SQL](/user-guide/data-integration/openflow/gen2/configure-connector-sql) for secret grants. For background on the execute-as role, see [Openflow gen 1 and gen 2](/user-guide/data-integration/openflow/gen2/openflow-generations) or [](/user-guide/data-integration/openflow/about-spcs#label-openflow-spcs-what-is-runtime-role). ### Configure external access (Snowflake deployments) Openflow BYOC runtimes reach external sources through outbound connectivity you configure in your cloud environment; EAIs are not used. See [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc). For %OFSFSPCS-plural%, the runtime must be associated with an [external access integration](/developer-guide/external-network-access/external-network-access-overview) (EAI) before connectors can reach external sources. The hostname and port in the network rule come from your connector's setup topic—update the rule before you start the connector (see [Before you install a connector](#label-openflow-gen2-quickstart-connector-prereqs)). 1. Create a [network rule](/sql-reference/sql/create-network-rule) shell (placeholder `VALUE_LIST` is fine for now). 2. Create an [external access integration](/sql-reference/sql/create-external-access-integration) that references the network rule. 3. Grant `USAGE` on the integration to `openflow_execute_as_rl`. 4. Pass the integration in `EXTERNAL_ACCESS_INTEGRATIONS` when you create the runtime (next section), or run `ALTER OPENFLOW RUNTIME ... ADD EXTERNAL_ACCESS_INTEGRATIONS` afterward. Network rules are schema-level objects. Set the session database and schema (or use a fully qualified rule name) before you create them: ```sql USE ROLE ACCOUNTADMIN; USE DATABASE openflow_db; USE SCHEMA openflow_schema; CREATE NETWORK RULE IF NOT EXISTS openflow_my_runtime_network_rule MODE = EGRESS TYPE = HOST_PORT VALUE_LIST = (':'); -- Placeholder; we'll update this VALUE_LIST at connector setup time CREATE EXTERNAL ACCESS INTEGRATION IF NOT EXISTS openflow_my_runtime_eai ALLOWED_NETWORK_RULES = (openflow_db.openflow_schema.openflow_my_runtime_network_rule) ENABLED = TRUE; GRANT USAGE ON INTEGRATION openflow_my_runtime_eai TO ROLE openflow_execute_as_rl; ``` If your source system is reachable only over **outbound PrivateLink** (not the public internet), use `TYPE = PRIVATE_HOST_PORT` network rules and provision private connectivity endpoints before you create the EAI. Outbound PrivateLink requires Business Critical Edition (or later). See [](/user-guide/private-connectivity-outbound#label-private-connect-external-access) and [](/developer-guide/external-network-access/creating-using-external-network-access#label-creating-using-external-access-integration-connectivity) (AWS, Azure, and Google Cloud private-connectivity topics are linked from that page). ### Create the runtime Set the session context, then create the runtime: ```sql USE ROLE openflow_admin; USE DATABASE openflow_db; USE SCHEMA openflow_schema; CREATE OPENFLOW RUNTIME my_runtime IN DEPLOYMENT my_deployment NODE_TYPE = MEDIUM MIN_NODES = 1 MAX_NODES = 1 EXECUTE_AS_ROLE = openflow_execute_as_rl DISPLAY_NAME = 'My gen 2 Runtime'; ``` For a Snowflake deployment, add `EXTERNAL_ACCESS_INTEGRATIONS` so the runtime can use the EAI you created: ```sql CREATE OPENFLOW RUNTIME my_runtime IN DEPLOYMENT my_snowflake_deployment NODE_TYPE = MEDIUM MIN_NODES = 1 MAX_NODES = 1 EXECUTE_AS_ROLE = openflow_execute_as_rl EXTERNAL_ACCESS_INTEGRATIONS = (openflow_my_runtime_eai) DISPLAY_NAME = 'My gen 2 Runtime'; ``` To add or change EAIs on an existing runtime, see `ADD EXTERNAL_ACCESS_INTEGRATIONS` in [ALTER OPENFLOW RUNTIME](/sql-reference/sql/alter-openflow-runtime). ## Create a gen 2 connector Gen 2 runtimes also run gen 1 connectors. If a gen 2 catalog entry isn't available for your source yet, or if you prefer the gen 1 connector, install it from the connector catalog — it runs on the same runtime and follows that connector's public setup documentation. ### Before you install a connector Complete connector-specific setup before you run the wizard or start a connector: - **Network rule (Snowflake deployments):** Update the rule you created for the runtime with the source hostname and port from your connector's setup topic. For domain lists by connector, see [Set up Openflow - Snowflake Deployment: Configure allowed domains for Openflow connectors](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list). ```sql ALTER NETWORK RULE openflow_my_runtime_network_rule SET VALUE_LIST = (':'); ``` - **Destination database (PostgreSQL CDC and MySQL CDC):** Create a destination database if you don't already have one. Grant the runtime's `EXECUTE_AS_ROLE` **USAGE** on the database and **CREATE SCHEMA** on the database—the connector creates destination schemas; you do not grant **USAGE** on a pre-existing destination schema. Also grant **USAGE, OPERATE** on the ingest warehouse. See [Set up the Openflow Connector for PostgreSQL](/user-guide/data-integration/openflow/connectors/postgres/setup) or [Set up the Openflow Connector for MySQL](/user-guide/data-integration/openflow/connectors/mysql/setup) for full destination setup. ```sql CREATE DATABASE IF NOT EXISTS my_dest_db; GRANT USAGE ON DATABASE my_dest_db TO ROLE openflow_execute_as_rl; GRANT CREATE SCHEMA ON DATABASE my_dest_db TO ROLE openflow_execute_as_rl; GRANT USAGE, OPERATE ON WAREHOUSE my_ingest_wh TO ROLE openflow_execute_as_rl; ``` - **Secrets:** Create [Snowflake secrets](/sql-reference/sql/create-secret) for credentials (for example, database passwords) and grant **READ** to the runtime's `EXECUTE_AS_ROLE`. Check your connector's setup topic for the required secret type. See [Create an execute-as role](#label-openflow-gen2-quickstart-execute-as-role). - **Source preparation:** Follow the public connector setup topic for your source (for example, PostgreSQL publication and replication for PostgreSQL CDC). For your first connector, using the setup wizard is recommended: - [Configure a connector with the setup wizard](/user-guide/data-integration/openflow/gen2/setup-connector-wizard) — Install a **gen 2** catalog entry with step-by-step validation. The wizard manages configuration and versioning; you do not need [gen 2 connector configuration and versioning](/user-guide/data-integration/openflow/gen2/connector-versioning) for day-to-day UI setup. To create another connector from an already validated configuration—for example, when promoting the same settings to another runtime—see [Create from a known configuration](#label-openflow-fbe-git-create) in [gen 2 connector configuration and versioning](/user-guide/data-integration/openflow/gen2/connector-versioning). ### Create a connector with SQL (optional) Use SQL when you need automation or repeat deployments. See [Configure a gen 2 connector with SQL](/user-guide/data-integration/openflow/gen2/configure-connector-sql) for the full workflow. Example (PostgreSQL CDC connector): Use the catalog **definition ID** in `FROM DEFINITION`. For PostgreSQL CDC, the ID is `OPENFLOW_POSTGRES_CDC`. To list definition IDs available in your account, run `SHOW OPENFLOW CONNECTOR DEFINITIONS` (see [SHOW OPENFLOW CONNECTOR DEFINITIONS](/sql-reference/sql/show-openflow-connector-definitions)). ```sql CREATE OPENFLOW CONNECTOR my_postgres_connector IN RUNTIME my_runtime FROM DEFINITION OPENFLOW_POSTGRES_CDC DISPLAY_NAME = 'My PostgreSQL CDC Connector'; ``` The connector will be in a **STOPPED** state and is a **Draft** until you commit a configuration version. See [Configure a gen 2 connector with SQL](/user-guide/data-integration/openflow/gen2/configure-connector-sql) (and [gen 2 connector configuration and versioning](/user-guide/data-integration/openflow/gen2/connector-versioning) if you use SQL or automation). ## Start the connector After configuration is committed: ```sql ALTER OPENFLOW CONNECTOR my_postgres_connector START; SELECT SYSTEM$WAIT_FOR_STABLE_OPENFLOW_CONNECTORS( 600, 'my_postgres_connector' ); ``` Manage the connector from the UI (**Installed Connectors** %raa% **Start** / **Stop**) or with SQL. See [Manage the gen 2 Openflow connector lifecycle](/user-guide/data-integration/openflow/gen2/manage-connector-lifecycle). ## Next steps - [Configure a gen 2 connector with SQL](/user-guide/data-integration/openflow/gen2/configure-connector-sql) — Full SQL workflow to configure and commit connector settings. - [Second generation Openflow SQL command reference](/sql-reference/commands-openflow-gen2) — Full SQL command reference for gen 2 objects. - [gen 2 connector configuration and versioning](/user-guide/data-integration/openflow/gen2/connector-versioning) — Versioning model for SQL and Git (optional if you use the UI only). - [Openflow gen 1 and gen 2](/user-guide/data-integration/openflow/gen2/openflow-generations) — gen 1 vs gen 2 comparison, key differences, and documentation map. --- title: ReaderLookup source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/readerlookup.md section: Loading & Unloading Data --- # ReaderLookup This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides a RecordReaderFactory that can be used to dynamically select another RecordReaderFactory. This will allow multiple RecordReaderFactories to be defined and registered, and then selected dynamically at runtime by referencing a FlowFile attribute in the Service to Use property. ## Tags lookup, parse, reader, record, row ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: RecordSetWriterLookup source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/recordsetwriterlookup.md section: Loading & Unloading Data --- # RecordSetWriterLookup This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides a RecordSetWriterFactory that can be used to dynamically select another RecordSetWriterFactory. This will allow multiple RecordSetWriterFactory's to be defined and registered, and then selected dynamically at runtime by tagging FlowFiles with the attributes and referencing those attributes in the Service to Use property. ## Tags lookup, record, recordset, result, row, serializer, set, writer ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: RecordSinkServiceLookup source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/recordsinkservicelookup.md section: Loading & Unloading Data --- # RecordSinkServiceLookup This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides a RecordSinkService that can be used to dynamically select another RecordSinkService. This service requires an attribute named 'record.sink.name' to be passed in when asking for a connection, and will throw an exception if the attribute is missing. The value of 'record.sink.name' will be used to select the RecordSinkService that has been registered with that name. This will allow multiple RecordSinkServices to be defined and registered, and then selected dynamically at runtime by tagging flow files with the appropriate 'record.sink.name' attribute. Note that this controller service is not intended for use in reporting tasks that employ RecordSinkService instances, such as QueryNiFiReportingTask. ## Tags lookup, record, sink ## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: RedisConnectionPoolService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/redisconnectionpoolservice.md section: Loading & Unloading Data --- # RedisConnectionPoolService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description A service that provides connections to Redis. ## Tags cache, redis ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: RedisDistributedMapCacheClientService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/redisdistributedmapcacheclientservice.md section: Loading & Unloading Data --- # RedisDistributedMapCacheClientService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description An implementation of DistributedMapCacheClient that uses Redis as the backing cache. This service relies on the WATCH, MULTI, and EXEC commands in Redis, which are not fully supported when Redis is clustered. As a result, this service can only be used with a Redis Connection Pool that is configured for standalone or sentinel mode. Sentinel mode can be used to provide high-availability configurations. ## Tags cache, distributed, map, redis ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: RemoveFieldRecordReader source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/removefieldrecordreader.md section: Loading & Unloading Data --- # RemoveFieldRecordReader This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description A wrapper for a RecordReaderFactory that supports filtering out specified fields from NiFi Records. It allows users to specify a list of field names that should be ignored when reading records from the record reader returned from the wrapped RecordReaderFactory. The ignored record fields are specified as dynamic properties. At least one dynamic property must be set. The dynamic property name is used as a description of the field to remove, and the dynamic property value is a RecordPath that identifies the field to be removed. Nested paths are supported. Record paths targeting the root path ("/") are not allowed and will result in a validation error. This service should be used when all of the following criteria are met: - your delegate RecordReaderFactory is configured to infer the schema from the data - you do not have or do not want to define a static schema for the data you 're reading - the fields you set to be ignored should not be serialized to the NiFi content repository for security or performance reasons If any of the above criteria are not met, consider using the RecordFieldRemover processor instead. NOTE: The RecordReader returned by this implementation is hardcoded to drop unknown fields rather than ignoring them. Even when the RecordReader's nextRecord(coerceTypes, dropUnknownFields) method is called with dropUnknownFields set to false, the RecordReader will still drop unknown fields. ## Tags delete, field, filter, reader, record, remove ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: RemoveRecordField 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/removerecordfield.md section: Loading & Unloading Data --- # RemoveRecordField 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Modifies the contents of a FlowFile that contains Record-oriented data (i.e. data that can be read via a RecordReader and written by a RecordWriter) by removing selected fields. This Processor requires that at least one user-defined Property be added. The name of the property is ignored by the processor, but could be a meaningful identifier for the user. The value of the property should indicate a RecordPath that determines the field to be removed. The processor executes the removal in the order in which these properties are added to the processor. Set the "Record Writer" to "Inherit Record Schema" in order to use the updated Record Schema modified when removing Fields. ## Tags avro, csv, delete, freeform, generic, json, record, remove, schema, text, update ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## Use cases | Remove one or more fields from a Record, where the names of the fields to remove are known. | | ------------------------------------------------------------------------------------------- | ## See also - [org.apache.nifi.processors.standard.UpdateRecord](/user-guide/data-integration/openflow/processors/updaterecord) --- title: RenameRecordField 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/renamerecordfield.md section: Loading & Unloading Data --- # RenameRecordField 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Renames one or more fields in each Record of a FlowFile. This Processor requires that at least one user-defined Property be added. The name of the Property should indicate a RecordPath that determines the field that should be updated. The value of the Property is the new name to assign to the Record Field that matches the RecordPath. The property value may use Expression Language to reference FlowFile attributes as well as the variables *field.name*, *field.value*, *field.type*, and *record.index* ## Tags avro, csv, field, generic, json, log, logs, record, rename, schema, update ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## Use cases | Rename a field in each Record to a specific, known name. | | ---------------------------------------------------------------------------------------- | | Rename a field in each Record to a name that is derived from a FlowFile attribute. | | Rename a field in each Record to a new name that is derived from the current field name. | ## See also - [org.apache.nifi.processors.standard.RemoveRecordField](/user-guide/data-integration/openflow/processors/removerecordfield) - [org.apache.nifi.processors.standard.UpdateRecord](/user-guide/data-integration/openflow/processors/updaterecord) --- title: ReplaceText 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/replacetext.md section: Loading & Unloading Data --- # ReplaceText 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Updates the content of a FlowFile by searching for some textual value in the FlowFile content (via Regular Expression/regex, or literal value) and replacing the section of the content that matches with some alternate value. It can also be used to append or prepend text to the contents of a FlowFile. ## Tags Change, Modify, Regex, Regular Expression, Replace, Text, Update ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Use cases | Append text to the end of every line in a FlowFile | | ----------------------------------------------------------------------------------- | | Prepend text to the beginning of every line in a FlowFile | | Replace every occurrence of a literal string in the FlowFile with a different value | | Transform every occurrence of a literal string in a FlowFile | | Completely replace the contents of a FlowFile to a specific text | --- title: ReplaceTextWithMapping 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/replacetextwithmapping.md section: Loading & Unloading Data --- # ReplaceTextWithMapping 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Updates the content of a FlowFile by evaluating a Regular Expression against it and replacing the section of the content that matches the Regular Expression with some alternate value provided in a mapping file. ## Tags Change, Mapping, Modify, Regex, Regular Expression, Replace, Text, Update ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: RestLookupService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/restlookupservice.md section: Loading & Unloading Data --- # RestLookupService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Use a REST service to look up values. ## Tags http, json, lookup, rest, xml ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: RetryFlowFile 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/retryflowfile.md section: Loading & Unloading Data --- # RetryFlowFile 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description FlowFiles passed to this Processor have a 'Retry Attribute' value checked against a configured 'Maximum Retries' value. If the current attribute value is below the configured maximum, the FlowFile is passed to a retry relationship. The FlowFile may or may not be penalized in that condition. If the FlowFile 's attribute value exceeds the configured maximum, the FlowFile will be passed to a' retries_exceeded 'relationship. WARNING: If the incoming FlowFile has a non-numeric value in the configured'Retry Attribute 'attribute, it will be reset to'1 '. You may choose to fail the FlowFile instead of performing the reset. Additional dynamic properties can be defined for any attributes you wish to add to the FlowFiles transferred to' retries_exceeded'. These attributes support attribute expression language. ## Tags FlowFile, Retry ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: RouteOnAttribute 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/routeonattribute.md section: Loading & Unloading Data --- # RouteOnAttribute 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Routes FlowFiles based on their Attributes using the Attribute Expression Language ## Tags Attribute Expression Language, Expression Language, Regular Expression, attributes, detect, filter, find, regex, regexp, routing, search, string, text ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## Use cases | Route data to one or more relationships based on its attributes using the NiFi Expression Language. | | --------------------------------------------------------------------------------------------------- | | Keep data only if its attributes meet some criteria, such as its filename ends with .txt. | | Discard or drop a file based on attributes, such as filename. | ## Use Cases Involving Other Components | Route record-oriented data based on whether or not the record's values meet some criteria | | ----------------------------------------------------------------------------------------- | --- title: RouteOnContent 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/routeoncontent.md section: Loading & Unloading Data --- # RouteOnContent 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Applies Regular Expressions to the content of a FlowFile and routes a copy of the FlowFile to each destination whose Regular Expression matches. Regular Expressions are added as User-Defined Properties where the name of the property is the name of the relationship and the value is a Regular Expression to match against the FlowFile content. User-Defined properties do support the Attribute Expression Language, but the results are interpreted as literal values, not Regular Expressions ## Tags content, detect, filter, find, regex, regexp, regular expression, route, search, string, text ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: RouteText 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/routetext.md section: Loading & Unloading Data --- # RouteText 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Routes textual data based on a set of user-defined rules. Each line in an incoming FlowFile is compared against the values specified by user-defined Properties. The mechanism by which the text is compared to these user-defined properties is defined by the 'Matching Strategy'. The data is then routed according to these rules, routing each line of the text individually. ## Tags Expression Language, Regular Expression, attributes, csv, delimited, detect, filter, find, logs, regex, regexp, routing, search, string, text ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## Use cases | Drop blank or empty lines from the FlowFile's content. | | -------------------------------------------------------------------------------------------------------------------------------- | | Remove specific lines of text from a file, such as those containing a specific word or having a line length over some threshold. | --- title: RunDatabricksJob 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/rundatabricksjob.md section: Loading & Unloading Data --- # RunDatabricksJob 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-databricks-processors-nar ## Description Triggers a pre-defined Databricks job to run with custom parameters. Job parameters can be set using dynamic properties ## Tags databricks, jobs, openflow ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: RunMongoAggregation 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/runmongoaggregation.md section: Loading & Unloading Data --- # RunMongoAggregation 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-mongodb-nar ## Description A processor that runs an aggregation query whenever a flowfile is received. ## Tags aggregate, aggregation, mongo ## Input Requirement ALLOWED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: Runtime sizing and packing for CDC connectors source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/cdc-runtime-sizing.md section: Loading & Unloading Data --- # Runtime sizing and packing for CDC connectors This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [Set up Openflow - Snowflake Deployment: Create runtime](/user-guide/data-integration/openflow/setup-openflow-spcs-create-runtime) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Manage Openflow](/user-guide/data-integration/openflow/manage) This topic describes how to size an Openflow runtime for change data capture (CDC) connectors, how many connectors you can run on one runtime, and what to do when you need a different size after a connector is already installed. The guidance applies to all Openflow CDC connectors, because the sizing thresholds are expressed in replication throughput rather than in terms of any particular source database. ## Size a runtime The runtime size determines the CPU, memory, and disk available to the connector. The available sizes are Small, Medium, and Large. Choose the size when you create the runtime: you can't change the size of an existing runtime in place. Size the runtime based on the sustained workload it needs to handle across all connectors running on it. Sustained means typical steady-state throughput, not peak. Peak load can temporarily increase connector queues and end-to-end replication latency; the workload catches up when the load drops back to the steady-state level. The following ranges are starting points based on internal benchmarks and production customer data. They aren't service guarantees. Your fit depends on row size, event distribution, schema width, and source burstiness. Start at the lower bound, measure runtime CPU, memory, queue depth, and end-to-end replication latency in production, then increase from there. - Light workload (aggregate sustained throughput below approximately 1,000 events per second, fewer than approximately 100 actively changing tables): a Small runtime can host a single low-volume connector. Pack additional connectors on Small only when each source is genuinely light. - Moderate workload (approximately 1,000 to 5,000 events per second, hundreds of actively changing tables): a Medium runtime can typically host 5 to 8 connectors. - Heavy workload (approximately 5,000 to 15,000 events per second, hundreds to low thousands of actively changing tables): a Large runtime can typically host 15 or more connectors. If you want a smaller blast radius, split across two Medium runtimes instead. For the steps to create a runtime at the size you choose, see [Set up Openflow - Snowflake Deployment: Create runtime](/user-guide/data-integration/openflow/setup-openflow-spcs-create-runtime). ## Run multiple connectors on one runtime You can run multiple CDC connector instances on a single runtime. This is useful for replicating many small databases, for example a multi-tenant SaaS with one database per tenant, or a fleet of operational databases per business unit or region. Run a connector on a dedicated runtime, not packed with others, when any of the following applies: - A single source sustains more than approximately 15,000 events per second. - You need sub-1-minute end-to-end replication latency under load. - You can't tolerate noisy-neighbor effects from other sources sharing the runtime. Each replicated table can consume two Snowpipe Streaming pipes: one for snapshot replication and one for incremental replication. As you pack more tables onto a runtime, check your account's [Snowpipe Streaming pipe limit](/user-guide/snowpipe-streaming/snowpipe-streaming-high-performance-limitations#pipe-limits) and raise it before you approach the cap. How you configure multiple connector instances on one runtime depends on the generation: - **Gen 2**: each connector instance carries its own configuration, so running multiple instances on one runtime is just installing each connector on the same runtime. There is no shared configuration to inherit or override. - **Gen 1**: each connector instance uses Source, Destination, and Ingestion parameter contexts. The Ingestion context inherits from the Source and Destination contexts, so any value you don't override in Ingestion resolves from the parent context. The rest of this section describes the recommended gen 1 setup. ### Use shared Source and Destination contexts with per-connector overrides in Ingestion Snowflake recommends this setup for running multiple CDC connector instances manually. It's the same pattern the openflow skill applies automatically at scale. You don't have to configure multiple CDC connector instances by hand. The **openflow skill in Snowflake CoCo** is the recommended path when you need to run many CDC connectors on one runtime. The skill applies this pattern consistently across the connector fleet. To get started, install and connect the [Snowflake CoCo CLI](/user-guide/cortex-code/cortex-code-cli), then ask the bundled [openflow skill](/user-guide/cortex-code/bundled-skills#label-bundled-skill-openflow) to configure the layout. When you import more than one CDC connector instance of the same type into one runtime, keep the Source and Destination contexts at their default names and let every connector instance inherit from them. In that connector's Ingestion parameter context, override only the values that differ from the shared defaults: the connection URL, replication slot or server ID, destination database, and table list. Leave shared values, such as the Snowflake role, warehouse, and JDBC driver, in the Source and Destination contexts so every connector instance inherits them. Use the following process for each additional connector instance: 1. Import the connector instance. 2. Confirm that its Ingestion context inherits from the existing Source and Destination contexts, instead of creating a new set of Source and Destination contexts. 3. In the Ingestion context, override every value that must differ from the shared defaults: at minimum, the source connection identity (for example, the JDBC URL and replication slot or server ID) and the destination database. 4. Confirm that the connector replicates from the correct source into the correct destination before moving on to the next connector instance. ### Don't rename the Source and Destination contexts Don't rename the Source or Destination parameter contexts to make them unique per connector instance. Renaming these contexts might seem like a simpler way to keep each connector instance visually distinct, but it silently breaks future connector version upgrades. When Snowflake ships a connector version that adds a new parameter to the Source or Destination context, the upgrade process looks for a context with the connector's default name to apply that new parameter to. If you renamed the context, the upgrade process can't find it, and the new parameter isn't added to the context your connector instances actually use. Your connector instances then silently fall out of sync with the new version, and the Snowflake registry can't repair this automatically. This risk applies whether you rename the contexts to a single shared alternate name or to a distinct name per connector instance. The Ingestion context is safe to rename, because the registry creates a fresh Ingestion context for every new connector instance. Renaming it doesn't affect any other connector instance or any future upgrade. If you want every connector instance to be individually identifiable in the parameter context list, rename only its Ingestion context, for example to the source database name, tenant name, or region. ### Avoid unintended inheritance from an earlier connector instance The most common mistake when importing an additional CDC connector instance is unintentionally reusing the previous instance's Ingestion context, instead of creating a dedicated context. If this happens, the new connector instance uses the earlier instance's source database, destination database, table list, replication slot, server ID, or XStream configuration, and replicates the wrong data without any error. After importing each additional connector instance, always confirm that its Ingestion context is new and dedicated to that instance, and not shared with any earlier connector instance. If the new Ingestion context rather than reusing an existing one. ## Resize a runtime Runtime size is fixed at creation, so to change size you run the connector on a different runtime. You have two options depending on whether you want to preserve the current replication progress. If you don't need to keep the progress of the current connector, the simplest path is to create a new runtime at the size you need and install a new connector instance on it. The new connector starts from scratch: it snapshots all configured tables and then captures ongoing changes from that point. The replication progress of the existing connector is discarded. To keep the progress of the current connector, for example to avoid re-snapshotting tables that took a long time to snapshot initially, migrate the connector to the new runtime. This reuses the existing destination tables and resumes incremental replication from where it left off. For the migration steps, which differ by source, see the reinstall or migration instructions for the connector you are running. --- title: S3FileResourceService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/s3fileresourceservice.md section: Loading & Unloading Data --- # S3FileResourceService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides an Amazon Web Services (AWS) S3 file resource for other components. ## Tags AWS, Amazon, S3, file, resource ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: Salesforce Data Cloud Zerocopy Connector: Security and privileges source: https://docs.snowflake.cn/en/user-guide/data-integration/zero-copy/salesforce/security.md section: Loading & Unloading Data --- # Salesforce Data Cloud Zerocopy Connector: Security and privileges - [Set up the Salesforce Data Cloud Zerocopy Connector](/user-guide/data-integration/zero-copy/salesforce/setup) - [Explore data products from Salesforce Data Cloud](/user-guide/data-integration/zero-copy/salesforce/explore-data-products) This topic describes the privileges required to create and manage a Zerocopy Connector and the catalog-linked databases created from it. ## Access control requirements A [role](#label-access-control-overview-roles) used to execute this operation must have the following [privileges](#label-access-control-overview-privileges) at a minimum:
For instructions on creating a custom role with a specified set of privileges, see [](#label-security-custom-role). For general information about roles and privilege grants for performing SQL actions on [securable objects](#label-access-control-securable-objects), see [Overview of Access Control](/user-guide/security-access-control-overview). ## Connector states A Zerocopy Connector transitions through the following states. Understanding the state is important because some operations are only permitted in specific states.
### State transition rules - The connector transitions to `CONNECTING` automatically when a Snowflake V2 Data Share Target is created in Salesforce Data Cloud. - `ALTER ... DISCONNECT` is permitted when the connector is in `CONNECTED` or `DISCONNECT_ERROR` state. - All catalog-linked databases created from the connector must be dropped before disconnecting. - `DROP ZEROCOPY CONNECTOR` is permitted when the connector is in `NEW`, `CONNECT_ERROR`, `DISCONNECT_ERROR`, or `DISCONNECTED` state. - Catalog-linked databases do not support `UNDROP`. --- title: SalesforceDataCloudOAuthTokenProvider source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/salesforcedatacloudoauthtokenprovider.md section: Loading & Unloading Data --- # SalesforceDataCloudOAuthTokenProvider This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Retrieves an OAuth2 access token from Salesforce using the configured OAuth2 Access Token Provider and exchanges the token for a Data Cloud API token. The token is then used to authenticate with Salesforce Data Cloud APIs. ## Tags preview, salesforce ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: SampleRecord 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/samplerecord.md section: Loading & Unloading Data --- # SampleRecord 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Samples the records of a FlowFile based on a specified sampling strategy (such as Reservoir Sampling). The resulting FlowFile may be of a fixed number of records (in the case of reservoir-based algorithms) or some subset of the total number of records (in the case of probabilistic sampling), or a deterministic number of records (in the case of interval sampling). ## Tags interval, range, record, reservoir, sample ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: SAP® BDC Connect for Snowflake source: https://docs.snowflake.cn/en/user-guide/data-integration/zero-copy/sap-sql/setup-sap-bdc.md section: Loading & Unloading Data --- # SAP® BDC Connect for Snowflake - [About Snowflake and SAP® Zero-Copy Integration](/user-guide/data-integration/zero-copy/about-sap-snowflake) - [Setup tasks for SAP® Snowflake and SAP® BDC Connect for Snowflake](/user-guide/data-integration/zero-copy/sap-sql/setup-tasks) - [SAP® Snowflake](/user-guide/data-integration/zero-copy/sap-sql/setup-sap-snowflake) This topic describes the steps to set up an SAP® Business Data Cloud connection for use with an existing Snowflake account. The Snowflake account must be Standard, Enterprise, or Business Critical edition and must be on AWS commercial or Azure commercial in a supported region as described in [Supported Cloud Regions](/user-guide/intro-regions). For more information, see Provisioning SAP Business Data Cloud Connect (https://help.sap.com/docs/business-data-cloud/administering-sap-business-data-cloud/provision-sap-business-data-cloud-connector-for-supported-external-systems). As an SAP® administrator, perform the following steps: 1. Obtain your Snowflake account URL and ensure it follows the format https://orgName-accountName.snowflakecomputing.cn. Which should be all lowercase and replace _ (underscore) with - (dash) for RFC compliance. 2. Provision SAP Business Data Cloud Connect as documented here: Provisioning SAP Business Data Cloud Connect (https://help.sap.com/docs/business-data-cloud/administering-sap-business-data-cloud/provision-sap-business-data-cloud-connector-for-supported-external-systems). 3. Follow steps 1-5 in the wizard 4. In wizard step 6: Configure Parameters: - **External System Instance Identifier**: Enter your Snowflake account URL: https://orgName-accountName.snowflakecomputing.cn - **Region**: Select the same region that you used for enabling SAP Business Data Cloud Core. 5. Complete wizard steps 7 and 8. 6. In step 9: Hover over the **View Tenant Notifications** button. A pop-up window opens with an **Invitation Link** that can be used to complete the configuration in Snowflake. 7. Copy the Invitation Link 8. Log in to your Snowflake account to complete the remainder of the configuration to create a Zerocopy Connector as described in [Set Up SAP® BDC Connect for Snowflake Zerocopy Connector](/user-guide/data-integration/zero-copy/sap-sql/setup). ## Next steps In your SAP for Me (https://me.sap.com/) environment, choose the Customer Landscape tab and, under the Formations tab, choose Include Systems to add the SAP BDC Connect instance to an existing formation. Customers can create additional Zerocopy Connectors in the same Snowflake account and enroll them with the same or different SAP® Business Data Cloud tenant. Each Zerocopy Connector requires a new **Invitation Link** that can be obtained from SAP for Me (https://me.sap.com/). Each **Invitation Link** can be enrolled only once with SAP® Business Data Cloud. To create a new formation, see Creating SAP Business Data Cloud Formations (https://help.sap.com/docs/business-data-cloud/administering-sap-business-data-cloud/integrate-sap-business-data-cloud-provisioned-systems?locale=en-US&state=PRODUCTION&version=SHIP). --- title: SAP® BDC Connect for Snowflake Zerocopy Connector — Security and Privileges source: https://docs.snowflake.cn/en/user-guide/data-integration/zero-copy/sap-sql/security.md section: Loading & Unloading Data --- # %sapbdc% Zerocopy Connector — Security and Privileges - [Set Up SAP® BDC Connect for Snowflake Zerocopy Connector](/user-guide/data-integration/zero-copy/sap-sql/setup) - [Explore Data Products from SAP® BDC Connect for Snowflake](/user-guide/data-integration/zero-copy/sap-sql/explore-data-products) This topic describes the privileges required to create and manage a Zerocopy Connector and the catalog-linked databases created from it. ## Access Control Requirements A [role](#label-access-control-overview-roles) used to execute this operation must have the following [privileges](#label-access-control-overview-privileges) at a minimum:
For instructions on creating a custom role with a specified set of privileges, see [](#label-security-custom-role). For general information about roles and privilege grants for performing SQL actions on [securable objects](#label-access-control-securable-objects), see [Overview of Access Control](/user-guide/security-access-control-overview). ## Connector States A Zerocopy Connector transitions through the following states. Understanding the state is important because some operations are only permitted in specific states.
### State Transition Rules - `ALTER ... CONNECT` is permitted when the connector is in `NEW`, `CONNECT_ERROR`, or `DISCONNECTED` state. - `ALTER ... DISCONNECT` is permitted when the connector is in `CONNECTED` or `DISCONNECT_ERROR` state. - Share-back must be disabled before disconnecting. - All catalog-linked databases created from the connector must be dropped before disconnecting. - `DROP ZEROCOPY CONNECTOR` is permitted when the connector is in `NEW`, `CONNECT_ERROR`, `DISCONNECT_ERROR`, or `DISCONNECTED` state. - Catalog-linked databases do not support `UNDROP`. --- title: SAP® Snowflake source: https://docs.snowflake.cn/en/user-guide/data-integration/zero-copy/sap-sql/setup-sap-snowflake.md section: Loading & Unloading Data --- # SAP® Snowflake - [About Snowflake and SAP® Zero-Copy Integration](/user-guide/data-integration/zero-copy/about-sap-snowflake) - [Setup tasks for SAP® Snowflake and SAP® BDC Connect for Snowflake](/user-guide/data-integration/zero-copy/sap-sql/setup-tasks) - [SAP® BDC Connect for Snowflake](/user-guide/data-integration/zero-copy/sap-sql/setup-sap-bdc) This topic describes the steps to configure an instance for %sapsnowflake% for SAP customers without an existing Snowflake account. The SAP® Snowflake account provisioned is the Business Critical edition. SAP® BDC Connect for Snowflake is not available for Snowflake trial accounts. To request a SAP® Snowflake trial, please contact your SAP account executive, who can submit the request for trial through SAP's internal process for enterprise trials. As an SAP® administrator, perform the following steps: 1. Sign in to SAP for Me (https://me.sap.com/) with an S-user ID or login name. 2. From the sidebar menu, choose **Portfolio & products**. 3. In the **My Product Packages** tab, select the **SAP Business Data Cloud** product. 4. Select the **Applications** tab and in the **SAP Snowflake** card, click **Start Provisioning**.
The **Provision SAP® Snowflake** wizard dialog displays and guides you through the provisioning process. 5. In the Provision SAP® Snowflake dialog, configure the following parameters and click **Next**: - **Entitlement System**: Displays the ID of the SAP® Business Data Cloud Entitlement set. Cannot be changed. - **Name**: Enter an appropriate name for the SAP solution. - **Path**: Select or create a resource group under which to group the solution components provisioned for SAP® Business Data Cloud. Create it in the same location selected for the SAP® Business Data Cloud cockpit system. - **Business Type**: Preset to Production. 6. In the **Select Application** step, SAP Snowflake is pre-selected.
The **Configure Parameters** step displays. 7. In the **Configure Parameters** step, configure the following parameters and click **Next**: - **Region**: Choose an available region in the SAP for Me (https://me.sap.com/) portal. Snowflake recommends choosing the same region as the SAP® Business Data Cloud core for optimal performance. - **Admin email**: Provide the email address of the user to be defined as the administrator of your SAP Snowflake system. This user is responsible for adding additional users and for further configuration. - **Admin First Name**: The first name of the administrator of your SAP Snowflake system. - **Admin Last Name**: The last name of the administrator of your SAP Snowflake system. Provisioning begins and SAP® notifies you that a provisioning request was sent to the specified owner's e-mail address. 8. Click **View in Resources** to view the tenant within the indicated resource group. The **Resources** tab shows the current solution status, which should be `Processing`. 9. Select the tenant below the new solution and click **Details** to view the details of the tenant. 10. On top of the **details** view of the tenant, choose the **View Details** link. A pop-up window opens that provides an activation link to the SAP Snowflake account. If you are the SAP Snowflake system owner, select this link and complete the activation flow in SAP Snowflake (see Activating the SAP Snowflake Account (https://help.sap.com/docs/business-data-cloud/introducing-sap-snowflake/introducing-sap-snowflake)). If not, share the activation link with the SAP Snowflake owner and ask them to complete the activation flow. 11. After the account has been activated in SAP for Me, the status for your SAP Snowflake solution and tenant changes to `Ready`. In the details view of the SAP Snowflake tenant, in the Path field, select the URL to open SAP Snowflake and log in. ## Next steps The SAP® BDC admin may provision as many SAP® Snowflake accounts as they need with unique account names to help distinguish them. Every SAP® Snowflake account will need to be activated as described in the note below. After activation, the SAP® Snowflake is ready for you to share Data Products from SAP® BDC to SAP® Snowflake. As part of the provisioning process, a Zerocopy Connector called `DEFAULT_SAP_BDC_CONNECTOR` is automatically created under the `CONNECTORS.ZEROCOPY` schema and enrolled with SAP® Business Data Cloud in the SAP® Snowflake account. You are ready to share data products from SAP® BDC and consume them in SAP® Snowflake. For more information, see [Explore Data Products from SAP® BDC Connect for Snowflake](/user-guide/data-integration/zero-copy/sap-sql/explore-data-products). Customers can create additional Zerocopy Connectors in the same SAP® Snowflake account and enroll them with the same or different SAP® Business Data Cloud tenant. Each Zerocopy Connector requires a new Invitation Link that can be obtained from SAP for Me (https://me.sap.com/). Each Invitation Link can be enrolled only once with SAP® Business Data Cloud. Customers can view the status of provisioning in the **Details** view. After provisioning is complete, the customer can click the Snowflake activation link available in the Details view to activate their SAP® Snowflake account, login, change their username and reset their password, setup MFA, and perform other operations. --- title: ScanAttribute 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/scanattribute.md section: Loading & Unloading Data --- # ScanAttribute 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Scans the specified attributes of FlowFiles, checking to see if any of their values are present within the specified dictionary of terms ## Tags attributes, find, lookup, scan, search, text ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: ScanContent 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/scancontent.md section: Loading & Unloading Data --- # ScanContent 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Scans the content of FlowFiles for terms that are found in a user-supplied dictionary. If a term is matched, the UTF-8 encoded version of the term will be added to the FlowFile using the 'matching.term' attribute ## Tags aho-corasick, byte sequence, content, dictionary, find, scan, search ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: ScriptedFilterRecord 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/scriptedfilterrecord.md section: Loading & Unloading Data --- # ScriptedFilterRecord 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-scripting-nar ## Description This processor provides the ability to filter records out from FlowFiles using the user-provided script. Every record will be evaluated by the script which must return with a boolean value. Records with "true" result will be routed to the "matching" relationship in a batch. Other records will be filtered out. ## Tags filter, groovy, record, script ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Restrictions
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.script.ScriptedPartitionRecord](/user-guide/data-integration/openflow/processors/scriptedpartitionrecord) - [org.apache.nifi.processors.script.ScriptedTransformRecord](/user-guide/data-integration/openflow/processors/scriptedtransformrecord) - [org.apache.nifi.processors.script.ScriptedValidateRecord](/user-guide/data-integration/openflow/processors/scriptedvalidaterecord) --- title: ScriptedLookupService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/scriptedlookupservice.md section: Loading & Unloading Data --- # ScriptedLookupService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Allows the user to provide a scripted LookupService instance in order to enrich records from an incoming flow file. ## Tags groovy, invoke, lookup, record, script ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted ## Restrictions
## System Resource Considerations This component does not specify system resource considerations. --- title: ScriptedPartitionRecord 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/scriptedpartitionrecord.md section: Loading & Unloading Data --- # ScriptedPartitionRecord 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-scripting-nar ## Description Receives Record-oriented data (i.e., data that can be read by the configured Record Reader) and evaluates the user provided script against each record in the incoming flow file. Each record is then grouped with other records sharing the same partition and a FlowFile is created for each groups of records. Two records shares the same partition if the evaluation of the script results the same return value for both. Those will be considered as part of the same partition. ## Tags groovy, group, organize, partition, record, script, segment, split ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Restrictions
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.script.ScriptedFilterRecord](/user-guide/data-integration/openflow/processors/scriptedfilterrecord) - [org.apache.nifi.processors.script.ScriptedTransformRecord](/user-guide/data-integration/openflow/processors/scriptedtransformrecord) - [org.apache.nifi.processors.script.ScriptedValidateRecord](/user-guide/data-integration/openflow/processors/scriptedvalidaterecord) --- title: ScriptedReader source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/scriptedreader.md section: Loading & Unloading Data --- # ScriptedReader This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Allows the user to provide a scripted RecordReaderFactory instance in order to read/parse/generate records from an incoming flow file. ## Tags groovy, invoke, record, recordFactory, script ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted ## Restrictions
## System Resource Considerations This component does not specify system resource considerations. --- title: ScriptedRecordSetWriter source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/scriptedrecordsetwriter.md section: Loading & Unloading Data --- # ScriptedRecordSetWriter This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Allows the user to provide a scripted RecordSetWriterFactory instance in order to write records to an outgoing flow file. ## Tags groovy, invoke, record, script, writer ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted ## Restrictions
## System Resource Considerations This component does not specify system resource considerations. --- title: ScriptedRecordSink source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/scriptedrecordsink.md section: Loading & Unloading Data --- # ScriptedRecordSink This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Allows the user to provide a scripted RecordSinkService instance in order to transmit records to the desired target. The script must set a variable 'recordSink' to an implementation of RecordSinkService. ## Tags groovy, invoke, record, record sink, script ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted ## Restrictions
## System Resource Considerations This component does not specify system resource considerations. --- title: ScriptedTransformRecord 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/scriptedtransformrecord.md section: Loading & Unloading Data --- # ScriptedTransformRecord 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-scripting-nar ## Description Provides the ability to evaluate a simple script against each record in an incoming FlowFile. The script may transform the record in some way, filter the record, or fork additional records. See Processor's Additional Details for more information. ## Tags filter, groovy, modify, record, script, transform, update ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Restrictions
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.jolt.JoltTransformRecord](/user-guide/data-integration/openflow/processors/jolttransformrecord) - [org.apache.nifi.processors.script.ExecuteScript](/user-guide/data-integration/openflow/processors/executescript) - [org.apache.nifi.processors.standard.LookupRecord](/user-guide/data-integration/openflow/processors/lookuprecord) - [org.apache.nifi.processors.standard.QueryRecord](/user-guide/data-integration/openflow/processors/queryrecord) - [org.apache.nifi.processors.standard.UpdateRecord](/user-guide/data-integration/openflow/processors/updaterecord) --- title: ScriptedValidateRecord 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/scriptedvalidaterecord.md section: Loading & Unloading Data --- # ScriptedValidateRecord 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-scripting-nar ## Description This processor provides the ability to validate records in FlowFiles using the user-provided script. The script is expected to have a record as incoming argument and return with a boolean value. Based on this result, the processor categorizes the records as "valid" or "invalid" and routes them to the respective relationship in batch. Additionally the original FlowFile will be routed to the "original" relationship or in case of unsuccessful processing, to the "failed" relationship. ## Tags groovy, record, script, validate ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Restrictions
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.script.ScriptedFilterRecord](/user-guide/data-integration/openflow/processors/scriptedfilterrecord) - [org.apache.nifi.processors.script.ScriptedPartitionRecord](/user-guide/data-integration/openflow/processors/scriptedpartitionrecord) - [org.apache.nifi.processors.script.ScriptedTransformRecord](/user-guide/data-integration/openflow/processors/scriptedtransformrecord) --- title: SearchElasticsearch 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/searchelasticsearch.md section: Loading & Unloading Data --- # SearchElasticsearch 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-elasticsearch-restapi-nar ## Description A processor that allows the user to repeatedly run a paginated query (with aggregations) written with the Elasticsearch JSON DSL. Search After/Point in Time queries must include a valid "sort" field. The processor will retrieve multiple pages of results until either no more results are available or the Pagination Keep Alive expiration is reached, after which the query will restart with the first page of results being retrieved. ## Tags elasticsearch, elasticsearch7, elasticsearch8, elasticsearch9, json, page, query, scroll, search ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.elasticsearch.ConsumeElasticsearch](/user-guide/data-integration/openflow/processors/consumeelasticsearch) - [org.apache.nifi.processors.elasticsearch.PaginatedJsonQueryElasticsearch](/user-guide/data-integration/openflow/processors/paginatedjsonqueryelasticsearch) --- title: Second generation Openflow objects and interfaces source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/gen2/index.md section: Loading & Unloading Data --- # Second generation Openflow objects and interfaces Available to all accounts. Gen 2 Openflow is available on AWS and Azure. GCP support isn't available yet. - [Openflow gen 1 and gen 2](/user-guide/data-integration/openflow/gen2/openflow-generations) - [About Openflow](/user-guide/data-integration/openflow/about) - [Configure a connector with the setup wizard](/user-guide/data-integration/openflow/gen2/setup-connector-wizard) - [Configure a gen 2 connector with SQL](/user-guide/data-integration/openflow/gen2/configure-connector-sql) - [Manage the gen 2 Openflow connector lifecycle](/user-guide/data-integration/openflow/gen2/manage-connector-lifecycle) Second-generation (**gen 2**) Openflow **deployments**, **runtimes**, and **connectors** are first-class Snowflake objects. You can use the Openflow UI or SQL commands to work with the same underlying objects. Gen 1 and gen 2 resources can coexist in the same account: - **New deployments are gen 2 only.** You can no longer create new gen 1 deployments (BYOC or Snowflake). All new deployments must use `CREATE OPENFLOW DEPLOYMENT`. - **Runtimes inherit the generation of their parent deployment.** New runtimes on a gen 1 deployment are gen 1; new runtimes on a gen 2 deployment are gen 2. - **Gen 2 runtimes support both gen 1 and gen 2 connectors.** Both types can coexist on the same gen 2 runtime. - **Gen 1 runtimes support gen 1 connectors only.** Don't install gen 2 connectors on a gen 1 runtime. - **Existing gen 1 resources stay gen 1** and continue to work unchanged. Migration from gen 1 to gen 2 is available in Private Preview; contact your Snowflake account representative to be included. Gen 2 introduces SQL-first lifecycle management, a revised security model, and connectors managed as [File Based Entities (FBEs)](/user-guide/data-integration/openflow/gen2/connector-versioning) with versioned configuration. ## Start here If you are new to gen 2 Openflow, read these topics in order: 1. [Openflow gen 1 and gen 2](/user-guide/data-integration/openflow/gen2/openflow-generations) — Understand gen 1 vs gen 2 for deployments, runtimes, and connectors, and which documentation set applies to each. 2. [About Openflow](/user-guide/data-integration/openflow/about) — Review Openflow concepts shared by gen 1 and gen 2 (deployment types, architecture, use cases). 3. [Quickstart: gen 2 Openflow](/user-guide/data-integration/openflow/gen2/quickstart) — Set up privileges and create your first gen 2 deployment, runtime, and connector. 4. **Migrating from gen 1?** Migration from gen 1 to gen 2 is available in Private Preview; contact your Snowflake account representative to be included. 5. [Configure a connector with the setup wizard](/user-guide/data-integration/openflow/gen2/setup-connector-wizard) — Install and configure a gen 2 connector with the setup wizard. 6. [Configure a gen 2 connector with SQL](/user-guide/data-integration/openflow/gen2/configure-connector-sql) — Create and configure a gen 2 connector with SQL and stage commands. ## Known limitations For how gen 2 differs from gen 1 in supported operations and lifecycle, see [Openflow gen 1 and gen 2](/user-guide/data-integration/openflow/gen2/openflow-generations). **Preview quotas** - **BYOC deployments:** At most 20 per account (enforced by Openflow and Snowflake). - **Snowflake deployments:** At most three per account. - **Runtimes:** At most 100 per deployment. You can hit other limits before that maximum—for example, 50 EC2 nodes per node type on a BYOC deployment, or block storage quota on a Snowflake deployment when other applications consume storage. - A runtime can have at most 50 nodes. This applies to both generations (BYOC node groups and Snowflake deployment compute pools). **Diagnostics** - Gen 2 runtime diagnostic bundles can be created from SQL or the Openflow UI. Snowflake **deployment** diagnostic bundles (not scoped to a single runtime) are also supported from SQL. For BYOC troubleshooting, you can also run `./diagnostics.sh` on the deployment agent instance; see [Troubleshoot Openflow](/user-guide/data-integration/openflow/troubleshoot). **Operations shared with gen 1** - `GRANT OWNERSHIP` on gen 2 deployments, runtimes, or connectors can break underlying functionality today. Avoid ownership transfer until an upcoming update; see [Transferring OWNERSHIP](#label-openflow-generations-ownership-transfer) in [Openflow gen 1 and gen 2](/user-guide/data-integration/openflow/gen2/openflow-generations). - For BYOC deployments, installation and upgrade documentation can only be downloaded from the UI; upgrades are not automatic. See [Manage Openflow](/user-guide/data-integration/openflow/manage). **Setup wizard** - Private link is not supported in the setup wizard flow. Private link for deployments and runtime UI access is supported separately; see [Set up PrivateLink UI access in Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/setup-openflow-spcs-configure-pr-ui). ## Gen 2 documentation
## Gen 1 documentation Gen 1 Openflow resources continue to use the public Openflow documentation. When you work with gen 1 deployments, runtimes, or catalog-installed connectors, follow these topics: - [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) and [Set up Openflow - Snowflake Deployment - Task overview](/user-guide/data-integration/openflow/setup-openflow-spcs) — Create gen 1 deployments. - [Set up Openflow - Snowflake Deployment: Create runtime](/user-guide/data-integration/openflow/setup-openflow-spcs-create-runtime) — Create gen 1 runtimes. - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) — Install and configure gen 1 connectors with **Install** or **Import from Registry** on the runtime canvas. - [Manage Openflow](/user-guide/data-integration/openflow/manage) — Manage gen 1 deployments and runtimes in the UI. For source-specific setup (for example, preparing PostgreSQL for CDC), use the connector setup topic in the public docs for gen 1 and gen 2 connectors alike. Gen 2 connector topics link to those instructions where the source configuration is the same. --- title: SegmentContent 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/segmentcontent.md section: Loading & Unloading Data --- # SegmentContent 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Segments a FlowFile into multiple smaller segments on byte boundaries. Each segment is given the following attributes: fragment.identifier, fragment.index, fragment.count, segment.original.filename; these attributes can then be used by the MergeContent processor in order to reconstitute the original FlowFile ## Tags segment, split ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.standard.MergeContent](/user-guide/data-integration/openflow/processors/mergecontent) --- title: Set up and access Openflow source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/setup-openflow-roles-login.md section: Loading & Unloading Data --- # Set up and access Openflow This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions). - [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) - [Set up Openflow - Snowflake Deployment - Task overview](/user-guide/data-integration/openflow/setup-openflow-spcs) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index) To use Openflow, you must configure roles and permissions in your Snowflake account, and set up a database. This topic describes how to set up the necessary roles and permissions. Openflow isn't automatically available in trial accounts. To enable it, contact your Snowflake account team. ## Set up the Openflow admin roles The **Openflow Admin role** is used by a deployment engineer to set up Openflow workflows. A Snowflake administrator adds this role by performing the following steps: 1. Sign in to %sf-web-interface-link%. 2. Open a SQL worksheet. 3. Create a role for the Openflow admin, allowing it the required permissions to manage integrations and compute pools required for deployments. In the SQL below, OPENFLOW_ADMIN is the default name for the Openflow admin, but you can choose any name. ```sql USE ROLE ACCOUNTADMIN; CREATE ROLE IF NOT EXISTS OPENFLOW_ADMIN; GRANT CREATE ROLE ON ACCOUNT TO ROLE OPENFLOW_ADMIN; -- Gen 2 privileges: GRANT CREATE OPENFLOW DEPLOYMENT ON ACCOUNT TO ROLE OPENFLOW_ADMIN; GRANT CREATE DATABASE ON ACCOUNT TO ROLE OPENFLOW_ADMIN; GRANT CREATE INTEGRATION ON ACCOUNT TO ROLE OPENFLOW_ADMIN; -- Gen 1 privileges (instead of the gen 2 grants above): -- GRANT CREATE OPENFLOW DATA PLANE INTEGRATION ON ACCOUNT TO ROLE OPENFLOW_ADMIN; -- GRANT CREATE OPENFLOW RUNTIME INTEGRATION ON ACCOUNT TO ROLE OPENFLOW_ADMIN; -- GRANT CREATE INTEGRATION ON ACCOUNT TO ROLE OPENFLOW_ADMIN; ``` 4. Grant the admin role and secondary roles to a user. To prevent issues with login, when you create an Openflow user, Snowflake recommends that you also assign and set default secondary roles to that user. This is helpful because Openflow doesn't allow users with the following roles to log in: ACCOUNTADMIN, ORGADMIN, GLOBALORGADMIN, or SECURITYADMIN. While logged in, Openflow actions can be authorized by any of the authenticated user's roles, not just the default role. Substitute <OPENFLOW_USER> with the appropriate username: ```sql USE ROLE ACCOUNTADMIN; GRANT ROLE OPENFLOW_ADMIN TO USER ; ALTER USER SET DEFAULT_ROLE = OPENFLOW_ADMIN; ALTER USER SET DEFAULT_SECONDARY_ROLES = ('ALL'); ``` ## Accept the Openflow terms of service This step is only required once for your organization. 1. Sign in to Snowflake as a user with the ORGADMIN role. 2. In the navigation menu, select **Ingestion** %raa% **Openflow**. 3. Review the agreement and select **Accept**. ## Start Openflow Log in to Openflow by performing the following steps: 1. Sign in to %sf-web-interface-link%. 2. In the navigation menu, select **Ingestion** %raa% **Openflow**. 3. Select **Launch Openflow**. ### Troubleshooting login issues - If you can log into Snowflake but can't log into Openflow, try the following: - Try changing your role to something other than ACCOUNTADMIN, ORGADMIN, GLOBALORGADMIN, or SECURITYADMIN. - Try adding default secondary roles to the account: ```sql USE ROLE ACCOUNTADMIN; ALTER USER SET DEFAULT_SECONDARY_ROLES = ('ALL'); ``` --- title: Set up Openflow - BYOC source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/setup-openflow-byoc.md section: Loading & Unloading Data --- # Set up Openflow - BYOC This feature is not available in the People's Republic of China. Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions). - [About Openflow: BYOC deployments](/user-guide/data-integration/openflow/about-byoc) - [Openflow BYOC - Set up custom ingress](/user-guide/data-integration/openflow/setup-openflow-byoc-custom-ingress) - [Openflow BYOC - Set up encrypted EBS volumes](/user-guide/data-integration/openflow/setup-openflow-byoc-encrypted-volumes) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Monitor Openflow using telemetry data](/user-guide/data-integration/openflow/monitor) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) This topic describes the steps to set up Openflow. Setting up Openflow involves the following steps: - [Create an Openflow deployment](#create-an-openflow-deployment) - [Create an Openflow runtime](#create-an-openflow-runtime) ## Prerequisites The prerequisites to be completed on your Snowflake and AWS accounts are as follows: ### Snowflake account First, grant the required privileges to the Openflow admin at the account level. 1. Run the following SQL commands to grant the required privileges to the Openflow admin. For help choosing a generation, see [Openflow gen 1 and gen 2](/user-guide/data-integration/openflow/gen2/openflow-generations). **Gen 2:** ```sql USE ROLE ACCOUNTADMIN; GRANT CREATE OPENFLOW DEPLOYMENT ON ACCOUNT TO ROLE openflow_admin; GRANT CREATE DATABASE ON ACCOUNT TO ROLE openflow_admin; -- Run these two after creating the database and schema for gen 2 objects: -- GRANT CREATE OPENFLOW RUNTIME ON SCHEMA . TO ROLE openflow_admin; -- GRANT CREATE OPENFLOW CONNECTOR ON SCHEMA . TO ROLE openflow_admin; ``` **Gen 1:** ```sql USE ROLE ACCOUNTADMIN; GRANT CREATE OPENFLOW DATA PLANE INTEGRATION ON ACCOUNT TO ROLE openflow_admin; GRANT CREATE OPENFLOW RUNTIME INTEGRATION ON ACCOUNT TO ROLE openflow_admin; ``` These privileges are assigned to the ACCOUNTADMIN role as part of the default set of privileges, and that role can grant the privileges to a role of their choosing for the Openflow admin, denoted as `openflow_admin` in the code. 2. Next, set `default_secondary_roles` to `ALL` for all Openflow users: 1. Sign in to Snowflake and switch to a role that your account admin has set up for using Openflow, for example `openflow_admin`. This may not be any of the following roles: ACCOUNTADMIN, ORGADMIN, GLOBALORGADMIN, or SECURITYADMIN. If you see a blank screen or the error "message: Invalid consent request" when logging into Openflow, change your role to a role that is not one of these listed roles. For more information, see [Prerequisites](#prerequisites). 2. Run the following code, replacing `` for each Openflow user: ```sql USE ROLE ACCOUNTADMIN; ALTER USER SET DEFAULT_SECONDARY_ROLES = ('ALL'); ``` This setting is required because Openflow actions are authorized by using any of the authenticated user's roles, and not just the default role. #### Deployment privileges The deployment object represents a set of resources provisioned to deploy one or more Snowflake Openflow runtimes. For organizations bringing their own cloud resources, the deployment represents a managed Kubernetes cluster along with its associated nodes. Users with `CREATE OPENFLOW DATA PLANE INTEGRATION` (gen 1) or `CREATE OPENFLOW DEPLOYMENT` (gen 2) on the account can create deployment objects. Additional privileges can be defined on deployment objects directly to support differentiation of access. You can grant the following privileges on a deployment object: - OWNERSHIP: Enables full control over deployment actions, including deletion of the deployment. - USAGE: Enables creation of runtime child objects. #### Runtime privileges The runtime object represents a cluster of one or more Snowflake Openflow runtime servers, provisioned to run flow definitions. For Kubernetes deployments, the runtime object represents a stateful set of Snowflake Openflow runtime containers deployed in a namespace, along with supporting components. Users with the OWNERSHIP privilege on the parent deployment object and the `CREATE OPENFLOW RUNTIME INTEGRATION` (gen 1) or `CREATE OPENFLOW RUNTIME` (gen 2) privilege can create runtimes. Additional privileges can be defined on runtime objects directly. You can grant the following privileges on a runtime object: - OWNERSHIP: Enables full control over runtime actions, including deletion of the associated runtime and modification of runtime flow definitions. - USAGE: Enables write access to the deployed runtime, including creating and modifying connectors and flow definitions. - MONITOR: Enables read-only access to the deployed runtime for observing health and status, without making any changes. #### Execute-as role An execute-as role is a Snowflake role bound to a specific Openflow runtime. Connectors that use `SNOWFLAKE_MANAGED` authentication run with this role's privileges (or those of a child role granted to it). The execute-as role is used for the following tasks: - Grant access to Snowflake resources. - Grant access to connector-specific resources. Because execute-as roles are linked to Openflow managed tokens, you don't need to create separate service users and key pairs for authentication to Snowflake. <RUNTIME_NAME> denotes the name of the associated runtime. To create an execute-as role: 1. Create the role. ```sql USE ROLE ACCOUNTADMIN; CREATE ROLE IF NOT EXISTS OPENFLOW__EXECUTE_AS_RL; ``` 2. Grant the execute-as role access to a warehouse. Snowflake recommends using a dedicated warehouse for data ingestion. This warehouse should be used when configuring your connectors for runtimes where you use this execute-as role. ```sql GRANT USAGE, OPERATE ON WAREHOUSE TO ROLE OPENFLOW__EXECUTE_AS_RL; ``` 3. Allow the execute-as role to use, create, or otherwise access Snowflake objects.
Depending on the Openflow connector being created, the required underlying objects vary. The example below is for illustration purposes only.
```sql GRANT USAGE ON DATABASE TO ROLE OPENFLOW__EXECUTE_AS_RL; GRANT USAGE ON SCHEMA TO ROLE OPENFLOW__EXECUTE_AS_RL; ``` 4. Allow the user to use the execute-as role. ```sql GRANT ROLE OPENFLOW__EXECUTE_AS_RL TO USER ; ``` #### Example for role setup Consider a scenario where the following roles should be set up: - **accountadmin:** Out-of-the box role from Snowflake, which has these CREATE privileges: - CREATE OPENFLOW DATA PLANE INTEGRATION (gen 1) / CREATE OPENFLOW DEPLOYMENT (gen 2) - CREATE OPENFLOW RUNTIME INTEGRATION (gen 1) / CREATE OPENFLOW RUNTIME (gen 2, on schema) - **openflow_admin:** Can create, manage, and delete deployments. - **deployment1_runtime_manager_1:** Can create a runtime only within deployment 1. It can modify and delete a runtime that it created within deployment 1, but not a runtime created by deployment1_runtime_manager_2. - **deployment1_runtime_manager_2:** Can create a runtime only within deployment 1. It can modify and delete a runtime that it created within deployment 1, but not a runtime created by deployment1_runtime_manager_1. - **deployment1_runtime_viewer_1:** Can view a runtime canvas within deployment 1 that was created by deployment1_runtime_manager_1. - **deployment1_runtime_viewer_2:** Can view a runtime canvas within deployment 1 that was created by deployment1_runtime_manager_2. - **deployment2_runtime_manager:** Can create a runtime only within deployment 2. - **deployment2_runtime_viewer:** Can view a runtime canvas within deployment 2. To set up Openflow with these roles, follow these steps: 1. Create new roles and assign the relevant privileges: ```sql use role ACCOUNTADMIN; create role if not exists openflow_admin; create role if not exists deployment1_runtime_manager_1; create role if not exists deployment1_runtime_manager_2; create role if not exists deployment1_runtime_viewer_1; create role if not exists deployment1_runtime_viewer_2; create role if not exists deployment2_runtime_manager; create role if not exists deployment2_runtime_viewer; -- Assign create deployment privilege to roles. (This privilege cannot be granted in Openflow UI.) -- Gen 2: -- grant create openflow deployment on account to role openflow_admin; -- Gen 1: grant create openflow data plane integration on account to role openflow_admin; -- Assign create runtime privilege to roles. (This privilege cannot be granted in the Control Plane UI.) -- Gen 1: grant create openflow runtime integration on account to role deployment1_runtime_manager_1; grant create openflow runtime integration on account to role deployment1_runtime_manager_2; grant create openflow runtime integration on account to role deployment2_runtime_manager; -- Grant roles to users. (Repeat this step for each user.) grant role to user ; ``` 2. To create a deployment, follow these steps: 1. Sign in to Snowsight as openflow_admin. 2. In the navigation menu, select **Ingestion** %raa% **Openflow**. 3. To create deployment 1, select **Create a deployment**, and grant the USAGE privilege to deployment1_runtime_manager_1 and deployment1_runtime_manager_2. 4. To create deployment 2, select **Create a deployment**, and grant the USAGE privilege to deployment2_runtime_manager. 3. To create a runtime in deployment 1, follow these steps: 1. Log in as deployment1_runtime_manager_1. 2. Create a runtime as described in the following sections. deployment1_runtime_manager_1 should be able to create runtimes and manage any runtimes it created within this deployment. 3. In the Openflow UI, select deployment1_runtime_viewer_1 and grant it the USAGE privilege. ### AWS account Ensure the following on your AWS account: - You have an AWS account with permissions required to create a CloudFormation stack. - An AWS administrator in your organization can execute CloudFormation script to set up Amazon Elastic Kubernetes Service (EKS) inside a new VPC (created by CloudFormation) or an existing VPC. See [Prerequisites for BYO-VPC (existing VPC)](#prerequisites-for-byo-vpc-existing-vpc). To learn about how the Openflow installation happens in your AWS account and the permissions that are configured by the CloudFormation template, see [Installation process](#installation-process). #### Prerequisites for BYO-VPC (existing VPC) If you want to use an existing VPC and your own subnets, ensure that you have the following: - For Snowflake managed ingress, two public subnets with:
- Different availability zones - At least /27 CIDR ranges with 32 available IPs. - Routes for destination 0.0.0.0/0 and target internet gateway or some other egress routing to the internet. - A tag that allows Openflow to create a load balancer: - Key: `kubernetes.io/role/elb` - Value: `1` - If your public subnets are used by other EKS clusters, a tag that allows Openflow to create a load balancer alongside other load balancers: - Key: `kubernetes.io/cluster/{deployment-key}` - Value: `1` Managing your own ingress eliminates the need for public subnets, but requires additional configuration in your AWS account. For more information, see [Openflow BYOC - Set up custom ingress](/user-guide/data-integration/openflow/setup-openflow-byoc-custom-ingress).
- Two private subnets with: - Different availability zones - At least /24 CIDR ranges with 255 available IPs. This limits the number and scale of runtimes you can create, so it may be more appropriate to use a larger range for the deployment. - Connectivity to Snowflake and AWS services from Private Subnet 1 where the Openflow deployment runs. - Among many options, you can connect using route tables with a NAT Gateway, a Transit Gateway, or PrivateLink VPC Endpoints. - Without this connectivity, the Openflow deployment will not initialize or set up properly and no infrastructure will be provisioned. - For Snowflake managed ingress, ensure that your private subnets have egress connectivity for TLS certificate provisioning. Cert-manager uses DNS-01 validation, which requires: - HTTPS (port 443) to the Let's Encrypt ACME API at `acme-v02.api.letsencrypt.org` - DNS resolution of `snowflake-customer.app` and its subdomains. Your network must be able to resolve these names, either through a NAT Gateway with public DNS access or a private DNS resolver configured to cover the `snowflake-customer.app` domain. - A NAT Gateway or similar egress path from the private subnets. If your security groups or network ACLs restrict outbound traffic, ensure they allow these destinations. If your VPC has no public internet egress, use [custom ingress](/user-guide/data-integration/openflow/setup-openflow-byoc-custom-ingress) instead of Snowflake managed ingress. Custom ingress eliminates the Let's Encrypt dependency. See [Configuring private deployments](#configuring-private-deployments). ## Accept the Openflow terms of service This step is only required once for your organization. 1. Sign in to Snowflake as a user with the ORGADMIN role. 2. In the navigation menu, select **Ingestion** %raa% **Openflow**. 3. Accept the Openflow terms of service. If you don't see this option, the terms have already been accepted for your organization. ## Create an Openflow deployment ### Configure the deployment in your Snowflake account Sign in to Snowflake and switch to a role that your account admin has set up for using Openflow, for example `openflow_admin`. This may not be any of the following roles: ACCOUNTADMIN, ORGADMIN, GLOBALORGADMIN, or SECURITYADMIN. If you see a blank screen, or the error: "message: Invalid consent request", when logging into Openflow, change your role to a role that is not one of these listed roles. For more information, see [Prerequisites](#prerequisites). 1. In the navigation menu, select **Ingestion** %raa% **Openflow**. 2. Select **Launch Openflow**. 3. In the Openflow UI, select **Create a deployment**. 4. On the **Deployments** tab, select **Create a deployment**. The **Creating a deployment** wizard opens. 5. In the **Prerequisites** step, ensure that you meet all the requirements, and then select **Next**. 6. In the **Deployment location** step, select **Amazon Web Services** as the deployment location, enter a name for your deployment, and then select **Next**. 7. In the **Configuration** step, select one of the following options: - **Managed VPC**: Choose this option if you want your VPC to be managed by Snowflake. - **Bring your own VPC**: Choose this option if you want to use an existing VPC. 1. In the **PrivateLink** step, you can select if you want to establish communication with Snowflake over the private link. Enabling this option requires additional setup in your AWS account. For more information, see [AWS PrivateLink and Snowflake](/user-guide/admin-security-privatelink). - If the **PrivateLink** option is enabled, the **End user authentication over PrivateLink** step displays. - If enabled, browser-based authentication redirects use PrivateLink endpoints. - If disabled, end-user authentication uses public Snowflake URLs. Regardless of this setting, Deployment communications to Snowflake will use PrivateLink. If you access %sf-web-interface% through a PrivateLink URL, ensure it is enabled. If you access %sf-web-interface% through a non-PrivateLink URL, leave it disabled. 2. In the **Custom Ingress** step, you can choose to manage your own ingress configuration for the Openflow deployment, such as specifying custom security groups, load balancer settings, or other network controls. Enabling this option requires additional setup in your AWS account. For more information, see [Openflow BYOC - Set up custom ingress](/user-guide/data-integration/openflow/setup-openflow-byoc-custom-ingress). 3. Select **Create Deployment**. 4. Once your deployment is configured, a dialog box appears that lets you download the CloudFormation template to complete the setup process in your AWS account. Download this template. Note that Openflow doesn't support modifying the CloudFormation template. Don't modify any values after downloading the template, other than choosing drop-down options. 5. (Optional) To encrypt EBS volumes for your Openflow BYOC deployment, see [Openflow BYOC - Set up encrypted EBS volumes](/user-guide/data-integration/openflow/setup-openflow-byoc-encrypted-volumes). ### Apply the CloudFormation template in your AWS account 1. In your AWS account, create a new CloudFormation Stack using the template. After the Openflow deployment agent's Amazon Elastic Compute Cloud (EC2) instance is created, it completes the rest of the [Installation process](#installation-process) using infrastructure as code scripts. You can track the installation progress as described in [Track the installation progress](#track-the-installation-progress). If you're using an existing VPC, upon uploading the CloudFormation template, select the respective values in the drop-down lists for the two private subnets and your VPC. ### Create a network rule for Openflow in your Snowflake account This step is required only if you're using network policies to control access to Snowflake. A network policy is a set of rules that control which IP addresses can access your Snowflake account. 1. Navigate to your Snowflake account. 2. Identify the NAT gateway public IP address that was created as part of the CloudFormation stack. You can find this either by searching for NAT Gateway on AWS console or checking the output of the CloudFormation stack. The NAT gateway is responsible for Openflow egress for both the Data Plane Agent (DPA) and EKS. Both DPA and EKS run in the Private Subnet 1 of the installation. 3. Create a network rule for Openflow and add it to your existing network policy. Replace \{$NAT_GATEWAY_PUBLIC_IP\} in the following code snippet with the NAT gateway public IP address that was created as part of the CloudFormation stack. ```sql USE ROLE ACCOUNTADMIN; USE DATABASE ; USE SCHEMA ; CREATE NETWORK RULE allow_openflow_deployment MODE = INGRESS TYPE = IPV4 VALUE_LIST = ('{$NAT_GATEWAY_PUBLIC_IP}/32'); ``` 4. Find your currently active network policy. ```sql SHOW PARAMETERS LIKE 'NETWORK_POLICY' IN ACCOUNT; ``` 5. Copy the value column from the output, and use it to create a network rule: ```sql ALTER NETWORK POLICY {ENTER_YOUR_ACTIVE_NETWORK_POLICY_NAME} ADD ALLOWED_NETWORK_RULE_LIST = (allow_openflow_deployment); ``` ### [Optional] Configure an Openflow-specific event table Openflow generates logs and metrics and sends them to the Snowflake Event Table. For helpful queries to analyze this telemetry data, see [Monitor Openflow](/user-guide/data-integration/openflow/monitor). By default, Openflow uses the [account event table](/developer-guide/logging-tracing/event-table-setting-up#label-logging-event-table-default) (SNOWFLAKE.TELEMETRY.EVENTS), but you can configure an Openflow-specific event table per deployment. A dedicated event table is recommended to optimize query performance, enable granular access control, and simplify Openflow monitoring and maintenance. Use one of the following options: - Create an Openflow-specific event table: ```sql USE ROLE ACCOUNTADMIN; USE DATABASE ; USE SCHEMA ; GRANT CREATE EVENT TABLE ON SCHEMA . TO ROLE ; USE ROLE ; CREATE EVENT TABLE IF NOT EXISTS ..openflow_events; -- Find the deployment (gen 2: SHOW OPENFLOW DEPLOYMENTS; gen 1: SHOW OPENFLOW DATA PLANE INTEGRATIONS) SHOW OPENFLOW DEPLOYMENTS; -- Set event table (gen 2: ALTER OPENFLOW DEPLOYMENT; gen 1: ALTER OPENFLOW DATA PLANE INTEGRATION) ALTER OPENFLOW DEPLOYMENT SET EVENT_TABLE = '..openflow_events'; ``` - Use an existing account-specific event table: ```sql USE ROLE ACCOUNTADMIN; ALTER ACCOUNT SET EVENT_TABLE = 'existing_database.existing_schema.existing_event_table'; ``` ### Verify the deployment 1. In the navigation menu, select **Ingestion** %raa% **Openflow**. Creating a deployment takes about 45 minutes on AWS. Once it's created, you can view your deployment in the Deployments tab of Openflow UI with its state marked as **Active**. ## Create an Openflow runtime 1. In **Openflow Control Plane**, select **Create a runtime**. The **Create Runtime** dialog box appears. 2. From the **Deployment** drop-down list, choose the deployment in which you want to create a runtime. 3. Enter a name for your runtime. 4. Choose a node type from the **Node type** drop-down list. This specifies the size of your nodes. For guidance on choosing a size and node count, see [Runtime sizing and packing for CDC connectors](/user-guide/data-integration/openflow/connectors/cdc-runtime-sizing). 5. In the **Min/Max node** range selector, select a range. The minimum value specifies the number of nodes that the runtime starts with when idle and the maximum value specifies the number of nodes that the runtime can scale up to, in the event of high data volume or CPU load. 6. Select **Create**. The runtime takes a couple of minutes to get created. Once created, you can view your runtime by navigating to the **Runtimes** tab of the Openflow control plane. Click the runtime to open the Openflow canvas. ## Next step Deploy a connector in a runtime. For a list of connectors available in Openflow, see [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors). ## Networking considerations: Openflow EKS to source systems For BYOC deployments, take note of the following considerations: - Openflow CloudFormation stack creates one VPC with two public subnets and two private subnets. - Public subnets host the AWS Network Load Balancer, which is created later. Private subnets host the EKS Cluster and all of the EC2 instances backing the node groups. Openflow runtimes run within Private subnet 1. - NAT Gateway is currently the egress for both DPA and EKS. Both DPA and EKS run in the Private subnet 1 of the installation. For BYO-VPC deployments, take note of the following considerations: - Openflow requires you to enter the two private subnets that will run Openflow and two public subnets for the AWS Load Balancer. - You have to provide your own egress routing to the Internet from those private subnets, which can be the central NAT Gateway. - No Internet Gateway is created by Openflow. You have to provide appropriate public internet egress routing. The network connectivity generally is as follows: **An Openflow EC2 Instance** (Agent or EKS) runs in a **private subnet** that requires **Route Table entries** to send egress traffic to a **Transit Gateway**, a **PrivateLink VPC Endpoint**, or a **NAT Gateway** connected to an **Internet Gateway**. ### Example: BYOC deployment with a new VPC to communicate with RDS in a different VPC of the same account To enable communication between the Openflow EKS cluster and the RDS instance, you need to create a new security group, with the EKS cluster security group as the source for the inbound rule for RDS connectivity, and attach the group in RDS. 1. Find the EKS cluster security group, navigate to EKS and find your deployment key. You can also find it on the Openflow UI by performing the following steps: 1. Sign in to Openflow. 2. Go to the **Deployments** tab. 3. Select the More options icon next to your deployment. 4. Select **View details**. The value in the field **Key** is your deployment key. 2. After finding the deployment key, you can use it to filter your AWS resources by the key value. 3. Create a new security group that allows access from the Openflow EKS cluster using the relevant database port. For PostgreSQL the default port is 5432. 4. Attach it in RDS as a new security group. If you need to troubleshoot, the Reachability Analyzer (https://docs.aws.amazon.com/vpc/latest/reachability/getting-started.html) can be useful. It will give you detailed information about what may be blocking connectivity by using tracing capabilities within the AWS platform. See the following AWS docs for accessing DB instances using VPC peering and the associated security group configuration: - Scenarios for accessing a DB instance in a VPC - Amazon Relational Database Service (https://docs.aws.amazon.com/AmazonRDS/latest/UserGuide/USER_VPC.Scenarios.html#USER_VPC.Scenario3) - Update your security groups to reference peer security groups - Amazon Virtual Private Cloud (https://docs.aws.amazon.com/vpc/latest/peering/vpc-peering-security-groups.html) ## Configuring PrivateLink in AWS This section explains how to access and configure Openflow using private connectivity. ### Access Openflow over PrivateLink Before starting with the private link configuration, enable PrivateLink for your account as described in [AWS PrivateLink and Snowflake](/user-guide/admin-security-privatelink). 1. Using the `ACCOUNTADMIN` role, call the `SYSTEM$GET_PRIVATELINK_CONFIG` function in your Snowflake account and identify the value for `openflow-privatelink-url`. This is the URL for accessing Openflow over PrivateLink. 2. Create a `CNAME` record in your DNS to resolve the URL value to your VPC endpoint. 3. Confirm that your DNS settings can resolve the value. 4. Confirm that you can connect to Openflow UI using this URL from your browser. ### Configure a new deployment using PrivateLink Snowflake recommends that you use the **Bring your own VPC** version of Openflow deployment and create a VPC endpoint in your VPC before applying the CloudFormation template. Before starting with the PrivateLink configuration, make sure that PrivateLink is enabled for your account as described in [AWS PrivateLink and Snowflake](/user-guide/admin-security-privatelink). Perform the following steps: 1. Retrieve Snowflake's VPC endpoint service ID and Openflow PrivateLink URLs: 1. Run the following SQL command using the `ACCOUNTADMIN` role: ```sql SELECT SYSTEM$GET_PRIVATELINK_CONFIG() ``` 2. From the output, identify and save the values for the following keys: - `privatelink-vpce-id` - `openflow-privatelink-url` - `external-telemetry-privatelink-url` 2. Create a VPC endpoint with parameters: - Type: **PrivateLink Ready partner services** - Service: `privatelink-vpce-id` value obtained in the previous step. - VPC: The VPC where your Openflow deployment will be running. - Subnets: Select two availability zones and private subnets where your Openflow deployment will be running. 3. Set up Route 53 private hosted zone with the following parameters: 1. Domain: `privatelink.snowflakecomputing.cn` 2. Type: **Private hosted zone** 3. Select the region and VPC where your Openflow deployment will be running. 4. Add two `CNAME` records for the URLs identified in the first step: 1. For `openflow-privatelink-url` - Record name: `openflow-privatelink-url` value obtained in the first step - Record type: `CNAME` - Value: DNS name of your VPC endpoint 2. For `external-telemetry-privatelink-url` - Record name: `external-telemetry-privatelink-url` value obtained in the first step - Record type: `CNAME` - Value: DNS name of your VPC endpoint 5. Create a dedicated security group for the deployment and enable traffic from the security group to the VPC endpoint: 1. Open the security group associated with your VPC endpoint. 2. Add an inbound rule to the security group that allows **All traffic** from the security group created for your deployment. 6. Create a new deployment and apply the CloudFormation Stack following the instructions in the [Create an Openflow deployment](#create-an-openflow-deployment) section and ensure that: - The **PrivateLink** option is enabled. The **End user authentication over PrivateLink** option can be either enabled or disabled. - The security group created for the deployment is used when creating the CloudFormation stack. 7. Wait until the EKS cluster for your deployment is created. To confirm successful creation, navigate to AWS Console under **Elastic Kubernetes Service**. Verify that a cluster identified as `` displays status **ACTIVE**. 8. Allow for traffic from your EKS to the VPC endpoint: 1. Open the security group associated with your VPC endpoint. 2. Add an inbound rule to the security group that allows **All traffic** from the security group assigned to your EKS cluster. The EKS cluster's security group starts with `eks-cluster-sg--`. ### Configuring VPC Gateway Endpoints for S3 in AWS Configuring an AWS VPC Gateway Endpoint for S3 is the primary method to allow an Agent EC2 instance in a private subnet to access the Amazon Linux 2023 repository privately, without requiring an Internet Gateway, a NAT Gateway, or a public IP address on the instance. The Agent EC2 instance uses this repository to install its dependencies, for instance Docker. To configure a VPC Gateway Endpoint for S3: 1. Open a browser to the AWS VPC dashboard. 2. In the navigation pane, select **Endpoints**. 3. Click **Create endpoint** and create a new VPC endpoint with parameters: - Type: **AWS services** - Service: `com.amazonaws..s3` of type `Gateway` - VPC: Select the VPC of your deployment - Route tables: Select the route table(s) that are associated with your private subnet(s) - Policy: Choose **Full access** ## Configuring private deployments Private deployments are a feature that allows you to deploy Openflow in a VPC without the need for public internet ingress or egress. Private deployments must use custom ingress. Snowflake managed ingress requires DNS resolution of `snowflake-customer.app` subdomains and HTTPS egress to the Let's Encrypt ACME API, as described in [Prerequisites for BYO-VPC (existing VPC)](#prerequisites-for-byo-vpc-existing-vpc). Deployments that use Snowflake managed ingress without this connectivity cannot issue or renew TLS certificates, and upgrades can fail. To configure private deployments, you need to choose the following options when creating a new deployment: 1. In the **Deployment location** step, select **Amazon Web Services** as the deployment location. 2. In the **VPC Configuration** step, select **Bring your own VPC** to use an existing VPC. 3. In the **PrivateLink** step, enable the PrivateLink feature. Enabling this option requires additional setup in your AWS account, see [Configuring PrivateLink in AWS](#configuring-privatelink-in-aws). The **End user authentication over PrivateLink** option can be either enabled or disabled. 4. In the **Custom ingress** step, enable the custom ingress feature. Enabling this option requires additional setup in your AWS account. For more information, see [Openflow BYOC - Set up custom ingress](/user-guide/data-integration/openflow/setup-openflow-byoc-custom-ingress). Private deployments require that your existing VPC is able to access the following domains: - `*.amazonaws.com`, a detailed list of services being accessed includes: - `com.amazonaws.iam` - `com.amazonaws..s3` - `com.amazonaws..ec2` - `com.amazonaws..ecr.api` - `com.amazonaws..ecr.dkr` - `com.amazonaws..secretsmanager` - `com.amazonaws..sts` - `com.amazonaws..eks` - `com.amazonaws..autoscaling` - `*.privatelink.snowflakecomputing.cn` - `oidc-eks..api.aws` - `shield.us-east-1.amazonaws.com` ## BYOC deployment customization and tagging behavior Openflow BYOC creates and manages AWS infrastructure using the generated CloudFormation template and the Openflow deployment agent. Some AWS resource names and configuration choices are controlled by Openflow so that deployments can be installed, upgraded, and operated consistently. ### Container image source As part of the installation process, the Openflow deployment agent authenticates with the Snowflake System Image Registry to obtain Openflow container images, and configures the cluster to pull all workload images from Snowflake-managed repositories. Pulling Openflow images from a customer-owned AWS ECR repository is not supported. You can optionally reach the Snowflake image registry over AWS PrivateLink, but the registry itself is always the Snowflake System Image Registry. ### EKS cluster naming Openflow uses the generated deployment key as the stable identifier for AWS resources created for a BYOC deployment. The EKS cluster name and related AWS resource names, such as the VPC, IAM roles, the Terraform state S3 bucket, and node groups, are derived from this deployment key. The EKS cluster name is not configurable during deployment creation. ### AWS resource tagging You can apply AWS CloudFormation stack tags when you deploy Openflow BYOC. These tags can support cost allocation, ownership tracking, inventory, governance, and compliance workflows. Openflow propagates CloudFormation stack tags to the AWS-level resources created for the BYOC deployment, including resources such as: - The deployment S3 bucket - Openflow agent EC2 instances - EKS worker EC2 instances - The EKS cluster - EBS volumes - Auto Scaling groups - Load balancers - Other AWS infrastructure resources created as part of the deployment CloudFormation stack tags are not applied to Kubernetes-level objects inside the EKS cluster, such as namespaces, pods, services, deployments, StatefulSets, ConfigMaps, secrets, service accounts, or persistent volume claims. If your organization requires Kubernetes-level labels or annotations for compliance, inventory, or policy enforcement, validate whether AWS-level tagging satisfies your control requirements before you deploy Openflow BYOC. Kubernetes-level tagging customization is not currently supported. ## Installation process Between the CloudFormation stack and the Openflow Agent, there are several coordinated steps that the BYOC deployment installation process manages. The goal is to separate responsibilities between a cold-start that gives organizations an easy way to provide inputs to their BYOC deployment (solved via CloudFormation), and the configuration of the deployment and its core software components that will need to change over time (solved by the Openflow Agent). The deployment Agent facilitates the creation of the Openflow deployment infrastructure and installation of the deployment software components including the deployment service. The deployment agent authenticates with Snowflake System Image Registry to obtain Openflow container images. The steps are as follows: When using BYO-VPC, you will choose a VPC ID and two private subnet IDs from the template, and the CloudFormation stack will use the selected ones rather than creating the resources mentioned in steps 1a, 1b, and 1c. 1. The CloudFormation template creates the following and configures with the AWS permissions mentioned in [Configured AWS permissions](#configured-aws-permissions): 1. One VPC with two public subnets and two private subnets. Public subnets host the AWS Network Load Balancer (created later). Private Subnets host the EKS cluster and all of the EC2 instances backing the NodeGroups. Openflow runtimes run within a private subnet. 2. Internet Gateway for egress from the VPC 3. NAT Gateway for egress from the private subnets 4. AWS Secrets Manager entry for the OIDC configuration input by the user 5. IAM role and instance profile for the Openflow Agent to use from its EC2 instance 6. An EC2 instance for Openflow deployment agent, complete with a UserData script to automatically run the initialization process. This script sets environment variables for the Openflow deployment agent to use, derived from the input CloudFormation parameters. 7. EC2 Instance Connect endpoint for the Openflow deployment agent to upgrade the deployment when needed. - When using BYO-VPC, by default the CloudFormation stack will create an EC2 Instance Connect endpoint. However, this default behavior can be modified. When using the managed VPC option, the CloudFormation stack will always create an EC2 Instance Connect endpoint. - The Instance Connect endpoint can be shared across many VPCs. - If a deployment is deleted, along with deleting the CloudFormation stack, it will also remove the endpoint. This would block access to other BYO-VPC agents if the endpoint is shared. - To add an EC2 Instance Connect endpoint, perform the following steps in your AWS account: 1. In the left navigation, navigate to **VPC** %raa% **Endpoints**. 2. Select **Create Endpoint**. 3. Choose the endpoint type as EC2 Instance Connect Endpoint. 4. Select a VPC. Leave all the security groups clear (not selected) to use the default VPC security group. 5. When selecting a subnet, use the same value as Private Subnet 1 in the CloudFormation parameters. 6. Select **Create**. It takes approximately 5 minutes for the endpoint to be created. 8. S3 Bucket that stores the Terraform state, logs, and outputs for the Openflow Agent 2. The Openflow deployment agent creates the following: 1. An EKS cluster containing: - Node groups - Autoscaling groups - AWS VPC Container Network Interface (CNI) add-on - Amazon Elastic Block Store (EBS) CSI add-on 1. Secrets manager records for PostgreSQL, OAuth credentials, and so on. 2. IAM policies and roles for various K8s service accounts to retrieve their secrets from AWS Secrets Manager. 3. K8s components - Namespaces - Cluster autoscaler - EBS CSI expandable storage - AWS Load Balancer Controller, which creates the publicly accessible Network Load Balancer - Let's Encrypt certificate issuer - Nginx Ingress, configured for Let's Encrypt - Metrics Server - Certificate manager from Jetstack (http://jetstack.io/) - External secrets operator (http://external-secrets.io/) - Service accounts for Temporal, deployment service, and OIDC - Secrets stores for Temporal, deployment service, and OIDC - External secrets for Temporal and deployment service. The external secret for OIDC is created and managed by the runtime operator. - PostgreSQL - Temporal - Self-signed certificate issuer and ingress configuration for communications between runtime nodes - Openflow runtime operator - Openflow deployment service By default, all AWS accounts have a quota of five Elastic IP addresses per region, because public (IPv4) internet addresses are a scarce public resource. Snowflake strongly recommends that you use Elastic IP addresses primarily for their ability to remap the address to another instance in the case of instance failure, and to use DNS hostnames for all other inter-node communication. ### Track the installation progress After the CloudFormation stack moves into the CREATE_COMPLETE state, the Openflow agent automatically creates the rest of the infrastructure. There are a few steps that can take 10-15 minutes each, such as: 1. Creating the EKS cluster 2. Installing the EBS CSI add-on to the EKS cluster 3. Creating the RDS PostgreSQL database Status reporting for the Openflow agent is not available yet. In the meantime, you can view logs on the Openflow agent to verify whether the BYOC deployment is ready for runtimes. To do this, perform the following steps: 1. In the EC2 instances list, locate the following two instances: - openflow-agent-\{data-plane-key\}: This is the Openflow agent that you will use to manage runtimes - \{data-plane-key\}-mgmt-group: This is a node in the BYOC deployment's EKS cluster that runs an operator and other core software 2. Right-click on the openflow-agent-\{data-plane-key\} instance and select **Connect**. 3. Switch from **EC2 Instance Connect** to **Connect using EC2 Instance Connect Endpoint**. Leave the default EC2 Instance Connect Endpoint in place. 4. Click **Connect**. A new browser tab or window will appear with a command-line interface. 5. Run the following command to tail the installation logs of the docker image that is configuring your deployment: ```bash journalctl -xe -f -n 100 -u docker ``` 6. Once the installation is complete, you'll see the following output: ```text {timestamp} - app stack applied successfully {timestamp} - All resources applied successfully ``` ### Configured AWS permissions This section lists the AWS permissions configured by Openflow BYOC stack based on the roles. \{key\} represents the deployment key that uniquely identifies cloud resources created and managed by Openflow for a particular deployment. **Administrative user** `cloudformation` and all of the following permissions. **IAM Role: openflow-agent-role-\{key\}** This role is assumed by the Openflow deployment agent EC2 instance through the instance profile `OpenflowAgentEC2InstanceProfile-{key}`. The following Openflow-managed policies are attached to the role. Openflow-managed policy: `openflow-agent-ec2-policy-{key}` ```json { "Version": "2012-10-17", "Statement": [ { "Effect": "Allow", "Action": [ "ec2:CreateSecurityGroup", "ec2:AuthorizeSecurityGroupIngress", "ec2:AuthorizeSecurityGroupEgress", "ec2:RevokeSecurityGroupIngress", "ec2:RevokeSecurityGroupEgress", "ec2:DeleteSecurityGroup" ], "Condition": { "StringLike": { "aws:ResourceTag/Name": [ "{key}-*", "k8s-traffic-{key}-*", "eks-cluster-sg-{key}-*" ] } }, "Resource": "arn:aws:ec2:{Region}:{Account_ID}:security-group/*" }, { "Effect": "Allow", "Action": [ "ec2:CreateLaunchTemplateVersion", "ec2:ModifyLaunchTemplate" ], "Condition": { "StringLike": { "aws:ResourceTag/Name": "{key}-*-group" } }, "Resource": [ "arn:aws:ec2:{Region}:{Account_ID}:launch-template/*" ] } ] } ``` Openflow-managed policy: `openflow-agent-eks-policy-{key}` ```json { "Version": "2012-10-17", "Statement": [ { "Effect": "Allow", "Action": [ "eks:ListTagsForResource", "eks:TagResource", "eks:UntagResource", "eks:UpdateClusterVersion", "eks:UpdateNodegroupVersion" ], "Resource": [ "arn:aws:eks:{Region}:{Account_ID}:cluster/{key}", "arn:aws:eks:{Region}:{Account_ID}:nodegroup/{key}/*", "arn:aws:eks:{Region}:{Account_ID}:addon/{key}/*" ] }, { "Effect": "Allow", "Action": [ "eks:DescribeAddonVersions" ], "Resource": "*" } ] } ``` Openflow-managed policy: `openflow-agent-iam-policy-{key}` ```json { "Version": "2012-10-17", "Statement": [ { "Effect": "Allow", "Action": [ "iam:TagRole", "iam:UntagRole" ], "Resource": [ "arn:aws:iam::{Account_ID}:role/{key}-*" ] }, { "Effect": "Allow", "Action": [ "iam:ListOpenIDConnectProviderTags", "iam:TagOpenIDConnectProvider", "iam:UntagOpenIDConnectProvider" ], "Resource": "arn:aws:iam::{Account_ID}:oidc-provider/oidc.eks.{Region}.amazonaws.com/id/*" }, { "Effect": "Allow", "Action": [ "iam:CreatePolicy", "iam:DeletePolicy", "iam:DeletePolicyVersion", "iam:GetPolicy", "iam:GetPolicyVersion", "iam:ListPolicyVersions", "iam:CreatePolicyVersion", "iam:TagPolicy", "iam:UntagPolicy" ], "Resource": [ "arn:aws:iam::{Account_ID}:policy/*-role-policy-{key}" ] }, { "Effect": "Allow", "Action": [ "iam:AttachRolePolicy", "iam:CreateRole", "iam:UpdateRole", "iam:DeleteRole", "iam:DeleteRolePolicy", "iam:DetachRolePolicy", "iam:GetRolePolicy", "iam:ListAttachedRolePolicies", "iam:ListInstanceProfilesForRole", "iam:ListRolePolicies", "iam:PutRolePolicy", "iam:TagRole", "iam:UntagRole", "iam:UpdateAssumeRolePolicy" ], "Resource": [ "arn:aws:iam::{Account_ID}:role/*-role-{key}", "arn:aws:iam::{Account_ID}:role/{key}-*" ] } ] } ``` Openflow-managed policy: `openflow-agent-misc-policy-{key}` ```json { "Version": "2012-10-17", "Statement": [ { "Effect": "Allow", "Action": [ "secretsmanager:TagResource", "secretsmanager:UntagResource" ], "Resource": "arn:aws:secretsmanager:{Region}:{Account_ID}:secret:*-{key}*" }, { "Effect": "Allow", "Action": [ "ssm:GetParameter" ], "Resource": [ "arn:aws:ssm:{Region}::parameter/aws/service/eks/optimized-ami/*" ] }, { "Effect": "Allow", "Action": [ "elasticloadbalancing:DeleteTargetGroup" ], "Condition": { "StringEquals": { "aws:ResourceTag/elbv2.k8s.aws/cluster": "{key}" } }, "Resource": "arn:aws:elasticloadbalancing:{Region}:{Account_ID}:targetgroup/*/*" }, { "Effect": "Allow", "Action": [ "elasticloadbalancing:DescribeListeners", "elasticloadbalancing:DescribeLoadBalancers", "elasticloadbalancing:DescribeTags", "elasticloadbalancing:DescribeTargetGroups" ], "Resource": "*" }, { "Effect": "Allow", "Action": [ "elasticloadbalancing:DeleteLoadBalancer", "elasticloadbalancing:SetSecurityGroups" ], "Resource": "arn:aws:elasticloadbalancing:{Region}:{Account_ID}:loadbalancer/net/runtime-ingress-{key}*" } ] } ``` The following inline policies are also attached to the role. Inline policy: `managed-policy-creation-permission` ```json { "Version": "2012-10-17", "Statement": [ { "Effect": "Allow", "Action": [ "iam:CreatePolicy", "iam:DeletePolicy", "iam:DeletePolicyVersion", "iam:GetPolicy", "iam:GetPolicyVersion", "iam:ListPolicyVersions", "iam:CreatePolicyVersion", "iam:TagPolicy", "iam:UntagPolicy" ], "Resource": [ "arn:aws:iam::{Account_ID}:policy/openflow-agent-ec2-policy-{key}", "arn:aws:iam::{Account_ID}:policy/openflow-agent-iam-policy-{key}", "arn:aws:iam::{Account_ID}:policy/openflow-agent-eks-policy-{key}", "arn:aws:iam::{Account_ID}:policy/openflow-agent-misc-policy-{key}" ] } ] } ``` Inline policy: `OpenflowAgentPolicy` ```json { "Version": "2012-10-17", "Statement": [ { "Action": [ "autoscaling:DescribeTags", "ec2:DescribeImages", "ec2:DescribeInstances", "ec2:DescribeLaunchTemplates", "ec2:DescribeLaunchTemplateVersions", "ec2:DescribeNetworkInterfaces", "ec2:DescribeSecurityGroups", "ec2:DescribeSubnets", "ec2:DescribeTags", "ec2:DescribeVolumes", "ec2:DescribeVpcs", "ec2:DescribeVpcAttribute", "iam:GetRole", "iam:GetOpenIDConnectProvider", "ec2:RunInstances", "ec2:CreateLaunchTemplate", "ec2:CreateSecurityGroup", "ec2:CreateTags", "ec2:DeleteTags" ], "Resource": "*", "Effect": "Allow" }, { "Condition": { "StringLike": { "aws:ResourceTag/Name": [ "{key}-oidc-provider" ] } }, "Action": [ "iam:CreateOpenIDConnectProvider", "iam:DeleteOpenIDConnectProvider", "iam:TagOpenIDConnectProvider", "iam:UpdateOpenIDConnectProviderThumbprint" ], "Resource": "arn:aws:iam::{Account_ID}:oidc-provider/oidc.eks.{Region}.amazonaws.com/id/*", "Effect": "Allow" }, { "Action": [ "iam:CreatePolicy", "iam:DeletePolicy", "iam:DeletePolicyVersion", "iam:GetPolicy", "iam:GetPolicyVersion", "iam:ListPolicyVersions", "iam:CreatePolicyVersion", "iam:TagPolicy", "iam:UntagPolicy" ], "Resource": [ "arn:aws:iam::{Account_ID}:policy/dp-service-role-policy-{key}", "arn:aws:iam::{Account_ID}:policy/oauth2-role-policy-{key}", "arn:aws:iam::{Account_ID}:policy/temporal-service-role-policy-{key}", "arn:aws:iam::{Account_ID}:policy/oidc-service-role-policy-{key}", "arn:aws:iam::{Account_ID}:policy/dps-temporal-role-policy-{key}", "arn:aws:iam::{Account_ID}:policy/dps-postgres-role-policy-{key}", "arn:aws:iam::{Account_ID}:policy/token-refresh-role-policy-{key}" ], "Effect": "Allow" }, { "Action": [ "iam:AttachRolePolicy", "iam:CreateRole", "iam:UpdateRole", "iam:DeleteRole", "iam:DeleteRolePolicy", "iam:DetachRolePolicy", "iam:GetRolePolicy", "iam:ListAttachedRolePolicies", "iam:ListInstanceProfilesForRole", "iam:ListRolePolicies", "iam:PutRolePolicy", "iam:TagRole", "iam:UntagRole", "iam:UpdateAssumeRolePolicy" ], "Resource": [ "arn:aws:iam::{Account_ID}:role/openflow-agent-role-{key}", "arn:aws:iam::{Account_ID}:role/{key}-*", "arn:aws:iam::{Account_ID}:role/dps-temporal-role-{key}", "arn:aws:iam::{Account_ID}:role/dps-postgres-role-{key}", "arn:aws:iam::{Account_ID}:role/dp-service-role-{key}", "arn:aws:iam::{Account_ID}:role/oauth2-role-{key}", "arn:aws:iam::{Account_ID}:role/oidc-service-role-{key}", "arn:aws:iam::{Account_ID}:role/token-refresh-role-{key}" ], "Effect": "Allow" }, { "Action": [ "autoscaling:CreateOrUpdateTags", "autoscaling:DeleteTags" ], "Resource": "arn:aws:autoscaling:{Region}:{Account_ID}:autoScalingGroup:*:autoScalingGroupName/eks-{key}-*", "Effect": "Allow" }, { "Condition": { "StringLike": { "aws:ResourceTag/Name": [ "{key}-EC2SecurityGroup-*", "k8s-traffic-{key}-*", "eks-cluster-sg-{key}-*", "{key}-cluster-sg", "{key}-custom-ingress-default-sg" ] } }, "Action": [ "ec2:AuthorizeSecurityGroupEgress", "ec2:AuthorizeSecurityGroupIngress", "ec2:RevokeSecurityGroupIngress", "ec2:RevokeSecurityGroupEgress", "ec2:DeleteSecurityGroup", "ec2:CreateTags", "ec2:DeleteTags", "ec2:CreateNetworkInterface", "ec2:DeleteNetworkInterface" ], "Resource": "arn:aws:ec2:{Region}:{Account_ID}:security-group/*", "Effect": "Allow" }, { "Condition": { "StringLike": { "aws:ResourceTag/elbv2.k8s.aws/cluster": "{key}" } }, "Action": [ "ec2:AuthorizeSecurityGroupEgress", "ec2:AuthorizeSecurityGroupIngress", "ec2:RevokeSecurityGroupEgress", "ec2:DeleteSecurityGroup", "ec2:CreateTags", "ec2:DeleteTags", "ec2:CreateNetworkInterface", "ec2:DeleteNetworkInterface" ], "Resource": "arn:aws:ec2:{Region}:{Account_ID}:security-group/*", "Effect": "Allow" }, { "Action": [ "ec2:CreateSecurityGroup" ], "Resource": "arn:aws:ec2:{Region}:{Account_ID}:vpc/{VPC_ID}", "Effect": "Allow" }, { "Condition": { "StringLike": { "ec2:ResourceTag/Name": "openflow-agent-{key}" } }, "Action": [ "ec2:AttachNetworkInterface" ], "Resource": "arn:aws:ec2:{Region}:{Account_ID}:instance/*", "Effect": "Allow" }, { "Condition": { "StringLike": { "aws:ResourceTag/Name": "{key}-*-group" } }, "Action": [ "ec2:DeleteLaunchTemplate" ], "Resource": "arn:aws:ec2:{Region}:{Account_ID}:launch-template/*", "Effect": "Allow" }, { "Action": [ "eks:CreateCluster", "eks:CreateAccessEntry", "eks:CreateAddon", "eks:CreateNodegroup", "eks:DeleteCluster", "eks:DescribeCluster", "eks:ListClusters", "eks:ListNodeGroups", "eks:DescribeUpdate", "eks:UpdateClusterConfig", "eks:TagResource" ], "Resource": "arn:aws:eks:{Region}:{Account_ID}:cluster/{key}", "Effect": "Allow" }, { "Action": [ "eks:DescribeAddon", "eks:DescribeAddonVersions", "eks:UpdateAddon", "eks:DeleteAddon", "eks:DescribeUpdate" ], "Resource": "arn:aws:eks:{Region}:{Account_ID}:addon/{key}/*", "Effect": "Allow" }, { "Action": [ "eks:DeleteNodegroup", "eks:DescribeNodegroup", "eks:ListNodegroups", "eks:UpdateNodegroupConfig", "eks:TagResource", "eks:DescribeUpdate" ], "Resource": "arn:aws:eks:{Region}:{Account_ID}:nodegroup/{key}/*", "Effect": "Allow" }, { "Action": [ "s3:CreateBucket", "s3:ListBucket" ], "Resource": "arn:aws:s3:::byoc-tf-state-{key}-{Region}", "Effect": "Allow" }, { "Action": [ "s3:DeleteObject", "s3:GetObject", "s3:PutObject" ], "Resource": "arn:aws:s3:::byoc-tf-state-{key}-{Region}/*", "Effect": "Allow" }, { "Action": [ "s3:PutBucketPublicAccessBlock", "s3:GetBucketPublicAccessBlock", "s3:PutBucketPolicy", "s3:GetBucketPolicy", "s3:DeleteBucketPolicy", "s3:PutEncryptionConfiguration", "s3:GetEncryptionConfiguration" ], "Resource": "arn:aws:s3:::byoc-tf-state-{key}-{Region}", "Effect": "Allow" }, { "Action": [ "secretsmanager:CreateSecret", "secretsmanager:DeleteSecret", "secretsmanager:DescribeSecret", "secretsmanager:GetResourcePolicy", "secretsmanager:GetSecretValue", "secretsmanager:PutSecretValue", "secretsmanager:UpdateSecretVersionStage", "secretsmanager:TagResource", "secretsmanager:UntagResource" ], "Resource": "arn:aws:secretsmanager:{Region}:{Account_ID}:secret:*-{key}*", "Effect": "Allow" }, { "Condition": { "StringLike": { "iam:AWSServiceName": "eks.amazonaws.com" } }, "Action": [ "iam:CreateServiceLinkedRole" ], "Resource": "arn:aws:iam::*:role/aws-service-role/eks.amazonaws.com/AWSServiceRoleForAmazonEKS", "Effect": "Allow" }, { "Condition": { "StringLike": { "iam:AWSServiceName": "eks-nodegroup.amazonaws.com" } }, "Action": [ "iam:CreateServiceLinkedRole" ], "Resource": "arn:aws:iam::*:role/aws-service-role/eks-nodegroup.amazonaws.com/AWSServiceRoleForAmazonEKSNodegroup", "Effect": "Allow" }, { "Action": [ "eks:AssociateAccessPolicy", "eks:ListAssociatedAccessPolicies", "eks:DisassociateAccessPolicy" ], "Resource": "arn:aws:eks:{Region}:{Account_ID}:access-entry/{key}/*", "Effect": "Allow" }, { "Action": "iam:PassRole", "Resource": "*", "Effect": "Allow" }, { "Action": [ "iam:TagRole", "iam:UntagRole" ], "Resource": "arn:aws:iam::{Account_ID}:role/{key}-*", "Effect": "Allow" }, { "Action": [ "iam:UntagOpenIDConnectProvider" ], "Resource": "arn:aws:iam::{Account_ID}:oidc-provider/oidc.eks.{Region}.amazonaws.com/id/*", "Effect": "Allow" }, { "Action": [ "eks:TagResource", "eks:UntagResource", "eks:UpdateNodegroupVersion" ], "Resource": [ "arn:aws:eks:{Region}:{Account_ID}:cluster/{key}", "arn:aws:eks:{Region}:{Account_ID}:nodegroup/{key}/*", "arn:aws:eks:{Region}:{Account_ID}:addon/{key}/*" ], "Effect": "Allow" }, { "Condition": { "StringLike": { "aws:ResourceTag/Name": "{key}-*-group" } }, "Action": [ "ec2:CreateLaunchTemplateVersion", "ec2:ModifyLaunchTemplate" ], "Resource": "arn:aws:ec2:{Region}:{Account_ID}:launch-template/*", "Effect": "Allow" }, { "Action": [ "ssm:GetParameter" ], "Resource": "arn:aws:ssm:{Region}::parameter/aws/service/eks/optimized-ami/*", "Effect": "Allow" } ] } ``` **IAM Role: \{key\}-cluster-ServiceRole** AWS-managed policies: - AmazonEKSClusterPolicy - AmazonEKSVPCResourceController ```json { "Version": "2012-10-17", "Statement": [ { "Action": [ "cloudwatch:PutMetricData" ], "Effect": "Allow", "Resource": "*" } ] } { "Version": "2012-10-17", "Statement": [ { "Action": [ "ec2:DescribeAccountAttributes", "ec2:DescribeAddresses", "ec2:DescribeInternetGateways" ], "Effect": "Allow", "Resource": "*" } ] } ``` **IAM Role: \{key\}-addon-vpc-cni-Role** AWS-managed policies: - AmazonEKS_CNI_Policy **IAM Role: \{key\}-eks-role** AWS-managed policies: - AmazonEBSCSIDriverPolicy - AmazonEC2ContainerRegistryReadOnly - AmazonEKS_CNI_Policy - AmazonEKSWorkerNodePolicy - AmazonSSMManagedInstanceCore - AutoScalingFullAccess - ElasticLoadBalancingFullAccess ```json { "Version": "2012-10-17", "Statement": [ { "Action": [ "ec2:CreateSecurityGroup", "ec2:CreateTags" ], "Effect": "Allow", "Resource": [ "arn:aws:ec2:{Region}:{Account_ID}:security-group/*", "arn:aws:ec2:{Region}:{Account_ID}:vpc/{VPC_ID}" ], "Sid": "CreateOpenflowEKSSecurityGroupAndTags" }, { "Action": [ "ec2:AuthorizeSecurityGroupIngress", "ec2:DeleteSecurityGroup" ], "Condition": { "StringLike": { "aws:ResourceTag/Name": "eks-cluster-sg-{key}-*" } }, "Effect": "Allow", "Resource": [ "arn:aws:ec2:{Region}:{Account_ID}:security-group/*" ], "Sid": "OpenflowManageEKSSecurityGroup" } ] } ``` \{VPC_ID\} represents the identifier of the VPC that was either created by BYOC or used by BYO-VPC. The following roles are used by Kubernetes service accounts to read their secrets from AWS Secrets Manager. Each role has a single Openflow-managed policy attached whose name matches the role name with a `-policy` suffix (for example, the `oidc-service-role-{key}` role uses the `oidc-service-role-policy-{key}` policy). **IAM Role: oidc-service-role-\{key\}** Openflow-managed policy: `oidc-service-role-policy-{key}` ```json { "Statement": [ { "Action": [ "secretsmanager:GetSecretValue", "secretsmanager:DescribeSecret", "secretsmanager:GetResourcePolicy", "secretsmanager:ListSecretVersionIds" ], "Effect": "Allow", "Resource": [ "arn:aws:secretsmanager:{Region}:{Account_ID}:secret:oidc-{key}*" ] } ], "Version": "2012-10-17" } ``` **IAM Role: dps-postgres-role-\{key\}** Openflow-managed policy: `dps-postgres-role-policy-{key}` ```json { "Statement": [ { "Action": [ "secretsmanager:GetSecretValue", "secretsmanager:DescribeSecret", "secretsmanager:GetResourcePolicy", "secretsmanager:ListSecretVersionIds" ], "Effect": "Allow", "Resource": [ "arn:aws:secretsmanager:{Region}:{Account_ID}:secret:postgres_creds-{key}*" ] } ], "Version": "2012-10-17" } ``` **IAM Role: dps-temporal-role-\{key\}** Openflow-managed policy: `dps-temporal-role-policy-{key}` ```json { "Statement": [ { "Action": [ "secretsmanager:GetSecretValue", "secretsmanager:DescribeSecret", "secretsmanager:GetResourcePolicy", "secretsmanager:ListSecretVersionIds" ], "Effect": "Allow", "Resource": [ "arn:aws:secretsmanager:{Region}:{Account_ID}:secret:temporal_creds-{key}*" ] } ], "Version": "2012-10-17" } ``` **IAM Role: dp-service-role-\{key\}** Openflow-managed policy: `dp-service-role-policy-{key}` ```json { "Statement": [ { "Action": [ "secretsmanager:GetSecretValue", "secretsmanager:DescribeSecret", "secretsmanager:GetResourcePolicy", "secretsmanager:ListSecretVersionIds" ], "Effect": "Allow", "Resource": [ "arn:aws:secretsmanager:{Region}:{Account_ID}:secret:dps_creds-{key}*", "arn:aws:secretsmanager:{Region}:{Account_ID}:secret:snowflake-oauth2-{key}*" ] } ], "Version": "2012-10-17" } ``` **IAM Role: oauth2-role-\{key\}** Openflow-managed policy: `oauth2-role-policy-{key}` ```json { "Statement": [ { "Action": [ "secretsmanager:GetSecretValue", "secretsmanager:DescribeSecret", "secretsmanager:GetResourcePolicy", "secretsmanager:ListSecretVersionIds" ], "Effect": "Allow", "Resource": [ "arn:aws:secretsmanager:{Region}:{Account_ID}:secret:snowflake-oauth2-{key}*" ] } ], "Version": "2012-10-17" } ``` **IAM Role: token-refresh-role-\{key\}** Openflow-managed policy: `token-refresh-role-policy-{key}` ```json { "Statement": [ { "Action": [ "secretsmanager:GetSecretValue", "secretsmanager:DescribeSecret", "secretsmanager:GetResourcePolicy", "secretsmanager:ListSecretVersionIds" ], "Effect": "Allow", "Resource": [ "arn:aws:secretsmanager:{Region}:{Account_ID}:secret:snowflake-oauth2-{key}*" ] } ], "Version": "2012-10-17" } ``` **IAM Role: \{key\}-nodegroup-NodeInstanceRole** AWS-managed policies: - AmazonEBSCSIDriverPolicy - AmazonEC2ContainerRegistryReadOnly - AmazonEKS_CNI_Policy - AmazonEKSWorkerNodePolicy - AmazonSSMManagedInstanceCore - AutoScalingFullAccess - ElasticLoadBalancingFullAccess ```json { "Version": "2012-10-17", "Statement": [ { "Action": [ "servicediscovery:CreateService", "servicediscovery:DeleteService", "servicediscovery:GetService", "servicediscovery:GetInstance", "servicediscovery:RegisterInstance", "servicediscovery:DeregisterInstance", "servicediscovery:ListInstances", "servicediscovery:ListNamespaces", "servicediscovery:ListServices", "servicediscovery:GetInstancesHealthStatus", "servicediscovery:UpdateInstanceCustomHealthStatus", "servicediscovery:GetOperation", "route53:GetHealthCheck", "route53:CreateHealthCheck", "route53:UpdateHealthCheck", "route53:ChangeResourceRecordSets", "route53:DeleteHealthCheck", "appmesh:*" ], "Effect": "Allow", "Resource": "*" } ] } { "Version": "2012-10-17", "Statement": [ { "Action": [ "autoscaling:DescribeAutoScalingGroups", "autoscaling:DescribeAutoScalingInstances", "autoscaling:DescribeLaunchConfigurations", "autoscaling:DescribeScalingActivities", "autoscaling:DescribeTags", "ec2:DescribeInstanceTypes", "ec2:DescribeLaunchTemplateVersions" ], "Effect": "Allow", "Resource": "*" }, { "Action": [ "autoscaling:SetDesiredCapacity", "autoscaling:TerminateInstanceInAutoScalingGroup", "ec2:DescribeImages", "ec2:GetInstanceTypesFromInstanceRequirements", "eks:DescribeNodegroup" ], "Effect": "Allow", "Resource": "*" } ] } { "Version": "2012-10-17", "Statement": [ { "Action": [ "iam:CreateServiceLinkedRole" ], "Condition": { "StringEquals": { "iam:AWSServiceName": "elasticloadbalancing.amazonaws.com" } }, "Effect": "Allow", "Resource": "*" }, { "Action": [ "ec2:DescribeAccountAttributes", "ec2:DescribeAddresses", "ec2:DescribeAvailabilityZones", "ec2:DescribeInternetGateways", "ec2:DescribeVpcs", "ec2:DescribeVpcPeeringConnections", "ec2:DescribeSubnets", "ec2:DescribeSecurityGroups", "ec2:DescribeInstances", "ec2:DescribeNetworkInterfaces", "ec2:DescribeTags", "ec2:GetCoipPoolUsage", "ec2:DescribeCoipPools", "elasticloadbalancing:DescribeLoadBalancers", "elasticloadbalancing:DescribeLoadBalancerAttributes", "elasticloadbalancing:DescribeListeners", "elasticloadbalancing:DescribeListenerCertificates", "elasticloadbalancing:DescribeSSLPolicies", "elasticloadbalancing:DescribeRules", "elasticloadbalancing:DescribeTargetGroups", "elasticloadbalancing:DescribeTargetGroupAttributes", "elasticloadbalancing:DescribeTargetHealth", "elasticloadbalancing:DescribeTags" ], "Effect": "Allow", "Resource": "*" }, { "Action": [ "cognito-idp:DescribeUserPoolClient", "acm:ListCertificates", "acm:DescribeCertificate", "iam:ListServerCertificates", "iam:GetServerCertificate", "waf-regional:GetWebACL", "waf-regional:GetWebACLForResource", "waf-regional:AssociateWebACL", "waf-regional:DisassociateWebACL", "wafv2:GetWebACL", "wafv2:GetWebACLForResource", "wafv2:AssociateWebACL", "wafv2:DisassociateWebACL", "shield:GetSubscriptionState", "shield:DescribeProtection", "shield:CreateProtection", "shield:DeleteProtection" ], "Effect": "Allow", "Resource": "*" }, { "Action": [ "ec2:AuthorizeSecurityGroupIngress", "ec2:RevokeSecurityGroupIngress" ], "Effect": "Allow", "Resource": "*" }, { "Action": [ "ec2:CreateSecurityGroup" ], "Effect": "Allow", "Resource": "*" }, { "Action": [ "ec2:CreateTags" ], "Condition": { "Null": { "aws:RequestTag/elbv2.k8s.aws/cluster": "false" }, "StringEquals": { "ec2:CreateAction": "CreateSecurityGroup" } }, "Effect": "Allow", "Resource": "arn:aws:ec2:*:*:security-group/*" }, { "Action": [ "ec2:CreateTags", "ec2:DeleteTags" ], "Condition": { "Null": { "aws:RequestTag/elbv2.k8s.aws/cluster": "true", "aws:ResourceTag/elbv2.k8s.aws/cluster": "false" } }, "Effect": "Allow", "Resource": "arn:aws:ec2:*:*:security-group/*" }, { "Action": [ "ec2:AuthorizeSecurityGroupIngress", "ec2:RevokeSecurityGroupIngress", "ec2:DeleteSecurityGroup" ], "Condition": { "Null": { "aws:ResourceTag/elbv2.k8s.aws/cluster": "false" } }, "Effect": "Allow", "Resource": "*" }, { "Action": [ "elasticloadbalancing:CreateLoadBalancer", "elasticloadbalancing:CreateTargetGroup" ], "Condition": { "Null": { "aws:RequestTag/elbv2.k8s.aws/cluster": "false" } }, "Effect": "Allow", "Resource": "*" }, { "Action": [ "elasticloadbalancing:CreateListener", "elasticloadbalancing:DeleteListener", "elasticloadbalancing:CreateRule", "elasticloadbalancing:DeleteRule" ], "Effect": "Allow", "Resource": "*" }, { "Action": [ "elasticloadbalancing:AddTags", "elasticloadbalancing:RemoveTags" ], "Condition": { "Null": { "aws:RequestTag/elbv2.k8s.aws/cluster": "true", "aws:ResourceTag/elbv2.k8s.aws/cluster": "false" } }, "Effect": "Allow", "Resource": [ "arn:aws:elasticloadbalancing:*:*:targetgroup/*/*", "arn:aws:elasticloadbalancing:*:*:loadbalancer/net/*/*", "arn:aws:elasticloadbalancing:*:*:loadbalancer/app/*/*" ] }, { "Action": [ "elasticloadbalancing:AddTags", "elasticloadbalancing:RemoveTags" ], "Effect": "Allow", "Resource": [ "arn:aws:elasticloadbalancing:*:*:listener/net/*/*/*", "arn:aws:elasticloadbalancing:*:*:listener/app/*/*/*", "arn:aws:elasticloadbalancing:*:*:listener-rule/net/*/*/*", "arn:aws:elasticloadbalancing:*:*:listener-rule/app/*/*/*" ] }, { "Action": [ "elasticloadbalancing:ModifyLoadBalancerAttributes", "elasticloadbalancing:SetIpAddressType", "elasticloadbalancing:SetSecurityGroups", "elasticloadbalancing:SetSubnets", "elasticloadbalancing:DeleteLoadBalancer", "elasticloadbalancing:ModifyTargetGroup", "elasticloadbalancing:ModifyTargetGroupAttributes", "elasticloadbalancing:DeleteTargetGroup" ], "Condition": { "Null": { "aws:ResourceTag/elbv2.k8s.aws/cluster": "false" } }, "Effect": "Allow", "Resource": "*" }, { "Action": [ "elasticloadbalancing:AddTags" ], "Condition": { "Null": { "aws:RequestTag/elbv2.k8s.aws/cluster": "false" }, "StringEquals": { "elasticloadbalancing:CreateAction": [ "CreateTargetGroup", "CreateLoadBalancer" ] } }, "Effect": "Allow", "Resource": [ "arn:aws:elasticloadbalancing:*:*:targetgroup/*/*", "arn:aws:elasticloadbalancing:*:*:loadbalancer/net/*/*", "arn:aws:elasticloadbalancing:*:*:loadbalancer/app/*/*" ] }, { "Action": [ "elasticloadbalancing:RegisterTargets", "elasticloadbalancing:DeregisterTargets" ], "Effect": "Allow", "Resource": "arn:aws:elasticloadbalancing:*:*:targetgroup/*/*" }, { "Action": [ "elasticloadbalancing:SetWebAcl", "elasticloadbalancing:ModifyListener", "elasticloadbalancing:AddListenerCertificates", "elasticloadbalancing:RemoveListenerCertificates", "elasticloadbalancing:ModifyRule" ], "Effect": "Allow", "Resource": "*" } ] } { "Version": "2012-10-17", "Statement": [ { "Action": [ "route53:ChangeResourceRecordSets" ], "Effect": "Allow", "Resource": "arn:aws:route53:::hostedzone/*" } ] } { "Version": "2012-10-17", "Statement": [ { "Action": [ "route53:GetChange" ], "Effect": "Allow", "Resource": "arn:aws:route53:::change/*" } ] } { "Version": "2012-10-17", "Statement": [ { "Action": [ "route53:ListResourceRecordSets", "route53:ListHostedZonesByName" ], "Effect": "Allow", "Resource": "*" } ] } { "Version": "2012-10-17", "Statement": [ { "Action": [ "ec2:CreateSnapshot", "ec2:AttachVolume", "ec2:DetachVolume", "ec2:ModifyVolume", "ec2:DescribeAvailabilityZones", "ec2:DescribeInstances", "ec2:DescribeSnapshots", "ec2:DescribeTags", "ec2:DescribeVolumes", "ec2:DescribeVolumesModifications" ], "Effect": "Allow", "Resource": "*" }, { "Action": [ "ec2:CreateTags" ], "Condition": { "StringEquals": { "ec2:CreateAction": [ "CreateVolume", "CreateSnapshot" ] } }, "Effect": "Allow", "Resource": [ "arn:aws:ec2:*:*:volume/*", "arn:aws:ec2:*:*:snapshot/*" ] }, { "Action": [ "ec2:DeleteTags" ], "Effect": "Allow", "Resource": [ "arn:aws:ec2:*:*:volume/*", "arn:aws:ec2:*:*:snapshot/*" ] }, { "Action": [ "ec2:CreateVolume" ], "Condition": { "StringLike": { "aws:RequestTag/ebs.csi.aws.com/cluster": "true" } }, "Effect": "Allow", "Resource": "*" }, { "Action": [ "ec2:CreateVolume" ], "Condition": { "StringLike": { "aws:RequestTag/CSIVolumeName": "*" } }, "Effect": "Allow", "Resource": "*" }, { "Action": [ "ec2:DeleteVolume" ], "Condition": { "StringLike": { "ec2:ResourceTag/ebs.csi.aws.com/cluster": "true" } }, "Effect": "Allow", "Resource": "*" }, { "Action": [ "ec2:DeleteVolume" ], "Condition": { "StringLike": { "ec2:ResourceTag/CSIVolumeName": "*" } }, "Effect": "Allow", "Resource": "*" }, { "Action": [ "ec2:DeleteVolume" ], "Condition": { "StringLike": { "ec2:ResourceTag/kubernetes.io/created-for/pvc/name": "*" } }, "Effect": "Allow", "Resource": "*" }, { "Action": [ "ec2:DeleteSnapshot" ], "Condition": { "StringLike": { "ec2:ResourceTag/CSIVolumeSnapshotName": "*" } }, "Effect": "Allow", "Resource": "*" }, { "Action": [ "ec2:DeleteSnapshot" ], "Condition": { "StringLike": { "ec2:ResourceTag/ebs.csi.aws.com/cluster": "true" } }, "Effect": "Allow", "Resource": "*" } ] } { "Version": "2012-10-17", "Statement": [ { "Action": [ "route53:ChangeResourceRecordSets" ], "Effect": "Allow", "Resource": "arn:aws:route53:::hostedzone/*" } ] } { "Version": "2012-10-17", "Statement": [ { "Action": [ "route53:ListHostedZones", "route53:ListResourceRecordSets", "route53:ListTagsForResource" ], "Effect": "Allow", "Resource": "*" } ] } ``` --- title: Set up Openflow - Snowflake Deployment - Task overview source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/setup-openflow-spcs.md section: Loading & Unloading Data --- # Set up Openflow - Snowflake Deployment - Task overview This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). - [About Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/about-spcs) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Monitor Openflow using telemetry data](/user-guide/data-integration/openflow/monitor) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) To setup an %ofsfspcs%, perform the following tasks: The steps below cover both generations. Which generation you get for a new deployment is determined by your account: once your account is enabled for gen 2, every new deployment is gen 2. For details, see [Create a deployment](/user-guide/data-integration/openflow/setup-openflow-spcs-deployment#label-openflow-spcs-create-deployment). New to gen 2? See the [gen 2 Openflow quickstart](/user-guide/data-integration/openflow/gen2/quickstart) for a streamlined SQL-first walkthrough.
Note that step 3 (deployment creation) is typically done once. Steps 4 and 5 (role and runtime creation) are repeated for each runtime you add to the deployment. ## Next steps [Set up Openflow - Snowflake Deployment: Core Snowflake](/user-guide/data-integration/openflow/setup-openflow-spcs-sf) --- title: Set up Openflow - Snowflake Deployment: Configure allowed domains for Openflow connectors source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list.md section: Loading & Unloading Data --- " /> # Set up %ofsfspcs%: Configure allowed domains for Openflow connectors This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). - [About Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/about-spcs) - [Set up Openflow - Snowflake Deployment - Task overview](/user-guide/data-integration/openflow/setup-openflow-spcs) %ofsfspcs-plural% access external domain resources. Snowflake controls access to external domains using [network rules](/user-guide/network-rules) and [external access integrations](/developer-guide/external-network-access/creating-using-external-network-access) to either grant or deny access to specific domains. This topic describes the process of [creating a network rule](/sql-reference/sql/create-network-rule) and [creating an external access integration](/sql-reference/sql/create-external-access-integration) to grant access to a specific domain. In addition, the known domains used by Openflow connectors are provided. Two possible workflows exist for managing access to external domains: - [Create a new network rule and external access integration](#label-openflow-create-new-network-rule-grant-domain-access): Create a new network rule that defines a list of allowed domain/port combinations and create a new external access integration using the newly created network rule. - [Alter an existing network rule](#label-openflow-alter-existing-network-rule-grant-domain-access): Alter an existing network rule to add a list of allowed domain/port combinations. ## Create a network rule granting access to one or more domains To create a new network rule that grants access to one or more domain/port combinations, execute an SQL statement similar to: ```sql USE ROLE OPENFLOW_ADMIN; USE DATABASE ; USE SCHEMA ; CREATE NETWORK RULE MY_OPENFLOW_NETWORK_RULE TYPE = HOST_PORT MODE = EGRESS VALUE_LIST = ('', ''); ``` For example, to allow Snowflake to access `googleads.googleapis.com`, execute the following. ```sql USE ROLE OPENFLOW_ADMIN; USE DATABASE ; USE SCHEMA ; CREATE NETWORK RULE GOOGLEADS_OPENFLOW_NETWORK_RULE TYPE = HOST_PORT MODE = EGRESS VALUE_LIST = ('googleads.googleapis.com'); ``` For more information, see [CREATE NETWORK RULE](/sql-reference/sql/create-network-rule). After the network rule is created, a external access integration has to be created. To create a new integration, execute an SQL statement similar to: ```sql USE ROLE OPENFLOW_ADMIN; CREATE EXTERNAL ACCESS INTEGRATION MY_OPENFLOW_EAI ALLOWED_NETWORK_RULES = (MY_OPENFLOW_NETWORK_RULE) ENABLED = TRUE COMMENT = 'External Access Integration for Openflow connectivity'; ``` ## Alter an existing network rule granting access to one or more domains To alter an existing network rule to grant access to one or more domain/port combinations, execute an SQL statement similar to: ```sql USE ROLE OPENFLOW_ADMIN; USE DATABASE ; USE SCHEMA ; ALTER NETWORK RULE GOOGLEADS_OPENFLOW_NETWORK_RULE SET VALUE_LIST = ('', '', 'googleads.googleapis.com'); ``` For more information, see [ALTER NETWORK RULE](/sql-reference/sql/alter-network-rule). Use [SHOW NETWORK RULES](/sql-reference/sql/show-network-rules) to list the existing network rules.
Use [DESCRIBE NETWORK RULE](/sql-reference/sql/desc-network-rule) to describe the properties of a specific network rule. If the altered network rule is already associated with an external access integration, it will be updated automatically. If you do not have an external access integration for the altered network rule, refer to the section above for instructions on creating a new integration. ## Alter an existing external access integration To add a network rule to an existing external access integration, first check which network rules the EAI already allows, then add the new rule alongside them: ```sql USE ROLE OPENFLOW_ADMIN; ALTER EXTERNAL ACCESS INTEGRATION SET ALLOWED_NETWORK_RULES = (, ); ``` Use [](/sql-reference/sql/desc-external-access-integration) to see which network rules an EAI already references. ## Next steps 1. Associate an external access integration with your runtime: 1. Navigate to the Openflow canvas. 2. Select the **Runtimes** tab. 3. For the runtime which requires the new external access integration, click the %vertical-more-icon% menu. 4. Select **External access integrations**. 5. Select all required external access integrations from the dropdown list.
Note you may select multiple external access integrations. 6. Click **Save**. Restarting the runtime is not required and the changes are applied immediately. 2. Deploy a connector in a runtime, for a list of connectors available in Openflow, see [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors). ## Domains used by Openflow connectors The following domains are used by Openflow connectors and require network rules to be granted access. ### Amazon Ads The following domains are used by the Amazon Ads connector. - `advertising-api.amazon.com` - `advertising-api-eu.amazon.com` - `advertising-api-fe.amazon.com` - `api.amazon.com` - `api.amazon.co.uk` - `api.amazon.co.jp` - Report location. For example, `offline-report-storage-eu-west-1-prod.s3.eu-west-1.amazonaws.com` is used to download reports. The exact report URL location is not always known before creating a report. Snowflake recommends allow listing all s3 regions:
- `*.s3.eu-west-[1-3].amazonaws.com` - `*.s3.eu-central-[1-2].amazonaws.com` - `*.s3.eu-north-1.amazonaws.com` - `*.s3.eu-south-[1-2].amazonaws.com` - `*.s3.il-central-1.amazonaws.com`
- For advertising-api-fe.amazon.com (Far East / APAC): - `*.s3.ap-northeast-[1-3].amazonaws.com` - `*.s3.ap-south-[1-2].amazonaws.com` - `*.s3.ap-southeast-[1-7].amazonaws.com` - `*.s3.ap-east-[1-2].amazonaws.com` - `*.s3.me-south-1.amazonaws.com` - `*.s3.me-central-1.amazonaws.com` - `*.s3.af-south-1.amazonaws.com` The last domain is obtained from the report URL is returned after the report is ready to fetch. This is an Amazon S3 bucket where the report is stored. Customers will need to specify their own AWS region. for example, `us-east-1` or `eu-west-1` and a specific bucket. As it may be not possible to know the exact region and bucket, Snowflake suggests using wildcards and listing all possible regions for a given location. ### AWS Secret Manager The following domains are used by the AWS Secret Manager connector. - `secretsmanager.us-west-2.amazonaws.com` - `sts.us-west-2.amazonaws.com` - `aws.amazon.com` - `amazonaws.com` ### Box The following domains are used by the Box connector.
- `api.box.com` - `box.com`
### Confluence The following domains are used by the Confluence connector.
- Customer-specific domain name, such as `https://company-name.atlassian.net/`. - For OAuth, https://atlassian.company-name.com/ (https://atlassian.company-name.com/)
### Microsoft Dataverse The following domains are used by the Dataverse connector. - Customer-specific domain name, such as `org12345467.crm.dynamics.com` - For OAuth, `login.microsoftonline.com` ### Google Ads The following domains are used by the Google Ads connector. - `googleads.googleapis.com` ### Google Drive The following domains are used by the Google Drive connector: - `drive.google.com` - `www.googleapis.com` - `oauth2.googleapis.com` - `www.googleapis.com` ### Google Sheets The following domains are used by the Google Sheets connector. - `sheets.googleapis.com` ### Hubspot The following domains are used by the HubSpot connector. - `api.hubapi.com` ### Jira Cloud The following domains are used by the Jira Cloud connector. - Customer-specific domain name, for example `company-name.atlassian.net` - `api.atlassian.com` ### Kafka The following domains are used by the Kafka connector. - Customer Kafka bootstrap servers and all Kafka brokers ### Kinesis The following domains are used by the Kinesis connector. - AWS region dependent. For example: for us-west-2: - `kinesis.us-west-2.amazonaws.com` - `kinesis-fips.us-west-2.api.aws` - `kinesis-fips.us-west-2.amazonaws.com` - `kinesis.us-west-2.api.aws` - `*.control-kinesis.us-west-2.amazonaws.com` - `*.control-kinesis.us-west-2.api.aws` - `*.data-kinesis.us-west-2.amazonaws.com` - `*.data-kinesis.us-west-2.api.aws` - `dynamodb.us-west-2.amazonaws.com` ### LinkedIn Ads The following domains are used by the LinkedIn Ads connector. - `www.linkedin.com` - `api.linkedin.com` ### Meta Ads The following domains are used by the Meta Ads connector. - `graph.facebook.com` ### MySQL The following domains are used by the MySQL connector. - Customer-specific domain and port combination. ### PostgreSQL The following domains are used by the PostgreSQL connector. - Customer-specific domain and port combination. ### SharePoint The following domains are used by the SharePoint connector. - Customer-specific domain—for example, `company-domain.sharepoint.com` or an alias that redirects to `company-domain.sharepoint.com` - `graph.microsoft.com:80` - `graph.microsoft.com:443` - `login.microsoftonline.com` ### Slack The following domains are used by the Slack connector. - `slack.com` - `api.slack.com` - `hooks.slack.com` - `files.slack.com` - `wss-primary.slack.com` - `wss-backup.slack.com` ### SQL Server The following domains are used by the SQL Server connector. - Customer-specific domain and port combination. ### Workday The following domains are used by the Workday connector. - Customer-specific domain and port combination. For example, `company-domain.tenant.myworkday.com`. To obtain the domain, you can use the report URL (base URL is always the same). --- title: Set up Openflow - Snowflake Deployment: Connect to private data sources source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/setup-openflow-spcs-dcp.md section: Loading & Unloading Data --- # Set up %ofsfspcs%: Connect to private data sources This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). - [Data Connectivity Proxy](/user-guide/data-connectivity-proxy) - [Set up Data Connectivity Proxy](/user-guide/data-connectivity-proxy-setup) - [About Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/about-spcs) - [Set up Openflow - Snowflake Deployment - Task overview](/user-guide/data-integration/openflow/setup-openflow-spcs) - [Set up Openflow - Snowflake Deployment: Configure allowed domains for Openflow connectors](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list) - [Set up Openflow - Snowflake Deployment: Create runtime](/user-guide/data-integration/openflow/setup-openflow-spcs-create-runtime) - [CREATE NETWORK RULE](/sql-reference/sql/create-network-rule) - [CREATE EXTERNAL ACCESS INTEGRATION](/sql-reference/sql/create-external-access-integration) Data Connectivity Proxy (DCP) lets connectors on an %ofsfspcs% reach private data sources in your VPC or on-premises network. You deploy a lightweight agent in your network which establishes an encrypted tunnel to Snowflake over port 443. As a result, Snowflake never needs inbound access into your network. While the agent enables network connectivity to data sources, all data processing still happens in Openflow runtimes hosted by Snowflake. Connector state stays with the runtime, so replacing an agent doesn't change it. ## When to use DCP with Openflow DCP is for **Snowflake Deployments**, where the runtime runs in Snowflake and can't otherwise reach hosts behind your firewall. Choose a connectivity option based on where the runtime runs and whether Snowflake can already reach the source:
For a fuller comparison, see [How DCP compares to other private connectivity options](/user-guide/data-connectivity-proxy#how-dcp-compares-to-other-private-connectivity-options). ## Prerequisites Before you configure Openflow to use DCP, make sure you have: - An %ofsfspcs% and a runtime. See [Set up Openflow - Snowflake Deployment - Task overview](/user-guide/data-integration/openflow/setup-openflow-spcs). - An execute-as role for the runtime, with `USAGE` on the DCP external access integration. See [Set up Openflow - Snowflake Deployment: Create the execute-as role and external access integrations](/user-guide/data-integration/openflow/setup-openflow-spcs-create-rr). - An existing Data Connectivity Proxy object that's enabled. See [Create a DCP object in Snowflake](/user-guide/data-connectivity-proxy-setup#label-dcp-setup-create-object). - A DCP agent deployed where it can: - Make outbound TCP/TLS connections on port 443 to Snowflake DCP endpoints. See [Outbound ports](/user-guide/data-connectivity-proxy-setup#label-dcp-outbound-ports). - Resolve Snowflake DNS names. See [DNS](/user-guide/data-connectivity-proxy-setup#label-dcp-dns). - Reach the private data source (host and port) from the agent host. See [Deploy the agent](/user-guide/data-connectivity-proxy-setup#label-dcp-setup-deploy-agent). ## Configure Openflow to use the proxy After the proxy object is enabled and the agent is connected, complete the following steps to ensure Openflow connectors can connect to your data source. To verify the agent is connected, see [Verify the agent is connected](/user-guide/data-connectivity-proxy-setup#label-dcp-setup-verify). The following diagram shows where each component runs and how the connection is established: ![The DCP agent and private data sources run in your network, while the Openflow runtime and connector run in Snowflake. An external access integration associated with the runtime holds a network rule with a DATA_CONNECTIVITY_PROXY_EGRESS entry for the source host and port, and matching traffic leaves through the Data Connectivity Proxy object. The agent opens an outbound TLS connection to Snowflake on port 443, and connector traffic reaches the private source back through that tunnel.](/static/images/connectivity/openflow-dcp-architecture.svg) ### Create a network rule for your data source This network rule of mode `DATA_CONNECTIVITY_PROXY_EGRESS` ensures that any traffic to the specified `TARGET_HOSTNAME:TARGET_PORT` is routed through DCP and not through public internet gateways. You can specify multiple hostname and port combinations in a network rule. `TARGET_HOSTNAME` requires a fully qualified domain name. Network rule creation fails if you provide an IP address instead. ```sql CREATE NETWORK RULE IF NOT EXISTS MODE = DATA_CONNECTIVITY_PROXY_EGRESS TYPE = HOST_PORT VALUE_LIST = (':'); ``` ### Create an external access integration for your data source An external access integration provides secure access to external resources for Openflow runtimes and connectors. Associate it with the Data Connectivity Proxy object, and with Openflow runtimes. Its `ALLOWED_NETWORK_RULES` determine which endpoints are accessible through the integration. ```sql CREATE EXTERNAL ACCESS INTEGRATION IF NOT EXISTS ALLOWED_NETWORK_RULES = () ENABLED = TRUE; ``` Associate the integration with the DCP object if you didn't set `EXTERNAL_ACCESS_INTEGRATIONS` when you created the proxy: ```sql ALTER DATA CONNECTIVITY PROXY SET EXTERNAL_ACCESS_INTEGRATIONS = (); ``` ### Grant the execute-as role and Openflow admin access to the integration Grant `USAGE` on the DCP external access integration to the execute-as role associated with the runtime: ```sql GRANT USAGE ON INTEGRATION TO ROLE ; ``` To allow users to associate the DCP external access integration with a runtime, grant `USAGE` to the role that users use to create or update runtimes: ```sql GRANT USAGE ON INTEGRATION TO ROLE ; ``` ### Attach the external access integration to the runtime The Openflow runtime also needs the same external access integration so the connector is allowed to open connections to the destination. To attach it in the Openflow UI: 1. Sign in to %sf-web-interface-link%. 2. In the navigation menu, select **Ingestion** %raa% **Openflow**. 3. Select **Launch Openflow**. 4. Navigate to the runtime listing to view your existing runtimes, or create one as described in [Set up Openflow - Snowflake Deployment: Create runtime](/user-guide/data-integration/openflow/setup-openflow-spcs-create-runtime). 5. In the runtime list view, select %sf-vertical-more-button% next to the runtime %raa% **External access integrations**. Pick the DCP external access integration and select **Save**. You can select more than one integration if the runtime also needs allowlisted public destinations. Openflow gen 2 deployments and runtimes are in public preview. On a gen 2 runtime, you can do the same thing in SQL. To add the integration to an existing runtime: ```sql ALTER OPENFLOW RUNTIME .. ADD EXTERNAL_ACCESS_INTEGRATIONS = (); ``` To create a runtime with the integration already attached: ```sql CREATE OPENFLOW RUNTIME .. IN DEPLOYMENT NODE_TYPE = MEDIUM MIN_NODES = 1 MAX_NODES = 1 EXECUTE_AS_ROLE = EXTERNAL_ACCESS_INTEGRATIONS = (); ``` Adding or removing integrations with `ALTER OPENFLOW RUNTIME` requires `OWNERSHIP` on the runtime. To confirm which integrations are attached, run `DESCRIBE OPENFLOW RUNTIME` and check the `external_integrations` column. ### Configure the connector with the private DNS name Set the connector's source host and port to the same fully qualified hostname you listed in the DCP network rule. Don't substitute a Snowflake hostname, a proxy URL, or the source's private IP. The host and port have to match the network rule exactly. The rest of the connection string works as usual, so keep the scheme and any parameters your source requires. For example, if the network rule lists `mydb.internal.corp:5432`, a PostgreSQL connector can use `jdbc:postgresql://mydb.internal.corp:5432/mydb?sslmode=require`. Then run the connector's usual connectivity check from the Openflow UI. A successful check confirms the path from the Snowflake-hosted runtime through the DCP tunnel to the source. Start your connector and validate that data is being ingested successfully. ## Considerations - The agent must be able to resolve the hostname you use in the network rule and in the connector. If you don't have DNS for the target, add a host entry on the **agent** host (not in Snowflake), as described in [Create a network rule for the private destination](/user-guide/data-connectivity-proxy-setup#label-dcp-setup-network-rule). - Enable the Data Connectivity Proxy object before you expect connector traffic. If the object exists but is disabled, the agent can appear to connect and then retry with an error that the agent isn't known or is disabled. See [](/user-guide/data-connectivity-proxy-troubleshoot#label-dcp-ts-disconnected). - Deploy more than one agent in separate failure domains if you need redundancy. Connector checkpoints remain in Openflow if you replace an agent. See [High availability](/user-guide/data-connectivity-proxy-setup#label-dcp-high-availability). - Rotate the bootstrap credential before it expires. Rotation is a DCP agent operation; you don't reconfigure the Openflow connector when the token changes. See [Rotate the bootstrap token without downtime](/user-guide/data-connectivity-proxy-setup#label-dcp-rotate-bootstrap-token). ## Troubleshooting Openflow connectivity If the connector can't reach the source after the agent is running, check the Openflow side first:
For agent startup errors, bootstrap JWT issues, outbound port 443, DNS to Snowflake, and Prometheus metrics, see [Troubleshoot Data Connectivity Proxy](/user-guide/data-connectivity-proxy-troubleshoot) and [Monitor Data Connectivity Proxy](/user-guide/data-connectivity-proxy-monitor). --- title: Set up Openflow - Snowflake Deployment: Core Snowflake source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/setup-openflow-spcs-sf.md section: Loading & Unloading Data --- # Set up %ofsfspcs%: Core Snowflake This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). - [About Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/about-spcs) - [Set up Openflow - Snowflake Deployment - Task overview](/user-guide/data-integration/openflow/setup-openflow-spcs) %ofsfspcs% requires the creation of the following Snowflake specific resources:
1. [Create the OPENFLOW_ADMIN role](#create-the-openflow-admin-role) 2. [Configure required privileges](#configure-required-privileges)
To complete these tasks, Sign in to %sf-web-interface-link% and open a SQL worksheet. ## Create the OPENFLOW_ADMIN role Create the required Openflow administration role. `` denotes the user that will be used to access Openflow. ```sql USE ROLE ACCOUNTADMIN; CREATE ROLE IF NOT EXISTS OPENFLOW_ADMIN; GRANT ROLE OPENFLOW_ADMIN TO USER ; ``` Users with a default role of ACCOUNTADMIN can't login to %ofsfspcs% runtimes and will get an error message when attempting to do so. Snowflake recommends assigning a different default role to any user that will login to a runtime. In addition, Snowflake recommends setting default secondary roles to `ALL` for all Openflow users. To change the default role and enable all secondary roles, execute the following: For example: ```sql USE ROLE ACCOUNTADMIN; ALTER USER SET DEFAULT_ROLE = ; ALTER USER SET DEFAULT_SECONDARY_ROLES = ('ALL'); ``` ## Configure required privileges Openflow requires defining specific Snowflake account-level privileges. These privileges are assigned to the ACCOUNTADMIN role as part of the default set of privileges. ACCOUNTADMIN will automatically have the following privileges and will be able to grant them to a role of their choosing for the Openflow admin role, shown as `OPENFLOW_ADMIN` role in the following examples. ### Gen 2 privileges Gen 2 deployments are account-level objects, while runtimes and connectors are schema-level objects. Those schema-level objects need a database and schema to live in. Snowflake recommends designating one database and schema to hold your Openflow infrastructure objects, which keeps them easy to manage. 1. Grant the Openflow admin role the account-level privileges it needs: ```sql USE ROLE ACCOUNTADMIN; GRANT CREATE OPENFLOW DEPLOYMENT ON ACCOUNT TO ROLE OPENFLOW_ADMIN; GRANT CREATE DATABASE ON ACCOUNT TO ROLE OPENFLOW_ADMIN; GRANT CREATE INTEGRATION ON ACCOUNT TO ROLE OPENFLOW_ADMIN; -- Snowflake deployments only: GRANT CREATE COMPUTE POOL ON ACCOUNT TO ROLE OPENFLOW_ADMIN; ``` 2. Create the database and schema that will hold your gen 2 Openflow objects: ```sql USE ROLE OPENFLOW_ADMIN; CREATE DATABASE IF NOT EXISTS openflow_db; CREATE SCHEMA IF NOT EXISTS openflow_db.openflow_schema; ``` This is your Openflow **infrastructure database and schema**, also referred to as the control schema. Your deployments' runtimes, your connectors, and any secrets those connectors reference live here. You create it once and reuse it. Keep the infrastructure database separate from the databases your connectors write data to. Snowflake recommends a dedicated destination database per connector. A connector creates destination schemas and tables named after the source's schemas and tables. Those names aren't under your control and can change as the source changes, so pointing a connector at your infrastructure database risks collisions with the Openflow objects that live there. 3. Grant the Openflow admin role the ability to create gen 2 objects in that schema: ```sql USE ROLE ACCOUNTADMIN; GRANT CREATE OPENFLOW RUNTIME ON SCHEMA openflow_db.openflow_schema TO ROLE OPENFLOW_ADMIN; GRANT CREATE OPENFLOW CONNECTOR ON SCHEMA openflow_db.openflow_schema TO ROLE OPENFLOW_ADMIN; ``` For the full gen 2 setup workflow, see [Quickstart: gen 2 Openflow](/user-guide/data-integration/openflow/gen2/quickstart). ### Gen 1 privileges ```sql USE ROLE ACCOUNTADMIN; GRANT CREATE OPENFLOW DATA PLANE INTEGRATION ON ACCOUNT TO ROLE OPENFLOW_ADMIN; GRANT CREATE OPENFLOW RUNTIME INTEGRATION ON ACCOUNT TO ROLE OPENFLOW_ADMIN; GRANT CREATE DATABASE ON ACCOUNT TO ROLE OPENFLOW_ADMIN; GRANT CREATE INTEGRATION ON ACCOUNT TO ROLE OPENFLOW_ADMIN; GRANT CREATE COMPUTE POOL ON ACCOUNT TO ROLE OPENFLOW_ADMIN; ``` ## Next steps Optionally, [Set up PrivateLink UI access](/user-guide/data-integration/openflow/setup-openflow-spcs-configure-pr-ui) to access the Snowflake Openflow Runtime UI using private connectivity. [Create deployment](/user-guide/data-integration/openflow/setup-openflow-spcs-deployment) --- title: Set up Openflow - Snowflake Deployment: Create deployment source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/setup-openflow-spcs-deployment.md section: Loading & Unloading Data --- # Set up %ofsfspcs%: Create deployment This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Gen 2 Openflow deployments are in public preview and available on AWS and Azure (GCP support isn't available yet). The **Generally Available** note above applies to gen 1 deployments. The generation you get for a new deployment is determined by your account, not by how you create it. After configuring core Snowflake, create an Openflow deployment. A deployment is the data plane container for your runtimes and connectors. Each deployment can host multiple runtimes, and each runtime can run multiple connectors, giving you flexibility to isolate workloads by project, team, or environment. There is no separate charge for the deployment itself; only active runtimes consume Snowflake credits. 1. [Create a deployment](#label-openflow-spcs-create-deployment). 2. [[Optional] Configure an Openflow-specific event table](#label-openflow-spcs-event-table) - configure an Openflow-specific event table to store Openflow logs and metrics. ## Create a deployment You can create a deployment from the Openflow UI, which works for both generations, or with SQL. The SQL commands in this topic create gen 2 deployments. Which generation you get is determined by your account, not by how you create the deployment. Once your account is enabled for gen 2, every new deployment is gen 2 and you can no longer create gen 1 deployments. Existing gen 1 deployments keep working unchanged. To check whether your account is enabled for gen 2, run the following command: ```sql SHOW OPENFLOW DEPLOYMENTS; ``` If the command succeeds, your account is enabled for gen 2, including when it returns no rows. If it returns a SQL error, your account isn't enabled for gen 2 and new deployments are gen 1. For other ways to tell gen 1 and gen 2 resources apart, see [](/user-guide/data-integration/openflow/gen2/openflow-generations#label-openflow-generations-identify). ### Using the Openflow UI To access the Openflow Runtime UI using PrivateLink as described in [Setup PrivateLink UI access](/user-guide/data-integration/openflow/setup-openflow-spcs-configure-pr-ui), ensure the **PrivateLink** option is enabled when creating a new %ofsfspcs%. 1. Sign in to %sf-web-interface-link% with a role defined in [Configure core Snowflake requirements](/user-guide/data-integration/openflow/setup-openflow-spcs-sf). 2. In the navigation menu, select **Ingestion** %raa% **Openflow**. 3. Select **Launch Openflow**. 4. In the Openflow UI, select **Create a deployment**. The **Deployments** tab opens. 5. Select **Create a deployment**. The Creating a deployment wizard opens. 6. In the **Prerequisites** step, ensure that you meet all the requirements. Select **Next**. 7. In the **Deployment location** step, select **Snowflake** as the deployment location. Enter a name for your deployment. Select **Next**. 8. Select **Create Deployment**. ### Using SQL (gen 2) Gen 2 deployments are first-class Snowflake objects created with SQL: ```sql USE ROLE OPENFLOW_ADMIN; CREATE OPENFLOW DEPLOYMENT my_deployment DEPLOYMENT_TYPE = SNOWFLAKE -- USE_PRIVATE_LINK = TRUE, -- Enable if you need PrivateLink DISPLAY_NAME = 'My Snowflake Deployment'; ``` For PrivateLink considerations and additional parameters, see [Quickstart: gen 2 Openflow](/user-guide/data-integration/openflow/gen2/quickstart#create-a-gen-2-deployment). ## [Optional] Configure an Openflow-specific event table Openflow generates logs and metrics and sends them to the Snowflake Event Table. For helpful queries to analyze this telemetry data, see [Monitor Openflow](/user-guide/data-integration/openflow/monitor). By default, Openflow uses the [account event table](/developer-guide/logging-tracing/event-table-setting-up#label-logging-event-table-default) (SNOWFLAKE.TELEMETRY.EVENTS), but you can configure an Openflow-specific event table per deployment. A dedicated event table is recommended to optimize query performance, enable granular access control, and simplify Openflow monitoring and maintenance. 1. Create the event table in the Openflow infrastructure schema: ```sql USE ROLE OPENFLOW_ADMIN; USE DATABASE ; USE SCHEMA ; CREATE EVENT TABLE IF NOT EXISTS ..openflow_events; ``` 2. Get your deployment name and set the event table: **Gen 2:** ```sql SHOW OPENFLOW DEPLOYMENTS; ALTER OPENFLOW DEPLOYMENT SET EVENT_TABLE = '..openflow_events'; ``` **Gen 1:** ```sql SHOW OPENFLOW DATA PLANE INTEGRATIONS; ALTER OPENFLOW DATA PLANE INTEGRATION SET EVENT_TABLE = '..openflow_events'; ``` ## [Optional] Create a monitoring role A monitoring role lets data engineers or operations teams monitor Openflow without having the OPENFLOW_ADMIN role. - To create a monitoring role, run the following code: **Gen 2:** ```sql USE ROLE OPENFLOW_ADMIN; CREATE ROLE IF NOT EXISTS ; GRANT MONITOR ON OPENFLOW DEPLOYMENT TO ROLE ; GRANT ROLE TO ROLE ; GRANT ROLE TO USER ; ``` **Gen 1:** ```sql USE ROLE OPENFLOW_ADMIN; CREATE ROLE IF NOT EXISTS ; GRANT MONITOR ON INTEGRATION TO ROLE ; GRANT ROLE TO ROLE ; GRANT ROLE TO USER ; ``` ### Next steps [Create the execute-as role and external access integrations](/user-guide/data-integration/openflow/setup-openflow-spcs-create-rr) --- title: Set up Openflow - Snowflake Deployment: Create runtime source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/setup-openflow-spcs-create-runtime.md section: Loading & Unloading Data --- # Set up %ofsfspcs%: Create runtime This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). - [About Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/about-spcs) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Monitor Openflow using telemetry data](/user-guide/data-integration/openflow/monitor) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) A runtime hosts your data integration flows within a deployment: connectors and custom flow definitions. Each runtime is isolated for security and resource control, and can scale from one node up to fifty to handle varying data volumes. You can create a runtime from the Openflow UI, which works for both generations, or with SQL. The SQL commands in this topic create gen 2 runtimes. ### Using the Openflow UI To create a runtime in your Snowflake deployment: 1. Sign in to %sf-web-interface-link%. 2. In the navigation menu, select **Ingestion** %raa% **Openflow**. 3. Select **Launch Openflow**. A new tab opens for the Openflow canvas. 4. In **Openflow Control Plane**, select **Create a runtime**. The **Create Runtime** dialog box appears. 5. In the **Create Runtime** populate the following fields:
[Set up Openflow - Snowflake Deployment: Create deployment] <[Set up Openflow - Snowflake Deployment: Create the execute-as role and external access integrations]>**Execute-as role** 6. Select **Create**. The runtime takes a couple of minutes to be created. Your runtime will appear in the runtime table in the control plane. ### Using SQL (gen 2) Gen 2 runtimes are schema-level objects created with SQL: ```sql USE ROLE OPENFLOW_ADMIN; USE DATABASE openflow_db; USE SCHEMA openflow_schema; CREATE OPENFLOW RUNTIME my_runtime IN DEPLOYMENT my_deployment NODE_TYPE = MEDIUM MIN_NODES = 1 MAX_NODES = 1 EXECUTE_AS_ROLE = openflow_execute_as_rl EXTERNAL_ACCESS_INTEGRATIONS = (my_eai) DISPLAY_NAME = 'My Runtime'; ``` For the full gen 2 workflow, see [Quickstart: gen 2 Openflow](/user-guide/data-integration/openflow/gen2/quickstart#label-openflow-gen2-quickstart-runtime). ## [Optional] Grant MONITOR privileges on the runtime If you created a [monitoring role](#label-openflow-spcs-monitoring-role) when setting up your deployment, you can add the runtime to that role. This allows data engineers or operations teams to monitor the runtime without having the OPENFLOW_ADMIN role. - To add the runtime to the monitoring role, run the code for your generation: **Gen 2** (runtimes are schema-level objects): ```sql USE ROLE OPENFLOW_ADMIN; GRANT MONITOR ON OPENFLOW RUNTIME .. TO ROLE ; ``` **Gen 1** (runtimes are data plane integrations): ```sql USE ROLE OPENFLOW_ADMIN; GRANT MONITOR ON INTEGRATION TO ROLE ; ``` ## Next step Configure allowed domains for Openflow connectors. See [Set up Openflow - Snowflake Deployment: Configure allowed domains for Openflow connectors](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list). --- title: Set up Openflow - Snowflake Deployment: Create the execute-as role and external access integrations source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/setup-openflow-spcs-create-rr.md section: Loading & Unloading Data --- # Set up %ofsfspcs%: Create the execute-as role and external access integrations This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). - [About Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/about-spcs) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Monitor Openflow using telemetry data](/user-guide/data-integration/openflow/monitor) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) %ofsfspcs% runtimes need a few supporting resources before they can access your data: - An execute-as role that flows use to access Snowflake objects - Network rules and external access integrations (EAI) that let the runtime reach external data sources This topic describes the creation of these resources. 1. Create an execute-as role and grant it the privileges needed to write data to Snowflake. 2. Associate the execute-as role with the runtime. 3. Create external access integrations and associate them with the runtime. See [Creating network rules and external access integrations](#label-create-network-rules-and-external-access-integrations). 4. Configure outbound PrivateLink if required to connect to a private system using SPCS egress. ## Create the execute-as role When creating an Openflow runtime, you associate a role with it. Flows that run within the runtime execute as this role, so it's called the execute-as role. You can reuse the same execute-as role across multiple runtimes. For more information, see [What is an execute-as role?](/user-guide/data-integration/openflow/about-spcs#label-openflow-spcs-what-is-runtime-role). Creating the role is a prerequisite for creating a runtime: 1. Create the role. `` denotes the name of the associated runtime. ```sql USE ROLE ACCOUNTADMIN; CREATE ROLE IF NOT EXISTS OPENFLOW__EXECUTE_AS_RL; GRANT ROLE OPENFLOW__EXECUTE_AS_RL TO ROLE OPENFLOW_ADMIN; ``` 2. Allow the execute-as role to use an existing warehouse that you plan to use for data ingestion. Use this warehouse later when configuring your connectors for runtimes where you use this execute-as role. ```sql GRANT USAGE, OPERATE ON WAREHOUSE TO ROLE OPENFLOW__EXECUTE_AS_RL; ``` 3. Allow the execute-as role to use, create, or otherwise access Snowflake objects. Depending on the Openflow connector being created, the required underlying objects vary. The example below is for illustration purposes only. ```sql GRANT USAGE ON DATABASE TO ROLE OPENFLOW__EXECUTE_AS_RL; GRANT USAGE ON SCHEMA TO ROLE OPENFLOW__EXECUTE_AS_RL; ``` ## Creating network rules and external access integrations The following steps apply to both gen 1 and gen 2 Snowflake deployments. Both generations require network rules and EAIs so the runtime can reach external data sources. Snowflake's security model provides secure access to specific endpoints and systems external to Snowflake using [network policies](/user-guide/network-policies). Two key aspects of network policies are [Network rules](/user-guide/network-rules) and [External Access Integrations (EAI)](/developer-guide/external-network-access/external-network-access-overview). Each of which is used to provide secure access to external resources required by the runtime. There are three steps that are required to create network rules and external access integrations: 1. Create the network rule, grouping the network identifiers into logical areas. 2. Create the external access integration (EAI), specifying the list of network rules and ensuring the execute-as role has USAGE on the EAI. 3. Associate the EAI with the Runtime in the Openflow UI when creating Runtimes. To create the required network rule and EAI, perform the following steps: These examples use RUNTIME_NAME as a placeholder for the name of the Runtime being created. Replacing a network rule or external access integration silently detaches it from every runtime that references it. Use `CREATE ... IF NOT EXISTS` for new objects, and `ALTER` to modify existing ones. 1. Create an appropriate network rule. See [CREATE NETWORK RULE](/sql-reference/sql/create-network-rule) for more information. Snowflake recommends creating network rules in the same infrastructure schema (`openflow_db.openflow_schema`) you've been using for Openflow objects, so that everything is in one place. An EAI is an account-level object, so it has no database or schema; a network rule is a schema-level object. Where you keep the network rule is your choice as long as the execute-as role has access to the EAI, but using the infrastructure schema keeps things simple and consistent. ```sql USE DATABASE ; USE SCHEMA ; CREATE NETWORK RULE IF NOT EXISTS OPENFLOW__NETWORK_RULE MODE = EGRESS TYPE = HOST_PORT VALUE_LIST = ('comma separated list of host:port pairs'); ``` 2. Create an external access integration, or add the network rule to an existing one. See [CREATE EXTERNAL ACCESS INTEGRATION](/sql-reference/sql/create-external-access-integration) for more information. To create a new EAI: ```sql USE ROLE ACCOUNTADMIN; CREATE EXTERNAL ACCESS INTEGRATION IF NOT EXISTS OPENFLOW__EAI ALLOWED_NETWORK_RULES = (OPENFLOW__NETWORK_RULE) ENABLED = TRUE; ``` To add the network rule to an existing EAI, first check which rules are already associated with it, then update the EAI to include both the existing and new rules: ```sql USE ROLE ACCOUNTADMIN; -- Check the current rules on the EAI DESCRIBE EXTERNAL ACCESS INTEGRATION OPENFLOW__EAI; ``` In the output, find the `ALLOWED_NETWORK_RULES` property and note the existing rules. Then update the EAI, listing all existing rules along with the new one: ```sql ALTER EXTERNAL ACCESS INTEGRATION OPENFLOW__EAI SET ALLOWED_NETWORK_RULES = ( , , OPENFLOW__NETWORK_RULE ); ``` 3. Grant access to the EAI to the previously created execute-as role. ```sql GRANT USAGE ON INTEGRATION OPENFLOW__EAI TO ROLE OPENFLOW__EXECUTE_AS_RL; ``` Replacing a network rule or external access integration silently detaches it from every runtime that references it. Use `CREATE ... IF NOT EXISTS` for new objects, and `ALTER` to modify existing ones. ## Next steps [Create runtime](/user-guide/data-integration/openflow/setup-openflow-spcs-create-runtime) --- title: Set up Openflow Connector for Amazon Kinesis Data Streams source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/kinesis/setup.md section: Loading & Unloading Data --- # Set up %kinesis% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [Openflow Connector for Amazon Kinesis Data Streams](/user-guide/data-integration/openflow/connectors/kinesis/about) - [Maintain Openflow Connector for Amazon Kinesis Data Streams](/user-guide/data-integration/openflow/connectors/kinesis/maintenance) - [Troubleshooting the Openflow Connector for Amazon Kinesis Data Streams](/user-guide/data-integration/openflow/connectors/kinesis/troubleshoot) - [Performance tuning of the Openflow Connector for Amazon Kinesis Data Streams](/user-guide/data-integration/openflow/connectors/kinesis/performance-tuning) This topic describes how to set up %kinesis%. %kinesis% is designed for JSON message ingestion from Kinesis streams to Snowflake tables, with schema evolution capabilities. ## Set up the Openflow Connector for Kinesis ### Prerequisites 1. Review [Openflow Connector for Amazon Kinesis Data Streams](/user-guide/data-integration/openflow/connectors/kinesis/about). 2. Ensure that you have [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) or [Set up Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/setup-openflow-spcs). 3. If you are using Openflow - Snowflake Deployments, ensure that you have reviewed [configuring required domains](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list) and have granted access to the required domains for the Kinesis connector. ### Set up IAM roles and policies in AWS As an AWS administrator, perform the following actions in your AWS account: 1. Create an AWS IAM user or role that Openflow will use to access the Kinesis data stream. For more information, see Creating IAM users (https://docs.aws.amazon.com/IAM/latest/UserGuide/id_users_create.html) in the AWS documentation. 2. Ensure that the AWS user has configured Access Key credentials (https://docs.aws.amazon.com/IAM/latest/UserGuide/id_credentials_access-keys.html). 3. Grant the AWS user the following IAM permissions:
Example IAM policy: ```json { "Version": "2012-10-17", "Statement": [ { "Sid": "KinesisStreamAccess", "Effect": "Allow", "Action": [ "kinesis:DescribeStream", "kinesis:DescribeStreamConsumer", "kinesis:GetRecords", "kinesis:GetShardIterator", "kinesis:ListShards", "kinesis:RegisterStreamConsumer" ], "Resource": "arn:aws:kinesis:${REGION}:${ACCOUNT_ID}:stream/${STREAM_NAME}" }, { "Sid": "KinesisConsumerAccess", "Effect": "Allow", "Action": [ "kinesis:DeregisterStreamConsumer", "kinesis:DescribeStreamConsumer", "kinesis:SubscribeToShard" ], "Resource": "arn:aws:kinesis:${REGION}:${ACCOUNT_ID}:stream/${STREAM_NAME}/consumer/*" }, { "Sid": "DynamoDBTableAccess", "Effect": "Allow", "Action": [ "dynamodb:CreateTable", "dynamodb:DeleteTable", "dynamodb:DescribeTable", "dynamodb:GetItem", "dynamodb:PutItem", "dynamodb:Query", "dynamodb:Scan", "dynamodb:UpdateItem" ], "Resource": [ "arn:aws:dynamodb:${REGION}:${ACCOUNT_ID}:table/${APPLICATION_NAME}", "arn:aws:dynamodb:${REGION}:${ACCOUNT_ID}:table/${APPLICATION_NAME}_migration" ] } ] } ``` Before using the example policy, replace the following placeholders:
- The `${APPLICATION_NAME}_migration` table is a temporary DynamoDB table created only during a one-time migration from legacy checkpoint tables to the new schema. It's deleted automatically when migration completes. If your deployment has never used the legacy KCL-based connector, you can omit the migration table ARN from the policy. - The `dynamodb:DeleteTable` action is used during the migration process and can be removed from the policy after migration is confirmed complete. - The `kinesis:DeregisterStreamConsumer` action is invoked when the processor is removed from the canvas. If the IAM principal doesn't have this permission, the consumer must be deregistered manually through the AWS console or CLI. ### Set up Snowflake account As a Snowflake account administrator, perform the following tasks: 1. Create a new Snowflake service user with the type as [SERVICE](#label-user-type-property). 2. Create a new role or use an existing role and grant the [database privileges](/sql-reference/sql/grant-privilege). The connector requires the user to create the destination table. Make sure the user has the required privileges for managing Snowflake objects:
Snowflake recommends creating a separate user and role for each Kinesis stream for better access control. You can use the following script to create and configure a custom role (requires SECURITYADMIN or equivalent): ```sql USE ROLE securityadmin; CREATE ROLE openflow_kinesis_connector_role_1; GRANT USAGE ON DATABASE kinesis_db TO ROLE openflow_kinesis_connector_role_1; GRANT USAGE ON SCHEMA kinesis_schema TO ROLE openflow_kinesis_connector_role_1; ``` Privileges must be granted directly to the connector role and can't be inherited. 3. Configure the destination table Snowflake recommends using server-side schema evolution for schema changes and [an error table for DML error logging](#label-kinesis-dml-error-logging). The example below shows how to create a table and add OWNERSHIP permissions. ```sql USE ROLE openflow_kinesis_connector_role_1; CREATE TABLE kinesis_db.kinesis_schema. ( kinesisMetadata object ) ENABLE_SCHEMA_EVOLUTION = TRUE ERROR_LOGGING = TRUE; USE ROLE securityadmin; GRANT OWNERSHIP ON TABLE TO ROLE openflow_kinesis_connector_role_1; ``` This connector provides support for automatic schema detection and evolution. The structure of tables in Snowflake is defined and evolved automatically to support the structure of new data loaded by the connector. It will automatically map the record content's first-level keys to table columns matching by name (case-insensitive). With Schema evolution enabled, Snowflake can automatically expand the destination table by adding new columns that are detected in the incoming stream and dropping NOT NULL constraints to accommodate new data patterns. For more information, see [Table schema evolution](/user-guide/data-load-schema-evolution). If ENABLE_SCHEMA_EVOLUTION is not enabled, then you have to create the schema manually by extending the table definition. The connector tries to match the record content's first-level keys to the table columns by name. If keys from the JSON do not match the table columns, the connector ignores the keys. 4. (Optional) Configure a secrets manager Snowflake strongly recommends this step. Configure a secrets manager supported by Openflow, for example, AWS, Azure, and HashiCorp, and store the public and private keys in the secret store. 1. Once the secrets manager is configured, determine how you will authenticate to it. On AWS, it's recommended that you use the EC2 instance role associated with Openflow as this way no other secrets have to be persisted. 2. In the Openflow canvas, configure a Parameter Provider associated with this Secrets Manager, from the hamburger menu in the upper right. Navigate to **Controller Settings** %raa% **Parameter Provider** and then fetch your parameter values. 3. At this point all credentials can be referenced with the associated parameter paths and no sensitive values need to be persisted within Openflow. 5. Grant access to users Any other Snowflake users who require access to the raw ingested data by the connector (for example, for custom processing in Snowflake), should be granted the role created in step 2. ### (Optional) Configure outbound AWS PrivateLink If you're running the connector in Openflow - Snowflake Deployments and want to route the connector's Kinesis traffic over [outbound private connectivity](/user-guide/private-connectivity-outbound) (AWS PrivateLink) instead of the public internet, follow the steps in this section. The connector makes outbound calls to the following AWS services:
Amazon DynamoDB doesn't support Private DNS for its PrivateLink endpoint. See Considerations when using AWS PrivateLink for Amazon DynamoDB (https://docs.aws.amazon.com/amazondynamodb/latest/developerguide/privatelink-interface-endpoints.html#privatelink-considerations) in the AWS documentation. Because Snowflake's `PRIVATE_HOST_PORT` network rule type relies on Private DNS, the connector can't route DynamoDB traffic through a PrivateLink endpoint. Configure DynamoDB using `HOST_PORT` (public endpoint) as shown in the example. Only checkpoint metadata flows through the public endpoint to DynamoDB. Stream records flow through the private Kinesis endpoint. To configure outbound AWS PrivateLink, complete the following steps: 1. As ACCOUNTADMIN, provision an outbound PrivateLink endpoint for Amazon Kinesis Data Streams in the region where your stream is located. Replace `` with your AWS region (for example, `us-east-1`): ```sql USE ROLE ACCOUNTADMIN; SELECT SYSTEM$PROVISION_PRIVATELINK_ENDPOINT( 'com.amazonaws..kinesis-streams', 'kinesis..amazonaws.com' ); ``` For more information, see [SYSTEM$PROVISION_PRIVATELINK_ENDPOINT](/sql-reference/functions/system_provision_privatelink_endpoint) and [Managing outbound private connectivity endpoints on AWS](/user-guide/private-manage-endpoints-aws). 2. Create network rules that reach `kinesis..amazonaws.com` through the private endpoint and DynamoDB through the public endpoint. Replace `` with the schema you use to host network rules: ```sql USE ROLE ACCOUNTADMIN; USE SCHEMA ; CREATE OR REPLACE NETWORK RULE openflow_kinesis_private_network_rule MODE = EGRESS TYPE = PRIVATE_HOST_PORT VALUE_LIST = ('kinesis..amazonaws.com'); CREATE OR REPLACE NETWORK RULE openflow_kinesis_public_network_rule MODE = EGRESS TYPE = HOST_PORT VALUE_LIST = ('dynamodb..amazonaws.com:443'); ``` 3. Attach both network rules to an external access integration, then grant the execute-as role permission to use the integration: ```sql USE ROLE ACCOUNTADMIN; CREATE OR REPLACE EXTERNAL ACCESS INTEGRATION openflow_kinesis_eai ALLOWED_NETWORK_RULES = ( openflow_kinesis_private_network_rule, openflow_kinesis_public_network_rule ) ENABLED = TRUE COMMENT = 'External access integration for the Openflow Connector for Kinesis'; GRANT USAGE ON INTEGRATION openflow_kinesis_eai TO ROLE OPENFLOW__EXECUTE_AS_RL; ``` For the steps to associate the integration with a runtime, see [Set up Openflow - Snowflake Deployment: Configure allowed domains for Openflow connectors](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list). ### Set up the connector As a data engineer, perform the following tasks to install and configure the connector: #### Install the connector 1. Navigate to the Openflow overview page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find the **Openflow connector for Amazon Kinesis Data Streams** and select **Install**. 3. In the Select runtime dialog, select your runtime from the **Available runtimes** drop-down list and click **Add**. Before you install the connector, ensure that you have created a database, schema, and a table in Snowflake for the connector to store ingested data. 4. Authenticate to the deployment with your Snowflake account credentials and select **Allow** when prompted to allow the runtime application to access your Snowflake account. The connector installation process takes a few minutes to complete. 5. Authenticate to the runtime with your Snowflake account credentials. The Openflow canvas appears with the connector process group added to it. #### Configure the connector 1. If needed, customize the connector configuration before configuring the built-in parameters. 2. Populate the process group parameters 1. Right-click on the imported process group and select **Parameters**. 2. Fill out the required parameter values. ##### Common parameters
#### Start the connector 1. Right-click on the canvas and select **Enable all Controller Services**. 2. Right-click on the canvas and select **Start**. The connector starts data ingestion. ## Understanding the KINESISMETADATA column The connector populates the KINESISMETADATA structure with metadata about the Kinesis record. The structure contains the following information:
## Measuring ingestion latency For change tracking, incremental processing, and Time Travel queries based on row modification time, the ROW_TIMESTAMP feature can be used. It can be enabled by running the following command on your destination table: ```sql ALTER TABLE SET ROW_TIMESTAMP = TRUE; ``` After row timestamps are enabled, tables expose the `METADATA$ROW_LAST_COMMIT_TIME` column, which returns the timestamp when each row was last modified. For more information, see [Row timestamps](/user-guide/data-engineering/row-timestamps). Row timestamp isn't available for interactive tables. For more information, see [](#label-limitations-of-interactive-tables). ## Using the connector with Apache Iceberg™ tables The connector can ingest data into a Snowflake-managed Apache Iceberg™ table. The connector doesn't create Iceberg tables automatically. You must create the Iceberg table manually before you run the connector. The connector supports server-side schema evolution for Iceberg destination tables, the same way it does for standard Snowflake tables. When the destination table has `ENABLE_SCHEMA_EVOLUTION = TRUE`, Snowflake automatically adds new columns that are detected in the incoming stream and drops NOT NULL constraints to accommodate new data patterns. For more information about how schema evolution behaves, see [Table schema evolution](/user-guide/data-load-schema-evolution). The Iceberg table can use either of the following storage options: - [Snowflake storage](/user-guide/tables-iceberg-internal-storage): Snowflake stores and manages the Iceberg table files for you, so you don't need to create an external volume or grant the connector access to it. - External cloud storage that you manage, accessed through an external volume. You must grant the connector role USAGE on the external volume. ### Grant usage on an external volume This step applies only when the Iceberg table uses an external volume that you manage. If the table uses [Snowflake storage](/user-guide/tables-iceberg-internal-storage), skip this step. For example, if your Iceberg table uses the `kinesis_external_volume` external volume and the connector uses the role `openflow_kinesis_connector_role_1`, run the following statement: ```sql USE ROLE ACCOUNTADMIN; GRANT USAGE ON EXTERNAL VOLUME kinesis_external_volume TO ROLE openflow_kinesis_connector_role_1; ``` ### Create an Apache Iceberg™ table for ingestion When you create an Iceberg table, you can use Iceberg data types (including VARIANT) or [compatible Snowflake types](/user-guide/tables-iceberg-data-types). For example, consider the following message: ```json { "id": 1, "name": "Steve", "body_temperature": 36.6, "approved_coffee_types": ["Espresso", "Doppio", "Ristretto", "Lungo"], "animals_possessed": { "dogs": true, "cats": false }, "options": { "can_walk": true, "can_talk": false }, "date_added": "2024-10-15" } ``` To create an Iceberg table for the example message, use one of the following statements. To use [Snowflake storage](/user-guide/tables-iceberg-internal-storage), set `EXTERNAL_VOLUME = 'SNOWFLAKE_MANAGED'` and omit `BASE_LOCATION`: ```sql CREATE OR REPLACE ICEBERG TABLE my_iceberg_table ( kinesisMetadata OBJECT( stream STRING, shardId STRING, approximateArrival STRING, partitionKey STRING, sequenceNumber STRING, subSequenceNumber INTEGER, shardedSequenceNumber STRING ), id INT, name string, body_temperature float, approved_coffee_types array(string), animals_possessed variant, date_added date, options object(can_walk boolean, can_talk boolean) ) EXTERNAL_VOLUME = 'SNOWFLAKE_MANAGED' CATALOG = 'SNOWFLAKE' ICEBERG_VERSION = 3; ``` To use your own external volume, set `EXTERNAL_VOLUME` to the volume name and provide a `BASE_LOCATION`: ```sql CREATE OR REPLACE ICEBERG TABLE my_iceberg_table ( kinesisMetadata OBJECT( stream STRING, shardId STRING, approximateArrival BIGINT, partitionKey STRING, sequenceNumber STRING, subSequenceNumber INTEGER, shardedSequenceNumber STRING ), id INT, name string, body_temperature float, approved_coffee_types array(string), animals_possessed variant, date_added date, options object(can_walk boolean, can_talk boolean) ) EXTERNAL_VOLUME = 'my_volume' CATALOG = 'SNOWFLAKE' BASE_LOCATION = 'my_location/my_iceberg_table' ICEBERG_VERSION = 3; ``` ## Using the connector with Interactive Tables Interactive tables are a special type of Snowflake table optimized for low-latency, high-concurrency queries. You can find out more about interactive tables in the [interactive tables documentation](/user-guide/interactive). 1. Create an interactive table: ```sql CREATE INTERACTIVE TABLE REALTIME_METRICS ( metric_name VARCHAR, metric_value NUMBER, source_stream VARCHAR, approximate_arrival NUMBER ) CLUSTER BY (metric_name) AS (SELECT $1:M_NAME::VARCHAR, $1:M_VALUE::NUMBER, $1:kinesisMetadata.stream::VARCHAR, $1:kinesisMetadata.approximateArrival::NUMBER from TABLE(DATA_SOURCE(TYPE => 'STREAMING'))); ``` Important considerations: - Interactive tables have specific limitations and query restrictions. Review the [interactive tables documentation](/user-guide/interactive) before using them with the connector. - For interactive tables, any required transformations must be handled in the table definition. - Interactive warehouses are required to query interactive tables efficiently. ## Using the connector with a customer-defined schema for the destination table The connector treats each Kinesis record as a row to be inserted into a Snowflake table. For example, if you have a Kinesis stream with the content of the message structured like the following JSON: ```json { "order_id": 12345, "customer_name": "John", "order_total": 100.00, "isPaid": true } ``` By default you don't have to specify all fields from the JSON. Schema evolution will take care of it. However, if you prefer a static schema, it can be created by running: ```sql CREATE TABLE ORDERS ( kinesisMetadata OBJECT, order_id NUMBER, customer_name VARCHAR, order_total FLOAT, ispaid BOOLEAN ); ``` ## Using the connector with a customer-defined PIPE If you choose to create your own pipe, you can define the data transformation logic in the pipe's [COPY INTO](/sql-reference/sql/copy-into-table) statement. You can rename columns as required and cast the data types as needed. For example: ```sql CREATE TABLE ORDERS ( order_id VARCHAR, customer_name VARCHAR, order_total VARCHAR, ispaid VARCHAR ); CREATE PIPE ORDERS AS COPY INTO ORDERS FROM ( SELECT $1:order_id::STRING, $1:customer_name, $1:order_total::STRING, $1:isPaid::STRING FROM TABLE(DATA_SOURCE(TYPE => 'STREAMING')) ); ``` When you define your own pipe your destination table columns do not have to match the JSON keys. You can rename the columns to your desired names and cast the data types if required. To adjust the connector to work with a custom pipe, perform the following tasks: 1. Right-click on the PublishSnowpipeStreaming processor used in your Kinesis ingestion flow in the Openflow canvas. 2. Select **Configure** from the context menu. 3. Navigate to the **Properties** tab. 4. In the Destination type field, pick **Pipe**. 5. In the Pipe field, type the name of your pipe. 6. Select **Apply** to save the configuration. ## Customizing error handling Error handling is split between Openflow-side failures and server-side failures within the Snowpipe Streaming service. - **Openflow Errors (Client-Side Failures)**: Errors such as unparseable payloads or custom transformation failures occur before records reach Snowflake. By default these records are discarded. It's possible to process these errors in Openflow - use FlowFiles from the parse failure relationship in the ConsumeKinesis processor. For a complete walkthrough, see [Kinesis as destination for DLQ messages](configuring-dead-letter-queue-handling) and the shared [Configuring Dead Letter Queue (DLQ) handling](/user-guide/data-integration/openflow/connectors/streaming/configuring-dead-letter-queue-handling). - **Snowpipe Streaming Errors (Server-Side Failures)**: Errors for records that successfully reach Snowflake but are incompatible with the destination table's schema (for example, type mismatches) are captured by the Snowflake infrastructure. When error logging is enabled on the destination table (`error_logging = true`), these failed rows are automatically ingested into the destination Error table. ## Next steps - [Performance tuning of the Openflow Connector for Amazon Kinesis Data Streams](/user-guide/data-integration/openflow/connectors/kinesis/performance-tuning) - [Maintain Openflow Connector for Amazon Kinesis Data Streams](/user-guide/data-integration/openflow/connectors/kinesis/maintenance) - [Troubleshooting the Openflow Connector for Amazon Kinesis Data Streams](/user-guide/data-integration/openflow/connectors/kinesis/troubleshoot) - [Openflow Connector for Kinesis Data Streams: Configuring DLQ handling](/user-guide/data-integration/openflow/connectors/kinesis/configuring-dead-letter-queue-handling) - [Configuring custom transformations](/user-guide/data-integration/openflow/connectors/streaming/configuring-custom-transformations) --- title: Set up PrivateLink UI access in Openflow - Snowflake Deployments source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/setup-openflow-spcs-configure-pr-ui.md section: Loading & Unloading Data --- # Set up PrivateLink UI access in %ofsfspcs-plural% This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). - [About Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/about-spcs) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Monitor Openflow using telemetry data](/user-guide/data-integration/openflow/monitor) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) This topic explains how to configure access to the Snowflake Openflow Runtime UI using private connectivity. This is an optional task. If you will not be accessing the Openflow Runtime UI using public connectivity, you can skip this task. There are two tasks to configure access to the Snowflake Openflow Runtime UI using private connectivity: 1. [](#label-openflow-spcs-configure-pr-ui-access-ui) 2. [](#label-openflow-spcs-configure-pr-ui-create-deployment) ## Prerequisites Before configuring private link for the Openflow Runtime UI, enable PrivateLink for your account as described in [AWS PrivateLink and Snowflake](/user-guide/admin-security-privatelink). ## Determine PrivateLink URLs 1. Using the ACCOUNTADMIN role, call the SYSTEM$GET_PRIVATELINK_CONFIG function in your Snowflake account and identify the value for `openflow-privatelink-url`. This is the URL for accessing Openflow UI over PrivateLink in the form: - `-.openflow..privatelink.snowflakecomputing.cn` 2. The URL for accessing the Runtime UI in a Snowflake deployment will be in the form: - `of---.spcs..privatelink.snowflake.app` 3. Create CNAME records in your DNS to resolve these URL values to your VPC endpoint. 4. Confirm that your DNS settings can resolve the value. 5. Confirm that you can connect to Openflow UI using this URL from your browser. 6. Confirm that you can connect to Runtime UI using this URL from your browser. ## Configure PrivateLink for Openflow Runtime UI access Perform the following steps: 1. Retrieve Snowflake's VPC endpoint service ID and Openflow PrivateLink URLs: 1. As a user with the ACCOUNTADMIN role, execute ```sql SELECT SYSTEM$GET_PRIVATELINK_CONFIG(); ``` 1. From the output, identify and save the values for the following keys: - `privatelink-vpce-id` - `openflow-privatelink-url` - `external-telemetry-privatelink-url` 2. Construct the Runtime URL - `of---.spcs..privatelink.snowflake.app` 2. Create a VPC endpoint with parameters: If the Snowflake account where you plan to create your Openflow Deployment had previously configured PrivateLink for %sf-web-interface%, use the existing AWS VPC endpoint and add the additional OpenFlow DNS records to your Route 53. - Type: `PrivateLink Ready partner services` - Service: `privatelink-vpce-id` value obtained in the previous step. - VPC: The VPC where your Openflow deployment will be running. - Subnets: Select two availability zones and private subnets where your Openflow deployment will run. 3. Set up a Route 53 private hosted zone for Openflow UI with the following parameters: - Domain: `privatelink.snowflakecomputing.cn` - Type: `Private hosted zone` - Select the region and VPC where your Openflow deployment will run. 4. Set up a Route 53 private hosted zone for Openflow UI with the following parameters: - Domain: `privatelink.snowflakecomputing.cn` - Type: `Private hosted zone` - Select the region and VPC where your Openflow deployment will run. 5. Set up a Route 53 private hosted zone for Runtime UI with the following parameters: - Domain: `privatelink.snowflake.app` - Type: `Private hosted zone` - Select the region and VPC where your Openflow deployment will run. 6. Add two CNAME records for the URLs identified in the first step: - For `openflow-privatelink-url` - Record name: `openflow-privatelink-url` value obtained in the first step - Record type: `CNAME` - Value: DNS name of your VPC endpoint - For Runtime UI URL - Record name: `openflow-runtime-ui-privatelink-url` value obtained in the first step - Record type: `CNAME` - Value: DNS name of your VPC endpoint When creating a new %ofsfspcs%, ensure the **PrivateLink** option is enabled. ### Next steps [Create deployment](/user-guide/data-integration/openflow/setup-openflow-spcs-deployment) --- title: Set up Salesforce Data Cloud for Zero-Copy source: https://docs.snowflake.cn/en/user-guide/data-integration/zero-copy/salesforce/setup-salesforce.md section: Loading & Unloading Data --- # Set up Salesforce Data Cloud for Zero-Copy - [About Salesforce Data Cloud and Snowflake](/user-guide/data-integration/zero-copy/about-salesforce-datacloud) - [Set up the Salesforce Data Cloud Zerocopy Connector](/user-guide/data-integration/zero-copy/salesforce/setup) - [Explore data products from Salesforce Data Cloud](/user-guide/data-integration/zero-copy/salesforce/explore-data-products) This topic describes the steps a Salesforce administrator must perform in Salesforce Data Cloud to authorize the connection to Snowflake and make data products available for querying. Complete these steps after the Snowflake administrator has created the Zerocopy Connector and provided the Enrollment ID. See [Set up the Salesforce Data Cloud Zerocopy Connector](/user-guide/data-integration/zero-copy/salesforce/setup). ## Prerequisites Before starting, ensure: - You have the **Data Cloud Architect** permission set in Salesforce. - Your Salesforce org is enabled for the Snowflake V2 pilot. - You have the **Enrollment ID** from your Snowflake administrator. This value is generated when the Zerocopy Connector is created in Snowflake and is available in Snowsight or via `SYSTEM$GET_ZEROCOPY_CONNECTOR_CONFIG`. If you have an existing data share linked to a legacy Snowflake data share target, migrate it to the Snowflake V2 data share target before proceeding. Link the data share to the Snowflake V2 target first, verify it's working, then unlink from the legacy target. ## Create a Data Share A Data Share defines which Salesforce Data 360 objects are made available to Snowflake. Each data share you link to the connector appears as a mountable data product on the Snowflake side. Required permission: **Data Cloud Architect** permission set. 1. In Salesforce, navigate to **Data 360** %raa% **Data Shares**. 2. Click **New**. 3. Enter the following details and click **Next**: - **Label**: Display name for the data share. - **Name**: API name. Auto-populated from the label; you can change it. - **Data Space**: Select **Default** if no other data space is provisioned in your org. - **Provide consent**: Check to allow admins or privileged users in the receiving Snowflake account to view and query all records of the data lake objects (DLOs) mapped to data model objects (DMOs) in the share. - **Description**: Optional. To comply with data policies and regulations, data sharing automatically includes the `IndividualGDPRState__dll` object, which provides consent information. Use the Individual ID to honor consent data for individuals at the share target. 4. Select the Data 360 objects to include in the data share. You can't share an external data lake object (DLO) or a data model object (DMO) that is mapped to an external DLO. 5. Click **Save**. ## Create a Data Share Target A Data Share Target represents the Snowflake account that receives the shared data. The Enrollment ID from Snowflake authorizes the connection. Required permission: **Data Cloud Architect** permission set. 1. In Salesforce, navigate to **Data Cloud** %raa% **Data Share Targets**. 2. Click **New**. 3. For the connection type, select **Snowflake V2** and click **Next**. 4. Enter the following details: - **Label**: Display name for the data share target. - **API Name**: Auto-populated from the label; you can change it. - **Enrollment ID**: Paste the Enrollment ID provided by your Snowflake administrator. - **Description**: Optional. 5. Click **Save**. ## Link the Data Share to the Data Share Target Linking makes the data share available to the connected Snowflake account. Until a data share is linked to a target, it doesn't appear in Snowflake. Required permission: **Data Cloud Architect** permission set. 1. In Salesforce, navigate to **Data 360** %raa% **Data Shares**. 2. Click the data share you want to link. 3. On the data share record, click **Link/Unlink Data Share Target**. 4. Select the Snowflake V2 data share target you created in the previous step. To unlink, follow the same process and deselect the target instead. 5. Click **Save**. Don't unlink a data share from a legacy Snowflake data share target before confirming the Snowflake V2 link is working. Downstream processes in Snowflake may still reference the database created from the legacy target. After linking, the data shares will appear in the Zerocopy Connector in Snowflake. To confirm, use `SYSTEM$ZEROCOPY_CONNECTOR_LIST_SHARES`. Linked data share targets are listed on the data share record home page. ## Next steps Return to Snowflake to list available data products and create catalog-linked databases. See [Explore data products from Salesforce Data Cloud](/user-guide/data-integration/zero-copy/salesforce/explore-data-products). --- title: Set Up SAP® BDC Connect for Snowflake Zerocopy Connector source: https://docs.snowflake.cn/en/user-guide/data-integration/zero-copy/sap-sql/setup.md section: Loading & Unloading Data --- # Set up %sapbdc% Zerocopy Connector - [About Snowflake and SAP® Zero-Copy Integration](/user-guide/data-integration/zero-copy/about-sap-snowflake) - [SAP® Snowflake](/user-guide/data-integration/zero-copy/sap-sql/setup-sap-snowflake) - [SAP® BDC Connect for Snowflake](/user-guide/data-integration/zero-copy/sap-sql/setup-sap-bdc) - [SAP® BDC Connect for Snowflake Zerocopy Connector — Security and Privileges](/user-guide/data-integration/zero-copy/sap-sql/security) - [Explore Data Products from SAP® BDC Connect for Snowflake](/user-guide/data-integration/zero-copy/sap-sql/explore-data-products) - [Publish Data from Snowflake to SAP® BDC Connect for Snowflake](/user-guide/data-integration/zero-copy/sap-sql/publish-data) The [`manage-zerocopy-sapbdc`](/user-guide/cortex-code/bundled-skills#label-bundled-skill-manage-zerocopy-sapbdc) skill manages the end-to-end lifecycle of the SAP and Snowflake Zero-Copy Integration and connector — creating connectors, consuming data products from SAP® BDC, publishing Snowflake data to SAP® BDC, analyzing shared data, and troubleshooting issues, all through a conversational, step-by-step workflow. This skill is now bundled with Cortex Code (CoCo), and you can use it to automate the steps in this topic. The Zerocopy Connector is subject to the [SAP® BDC Connect for Snowflake Terms](https://www.snowflake.cn/en/legal/optional-offerings/offering-specific-terms/sap-bdc-connect-snowflake/). The steps to share Data Products from SAP® BDC to SAP® Snowflake accounts and existing Snowflake accounts that use the SAP® BDC Connect for Snowflake are exactly the same. This topic describes how to create and manage a Zerocopy Connector for %sapbdc% on the Snowflake side. For the SAP® side setup, see [SAP® Snowflake](/user-guide/data-integration/zero-copy/sap-sql/setup-sap-snowflake) or [SAP® BDC Connect for Snowflake](/user-guide/data-integration/zero-copy/sap-sql/setup-sap-bdc). For the privileges required for each operation, see [SAP® BDC Connect for Snowflake Zerocopy Connector — Security and Privileges](/user-guide/data-integration/zero-copy/sap-sql/security). ## Prerequisites Before creating a Zerocopy Connector: - An `ORGADMIN` must accept the SAP® BDC Connect for Snowflake Terms. This only needs to be done once per Snowflake organization. Terms of Service cannot be self-revoked — contact Snowflake support and legal to revoke them. To accept the SAP® BDC Connect for Snowflake Terms in Snowsight: 1. Sign in to Snowflake as a user with the `ORGADMIN` role. 2. In the navigation menu, select **Admin** %raa% **Terms**. 3. In the **Snowflake Marketplace** section, next to **SAP® BDC Connect for Snowflake Terms**, select **Review**. 4. Select **Acknowledge & Continue**. - Complete the SAP® side setup described in [SAP® Snowflake](/user-guide/data-integration/zero-copy/sap-sql/setup-sap-snowflake) or [SAP® BDC Connect for Snowflake](/user-guide/data-integration/zero-copy/sap-sql/setup-sap-bdc). - The role used to create the connector must have `CREATE ZEROCOPY CONNECTOR` on the target schema. By default, the owner role of a schema has this privilege. ## Create a database and schema A Zerocopy Connector is a schema-level object. Before creating one, ensure you have a target database and schema, or create new ones. For reference, see [CREATE DATABASE](/sql-reference/sql/create-database) and [CREATE SCHEMA](/sql-reference/sql/create-schema). ```sql CREATE DATABASE IF NOT EXISTS my_db; CREATE SCHEMA IF NOT EXISTS my_db.my_schema; ``` ## Create a Zerocopy Connector A Zerocopy Connector is a schema-level object. You can specify a fully qualified name (`..`), a partially qualified name, or a plain name when the database and schema are set in the current session context. ```sql CREATE [ OR REPLACE ] ZEROCOPY CONNECTOR [ IF NOT EXISTS ] PARTNER = SAP_BDC; ``` ```sql CREATE ZEROCOPY CONNECTOR IF NOT EXISTS my_db.my_schema.my_sap_connector PARTNER = SAP_BDC; ``` After creation, the connector is in `NEW` state. No connection is established until you run `ALTER ... CONNECT`. ## Enroll with SAP® BDC The connector must be in `NEW`, `CONNECT_ERROR`, or `DISCONNECTED` state. See [](#connector-states) for details. ```sql ALTER ZEROCOPY CONNECTOR IF EXISTS my_db.my_schema.my_sap_connector CONNECT WITH CONFIG = ( INVITATION_LINK = '' ); ``` The connector immediately enters `CONNECTING` state while the connection is established asynchronously. Use `DESC ZEROCOPY CONNECTOR` to check the current state. ### Verify connector state Use `DESCRIBE` to check the current state of a connector: ```sql DESC ZEROCOPY CONNECTOR my_db.my_schema.my_sap_connector; ``` #### Output
To list all connectors visible to the current role: ```sql SHOW ZEROCOPY CONNECTORS IN SCHEMA my_db.my_schema; SHOW ZEROCOPY CONNECTORS IN DATABASE my_db; SHOW ZEROCOPY CONNECTORS IN ACCOUNT; ``` ## Set properties You can set optional properties on a connector using `ALTER ... SET`: ```sql -- Set a comment ALTER ZEROCOPY CONNECTOR IF EXISTS my_db.my_schema.my_sap_connector SET COMMENT = 'SAP BDC connector for sales data products'; -- Enabling share back allows publishing data from Snowflake to SAP BDC ALTER ZEROCOPY CONNECTOR IF EXISTS my_db.my_schema.my_sap_connector SET SHARE_BACK = TRUE; ``` To unset a property and restore its default value: ```sql ALTER ZEROCOPY CONNECTOR IF EXISTS my_db.my_schema.my_sap_connector UNSET COMMENT; ALTER ZEROCOPY CONNECTOR IF EXISTS my_db.my_schema.my_sap_connector UNSET SHARE_BACK; ``` ## Disconnect the connector All catalog-linked databases created from the connector must be dropped before disconnecting. Share-back must be disabled before disconnecting. The connector must be in `CONNECTED` or `DISCONNECT_ERROR` state. ```sql ALTER ZEROCOPY CONNECTOR IF EXISTS my_db.my_schema.my_sap_connector DISCONNECT; ``` The connector immediately enters `DISCONNECTING` state while the connection is dropped asynchronously. When successful, it transitions to `DISCONNECTED`. ## Drop the connector You can only drop a connector that is in `NEW`, `CONNECT_ERROR`, `DISCONNECT_ERROR`, or `DISCONNECTED` state. Zerocopy Connectors do not support `UNDROP`. ```sql DROP ZEROCOPY CONNECTOR IF EXISTS my_db.my_schema.my_sap_connector; ``` ## Next steps Once the connector is in `CONNECTED` state, you can: - List available SAP® data products and create catalog-linked databases. See [Explore Data Products from SAP® BDC Connect for Snowflake](/user-guide/data-integration/zero-copy/sap-sql/explore-data-products). - Publish Snowflake data back to SAP® BDC. See [Publish Data from Snowflake to SAP® BDC Connect for Snowflake](/user-guide/data-integration/zero-copy/sap-sql/publish-data). --- title: Set up Snowflake for Workday Live Data Query source: https://docs.snowflake.cn/en/user-guide/data-integration/zero-copy/workday/snowflake-setup.md section: Loading & Unloading Data --- # Set up Snowflake for Workday Live Data Query Available to all accounts. - [About Workday Live Data Query for Snowflake](/user-guide/data-integration/zero-copy/about-workday-ldq) - [Connect to Workday and query data from Snowflake](/user-guide/data-integration/zero-copy/workday/connect-and-query) - [Troubleshoot Workday Live Data Query](/user-guide/data-integration/zero-copy/workday/troubleshooting) Workday Live Data Query for Snowflake is in Early Adopter (EA) for Workday and in Preview for Snowflake. To request access, contact your Workday account representative. This topic describes how to create the Snowflake objects needed to connect to the Workday Live Data Query (LDQ) service: a dedicated role and user, a database and schema, a stage to hold the Python connector, a network rule to allow outbound traffic to Workday, a secret to store your private key, and an external access integration to tie them together. Complete these steps before creating a Snowflake Notebook. See [About Workday Live Data Query for Snowflake](/user-guide/data-integration/zero-copy/about-workday-ldq) for the full setup checklist. ## Step 1: Download the Python connector The Workday LDQ connector ships as a `.whl` (wheel) file. Download it from the Workday Community portal before starting the Snowflake setup so it's available to upload in a later step. 1. Sign in to Workday Community (https://community.workday.com) with your Workday credentials. 2. Download the latest `.whl` file (for example, `ldq_python_client-1.0.3-py3-none-any.whl`) to your local computer. The download may be packaged as a zip file named `Datacloud-LiveDataQueryPython.zip`. 3. If you downloaded a zip file, extract it to get the `.whl` file. You must have a valid Workday customer or partner account to access the download. If you can't find the file, contact your Workday account representative. ## Step 2: Create a role and user Create a dedicated role and user for LDQ instead of using `ACCOUNTADMIN`. This role will have only the minimum privileges needed to create and manage the LDQ objects. This step requires `ACCOUNTADMIN` (or `SECURITYADMIN` + `SYSADMIN`). All subsequent steps use the new `WORKDAY_LDQ_TEST_ROLE` role. You can complete this step using SQL or Snowsight. ### Using SQL In Snowsight, go to **Projects** > **Worksheets**, click **+ Worksheet**, set your role to `ACCOUNTADMIN`, and run: ```sql -- Create the role CREATE ROLE IF NOT EXISTS WORKDAY_LDQ_TEST_ROLE; -- Create a dedicated user and assign the role CREATE USER IF NOT EXISTS WORKDAY_LDQ_TEST_USER DEFAULT_ROLE = WORKDAY_LDQ_TEST_ROLE MUST_CHANGE_PASSWORD = TRUE PASSWORD = ''; GRANT ROLE WORKDAY_LDQ_TEST_ROLE TO USER WORKDAY_LDQ_TEST_USER; -- Grant account-level privileges needed for setup GRANT CREATE DATABASE ON ACCOUNT TO ROLE WORKDAY_LDQ_TEST_ROLE; GRANT CREATE INTEGRATION ON ACCOUNT TO ROLE WORKDAY_LDQ_TEST_ROLE; GRANT USAGE ON WAREHOUSE COMPUTE_WH TO ROLE WORKDAY_LDQ_TEST_ROLE; ``` Replace `COMPUTE_WH` with the name of the warehouse you plan to use. After the database and schema are created in the next step, `WORKDAY_LDQ_TEST_ROLE` automatically owns those objects and has full privileges on them. ### Using Snowsight 1. Navigate to **Admin** > **Users & Roles** > **Roles**. 2. Click **+ Role**, enter `WORKDAY_LDQ_TEST_ROLE`, and click **Create Role**. 3. Navigate to **Admin** > **Users & Roles** > **Users**. 4. Click **+ User**, enter `WORKDAY_LDQ_TEST_USER`, set the default role to `WORKDAY_LDQ_TEST_ROLE`, and click **Create User**. 5. Grant the role to the user and the account-level privileges as shown in the SQL above. Switch to `WORKDAY_LDQ_TEST_ROLE` for all remaining steps. You no longer need `ACCOUNTADMIN`. ## Step 3: Create a database and schema Create a dedicated database and schema to hold the LDQ stage, network rule, secret, and integration. ### Using SQL Open a Snowflake worksheet, set your role to `WORKDAY_LDQ_TEST_ROLE`, and run: ```sql CREATE DATABASE IF NOT EXISTS WORKDAY_LDQ_TEST; CREATE SCHEMA IF NOT EXISTS WORKDAY_LDQ_TEST.LIVEDATA; ``` ### Using Snowsight 1. Navigate to **Catalog** > **Database Explorer**. 2. Click **+ Database**, enter `WORKDAY_LDQ_TEST`, and click **Create**. 3. Open the new database, click **+ Schema**, enter `LIVEDATA`, and click **Create**. ## Step 4: Create a stage for the Python connector Create a Snowflake internal stage to store the wheel file so it can be installed inside your notebook. Create the stage first, then upload the file you downloaded in Step 1. ### Create the stage 1. In Snowsight, navigate to **Catalog** > **Database Explorer**. 2. Search for `WORKDAY_LDQ_TEST` and click on it. 3. Click **Schemas**, then **LIVEDATA**, then **Stages**. 4. Click **+ Stage** > **Snowflake Managed**. 5. Enter `LDQ_STAGE` as the name, enable **Directory table**, and click **Create**. ### Upload the wheel file 1. Open the `LDQ_STAGE` stage. 2. Click the **Files** tab, then **+ Files**. 3. Select the `.whl` file from your local computer. 4. Click **Upload**. ## Step 5: Create a network rule By default, Snowflake Notebooks can't make outbound network calls. A network rule defines which external hosts are permitted. Create one that allows HTTPS traffic to your Workday host (for OAuth2 and the live data service) and to PyPI (so `pip install` can download the connector's dependencies). ### Using SQL In the same worksheet (with `WORKDAY_LDQ_TEST_ROLE`), run: ```sql CREATE OR REPLACE NETWORK RULE WORKDAY_LDQ_TEST.LIVEDATA.WORKDAY_LDQ_TEST_RULE MODE = EGRESS TYPE = HOST_PORT VALUE_LIST = ( 'impl-services1.wd12.myworkday.com:443', 'pypi.org:443', 'files.pythonhosted.org:443' ); ``` ### Using Snowsight 1. Navigate to **Admin** > **Security** > **Network Rules**. 2. Click **+ Network Rule** and fill in the following fields: - **Name:** `WORKDAY_LDQ_TEST_RULE` - **Database / Schema:** `WORKDAY_LDQ_TEST` / `LIVEDATA` - **Type:** Host & Port - **Mode:** Egress - **Hosts:** `impl-services1.wd12.myworkday.com:443`, `pypi.org:443`, `files.pythonhosted.org:443` 3. Click **Create Network Rule**. Replace `impl-services1.wd12.myworkday.com` with the host from your token endpoint URL. The same host serves both the data service and the token endpoint. The `pypi.org` and `files.pythonhosted.org` entries are required so that `pip install` can download the connector's dependencies at notebook runtime. ## Step 6: Store the private key as a Snowflake secret Store the RSA private key as a Snowflake secret to prevent it from being hardcoded in notebooks or configuration files. The secret is encrypted at rest and only accessible to notebooks granted access through the external access integration in Step 7. ### Using SQL In the same worksheet, run: ```sql CREATE SECRET WORKDAY_LDQ_TEST.LIVEDATA.WORKDAY_PRIVATE_KEY TYPE = GENERIC_STRING SECRET_STRING = '-----BEGIN RSA PRIVATE KEY----- -----END RSA PRIVATE KEY-----'; ``` Paste the PEM content directly into the SQL worksheet. Don't save it to a file or share it in plain text. Once created, the secret value can't be retrieved via SQL. ### Using Snowsight 1. Navigate to **Admin** > **Security** > **Secrets**. 2. Click **+ Secret** and fill in the following fields: - **Name:** `WORKDAY_PRIVATE_KEY` - **Database / Schema:** `WORKDAY_LDQ_TEST` / `LIVEDATA` - **Type:** Generic String - **Secret value:** paste the full contents of `private-key.pem`, including the `-----BEGIN-----` and `-----END-----` lines 3. Click **Create Secret**. The secret value is encrypted at rest and can't be retrieved after creation through the UI or SQL. ## Step 7: Create an external access integration An external access integration (EAI) references the network rule and the private key secret, and acts as the Snowflake-level permission grant that allows a notebook to use both. You must attach the EAI to your notebook before any outbound calls to Workday succeed. Creating an external access integration requires the `CREATE INTEGRATION` privilege on the account, which was granted to `WORKDAY_LDQ_TEST_ROLE` in Step 2. ### Using SQL In the same worksheet, run: ```sql CREATE OR REPLACE EXTERNAL ACCESS INTEGRATION WORKDAY_LDQ_TEST_EAI ALLOWED_NETWORK_RULES = (WORKDAY_LDQ_TEST.LIVEDATA.WORKDAY_LDQ_TEST_RULE) ALLOWED_AUTHENTICATION_SECRETS = (WORKDAY_LDQ_TEST.LIVEDATA.WORKDAY_PRIVATE_KEY) ENABLED = TRUE; ``` ### Using Snowsight 1. Navigate to **Admin** > **Security** > **External Access Integrations**. 2. Click **+ External Access Integration** and fill in the following fields: - **Name:** `WORKDAY_LDQ_TEST_EAI` - **Allowed Network Rules:** select `WORKDAY_LDQ_TEST.LIVEDATA.WORKDAY_LDQ_TEST_RULE` - **Allowed Authentication Secrets:** select `WORKDAY_LDQ_TEST.LIVEDATA.WORKDAY_PRIVATE_KEY` - **Enabled:** toggle on 3. Click **Create External Access Integration**. ## Next steps With the Snowflake setup complete, continue to [Connect to Workday and query data from Snowflake](/user-guide/data-integration/zero-copy/workday/connect-and-query) to create a notebook, install the connector, and run your first queries. --- title: Set up tasks for the Openflow Connector for Oracle source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/oracle/setup-tasks.md section: Loading & Unloading Data --- # Set up tasks for the %oracleofc% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). The %oracleofc% is also subject to additional terms of service beyond the standard connector terms of service. For more information, see the [Openflow Connector for Oracle Addendum](https://www.snowflake.cn/en/legal/optional-offerings/offering-specific-terms/openflow-oracle-terms/). - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [About Openflow Connector for Oracle](/user-guide/data-integration/openflow/connectors/oracle/about) - [Openflow Connector for Oracle: Enable and manage commercial terms](/user-guide/data-integration/openflow/connectors/oracle/manage-commercial-terms) - [Openflow Connector for Oracle: Data mapping](/user-guide/data-integration/openflow/connectors/oracle/data-mapping) - [Openflow Connector for Oracle: Configure the Oracle database](/user-guide/data-integration/openflow/connectors/oracle/setup-oracledb) This topic describes the overall tasks required to set up, configure, and run the %oracleofc%. ## Prerequisites Before you set up the %oracleofc%, verify that the following prerequisites are met: 1. Ensure that you have reviewed [About Openflow Connector for Oracle](/user-guide/data-integration/openflow/connectors/oracle/about). 2. Ensure that you have set up an Openflow deployment: - [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) - [Set up Openflow - Snowflake Deployment](/user-guide/data-integration/openflow/setup-openflow-spcs) ## Tasks Perform the following tasks to set up, configure, and run the %oracleofc%.
## Next steps - [Monitor the flow](/user-guide/data-integration/openflow/monitor). - [Maintenance](/user-guide/data-integration/openflow/connectors/oracle/maintenance) for reinstalling the connector or changing the XStream position. --- title: Set up the Atlassian Jira Cloud (Agile) flow source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/jira-cloud/setup-agile.md section: Loading & Unloading Data --- # Set up the %jiraagile% flow This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [About Openflow Connector for Jira Cloud](/user-guide/data-integration/openflow/connectors/jira-cloud/about) - [Set up the Atlassian Jira Cloud (Core) flow](/user-guide/data-integration/openflow/connectors/jira-cloud/setup-core) - [Migrate from the legacy Openflow Connector for Jira Cloud](/user-guide/data-integration/openflow/connectors/jira-cloud/migrate-from-legacy) This topic describes the steps to install and configure the %jiraagile% flow, the agile flow of the %jira%. The core flow is documented separately in [Set up the Atlassian Jira Cloud (Core) flow](/user-guide/data-integration/openflow/connectors/jira-cloud/setup-core). The agile flow is independent of the core flow. It uses its own API token, parameter contexts, state service, and Snowflake destination configuration. Both flows can write to the same Snowflake database and schema, since they create tables with different names. ## Prerequisites 1. Ensure that you have reviewed [About Openflow Connector for Jira Cloud](/user-guide/data-integration/openflow/connectors/jira-cloud/about). 2. Ensure that you have [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) or [Set up Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/setup-openflow-spcs). 3. If using %OFSFSPCS-plural%, ensure that you've reviewed [configuring required domains](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list) and have granted access to the required domains for the [](#label-openflow-domains-used-by-openflow-connectors-jira-cloud) connector. ## Get the credentials As a Jira Cloud administrator, perform the following tasks in your Atlassian account. You can reuse the API token from the core flow or create a separate token. The core flow and agile flow can use the same token, but they always share the underlying Jira API rate budget regardless. 1. Navigate to the API tokens page (https://id.atlassian.com/manage-profile/security/api-tokens). 2. Select **Create API token with scopes**. 3. In the **Create an API token** dialog box, provide a descriptive name for the API token and select an expiration date for the API token. This can range from 1 to 365 days. 4. Select the API token app **Jira**. 5. Select the agile scopes listed in [Required API scopes](#label-jira-agile-api-scopes). 6. Select **Create token**. 7. In the **Copy your API token** dialog box, select **Copy** to copy your generated API token and then paste the token to the connector parameters, or save it securely. 8. Select **Close** to close the dialog box. ### Required API scopes Atlassian API tokens with scopes list both **classic** (broader, recommended) and **granular** (narrower) scopes. The agile flow uses Jira Software scopes. Classic scopes are the recommended starting set when Atlassian documents one. Use granular scopes when your organization requires a narrower token; a granular token needs every scope Atlassian lists for an endpoint, not just one. The `BOARD` table is always created, so every token needs the scopes in the `BOARD` row of the following table. The connector also calls `GET /rest/api/3/myself` (https://developer.atlassian.com/cloud/jira/platform/rest/v3/api-group-myself/#api-rest-api-3-myself-get) for connection verification. The `BOARD_ISSUE` ingestion path also calls this endpoint at startup to look up the Jira timezone. For this endpoint, use the classic scope `read:jira-user` or the granular scopes `read:application-role:jira`, `read:group:jira`, `read:user:jira`, and `read:avatar:jira`. To ingest a board, the API token owner must be able to view the board and its saved filter. A saved filter is visible when the token owner owns it or when it is shared with the token owner through a group, a project that the token owner can browse, or public access. For the `Enabled Tables` parameter that turns optional tables on, see [](#label-jira-agile-ingestion-parameters). The following table lists each destination table, the recommended classic scope when Atlassian documents one, the full set of granular scopes Atlassian documents for the endpoints, and links to the endpoints the connector calls:
If you reuse a single API token across both flows, combine these scopes with the core flow scopes documented in [](#label-jira-core-api-scopes). Tokens without scopes are also supported and grant access based solely on the API token owner's permissions. However, tokens with scopes are recommended for fine-grained access control. ## Set up Snowflake account If you've already completed the Snowflake account setup for the core flow, you can reuse the same role, service user, key pair, database, schema, and warehouse for the agile flow. The agile flow parameters point at this same Snowflake configuration. Otherwise, perform the following tasks: As a Snowflake account administrator, perform the following tasks: 1. Create a new role or use an existing role. 2. Create a new Snowflake service user with the type as [SERVICE](#label-user-type-property). 3. Grant the Snowflake service user the role you created in the previous steps. 4. Configure with [key-pair auth](/user-guide/key-pair-auth) for the Snowflake SERVICE user from step 2. 5. Configure a secrets manager supported by Openflow (recommended), for example, AWS, Azure, and HashiCorp, and store the public and private keys in the secret store. If for any reason, you don't want to use a secrets manager, then you are responsible for safeguarding the public key and private key files used for key-pair authentication according to the security policies of your organization. 1. After the secrets manager is configured, determine how you will authenticate to it. On AWS, use the EC2 instance role associated with Openflow as this way no other secrets have to be persisted. 2. In Openflow, configure a Parameter Provider associated with this Secrets Manager, from the main menu (⋮) in the upper-right corner. Navigate to **Controller Settings** %raa% **Parameter Provider** and then fetch your parameter values. 3. At this point, all credentials can be referenced with the associated parameter paths and no sensitive values need to be persisted within Openflow. 6. If any other Snowflake users require access to the tables ingested by the connector (for example, for custom processing in Snowflake), then grant those users the role created in step 1. 7. Create a database and schema in Snowflake for the connector to store ingested data. Grant the following [](#label-database-privileges) to the role created in the first step. ```sql CREATE DATABASE jira_destination_db; CREATE SCHEMA jira_destination_db.jira_destination_schema; GRANT USAGE ON DATABASE jira_destination_db TO ROLE ; GRANT USAGE ON SCHEMA jira_destination_db.jira_destination_schema TO ROLE ; GRANT CREATE TABLE ON SCHEMA jira_destination_db.jira_destination_schema TO ROLE ; ``` 8. Create a warehouse that the connector will use or use an existing one. Start with the smallest warehouse size, then experiment with size depending on the amount of data transferred. Large data volumes typically scale better with [multi-cluster warehouses](/user-guide/warehouses-multicluster), rather than larger warehouse sizes. 9. Ensure that the user with the role used by the connector has the required privileges to use the warehouse. If that's not the case then grant the required privileges to the role. ```sql CREATE WAREHOUSE jira_connector_warehouse WITH WAREHOUSE_SIZE = 'X-Small'; GRANT USAGE ON WAREHOUSE jira_connector_warehouse TO ROLE ; ``` ## Set up the connector The agile flow is shipped as the %jiraagile% process group. As a data engineer, perform the following tasks to install and configure it. ### Install the connector To install the connector, do the following as a data engineer: 1. Navigate to the Openflow overview page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find the connector and select **Install**. 3. In the **Select runtime** dialog, select your runtime from the **Available runtimes** drop-down list and click **Install**. Before you install the connector, ensure that you have created a database and schema in Snowflake for the connector to store ingested data. 4. Authenticate to the deployment with your Snowflake account credentials and select **Allow** when prompted to allow the runtime application to access your Snowflake account. The connector installation process takes a few minutes to complete. 5. Authenticate to the runtime with your Snowflake account credentials. The Openflow canvas appears with the connector process group added to it. After import, the agile flow appears on the canvas as the %jiraagile% process group. ### Configure the connector 1. Right-click on the imported %jiraagile% process group and select **Parameters**. 2. Populate the required parameter values as described in [Flow parameters](#label-jira-agile-flow-parameters). ### Flow parameters The agile flow uses its own separate parameter contexts. The Jira credentials and Snowflake destination must be configured independently from the core flow. Both flows can point to the same Snowflake destination database and schema. - [Jira Cloud (Agile) Source Parameters](#label-jira-agile-source-parameters): Used to establish connection with the Jira API. - [Jira Cloud (Agile) Destination Parameters](#label-jira-agile-destination-parameters): Used to establish connection with Snowflake. - [Jira Cloud (Agile) Ingestion Parameters](#label-jira-agile-ingestion-parameters): Used to define the configuration of data ingested from Jira. #### Jira Cloud (Agile) Source Parameters
#### Jira Cloud (Agile) Destination Parameters
#### Jira Cloud (Agile) Ingestion Parameters
## Run the flow 1. Right-click on the canvas and select **Enable all Controller Services**. 2. Right-click on the %jiraagile% process group and select **Start**. The flow starts the data ingestion. On first run, the flow creates the required Snowflake tables in the destination schema. See [](#label-jira-entities) for the full list of tables created by the agile flow and the parameters that control which optional tables are populated. ## Resetting the connector state If you want to restart the ingestion from scratch, clear the agile flow's ingestion state. The agile flow uses its own centralized state service rather than per-processor state. To reset the state, perform the following steps: 1. Right-click the %jiraagile% process group and select **Stop**. 2. Navigate to the **Controller Settings** for the process group. 3. Find the **StandardJiraIngestionStateService** controller service and select **View State**. 4. Select **Clear State**. This clears the agile flow's ingestion tracking. 5. Optionally, update the connector parameters if needed. 6. Right-click the %jiraagile% process group and select **Start**. The agile flow's destination tables (`BOARD`, `SPRINT`, `BOARD_SPRINT`, `BOARD_PROJECT`, `BOARD_ISSUE`) are fully refreshed on every scheduled run, regardless of whether you clear the state. ## Next steps - [Set up the Atlassian Jira Cloud (Core) flow](/user-guide/data-integration/openflow/connectors/jira-cloud/setup-core) if you haven't yet installed the core flow. - [Migrate from the legacy Openflow Connector for Jira Cloud](/user-guide/data-integration/openflow/connectors/jira-cloud/migrate-from-legacy) if you're moving from a previous version of the Jira Cloud connector. --- title: Set up the Atlassian Jira Cloud (Core) flow source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/jira-cloud/setup-core.md section: Loading & Unloading Data --- # Set up the %jiracore% flow This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [About Openflow Connector for Jira Cloud](/user-guide/data-integration/openflow/connectors/jira-cloud/about) - [Set up the Atlassian Jira Cloud (Agile) flow](/user-guide/data-integration/openflow/connectors/jira-cloud/setup-agile) - [Migrate from the legacy Openflow Connector for Jira Cloud](/user-guide/data-integration/openflow/connectors/jira-cloud/migrate-from-legacy) This topic describes the steps to install and configure the %jiracore% flow, the core flow of the %jira%. The agile flow is documented separately in [Set up the Atlassian Jira Cloud (Agile) flow](/user-guide/data-integration/openflow/connectors/jira-cloud/setup-agile). ## Prerequisites 1. Ensure that you have reviewed [About Openflow Connector for Jira Cloud](/user-guide/data-integration/openflow/connectors/jira-cloud/about). 2. Ensure that you have [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) or [Set up Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/setup-openflow-spcs). 3. If using %OFSFSPCS-plural%, ensure that you've reviewed [configuring required domains](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list) and have granted access to the required domains for the [](#label-openflow-domains-used-by-openflow-connectors-jira-cloud) connector. ## Get the credentials As a Jira Cloud administrator, perform the following tasks in your Atlassian account: 1. Navigate to the API tokens page (https://id.atlassian.com/manage-profile/security/api-tokens). 2. Select **Create API token with scopes**. 3. In the **Create an API token** dialog box, provide a descriptive name for the API token and select an expiration date for the API token. This can range from 1 to 365 days. 4. Select the API token app **Jira**. 5. Select the required scopes based on the features you plan to use. See [Required API scopes](#label-jira-core-api-scopes) for details. 6. Select **Create token**. 7. In the **Copy your API token** dialog box, select **Copy** to copy your generated API token and then paste the token to the connector parameters, or save it securely. 8. Select **Close** to close the dialog box. ### Required API scopes Atlassian API tokens with scopes list both **classic** (broader, recommended) and **granular** (narrower) scopes. Classic scopes are the recommended starting set. Use granular scopes when your organization requires a narrower token; a granular token needs every scope Atlassian lists for an endpoint, not just one. The core flow always requires these classic baseline scopes (or the equivalent granular set for each table you enable): - `read:jira-work` - `read:jira-user` (covers users and user groups, and the connection verification and timezone lookup that run at startup against `GET /rest/api/3/myself` (https://developer.atlassian.com/cloud/jira/platform/rest/v3/api-group-myself/#api-rest-api-3-myself-get)) The API token owner additionally needs the **Browse projects** Jira permission on every project that you want to ingest. For the `Enabled Tables` parameter that turns optional tables on, see [](#label-jira-core-enabled-tables). The following table lists each destination table, the recommended classic scope, the full set of granular scopes Atlassian documents for the endpoints, and links to the endpoints the connector calls:
For the `ISSUE`, `CHANGELOG`, `COMMENT`, `ISSUE_REMOTE_LINK`, `ISSUE_VOTE`, and `ISSUE_WATCHER` tables, the API token owner must also have permission to view an issue when issue-level security is configured for the issue. Comments restricted to specific roles or groups are visible only when the API token owner is a member of these roles or groups, regardless of the token scope or permission configuration. The `ISSUE_REMOTE_LINK` table requires issue linking to be active in Jira. The `ISSUE_VOTE` and `ISSUE_WATCHER` tables require the Jira settings that allow users to vote on and watch issues, respectively. Tokens without scopes are also supported and grant access based solely on the API token owner's permissions. However, tokens with scopes are recommended for fine-grained access control. ## Set up Snowflake account As a Snowflake account administrator, perform the following tasks: 1. Create a new role or use an existing role. 2. Create a new Snowflake service user with the type as [SERVICE](#label-user-type-property). 3. Grant the Snowflake service user the role you created in the previous steps. 4. Configure with [key-pair auth](/user-guide/key-pair-auth) for the Snowflake SERVICE user from step 2. 5. Configure a secrets manager supported by Openflow (recommended), for example, AWS, Azure, and HashiCorp, and store the public and private keys in the secret store. If for any reason, you don't want to use a secrets manager, then you are responsible for safeguarding the public key and private key files used for key-pair authentication according to the security policies of your organization. 1. After the secrets manager is configured, determine how you will authenticate to it. On AWS, use the EC2 instance role associated with Openflow as this way no other secrets have to be persisted. 2. In Openflow, configure a Parameter Provider associated with this Secrets Manager, from the main menu (⋮) in the upper-right corner. Navigate to **Controller Settings** %raa% **Parameter Provider** and then fetch your parameter values. 3. At this point, all credentials can be referenced with the associated parameter paths and no sensitive values need to be persisted within Openflow. 6. If any other Snowflake users require access to the tables ingested by the connector (for example, for custom processing in Snowflake), then grant those users the role created in step 1. 7. Create a database and schema in Snowflake for the connector to store ingested data. Grant the following [](#label-database-privileges) to the role created in the first step. ```sql CREATE DATABASE jira_destination_db; CREATE SCHEMA jira_destination_db.jira_destination_schema; GRANT USAGE ON DATABASE jira_destination_db TO ROLE ; GRANT USAGE ON SCHEMA jira_destination_db.jira_destination_schema TO ROLE ; GRANT CREATE TABLE ON SCHEMA jira_destination_db.jira_destination_schema TO ROLE ; ``` 8. Create a warehouse that the connector will use or use an existing one. Start with the smallest warehouse size, then experiment with size depending on the amount of data transferred. Large data volumes typically scale better with [multi-cluster warehouses](/user-guide/warehouses-multicluster), rather than larger warehouse sizes. 9. Ensure that the user with the role used by the connector has the required privileges to use the warehouse. If that's not the case then grant the required privileges to the role. ```sql CREATE WAREHOUSE jira_connector_warehouse WITH WAREHOUSE_SIZE = 'X-Small'; GRANT USAGE ON WAREHOUSE jira_connector_warehouse TO ROLE ; ``` ## Set up the connector The core flow is shipped as the %jiracore% process group. As a data engineer, perform the following tasks to install and configure it. ### Install the connector To install the connector, do the following as a data engineer: 1. Navigate to the Openflow overview page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find the connector and select **Install**. 3. In the **Select runtime** dialog, select your runtime from the **Available runtimes** drop-down list and click **Install**. Before you install the connector, ensure that you have created a database and schema in Snowflake for the connector to store ingested data. 4. Authenticate to the deployment with your Snowflake account credentials and select **Allow** when prompted to allow the runtime application to access your Snowflake account. The connector installation process takes a few minutes to complete. 5. Authenticate to the runtime with your Snowflake account credentials. The Openflow canvas appears with the connector process group added to it. After import, the core flow appears on the canvas as the %jiracore% process group. ### Configure the connector 1. Right-click on the imported %jiracore% process group and select **Parameters**. 2. Populate the required parameter values as described in [Flow parameters](#label-jira-core-flow-parameters). ### Flow parameters The core flow uses the following parameter contexts: - [Jira Cloud (Core) Source Parameters](#label-jira-core-source-parameters): Used to establish connection with the Jira API. - [Jira Cloud (Core) Destination Parameters](#label-jira-core-destination-parameters): Used to establish connection with Snowflake. - [Jira Cloud (Core) Ingestion Parameters](#label-jira-core-ingestion-parameters): Used to define the configuration of data ingested from Jira. #### Jira Cloud (Core) Source Parameters
#### Jira Cloud (Core) Destination Parameters
#### Jira Cloud (Core) Ingestion Parameters
## Run the flow 1. Right-click on the canvas and select **Enable all Controller Services**. 2. Right-click on the %jiracore% process group and select **Start**. The flow starts the data ingestion. On first run, the flow creates the required Snowflake tables in the destination schema. See [](#label-jira-entities) for the full list of tables created by the core flow and the parameters that control which optional tables are populated. ## Resetting the connector state If you need to change the project filter or want to restart the ingestion from scratch, you must clear the ingestion state. The core flow uses a centralized state service rather than per-processor state. To reset the state, perform the following steps: 1. Right-click the %jiracore% process group and select **Stop**. 2. Navigate to the **Controller Settings** for the process group. 3. Find the **StandardJiraIngestionStateService** controller service and select **View State**. 4. Select **Clear State**. This clears all project tracking, pagination, and timestamp state. 5. Optionally, update the connector parameters if needed. 6. Right-click the %jiracore% process group and select **Start**. Clearing the ingestion state causes the connector to re-fetch all data from the beginning. The destination tables are not truncated. Existing rows are updated in place, and rows that no longer exist in Jira are flagged with `_SNOWFLAKE_DELETED = TRUE`. ## Accessing the data Data fetched from Jira is available in the destination tables with explicit column schemas. There is no need to use JSON flattening or views to query the data. Each entity is stored in its own table. For example, to query issues and their comments: ```sql SELECT i.KEY, i.SUMMARY, c.BODY AS comment_body, c.CREATED AS comment_created FROM ISSUE i JOIN COMMENT c ON i.ID = c.ISSUE_ID ORDER BY c.CREATED DESC; ``` The `ISSUE` table stores Jira IDs for issue type, priority, resolution, and status, not the display names. Enable the matching lookup tables (they're in the default `Enabled Tables` value) and join them to resolve names: ```sql SELECT i.KEY, i.SUMMARY, it.NAME AS issue_type_name, p.NAME AS priority_name, r.NAME AS resolution_name, s.NAME AS status_name FROM ISSUE i LEFT JOIN ISSUE_TYPE it ON i.ISSUE_TYPE = it.ID LEFT JOIN PRIORITY p ON i.PRIORITY = p.ID LEFT JOIN RESOLUTION r ON i.RESOLUTION = r.ID LEFT JOIN STATUS s ON i.STATUS = s.ID WHERE i._SNOWFLAKE_DELETED = FALSE; ``` To exclude deleted issues from query results, filter on the connector-managed `_SNOWFLAKE_DELETED` column. The connector sets this flag to `TRUE` on the matching `ISSUE` row when an issue is deleted in Jira, so no anti-join against `DELETED_ISSUE` is needed: ```sql SELECT i.* FROM ISSUE i WHERE i._SNOWFLAKE_DELETED = FALSE; ``` The `DELETED_ISSUE` table is still useful when you need the deletion timestamp or the user who performed the deletion. See [](#label-jira-metadata-columns) for the full set of connector-managed metadata columns. ## Enabled tables configuration The `Enabled Tables` parameter controls which optional tables are populated. Ingestion of the `ISSUE`, `PROJECT`, `USER`, and `FIELD` tables is always enabled and can't be disabled. `ISSUE_TYPE`, `PRIORITY`, `RESOLUTION`, and `STATUS` are lookup tables that resolve the Jira IDs stored on `ISSUE` to their descriptive names. Enabling all tables may cause performance issues and require a larger runtime. Available values for `Enabled Tables`: - `CHANGELOG` (field change history for issues) - `COMMENT` (comments on issues) - `ISSUE_REMOTE_LINK` (remote links attached to issues) - `ISSUE_SECURITY_SCHEME` (issue-level security configurations) - `ISSUE_TYPE` (issue type names referenced by issues) - `ISSUE_VOTE` (users who voted on issues) - `ISSUE_WATCHER` (users watching issues) - `PERMISSION` (global and project permission definitions) - `PRIORITY` (priority names referenced by issues) - `PROJECT_COMPONENT` (components defined in a project) - `PROJECT_VERSION` (release versions of a project) - `RESOLUTION` (resolution names referenced by issues) - `STATUS` (status names and categories referenced by issues) - `USER_GROUP` (group memberships per user) - `WORKLOG` (time tracking entries on issues) The per-issue tables (`CHANGELOG`, `COMMENT`, `ISSUE_REMOTE_LINK`, `ISSUE_VOTE`, `ISSUE_WATCHER`, `WORKLOG`) and per-project tables (`PROJECT_COMPONENT`, `PROJECT_VERSION`) only ingest data for issues and projects that are also covered by `Project Keys Filter`. Some tables are populated by calling the Jira API once per parent entity (for example, once per user or once per issue). On large Jira instances, enabling these tables can significantly increase the number of API calls and the load on the ingestion runtime, and can slow down population of the parent table due to back-pressure on the upstream processor. Enable these tables only when the corresponding data is required. ## Issue fields configuration The `ISSUE` table schema depends on the `Issue Fields` parameter. The parameter accepts a comma-separated list of field IDs or one of the special values below. Prefix a field with a minus (`-`) to exclude it. For example, `*all,-description` returns all fields except `description`. - `*standard` (default): Fetches all non-custom Jira fields. For information about resolving Jira IDs to display names, see [Accessing the data](#label-jira-core-accessing-data). - `*navigable`: Fetches all navigable fields. - `*all`: Fetches all fields, including custom fields. - Individual field IDs can be specified (for example, `summary,status,customfield_10001`). The default value `*standard` **doesn't include custom fields**. To ingest custom fields, set this parameter to `*all` or list the custom fields explicitly by ID, for example, `*standard,customfield_10001`. To find custom field IDs, follow this guide (https://confluence.atlassian.com/jirakb/get-custom-field-ids-for-jira-and-jira-service-management-744522503.html). Column names in the `ISSUE` table are derived from Jira field display names by: 1. Uppercasing the display name. 2. Replacing spaces with underscores. 3. Removing every character that isn't a letter, digit, or underscore. For example, the display name `OF Test (Multi-User)` becomes the column `OF_TEST_MULTIUSER`. If two fields produce the same column name after this transformation, the second field's column is suffixed with `__` to keep names unique. For example, two fields with display name `Custom Field` and IDs `customfield_1` and `customfield_2` produce columns `CUSTOM_FIELD` and `CUSTOM_FIELD__CUSTOMFIELD_2`. Jira field types are mapped to Snowflake column types as follows:
## Next steps - [Set up the Atlassian Jira Cloud (Agile) flow](/user-guide/data-integration/openflow/connectors/jira-cloud/setup-agile) to install the agile flow. - [Migrate from the legacy Openflow Connector for Jira Cloud](/user-guide/data-integration/openflow/connectors/jira-cloud/migrate-from-legacy) if you're moving from a previous version of the Jira Cloud connector. --- title: Set up the Openflow Connector for Amazon Ads source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/amazon-ads/setup.md section: Loading & Unloading Data --- # Set up the %amazonads% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) This topic describes the steps to set up the %amazonads%. ## Prerequisites 1. Ensure that you have reviewed [About Openflow Connector for Amazon Ads](/user-guide/data-integration/openflow/connectors/amazon-ads/about). 2. Ensure that you have [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) or [Set up Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/setup-openflow-spcs). 3. If using %ofsfspcs-plural%, ensure that you have reviewed [configuring required domains](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list) and have granted access to the required domains for the [](#label-openflow-domains-used-by-openflow-connectors-amazon-ads) connector. ## Get the credentials As an Amazon Ads administrator, perform the following actions: 1. Make sure that you have access to an Amazon Ads account (https://advertising.amazon.com/). 2. Acquire Access to Amazon Ads API (https://advertising.amazon.com/API/docs/en-us/guides/onboarding/overview) and complete the onboarding process. 3. Get client ID and client secret (https://advertising.amazon.com/API/docs/en-us/guides/get-started/retrieve-access-token). 4. Create an authorization grant (https://advertising.amazon.com/API/docs/en-us/guides/get-started/create-authorization-grant) and retrieve a refresh token (https://advertising.amazon.com/API/docs/en-us/guides/get-started/retrieve-access-token). 5. Review the available regions (https://advertising.amazon.com/API/docs/en-us/reference/api-overview#api-endpoints) and get a base URL used for requests based on the region in which you are advertising. 6. Fetch profile IDs (https://advertising.amazon.com/API/docs/en-us/guides/get-started/retrieve-profiles) for report configuration. ## Set up Snowflake account As a Snowflake account administrator, perform the following tasks: 1. Create a new role or use an existing role and grant the [](#label-database-privileges). 2. Create a new Snowflake service user with the type as [SERVICE](#label-user-type-property). 3. Grant the Snowflake service user the role you created in the previous steps. 4. Configure with [key-pair auth](/user-guide/key-pair-auth) for the Snowflake SERVICE user from step 2. 5. Snowflake strongly recommends this step. Configure a secrets manager supported by Openflow, for example, AWS, Azure, and Hashicorp, and store the public and private keys in the secret store. If for any reason, you do not wish to use a secrets manager, then you are responsible for safeguarding the public key and private key files used for key-pair authentication according to the security policies of your organization. 1. Once the secrets manager is configured, determine how you will authenticate to it. On AWS, it's recommended that you the EC2 instance role associated with Openflow as this way no other secrets have to be persisted. 2. In Openflow, configure a Parameter Provider associated with this Secrets Manager, from the hamburger menu in the upper right. Navigate to **Controller Settings** %raa% **Parameter Provider** and then fetch your parameter values. 3. At this point all credentials can be referenced with the associated parameter paths and no sensitive values need to be persisted within Openflow. 6. If any other Snowflake users require access to the raw ingested documents and tables ingested by the connector (for example, for custom processing in Snowflake), then grant those users the role created in step 1. 7. Designate a warehouse for the connector to use. Start with the smallest warehouse size, then experiment with size depending on the number of tables being replicated, and the amount of data transferred. Large table numbers typically scale better with [multi-cluster warehouses](/user-guide/warehouses-multicluster), rather than larger warehouse sizes. ## Set up the connector As a data engineer, perform the following tasks to install and configure the connector: ### Install the connector To install the connector, do the following as a data engineer: 1. Navigate to the Openflow overview page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find the connector and select **Install**. 3. In the **Select runtime** dialog, select your runtime from the **Available runtimes** drop-down list and click **Install**. Before you install the connector, ensure that you have created a database and schema in Snowflake for the connector to store ingested data. 4. Authenticate to the deployment with your Snowflake account credentials and select **Allow** when prompted to allow the runtime application to access your Snowflake account. The connector installation process takes a few minutes to complete. 5. Authenticate to the runtime with your Snowflake account credentials. The Openflow canvas appears with the connector process group added to it. ### Configure the connector 1. Right-click on the imported process group and select **Parameters**. 2. Populate the required parameter values as described in [Flow parameters](#flow-parameters). ### Flow parameters This section describes the flow parameters that you can configure based on the following parameter contexts: - [Amazon Ads source parameters](#amazon-ads-source-parameters): Used to establish connection with Amazon Ads API. - [Amazon Ads destination parameters](#amazon-ads-destination-parameters): Used to establish connection with Snowflake. - [Amazon Ads ingestion parameters](#amazon-ads-ingestion-parameters): Used to define the configuration of data downloaded from Amazon Ads. #### Amazon Ads source parameters
#### Amazon Ads destination parameters
#### Amazon Ads Ingestion Parameters
Data retention in the Amazon Ads API is a specific timeframe, ranging from 60 to 365 days depending on the report type, during which historical advertising performance data is stored and accessible for retrieval. After this period, older data may no longer be available. ## Run the flow 1. Right-click on the plane and select **Enable all Controller Services**. 2. Right-click on the imported process group and select **Start**. The connector starts the data ingestion. --- title: Set up the Openflow Connector for Box source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/box/setup.md section: Loading & Unloading Data --- # Set up the %box% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) This topic describes the steps to set up the %box%. ## Prerequisites 1. Ensure that you have reviewed [About Openflow Connector for Box](/user-guide/data-integration/openflow/connectors/box/about). 2. Ensure that you have [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) or [Set up Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/setup-openflow-spcs). 3. If using %ofsfspcs-plural%, ensure that you have reviewed [configuring required domains](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list) and have granted access to the required domains for the [](#label-openflow-domains-used-by-openflow-connectors-box) connector. ## Get the credentials As a **Box developer** or **Box administrator**, create a Box Platform application (https://developer.box.com/guides/applications/app-types/platform-apps/) as follows: 1. Navigate to Box Developer Console (https://app.box.com/developers/console). 2. Select **Create Platform App**. 3. Select **Custom App** as the application type. 4. Provide a name and description for the app, and select a purpose from the drop-down list. 5. Select **Server Authentication (with JWT)** as the authentication method. 6. Select **Create App**. 7. To configure the app, navigate to the **Configuration** tab. 8. In the **App Access Level** section, select **App + Enterprise Access**. 9. In the **Application Scopes** section, select the following options: - **Read all files and folders stored in Box**. - **Write all files and folders stored in Box**: To download files and folders. Note that the connector can't upload any files. Snowflake recommends granting the service account only the Viewer role. To grant the application access to files in Box, select a folder that you want to synchronize. Share it with the app service account using the email of the service account saved from the **General Settings** tab. %box% is able to discover and download files from the specified folder and all its subfolders, but it cannot modify the files. - **Manage users**: To read users in the enterprise. - **Manage groups**: To read groups and their members in the enterprise. - **Manage enterprise properties**: To read enterprise events. 10. In the **Add and Manage Public Keys** section, generate a public/private key pair. Box downloads a JSON configuration file with a private key. 11. Save the changes. 12. Navigate to the **Authorization** tab, and submit the app for authorization for access to the enterprise. 13. Request your enterprise administrator to approve the app. 14. After the approval is granted, go to the **General Settings** tab and save the app service account email address. For more information, see Setup with JWT (https://developer.box.com/guides/authentication/jwt/jwt-setup/). ## Set up Snowflake account As a Snowflake account administrator, perform the following tasks manually or by using the script included below: 1. Create a new role or use an existing role and grant the [](#label-database-privileges). 2. Create a new Snowflake service user with the type as [SERVICE](#label-user-type-property). 3. Grant the Snowflake service user the role you created in the previous steps. 4. Configure with [key-pair auth](/user-guide/key-pair-auth) for the Snowflake SERVICE user from step 2. 5. Snowflake strongly recommends this step. Configure a secrets manager supported by Openflow, for example, AWS, Azure, and HashiCorp, and store the public and private keys in the secret store. If for any reason, you do not wish to use a secrets manager, then you are responsible for safeguarding the public key and private key files used for key-pair authentication according to the security policies of your organization. 1. Once the secrets manager is configured, determine how you will authenticate to it. On AWS, it's recommended that you use the EC2 instance role associated with Openflow, so no other secrets have to be persisted. 2. In Openflow, configure a Parameter Provider associated with this Secrets Manager, from the hamburger menu in the upper right. Navigate to **Controller Settings** %raa% **Parameter Provider** and then fetch your parameter values. 3. At this point all credentials can be referenced with the associated parameter paths and no sensitive values need to be persisted within Openflow. 6. If any other Snowflake users require access to the raw documents and tables ingested by the connector (for example, for custom processing in Snowflake), then grant those users the role created in step 1. 7. Designate a warehouse for the connector to use. Start with the smallest warehouse size, then experiment with size depending on the number of tables being replicated, and the amount of data transferred. Large table numbers typically scale better with [multi-cluster warehouses](/user-guide/warehouses-multicluster), rather than larger warehouse sizes. ### Example setup
```sql --The following script assumes you'll need to create all required roles, users, and objects. --However, you may want to reuse some that are already in existence. --Create a Snowflake service user to manage the connector USE ROLE USERADMIN; CREATE USER TYPE=SERVICE COMMENT='Service user for Openflow automation'; --Create a pair of secure keys (public and private). For more information, see --key-pair authentication. Store the private key for the user in a file to supply --to the connector’s configuration. Assign the public key to the Snowflake service user: ALTER USER SET RSA_PUBLIC_KEY = ''; --Create a role to manage the connector and the associated data and --grant it to that user USE ROLE SECURITYADMIN; CREATE ROLE ; GRANT ROLE TO USER ; --The following block is for the use case: Ingest files and perform processing with Cortex --Create a role for read access to the cortex search service created by this connector. --This role should be granted to any role that will use the service CREATE ROLE ; GRANT ROLE TO ROLE ; --Create the database the data will be stored in and grant usage to the roles created USE ROLE ACCOUNTADMIN; --use whatever role you want to own your DB CREATE DATABASE IF NOT EXISTS ; GRANT USAGE ON DATABASE TO ROLE ; --Create the schema the data will be stored in and grant the necessary privileges --on that schema to the connector admin role: USE DATABASE ; CREATE SCHEMA IF NOT EXISTS ; GRANT USAGE ON SCHEMA TO ROLE ; GRANT CREATE TABLE, CREATE DYNAMIC TABLE, CREATE STAGE, CREATE SEQUENCE, CREATE CORTEX SEARCH SERVICE ON SCHEMA TO ROLE ; --The following block is for use case: Ingest files and perform processing with Cortex --Grant the Cortex read-only role access to the database and schema GRANT USAGE ON DATABASE TO ROLE ; GRANT USAGE ON SCHEMA TO ROLE ; --Create the warehouse this connector will use if it doesn't already exist. Grant the --appropriate privileges to the connector admin role. Adjust the size according to your needs. CREATE WAREHOUSE WITH WAREHOUSE_SIZE = 'MEDIUM' AUTO_SUSPEND = 300 AUTO_RESUME = TRUE; GRANT USAGE, OPERATE ON WAREHOUSE TO ROLE ; ```
## Use cases You can configure the connector for the following use cases: - [Ingest files only](#ingest-files-only) - [Ingest files and perform processing with Cortex](#ingest-files-and-perform-processing-with-cortex) - [Extract Box metadata using Box AI and ingest it into a Snowflake table](#extract-box-metadata-using-box-ai-and-ingest-it-into-a-snowflake-table) - [Synchronize Box file metadata instances with a Snowflake table](#synchronize-box-file-metadata-instances-with-a-snowflake-table) ### Ingest files only Use the connector definition to perform custom processing on ingested files. #### Set up the connector As a data engineer, perform the following tasks to install and configure the connector: ##### Install the connector To install the connector, do the following as a data engineer: 1. Navigate to the Openflow overview page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find the connector and select **Install**. 3. In the **Select runtime** dialog, select your runtime from the **Available runtimes** drop-down list and click **Install**. Before you install the connector, ensure that you have created a database and schema in Snowflake for the connector to store ingested data. 4. Authenticate to the deployment with your Snowflake account credentials and select **Allow** when prompted to allow the runtime application to access your Snowflake account. The connector installation process takes a few minutes to complete. 5. Authenticate to the runtime with your Snowflake account credentials. The Openflow canvas appears with the connector process group added to it. ##### Configure the connector 1. Right-click on the imported process group and select **Parameters**. 2. Enter the required parameter values as described in [Box ingestion parameters](#box-ingestion-parameters), [Box destination parameters](#box-destination-parameters) and [Box source parameters](#box-source-parameters). ###### Box source parameters
###### Box destination parameters
###### Box ingestion parameters
#### Run the flow 1. Right-click on the plane and select **Enable all Controller Services**. 2. Right-click on the imported process group and select **Start**. The connector starts the data ingestion. After starting the connector, it retrieves all files from the specified folder, and then consumes `admin_logs_streaming` events within the last 14 days. This is done to capture data that may otherwise have been missed during the initialization process. During that time, `not found` errors may occur, which are caused by files that appear in the events but are no longer present. ### Ingest files and perform processing with Cortex Use the connector definition to: - Create AI assistants for public documents within your organization's Box enterprise - Enable your AI assistants to adhere to access controls specified in your organization's Box enterprise #### Set up the connector As a data engineer, perform the following tasks to install and configure the connector: ##### Install the connector To install the connector, do the following as a data engineer: 1. Navigate to the Openflow overview page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find the connector and select **Install**. 3. In the **Select runtime** dialog, select your runtime from the **Available runtimes** drop-down list and click **Install**. Before you install the connector, ensure that you have created a database and schema in Snowflake for the connector to store ingested data. 4. Authenticate to the deployment with your Snowflake account credentials and select **Allow** when prompted to allow the runtime application to access your Snowflake account. The connector installation process takes a few minutes to complete. 5. Authenticate to the runtime with your Snowflake account credentials. The Openflow canvas appears with the connector process group added to it. ##### Configure the connector 1. Right-click on the imported process group and select **Parameters**. 2. Populate the required parameter values as described in [Box Cortex Connect Ingestion Parameters](#box-cortex-connect-ingestion-parameters), [Box Cortex Connect Destination Parameters](#box-cortex-connect-destination-parameters) and [Box Cortex Connect Source Parameters](#box-cortex-connect-source-parameters). ###### Box Cortex Connect Source Parameters
###### Box Cortex Connect Destination Parameters
###### Box Cortex connect ingestion parameters
#### Run the flow 1. Right-click on the plane and select **Enable all Controller Services**. 2. Right-click on the imported process group and select **Start**. The connector starts the data ingestion. After starting the connector, it retrieves all files from the specified folder, and then consumes `admin_logs_streaming` events within the last 14 days. This is done to capture any data that may have been missed during the initialization process. During that time, `not found` errors may occur, caused by the files that appear in the events but are no longer present. #### Query the Cortex Search service You can use the [Cortex Search](/user-guide/snowflake-cortex/cortex-search/cortex-search-overview) service to build chat and search applications to chat with or query your documents in Box. After you install and configure the connector and it begins ingesting content from Box, you can query the Cortex Search service. For more information about using Cortex Search, see [Query a Cortex Search service](/user-guide/snowflake-cortex/cortex-search/query-cortex-search-service). **Filter responses** To restrict responses from the Cortex Search service to documents that a specific user has access to in Box, you can specify a filter containing the user ID or email address of the user when you query Cortex Search. For example, `filter.@contains.user_ids` or `filter.@contains.user_emails`. The name of the Cortex Search service created by the connector is `search_service` in the schema `Cortex`. Run the following SQL code in a SQL worksheet to query the Cortex Search service with files ingested from Box. Replace the following: - application_instance_name: Name of your database and connector application instance. - user_emailID: Email ID of the user who you want to filter the responses for. - your_question: The question that you want to get responses for. - number_of_results: Maximum number of results to return in the response. The maximum value is 1,000 and the default value is 10. ```sql SELECT PARSE_JSON( SNOWFLAKE.CORTEX.SEARCH_PREVIEW( '.cortex.search_service', '{ "query": "", "columns": ["chunk", "web_url"], "filter": {"@contains": {"user_emails": ""} }, "limit": }' ) )['results'] AS results ``` Here is a complete list of values that you can enter for `columns`:
**Example: Query an AI assistant for human resources (HR) information** You can use Cortex Search to query an AI assistant for employees to chat with the latest versions of HR information, such as onboarding, code of conduct, team processes, and organization policies. Using response filters, you can also allow HR team members to query employee contracts while adhering to access controls configured in Box. **SQL:** Run the following in a [SQL worksheet](#label-snowsight-worksheets-create-file) to query the Cortex Search service with files ingested from Box. Select the database as your application instance name and schema as **Cortex**. Replace the following: - application_instance_name: Name of your database and connector application instance. - user_emailID: Email ID of the user who you want to filter the responses for. ```sql SELECT PARSE_JSON( SNOWFLAKE.CORTEX.SEARCH_PREVIEW( '.cortex.search_service', '{ "query": "What is my vacation carryover policy?", "columns": ["chunk", "web_url"], "filter": {"@contains": {"user_emails": ""} }, "limit": 1 }' ) )['results'] AS results ``` **Python:** Run the following code in a [Python worksheet](#label-snowsight-worksheets-create) to query the Cortex Search service with files ingested from Box. Ensure that you add the `snowflake.core` package to your database. Replace the following: - application_instance_name: Name of your database and connector application instance. - user_emailID: Email ID of the user who you want to filter the responses for. ```python from snowflake.snowpark import Session from snowflake.core import Root def main(session: snowpark.Session): root = Root(session) # fetch service my_service = (root .databases[""] .schemas["cortex"] .cortex_search_services["search_service"] ) # query service resp = my_service.search( query="What is my vacation carryover policy?", columns = ["chunk", "web_url"], filter = {"@contains": {"user_emails": ""} }, limit=1 ) return (resp.to_json()) ``` **REST API:** Execute the following code in a command-line interface to query the Cortex Search service with files ingested from your Box. Access to the Snowflake REST APIs requires authentication via both key pair authentication and OAuth. For more information, see [](#label-cortex-search-query-syntax-rest) and [Authenticating Snowflake REST APIs with Snowflake](/developer-guide/snowflake-rest-api/authentication). Replace the following: - application_instance_name: Name of your database and connector application instance. - account_url: Your Snowflake account URL. For instructions on finding your account URL, see [](#label-account-name-find). ```bash curl --location "https:///api/v2/databases//schemas/cortex/cortex-search-services/search_service" \ --header 'Content-Type: application/json' \ --header 'Accept: application/json' \ --header "Authorization: Bearer " \ --data '{ "query": "What is my vacation carryover policy?", "columns": ["chunk", "web_url"], "limit": 1 }' ``` Sample response: ```text { "results" : [ { "web_url" : "https://.box.com/sites//", "chunk" : "Answer to the question asked." } ] } ``` ### Extract Box metadata using Box AI and ingest it into a Snowflake table Use the connector definition to: - Extract metadata about your Box files and ingest it into a Snowflake table - Perform operations on the metadata of your files stored in Box #### Create a Snowflake table for storing the Box metadata 1. Ensure that Box AI is enabled for the extraction of metadata to occur. For more information, see Configuring Box AI (https://support.box.com/hc/en-us/articles/22166647877011-Configuring-Box-AI). 2. Create a Snowflake table where the metadata will be sent. For the connector to know what kind of metadata to extract, you must create a Snowflake table in your database and schema with the column names of the fields you would like to extract. Add descriptions to each column to improve the performance of the model used to extract the metadata from the files. 3. In the table created in the previous step, ensure that there is a column to store the Box file ID and that it is of type VARCHAR. The name of this column is required to be entered as the Box File Identifier Column parameter in later steps. The list of supported column types for the metadata table is VARCHAR, STRING, TEXT, FLOAT, DOUBLE, and DATE. Here is an example of the table that you can create for this connector: ```sql CREATE OR REPLACE TABLE OPENFLOW.BOX_METADATA_SCHEMA.LOAN_AGREEMENT_METADATA ( BOX_FILE_ID VARCHAR COMMENT 'Box file identifier column', LOAN_ID STRING COMMENT 'Unique loan agreement identifier (e.g. L-2025-0001)', BORROWER_NAME STRING COMMENT 'Name of the borrower entity or individual', LENDER_NAME STRING COMMENT 'Name of the lending institution', LOAN_AMOUNT DOUBLE COMMENT 'Principal amount of the loan (in USD)', INTEREST_RATE FLOAT COMMENT 'Annual interest rate (%)', EFFECTIVE_DATE DATE COMMENT 'Date on which the loan becomes effective', MATURITY_DATE DATE COMMENT 'Scheduled loan maturity date', LOAN_TERM_MONTHS FLOAT COMMENT 'Original term length in months', COLLATERAL_DESCRIPTION TEXT COMMENT 'Description of collateral securing the loan', CREDIT_SCORE FLOAT COMMENT 'Borrower credit score', JURISDICTION STRING COMMENT 'Governing law jurisdiction (e.g. NY, CA)' ); ``` #### Set up the connector As a data engineer, perform the following tasks to install and configure the connector: ##### Install the connector To install the connector, do the following as a data engineer: 1. Navigate to the Openflow overview page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find the connector and select **Install**. 3. In the **Select runtime** dialog, select your runtime from the **Available runtimes** drop-down list and click **Install**. Before you install the connector, ensure that you have created a database and schema in Snowflake for the connector to store ingested data. 4. Authenticate to the deployment with your Snowflake account credentials and select **Allow** when prompted to allow the runtime application to access your Snowflake account. The connector installation process takes a few minutes to complete. 5. Authenticate to the runtime with your Snowflake account credentials. The Openflow canvas appears with the connector process group added to it. ##### Configure the connector 1. Right-click on the imported process group and select **Parameters**. 2. Populate the required parameter values as described in [Box Ingest Metadata Source Parameters](#box-ingest-metadata-source-parameters), [Box Ingest Metadata Destination Parameters](#box-ingest-metadata-destination-parameters) and [Box Ingest Metadata Ingestion Parameters](#box-ingest-metadata-ingestion-parameters). ###### Box Ingest Metadata Source Parameters
###### Box Ingest Metadata Destination Parameters
###### Box Ingest Metadata Ingestion Parameters
#### Run the flow 1. Right-click on the plane and select **Enable all Controller Services**. 2. Right-click on the imported process group and select **Start**. The connector starts the data ingestion. After starting the connector, it retrieves all files from the specified folder, and then consumes `admin_logs_streaming` events from the last 14 days. This is done to capture any data that may have been missed during the initialization process. During that time, `not found` errors may occur, caused by the files that appear in the events but are no longer present. ### Synchronize Box file metadata instances with a Snowflake table Use the connector definition to perform a data transformation on metadata from Box in a Snowflake table and add the changes back to a Box metadata instance. #### Create a Snowflake stream for storing the Box metadata 1. Create a Snowflake stream for the metadata table you want to use. The stream is used to monitor any changes that occur to the table with which you want to synchronize your Box files. To learn how to create a table for storing Box metadata, see [Create a Snowflake table for storing the Box metadata](#create-a-snowflake-table-for-storing-the-box-metadata). If the connector is stopped beyond the data retention time and the stream becomes stale, then you must recreate a stream and replace the previous one. To learn more about managing streams, see [Manage streams](/user-guide/streams-manage). Here is an example of a stream that you can create for this connector: ```sql CREATE OR REPLACE STREAM OPENFLOW.BOX_METADATA_SCHEMA.LOAN_AGREEMENT_METADATA_STREAM ON TABLE OPENFLOW.BOX_METADATA_SCHEMA.LOAN_AGREEMENT_METADATA ``` 2. In the metadata table, ensure that there is a column to store the Box file ID and that it is of type VARCHAR. The name of this column is required to be entered as the Box File Identifier Column parameter in later steps. The list of supported column types for the metadata table is VARCHAR, STRING, TEXT, FLOAT, DOUBLE, and DATE. #### Set up the connector As a data engineer, perform the following tasks to install and configure the connector: ##### Install the connector To install the connector, do the following as a data engineer: 1. Navigate to the Openflow overview page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find the connector and select **Install**. 3. In the **Select runtime** dialog, select your runtime from the **Available runtimes** drop-down list and click **Install**. Before you install the connector, ensure that you have created a database and schema in Snowflake for the connector to store ingested data. 4. Authenticate to the deployment with your Snowflake account credentials and select **Allow** when prompted to allow the runtime application to access your Snowflake account. The connector installation process takes a few minutes to complete. 5. Authenticate to the runtime with your Snowflake account credentials. The Openflow canvas appears with the connector process group added to it. ##### Configure the connector 1. Right-click on the imported process group and select **Parameters**. 2. Populate the required parameter values as described in [Box Publish Metadata Source Parameters](#box-publish-metadata-source-parameters), [Box Publish Metadata Destination Parameters](#box-publish-metadata-destination-parameters) and [Box Publish Metadata Ingestion Parameters](#box-publish-metadata-ingestion-parameters). ###### Box Publish Metadata Source Parameters
###### Box Publish Metadata Destination Parameters
###### Box Publish Metadata Ingestion Parameters
#### Run the flow 1. Right-click on the plane and select **Enable all Controller Services**. 2. Right-click on the imported process group and select **Start**. The connector starts the data ingestion. After running the flow, you can query the Cortex Search service. For information on how to query the Cortex Search service, see [Query the Cortex Search service](#query-the-cortex-search-service). ### Finding files in stage Files stored in the stage may have unreadable names. To find specific files, use the metadata tables as your source of truth. These tables contain the mapping between file names and their corresponding file IDs in the stage. For Cortex-enabled setups, use the following query to find files: ```sql SELECT DISTINCT METADATA:id FROM DOCS_CHUNKS WHERE METADATA:fullName LIKE '%'; ``` For non-Cortex setups, use the following query: ```sql SELECT FILE_ID FROM DOC_METADATA WHERE FILE_NAME = ''; ``` Replace `` with the name or partial name of the file you're looking for. The files in the stage start with the ID returned from these queries. --- title: Set up the Openflow Connector for Google Ads source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/google-ads/setup.md section: Loading & Unloading Data --- # Set up the Openflow Connector for Google Ads This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) This topic describes the steps to set up the Openflow Connector for Google Ads. ## Prerequisites 1. Ensure that you have reviewed [About Openflow Connector for Google Ads](/user-guide/data-integration/openflow/connectors/google-ads/about). 2. Ensure that you have [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) or [Set up Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/setup-openflow-spcs). 3. If using %ofsfspcs-plural%, ensure that you've reviewed [configuring required domains](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list) and have granted access to the required domains for the [](#label-openflow-domains-used-by-openflow-connectors-google-ads) connector. ## Get the credentials As a Google Ads administrator, perform the following steps: - Ensure that you have access to a Google Cloud project or create a new one (https://developers.google.com/workspace/guides/create-project). - Ensure that the Google Ads API (https://cloud.google.com/endpoints/docs/openapi/enable-api) is enabled for your Google Cloud project. Google Ads API access is required to ingest data. - Configure (https://developers.google.com/google-ads/api/docs/oauth/service-accounts) Service account authentication for Google Ads. - Obtain developer token for your organization following instructions (https://developers.google.com/google-ads/api/docs/get-started/dev-token). Developer token should have Access Level either Basic or Standard. For more information about Access Level please see documentation (https://developers.google.com/google-ads/api/docs/access-levels). ## Set up Snowflake account As a Snowflake account administrator, perform the following tasks: 1. Create a new role or use an existing role and grant the [](#label-database-privileges). 2. Create a new Snowflake service user with the type as [SERVICE](#label-user-type-property). 3. Grant the Snowflake service user the role you created in the previous steps. 4. Configure with [key-pair auth](/user-guide/key-pair-auth) for the Snowflake SERVICE user from step 2. 5. Snowflake strongly recommends this step. Configure a secrets manager supported by Openflow, for example, AWS, Azure, and Hashicorp, and store the public and private keys in the secret store. If for any reason, you do not wish to use a secrets manager, then you are responsible for safeguarding the public key and private key files used for key-pair authentication according to the security policies of your organization. 1. Once the secrets manager is configured, determine how you will authenticate to it. On AWS, it's recommended that you the EC2 instance role associated with Openflow as this way no other secrets have to be persisted. 2. In Openflow, configure a Parameter Provider associated with this Secrets Manager, from the hamburger menu in the upper right. Navigate to **Controller Settings** %raa% **Parameter Provider** and then fetch your parameter values. 3. At this point all credentials can be referenced with the associated parameter paths and no sensitive values need to be persisted within Openflow. 6. If any other Snowflake users require access to the raw ingested documents and tables ingested by the connector (for example, for custom processing in Snowflake), then grant those users the role created in step 1. 7. Designate a warehouse for the connector to use. Start with the smallest warehouse size, then experiment with size depending on the number of tables being replicated, and the amount of data transferred. Large table numbers typically scale better with [multi-cluster warehouses](/user-guide/warehouses-multicluster), rather than larger warehouse sizes. ## Set up the connector As a data engineer, perform the following tasks to install and configure the connector: ### Install the connector 1. Create a database and schema in Snowflake for the connector to store ingested data. Grant required [](#label-database-privileges) to the role created in the first step. Substitute the role placeholder with the actual value and use the following sql commands:
```sql CREATE DATABASE GOOGLE_ADS_DESTINATION_DB; CREATE SCHEMA GOOGLE_ADS_DESTINATION_DB.GOOGLE_ADS_DESTINATION_SCHEMA; GRANT USAGE ON DATABASE GOOGLE_ADS_DESTINATION_DB TO ROLE ; GRANT USAGE ON SCHEMA GOOGLE_ADS_DESTINATION_DB.GOOGLE_ADS_DESTINATION_SCHEMA TO ROLE ; GRANT CREATE TABLE ON SCHEMA GOOGLE_ADS_DESTINATION_DB.GOOGLE_ADS_DESTINATION_SCHEMA TO ROLE ; ```
To install the connector, do the following as a data engineer: 1. Navigate to the Openflow overview page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find the connector and select **Install**. 3. In the **Select runtime** dialog, select your runtime from the **Available runtimes** drop-down list and click **Install**. Before you install the connector, ensure that you have created a database and schema in Snowflake for the connector to store ingested data. 4. Authenticate to the deployment with your Snowflake account credentials and select **Allow** when prompted to allow the runtime application to access your Snowflake account. The connector installation process takes a few minutes to complete. 5. Authenticate to the runtime with your Snowflake account credentials. The Openflow canvas appears with the connector process group added to it. ### Configure the connector 1. Right-click on the imported process group and select **Parameters**. 2. Populate the required parameter values as described in [Flow parameters](#flow-parameters). #### Flow parameters There are three parameter contexts. *Google Ads Destination Parameters* and *Google Ads Source Parameters* are respectively responsible for allowing connections with GoogleAds API and Snowflake. *Google Ads Ingestion Parameters* is used to define the reconfiguration of data downloaded from Google Ads. *Google Ads Parameters* aggregates all of them in one. ##### Google Ads Ingestion Parameters
The easiest way to obtain proper combination of *Report Attributes*, *Report Metrics* and *Report Segments* is to use Google Ads Query Builder (https://developers.google.com/google-ads/api/fields/v19/overview_query_builder). Select the resource based on the one inserted into parameter *Google Ads Resource Name* and construct the query. Then copy and paste attributes, metrics and segments to corresponding parameters. ##### Google Ads Source Parameters
##### Google Ads Destination Parameters
## Run the flow 1. Right-click on the plane and select **Enable all Controller Services**. 2. Right-click on the imported process group and select **Start**. The connector starts the data ingestion. ## How to reset the connector To fully reset connector to the initial state, do the following: 1. Ensure that there are no more flow files in the queues. 2. Stop all the processors. 3. Clear the state of the initial processor. 1. Right click on the processor `Get Google Ads Report` and select **View State**. 2. Select the option **Clear State**. This resets the state of the processor. 4. Drop the destination table in Snowflake. --- title: Set up the Openflow Connector for Google Drive source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/google-drive/setup.md section: Loading & Unloading Data --- # Set up the Openflow Connector for Google Drive This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) This topic describes the steps to set up the Openflow Connector for Google Drive. ## Prerequisites 1. Ensure that you have reviewed [About Openflow Connector for Google Drive](/user-guide/data-integration/openflow/connectors/google-drive/about). 2. Ensure that you have [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) or [Set up Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/setup-openflow-spcs). 3. If using %ofsfspcs-plural%, ensure that you've reviewed [configuring required domains](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list) and have granted access to the required domains for the [](#label-openflow-domains-used-by-openflow-connectors-google-drive) connector. ## Get the credentials Setting up the connector requires specific permissions and account settings for Snowflake Openflow processors to read data from Google. This access is provided in part through setting up a service account and a key for Openflow to authenticate as that service account. For more information, see: - Configure access to the Google Cloud Search API (https://developers.google.com/cloud-search/docs/guides/project-setup#create_service_account_credentials) - Delegating domain-wide authority to the service account (https://developers.google.com/identity/protocols/oauth2/service-account#delegatingauthority) As a Google Drive administrator, perform the following steps: ### Prerequisites Ensure that you meet the following requirements: - You have a Google user with Super Admin permissions - You have a Google Cloud Project with the following roles: - Organization Policy Administrator - Organization Administrator ### Enable service account key creation By default Google disables service account key creation. For Openflow to use the service account JSON, this key creation policy must be turned off. 1. Log in to the Google Cloud Console (https://console.cloud.google.com/) with a super admin account that has the Organizational Policy Admin Role. 2. Ensure you are in the project associated with your organization, not the project in your organization. 3. Click **Organization Policies**. 4. Select the **Disable service account key creation** policy. 5. Click **Manage Policy** and turn off enforcement. 6. Click **Set Policy**. ### Create service account and key 1. Open the Google Cloud Console (https://console.cloud.google.com/) and authenticate using a user that has been granted access to create service accounts. 2. Ensure you are in a project of your organization. 3. In the left navigation, under **IAM & Admin**, select the **Service Accounts** tab. 4. Click **Create Service Account**. 5. Enter the service account name and click **Create and Continue**. 6. Click **Done**. In the table with the service accounts listed, find the **OAuth 2 Client ID** column. Copy the Client ID as this will be required later to set up domain-wide delegation in the next section. 7. On the newly created service account, click the menu under the table with the service accounts listed for that service account and select **Manage keys**. 8. Select **Add key** and then **Create new key**. 9. Leave the default selection of JSON and click **Create**. The key is downloaded into your browser Downloads directory as a .json file. ### Grant service account domain-wide delegation for listed scopes 1. Log in to your Google Admin account. 2. Select **Admin** from **Google Apps selector**. 3. In the left navigation, expand **Security** and then **Access** and select **Data control**, then click on **API Controls**. 4. On the **API Controls** screen, select **Manage domain-wide delegation**. 5. Click **Add new**. 6. Enter the OAuth 2 Client ID taken from the Create service account and key section and the following scopes: - https://www.googleapis.com/auth/drive (https://www.googleapis.com/auth/drive) - https://www.googleapis.com/auth/drive.metadata.readonly (https://www.googleapis.com/auth/drive.metadata.readonly) - https://www.googleapis.com/auth/admin.directory.group.member.readonly (https://www.googleapis.com/auth/admin.directory.group.member.readonly) - https://www.googleapis.com/auth/admin.directory.group.readonly (https://www.googleapis.com/auth/admin.directory.group.readonly) - https://www.googleapis.com/auth/drive.file (https://www.googleapis.com/auth/drive.file) - https://www.googleapis.com/auth/drive.metadata (https://www.googleapis.com/auth/drive.metadata) 7. Click **Authorize**. ## Set up Snowflake account As a Snowflake account administrator, perform the following tasks manually or by using the script included below: 1. Create a new role or use an existing role and grant the [](#label-database-privileges). 2. Create a new Snowflake service user with the type as [SERVICE](#label-user-type-property). 3. Grant the Snowflake service user the role you created in the previous steps. 4. Configure with [key-pair auth](/user-guide/key-pair-auth) for the Snowflake SERVICE user from step 2. 5. Snowflake strongly recommends this step. Configure a secrets manager supported by Openflow, for example, AWS, Azure, and HashiCorp, and store the public and private keys in the secret store. If for any reason, you do not wish to use a secrets manager, then you are responsible for safeguarding the public key and private key files used for key-pair authentication according to the security policies of your organization. 1. Once the secrets manager is configured, determine how you will authenticate to it. On AWS, it's recommended that you use the EC2 instance role associated with Openflow, so no other secrets have to be persisted. 2. In Openflow, configure a Parameter Provider associated with this Secrets Manager, from the hamburger menu in the upper right. Navigate to **Controller Settings** %raa% **Parameter Provider** and then fetch your parameter values. 3. At this point all credentials can be referenced with the associated parameter paths and no sensitive values need to be persisted within Openflow. 6. If any other Snowflake users require access to the raw ingested documents and tables ingested by the connector (for example, for custom processing in Snowflake), then grant those users the role created in step 1. 7. Designate a warehouse for the connector to use. Start with the smallest warehouse size, then experiment with size depending on the number of tables being replicated, and the amount of data transferred. Large table numbers typically scale better with [multi-cluster warehouses](/user-guide/warehouses-multicluster), rather than larger warehouse sizes. ### Example setup
```sql --The following script assumes you'll need to create all required roles, users, and objects. --However, you may want to reuse some that are already in existence. --Create a Snowflake service user to manage the connector USE ROLE USERADMIN; CREATE USER TYPE=SERVICE COMMENT='Service user for Openflow automation'; --Create a pair of secure keys (public and private). For more information, see --key-pair authentication. Store the private key for the user in a file to supply --to the connector’s configuration. Assign the public key to the Snowflake service user: ALTER USER SET RSA_PUBLIC_KEY = ''; --Create a role to manage the connector and the associated data and --grant it to that user USE ROLE SECURITYADMIN; CREATE ROLE ; GRANT ROLE TO USER ; --The following block is for USE CASE 2 (Cortex connect) ONLY --Create a role for read access to the cortex search service created by this connector. --This role should be granted to any role that will use the service CREATE ROLE ; GRANT ROLE TO ROLE ; --Create the database the data will be stored in and grant usage to the roles created USE ROLE ACCOUNTADMIN; --use whatever role you want to own your DB CREATE DATABASE IF NOT EXISTS ; GRANT USAGE ON DATABASE TO ROLE ; --Create the schema the data will be stored in and grant the necessary privileges --on that schema to the connector admin role: USE DATABASE ; CREATE SCHEMA IF NOT EXISTS ; GRANT USAGE ON SCHEMA TO ROLE ; GRANT CREATE TABLE, CREATE DYNAMIC TABLE, CREATE STAGE, CREATE SEQUENCE, CREATE CORTEX SEARCH SERVICE ON SCHEMA TO ROLE ; --The following block is for USE CASE 2 (Cortex connect) ONLY --Grant the Cortex read-only role access to the database and schema GRANT USAGE ON DATABASE TO ROLE ; GRANT USAGE ON SCHEMA TO ROLE ; --Create the warehouse this connector will use if it doesn't already exist. Grant the --appropriate privileges to the connector admin role. Adjust the size according to your needs. CREATE WAREHOUSE WITH WAREHOUSE_SIZE = 'MEDIUM' AUTO_SUSPEND = 300 AUTO_RESUME = TRUE; GRANT USAGE, OPERATE ON WAREHOUSE TO ROLE ; ```
## Use case 1: Use the connector definition to ingest files only Use the connector definition to: - Perform custom processing on ingested files - Ingest Google Drive files and permissions and keep them up to date ### Set up the connector As a data engineer, perform the following tasks to install and configure the connector: #### Install the connector To install the connector, do the following as a data engineer: 1. Navigate to the Openflow overview page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find the connector and select **Install**. 3. In the **Select runtime** dialog, select your runtime from the **Available runtimes** drop-down list and click **Install**. Before you install the connector, ensure that you have created a database and schema in Snowflake for the connector to store ingested data. 4. Authenticate to the deployment with your Snowflake account credentials and select **Allow** when prompted to allow the runtime application to access your Snowflake account. The connector installation process takes a few minutes to complete. 5. Authenticate to the runtime with your Snowflake account credentials. The Openflow canvas appears with the connector process group added to it. #### Configure the connector 1. Right-click on the imported process group and select **Parameters**. 2. Enter the required parameter values as described in [Google Drive Source Parameters](#google-drive-source-parameters), [Google Drive Destination Parameters](#google-drive-destination-parameters) and [Google Drive Ingestion Parameters](#google-drive-ingestion-parameters). ##### Google Drive Source Parameters
##### Google Drive Destination Parameters
##### Google Drive Ingestion Parameters
1. Right-click on the plane and select **Enable all Controller Services**. 2. Right-click on the imported process group and select **Start**. The connector starts the data ingestion. ## Use case 2: Use the connector definition to ingest files and perform processing with Cortex Use the predefined flow definition to: - Create AI assistants for public documents within your organization's Google Drive. - Enable your AI assistants to adhere to access controls specified in your organization's Google Drive. ### Set up the connector As a data engineer, perform the following tasks to install and configure the connector: #### Install the connector To install the connector, do the following as a data engineer: 1. Navigate to the Openflow overview page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find the connector and select **Install**. 3. In the **Select runtime** dialog, select your runtime from the **Available runtimes** drop-down list and click **Install**. Before you install the connector, ensure that you have created a database and schema in Snowflake for the connector to store ingested data. 4. Authenticate to the deployment with your Snowflake account credentials and select **Allow** when prompted to allow the runtime application to access your Snowflake account. The connector installation process takes a few minutes to complete. 5. Authenticate to the runtime with your Snowflake account credentials. The Openflow canvas appears with the connector process group added to it. #### Configure the connector 1. Right-click on the imported process group and select **Parameters**. 2. Enter the required parameter values as described in [Google Drive Cortex Connect Source Parameters](#google-drive-cortex-connect-source-parameters), [Google Drive Cortex Connect Destination Parameters](#google-drive-cortex-connect-destination-parameters) and [Google Drive Cortex Connect Ingestion Parameters](#google-drive-cortex-connect-ingestion-parameters). ##### Google Drive Cortex Connect Source Parameters
##### Google Drive Cortex Connect Destination Parameters
##### Google Drive Cortex Connect Ingestion Parameters
1. Right-click on the plane and select **Enable all Controller Services**. 2. Right-click on the imported process group and select **Start**. The connector starts the data ingestion. 3. [](#label-openflow-gdrive-cortex). ## Use case 3: Customize the connector definition Customize the connector definition to perform custom processing on ingested files. ### Set up the connector As a data engineer, perform the following tasks to install and configure the connector: #### Install the connector To install the connector, do the following as a data engineer: 1. Navigate to the Openflow overview page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find the connector and select **Install**. 3. In the **Select runtime** dialog, select your runtime from the **Available runtimes** drop-down list and click **Install**. Before you install the connector, ensure that you have created a database and schema in Snowflake for the connector to store ingested data. 4. Authenticate to the deployment with your Snowflake account credentials and select **Allow** when prompted to allow the runtime application to access your Snowflake account. The connector installation process takes a few minutes to complete. 5. Authenticate to the runtime with your Snowflake account credentials. The Openflow canvas appears with the connector process group added to it. #### Configure the connector 1. Customize the connector definition. 1. Remove the following process groups: - Check If Duplicate Content - Snowflake Stage and Parse PDF - Update Snowflake Cortex 2. Attach any custom processing to the output of the *Process Google Drive Metadata* process group. Each flow file represents a single Google Drive file change. Flow file attributes can be seen in the `Fetch Google Drive Metadata` documentation. 2. Populate the process group parameters. Follow the same process as for [Use case 1: Use the connector definition to ingest files only](#use-case-1-use-the-connector-definition-to-ingest-files-only). Note that after modifying the connector definition, not all parameters might be required. ### Run the flow 1. Run the flow. 1. Start the process group. The flow will create all required objects inside Snowflake. 2. Right-click on the imported process group and select **Start**. 2. [](#label-openflow-gdrive-cortex). #### Query the Cortex Search service You can use the [Cortex Search](/user-guide/snowflake-cortex/cortex-search/cortex-search-overview) service to build chat and search applications to chat with or query your documents in Google Drive. After you install and configure the connector and it begins ingesting content from Google Drive, you can query the Cortex Search service. For more information about using Cortex Search, see [Query a Cortex Search service](/user-guide/snowflake-cortex/cortex-search/query-cortex-search-service). **Filter responses** To restrict responses from the Cortex Search service to documents that a specific user has access to in Google Drive, you can specify a filter containing the user ID or email address of the user when you query Cortex Search. For example, `filter.@contains.user_ids` or `filter.@contains.user_emails`. The name of the Cortex Search service created by the connector is `search_service` in the schema `Cortex`. Run the following SQL code in a SQL worksheet to query the Cortex Search service with files ingested from your Google Drive. Replace the following: - application_instance_name: Name of your database and connector application instance. - user_emailID: Email ID of the user who you want to filter the responses for. - your_question: The question that you want to get responses for. - number_of_results: Maximum number of results to return in the response. The maximum value is 1000 and the default value is 10. ```sql SELECT PARSE_JSON( SNOWFLAKE.CORTEX.SEARCH_PREVIEW( '.cortex.search_service', '{ "query": "", "columns": ["chunk", "web_url"], "filter": {"@contains": {"user_emails": ""} }, "limit": }' ) )['results'] AS results ``` Here's a complete list of values that you can enter for `columns`:
**Example: Query an AI assistant for human resources (HR) information** You can use Cortex Search to query an AI assistant for employees to chat with the latest versions of HR information, such as onboarding, code of conduct, team processes, and organization policies. Using response filters, you can also allow HR team members to query employee contracts while adhering to access controls configured in Google Drive.
Run the following in a [SQL worksheet](#label-snowsight-worksheets-create-file) to query the Cortex Search service with files ingested from Google Drive. Select the database as your application instance name and schema as **Cortex**. Replace the following: - application_instance_name: Name of your database and connector application instance. - user_emailID: Email ID of the user who you want to filter the responses for. ```sql SELECT PARSE_JSON( SNOWFLAKE.CORTEX.SEARCH_PREVIEW( '.cortex.search_service', '{ "query": "What is my vacation carry over policy?", "columns": ["chunk", "web_url"], "filter": {"@contains": {"user_emails": ""} }, "limit": 1 }' ) )['results'] AS results ```
**Python:** Run the following code in a [Python worksheet](#label-snowsight-worksheets-create) to query the Cortex Search service with files ingested from Google Drive. Ensure that you add the `snowflake.core` package to your database. Replace the following: - application_instance_name: Name of your database and connector application instance. - user_emailID: Email ID of the user who you want to filter the responses for. ```python from snowflake.snowpark import Session from snowflake.core import Root def main(session: snowpark.Session): root = Root(session) # fetch service my_service = (root .databases[""] .schemas["cortex"] .cortex_search_services["search_service"] ) # query service resp = my_service.search( query="What is my vacation carry over policy?", columns = ["chunk", "web_url"], filter = {"@contains": {"user_emails": ""} }, limit=1 ) return (resp.to_json()) ``` **REST API:** Execute the following code in a command-line interface to query the Cortex Search service with files ingested from your Google Drive. You'll need to authenticate through key pair authentication and OAuth to access the Snowflake REST APIs. For more information, see [](#label-cortex-search-query-syntax-rest) and [Authenticating Snowflake REST APIs with Snowflake](/developer-guide/snowflake-rest-api/authentication). Replace the following: - application_instance_name: Name of your database and connector application instance. - account_url: Your Snowflake account URL. For instructions on finding your account URL, see [](#label-account-name-find). ```bash curl --location "https:///api/v2/databases//schemas/cortex/cortex-search-services/search_service" \ --header 'Content-Type: application/json' \ --header 'Accept: application/json' \ --header "Authorization: Bearer " \ --data '{ "query": "What is my vacation carry over policy?", "columns": ["chunk", "web_url"], "limit": 1 }' ``` ## Finding files in stage Files stored in the stage may have unreadable names. To find specific files, use the metadata tables as your source of truth. These tables contain the mapping between file names and their corresponding file IDs in the stage. For Cortex-enabled setups, use the following query to find files: ```sql SELECT DISTINCT METADATA:id FROM DOCS_CHUNKS WHERE METADATA:fullName LIKE '%%'; ``` For non-Cortex setups, use the following query: ```sql SELECT FILE_ID FROM DOC_METADATA WHERE FILE_NAME = ''; ``` Replace `` with the name or partial name of the file you're looking for. The files in the stage start with the ID returned from these queries. --- title: Set up the Openflow Connector for Google Sheets source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/google-sheets/setup.md section: Loading & Unloading Data --- # Set up the %sheets% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) This topic describes the steps to set up the %sheets%. ## Prerequisites 1. Ensure that you have reviewed [About Openflow Connector for Google Sheets](/user-guide/data-integration/openflow/connectors/google-sheets/about). 2. Ensure that you have [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) or [Set up Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/setup-openflow-spcs). 3. If using %ofsfspcs-plural%, ensure that you have reviewed [configuring required domains](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list) and have granted access to the required domains for the [](#label-openflow-domains-used-by-openflow-connectors-google-sheets) connector. ## Get the Google Cloud credentials and set up your Google Cloud Project As a Google Cloud administrator, perform the following tasks: 1. Ensure that you have the following: - A Google user with Super Admin permissions (https://support.google.com/a/answer/2405986?hl) - A Google Cloud Project (https://developers.google.com/workspace/guides/create-project) with the following roles: - Organization Policy Administrator (https://cloud.google.com/iam/docs/understanding-roles#orgpolicy.policyAdmin) - Organization Administrator (https://cloud.google.com/iam/docs/understanding-roles#resourcemanager.organizationAdmin) 2. Enable service account key creation. Google disables service account key creation by default. This key creation policy must be turned off for Snowflake Openflow to use the service account JSON. To enable service account key creation, perform the following tasks: 1. Log in to the Google Cloud Console (https://console.cloud.google.com/) with a super admin account that has the Organizational Policy Admin role. 2. Ensure that you are in the project associated with your organization, not the project in your organization. 3. Select **Organization Policies**. 4. Select the **Disable service account key creation** policy. 5. Select **Manage Policy** and turn off enforcement. 6. Select **Set Policy**. 3. Create a service account and key (https://developers.google.com/workspace/guides/create-credentials#service-account). 4. Share the Google Sheets spreadsheet with the service account email address. The email address can be found in the service account JSON file under the *client_email* field. Set the sharing permissions to *Viewer*. 5. Enable the Google Sheets API for your Google Cloud Project. For more information, see Enable the Google Sheets API (https://developers.google.com/sheets/api/guides/concepts#enable_the_google_sheets_api). ## Set up Snowflake account As a Snowflake account administrator, perform the following tasks: 1. Create a new role or use an existing role and grant the [](#label-database-privileges). 2. Create a new Snowflake service user with the type as [SERVICE](#label-user-type-property). 3. Grant the Snowflake service user the role you created in the previous steps. 4. Configure with [key-pair auth](/user-guide/key-pair-auth) for the Snowflake SERVICE user from step 2. 5. Snowflake strongly recommends this step. Configure a secrets manager supported by Openflow, for example, AWS, Azure, and Hashicorp, and store the public and private keys in the secret store. If for any reason, you do not wish to use a secrets manager, then you are responsible for safeguarding the public key and private key files used for key-pair authentication according to the security policies of your organization. 1. Once the secrets manager is configured, determine how you will authenticate to it. On AWS, it's recommended that you the EC2 instance role associated with Openflow as this way no other secrets have to be persisted. 2. In Openflow, configure a Parameter Provider associated with this Secrets Manager, from the hamburger menu in the upper right. Navigate to **Controller Settings** %raa% **Parameter Provider** and then fetch your parameter values. 3. At this point all credentials can be referenced with the associated parameter paths and no sensitive values need to be persisted within Openflow. 6. If any other Snowflake users require access to the raw ingested documents and tables ingested by the connector (for example, for custom processing in Snowflake), then grant those users the role created in step 1. 7. Designate a warehouse for the connector to use. Start with the smallest warehouse size, then experiment with size depending on the number of tables being replicated, and the amount of data transferred. Large table numbers typically scale better with [multi-cluster warehouses](/user-guide/warehouses-multicluster), rather than larger warehouse sizes. ## Set up the connector As a data engineer, perform the following tasks to install and configure the connector: ### Install the connector To install the connector, do the following as a data engineer: 1. Navigate to the Openflow overview page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find the connector and select **Install**. 3. In the **Select runtime** dialog, select your runtime from the **Available runtimes** drop-down list and click **Install**. Before you install the connector, ensure that you have created a database and schema in Snowflake for the connector to store ingested data. 4. Authenticate to the deployment with your Snowflake account credentials and select **Allow** when prompted to allow the runtime application to access your Snowflake account. The connector installation process takes a few minutes to complete. 5. Authenticate to the runtime with your Snowflake account credentials. The Openflow canvas appears with the connector process group added to it. ### Configure the connector 1. Right-click on the imported process group and select **Parameters**. 2. Populate the required parameter values as described in [Flow parameters](#flow-parameters). ### Flow parameters The configuration of the connector definition is divided into three parameter contexts: - [Google Sheets Source Parameters](#google-sheets-source-parameters): Used to establish connection with Google Sheets. - [Google Sheets Destination Parameters](#google-sheets-destination-parameters): Used to establish connection with Snowflake. - [Google Sheets Ingestion Parameters](#google-sheets-ingestion-parameters): Used to define the configuration of data downloaded from Google Sheets. The [Google Sheets Ingestion Parameters](#google-sheets-ingestion-parameters) parameter context contains spreadsheet-specific details, so you must create new parameter contexts for each new spreadsheet and process group. To create a new parameter context, go to the Openflow Canvas menu, select **Parameter Contexts** and add a new parameter context. It inherits parameters from both the Google Sheets Destination Parameters and Google Sheets Source Parameters parameter contexts. The following tables describe the flow parameters that you can configure based on the parameter contexts: #### Google Sheets Destination Parameters
#### Google Sheets Source Parameters
#### Google Sheets Ingestion Parameters The following table lists only those parameters that are not inherited from other parameter contexts.
The destination table identifier is a combination of the destination table prefix and range name and must be unique. If you download data from multiple spreadsheets, or single sheets, and ranges names are not unique, then you must specify unique destination table prefix for each flow. The connector may fail, overwriting existing destination tables, if destination table names aren't unique. ## Run the flow 1. Right-click on the plane and select **Enable all Controller Services**. 2. Right-click on the imported process group and select **Start**. The connector starts the data ingestion. Imported *.xlsx* must be in Google Sheets format. If you import files, ensure that the file is converted to Google Sheets format before running flows. Spreadsheets in any format other than Google Sheets cannot be read. For more information, see Convert files to Google Sheets format (https://support.google.com/docs/answer/9331167?hl=en#2.5). --- title: Set up the Openflow Connector for HubSpot source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/hubspot/setup.md section: Loading & Unloading Data --- # Set up the %hubspot% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) This topic describes the steps to set up the %hubspot%. ## Prerequisites 1. Ensure that you have reviewed [About Openflow Connector for HubSpot](/user-guide/data-integration/openflow/connectors/hubspot/about). 2. Ensure that you have [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) or [Set up Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/setup-openflow-spcs). 3. If using %ofsfspcs-plural%, ensure that you've reviewed [configuring required domains](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list) and have granted access to the required domains for the [](#label-openflow-domains-used-by-openflow-connectors-hubspot) connector. ## Get the credentials As a HubSpot administrator, generate a HubSpot private app token or create one in your HubSpot account. This lets you authenticate your requests to the HubSpot API. 1. Log in to your HubSpot account. 2. Navigate to **Settings** by selecting the gear icon in the top navigation bar. 3. In the left navigation, go to **Integrations** %raa% **Private Apps**. 4. Select **Create a private app**. 1. Enter a name for your app. 2. Navigate to the **Scopes** tab. 3. Select the scopes required for the API requests you intend to make. To find scopes required for the API requests, see Scopes (https://developers.hubspot.com/docs/guides/apps/authentication/scopes). 4. Select **Create app**. 5. Set the required scopes for the API requests you intend to make for each endpoint. 5. Select **View access token** to view the access token. Paste the token in the connector parameters, or save it securely. ## Set up Snowflake account As a Snowflake account administrator, perform the following tasks: 1. Create a new role or use an existing role and grant the [](#label-database-privileges) and [](#label-view-privileges). 2. Create a new Snowflake service user with the type as [SERVICE](#label-user-type-property). 3. Grant the Snowflake service user the role you created in the previous steps. 4. Configure with [key-pair auth](/user-guide/key-pair-auth) for the Snowflake SERVICE user from step 2. 5. Snowflake strongly recommends this step. Configure a secrets manager supported by Openflow, for example, AWS, Azure, and Hashicorp, and store the public and private keys in the secret store. If for any reason, you do not want to use a secrets manager, then you are responsible for safeguarding the public key and private key files used for key-pair authentication according to the security policies of your organization. 1. After the secrets manager is configured, determine how you will authenticate to it. On AWS, it's recommended that you the EC2 instance role associated with Openflow as this way no other secrets have to be persisted. 2. In Openflow, configure a Parameter Provider associated with this Secrets Manager, from the hamburger menu in the upper right. Navigate to **Controller Settings** %raa% **Parameter Provider** and then fetch your parameter values. 3. At this point all credentials can be referenced with the associated parameter paths and no sensitive values need to be persisted within Openflow. 6. If any other Snowflake users require access to the raw ingested documents and tables ingested by the connector (for example, for custom processing in Snowflake), then grant those users the role created in step 1. 7. Create a database and schema in Snowflake for the connector to store ingested data. Grant the following [](#label-database-privileges) to the role created in the first step. ```sql CREATE DATABASE hubspot_destination_db; CREATE SCHEMA hubspot_destination_db.hubspot_destination_schema; GRANT USAGE ON DATABASE hubspot_destination_db TO ROLE ; GRANT USAGE ON SCHEMA hubspot_destination_db.hubspot_destination_schema TO ROLE ; GRANT CREATE TABLE, CREATE VIEW ON SCHEMA hubspot_destination_db.hubspot_destination_schema TO ROLE ; ``` 8. Create a warehouse that will be used by the connector or use an existing one. Start with the smallest warehouse size, then experiment with size depending on the number of tables being replicated, and the amount of data transferred. Large table numbers typically scale better with [multi-cluster warehouses](/user-guide/warehouses-multicluster), rather than larger warehouse sizes. 9. Ensure that the user with role used by the connector has the required privileges to use the warehouse. If that's not the case then grant the required privileges to the role. ```sql CREATE WAREHOUSE hubspot_connector_warehouse WITH WAREHOUSE_SIZE = 'X-Small'; GRANT USAGE ON WAREHOUSE hubspot_connector_warehouse TO ROLE ; ``` ## Set up the connector As a data engineer, perform the following tasks to install and configure the connector: ### Install the connector To install the connector, do the following as a data engineer: 1. Navigate to the Openflow overview page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find the connector and select **Install**. 3. In the **Select runtime** dialog, select your runtime from the **Available runtimes** drop-down list and click **Install**. Before you install the connector, ensure that you have created a database and schema in Snowflake for the connector to store ingested data. 4. Authenticate to the deployment with your Snowflake account credentials and select **Allow** when prompted to allow the runtime application to access your Snowflake account. The connector installation process takes a few minutes to complete. 5. Authenticate to the runtime with your Snowflake account credentials. The Openflow canvas appears with the connector process group added to it. ### Configure the connector 1. Right-click on the imported process group and select **Parameters**. 2. Populate the required parameter values as described in [Flow parameters](#flow-parameters). ### Flow parameters This section describes the flow parameters that you can configure based on the following parameter contexts: - [HubSpot Source Parameters](#hubspot-source-parameters): Used to establish connection with HubSpot. - [HubSpot Destination Parameters](#hubspot-destination-parameters): Used to establish connection with Snowflake. - [HubSpot Ingestion Parameters](#hubspot-ingestion-parameters): Used to define the configuration of data downloaded from HubSpot. #### HubSpot Source Parameters
#### HubSpot Destination Parameters
#### HubSpot Ingestion Parameters
## Run the flow 1. Right-click on the plane and select **Enable all Controller Services**. 2. Right-click on the imported process group and select **Start**. The connector starts the data ingestion. ### Reconfigure the connector You can modify the connector parameters after the connector has started ingesting data. If the issue query criteria changes, perform the following steps to make sure that the data in the destination table is consistent. 1. Stop the connector: Ensure that all Openflow processors are stopped. 2. Access configuration settings: Navigate to the connector's configuration settings within the Snowflake Openflow interface. 3. Modify parameters: Adjust the parameters as required. 4. Clear processor state: If you are changing ingestion criteria, then Snowflake strongly recommends that you start ingestion from the beginning to keep the data in the destination table consistent. After clearing the state in the `List Fresh HubSpot Objects` processor, the connector will fetch all the objects from the beginning. Manual truncation of the destination table may be needed to prevent duplication of rows. ## Data structure and views The connector stores data in the following two formats within your Snowflake database: ### Raw data storage All raw HubSpot data is stored in tables with the exact names specified in the Object Types parameter. For example: - If you configure `Products,Contacts,Companies` in the Object Types parameter, the connector creates three tables: `PRODUCTS`, `CONTACTS`, and `COMPANIES`. - Each table contains the complete JSON payload from the HubSpot API responses. - Raw data preserves the original structure and all metadata from HubSpot. ### Flattened views For easier querying and analysis, the connector automatically creates flattened views for each object type: - Each raw table has a corresponding view with the suffix `_VIEW`. For example: `PRODUCTS_VIEW`, `CONTACTS_VIEW`, and `COMPANIES_VIEW`. - Views extract commonly used fields from the JSON payload into individual columns. - Complex nested structures are flattened for simplified SQL queries. --- title: Set up the Openflow Connector for Jira Cloud source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/jira-cloud/setup.md section: Loading & Unloading Data --- # Set up the %jira% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) This topic describes the steps to set up the %jira%. ## Prerequisites 1. Ensure that you have reviewed [About Openflow Connector for Jira Cloud](about). 2. Ensure that you have [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) or [Set up Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/setup-openflow-spcs). 3. If using %ofsfspcs-plural%, ensure that you've reviewed [configuring required domains](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list) and have granted access to the required domains for the [](#label-openflow-domains-used-by-openflow-connectors-jira-cloud) connector. ## Get the credentials As a Jira Cloud administrator, perform the following tasks in your Atlassian account: 1. Navigate to the API tokens page (https://id.atlassian.com/manage-profile/security/api-tokens). 2. Select **Create API token with scopes**. 3. In the **Create an API token** dialog box, provide a descriptive name for the API token and select an expiration date for the API token. This can range from 1 to 365 days. 4. Select the Api token app **Jira**. 5. Select jira scopes `read:jira-work` and `read:jira-user`. 6. Select **Create token**. 7. In the **Copy your API token** dialog box, select **Copy** to copy your generated API token and then paste the token to the connector parameters, or save it securely. 8. Select **Close** to close the dialog box. ## Set up Snowflake account As a Snowflake account administrator, perform the following tasks: 1. Create a new role or use an existing role. 2. Create a new Snowflake service user with the type as [SERVICE](#label-user-type-property). 3. Grant the Snowflake service user the role you created in the previous steps. 4. Configure with [key-pair auth](/user-guide/key-pair-auth) for the Snowflake SERVICE user from step 2. 5. Snowflake strongly recommends this step. Configure a secrets manager supported by Openflow, for example, AWS, Azure, and Hashicorp, and store the public and private keys in the secret store. If for any reason, you do not wish to use a secrets manager, then you are responsible for safeguarding the public key and private key files used for key-pair authentication according to the security policies of your organization. 6. Once the secrets manager is configured, determine how you will authenticate to it. On AWS, it's recommended that you the EC2 instance role associated with Openflow as this way no other secrets have to be persisted. 7. In Openflow, configure a Parameter Provider associated with this Secrets Manager, from the hamburger menu in the upper right. Navigate to **Controller Settings** %raa% **Parameter Provider** and then fetch your parameter values. 8. At this point all credentials can be referenced with the associated parameter paths and no sensitive values need to be persisted within Openflow. 9. If any other Snowflake users require access to the raw ingested documents and tables ingested by the connector (for example, for custom processing in Snowflake), then grant those users the role created in step 1. 10. Create a database and schema in Snowflake for the connector to store ingested data. Grant the following [](#label-database-privileges) to the role created in the first step.
```sql CREATE DATABASE jira_destination_db; CREATE SCHEMA jira_destination_db.jira_destination_schema; GRANT USAGE ON DATABASE jira_destination_db TO ROLE ; GRANT USAGE ON SCHEMA jira_destination_db.jira_destination_schema TO ROLE ; GRANT CREATE TABLE, CREATE VIEW ON SCHEMA jira_destination_db.jira_destination_schema TO ROLE ; ```
11. Create a warehouse that will be used by the connector or use an existing one. Start with the smallest warehouse size, then experiment with size depending on the number of tables being replicated, and the amount of data transferred. Large table numbers typically scale better with [multi-cluster warehouses](/user-guide/warehouses-multicluster), rather than larger warehouse sizes. 12. Ensure that the user with role used by the connector has the required privileges to use the warehouse. If that's not the case then grant the required privileges to the role.
```sql CREATE WAREHOUSE jira_connector_warehouse WITH WAREHOUSE_SIZE = 'X-Small'; GRANT USAGE ON WAREHOUSE jira_connector_warehouse TO ROLE ; ```
## Set up the connector As a data engineer, perform the following tasks to install and configure the connector: ### Install the connector To install the connector, do the following as a data engineer: 1. Navigate to the Openflow overview page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find the connector and select **Install**. 3. In the **Select runtime** dialog, select your runtime from the **Available runtimes** drop-down list and click **Install**. Before you install the connector, ensure that you have created a database and schema in Snowflake for the connector to store ingested data. 4. Authenticate to the deployment with your Snowflake account credentials and select **Allow** when prompted to allow the runtime application to access your Snowflake account. The connector installation process takes a few minutes to complete. 5. Authenticate to the runtime with your Snowflake account credentials. The Openflow canvas appears with the connector process group added to it. ### Configure the connector 1. Right-click on the imported process group and select **Parameters**. 2. Populate the required parameter values as described in [Flow parameters](#flow-parameters). ### Flow parameters This section describes the flow parameters that you can configure based on the following parameter contexts: - [Jira Cloud Source Parameters](#jira-cloud-source-parameters): Used to establish connection with Jira API. - [Jira Cloud Destination Parameters](#jira-cloud-destination-parameters): Used to establish connection with Snowflake. - [Jira Cloud Ingestion Parameters](#jira-cloud-ingestion-parameters): Used to define the configuration of data downloaded from Jira. Modifying the parameters related to ingestion configuration (for example, Search Type, JQL Query, Project Names, and Created After) will reset the state of the `FetchJiraIssues` processor, allowing it to fetch all issues again. This is useful if you want to change the issue query criteria or restart the ingestion from scratch. This reset action does not truncate the destination table. #### Jira Cloud Source Parameters
#### Jira Cloud Destination Parameters
#### Jira Cloud Ingestion Parameters
## Run the flow 1. Right-click on the plane and select **Enable all Controller Services**. 2. Right-click on the imported process group and select **Start**. The connector starts the data ingestion. If you need to change the issue query criteria or want to restart the ingestion from scratch, perform the following steps to ensure that the data in the destination table is consistent: 1. Right-click on the **FetchJiraIssues** processor and stop it. 2. Right-click on the **FetchJiraIssues** processor and then select **View State**. 3. In the **State** dialog box, select **Clear State**. This action clears the state of the processor and allows it to fetch all issues again. 4. Optional: If you want to change the issue query criteria, right-click on the imported process group and select **Parameters**. Update the parameters as needed. 5. Optional: If you want to change the destination table name, right-click on the imported process group and select **Parameters**. Update the `Destination Table` parameter. 6. Right-click on the **FetchJiraIssues** processor and select **Start**. The connector starts the data ingestion. 7. After ingestion, the data is available in the Snowflake destination table and in a flattened format in the destination view. The view includes all fields available in the Jira instance. ## Accessing the data Data fetched from Jira is available in the destination table. All fields fetched for Jira issue is available in the `ISSUE` column as an object in raw form fetched from the API. To help with querying the data, a flattened view is created based on the destination table. The view name is a concatenation of the table name and the suffix `_VIEW`. For example, if the destination table is named `JIRA_ISSUES`, then the view will be named `JIRA_ISSUES_VIEW`. In the view, all issue fields are extracted and available as separate columns. The column name is set to the field label. If there are many issues with the same label, a suffix with field ID is added to the column name to ensure uniqueness. For example, if there are two fields with IDs `customfield_1`, `customfield_2`, the label set in both fields to `Custom Field`, then the columns in the view will be named `Custom Field (customfield_1)`, `Custom Field (customfield_2)`. --- title: Set up the Openflow Connector for Kafka source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/kafka/setup.md section: Loading & Unloading Data --- # Set up the Openflow Connector for Kafka This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) ## Prerequisites 1. Ensure that you have reviewed [Snowflake Openflow Connector for Kafka](/user-guide/data-integration/openflow/connectors/kafka/about). 2. Ensure that you have [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) or [Set up Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/setup-openflow-spcs). 3. If using Openflow - Snowflake Deployments, ensure that you've reviewed [configuring required domains](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list) and have granted access to the required domains for the Kafka connector. The connector must be able to connect to all Kafka brokers in the cluster. ## Set up Snowflake account As a Snowflake account administrator, perform the following tasks: 1. Create a new Snowflake service user with the type as [SERVICE](#label-user-type-property). 2. Create a new role or use an existing role and grant the [Database privileges](#label-database-privileges). The connector requires a user to create the destination table. Make sure the user has the required privileges for managing Snowflake objects:
Snowflake recommends creating a separate user and role for each Kafka Cluster for better access control. You can use the following script to create and configure a custom role (requires SECURITYADMIN or equivalent): ```sql USE ROLE securityadmin; CREATE ROLE openflow_kafka_connector_role_1; GRANT USAGE ON DATABASE kafka_db TO ROLE openflow_kafka_connector_role_1; GRANT USAGE ON SCHEMA kafka_schema TO ROLE openflow_kafka_connector_role_1; ``` Privileges must be granted directly to the connector role and cannot be inherited. 3. Configure the destination table Snowflake highly recommends using server-side schema evolution for schema changes and [an error table for DML error logging](/user-guide/data-load-overview). The following example shows how to create a table and add proper OWNERSHIP permissions. ```sql USE ROLE openflow_kafka_connector_role_1; CREATE TABLE kafka_db.kafka_schema. ( kafkaMetadata variant ) ENABLE_SCHEMA_EVOLUTION = TRUE ERROR_LOGGING = TRUE; USE ROLE securityadmin; GRANT OWNERSHIP ON TABLE existing_table1 TO ROLE openflow_kafka_connector_role_1; ``` The connector supports automatic schema detection and evolution. The structure of tables in Snowflake is defined and evolved automatically to support the structure of new data loaded by the connector. It automatically maps the record content's first-level keys to table columns matching by name (case-insensitive). With Schema evolution enabled, Snowflake can automatically expand the destination table by adding new columns that are detected in the incoming stream and dropping NOT NULL constraints to accommodate new data patterns. For more information, see [Table schema evolution](/user-guide/data-load-schema-evolution). If ENABLE_SCHEMA_EVOLUTION isn't enabled, you must create the schema manually by extending the table definition. The connector tries to match the record content's first-level keys to the table columns by name. If keys from the JSON don't match the table columns, the connector ignores the keys. 4. (Optional) Configure a secrets manager Snowflake strongly recommends this step. Configure a secrets manager supported by Openflow, for example, AWS, Azure, and Hashicorp, and store the public and private keys in the secret store. 1. Determine how you'll authenticate to the secrets manager after it's configured. On AWS, Snowflake recommends using the EC2 instance role associated with Openflow so no other secrets need to be persisted. 2. Configure a Parameter Provider associated with this Secrets Manager in Openflow from the hamburger menu in the upper right. Navigate to Controller Settings > Parameter Provider and fetch your parameter values. 3. Reference all credentials with the associated parameter paths so no sensitive values need to be persisted within Openflow. 5. Grant access to users For any other Snowflake users who require access to the raw ingested data by the connector (for example, for custom processing in Snowflake), grant those users the role created in step 1. ## Set up the connector As a data engineer, perform the following tasks to install and configure the connector: ### Install the connector To install the connector, do the following: 1. Navigate to the Openflow overview page. In the **Featured connectors section**, select **View more connectors**. 2. On the Openflow connectors page, find the connector and select **Install**. 3. In the Select runtime dialog, select your runtime from the **Available runtimes** drop-down list and select **Add**. Before you install the connector, ensure that you have created a database, schema, and a table in Snowflake for the connector to store ingested data. 4. Authenticate to the deployment with your Snowflake account credentials and select **Allow** when prompted to allow the runtime application to access your Snowflake account. The connector installation process takes a few minutes to complete. 5. Authenticate to the runtime with your Snowflake account credentials. The Openflow canvas appears with the connector process group added to it. ### Configure the connector 1. If needed, customize the connector configuration before configuring the built-in parameters. Some common customizations have dedicated guides, such as custom transformations, Avro and Protobuf data type ingestion, and dead-letter-queue handling. You can also apply customizations using the Openflow skill in Snowflake CoCo. See [Configuring custom transformations](/user-guide/data-integration/openflow/connectors/streaming/configuring-custom-transformations) for more details. 2. Populate the process group parameters 1. Right click on the imported process group and select Parameters. 2. Fill out the required parameter values #### Parameters The following table describes the parameters for the Openflow Connector for Kafka:
### Start the connector 1. Right-click on the plane and select **Enable all Controller Services**. 2. Right-click on the plane and select **Start**. The connector starts data ingestion. ## Understanding KAFKAMETADATA column The connector populates the KAFKAMETADATA structure with metadata about the Kafka record. The structure contains the following information:
## Measuring ingestion latency For change tracking, incremental processing, and time-travel queries based on row modification time, the ROW_TIMESTAMP feature can be used. Enable it by running the following command on your destination table: ```sql ALTER TABLE SET ROW_TIMESTAMP = TRUE; ``` After row timestamps are enabled, tables expose the `METADATA$ROW_LAST_COMMIT_TIME` column, which returns the timestamp when each row was last modified. For more information, see [METADATA$ROW_LAST_COMMIT_TIME](/user-guide/data-load-overview). Row timestamp isn't available for interactive tables. For more information, see [Snowflake interactive analytics](/user-guide/interactive). ## Using the connector with Apache Iceberg™ tables The connector can ingest data into a Snowflake-managed Apache Iceberg™ table. The connector doesn't create Iceberg tables automatically. You must create the Iceberg table manually before you run the connector. The connector supports server-side schema evolution for Iceberg destination tables, the same way it does for standard Snowflake tables. When the destination table has `ENABLE_SCHEMA_EVOLUTION = TRUE`, Snowflake automatically adds new columns that are detected in the incoming stream and drops NOT NULL constraints to accommodate new data patterns. For more information about how schema evolution behaves, see [Table schema evolution](/user-guide/data-load-schema-evolution). The Iceberg table can use either of the following storage options: - [Snowflake storage](/user-guide/tables-iceberg-internal-storage): Snowflake stores and manages the Iceberg table files for you, so you don't need to create an external volume or grant the connector access to it. - External cloud storage that you manage, accessed through an external volume. You must grant the connector role USAGE on the external volume. ### Grant usage on an external volume This step applies only when the Iceberg table uses an external volume that you manage. If the table uses [Snowflake storage](/user-guide/tables-iceberg-internal-storage), skip this step. For example, if your Iceberg table uses the `kafka_external_volume` external volume and the connector uses the role `openflow_kafka_connector_role`, run the following statement: ```sql USE ROLE ACCOUNTADMIN; GRANT USAGE ON EXTERNAL VOLUME kafka_external_volume TO ROLE openflow_kafka_connector_role; ``` ### Create an Apache Iceberg™ table for ingestion When you create an Iceberg table, you can use Iceberg data types (including VARIANT) or [compatible Snowflake types](/user-guide/tables-iceberg-data-types). For example, consider the following message: ```json { "id": 1, "name": "Steve", "body_temperature": 36.6, "approved_coffee_types": ["Espresso", "Doppio", "Ristretto", "Lungo"], "animals_possessed": { "dogs": true, "cats": false }, "options": { "can_walk": true, "can_talk": false }, "date_added": "2024-10-15" } ``` To create an Iceberg table for the example message, use one of the following statements. To use [Snowflake storage](/user-guide/tables-iceberg-internal-storage), set `EXTERNAL_VOLUME = 'SNOWFLAKE_MANAGED'` and omit `BASE_LOCATION`: ```sql CREATE OR REPLACE ICEBERG TABLE my_iceberg_table ( kafkaMetadata OBJECT( topic STRING, partition INTEGER, offset BIGINT, key STRING, headers MAP(STRING, STRING), timestamp BIGINT ), id INT, name string, body_temperature float, approved_coffee_types array(string), animals_possessed variant, date_added date, options object(can_walk boolean, can_talk boolean) ) EXTERNAL_VOLUME = 'SNOWFLAKE_MANAGED' CATALOG = 'SNOWFLAKE' ICEBERG_VERSION = 3; ``` To use your own external volume, set `EXTERNAL_VOLUME` to the volume name and provide a `BASE_LOCATION`: ```sql CREATE OR REPLACE ICEBERG TABLE my_iceberg_table ( kafkaMetadata OBJECT( topic STRING, partition INTEGER, offset BIGINT, key STRING, headers MAP(STRING, STRING), timestamp BIGINT ), id INT, name string, body_temperature float, approved_coffee_types array(string), animals_possessed variant, date_added date, options object(can_walk boolean, can_talk boolean) ) EXTERNAL_VOLUME = 'my_volume' CATALOG = 'SNOWFLAKE' BASE_LOCATION = 'my_location/my_iceberg_table' ICEBERG_VERSION = 3; ``` ## Using the connector with Interactive Tables Interactive tables are a special type of Snowflake table optimized for low-latency, high-concurrency queries. For more information, see [Snowflake interactive analytics](/user-guide/interactive). 1. Create an interactive table: ```sql CREATE INTERACTIVE TABLE REALTIME_METRICS ( metric_name VARCHAR, metric_value NUMBER, source_topic VARCHAR, timestamp TIMESTAMP_NTZ ) AS (SELECT $1:M_NAME::VARCHAR, $1:M_VALUE::NUMBER, $1:RECORD_METADATA.topic::VARCHAR, $1:RECORD_METADATA.timestamp::TIMESTAMP_NTZ from TABLE(DATA_SOURCE(TYPE => 'STREAMING'))); ``` Important considerations: - Interactive tables have specific limitations and query restrictions. Review [Snowflake interactive analytics](/user-guide/interactive) before using them with the connector. - For interactive tables, any required transformations must be handled in the table definition. - Interactive warehouses are required to query interactive tables efficiently. ## Using the connector with a customer-defined schema for the destination table The connector treats each Kafka record as a row to be inserted into a Snowflake table. For example, if you have a Kafka topic with the content of the message structured like the following JSON: ```json { "order_id": 12345, "customer_name": "John", "order_total": 100.00, "isPaid": true } ``` By default you don't have to specify all fields from the JSON thanks to the `ENABLE_SCHEMA_EVOLUTION = TRUE` feature. However, if you prefer a static schema, it can be created by running: ```sql CREATE TABLE ORDERS ( kafkaMetadata OBJECT, order_id NUMBER, customer_name VARCHAR, order_total FLOAT, ispaid BOOLEAN ); ``` ## Using the connector with a customer-defined PIPE If you choose to create your own pipe, you can define the data transformation logic in the pipe's [COPY INTO](/sql-reference/sql/copy-into-table) statement. You can rename columns as required and cast the data types as needed. For example: ```sql CREATE TABLE ORDERS ( order_id VARCHAR, customer_name VARCHAR, order_total VARCHAR, ispaid VARCHAR ); CREATE PIPE ORDERS AS COPY INTO ORDERS SELECT $1:order_id::STRING, $1:customer_name, $1:order_total::STRING, $1:isPaid::STRING FROM TABLE(DATA_SOURCE(TYPE => 'STREAMING')); ``` When you define your own pipe, your destination table columns don't need to match the JSON keys. You can rename the columns to your desired names and cast the data types if required. To adjust the connector to work with a custom pipe, perform the following tasks: 1. Right-click on the PublishSnowpipeStreaming processor used in your Kafka ingestion flow in the Openflow canvas. 2. Select Configure from the context menu. 3. Navigate to the Properties tab. 4. In the Destination type field, pick Pipe. 5. In the Pipe field, type the name of your PIPE. 6. Select Apply to save the configuration. ## Customizing error handling Error handling is split between Openflow-side failures and server-side failures within the Snowpipe Streaming service. - **Openflow Errors (Client-Side Failures)**: Errors such as unparseable payloads or custom transformation failures occur before records reach Snowflake. By default these records are discarded. It's possible to process these errors in Openflow - use FlowFiles from the parse failure relationship in the ConsumeKafka processor. For a complete walkthrough, see [Kafka as destination for DLQ messages](configuring-dead-letter-queue-handling) and the shared [Configuring Dead Letter Queue (DLQ) handling](/user-guide/data-integration/openflow/connectors/streaming/configuring-dead-letter-queue-handling). - **Snowpipe Streaming Errors (Server-Side Failures)**: Errors for records that successfully reach Snowflake but are incompatible with the destination table's schema (for example, type mismatches) are captured by the Snowflake infrastructure. When error logging is enabled on the destination table (`error_logging = true`), these failed rows are automatically ingested into the destination Error table. ## Performance tuning [Performance Tuning of the Openflow Connector for Kafka](/user-guide/data-integration/openflow/connectors/kafka/performance-tuning) --- title: Set up the Openflow Connector for LinkedIn Ads source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/linkedin-ads/setup.md section: Loading & Unloading Data --- # Set up the %linkedinads% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) This topic describes the steps to set up the %linkedinads%. ## Prerequisites 1. Ensure that you have reviewed [About Openflow Connector for LinkedIn Ads](/user-guide/data-integration/openflow/connectors/linkedin-ads/about). 2. Ensure that you have [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) or [Set up Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/setup-openflow-spcs). 3. If using %ofsfspcs-plural%, ensure that you've reviewed [configuring required domains](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list) and have granted access to the required domains for the [](#label-openflow-domains-used-by-openflow-connectors-linkedinads) connector. ## Get the credentials 1. As a LinkedIn Ads user, perform the following tasks: 1. Optional: If you don't have an ad account to run and manage campaigns, create one. 2. Ensure that the user account has at least a VIEWER role on the ad account. 3. Use the user account to apply for Advertising API access. For more information, see the Microsoft quick start (https://learn.microsoft.com/en-us/linkedin/marketing/quick-start?view=li-lms-2025-02#step-1-apply-for-api-access). 4. Obtain a refresh token (https://learn.microsoft.com/en-us/linkedin/shared/authentication/developer-portal-tools?context=linkedin%2Fcontext#generate-a-token-in-the-developer-portal). Use `3-legged oAuth` and the `r_ads_reporting` scope. 5. Obtain the client ID and client secret from the LinkedIn Developer Portal. These credentials are available in the **Auth** tab in App Details. ## Set up Snowflake account As a Snowflake account administrator, perform the following tasks: 1. Create a new role or use an existing role. 2. Create a new Snowflake service user with the type as [SERVICE](#label-user-type-property). 3. Grant the Snowflake service user the role you created in the previous steps. 4. Configure with [key-pair auth](/user-guide/key-pair-auth) for the Snowflake SERVICE user from step 2. 5. Snowflake strongly recommends this step. Configure a secrets manager supported by Openflow, for example, AWS, Azure, and Hashicorp, and store the public and private keys in the secret store. If for any reason, you do not wish to use a secrets manager, then you are responsible for safeguarding the public key and private key files used for key-pair authentication according to the security policies of your organization. 6. Once the secrets manager is configured, determine how you will authenticate to it. On AWS, it's recommended that you the EC2 instance role associated with Openflow as this way no other secrets have to be persisted. 7. In Openflow, configure a Parameter Provider associated with this Secrets Manager, from the hamburger menu in the upper right. Navigate to **Controller Settings** %raa% **Parameter Provider** and then fetch your parameter values. 8. At this point all credentials can be referenced with the associated parameter paths and no sensitive values need to be persisted within Openflow. 9. If any other Snowflake users require access to the raw ingested documents and tables ingested by the connector (for example, for custom processing in Snowflake), then grant those users the role created in step 1. 10. Create a database and schema in Snowflake for the connector to store ingested data. Grant required [](#label-database-privileges) to the role created in the first step. Substitute the role placeholder with the actual value and use the following sql commands: ```sql CREATE DATABASE linkedin_destination_db; CREATE SCHEMA linkedin_destination_db.linkedin_destination_schema; GRANT USAGE ON DATABASE linkedin_destination_db TO ROLE ; GRANT USAGE ON SCHEMA linkedin_destination_db.linkedin_destination_schema TO ROLE ; GRANT CREATE TABLE ON SCHEMA linkedin_destination_db.linkedin_destination_schema TO ROLE ; ``` 11. Create a warehouse that will be used by the connector or use an existing one. Start with the smallest warehouse size, then experiment with size depending on the number of tables being replicated, and the amount of data transferred. Large table numbers typically scale better with [multi-cluster warehouses](/user-guide/warehouses-multicluster), rather than larger warehouse sizes. 12. Ensure that the user with role used by the connector has the required privileges to use the warehouse. If that's not the case then grant the required privileges to the role. ```sql CREATE WAREHOUSE linkedin_connector_warehouse WITH WAREHOUSE_SIZE = 'X-Small'; GRANT USAGE ON WAREHOUSE linkedin_connector_warehouse TO ROLE ; ``` ## Set up the connector As a data engineer, perform the following tasks to install and configure the connector: ### Install the connector 1. Create a database and schema in Snowflake for the connector to store ingested data. Grant required [](#label-database-privileges) to the role created in the first step. Substitute the role placeholder with the actual value and use the following SQL commands: ```sql CREATE DATABASE DESTINATION_DB; CREATE SCHEMA DESTINATION_DB.DESTINATION_SCHEMA; GRANT USAGE ON DATABASE DESTINATION_DB TO ROLE ; GRANT USAGE ON SCHEMA DESTINATION_DB.DESTINATION_SCHEMA TO ROLE ; GRANT CREATE TABLE, CREATE PIPE ON SCHEMA DESTINATION_DB.DESTINATION_SCHEMA TO ROLE ; ``` To install the connector, do the following as a data engineer: 1. Navigate to the Openflow overview page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find the connector and select **Install**. 3. In the **Select runtime** dialog, select your runtime from the **Available runtimes** drop-down list and click **Install**. Before you install the connector, ensure that you have created a database and schema in Snowflake for the connector to store ingested data. 4. Authenticate to the deployment with your Snowflake account credentials and select **Allow** when prompted to allow the runtime application to access your Snowflake account. The connector installation process takes a few minutes to complete. 5. Authenticate to the runtime with your Snowflake account credentials. The Openflow canvas appears with the connector process group added to it. ### Configure the connector Each process group is responsible for fetching data for a single report configuration. To use multiple configurations on a regular schedule, create a separate process group for each report configuration. 1. Right-click on the imported process group and select **Parameters**. 2. Populate the required parameter values as described in [Flow parameters](#flow-parameters). ### Flow parameters This section describes the flow parameters that you can configure based on the following parameter contexts: - [Linkedin Ads Source Parameters](#linkedin-ads-source-parameters): Used to establish connection with LinkedIn Ads API. - [Linkedin Ads Destination Parameters](#linkedin-ads-destination-parameters): Used to establish connection with Snowflake. -
[Linkedin Ads Ingestion Parameters](#linkedin-ads-ingestion-parameters): Contains all parameters from the other two parameter contexts and additional parameters specific to a given process group.
Because this parameter context contains ingestion-specific details, you must create new parameter contexts for each new report and process group.
#### Linkedin Ads Source Parameters
#### Linkedin Ads Destination Parameters
#### Linkedin Ads Ingestion Parameters The following table lists parameters that are not inherited from the other parameter contexts:
You must specify at least one of the filters, that is shares, campaigns, campaign groups, accounts, or companies. ## Run the flow 1. Right-click on the plane and select **Enable all Controller Services**. 2.
Right-click on the imported process group and select **Start**.
The connector starts the data ingestion.
--- title: Set up the Openflow Connector for Meta Ads source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/meta-ads/setup.md section: Loading & Unloading Data --- # Set up the %metaads% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) This topic describes the steps to set up the %metaads%. ## Prerequisites 1. Ensure that you have reviewed [About Openflow Connector for Meta Ads](/user-guide/data-integration/openflow/connectors/meta-ads/about). 2. Ensure that you have [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) or [Set up Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/setup-openflow-spcs). 3. If using %ofsfspcs-plural%, ensure that you've reviewed [configuring required domains](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list) and have granted access to the required domains for the [](#label-openflow-domains-used-by-openflow-connectors-meta-ads) connector. ## Get the credentials As a Meta Ads administrator, perform the following actions in your Meta Ads account: 1. Create a Meta App (https://developers.facebook.com/docs/development/create-an-app/) or ensure that you have access to one. 2. Enable Marketing API (https://developers.facebook.com/docs/marketing-api/get-started) in the App dashboard (https://developers.facebook.com/apps). 3. Generate a long-lived token (https://developers.facebook.com/docs/facebook-login/guides/access-tokens/get-long-lived/). 4. Optional: Increase the rate limit by changing the app access type (https://developers.facebook.com/docs/marketing-api/overview/rate-limiting) from `Standard access` to `Advanced access` of the Ads Management Standard Access. Enable the `ads_read` and `ads_management` permissions (https://developers.facebook.com/docs/permissions/). ## Set up Snowflake account As a Snowflake account administrator, perform the following tasks: 1. Create a new role or use an existing role and grant the [](#label-database-privileges). 2. Create a new Snowflake service user with the type as [SERVICE](#label-user-type-property). 3. Grant the Snowflake service user the role you created in the previous steps. 4. Configure with [key-pair auth](/user-guide/key-pair-auth) for the Snowflake SERVICE user from step 2. 5. Snowflake strongly recommends this step. Configure a secrets manager supported by Openflow, for example, AWS, Azure, and Hashicorp, and store the public and private keys in the secret store. If for any reason, you do not wish to use a secrets manager, then you are responsible for safeguarding the public key and private key files used for key-pair authentication according to the security policies of your organization. 1. Once the secrets manager is configured, determine how you will authenticate to it. On AWS, it's recommended that you the EC2 instance role associated with Openflow as this way no other secrets have to be persisted. 2. In Openflow, configure a Parameter Provider associated with this Secrets Manager, from the hamburger menu in the upper right. Navigate to **Controller Settings** %raa% **Parameter Provider** and then fetch your parameter values. 3. At this point all credentials can be referenced with the associated parameter paths and no sensitive values need to be persisted within Openflow. 6. If any other Snowflake users require access to the raw ingested documents and tables ingested by the connector (for example, for custom processing in Snowflake), then grant those users the role created in step 1. 7. Designate a warehouse for the connector to use. Start with the smallest warehouse size, then experiment with size depending on the number of tables being replicated, and the amount of data transferred. Large table numbers typically scale better with [multi-cluster warehouses](/user-guide/warehouses-multicluster), rather than larger warehouse sizes. ## Set up the connector As a data engineer, perform the following tasks to install and configure the connector: ### Install the connector 1. Create a database and schema in Snowflake for the connector to store ingested data.Grant required [](#label-database-privileges) to the role created in the first step. Substitute the role placeholder with the actual value and use the following sql commands: ```sql CREATE DATABASE META_ADS_DESTINATION_DB; CREATE SCHEMA META_ADS_DESTINATION_DB.META_ADS_DESTINATION_SCHEMA; GRANT USAGE ON DATABASE META_ADS_DESTINATION_DB TO ROLE ; GRANT USAGE ON SCHEMA META_ADS_DESTINATION_DB.META_ADS_DESTINATION_SCHEMA TO ROLE ; GRANT CREATE TABLE ON SCHEMA META_ADS_DESTINATION_DB.META_ADS_DESTINATION_SCHEMA TO ROLE ; ``` To install the connector, do the following as a data engineer: 1. Navigate to the Openflow overview page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find the connector and select **Install**. 3. In the **Select runtime** dialog, select your runtime from the **Available runtimes** drop-down list and click **Install**. Before you install the connector, ensure that you have created a database and schema in Snowflake for the connector to store ingested data. 4. Authenticate to the deployment with your Snowflake account credentials and select **Allow** when prompted to allow the runtime application to access your Snowflake account. The connector installation process takes a few minutes to complete. 5. Authenticate to the runtime with your Snowflake account credentials. The Openflow canvas appears with the connector process group added to it. ### Configure the connector 1. Right-click on the imported process group and select **Parameters**. 2. Populate the required parameter values as described in [Flow parameters](#flow-parameters). ### Flow parameters This section describes the flow parameters that you can configure based on the following parameter contexts: - [Meta Ads Source Parameters](#meta-ads-source-parameters): Used to establish connection with MetaAds API. - [Meta Ads Destination Parameters](#meta-ads-destination-parameters): Used to establish connection with Snowflake. - [Meta Ads Ingestion Parameters](#meta-ads-ingestion-parameters): Used to define the configuration of data downloaded from Meta Ads. #### Meta Ads Source Parameters
#### Meta Ads Destination Parameters
#### Meta Ads Ingestion Parameters
## Run the flow 1. Right-click on the plane and select **Enable all Controller Services**. 2. Right-click on the imported process group and select **Start**. The connector starts the data ingestion. ## How to reset the connector To fully reset connector to the initial state, do the following: 1. Ensure that there are no more flow files in the queues. 2. Stop all the processors. 3. Clear the state of the initial processor. 1. Right click on the processor `Create Meta Ads Report` and select **View State**. 2. Select the option **Clear State**. This resets the state of the processor. 4. Drop the destination table in Snowflake. --- title: Set up the Openflow Connector for Microsoft Dataverse source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/dataverse/setup.md section: Loading & Unloading Data --- # Set up the Openflow Connector for Microsoft Dataverse This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) This topic describes the steps to set up the Openflow Connector for Microsoft Dataverse. ## Prerequisites 1. Ensure that you have reviewed [About Openflow Connector for Microsoft Dataverse](/user-guide/data-integration/openflow/connectors/dataverse/about). 2. Ensure that you have [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) or [Set up Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/setup-openflow-spcs). 3. If using %ofsfspcs-plural%, ensure that you've reviewed [configuring required domains](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list) and have granted access to the required domains for the [](#label-openflow-domains-used-by-openflow-connectors-dataverse) connector. ## Get the credentials As a Microsoft Dataverse administrator, perform the following steps: 1. Ensure you have a Dataverse Environment to work with, and you have access to that environment through https://admin.powerplatform.microsoft.com/ (https://admin.powerplatform.microsoft.com/). 2. Ensure that you have an application registered in Microsoft Entra ID in portal.azure.com. This application must have access to the tenant we have our Dataverse Environment available. To register the application follow this guide (https://learn.microsoft.com/en-us/power-apps/developer/data-platform/walkthrough-register-app-azure-active-directory). 3. Generate and store ClientID and Client Secret within that application. 4. Go to Power Apps Admin Center and configure your Dataverse Environment to be accessed via applications registered before. To do that, go to **Manage** %raa% **Environments** and select the environment to configure. Then go to **Settings** %raa% **Users & permissions** %raa% **Application users**. Previously created applications must be added and granted with privileges necessary to read data from Microsoft Dataverse. 5. Copy and save the Environment URL of the selected Dataverse Environment from https://admin.powerplatform.microsoft.com/ (https://admin.powerplatform.microsoft.com/). ## Set up Snowflake account As a Snowflake account administrator, perform the following tasks: 1.
Create a Snowflake user with the type as [SERVICE](#label-user-type-property).
Create a database and schema to store the replicated data, and set up privileges for the service user to create tables in destination schema by granting the [USAGE and CREATE TABLE privileges](#label-database-privileges). ```sql CREATE DATABASE ; CREATE SCHEMA .; CREATE USER TYPE=SERVICE COMMENT='Service user for automated access of Openflow'; CREATE ROLE ; GRANT ROLE TO USER ; GRANT USAGE ON DATABASE TO ROLE ; GRANT USAGE ON SCHEMA . TO ROLE ; GRANT CREATE TABLE ON SCHEMA . TO ROLE ; CREATE WAREHOUSE WITH WAREHOUSE_SIZE = 'SMALL' AUTO_SUSPEND = 300 AUTO_RESUME = TRUE; GRANT USAGE, OPERATE ON WAREHOUSE TO ROLE ; ```
1. Create a pair of secure keys (public and private). Store the private key for the user in a file to supply to the connector's configuration. Assign the public key to the Snowflake service user: ```sql ALTER USER SET RSA_PUBLIC_KEY = 'thekey'; ``` For more information, see [pair of keys](/user-guide/key-pair-auth). 2. Snowflake strongly recommends this step. Configure a secrets manager supported by Openflow, for example, AWS, Azure, and Hashicorp, and store the public and private keys in the secret store. If for any reason, you do not wish to use a secrets manager, then you are responsible for safeguarding the public key and private key files used for key-pair authentication according to the security policies of your organization. 1. Once the secrets manager is configured, determine how you will authenticate to it. On AWS, it's recommended that you the EC2 instance role associated with Openflow as this way no other secrets have to be persisted. 2. In Openflow, configure a Parameter Provider associated with this Secrets Manager, from the hamburger menu in the upper right. Navigate to **Controller Settings** %raa% **Parameter Provider** and then fetch your parameter values. 3. At this point all credentials can be referenced with the associated parameter paths and no sensitive values need to be persisted within Openflow. 3. If any other Snowflake users require access to the raw ingested documents and tables ingested by the connector (for example, for custom processing in Snowflake), then grant those users the role created in step 1. 4. Designate a warehouse for the connector to use. Grant the USAGE privilege on the warehouse to the role created before. Start with the smallest warehouse size, then experiment with size depending on the number of tables being replicated, and the amount of data transferred. Large table numbers typically scale better with [multi-cluster warehouses](/user-guide/warehouses-multicluster), rather than larger warehouse sizes. ## Set up the connector As a data engineer, perform the following tasks to install and configure the connector: ### Install the connector To install the connector, do the following as a data engineer: 1. Navigate to the Openflow overview page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find the connector and select **Install**. 3. In the **Select runtime** dialog, select your runtime from the **Available runtimes** drop-down list and click **Install**. Before you install the connector, ensure that you have created a database and schema in Snowflake for the connector to store ingested data. 4. Authenticate to the deployment with your Snowflake account credentials and select **Allow** when prompted to allow the runtime application to access your Snowflake account. The connector installation process takes a few minutes to complete. 5. Authenticate to the runtime with your Snowflake account credentials. The Openflow canvas appears with the connector process group added to it. ### Configure the connector 1. Right-click on the imported process group and select **Parameters**. 2. Populate the required parameter values as described in [Flow parameters](#flow-parameters). ### Flow parameters This section describes the flow parameters that you can configure based on the following parameter contexts: - [Dataverse Source Parameters](#dataverse-source-parameters): Used to establish connection with Dataverse. - [Dataverse Destination Parameters](#dataverse-destination-parameters): Used to establish connection with Snowflake. - [Dataverse Ingestion Parameters](#dataverse-ingestion-parameters): Used to define the configuration of data downloaded from Dataverse. #### Dataverse Source Parameters
#### Dataverse Destination Parameters
#### Dataverse Ingestion Parameters
When configuring `Source Tables Filter Value`, use the **entity set name** (plural form, e.g., `annotations`) rather than the table name displayed in the Microsoft Dataverse interface. To find the entity set name for a table, go to Power Apps (https://make.powerapps.com), select **Tables**, find your table, then select **Advanced** %raa% **Tools** %raa% **Copy set name**. The `Column Filter JSON` parameter uses a different naming convention — it requires the **singular logical entity name** (e.g., `annotation`). See [Replicate a subset of columns in a table](#replicate-a-subset-of-columns-in-a-table) for details. ## Run the flow 1. Right-click on the plane and select **Enable all Controller Services**. 2. Right-click on the imported process group and select **Start**. The connector starts the data ingestion. ### Replicate a subset of columns in a table The connector can filter the data replicated per table to a subset of configured columns. To apply filters to columns, set the `Column Filter JSON` parameter in the Dataverse ingestion parameters to a JSON filter. Add an array of configurations, one entry for every table to which you want to apply a filter. The `table` field must use the **singular logical entity name** (e.g., `annotation`), not the plural entity set name used in `Source Tables Filter Value` (e.g., `annotations`). To find the logical entity name in Power Apps, go to Power Apps (https://make.powerapps.com), select **Tables**, find your table, then select **Advanced** %raa% **Tools** %raa% **Copy logical name**. Some columns have a binary representation stored under a `_binary`-suffixed column name (for example, a column `mycolumn` may also appear as `mycolumn_binary`). To fully exclude such a column, list both names in the `excluded` array. The following example excludes large binary columns from a table: ```javascript [ { "table": "mytable", "excluded": ["mycolumn", "mycolumn_binary"] } ] ``` Columns can be included or excluded by name or pattern. You can apply a single condition per table, or combine multiple conditions, with exclusions taking precedence over inclusions. The following example shows all available fields. The `table` field is mandatory. One or more of `included`, `excluded`, `includedPattern`, `excludedPattern` is required. ```javascript [ { "table" : "", "included": ["", ""], "excluded": ["", ""], "includedPattern": "", "excludedPattern": "", } ] ``` ### Include formatted values Microsoft Dataverse stores many columns as raw values, such as an option set integer, a lookup GUID, or an unformatted amount. For those columns, Dataverse can also return a display value, called a formatted value: the localized label of a choice, yes/no, status, or status reason column, the primary name of a lookup or owner column, and locale-formatted numbers, currencies, and dates. For details about which columns have formatted values, see Select columns using OData (https://learn.microsoft.com/en-us/power-apps/developer/data-platform/webapi/query/select-columns) in the Microsoft documentation. By default, the connector replicates raw values only. To also replicate formatted values, set the `Include Formatted Values` parameter in the Dataverse ingestion parameters to `true`, then restart the connector process group so that the change takes effect. Raw columns are unchanged when you enable this parameter. Instead, the connector adds a single `_DATAVERSE_FORMATTED_VALUES` column of type `OBJECT` to each replicated table. The keys of the object are source column names and the values are always strings: ```json { "statuscode": "Active", "annualincome": "$80,000.00", "_transactioncurrencyid_value": "US Dollar" } ``` Keep the following in mind when you query the column: - Lookup and owner columns keep the `__value` form that Dataverse uses, as shown by `_transactioncurrencyid_value` in the preceding example. - Columns that don't have a formatted value are absent from the object. If a row has no formatted values at all, `_DATAVERSE_FORMATTED_VALUES` is `NULL` for that row. - Rows that were deleted at the source don't carry formatted values. For more information about how deletes are replicated, see [](/user-guide/data-integration/openflow/connectors/dataverse/about#label-dataverse-connector-managed-columns). - If you enable the parameter for a connector that already replicated data, the column is populated from the next ingestion onwards. Rows that were replicated earlier keep `NULL` until they change at the source again. - If a source table already has a column named `_DATAVERSE_FORMATTED_VALUES`, ingestion of that table fails. To read a single formatted value, extract it by key and cast it: ```sql SELECT "statuscode", _DATAVERSE_FORMATTED_VALUES:statuscode::STRING AS statuscode_label FROM ..ACCOUNTS; ``` Dataverse column names are lowercase, so quote them in queries. The connector-managed columns are uppercase and don't need quoting. Formatted values are display strings that depend on the locale and configuration of your Dataverse environment, so they can change without the underlying data changing. Use the raw columns for joins, filters, and calculations, and use formatted values for presentation. ### Manage table state The connector maintains per-table ingestion state in the `Dataverse Table State Service` controller service. Each entry records the current ingestion status and the delta token used for change tracking. #### View connector state To view the current state of all tables: 1. Right-click on the canvas and select **Controller services**. 2. Locate the controller service named **Dataverse Table State Service**. 3. In the **Dataverse Table State Service** menu, click **View state**. The state is a set of key/value pairs where the key is the table entity set name (for example, `accounts`). The value has the format `;;;`, for example: ```text accounts -> DONE;!AAAAAjE...;; ``` The `STATUS` can be one of the following: - `FETCHING` — the connector is actively fetching records for this table. - `PROCESSING` — the table is queued for ingestion but not currently being fetched. - `DONE` — all available data was fetched successfully. The connector will check for new data on the next scheduled run according to the **Ingestion Schedule Interval** parameter. - `FAILED` — an unrecoverable error occurred. Review the connector logs for details. If the logs indicate a configuration issue or a [known limitation](/user-guide/data-integration/openflow/connectors/dataverse/about#limitations), resolve it and restart ingestion for the affected table. If no known cause is found, this may indicate a bug or an unsupported scenario; contact Snowflake Support. #### Restart ingestion for a single table Removing a table from the filter and re-adding it causes the connector to perform a full re-ingestion of that table. All currently available records are fetched again and merged into the destination table by primary key, so existing rows are updated in place rather than duplicated. However, the connector doesn't recover delete operations that occurred during downtime. To restart ingestion for a specific table: 1. Make sure the connector is running and open the connector process group. 2. Right-click on the canvas, select **Parameters** and remove the target table's entity set name from the **Source Tables Filter Value** parameter. 3. Stop the **List Dataverse Tables** processor and start it again to trigger removal of the table state. 4. Wait until the table's state has been removed: 1. Right-click on the canvas and select **Controller services**. 2. Locate the controller service named **Dataverse Table State Service** and select **View state** from its ellipsis menu. 3. Wait until the table's entity set name no longer appears in the list. 5. Stop the **List Dataverse Tables** processor and wait until all queues are empty. 6. (Optional) DROP the destination objects in Snowflake and let the connector recreate them. Since a full re-ingestion only upserts records that currently exist at the source, rows deleted at the source during downtime are not removed from the destination table automatically. After you delete the destination table and re-ingest it, the table includes only records that are still present in the source. DROP the following objects, where `` is the table's entity set name in uppercase: - Destination table: `..` - Journal table: `..__JOURNAL` - Journal stream: `..__JOURNAL_STREAM` ```sql DROP STREAM IF EXISTS ..__JOURNAL_STREAM; DROP TABLE IF EXISTS ..__JOURNAL; DROP TABLE IF EXISTS ..; ``` 7. Re-add the table's entity set name to **Source Tables Filter Value** and start the **List Dataverse Tables** processor again. 8. Verify that an entry for the table is present in **Dataverse Table State Service** state again. To restart ingestion for all replicated tables, repeat this procedure for each table, or remove all entity set names from the **Source Tables Filter Value** parameter and then re-add them. Do not delete FlowFiles manually while the connector is running. Doing so can leave a table in the `FETCHING` status indefinitely. If this occurs, restart ingestion for that table as described above. --- title: Set up the Openflow Connector for MongoDB source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/mongodb/setup.md section: Loading & Unloading Data --- # Set up the %mongodbof% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About the Openflow Connector for MongoDB](/user-guide/data-integration/openflow/connectors/mongodb/about) - [Connect to MongoDB](/user-guide/data-integration/openflow/connectors/mongodb/connect) - [Use the Openflow Connector for MongoDB](/user-guide/data-integration/openflow/connectors/mongodb/use) This topic describes the steps to set up the %mongodbof%. ## Configure the connector To configure the connector, perform the following steps: 1. Right-click on the added runtime, and select **Parameters**. 2. Populate the required parameter values as described in [](#label-specify-mongo-connector-flow-parameters). ### Specify flow parameters These sections describe the flow parameters that you can configure in the following parameter contexts: - [](#label-mongodb-source-parameters): Used to define the configuration for reading data from MongoDB. - [](#label-mongodb-destination-parameters): Used to establish a connection with Snowflake. - [](#label-mongodb-ingestion-parameters): Used to specify the collections to replicate. ### MongoDB source parameters
### MongoDB destination parameters
### MongoDB ingestion parameters
## Run the flow 1. Right-click on the plane and select **Enable all Controller Services**. 2. Right-click on the imported process group and select **Start**. The connector starts the data ingestion. ## Next steps For information about using the connector after installation, see [Use the %mongodbof%](/user-guide/data-integration/openflow/connectors/mongodb/use). --- title: Set up the Openflow Connector for MySQL source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/mysql/setup.md section: Loading & Unloading Data --- # Set up the %mysql% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Incremental replication](/user-guide/data-integration/openflow/connectors/mysql/incremental-replication) - [About Openflow Connector for MySQL](/user-guide/data-integration/openflow/connectors/mysql/about) - [Openflow Connector for MySQL: Data mapping](/user-guide/data-integration/openflow/connectors/mysql/data-mapping) This topic describes the steps to set up the %mysql%. ## Prerequisites ### Before you begin 1. Ensure that you have reviewed [About Openflow Connector for MySQL](/user-guide/data-integration/openflow/connectors/mysql/about). 2. Ensure that you have MySQL 8 or later to synchronize data with Snowflake. 3. Make sure you have an Openflow deployment and runtime for this connector. If you don't, see [Set up Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/setup-openflow-spcs) or [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc). A runtime's size is fixed when you create it, so decide on a size before you create the runtime. See [Runtime sizing and packing for CDC connectors](/user-guide/data-integration/openflow/connectors/cdc-runtime-sizing). 4. If using Snowflake deployments, ensure that you've reviewed [configuring required domains](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list) and have granted access to the required domains for the [](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list#label-openflow-domains-used-by-openflow-connectors-mysql) connector. ### Source database setup As a database administrator, perform the following tasks: 1. Enable binary logs (https://dev.mysql.com/doc/refman/8.4/en/binary-log.html), then save and configure its format as follows:
For example: ```sql log_bin = on binlog_format = row binlog_row_metadata = full binlog_row_image = full binlog_row_value_options = ``` 2. Increase the value of `sort_buffer_size`. ```sql sort_buffer_size = 4194304 ``` `sort_buffer_size` defines the amount of memory (in bytes) allocated per query thread for in-memory sorting operations, such as ORDER BY. If the value is too small, the connector may fail with the following error message: `Out of sort memory, consider increasing server sort buffer size`. This indicates that `sort_buffer_size` should be raised. 3. If you're using Amazon RDS databases, then increase the retention period relevant to *binlog_expire_logs_seconds* using *rds_set_configuration*. For example, if you want to store binlog for 24 hours, then call `mysql.rds_set_configuration('binlog retention hours', 24)`. 4. When using a read replica to connect, binary logging must be enabled on the replica. 5. After binary logging is enabled, configure the replica to log the events received from its source into its own binary log. ```sql log_replica_updates = ON ``` `log_replica_updates` allows the replica to write events received from its source to its own binary log, making those changes available to any databases that are replicating from it. 6. Connect via SSL. If you're planning to use an SSL connection to MySQL, prepare the root certificate for your database server. It is required during configuration. 7. Create a user for the connector. The connector requires a user with the REPLICATION SLAVE and REPLICATION CLIENT privileges for reading the binary logs. Grant these privileges: ```sql GRANT REPLICATION SLAVE ON *.* TO ''@'%' GRANT REPLICATION CLIENT ON *.* TO ''@'%' ``` 8. Grant the SELECT privilege on every replicated table: ```sql GRANT SELECT ON .* TO ''@'%' GRANT SELECT ON .
SQL Server type Snowflake (Standard) Iceberg v3 Iceberg v2
TINYINT / SMALLINT / INT INT `long` `long`
BIGINT INT `long` `long`
BIT BOOLEAN `boolean` `boolean`
DECIMAL(P,S) / NUMERIC(P,S) NUMBER(P,S) `decimal(P,S)` `decimal(P,S)`
MONEY NUMBER(19,4) `decimal(19,4)` `decimal(19,4)`
SMALLMONEY NUMBER(10,4) `decimal(10,4)` `decimal(10,4)`
FLOAT / FLOAT(53) FLOAT `double` `double`
REAL / FLOAT(n) (n ≤ 24) FLOAT `double` `double`
DATE DATE `date` `date`
TIME(0..6) TIME `time` `time`
TIME(7) TIME `time` (100ns truncated) `time` (100ns truncated)
SMALLDATETIME TIMESTAMP_NTZ `timestamp` `timestamp`
DATETIME TIMESTAMP_NTZ `timestamp` `timestamp`
DATETIME2(0..6) TIMESTAMP_NTZ `timestamp` `timestamp`
DATETIME2(7) TIMESTAMP_NTZ `timestamp_ns` `timestamp` (100ns truncated)
DATETIMEOFFSET(0..6) TIMESTAMP_TZ `timestamptz` `timestamptz`
DATETIMEOFFSET(7) TIMESTAMP_TZ `timestamptz_ns` `timestamptz` (100ns truncated)
CHAR / VARCHAR / NCHAR / NVARCHAR / TEXT / NTEXT TEXT `string` `string`
BINARY / VARBINARY / IMAGE BINARY `binary` `binary`
XML TEXT `string` `string`
JSON (SQL Server 2025) VARIANT `variant` `string`
UNIQUEIDENTIFIER TEXT `string` `string`
ROWVERSION TEXT `string` `string`
SQL_VARIANT TEXT `string` `string`
GEOMETRY / GEOGRAPHY TEXT `string` `string`
Parameter Description
Starting Change Tracking Position - `Latest` (default): change tracking table reading starts at the latest available position and continues from there. - `Earliest`: Switches the incremental load to start, or restart reading from the earliest available change tracking table positions.
Re-read Tables in State - `New` (default): Only new tables, added after the starting position was switched to `Earliest`, will have their change tracking tables read from the earliest available positions. Tables that started replication before the configuration change will continue reading from their last positions. - `Any active`: Re-read and re-process changes from any table currently in replication.
Connector Description
[Openflow Connector for Amazon Ads](/user-guide/data-integration/openflow/connectors/amazon-ads/about) Bring data from Amazon Ads for Ad performance statistics and insights
[Openflow Connector for Box](/user-guide/data-integration/openflow/connectors/box/about) Ingest Box content for your own custom processing in Snowflake Ingest Box content and make it ready for chat in your AI assistants with Snowflake Cortex Use Box AI to extract metadata from Box content for enrichment in Snowflake Add enriched metadata from Snowflake to content in Box
[Openflow Connector for Google Ads](/user-guide/data-integration/openflow/connectors/google-ads/about) Import metrics from Google Ads for performance tracking and optimization
[Openflow Connector for Google BigQuery](/user-guide/data-integration/openflow/connectors/google-big-query/about) Replicate datasets and tables from Google BigQuery into Snowflake with incremental change capture
[Openflow Connector for Google Drive](/user-guide/data-integration/openflow/connectors/google-drive/about) Ingest Google Drive content and make it ready for chat in your AI assistants with Snowflake Cortex Ingest Google Drive content for your own custom processing in Snowflake
[Openflow Connector for Google Sheets](/user-guide/data-integration/openflow/connectors/google-sheets/about) Load data from Google sheets into Snowflake tables for reporting, analytics, and insights
[Openflow Connector for HubSpot](/user-guide/data-integration/openflow/connectors/hubspot/about) Get HubSpot CRM data into Snowflake for reporting, analytics, and insights
[Openflow Connector for Jira Cloud](/user-guide/data-integration/openflow/connectors/jira-cloud/about) Ingest Jira issues, projects, comments, changelogs, worklogs, users, and agile boards into Snowflake for cross‐team visibility and deeper insights
[Openflow Connector for Kafka](/user-guide/data-integration/openflow/connectors/kafka/about) Ingest real‐time events from Apache Kafka into Snowflake for near real-time analytics
[Openflow Connector for Kinesis Data Streams](/user-guide/data-integration/openflow/connectors/kinesis/about) Ingest real‐time events from Amazon Kinesis Data Streams into Snowflake for near real-time analytics
[Openflow Connector for LinkedIn Ads](/user-guide/data-integration/openflow/connectors/linkedin-ads/about) Import campaign performance data from LinkedIn Ads to Snowflake for reporting, analytics, and insights
[Openflow Connector for Meta Ads](/user-guide/data-integration/openflow/connectors/meta-ads/about) Bring Meta (Facebook) Ads data to unify and analyze your marketing performance
[Openflow Connector for Microsoft Dataverse](/user-guide/data-integration/openflow/connectors/dataverse/about) Integrate data from Microsoft Power Platform and Dynamics 365 applications with Snowflake for holistic business insights
[Openflow Connector for MongoDB](/user-guide/data-integration/openflow/connectors/mongodb/about) CDC replication of MongoDB collections into Snowflake for comprehensive, centralized reporting
[Openflow Connector for MySQL](/user-guide/data-integration/openflow/connectors/mysql/about) CDC replication of MySQL tables into Snowflake for comprehensive, centralized reporting
[Openflow Connector for Oracle](/user-guide/data-integration/openflow/connectors/oracle/about) CDC replication of Oracle database tables into Snowflake for comprehensive, centralized reporting
[Openflow Connector for PostgreSQL](/user-guide/data-integration/openflow/connectors/postgres/about) CDC replication of PostgreSQL data with Snowflake for comprehensive, centralized reporting
[Openflow Connector for Salesforce Bulk API](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/about) Ingests Salesforce objects into Snowflake, with support for incremental change detection
[Openflow Connector for SharePoint](/user-guide/data-integration/openflow/connectors/sharepoint/about) Ingest SharePoint content and make it ready for chat in your AI assistants with Snowflake Cortex Ingest SharePoint content for your own custom processing in Snowflake
[Openflow Connector for Shopify](/user-guide/data-integration/openflow/connectors/shopify/about) Replicate Shopify store data into Snowflake using the Admin GraphQL API for e-commerce analytics and reporting
[Openflow Connector for Slack](/user-guide/data-integration/openflow/connectors/slack/about) Pull Slack messages and metadata into Snowflake for searchable, organization‐wide insights
[Openflow Connector for Snowflake to Kafka](/user-guide/data-integration/openflow/connectors/snowflake-to-kafka/about) CDC replication of Snowflake tables into Apache Kafka for real-time insights distribution and event-driven architectures
[Openflow Connector for SQL Server (CT)](/user-guide/data-integration/openflow/connectors/sql-server/about) Change tracking replication of Microsoft SQL Server data with Snowflake for comprehensive, centralized reporting
[Openflow Connector for SQL Server (CDC)](/user-guide/data-integration/openflow/connectors/sql-server-cdc/about) Capture every row-level change from Microsoft SQL Server using Change Data Capture for data synchronization and audit or history use cases
[Openflow Connector for Veeva Vault](/user-guide/data-integration/openflow/connectors/veeva-vault/about) Replicate Veeva Vault data into Snowflake using Direct Data archives for analytics and reporting
[Openflow Connector for Workday](/user-guide/data-integration/openflow/connectors/workday/about) Get Workday data into Snowflake using Report-as-a-Service (RaaS) streams for enterprise-level analytics and planning
SQL Server type Snowflake type Notes
TINYINT INT
SMALLINT INT
INT INT
BIGINT INT
DECIMAL NUMBER If precision exceeds Snowflake limitations (precision > 38), the value is stored as TEXT.
NUMERIC NUMBER If precision exceeds Snowflake limitations (precision > 38), the value is stored as TEXT.
SMALLMONEY NUMBER
MONEY NUMBER
REAL FLOAT
FLOAT FLOAT
BIT BOOLEAN
CHAR TEXT
VARCHAR TEXT Supported by default up to 16 MB.
NCHAR TEXT
NVARCHAR TEXT Supported by default up to 16 MB.
TEXT TEXT Supported by default up to 16 MB.
NTEXT TEXT Supported by default up to 16 MB.
DATE DATE
TIME TIME
SMALLDATETIME TIMESTAMP_NTZ
DATETIME TIMESTAMP_NTZ
DATETIME2 TIMESTAMP_NTZ
DATETIMEOFFSET TIMESTAMP_TZ
BINARY BINARY
VARBINARY BINARY Supported by default up to 8 MB.
IMAGE BINARY Supported by default up to 8 MB.
JSON VARIANT Supported by default up to 16 MB.
VECTOR VARIANT Supported by default up to 16 MB.
XML TEXT Supported by default up to 16 MB.
UNIQUEIDENTIFIER TEXT
ROWVERSION / TIMESTAMP TEXT
SQL_VARIANT TEXT
GEOGRAPHY TEXT Values of this type are inserted as NULL.
GEOMETRY TEXT Values of this type are inserted as NULL.
gen 1 gen 2
**Creation** `CREATE OPENFLOW DATA PLANE INTEGRATION` (UI or SQL) `CREATE OPENFLOW DEPLOYMENT` (UI or SQL)
**Required privilege** `CREATE OPENFLOW DATA PLANE INTEGRATION` on the account `CREATE OPENFLOW DEPLOYMENT` on the account
**Documentation** [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc), [Set up Openflow - Snowflake Deployment - Task overview](/user-guide/data-integration/openflow/setup-openflow-spcs) [Quickstart: gen 2 Openflow](/user-guide/data-integration/openflow/gen2/quickstart), [Second generation Openflow objects and interfaces](/user-guide/data-integration/openflow/gen2/index)
**Event table** Set on the data plane integration (`ALTER OPENFLOW DATA PLANE INTEGRATION ... SET EVENT_TABLE`). Value stored on the integration at creation. View with `DESCRIBE OPENFLOW DATA PLANE INTEGRATION`. [](/user-guide/data-integration/openflow/setup-openflow-spcs-deployment#label-openflow-spcs-event-table) Optional `EVENT_TABLE` on the deployment object. When unset, inherits the account-level event table. View with `SHOW PARAMETERS LIKE 'EVENT_TABLE' IN OPENFLOW DEPLOYMENT `. [CREATE OPENFLOW DEPLOYMENT](/sql-reference/sql/create-openflow-deployment)
**Available after gen 2 enablement** Existing gen 1 deployments continue to work unchanged, but you can't create new gen 1 deployments once your account is enabled for gen 2. All new deployments must be gen 2. Once your account is enabled for gen 2, `CREATE OPENFLOW DEPLOYMENT` is the only command available for new deployments.
gen 1 gen 2
**Creation** `CREATE OPENFLOW RUNTIME INTEGRATION` (UI or SQL) `CREATE OPENFLOW RUNTIME ... IN DEPLOYMENT ...` (UI or SQL)
**Account- or schema-level object** Account-level `OPENFLOW RUNTIME INTEGRATION` object Schema-level object; fully qualified name `..`. Read and write access during connector execution is dictated by the runtime's `EXECUTE_AS_ROLE`, not by the schema where the runtime object lives.
**Required privilege** `CREATE OPENFLOW RUNTIME INTEGRATION` on the account `CREATE OPENFLOW RUNTIME` on the target schema, `USAGE` on the containing database, and `USAGE` on the deployment (schema owners can create without the explicit `CREATE OPENFLOW RUNTIME` grant)
**Runtime object privileges** `USAGE`, `OPERATE`, or `MONITOR` on the `OPENFLOW RUNTIME INTEGRATION` object `USAGE`, `OPERATE`, or `MONITOR` on the runtime, and `USAGE` on its database and schema
**Deletion** Suspend, then delete from the UI (see [Runtime deletion workflow](#label-openflow-generations-runtime-deletion)) **UI:** **Suspend** → **Delete** → **Drop** from the runtime menu on the **Runtimes** tab (see [Runtime deletion workflow](#label-openflow-generations-runtime-deletion)). **SQL:** `ALTER OPENFLOW RUNTIME ... SUSPEND` → `TERMINATE` → `DROP`
**Documentation** [Set up Openflow - Snowflake Deployment: Create runtime](/user-guide/data-integration/openflow/setup-openflow-spcs-create-runtime), [Manage Openflow](/user-guide/data-integration/openflow/manage) [Quickstart: gen 2 Openflow](/user-guide/data-integration/openflow/gen2/quickstart), [Second generation Openflow objects and interfaces](/user-guide/data-integration/openflow/gen2/index)
**Generation** Determined by the parent deployment. All runtimes added to a gen 1 deployment are gen 1. Determined by the parent deployment. All runtimes added to a gen 2 deployment are gen 2.
gen 1 gen 2
**Creation** Install from connector catalog with **Install** (Openflow UI), or import from the registry on the runtime canvas (see [Coexistence](#label-openflow-generations-coexistence)) **Openflow UI:** install from connector catalog (**gen 2** entries; setup wizard). **SQL:** `CREATE OPENFLOW CONNECTOR ... FROM DEFINITION` (see [Quickstart: gen 2 Openflow](/user-guide/data-integration/openflow/gen2/quickstart), [Configure a gen 2 connector with SQL](/user-guide/data-integration/openflow/gen2/configure-connector-sql)). To reuse a validated configuration, see [Create from a known configuration](#label-openflow-fbe-git-create) in [gen 2 connector configuration and versioning](/user-guide/data-integration/openflow/gen2/connector-versioning).
**Object type** NiFi process group on the runtime canvas (not a separate Snowflake object) Schema-level `OPENFLOW CONNECTOR` [File Based Entity (FBE)](/user-guide/data-integration/openflow/gen2/connector-versioning) with versioned stage configuration
**Configuration** Runtime canvas: parameter contexts, controller services, processors Setup wizard, **Installed Connectors** %raa% **Edit**, or SQL/stage commands (`PUT`/`COMMIT` on the connector's live version). See [gen 2 connector configuration and versioning](/user-guide/data-integration/openflow/gen2/connector-versioning).
**Canvas** Full read/write configuration surface Read-only for gen 2 connectors; use **Installed Connectors** %raa% **Edit** or SQL/API for configuration changes
**Lifecycle** Start/stop processors on the canvas; remove via canvas and UI steps documented per connector **UI:** **Start** / **Stop** from **Installed Connectors**; remove with **Stop** → **Delete** → **Drop** (see [Manage the gen 2 Openflow connector lifecycle](/user-guide/data-integration/openflow/gen2/manage-connector-lifecycle)). **SQL:** `ALTER OPENFLOW CONNECTOR ... START|STOP|TERMINATE`; `DROP` after terminate.
**Documentation** [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) and connector-specific setup topics [Configure a connector with the setup wizard](/user-guide/data-integration/openflow/gen2/setup-connector-wizard), [Manage the gen 2 Openflow connector lifecycle](/user-guide/data-integration/openflow/gen2/manage-connector-lifecycle), [gen 2 connector configuration and versioning](/user-guide/data-integration/openflow/gen2/connector-versioning)
You want to… Follow…
Understand gen 1 vs gen 2 (this page) [Openflow gen 1 and gen 2](/user-guide/data-integration/openflow/gen2/openflow-generations)
Get started with gen 2 (privileges, first gen 2 resources) [Second generation Openflow objects and interfaces](/user-guide/data-integration/openflow/gen2/index), [Quickstart: gen 2 Openflow](/user-guide/data-integration/openflow/gen2/quickstart)
Create or manage a **gen 1** deployment or runtime Public Openflow setup and [Manage Openflow](/user-guide/data-integration/openflow/manage) topics
Install a **gen 1** catalog connector (**Install** or **Import from Registry** on the canvas) [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) and the connector's setup topic
Install a **gen 2** connector with the setup wizard [Configure a connector with the setup wizard](/user-guide/data-integration/openflow/gen2/setup-connector-wizard)
Configure a **gen 2** connector with SQL [Configure a gen 2 connector with SQL](/user-guide/data-integration/openflow/gen2/configure-connector-sql)
Start, stop, or remove a **gen 2** connector [Manage the gen 2 Openflow connector lifecycle](/user-guide/data-integration/openflow/gen2/manage-connector-lifecycle)
Manage gen 2 connector configuration versions (draft, commit, abort) [gen 2 connector configuration and versioning](/user-guide/data-integration/openflow/gen2/connector-versioning)
SQL reference for gen 2 deployments, runtimes, and connectors [Second generation Openflow SQL command reference](/sql-reference/commands-openflow-gen2)
Prepare a data source (for example, PostgreSQL CDC) The connector's public setup topic; return to gen 2 docs for connector creation
Runtime Activity Snowflake costs Cloud costs
No runtimes None Openflow Control Pool x 1 node = 1 CPU_X64_S instance-hour None
1 small runtime (1 vCPU) (min=1 max=2) Active for 1 hour. Runtime does not scale to 2. Openflow Control Pool x 1 node + Small Openflow Compute Pool (CPU_X64_S) x 1 node = 2 CPU_X64_S instance-hours None
2 small runtimes (1 vCPU) (min/max=2), 1 large runtime (8 vCPU) (min/max=10) Small: 4 nodes active for 1 hour Large: 10 nodes active for 1 hour Openflow Control Pool x 1 node + Small Openflow Compute Pool (CPU_X64_S) x 2 nodes + Large Openflow Compute Pool (CPU_X64_L) x 4 nodes = 3 CPU_X64_S instance-hours + 4 CPU_X64_L instance-hours None
1 medium (4 vCPU) (min=1 max=2) First 20 minutes 1 node is running After 20 minutes, scales to 2 nodes After 40 minutes, scales back to 1 node Total 1 hour Openflow Control Pool x 1 node + Medium Openflow Compute Pool (CPU_X64_SL) x 1 node = 1 CPU_X64_S instance-hour + 1 CPU_X64_SL instance-hour None
1 medium (4 vCPU) (min/max=2) First 30 minutes 2 nodes running Suspends after the first 30 minutes Openflow Control Pool x 1 node + Medium Openflow Compute Pool (CPU_X64_SL) x 1 node x 1/2 hour = 1 CPU_X64_S instance-hour + 1/2 CPU_X64_SL instance-hour None
Property Description
Maximum Batch Content Size Maximum combined content size of FlowFiles to package into one output FlowFile. Note, that FlowFiles whose content exceeds this limit are packaged separately.
max-batch-size Maximum number of FlowFiles to package into one output FlowFile.
Name Description
original The FlowFiles that were used to create the package are sent to this relationship
success The packaged FlowFile is sent to this relationship
Name Description
mime.type The mime.type will be changed to application/flowfile-v3
Property Description
Aggregation Results Format Format of Aggregation output.
Aggregation Results Split Output a flowfile containing all aggregations or one flowfile for each individual aggregation.
Aggregations One or more query aggregations (or "aggs"), in JSON syntax. Ex: \{"items": \{"terms": \{"field": "product", "size": 10\}\}\}
Client Service An Elasticsearch client service to use for running queries.
Fields Fields of indexed documents to be retrieved, in JSON syntax. Ex: ["user.id", "http.response.*", \{"field": "@timestamp", "format": "epoch_millis"\}]
Index The name of the index to use.
Max JSON Field String Length The maximum allowed length of a string value when parsing a JSON document or attribute.
Output No Hits Output a "hits" flowfile even if no hits found for query. If true, an empty "hits" flowfile will be output even if "aggregations" are output.
Pagination Keep Alive Pagination "keep_alive" period. Period Elasticsearch will keep the scroll/pit cursor alive in between requests (this is not the time expected for all pages to be returned, but the maximum allowed time for requests between page retrievals).
Pagination Type Pagination method to use. Not all types are available for all Elasticsearch versions, check the Elasticsearch docs to confirm which are applicable and recommended for your service.
Query A query in JSON syntax, not Lucene syntax. Ex: \{"query":\{"match":\{"somefield":"somevalue"\}\}\}. If this parameter is not set, the query will be read from the flowfile content. If the query (property and flowfile content) is empty, a default empty JSON Object will be used, which will result in a "match_all" query in Elasticsearch.
Query Attribute If set, the executed query will be set on each result flowfile in the specified attribute.
Query Clause A "query" clause in JSON syntax, not Lucene syntax. Ex: \{"match":\{"somefield":"somevalue"\}\}. If the query is empty, a default JSON Object will be used, which will result in a "match_all" query in Elasticsearch.
Query Definition Style How the JSON Query will be defined for use by the processor.
Script Fields Fields to created using script evaluation at query runtime, in JSON syntax. Ex: \{"test1": \{"script": \{"lang": "painless", "source": "doc[ 'price'].value * 2"\}\}, "test2": \{"script": \{"lang": "painless", "source": "doc[ 'price'].value * params.factor", "params": \{"factor": 2.0\}\}\}\}
Search Results Format Format of Hits output.
Search Results Split Output a flowfile containing all hits or one flowfile for each individual hit or one flowfile containing all hits from all paged responses.
Size The maximum number of documents to retrieve in the query. If the query is paginated, this "size" applies to each page of the query, not the "size" of the entire result set.
Sort Sort results by one or more fields, in JSON syntax. Ex: [\{"price" : \{"order" : "asc", "mode" : "avg"\}\}, \{"post_date" : \{"format": "strict_date_optional_time_nanos"\}\}]
Type The type of this document (used by Elasticsearch for indexing and searching).
Name Description
aggregations Aggregations are routed to this relationship.
failure All flowfiles that fail for reasons unrelated to server availability go to this relationship.
hits Search hits are routed to this relationship.
original All original flowfiles that don't cause an error to occur go to this relationship.
Name Description
mime.type application/json
aggregation.name The name of the aggregation whose results are in the output flowfile
aggregation.number The number of the aggregation whose results are in the output flowfile
page.number The number of the page (request), starting from 1, in which the results were returned that are in the output flowfile
hit.count The number of hits that are in the output flowfile
elasticsearch.query.error The error message provided by Elasticsearch if there is an error querying the index.
Display Name API Name Default Value Allowable Values Description
Write Target File Size * Write Target File Size 512 MB Controls the size of files generated to target about this many bytes
Property Description
Granularity Output flow file for each Record, Chunk, or File encountered in the event log
Name Description
bad chunk Any bad chunks of records will be transferred to this relationship in their original binary form
failure Any FlowFile that encountered an exception during conversion will be transferred to this relationship with as much parsing as possible done
original The unmodified input FlowFile will be transferred to this relationship
success Any FlowFile that was successfully converted from evtx to XML
Name Description
filename The output filename
mime.type The output filetype (application/xml for success and failure relationships, original value for bad chunk and original relationships)
Property Description
Ranges The comma-separated Excel ranges to parse in the A1 notation. For example: Sheet1!A1:B2,Sheet2!D4:E5,Sheet3. Ranges in R1C1 and 3-D reference style are not allowed. The value can't be empty.
Name Description
failure FlowFile with errors occurred while parsing ranges.
success FlowFile annotated with attributes containing parsed Excel range. For each range a separate FlowFile is produced.
Name Description
range.formula Single range formula that was used to produce other attributes, e.g. Sheet1!A1:B2.
range.sheetname Parsed sheet name.
range.rows.starting Starting row (numbered from 1) of parsed range.
range.rows.ending Ending row of parsed range.
range.columns.starting Number of starting column of parsed range.
range.columns.ending Number of ending column of parsed range.
Property Description
Character Set Specifies which character set of the Syslog messages
Name Description
failure Any FlowFile that could not be parsed as a Syslog message will be transferred to this Relationship without any attributes being added
success Any FlowFile that is successfully parsed as a Syslog message will be to this Relationship.
Name Description
syslog.priority The priority of the Syslog message.
syslog.severity The severity of the Syslog message derived from the priority.
syslog.facility The facility of the Syslog message derived from the priority.
syslog.version The optional version from the Syslog message.
syslog.timestamp The timestamp of the Syslog message.
syslog.hostname The hostname or IP address of the Syslog message.
syslog.sender The hostname of the Syslog server that sent the message.
syslog.body The body of the Syslog message, everything after the hostname.
Property Description
Character Set Specifies which character set of the Syslog messages
include_policy If true, then the Syslog Message body will be included in the attributes.
nil_policy Defines how NIL values are handled for header fields.
Name Description
failure Any FlowFile that could not be parsed as a Syslog message will be transferred to this Relationship without any attributes being added
success Any FlowFile that is successfully parsed as a Syslog message will be to this Relationship.
Name Description
syslog.priority The priority of the Syslog message.
syslog.severity The severity of the Syslog message derived from the priority.
syslog.facility The facility of the Syslog message derived from the priority.
syslog.version The optional version from the Syslog message.
syslog.timestamp The timestamp of the Syslog message.
syslog.hostname The hostname or IP address of the Syslog message.
syslog.appname The appname of the Syslog message.
syslog.procid The procid of the Syslog message.
syslog.messageid The messageid the Syslog message.
syslog.structuredData Multiple entries per structuredData of the Syslog message.
syslog.sender The hostname of the Syslog server that sent the message.
syslog.body The body of the Syslog message, everything after the hostname.
Property Description
record-reader Specifies the Controller Service to use for reading incoming data
record-writer Specifies the Controller Service to use for writing out the records
Name Description
failure If a FlowFile cannot be partitioned from the configured input format to the configured output format, the unchanged FlowFile will be routed to this relationship
original Once all records in an incoming FlowFile have been partitioned, the original FlowFile is routed to this relationship.
success FlowFiles that are successfully partitioned will be routed to this relationship
Name Description
record.count The number of records in an outgoing FlowFile
mime.type The MIME Type that the configured Record Writer indicates is appropriate
fragment.identifier All partitioned FlowFiles produced from the same parent FlowFile will have the same randomly generated UUID added for this attribute
fragment.index A one-up number that indicates the ordering of the partitioned FlowFiles that were created from a single parent FlowFile
fragment.count The number of partitioned FlowFiles generated from the parent FlowFile
segment.original.filename The filename of the parent FlowFile
<dynamic property name> For each dynamic property that is added, an attribute may be added to the FlowFile. See the description for Dynamic Properties for more information.
Display Name API Name Default Value Allowable Values Description
Certificate Authorities * Certificate Authorities PEM X.509 Certificate Authorities trusted for verifying peers in TLS communications containing one or more standard certificates
Certificate Authorities Source * Certificate Authorities Source PROPERTIES - Properties - System Source of information for loading trusted Certificate Authorities
Certificate Chain * Certificate Chain PEM X.509 Certificate Chain associated with Private Key starting with standard BEGIN CERTIFICATE header
Certificate Chain Location * Certificate Chain Location PEM X.509 Certificate Chain file location associated with Private Key starting with standard BEGIN CERTIFICATE header
Private Key * Private Key PEM Private Key encoded using either PKCS1 or PKCS8. Supported algorithms include ECDSA, Ed25519, and RSA
Private Key Location * Private Key Location PEM Private Key file location encoded using either PKCS1 or PKCS8. Supported algorithms include ECDSA, Ed25519, and RSA
Private Key Source * Private Key Source PROPERTIES - Undefined - Properties - Files Source of information for loading Private Key and Certificate Chain
TLS Protocol * TLS Protocol TLS - TLS - TLSv1.3 - TLSv1.2 TLS protocol version required for negotiating encrypted communications.
Node Size Recommended For Message Rate Capacity
Small (S) Low to moderate throughput scenarios Up to 27 MB/s per node
Medium (M) Moderate to high throughput scenarios Up to 135 MB/s per node
Large (L) High throughput scenarios Exceeding 135 MB/s per node. Up to 310 MB/s per node.
Average record size Approximate calculation Max Records Per Request
1 KB 1 MB / 1 KB 1000
200 bytes 1 MB / 200 bytes 5000
5 KB 1 MB / 5 KB 200
Node Size ConsumeKinesis Tasks PublishSnowpipeStreaming Tasks
Small (S) 2 1
Medium (M) 4 2
Large (L) 6 3
Node Size Recommended For Message Rate Capacity
Small (S) Low to moderate throughput scenarios Up to 18 MB/s per node
Medium (M) Moderate to high throughput scenarios Up to 145 MB/s per node
Large (L) High throughput scenarios Up to 250 MB/s per node
Node Size ConsumeKafka Tasks PublishSnowpipeStreaming Tasks
Small (S) 1 1
Medium (M) 4 2
Large (L) 8 2
Property Description
Database The Snowflake database containing the stage
Filename The filename of the file to perform OCR on, it must be uploaded to the stage prior to performing OCR. FlowFile attributes may be referenced via Expression Language.
Max Attribute Size The maximum size of the OCR results that can be written to an attribute. If the OCR results exceed this, the FlowFile will be routed to failure.
OCR Mode Specifies how document text and structure should be extracted. In 'OCR' mode, only raw text content is extracted, ignoring formatting and table structures. In 'LAYOUT' mode, the output preserves table structures as markdown.
Output Strategy Determines response output destination
Results Attribute The name of the attribute to write the OCR response to.
Schema The Snowflake schema containing the stage
Snowflake Connection Service Database Connection Service for accessing Snowflake
Stage The Snowflake stage where PDFs will be temporarily stored. The stage must have server-side encryption enabled. FlowFile attributes may be referenced via Expression Language
Name Description
empty FlowFiles for which OCR results are empty
failure FlowFiles that cannot be processed are routed to this relationship
success FlowFiles that are successfully processed (with non-empty OCR results) are routed to this relationship
Name Description
mime.type The MIME type of the output content (text/plain when output strategy is FLOW_FILE)
snowflake.error.information Contains error information if Snowflake Cortex OCR operation returns an error
Property Description
Table State Service A service containing currently replicated tables and their states
Name Description
existing FlowFile with qualified table name that is already being replicated
failure If a FlowFile attribute cannot be read or is incorrect, it will be routed to this Relationship.
new FlowFile with qualified table name that was is not replicated
stale FlowFile with qualified table name that used to be replicated but no longer is, either because it was removed from source database or excluded by parameter
Name Description
source.schema.name Name of the schema of the table from which an event originated
source.table.name Name of the table from which an event originated
Display Name API Name Default Value Allowable Values Description
Access Token Scopes * Access Token Scopes catalog Comma-separated list of one or more OAuth 2 scopes requested for Access Tokens
Authentication Strategy * Authentication Strategy OAUTH2 - Bearer Authentication - OAuth 2.0 Strategy for authenticating with the Apache Iceberg Catalog over HTTP
Authorization Grant Type * Authorization Grant Type CLIENT_CREDENTIALS - Client Credentials OAuth 2.0 Authorization Grant Type for obtaining Access Tokens
Authorization Server URI * Authorization Server URI Authorization Server URI supporting OAuth 2
Bearer Token * Bearer Token Bearer Token for authentication to Apache Iceberg Catalog
Catalog URI * Catalog URI Apache Iceberg Catalog REST URI
Client ID * Client ID Client ID for OAuth 2 Client Credentials
Client Secret * Client Secret Client Secret for OAuth 2 Client Credentials
Warehouse Location Warehouse Location Apache Iceberg Catalog Warehouse location or identifier
Property Description
Anthropic API Key The API Key for authenticating to Anthropic
Assistant Message The assistant message to send to Anthropic. FlowFile attributes may be referenced via Expression Language, and the contents of the FlowFile may be referenced via the flowfile_content variable. E.g., $\{flowfile_content\}. The assistant message is added last
Image MIME Type The MIME type of the image in the FlowFile content. Supported types are image/jpeg, image/png, image/gif, and image/webp.
Max File Size The maximum size of a FlowFile that can be sent to Anthropic as an image. If the FlowFile is larger than this, it will be routed to 'failure'.
Max Tokens The maximum number of tokens to generate
Model Name The name of the Anthropic model
Output Strategy Determines response output destination
Prompt Type The type of prompt to send to Anthropic. TEXT to send a simple prompt. IMAGE to send an image first and then a prompt. Use JSON for advanced use of Anthropic's /v1/messages endpoint.
Response Format The format of the response from Anthropic
Results Attribute The name of the attribute to write the response to.
Stop Sequences A comma delimited list of strings act as stop sequences. The model will halt after encountering one of the stop sequences.
System Message The system message to send to Anthropic. FlowFile attributes may be referenced via Expression Language, and the contents of the FlowFile may be referenced via the flowfile_content variable. E.g., $\{flowfile_content\}
Temperature The temperature to use for generating the response. Defaults to 1.0. Ranges from 0.0 to 1.0. Use temperature closer to 0.0 for analytical / multiple choice, and closer to 1.0 for creative and generative tasks.
Top K The top K value to use for generating the response. Only sample from the top K options for each subsequent token. Recommended for advanced use cases only. You usually only need to use temperature.
Top P The top P value to use for generating the response. Top P is for nucleus sampling, we compute the cumulative distribution over all the options for each subsequent token in decreasing probability order and cut it off once it reaches a particular probability specified by top_p. Recommended for advanced use cases only. You usually only need to use temperature.
User ID The user id to set in the request metadata
User Message The user message to send to Anthropic. FlowFile attributes may be referenced via Expression Language, and the contents of the FlowFile may be referenced via the flowfile_content variable. E.g., $\{flowfile_content\}. The user message is added first, unless an image is present.
Web Client Service The Web Client Service to use for communicating with Anthropic
Name Description
failure If unable to obtain a valid response from Anthropic, the original FlowFile will be routed to this relationship
retry If a 5XX response from Anthropic is returned, the original FlowFile will be routed to this relationship
success The response from Anthropic is routed to this relationship
Name Description
anthropic.usage.inputTokens The number of input tokens read in the request.
anthropic.usage.outputTokens The number of output tokens generated in the response.
anthropic.chat.completion.id A unique id assigned to the conversation
anthropic.chat.completion.stop.reason The reason that we stopped.
anthropic.chat.completion.stop.sequence Which custom stop sequence was generated, if any, may be 'null'.
mime.type The mime type of the response.
filename An updated filename for the response.
Property Description
API Key The API key for authenticating to the Azure OpenAI service
Deployment Name The name of the OpenAI model deployment
Detail Level The image detail level that OpenAI should use for processing the image. Low detail will be less expensive and lower latency, while a high level may provide better results.
Image MIME Type The MIME type of the image
Image URL The URL of the image to send to OpenAI. If not specified, the contents of the FlowFile will be used as the image.
Max File Size The maximum size of a FlowFile that can be sent to OpenAI as an image. If the FlowFile is larger than this, it will be routed to 'failure'.
Max Tokens The maximum number of tokens to generate
OpenAI Service Name The name of the OpenAI service to use
Prompt Type The type of prompt to send to OpenAI
Response Format The format of the response from OpenAI
Results Attribute The name of the attribute to write the response to. If unset, the response will be written to the FlowFile content.
Seed The seed to use for generating the response
System Message The system message to send to OpenAI. FlowFile attributes may be referenced via Expression Language, and the contents of the FlowFile may be referenced via the flowfile_content variable. E.g., $\{flowfile_content\}
Temperature The temperature to use for generating the response.
Top P The top P value to use for generating the response
User Your end user, sent to OpenAI for monitoring and detection of abuse
User Message The user message to send to OpenAI. FlowFile attributes may be referenced via Expression Language, and the contents of the FlowFile may be referenced via the flowfile_content variable. E.g., $\{flowfile_content\}
Web Client Service The Web Client Service to use for communicating with OpenAI
Name Description
failure If unable to obtain a valid response from Azure OpenAI, the original FlowFile will be routed to this relationship
success The response from Azure OpenAI is routed to this relationship
Property Description
Assistant Message The assistant message to send to the LLM. FlowFile attributes may be referenced via Expression Language, and the contents of the FlowFile may be referenced via the flowfile_content variable. E.g., $\{flowfile_content\}. The assistant message is added last
LLM Provider Service The provider service for sending evaluation prompts to LLM
Output Strategy Determines response output destination
Results Attribute The name of the attribute to write the response to.
System Message The system message to send to the LLM. FlowFile attributes may be referenced via Expression Language, and the contents of the FlowFile may be referenced via the flowfile_content variable. E.g., $\{flowfile_content\}. The system message is added first.
User Message The user message to send to the LLM. FlowFile attributes may be referenced via Expression Language, and the contents of the FlowFile may be referenced via the flowfile_content variable. E.g., $\{flowfile_content\}.
Name Description
failure FlowFiles that cannot be processed are routed to this relationship
success FlowFiles that are successfully processed are routed to this relationship
Property Description
Detail Level The image detail level that OpenAI should use for processing the image. Low detail will be less expensive and lower latency, while a high level may provide better results.
Image MIME Type The MIME type of the image
Image Model Name The name of the OpenAI model
Image URL The URL of the image to send to OpenAI. If not specified, the contents of the FlowFile will be used as the image.
Max File Size The maximum size of a FlowFile that can be sent to OpenAI as an image. If the FlowFile is larger than this, it will be routed to 'failure'.
Max Tokens The maximum number of tokens to generate
OpenAI API Key The API Key for authenticating to OpenAI
OpenAI Organization The organization to use for OpenAI
Prompt Type The type of prompt to send to OpenAI
Response Format The format of the response from OpenAI
Results Attribute The name of the attribute to write the response to. If unset, the response will be written to the FlowFile content.
Seed The seed to use for generating the response
System Message The system message to send to OpenAI. FlowFile attributes may be referenced via Expression Language, and the contents of the FlowFile may be referenced via the flowfile_content variable. E.g., $\{flowfile_content\}
Temperature The temperature to use for generating the response.
Text Model Name The name of the OpenAI model
Top P The top P value to use for generating the response
User Your end user, sent to OpenAI for monitoring and detection of abuse
User Message The user message to send to OpenAI. FlowFile attributes may be referenced via Expression Language, and the contents of the FlowFile may be referenced via the flowfile_content variable. E.g., $\{flowfile_content\}
Web Client Service The Web Client Service to use for communicating with OpenAI
Name Description
failure If unable to obtain a valid response from OpenAI, the original FlowFile will be routed to this relationship
success The response from OpenAI is routed to this relationship
Property Description
Enable Cortex Guardrails Filters potentially unsafe and harmful responses from a language model. Either true or false.
Max Tokens The maximum number of tokens to generate
Output Strategy Determines response output destination
Response Format The format of the response from Snowflake Cortex
Results Attribute The name of the attribute to write the response to.
Snowflake Connection Service Database Connection Service for accessing Snowflake
System Message The system message to send to Snowflake Cortex. FlowFile attributes may be referenced via Expression Language, and the contents of the FlowFile may be referenced via the flowfile_content variable. E.g., $\{flowfile_content\}
Temperature The temperature to use for generating the response.
Text Model Name The name of the Snowflake Cortex model
Top P The top P value to use for generating the response
User Message The user message to send to Snowflake Cortex. FlowFile attributes may be referenced via Expression Language, and the contents of the FlowFile may be referenced via the flowfile_content variable. E.g., $\{flowfile_content\}
Name Description
failure If unable to obtain a valid response from Snowflake Cortex, the original FlowFile will be routed to this relationship
success The response from Snowflake Cortex is routed to this relationship
Property Description
GCP Credentials Service The Controller Service used to obtain Google Cloud Platform credentials.
GCP Location The location to configure the Vertex client with
GCP Project ID The project ID to configure the Vertex client with
Max File Size The maximum size of a FlowFile that can be sent to Vertex as an image. If the FlowFile is larger than this, it will be routed to 'failure'.
Max Tokens The maximum number of tokens to generate
Media MIME Type The MIME type of the media in the FlowFile content. Supported media types are listed here: https://firebase.google.com/docs/vertex-ai/input-file-requirements (https://firebase.google.com/docs/vertex-ai/input-file-requirements)
Model Name The name of the Vertex model
Output Strategy Determines response output destination
Prompt Type The type of prompt to send to Vertex. Text to send a simple prompt. Media to send a multimedia type first followed by a text prompt.
Response Format The format of the response from Vertex
Results Attribute The name of the attribute to write the response to.
Stop Sequences A comma delimited list of strings act as stop sequences. The model will halt after encountering one of the stop sequences.
System Message The system message to send to Vertex. FlowFile attributes may be referenced via Expression Language, and the contents of the FlowFile may be referenced via the flowfile_content variable. E.g., $\{flowfile_content\}
Temperature The temperature to use for generating the response. Defaults to 1.0. Ranges from 0.0 to 1.0. Use temperature closer to 0.0 for analytical / multiple choice, and closer to 1.0 for creative and generative tasks.
Top K The top K value to use for generating the response. Only sample from the top K options for each subsequent token. Recommended for advanced use cases only. You usually only need to use temperature.
Top P The top P value to use for generating the response. Top P is for nucleus sampling, we compute the cumulative distribution over all the options for each subsequent token in decreasing probability order and cut it off once it reaches a particular probability specified by top_p. Recommended for advanced use cases only. You usually only need to use temperature.
User Message The user message to send to Vertex. FlowFile attributes may be referenced via Expression Language, and the contents of the FlowFile may be referenced via the flowfile_content variable. E.g., $\{flowfile_content\}. The user message is added first, unless an image is present.
Name Description
failure If unable to obtain a valid response from Vertex, the original FlowFile will be routed to this relationship
success The response from Vertex is routed to this relationship
Name Description
vertex.usage.inputTokens The number of input tokens read in the request.
vertex.usage.outputTokens The number of output tokens generated in the response.
vertex.chat.completion.id A unique id assigned to the conversation
mime.type The mime type of the response.
filename An updated filename for the response.
Display Name API Name Default Value Allowable Values Description
Configuration File * configuration-file A configuration file
Required Permission Explanation
read filesystem Provides operator the ability to read from any file that NiFi has access to.
Display Name API Name Default Value Allowable Values Description
Message Type * Message Type Fully qualified name of the Protocol Buffers message type including its package (eg. mypackage.MyMessage). The .proto files configured in 'Proto Directory' must contain the definition of this message type.
Proto Directory * Proto Directory Directory containing Protocol Buffers message definition (.proto) file(s).
Schema Access Strategy * Schema Access Strategy generate-from-proto-file - Use 'Schema Name' Property - Use 'Schema Text' Property - Schema Reference Reader - Generate from Proto file Specifies how to obtain the schema that is to be used for interpreting the data.
Schema Branch Schema Branch Specifies the name of the branch to use when looking up the schema in the Schema Registry property. If the chosen Schema Registry does not support branching, this value will be ignored.
Schema Name Schema Name $\{schema.name\} Specifies the name of the schema to lookup in the Schema Registry property
Schema Reference Reader * Schema Reference Reader Service implementation responsible for reading FlowFile attributes or content to determine the Schema Reference Identifier
Schema Registry Schema Registry Specifies the Controller Service to use for the Schema Registry
Schema Text Schema Text $\{avro.schema\} The text of an Avro-formatted Schema
Schema Version Schema Version Specifies the version of the schema to lookup in the Schema Registry. If not specified then the latest version of the schema will be retrieved.
Parameter Description
`connector_name` Fully qualified name of the Zerocopy Connector (for example, `my_db.my_schema.my_sap_connector`).
`snowflake_share_name` Name of the Snowflake share, also the name of the share on the SAP® BDC side.
`open_resource_discovery_metadata` A JSON object describing the data product in SAP® BDC. Contains the following fields: - `title`: Display name of the data product. - `shortDescription`: Brief summary of the data product. - `description`: Full description of the data product.
`csn_document_json` The SAP® Core Schema Notation (CSN) JSON payload describing the structure of the data product. Provided by the caller.
Property Description
AMQP Version AMQP Version. Currently only supports AMQP v0.9.1.
Brokers A comma-separated list of known AMQP Brokers in the format <host>:<port> (e.g., localhost:5672). If this is set, Host Name and Port are ignored. Only include hosts from the same AMQP cluster.
Client Certificate Authentication Enabled Authenticate using the SSL certificate rather than user name/password.
Exchange Name The name of the AMQP Exchange the messages will be sent to. Usually provided by the AMQP administrator (e.g., 'amq.direct'). It is an optional property. If kept empty the messages will be sent to a default AMQP exchange.
Header Separator The character that is used to split key-value for headers. The value must only one character. Otherwise you will get an error message
Headers Pattern Regular expression that will be evaluated against the FlowFile attributes to select the matching attributes and put as AMQP headers. Attribute name will be used as header key.
Headers Source The source of the headers which will be applied to the published message.
Host Name Network address of AMQP broker (e.g., localhost). If Brokers is set, then this property is ignored.
Password Password used for authentication and authorization.
Port Numeric value identifying Port of AMQP broker (e.g., 5671). If Brokers is set, then this property is ignored.
Routing Key The name of the Routing Key that will be used by AMQP to route messages from the exchange to a destination queue(s). Usually provided by the administrator (e.g., 'myKey')In the event when messages are sent to a default exchange this property corresponds to a destination queue name, otherwise a binding from the Exchange to a Queue via Routing Key must be set (usually by the AMQP administrator)
SSL Context Service The SSL Context Service used to provide client certificate information for TLS/SSL connections.
Username Username used for authentication and authorization.
Virtual Host Virtual Host name which segregates AMQP system for enhanced security.
Name Description
failure All FlowFiles that cannot be routed to the AMQP destination are routed to this relationship
success All FlowFiles that are sent to the AMQP destination are routed to this relationship
Property Description
Account Snowflake Account Identifier with Organization Name and Account Name formatted as [organization-name]-[account-name]
Authentication Strategy Strategy for authenticating Snowflake connections
Channel Group Group for managing distinct Snowpipe Streaming Channels with partitioning
Channel Insert Timeout Maximum duration to retry inserting records before failing with an upper bound of 5 minutes
Concurrency Group Controls access to the configured channel with serialized claims according to the configured value or expression
Database Snowflake Database destination for processed records
Destination Type Snowflake destination object for processed records with support for derived default pipes
Offset Token End Expression Expression Language definition to produce the highest offset token for a FlowFile as a monotonically increasing number
Offset Token Record Pointer JSON Pointer to offset token in each record required when the last committed offset token is between start and end boundaries
Offset Token Start Expression Expression Language definition to produce the lowest offset token for a FlowFile as a monotonically increasing number
Offset Tracking Resolution Resolution level for evaluating committed offset tokens against input FlowFiles and records. **Disabled**: opaque offset token handling without tracking across FlowFiles or records. **FlowFile**: track each FlowFile with monotonically increasing offset tokens. **Record**: track each record in each FlowFile with monotonically increasing offset tokens.
Offset Tracking Timeout Maximum duration to wait for channel status to confirm committed offset tokens before routing to failure
Pipe Snowflake Pipe destination for processed records
Private Key Service RSA Private Key Service for authenticating connections
Role Snowflake Role the user will assume when authenticating connections
Schema Snowflake Schema destination for processed records
Table Snowflake Table destination for processed records
Transfer Strategy Strategy for transferring records to Snowpipe Streaming. **Managed**: transfer records as either batches of rows or file fragments based on uncompressed size. **Rows**: transfer records as batches of rows over HTTP to Snowpipe Streaming. **File Fragments**: transfer records as file fragments over HTTP to cloud storage services.
User Snowflake User for authenticating connections
Web Client Service Provider Web Client Service Provider supporting HTTP request and response handling
Name Description
empty FlowFiles with empty content not sent to Snowflake
failure FlowFiles that failed to upload to Snowflake
invalid FlowFiles that Snowflake identified as containing one or more invalid rows resulting in partial transmission
success FlowFiles successfully uploaded to Snowflake
Property Description
GCP Credentials Provider Service The Controller Service used to obtain Google Cloud Platform credentials.
Input Batch Size Maximum number of FlowFiles processed for each Processor invocation
Maximum Message Size The maximum size of a Google PubSub message in bytes. Defaults to 1 MB (1048576 bytes)
Message Derivation Strategy The strategy used to publish the incoming FlowFile to the Google Cloud PubSub endpoint.
Record Reader The Record Reader to use for incoming FlowFiles
Record Writer The Record Writer to use in order to serialize the data before sending to GCPubSub endpoint
api-endpoint Override the gRPC endpoint in the form of [host:port]
gcp-batch-bytes Publish request gets triggered based on this Batch Bytes Threshold property and the Batch Size Threshold property, whichever condition is met first.
gcp-project-id Google Cloud Project ID
gcp-pubsub-publish-batch-delay Indicates the delay threshold to use for batching. After this amount of time has elapsed (counting from the first element added), the elements will be wrapped up in a batch and sent. This value should not be set too high, usually on the order of milliseconds. Otherwise, calls might appear to never complete.
gcp-pubsub-publish-batch-size Indicates the number of messages the cloud service should bundle together in a batch. If not set and left empty, only one message will be used in a batch
gcp-pubsub-topic Name of the Google Cloud PubSub Topic
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
failure FlowFiles are routed to this relationship if the Google Cloud Pub/Sub operation fails.
retry FlowFiles are routed to this relationship if the Google Cloud Pub/Sub operation fails but attempting the operation again may succeed.
success FlowFiles are routed to this relationship after a successful Google Cloud Pub/Sub operation.
Name Description
gcp.pubsub.messageId ID of the pubsub message published to the configured Google Cloud PubSub topic
gcp.pubsub.count.records Count of pubsub messages published to the configured Google Cloud PubSub topic
gcp.pubsub.topic Name of the Google Cloud PubSub topic the message was published to
Property Description
Connection Client ID The client id to be set on the connection, if set. For durable non shared consumer this is mandatory, for all others it is optional, typically with shared consumers it is undesirable to be set. Please see JMS spec for further details
Connection Factory Service The Controller Service that is used to obtain Connection Factory. Alternatively, the 'JNDI *' or the 'JMS *' properties can also be used to configure the Connection Factory.
Destination Name The name of the JMS Destination. Usually provided by the administrator (e.g., 'topic://myTopic' or 'myTopic').
Destination Type The type of the JMS Destination. Could be one of 'QUEUE' or 'TOPIC'. Usually provided by the administrator. Defaults to 'QUEUE'
Maximum Batch Size The maximum number of messages to publish or consume in each invocation of the processor.
Password Password used for authentication and authorization.
SSL Context Service The SSL Context Service used to provide client certificate information for TLS/SSL connections.
User Name User Name used for authentication and authorization.
allow-illegal-chars-in-jms-header-names Specifies whether illegal characters in header names should be sent to the JMS broker. Usually hyphens and full-stops.
attributes-to-send-as-jms-headers-regex Specifies the Regular Expression that determines the names of FlowFile attributes that should be sent as JMS Headers
broker URI pointing to the network location of the JMS Message broker. Example for ActiveMQ: '[tcp://myhost:61616](tcp://myhost:61616)'. Examples for IBM MQ: 'myhost(1414)' and 'myhost01(1414),myhost02(1414)'.
cf The fully qualified name of the JMS ConnectionFactory implementation class (eg. org.apache.activemq. ActiveMQConnectionFactory).
cflib Path to the directory with additional resources (eg. JARs, configuration files etc.) to be added to the classpath (defined as a comma separated list of values). Such resources typically represent target JMS client libraries for the ConnectionFactory implementation.
character-set The name of the character set to use to construct or interpret TextMessages
connection.factory.name The name of the JNDI Object to lookup for the Connection Factory.
java.naming.factory.initial The fully qualified class name of the JNDI Initial Context Factory Class (java.naming.factory.initial).
java.naming.provider.url The URL of the JNDI Provider to use as the value for java.naming.provider.url. See additional details documentation for allowed URL schemes.
java.naming.security.credentials The Credentials to use when authenticating with JNDI (java.naming.security.credentials).
java.naming.security.principal The Principal to use when authenticating with JNDI (java.naming.security.principal).
message-body-type The type of JMS message body to construct.
naming.factory.libraries Specifies jar files and/or directories to add to the ClassPath in order to load the JNDI / JMS client libraries. This should be a comma-separated list of files, directories, and/or URLs. If a directory is given, any files in that directory will be included, but subdirectories will not be included (i.e., it is not recursive).
record-reader The Record Reader to use for parsing the incoming FlowFile into Records.
record-writer The Record Writer to use for serializing Records before publishing them as an JMS Message.
Required Permission Explanation
reference remote resources Client Library Location can reference resources over HTTP
Name Description
failure All FlowFiles that cannot be sent to JMS destination are routed to this relationship
success All FlowFiles that are sent to the JMS destination are routed to this relationship
Property Description
Failure Strategy Specifies how the processor handles a FlowFile if it is unable to publish the data to Kafka
FlowFile Attribute Header Pattern A Regular Expression that is matched against all FlowFile attribute names. Any attribute whose name matches the pattern will be added to the Kafka messages as a Header. If not specified, no FlowFile attributes will be added as headers.
Header Encoding For any attribute that is added as a Kafka Record Header, this property indicates the Character Encoding to use for serializing the headers.
Kafka Connection Service Provides connections to Kafka Broker for publishing Kafka Records
Kafka Key The Key to use for the Message. If not specified, the FlowFile attribute 'kafka.key' is used as the message key, if it is present. Beware that setting Kafka key and demarcating at the same time may potentially lead to many Kafka messages with the same key. Normally this is not a problem as Kafka does not enforce or assume message and key uniqueness. Still, setting the demarcator and Kafka key at the same time poses a risk of data loss on Kafka. During a topic compaction on Kafka, messages will be deduplicated based on this key.
Kafka Key Attribute Encoding FlowFiles that are emitted have an attribute named 'kafka.key'. This property dictates how the value of the attribute should be encoded.
Message Demarcator Specifies the string (interpreted as UTF-8) to use for demarcating multiple messages within a single FlowFile. If not specified, the entire content of the FlowFile will be used as a single message. If specified, the contents of the FlowFile will be split on this delimiter and each section sent as a separate Kafka message. To enter special character such as 'new line' use CTRL+Enter or Shift+Enter, depending on your OS.
Message Key Field The name of a field in the Input Records that should be used as the Key for the Kafka message.
Publish Strategy The format used to publish the incoming FlowFile record to Kafka.
Record Key Writer The Record Key Writer to use for outgoing FlowFiles
Record Metadata Strategy Specifies whether the Record 's metadata (topic and partition) should come from the Record's metadata field or if it should come from the configured Topic Name and Partition / Partitioner class properties
Record Reader The Record Reader to use for incoming FlowFiles
Record Writer The Record Writer to use in order to serialize the data before sending to Kafka
Topic Name Name of the Kafka Topic to which the Processor publishes Kafka Records
Transactional ID Prefix Specifies the KafkaProducer config transactional.id will be a generated UUID and will be prefixed with the configured string.
Transactions Enabled Specifies whether to provide transactional guarantees when communicating with Kafka. If there is a problem sending data to Kafka, and this property is set to false, then the messages that have already been sent to Kafka will continue on and be delivered to consumers. If this is set to true, then the Kafka transaction will be rolled back so that those messages are not available to consumers. Setting this to true requires that the [Delivery Guarantee] property be set to [Guarantee Replicated Delivery.]
acks Specifies the requirement for guaranteeing that a message is sent to Kafka. Corresponds to Kafka Client acks property.
compression.type Specifies the compression strategy for records sent to Kafka. Corresponds to Kafka Client compression.type property.
max.request.size The maximum size of a request in bytes. Corresponds to Kafka Client max.request.size property.
partition Specifies the Kafka Partition destination for Records.
partitioner.class Specifies which class to use to compute a partition id for a message. Corresponds to Kafka Client partitioner.class property.
Name Description
failure Any FlowFile that cannot be sent to Kafka will be routed to this Relationship
success FlowFiles for which all content was sent to Kafka.
Name Description
msg.count The number of messages that were sent to Kafka for this FlowFile. This attribute is added only to FlowFiles that are routed to success.
Property Description
Broker URI The URI(s) to use to connect to the MQTT broker (e.g., [tcp://localhost:1883](tcp://localhost:1883)). The 'tcp', 'ssl', 'ws' and 'wss'schemes are supported. In order to use 'ssl', the SSL Context Service property must be set. When a comma-separated URI list is set (e.g., [tcp://localhost:1883,tcp://localhost:1884](tcp://localhost:1883,tcp://localhost:1884)), the processor will use a round-robin algorithm to connect to the brokers on connection failure.
Client ID MQTT client ID to use. If not set, a UUID will be generated.
Connection Timeout (seconds) Maximum time interval the client will wait for the network connection to the MQTT server to be established. The default timeout is 30 seconds. A value of 0 disables timeout processing meaning the client will wait until the network connection is made successfully or fails.
Keep Alive Interval (seconds) Defines the maximum time interval between messages sent or received. It enables the client to detect if the server is no longer available, without having to wait for the TCP/IP timeout. The client will ensure that at least one message travels across the network within each keep alive period. In the absence of a data-related message during the time period, the client sends a very small "ping" message, which the server will acknowledge. A value of 0 disables keepalive processing in the client.
Last Will Message The message to send as the client's Last Will.
Last Will QoS Level QoS level to be used when publishing the Last Will Message.
Last Will Retain Whether to retain the client's Last Will.
Last Will Topic The topic to send the client's Last Will to.
MQTT Specification Version The MQTT specification version when connecting with the broker. See the allowable value descriptions for more details.
Password Password to use when connecting to the broker
Quality of Service(QoS) The Quality of Service (QoS) to send the message with. Accepts three values '0', '1' and '2'; '0' for 'at most once', '1' for 'at least once', '2' for 'exactly once'. Expression language is allowed in order to support publishing messages with different QoS but the end value of the property must be either '0', '1' or '2'.
Retain Message Whether or not the retain flag should be set on the MQTT message.
SSL Context Service The SSL Context Service used to provide client certificate information for TLS/SSL connections.
Session Expiry Interval After this interval the broker will expire the client and clear the session state.
Session state Whether to start a fresh or resume previous flows. See the allowable value descriptions for more details.
Topic The topic to publish the message to.
Username Username to use when connecting to the broker
message-demarcator With this property, you have an option to publish multiple messages from a single FlowFile. This property allows you to provide a string (interpreted as UTF-8) to use for demarcating apart the FlowFile content. This is an optional property ; if not provided, and if not defining a Record Reader/Writer, each FlowFile will be published as a single message. To enter special character such as 'new line' use CTRL+Enter or Shift+Enter depending on the OS.
record-reader The Record Reader to use for parsing the incoming FlowFile into Records.
record-writer The Record Writer to use for serializing Records before publishing them as an MQTT Message.
Name Description
failure FlowFiles that failed to send to the destination are transferred to this relationship.
success FlowFiles that are sent successfully to the destination are transferred to this relationship.
Property Description
Access Token OAuth Access Token used for authenticating/authorizing the Slack request sent by NiFi. This may be either a User Token or a Bot Token. The token must be granted the chat:write scope. Additionally, in order to upload FlowFile contents as an attachment, it must be granted files:write.
Channel The name or identifier of the channel to send the message to. If using a channel name, it must be prefixed with the # character. For example, #general. This is valid only for public channels. Otherwise, the unique identifier of the channel to publish to must be provided.
Character Set Specifies the name of the Character Set used to encode the FlowFile contents.
Include FlowFile Content as Attachment Specifies whether or not the contents of the FlowFile should be uploaded as an attachment to the Slack message.
Max FlowFile Size The maximum size of a FlowFile that can be sent to Slack. If any FlowFile exceeds this size, it will be routed to failure. This plays an important role because the entire contents of the file must be loaded into NiFi's heap in order to send the data to Slack.
Message Text The text of the message to send to Slack.
Methods Endpoint Url Prefix Customization of the Slack Client. Set the methodsEndpointUrlPrefix. If you need to set a different URL prefix for Slack API Methods calls, you can set the one. Default value: https://slack.com/api/ (https://slack.com/api/)
Publish Strategy Specifies how the Processor will send the message or file to Slack.
Thread Timestamp The Timestamp identifier for the thread that this message is to be a part of. If not specified, the message will be a top-level message instead of being in a thread.
Name Description
failure FlowFiles are routed to 'failure' if unable to be sent to Slack for any other reason
rate limited FlowFiles are routed to 'rate limited' if the Rate Limit has been exceeded
success FlowFiles are routed to success after being successfully sent to Slack
Name Description
slack.channel.id The ID of the Slack Channel from which the messages were retrieved
slack.ts The timestamp of the slack messages that was sent; this is used by Slack as a unique identifier
Property Description
Account Snowflake Account Identifier with Organization Name and Account Name formatted as [organization-name]-[account-name]
Authentication Strategy Strategy for authenticating Snowflake connections
Channel Group Group for managing distinct Snowpipe Streaming Channels with partitioning
Channel Insert Timeout Maximum duration to retry inserting records before failing with an upper bound of 5 minutes
Database Snowflake Database destination for processed records
Destination Type Snowflake destination object for processed records with support for derived default pipes
File Fragment Count Maximum number of file fragments sent to object storage for Snowpipe Streaming ingestion from input FlowFiles. Must be between 1 and 100.
File Fragment Size Maximum size in bytes for each file fragment sent to object storage for Snowpipe Streaming ingestion. Must be between 1 KB and 256 MB
Offset Token End Expression Expression Language definition to produce the highest offset token for a FlowFile as a monotonically increasing number
Offset Token Record Pointer JSON Pointer to offset token in each record required when the last committed offset token is between start and end boundaries
Offset Token Start Expression Expression Language definition to produce the lowest offset token for a FlowFile as a monotonically increasing number
Offset Tracking Resolution Resolution level for evaluating committed offset tokens against input FlowFiles and records. **Disabled**: opaque offset token handling without tracking across FlowFiles or records. **FlowFile**: track each FlowFile with monotonically increasing offset tokens. **Record**: track each record in each FlowFile with monotonically increasing offset tokens.
Offset Tracking Timeout Maximum duration to wait for channel status to confirm committed offset tokens before routing to failure
Pipe Snowflake Pipe destination for processed records
Private Key Service RSA Private Key Service for authenticating connections
Role Snowflake Role the user will assume when authenticating connections
Schema Snowflake Schema destination for processed records
Table Snowflake Table destination for processed records
Transfer Strategy Strategy for transferring records to Snowpipe Streaming. **Managed**: transfer records as either batches of rows or file fragments based on uncompressed size. **Rows**: transfer records as batches of rows over HTTP to Snowpipe Streaming. **File Fragments**: transfer records as file fragments over HTTP to cloud storage services.
User Snowflake User for authenticating connections
Web Client Service Provider Web Client Service Provider supporting HTTP request and response handling
Name Description
empty FlowFiles with empty content not sent to Snowflake
failure FlowFiles that failed to upload to Snowflake
invalid FlowFiles that Snowflake identified as containing one or more invalid rows resulting in partial transmission
success FlowFiles successfully uploaded to Snowflake
Property Description
Blob Name The full name of the blob
Client-Side Encryption Key ID Specifies the ID of the key to use for client-side encryption.
Client-Side Encryption Key Type Specifies the key type to use for client-side encryption.
Client-Side Encryption Local Key When using local client-side encryption, this is the raw key, encoded in hexadecimal
Conflict Resolution Strategy Specifies whether an existing blob will have its contents replaced upon conflict.
Container Name Name of the Azure storage container. In case of PutAzureBlobStorage processor, container can be created if it does not exist.
Create Container Specifies whether to check if the container exists and to automatically create it if it does not. Permission to list containers is required. If false, this check is not made, but the Put operation will fail if the container does not exist.
File Resource Service File Resource Service providing access to the local resource to be transferred
Resource Transfer Source The source of the content to be transferred
Storage Credentials Controller Service used to obtain Azure Blob Storage Credentials.
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests. In case of SOCKS, it is not guaranteed that the selected SOCKS Version will be used by the processor.
Name Description
failure Unsuccessful operations will be transferred to the failure relationship.
success All successfully processed FlowFiles are routed to this relationship
Name Description
azure.container The name of the Azure Blob Storage container
azure.blobname The name of the blob on Azure Blob Storage
azure.primaryUri Primary location of the blob
azure.etag ETag of the blob
azure.blobtype Type of the blob (either BlockBlob, PageBlob or AppendBlob)
mime.type MIME Type of the content
lang Language code for the content
azure.timestamp Timestamp of the blob
azure.length Length of the blob
azure.error.code Error code reported during blob operation
azure.ignored When Conflict Resolution Strategy is 'ignore', this property will be true/false depending on whether the blob was ignored.
Property Description
Cosmos DB Access Key Cosmos DB Access Key from Azure Portal (Settings->Keys). Choose a read-write key to enable database or container creation at run time
Cosmos DB Conflict Handling Strategy Choose whether to ignore or upsert when conflict error occurs during insertion
Cosmos DB Connection Service If configured, the controller service used to obtain the connection string and access key
Cosmos DB Consistency Level Choose from five consistency levels on the consistency spectrum. Refer to Cosmos DB documentation for their differences
Cosmos DB Container ID The unique identifier for the container
Cosmos DB Name The database name or id. This is used as the namespace for document collections or containers
Cosmos DB Partition Key The partition key used to distribute data among servers
Cosmos DB URI Cosmos DB URI, typically in the form of https://\{databaseaccount\}.documents.azure.com:443/ Note this host URL is for Cosmos DB with Core SQL API from Azure Portal (Overview->URI)
Insert Batch Size The number of records to group together for one single insert operation against Cosmos DB
Record Reader Specifies the Controller Service to use for parsing incoming data and determining the data's schema
Name Description
failure All FlowFiles that cannot be written to Cosmos DB are routed to this relationship
success All FlowFiles that are written to Cosmos DB are routed to this relationship
Property Description
Data Format The format of the data that is sent to Azure Data Explorer. Supported formats include: avro, csv, json
Database Name Azure Data Explorer Database Name for ingesting data
Ingest Mapping Name The name of the mapping responsible for storing the data in the appropriate columns.
Ingest Status Polling Interval Defines the value of interval of time to poll for ingestion status
Ingest Status Polling Timeout Defines the total amount time to poll for ingestion status
Ingestion Ignore First Record Defines whether ignore first record while ingestion.
Kusto Ingest Service Azure Data Explorer Kusto Ingest Service
Partially Succeeded Routing Strategy Defines where to route FlowFiles that resulted in a partially succeeded status.
Poll for Ingest Status Determines whether to poll on ingestion status after an ingestion to Azure Data Explorer is completed
Streaming Enabled Whether to stream data to Azure Data Explorer.
Table Name Azure Data Explorer Table Name for ingesting data
Name Description
failure Ingest processing failed
success Ingest processing succeeded
Property Description
ADLS Credentials Controller Service used to obtain Azure Credentials.
Base Temporary Path The Path where the temporary directory will be created. The Path name cannot contain a leading '/'. The root directory can be designated by the empty string value. Non-existing directories will be created. The Temporary File Directory name is _nifitempdirectory
Conflict Resolution Strategy Indicates what should happen when a file with the same name already exists in the output directory
Directory Name Name of the Azure Storage Directory. The Directory Name cannot contain a leading '/'. The root directory can be designated by the empty string value. In case of the PutAzureDataLakeStorage processor, the directory will be created if not already existing.
File Name The filename
File Resource Service File Resource Service providing access to the local resource to be transferred
Filesystem Name Name of the Azure Storage File System (also called Container). It is assumed to be already existing.
Resource Transfer Source The source of the content to be transferred
Writing Strategy Defines the approach for writing the Azure file.
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests. In case of SOCKS, it is not guaranteed that the selected SOCKS Version will be used by the processor.
Name Description
failure Files that could not be written to Azure storage for some reason are transferred to this relationship
success Files that have been successfully written to Azure storage are transferred to this relationship
Name Description
azure.filesystem The name of the Azure File System
azure.directory The name of the Azure Directory
azure.filename The name of the Azure File
azure.primaryUri Primary location for file content
azure.length The length of the Azure File
Property Description
Event Hub Name Name of Azure Event Hubs destination
Event Hub Namespace Namespace of Azure Event Hubs prefixed to Service Bus Endpoint domain
Maximum Batch Size Maximum number of FlowFiles processed for each Processor invocation
Partitioning Key Attribute Name If specified, the value from argument named by this field will be used as a partitioning key to be used by event hub.
Service Bus Endpoint To support namespaces not in the default windows.net domain.
Shared Access Policy Key The key of the shared access policy. Either the primary or the secondary key can be used.
Shared Access Policy Name The name of the shared access policy. This policy must have Send claims.
Transport Type Advanced Message Queuing Protocol Transport Type for communication with Azure Event Hubs
Use Azure Managed Identity Choose whether or not to use the managed identity of Azure VM/VMSS
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
failure Any FlowFile that could not be sent to the event hub will be transferred to this Relationship.
success Any FlowFile that is successfully sent to the event hubs will be transferred to this Relationship.
Property Description
Credentials Service Controller Service used to obtain Azure Storage Credentials.
Endpoint Suffix Storage accounts in public Azure always use a common FQDN suffix. Override this endpoint suffix with a different suffix in certain circumstances (like Azure Stack or non-public Azure regions).
Message Time To Live Maximum time to allow the message to be in the queue
Queue Name Name of the Azure Storage Queue
Request Timeout The timeout for read or write requests to Azure Queue Storage. Defaults to 1 second.
Visibility Timeout The length of time during which the message will be invisible after it is read. If the processing unit fails to delete the message after it is read, then the message will reappear in the queue.
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests. In case of SOCKS, it is not guaranteed that the selected SOCKS Version will be used by the processor.
Name Description
failure Unsuccessful operations will be transferred to the failure relationship.
success All successfully processed FlowFiles are routed to this relationship
Property Description
GCP Credentials Provider Service The Controller Service used to obtain Google Cloud Platform credentials.
bigquery-api-endpoint Can be used to override the default BigQuery endpoint. Default is bigquerystorage.googleapis.com:443. Format must be hostname:port.
bq.append.record.count The number of records to be appended to the write stream at once. Applicable for both batch and stream types
bq.dataset BigQuery dataset name (Note - The dataset must exist in GCP)
bq.record.reader Specifies the Controller Service to use for parsing incoming data.
bq.skip.invalid.rows Sets whether to insert all valid rows of a request, even if invalid rows exist. If not set the entire insert request will fail if it contains an invalid row.
bq.table.name BigQuery table name
bq.transfer.type Defines the preferred transfer type streaming or batching
gcp-project-id Google Cloud Project ID
gcp-retry-count How many retry attempts should be made before routing to the failure relationship.
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
failure FlowFiles are routed to this relationship if the Google BigQuery operation fails.
success FlowFiles are routed to this relationship after a successful Google BigQuery operation.
Name Description
bq.records.count Number of records successfully inserted
Property Description
Box Client Service Controller Service used to obtain a Box API connection.
Chunked Upload Threshold The maximum size of the content which is uploaded at once. FlowFiles larger than this threshold are uploaded in chunks. Chunked upload is allowed for files larger than 20 MB. It is recommended to use chunked upload for files exceeding 50 MB.
Conflict Resolution Strategy Indicates what should happen when a file with the same name already exists in the specified Box folder.
Create Subfolder Specifies whether to check if the subfolder exists and to automatically create it if it does not. Permission to list folders is required.
Filename The name of the file to upload to the specified Box folder.
Folder ID The ID of the folder where the file is uploaded. Please see Additional Details to obtain Folder ID.
Subfolder Name The name (path) of the subfolder where files are uploaded. The subfolder name is relative to the folder specified by 'Folder ID'. Example: subFolder, subFolder1/subfolder2
Name Description
failure Files that could not be written to Box for some reason are transferred to this relationship.
success Files that have been successfully written to Box are transferred to this relationship.
Name Description
box.id The id of the file
filename The name of the file
path The folder path where the file is located
box.size The size of the file
box.timestamp The last modified time of the file
error.code The error code returned by Box
error.message The error message returned by Box
Property Description
AWS Credentials Provider service The Controller Service that is used to obtain AWS credentials provider
Communications Timeout
Endpoint Override URL Endpoint URL to use instead of the AWS default including scheme, host, port, and path. The AWS libraries select an endpoint URL based on the AWS region, but this property overrides the selected endpoint URL, allowing use with other S3-compatible endpoints.
Maximum The maximum value of the sample set. Must be a double
Metric Name The name of the metric
Minimum The minimum value of the sample set. Must be a double
Namespace The namespace for the metric data for CloudWatch
Region
SSL Context Service Specifies an optional SSL Context Service that, if provided, will be used to create connections
Sample Count The number of samples used for the statistic set. Must be a double
Sum The sum of values for the sample set. Must be a double
Timestamp A point in time expressed as the number of milliseconds since Jan 1, 1970 00:00:00 UTC. If not specified, the default value is set to the time the metric data was received
Unit The unit of the metric. (e.g Seconds, Bytes, Megabytes, Percent, Count, Kilobytes/Second, Terabits/Second, Count/Second) For details see http://docs.aws.amazon.com/AmazonCloudWatch/latest/APIReference/API_MetricDatum.html (http://docs.aws.amazon.com/AmazonCloudWatch/latest/APIReference/API_MetricDatum.html)
Value The value for the metric. Must be a double
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
failure FlowFiles are routed to failure relationship
success FlowFiles are routed to success relationship
Property Description
Column Name Translation Pattern Column name will be normalized with this regular expression
Column Name Translation Strategy The strategy used to normalize table column name. Column Name will be uppercased to do case-insensitive matching irrespective of strategy
Data Record Path If specified, this property denotes a RecordPath that will be evaluated against each incoming Record and the Record that results from evaluating the RecordPath will be sent to the database instead of sending the entire incoming Record. If not specified, the entire incoming Record will be published to the database.
Database Dialect Service Database Dialect Service for generating statements specific to a particular service or vendor.
Delete Keys A comma-separated list of column names that uniquely identifies a row in the database for DELETE statements. If the Statement Type is DELETE and this property is not set, the table's columns are used. This property is ignored if the Statement Type is not DELETE
Rollback On Failure Specify how to handle error. By default (false), if an error occurs while processing a FlowFile, the FlowFile will be routed to 'failure' or 'retry' relationship based on error type, and processor can continue with next FlowFile. Instead, you may want to rollback currently processed FlowFiles and stop further processing immediately. In that case, you can do so by enabling this 'Rollback On Failure' property. If enabled, failed FlowFiles will stay in the input relationship without penalizing it and being processed repeatedly until it gets processed successfully or removed by other means. It is important to set adequate 'Yield Duration' to avoid retrying too frequently.
Statement Type Record Path Specifies a RecordPath to evaluate against each Record in order to determine the Statement Type. The RecordPath should equate to either INSERT, UPDATE, UPSERT, or DELETE. (Debezium style operation types are also supported: "r" and "c" for INSERT, "u" for UPDATE, and "d" for DELETE)
database-session-autocommit The autocommit mode to set on the database connection being used. If set to false, the operation(s) will be explicitly committed or rolled back (based on success or failure respectively). If set to true, the driver/database automatically handles the commit/rollback.
db-type Database Type for generating statements specific to a particular service or vendor. The Generic Type supports most cases but selecting a specific type enables optimal processing or additional features.
put-db-record-allow-multiple-statements If the Statement Type is 'SQL' (as set in the statement.type attribute), this field indicates whether to split the field value by a semicolon and execute each statement separately. If any statement causes an error, the entire set of statements will be rolled back. If the Statement Type is not 'SQL', this field is ignored.
put-db-record-binary-format The format to be applied when decoding string values to binary.
put-db-record-catalog-name The name of the database (or the name of the catalog, depending on the destination system) that the statement should update. This may not apply for the database that you are updating. In this case, leave the field empty. Note that if the property is set and the database is case-sensitive, the catalog name must match the database's catalog name exactly.
put-db-record-dcbp-service The Controller Service that is used to obtain a connection to the database for sending records.
put-db-record-field-containing-sql If the Statement Type is 'SQL' (as set in the statement.type attribute), this field indicates which field in the record(s) contains the SQL statement to execute. The value of the field must be a single SQL statement. If the Statement Type is not 'SQL', this field is ignored.
put-db-record-max-batch-size Specifies maximum number of sql statements to be included in each batch sent to the database. Zero means the batch size is not limited, and all statements are put into a single batch which can cause high memory usage issues for a very large number of statements.
put-db-record-query-timeout The maximum amount of time allowed for a running SQL statement , zero means there is no limit. Max time less than 1 second will be equal to zero.
put-db-record-quoted-identifiers Enabling this option will cause all column names to be quoted, allowing you to use reserved words as column names in your tables.
put-db-record-quoted-table-identifiers Enabling this option will cause the table name to be quoted to support the use of special characters in the table name.
put-db-record-record-reader Specifies the Controller Service to use for parsing incoming data and determining the data's schema.
put-db-record-schema-name The name of the schema that the table belongs to. This may not apply for the database that you are updating. In this case, leave the field empty. Note that if the property is set and the database is case-sensitive, the schema name must match the database's schema name exactly.
put-db-record-statement-type Specifies the type of SQL Statement to generate. Please refer to the database documentation for a description of the behavior of each operation. Please note that some Database Types may not support certain Statement Types. If 'Use statement.type Attribute' is chosen, then the value is taken from the statement.type attribute in the FlowFile. The 'Use statement.type Attribute' option is the only one that allows the 'SQL'statement type. If 'SQL' is specified, the value of the field specified by the 'Field Containing SQL' property is expected to be a valid SQL statement on the target database, and will be executed as-is.
put-db-record-table-name The name of the table that the statement should affect. Note that if the database is case-sensitive, the table name must match the database's table name exactly.
put-db-record-translate-field-names If true, the Processor will attempt to translate field names into the appropriate column names for the table specified. If false, the field names must match the column names exactly, or the column will not be updated
put-db-record-unmatched-column-behavior If an incoming record does not have a field mapping for all of the database table's columns, this property specifies how to handle the situation
put-db-record-unmatched-field-behavior If an incoming record has a field that does not map to any of the database table's columns, this property specifies how to handle the situation
put-db-record-update-keys A comma-separated list of column names that uniquely identifies a row in the database for UPDATE statements. If the Statement Type is UPDATE and this property is not set, the table's Primary Keys are used. In this case, if no Primary Key exists, the conversion to SQL will fail if Unmatched Column Behaviour is set to FAIL. This property is ignored if the Statement Type is INSERT
table-schema-cache-size Specifies how many Table Schemas should be cached
Name Description
failure A FlowFile is routed to this relationship if the database cannot be updated and retrying the operation will also fail, such as an invalid query or an integrity constraint violation
retry A FlowFile is routed to this relationship if the database cannot be updated but attempting the operation again may succeed
success Successfully created FlowFile from SQL query result set.
Name Description
putdatabaserecord.error If an error occurs during processing, the flow file will be routed to failure or retry, and this attribute will be populated with the cause of the error.
Property Description
Databricks Client Databricks Client Service.
Default Catalog Default table catalog, some SQL statements such as 'COPY INTO' do not support using a default catalog
Default Schema Default table schema, some SQL statements such as 'COPY INTO' do not support using a default schema
Record Writer Specifies the Controller Service to use for writing results to a FlowFile. The Record Writer may use Inherit Schema to emulate the inferred schema behavior, i.e. an explicit schema need not be defined in the writer, and will be supplied by the same logic used to infer the schema from the column types.
SQL Warehouse ID Warehouse ID used to execute SQL
SQL Warehouse Name SQL Warehouse Name used to execute SQL, will search through all SQL Warehouses to find matching name.
Statement SQL statement to execute
Name Description
failure Databricks failure relationship
http.response HTTP Response to SQL API Request
original The original FlowFile is routed to this relationship when processing is successful.
records Serialized SQL Records
Name Description
statement.state The final state of the executed SQL statement
error.code The error code for the SQL statement if an error occurred.
error.message The error message for the SQL statement if an error occurred.
Property Description
DBFS File Path DBFS file path e.g. /directory/file.txt
Databricks Client Databricks Client Service.
Overwrite Policy What action to take if a file already exists at the destination path.
Name Description
failure Databricks failure relationship
success Databricks success relationship
Name Description
error.code The error code for the SQL statement if an error occurred.
error.message The error message for the SQL statement if an error occurred.
Property Description
Cache Entry Identifier A FlowFile attribute, or the results of an Attribute Expression Language statement, which will be evaluated against a FlowFile in order to determine the cache key
Cache update strategy Determines how the cache is updated if the cache already contains the entry
Distributed Cache Service The Controller Service that is used to cache flow files
Max cache entry size The maximum amount of data to put into cache
Name Description
failure Any FlowFile that cannot be inserted into the cache will be routed to this relationship
success Any FlowFile that is successfully inserted into cache will be routed to this relationship
Name Description
cached All FlowFiles will have an attribute 'cached'. The value of this attribute is true, is the FlowFile is cached, otherwise false.
Property Description
Chunked Upload Size Defines the size of a chunk. Used when a FlowFile 's size exceeds'Chunked Upload Threshold 'and content is uploaded in smaller chunks. It is recommended to specify chunked upload size smaller than'Chunked Upload Threshold' and as multiples of 4 MB. Maximum allowed value is 150 MB.
Chunked Upload Threshold The maximum size of the content which is uploaded at once. FlowFiles larger than this threshold are uploaded in chunks. Maximum allowed value is 150 MB.
Conflict Resolution Strategy Indicates what should happen when a file with the same name already exists in the specified Dropbox folder.
Dropbox Credential Service Controller Service used to obtain Dropbox credentials (App Key, App Secret, Access Token, Refresh Token). See controller service's Additional Details for more information.
Filename The full name of the file to upload.
Folder The path of the Dropbox folder to upload files to. The folder will be created if it does not exist yet.
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
failure Files that could not be written to Dropbox for some reason are transferred to this relationship.
success Files that have been successfully written to Dropbox are transferred to this relationship.
Name Description
error.message The error message returned by Dropbox
dropbox.id The Dropbox identifier of the file
path The folder path where the file is located
filename The name of the file
dropbox.size The size of the file
dropbox.timestamp The server modified time of the file
dropbox.revision Revision of the file
Property Description
AWS Credentials Provider service The Controller Service that is used to obtain AWS credentials provider
Batch items for each request (between 1 and 50) The items to be retrieved in one batch
Character set of document Character set of data in the document
Communications Timeout
Endpoint Override URL Endpoint URL to use instead of the AWS default including scheme, host, port, and path. The AWS libraries select an endpoint URL based on the AWS region, but this property overrides the selected endpoint URL, allowing use with other S3-compatible endpoints.
Hash Key Name The hash key name of the item
Hash Key Value The hash key value of the item
Hash Key Value Type The hash key value type of the item
Json Document attribute The Json document to be retrieved from the dynamodb item ( 's' type in the schema)
Range Key Name The range key name of the item
Range Key Value
Range Key Value Type The range key value type of the item
Region
SSL Context Service Specifies an optional SSL Context Service that, if provided, will be used to create connections
Table Name The DynamoDB table name
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
failure FlowFiles are routed to failure relationship
success FlowFiles are routed to success relationship
unprocessed FlowFiles are routed to unprocessed relationship when DynamoDB is not able to process all the items in the request. Typical reasons are insufficient table throughput capacity and exceeding the maximum bytes per request. Unprocessed FlowFiles can be retried with a new request.
Name Description
dynamodb.key.error.unprocessed DynamoDB unprocessed keys
dynmodb.range.key.value.error DynamoDB range key error
dynamodb.key.error.not.found DynamoDB key not found
dynamodb.error.exception.message DynamoDB exception message
dynamodb.error.code DynamoDB error code
dynamodb.error.message DynamoDB error message
dynamodb.error.service DynamoDB error service
dynamodb.error.retryable DynamoDB error is retryable
dynamodb.error.request.id DynamoDB error request id
dynamodb.error.status.code DynamoDB error status code
dynamodb.item.io.error IO exception message on creating item
Property Description
AWS Credentials Provider service The Controller Service that is used to obtain AWS credentials provider
Communications Timeout
Endpoint Override URL Endpoint URL to use instead of the AWS default including scheme, host, port, and path. The AWS libraries select an endpoint URL based on the AWS region, but this property overrides the selected endpoint URL, allowing use with other S3-compatible endpoints.
Partition Key Attribute Specifies the FlowFile attribute that will be used as the value of the partition key when using "Partition by attribute" partition key strategy.
Partition Key Field Defines the name of the partition key field in the DynamoDB table. Partition key is also known as hash key. Depending on the "Partition Key Strategy" the field value might come from the incoming Record or a generated one.
Partition Key Strategy Defines the strategy the processor uses to assign partition key value to the inserted Items.
Record Reader Specifies the Controller Service to use for parsing incoming data and determining the data's schema.
Region
SSL Context Service Specifies an optional SSL Context Service that, if provided, will be used to create connections
Sort Key Field Defines the name of the sort key field in the DynamoDB table. Sort key is also known as range key.
Sort Key Strategy Defines the strategy the processor uses to assign sort key to the inserted Items.
Table Name The DynamoDB table name
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
failure FlowFiles are routed to failure relationship
success FlowFiles are routed to success relationship
unprocessed FlowFiles are routed to unprocessed relationship when DynamoDB is not able to process all the items in the request. Typical reasons are insufficient table throughput capacity and exceeding the maximum bytes per request. Unprocessed FlowFiles can be retried with a new request.
Name Description
dynamodb.chunks.processed Number of chunks successfully inserted into DynamoDB. If not set, it is considered as 0
dynamodb.key.error.unprocessed DynamoDB unprocessed keys
dynmodb.range.key.value.error DynamoDB range key error
dynamodb.key.error.not.found DynamoDB key not found
dynamodb.error.exception.message DynamoDB exception message
dynamodb.error.code DynamoDB error code
dynamodb.error.message DynamoDB error message
dynamodb.error.service DynamoDB error service
dynamodb.error.retryable DynamoDB error is retryable
dynamodb.error.request.id DynamoDB error request id
dynamodb.error.status.code DynamoDB error status code
dynamodb.item.io.error IO exception message on creating item
Property Description
Batch Size The preferred number of FlowFiles to send over in a single batch
Character Set Specifies the character set of the document data.
Client Service An Elasticsearch client service to use for running queries.
Dynamic Templates The dynamic_templates for the document. Must be parsable as a JSON Object. Requires Elasticsearch 7+
Identifier Attribute The name of the FlowFile attribute containing the identifier for the document. If the Index Operation is "index", this property may be left empty or evaluate to an empty value, in which case the document's identifier will be auto-generated by Elasticsearch. For all other Index Operations, the attribute must evaluate to a non-empty value.
Index The name of the index to use.
Index Operation The type of the operation used to index (create, delete, index, update, upsert)
Log Error Responses If this is enabled, errors will be logged to the NiFi logs at the error log level. Otherwise, they will only be logged if debug logging is enabled on NiFi as a whole. The purpose of this option is to give the user the ability to debug failed operations without having to turn on debug logging.
Max JSON Field String Length The maximum allowed length of a string value when parsing a JSON document or attribute.
Output Error Responses If this is enabled, response messages from Elasticsearch marked as "error" will be output to the "error_responses" relationship. This does not impact the output of flowfiles to the "successful" or "errors" relationships
Script The script for the document update/upsert. Only applies to Update/Upsert operations. Must be parsable as JSON Object. If left blank, the FlowFile content will be used for document update/upsert
Scripted Upsert Whether to add the scripted_upsert flag to the Upsert Operation. If true, forces Elasticsearch to execute the Script whether or not the document exists, defaults to false. If the Upsert Document provided (from FlowFile content) will be empty, but sure to set the Client Service controller service's Suppress Null and Empty Values to Never Suppress or no "upsert" doc will be, included in the request to Elasticsearch and the operation will not create a new document for the script to execute against, resulting in a "not_found" error
Treat Not Found as Success If true, "not_found" Elasticsearch Document associated Records will be routed to the "successful" relationship, otherwise to the "errors" relationship. If Output Error Responses is "true" then "not_found" responses from Elasticsearch will be sent to the error_responses relationship.
Type The type of this document (used by Elasticsearch for indexing and searching).
Name Description
errors Record(s)/Flowfile(s) corresponding to Elasticsearch document(s) that resulted in an "error" (within Elasticsearch) will be routed here.
failure All flowfiles that fail for reasons unrelated to server availability go to this relationship.
original All flowfiles that are sent to Elasticsearch without request failures go to this relationship.
retry All flowfiles that fail due to server/cluster availability go to this relationship.
successful Record(s)/Flowfile(s) corresponding to Elasticsearch document(s) that did not result in an "error" (within Elasticsearch) will be routed here.
Name Description
elasticsearch.put.error The error message if there is an issue parsing the FlowFile, sending the parsed document to Elasticsearch or parsing the Elasticsearch response
elasticsearch.bulk.error The _bulk response if there was an error during processing the document within Elasticsearch.
Property Description
Batch Size The number of records to send over in a single batch.
Client Service An Elasticsearch client service to use for running queries.
Date Format Specifies the format to use when writing Date fields. If not specified, the default format 'yyyy-MM-dd' is used. If specified, the value must match the Java Simple Date Format (for example, MM/dd/yyyy for a two-digit month, followed by a two-digit day, followed by a four-digit year, all separated by '/' characters, as in 01/25/2017).
Dynamic Templates Record Path A RecordPath pointing to a field in the record(s) that contains the dynamic_templates for the document. Field must be Map-type compatible (e.g. a Map or Record) or a String parsable into a JSON Object. Requires Elasticsearch 7+
Group Results by Bulk Error Type The errored records written to the "errors" relationship will be grouped by error type and the error related to the first record within the FlowFile added to the FlowFile as "elasticsearch.bulk.error". If "Treat Not Found as Success" is "false" then records associated with "not_found" Elasticsearch document responses will also be send to the "errors" relationship.
ID Record Path A record path expression to retrieve the ID field for use with Elasticsearch. If left blank the ID will be automatically generated by Elasticsearch.
Index The name of the index to use.
Index Operation The type of the operation used to index (create, delete, index, update, upsert)
Index Operation Record Path A record path expression to retrieve the Index Operation field for use with Elasticsearch. If left blank the Index Operation will be determined using the main Index Operation property.
Index Record Path A record path expression to retrieve the index field for use with Elasticsearch. If left blank the index will be determined using the main index property.
Log Error Responses If this is enabled, errors will be logged to the NiFi logs at the error log level. Otherwise, they will only be logged if debug logging is enabled on NiFi as a whole. The purpose of this option is to give the user the ability to debug failed operations without having to turn on debug logging.
Max JSON Field String Length The maximum allowed length of a string value when parsing a JSON document or attribute.
Output Error Responses If this is enabled, response messages from Elasticsearch marked as "error" will be output to the "error_responses" relationship. This does not impact the output of flowfiles to the "successful" or "errors" relationships
Record Reader The record reader to use for reading incoming records from flowfiles.
Result Record Writer The response from Elasticsearch will be examined for failed records and the failed records will be written to a record set with this record writer service and sent to the "errors" relationship. Successful records will be written to a record set with this record writer service and sent to the "successful" relationship.
Retain ID (Record Path) Whether to retain the existing field used as the ID Record Path.
Retain Record Timestamp Whether to retain the existing field used as the @timestamp Record Path.
Script Record Path A RecordPath pointing to a field in the record(s) that contains the script for the document update/upsert. Only applies to Update/Upsert operations. Field must be Map-type compatible (e.g. a Map or a Record) or a String parsable into a JSON Object
Scripted Upsert Record Path A RecordPath pointing to a field in the record(s) that contains the scripted_upsert boolean flag. Whether to add the scripted_upsert flag to the Upsert Operation. Forces Elasticsearch to execute the Script whether or not the document exists, defaults to false. If the Upsert Document provided (from FlowFile content) will be empty, but sure to set the Client Service controller service's Suppress Null and Empty Values to Never Suppress or no "upsert" doc will be, included in the request to Elasticsearch and the operation will not create a new document for the script to execute against, resulting in a "not_found" error
Time Format Specifies the format to use when writing Time fields. If not specified, the default format 'HH:mm:ss' is used. If specified, the value must match the Java Simple Date Format (for example, HH:mm:ss for a two-digit hour in 24-hour format, followed by a two-digit minute, followed by a two-digit second, all separated by ':' characters, as in 18:04:15).
Timestamp Format Specifies the format to use when writing Timestamp fields. If not specified, the default format 'yyyy-MM-dd HH:mm:ss' is used. If specified, the value must match the Java Simple Date Format (for example, MM/dd/yyyy HH:mm:ss for a two-digit month, followed by a two-digit day, followed by a four-digit year, all separated by '/' characters; and then followed by a two-digit hour in 24-hour format, followed by a two-digit minute, followed by a two-digit second, all separated by ':' characters, as in 01/25/2017 18:04:15).
Timestamp Record Path A RecordPath pointing to a field in the record(s) that contains the @timestamp for the document. If left blank the @timestamp will be determined using the main @timestamp property
Timestamp Value The value to use as the @timestamp field (required for Elasticsearch Data Streams)
Treat Not Found as Success If true, "not_found" Elasticsearch Document associated Records will be routed to the "successful" relationship, otherwise to the "errors" relationship. If Output Error Responses is "true" then "not_found" responses from Elasticsearch will be sent to the error_responses relationship.
Type The type of this document (used by Elasticsearch for indexing and searching).
Type Record Path A record path expression to retrieve the type field for use with Elasticsearch. If left blank the type will be determined using the main type property.
Name Description
errors Record(s)/Flowfile(s) corresponding to Elasticsearch document(s) that resulted in an "error" (within Elasticsearch) will be routed here.
failure All flowfiles that fail for reasons unrelated to server availability go to this relationship.
original All flowfiles that are sent to Elasticsearch without request failures go to this relationship.
retry All flowfiles that fail due to server/cluster availability go to this relationship.
successful Record(s)/Flowfile(s) corresponding to Elasticsearch document(s) that did not result in an "error" (within Elasticsearch) will be routed here.
Name Description
elasticsearch.put.error The error message if there is an issue parsing the FlowFile records, sending the parsed documents to Elasticsearch or parsing the Elasticsearch response.
elasticsearch.put.error.count The number of records that generated errors in the Elasticsearch _bulk API.
elasticsearch.put.success.count The number of records that were successfully processed by the Elasticsearch _bulk API.
elasticsearch.bulk.error The _bulk response if there was an error during processing the record within Elasticsearch.
Property Description
Attach File Specifies whether or not the FlowFile content should be attached to the email
BCC The recipients to include in the BCC-Line of the email. Comma separated sequence of addresses following RFC822 syntax.
CC The recipients to include in the CC-Line of the email. Comma separated sequence of addresses following RFC822 syntax.
Content Type Mime Type used to interpret the contents of the email, such as text/plain or text/html
From Specifies the Email address to use as the sender. Comma separated sequence of addresses following RFC822 syntax.
Include All Attributes In Message Specifies whether or not all FlowFile attributes should be recorded in the body of the email message
Message The body of the email message
Reply-To The recipients that will receive the reply instead of the from (see RFC2822 §3.6.2).This feature is useful, for example, when the email is sent by a no-reply account. This field is optional. Comma separated sequence of addresses following RFC822 syntax.
SMTP Auth Flag indicating whether authentication should be used
SMTP Hostname The hostname of the SMTP host
SMTP Password Password for the SMTP account
SMTP Port The Port used for SMTP communications
SMTP Socket Factory Socket Factory to use for SMTP Connection
SMTP TLS Flag indicating whether Opportunistic TLS should be enabled using STARTTLS command
SMTP Username Username for the SMTP account
SMTP X-Mailer Header X-Mailer used in the header of the outgoing email
Subject The email subject
To The recipients to include in the To-Line of the email. Comma separated sequence of addresses following RFC822 syntax.
attribute-name-regex A Regular Expression that is matched against all FlowFile attribute names. Any attribute whose name matches the regex will be added to the Email messages as a Header. If not specified, no FlowFile attributes will be added as headers.
authorization-mode How to authorize sending email on the user's behalf.
email-ff-content-as-message Specifies whether or not the FlowFile content should be the message of the email. If true, the 'Message' property is ignored.
input-character-set Specifies the character set of the FlowFile contents for reading input FlowFile contents to generate the message body or as an attachment to the message. If not set, UTF-8 will be the default value.
oauth2-access-token-provider OAuth2 service that can provide access tokens.
Name Description
failure FlowFiles that fail to send will be routed to this relationship
success FlowFiles that are successfully sent will be routed to this relationship
Property Description
Conflict Resolution Strategy Indicates what should happen when a file with the same name already exists in the output directory
Create Missing Directories If true, then missing destination directories will be created. If false, flowfiles are penalized and sent to failure.
Directory The directory to which files should be written. You may use expression language such as /aa/bb/$\{path\}
Group Sets the group on the output file to the value of this attribute. You may also use expression language such as $\{file.group\}.
Last Modified Time Sets the lastModifiedTime on the output file to the value of this attribute. Format must be yyyy-MM-dd 'T'HH:mm:ssZ. You may also use expression language such as $\{file.lastModifiedTime\}.
Maximum File Count Specifies the maximum number of files that can exist in the output directory
Owner Sets the owner on the output file to the value of this attribute. You may also use expression language such as $\{file.owner\}. Note on many operating systems NiFi must be running as a super-user to have the permissions to set the file owner.
Permissions Sets the permissions on the output file to the value of this attribute. Format must be either UNIX rwxrwxrwx with a - in place of denied permissions (e.g. rw-r–r–) or an octal number (e.g. 644). You may also use expression language such as $\{file.permissions\}.
Required Permission Explanation
write filesystem Provides operator the ability to write to any file that NiFi has access to.
Name Description
failure Files that could not be written to the output directory for some reason are transferred to this relationship
success Files that have been successfully written to the output directory are transferred to this relationship
Property Description
Batch Size The maximum number of FlowFiles to send in a single connection
Conflict Resolution Determines how to handle the problem of filename collisions
Connection Mode The FTP Connection Mode
Connection Timeout Amount of time to wait before timing out while creating a connection
Create Directory Specifies whether or not the remote directory should be created if it does not exist.
Data Timeout When transferring a file between the local and remote system, this value specifies how long is allowed to elapse without any data being transferred between systems
Dot Rename If true, then the filename of the sent file is prepended with a "." and then renamed back to the original once the file is completely sent. Otherwise, there is no rename. This property is ignored if the Temporary Filename property is set.
Hostname The fully qualified hostname or IP address of the remote system
Internal Buffer Size Set the internal buffer size for buffered data streams
Last Modified Time The lastModifiedTime to assign to the file after transferring it. If not set, the lastModifiedTime will not be changed. Format must be yyyy-MM-dd 'T'HH:mm:ssZ. You may also use expression language such as $\{file.lastModifiedTime\}. If the value is invalid, the processor will not be invalid but will fail to change lastModifiedTime of the file.
Password Password for the user account
Permissions The permissions to assign to the file after transferring it. Format must be either UNIX rwxrwxrwx with a - in place of denied permissions (e.g. rw-r–r–) or an octal number (e.g. 644). If not set, the permissions will not be changed. You may also use expression language such as $\{file.permissions\}. If the value is invalid, the processor will not be invalid but will fail to change permissions of the file.
Port The port that the remote system is listening on for file transfers
Reject Zero-Byte Files Determines whether or not Zero-byte files should be rejected without attempting to transfer
Remote Path The path on the remote system from which to pull or push files
Temporary Filename If set, the filename of the sent file will be equal to the value specified during the transfer and after successful completion will be renamed to the original filename. If this value is set, the Dot Rename property is ignored.
Transfer Mode The FTP Transfer Mode
Use Compression Indicates whether or not ZLIB compression should be used when transferring files
Username Username
ftp-use-utf8 Tells the client to use UTF-8 encoding when processing files and filenames. If set to true, the server must also support UTF-8 encoding.
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
failure FlowFiles that failed to send to the remote system; failure is usually looped back to this processor
reject FlowFiles that were rejected by the destination system
success FlowFiles that are successfully sent will be routed to success
Property Description
File Resource Service File Resource Service providing access to the local resource to be transferred
GCP Credentials Provider Service The Controller Service used to obtain Google Cloud Platform credentials.
Resource Transfer Source The source of the content to be transferred
gcp-project-id Google Cloud Project ID
gcp-retry-count How many retry attempts should be made before routing to the failure relationship.
gcs-bucket Bucket of the object.
gcs-content-disposition-type Type of RFC-6266 Content Disposition to be attached to the object
gcs-content-type Content Type for the file, i.e. text/plain
gcs-key Name of the object.
gcs-object-acl Access Control to be attached to the object uploaded. Not providing this will revert to bucket defaults.
gcs-object-crc32c CRC32C Checksum (encoded in Base64, big-Endian order) of the file for server-side validation.
gcs-overwrite-object If false, the upload to GCS will succeed only if the object does not exist.
gcs-server-side-encryption-key An AES256 Encryption Key (encoded in base64) for server-side encryption of the object.
gzip.content.enabled Signals to the GCS Blob Writer whether GZIP compression during transfer is desired. False means do not gzip and can boost performance in many cases.
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
storage-api-url Overrides the default storage URL. Configuring an alternative Storage API URL also overrides the HTTP Host header on requests as described in the Google documentation for Private Service Connections.
Name Description
failure FlowFiles are routed to this relationship if the Google Cloud Storage operation fails.
success FlowFiles are routed to this relationship after a successful Google Cloud Storage operation.
Name Description
gcs.bucket Bucket of the object.
gcs.key Name of the object.
gcs.size Size of the object.
gcs.cache.control Data cache control of the object.
gcs.component.count The number of components which make up the object.
gcs.content.disposition The data content disposition of the object.
gcs.content.encoding The content encoding of the object.
gcs.content.language The content language of the object.
mime.type The MIME/Content-Type of the object
gcs.crc32c The CRC32C checksum of object's data, encoded in base64 in big-endian order.
gcs.create.time The creation time of the object (milliseconds)
gcs.update.time The last modification time of the object (milliseconds)
gcs.encryption.algorithm The algorithm used to encrypt the object.
gcs.encryption.sha256 The SHA256 hash of the key used to encrypt the object
gcs.etag The HTTP 1.1 Entity tag for the object.
gcs.generated.id The service-generated for the object
gcs.generation The data generation of the object.
gcs.md5 The MD5 hash of the object's data encoded in base64.
gcs.media.link The media download link to the object.
gcs.metageneration The metageneration of the object.
gcs.owner The owner (uploader) of the object.
gcs.owner.type The ACL entity type of the uploader of the object.
gcs.uri The URI of the object as a string.
Property Description
chunked-upload-size Defines the size of a chunk. Used when a FlowFile 's size exceeds'Chunked Upload Threshold' and content is uploaded in smaller chunks. Minimum allowed chunk size is 256 KB, maximum allowed chunk size is 1 GB.
chunked-upload-threshold The maximum size of the content which is uploaded at once. FlowFiles larger than this threshold are uploaded in chunks.
conflict-resolution-strategy Indicates what should happen when a file with the same name already exists in the specified Google Drive folder.
connect-timeout Maximum wait time for connection to Google Drive service.
file-name The name of the file to upload to the specified Google Drive folder.
folder-id The ID of the shared folder. Please see Additional Details to set up access to Google Drive and obtain Folder ID.
gcp-credentials-provider-service The Controller Service used to obtain Google Cloud Platform credentials.
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
read-timeout Maximum wait time for response from Google Drive service.
Name Description
failure Files that could not be written to Google Drive for some reason are transferred to this relationship.
success Files that have been successfully written to Google Drive are transferred to this relationship.
Name Description
drive.id The id of the file
filename The name of the file
mime.type The MIME type of the file
drive.size The size of the file. Set to 0 when the file size is not available (e.g. externally stored files).
drive.size.available Indicates if the file size is known / available
drive.timestamp The last modified time or created time (whichever is greater) of the file. The reason for this is that the original modified date of a file is preserved when uploaded to Google Drive. 'Created time' takes the time when the upload occurs. However uploaded files can still be modified later.
drive.created.time The file's creation time
drive.modified.time The file's last modification time
error.code The error code returned by Google Drive
error.message The error message returned by Google Drive
Property Description
gridfs-bucket-name The GridFS bucket where the files will be stored. If left blank, it will use the default value 'fs' that the MongoDB client driver uses.
gridfs-client-service The MongoDB client service to use for database connections.
gridfs-database-name The name of the database to use
gridfs-file-name The name of the file in the bucket that is the target of this processor. GridFS file names do not include path information because GridFS does not sort files into folders within a bucket.
putgridfs-chunk-size Controls the maximum size of each chunk of a file uploaded into GridFS.
putgridfs-enforce-uniqueness When enabled, this option will ensure that uniqueness is enforced on the bucket. It will do so by creating a MongoDB index that matches your selection. It should ideally be configured once when the bucket is created for the first time because it could take a long time to build on an existing bucket wit a lot of data.
putgridfs-hash-attribute If uniquness enforcement is enabled and the file hash is part of the constraint, this must be set to an attribute that exists on all incoming flowfiles.
putgridfs-properties-prefix Attributes that have this prefix will be added to the file stored in GridFS as metadata.
Name Description
duplicate Flowfiles that fail the duplicate check are sent to this relationship.
failure When there is a failure processing the flowfile, it goes to this relationship.
success When the operation succeeds, the flowfile is sent to this relationship.
Property Description
Associated Object ID Property Target HubSpot property used to uniquely identify the object to associate to from the configured object.
Associated Object ID Value Target HubSpot property value for the 'Associated Object ID Property' to associate to from the configured object.
Associated Object Type Target HubSpot object type to associate to from the configured object.
Association Type ID The HubSpot defined association id from the 'Object ID Value' to the 'Associated Object ID Value'.
HubSpot Service HubSpot Client Service.
Inverse Association Type ID The HubSpot defined association id from the 'Associated Object ID Value' to the 'Object ID Value'.
Missing HubSpot Property Policy What to action to take if HubSpot does not have a matching property.
Object ID Property HubSpot property used to uniquely identify the object.
Object ID Value Matching HubSpot property value to search for.
Object Override Properties Comma-delimited list of NiFi attributes, which if exist, will be added as object properties. Any existing properties in HubSpot will be overridden.
Object Set Properties Comma-delimited list of NiFi attributes, which if exist, will be added as object properties if the current object property in HubSpot is empty.
Object Type HubSpot object type
Name Description
failure HubSpot fail relationship
retry HubSpot retry relationship. FlowFiles that failed to process due to a server timeout or rate limit related error. FlowFiles routed here should be routed back into the processor.
success HubSpot success relationship
Property Description
Iceberg Catalog Provider Service for Iceberg Catalog
Iceberg Writer Provider Service for Iceberg Row Writers responsible for producing formatted Iceberg Data Files
Namespace Iceberg Namespace containing Tables
Record Reader Record Reader for incoming FlowFiles
Table Name Iceberg Table Name
Name Description
failure FlowFiles not transferred to Iceberg
success FlowFiles transferred to Iceberg
Property Description
AWS Credentials Provider service The Controller Service that is used to obtain AWS credentials provider
Amazon Kinesis Firehose Delivery Stream Name The name of kinesis firehose delivery stream
Batch Size Batch size for messages (1-500).
Communications Timeout
Endpoint Override URL Endpoint URL to use instead of the AWS default including scheme, host, port, and path. The AWS libraries select an endpoint URL based on the AWS region, but this property overrides the selected endpoint URL, allowing use with other S3-compatible endpoints.
Max message buffer size Max message buffer
Region
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
failure FlowFiles are routed to failure relationship
success FlowFiles are routed to success relationship
Name Description
aws.kinesis.firehose.error.message Error message on posting message to AWS Kinesis Firehose
aws.kinesis.firehose.error.code Error code for the message when posting to AWS Kinesis Firehose
aws.kinesis.firehose.record.id Record id of the message posted to Kinesis Firehose
Property Description
AWS Credentials Provider service The Controller Service that is used to obtain AWS credentials provider
Communications Timeout
Endpoint Override URL Endpoint URL to use instead of the AWS default including scheme, host, port, and path. The AWS libraries select an endpoint URL based on the AWS region, but this property overrides the selected endpoint URL, allowing use with other S3-compatible endpoints.
Max Message Buffer Size Max message buffer size defined with standard data size units
Message Batch Size Batch size for messages (1-500).
Region
Stream Name The name of Kinesis Stream
Stream Partition Key The partition key attribute. If it is not set, a random value is used
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
failure FlowFiles are routed to failure relationship
success FlowFiles are routed to success relationship
Name Description
aws.kinesis.error.message Error message on posting message to AWS Kinesis
aws.kinesis.error.code Error code for the message when posting to AWS Kinesis
aws.kinesis.sequence.number Sequence number for the message when posting to AWS Kinesis
aws.kinesis.shard.id Shard id of the message posted to AWS Kinesis
Property Description
AWS Credentials Provider service The Controller Service that is used to obtain AWS credentials provider
Amazon Lambda Name The Lambda Function Name
Amazon Lambda Qualifier (version) The Lambda Function Version
Communications Timeout
Endpoint Override URL Endpoint URL to use instead of the AWS default including scheme, host, port, and path. The AWS libraries select an endpoint URL based on the AWS region, but this property overrides the selected endpoint URL, allowing use with other S3-compatible endpoints.
Region
SSL Context Service Specifies an optional SSL Context Service that, if provided, will be used to create connections
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
failure FlowFiles are routed to failure relationship
success FlowFiles are routed to success relationship
Name Description
aws.lambda.result.function.error Function error message in result on posting message to AWS Lambda
aws.lambda.result.status.code Status code in the result for the message when posting to AWS Lambda
aws.lambda.result.payload Payload in the result from AWS Lambda
aws.lambda.result.log Log in the result of the message posted to Lambda
aws.lambda.exception.message Exception message on invoking from AWS Lambda
aws.lambda.exception.cause Exception cause on invoking from AWS Lambda
aws.lambda.exception.error.code Exception error code on invoking from AWS Lambda
aws.lambda.exception.request.id Exception request id on invoking from AWS Lambda
aws.lambda.exception.status.code Exception status code on invoking from AWS Lambda
Property Description
Character Set The Character Set in which the data is encoded
Mode Indicates whether the processor should insert or update content
Mongo Collection Name The name of the collection to use
Mongo Database Name The name of the database to use
Update Method MongoDB method for running collection update operations, such as updateOne or updateMany
Update Query Key One or more comma-separated document key names used to build the update query criteria, such as _id
Upsert When true, inserts a document if no document matches the update query criteria; this property is valid only when using update mode, otherwise it is ignored
mongo-client-service If configured, this property will use the assigned client service for connection pooling.
put-mongo-update-mode Choose an update mode. You can either supply a JSON document to use as a direct replacement or specify a document that contains update operators like $set, $unset, and $inc. When Operators mode is enabled, the flowfile content is expected to be the operator part for example: \{$set:\{"key": "value"\},$inc:\{"count":1234\}\} and the update query will come from the configured Update Query property.
putmongo-update-query Specify a full MongoDB query to be used for the lookup query to do an update/upsert. NOTE: this field is ignored if the 'Update Query Key' value is not empty.
Name Description
failure All FlowFiles that cannot be written to MongoDB are routed to this relationship
success All FlowFiles that are written to MongoDB are routed to this relationship
Name Description
mongo.put.update.match.count The match count from result if update/upsert is performed, otherwise not set.
mongo.put.update.modify.count The modify count from result if update/upsert is performed, otherwise not set.
mongo.put.upsert.id The '_id' hex value if upsert is performed, otherwise not set.
Property Description
Character Set The Character Set in which the data is encoded
Mongo Collection Name The name of the collection to use
Mongo Database Name The name of the database to use
Ordered Ordered execution of bulk-writes and break on error - otherwise arbitrary order and continue on error
mongo-client-service If configured, this property will use the assigned client service for connection pooling.
Name Description
failure All FlowFiles that cannot be written to MongoDB are routed to this relationship
success All FlowFiles that are written to MongoDB are routed to this relationship
Property Description
Mongo Collection Name The name of the collection to use
Mongo Database Name The name of the database to use
bypass-validation Enable or disable bypassing document schema validation during insert or update operations. Bypassing document validation is a Privilege Action in MongoDB. Enabling this property can result in authorization errors for users with limited privileges.
insert_count The number of records to group together for one single insert/upsert operation against MongoDB.
mongo-client-service If configured, this property will use the assigned client service for connection pooling.
ordered Perform ordered or unordered operations
record-reader Specifies the Controller Service to use for parsing incoming data and determining the data's schema
update-key-fields Comma separated list of fields based on which to identify documents that need to be updated. If this property is set NiFi will attempt an upsert operation on all documents. If this property is not set all documents will be inserted.
update-mode Choose between updating a single document or multiple documents per incoming record.
Name Description
failure All FlowFiles that cannot be written to MongoDB are routed to this relationship
success All FlowFiles that are written to MongoDB are routed to this relationship
Property Description
put-record-include-zero-record-results If no records are read from the incoming FlowFile, this property specifies whether or not an empty record set will be transmitted. The original FlowFile will still be routed to success, but if no transmission occurs, no provenance SEND event will be generated.
put-record-reader Specifies the Controller Service to use for reading incoming data
put-record-sink Specifies the Controller Service to use for writing out the query result records to some destination.
Name Description
failure A FlowFile is routed to this relationship if the records could not be transmitted and retrying the operation will also fail
retry The original FlowFile is routed to this relationship if the records could not be transmitted but attempting the operation again may succeed
success The original FlowFile will be routed to this relationship if the records were transmitted successfully
Property Description
charset Specifies the character set to use when storing record field values as strings. All fields will be converted to strings using this character set before being stored in Redis.
data-record-path This property denotes a RecordPath that will be evaluated against each incoming Record and the Record that results from evaluating the RecordPath will be sent to Redis instead of sending the entire incoming Record. The property defaults to the root '/' which corresponds to a 'flat' record (all fields/values at the top level of the Record.
hash-value-record-path Specifies a RecordPath to evaluate against each Record in order to determine the hash value associated with all the record fields/values (see 'hset' in Redis documentation for more details). The RecordPath must point at exactly one field or an error will occur.
record-reader Specifies the Controller Service to use for parsing incoming data and determining the data's schema
redis-connection-pool
Name Description
failure FlowFiles containing Records with processing errors will be routed to this relationship
success FlowFiles having all Records stored in Redis will be routed to this relationship
Name Description
redis.success.record.count Number of records written to Redis
Property Description
AWS Credentials Provider service The Controller Service that is used to obtain AWS credentials provider
Bucket The S3 Bucket to interact with
Cache Control Sets the Cache-Control HTTP header indicating the caching directives of the associated object. Multiple directives are comma-separated.
Canned ACL Amazon Canned ACL for an object, one of: BucketOwnerFullControl, BucketOwnerRead, LogDeliveryWrite, AuthenticatedRead, PublicReadWrite, PublicRead, Private; will be ignored if any other ACL/permission/owner property is specified
Communications Timeout The amount of time to wait in order to establish a connection to AWS or receive data from AWS before timing out.
Content Disposition Sets the Content-Disposition HTTP header indicating if the content is intended to be displayed inline or should be downloaded. Possible values are 'inline' or 'attachment'. If this property is not specified, object 's content-disposition will be set to filename. When' attachment 'is selected,'; filename='plus object key are automatically appended to form final value' attachment; filename="filename.jpg"'.
Content Type Sets the Content-Type HTTP header indicating the type of content stored in the associated object. The value of this header is a standard MIME type. AWS S3 Java client will attempt to determine the correct content type if one hasn't been set yet. Users are responsible for ensuring a suitable content type is set when uploading streams. If no content type is provided and cannot be determined by the filename, the default content type "application/octet-stream" will be used.
Custom Signer Class Name Fully qualified class name of the custom signer class. The signer must implement com.amazonaws.auth. Signer interface.
Custom Signer Module Location Comma-separated list of paths to files and/or directories which contain the custom signer's JAR file and its dependencies (if any).
Encryption Service Specifies the Encryption Service Controller used to configure requests. PutS3Object: For backward compatibility, this value is ignored when 'Server Side Encryption' is set. FetchS3Object: Only needs to be configured in case of Server-side Customer Key, Client-side KMS and Client-side Customer Key encryptions.
Endpoint Override URL Endpoint URL to use instead of the AWS default including scheme, host, port, and path. The AWS libraries select an endpoint URL based on the AWS region, but this property overrides the selected endpoint URL, allowing use with other S3-compatible endpoints.
Expiration Time Rule
File Resource Service File Resource Service providing access to the local resource to be transferred
FullControl User List A comma-separated list of Amazon User ID's or E-mail addresses that specifies who should have Full Control for an object
Multipart Part Size Specifies the part size for use when the PutS3Multipart Upload API is used. Flow files will be broken into chunks of this size for the upload process, but the last part sent can be smaller since it is not padded. The valid range is 50MB to 5GB.
Multipart Threshold Specifies the file size threshold for switch from the PutS3Object API to the PutS3MultipartUpload API. Flow files bigger than this limit will be sent using the stateful multipart process. The valid range is 50MB to 5GB.
Multipart Upload AgeOff Interval Specifies the interval at which existing multipart uploads in AWS S3 will be evaluated for ageoff. When processor is triggered it will initiate the ageoff evaluation if this interval has been exceeded.
Multipart Upload Max Age Threshold Specifies the maximum age for existing multipart uploads in AWS S3. When the ageoff process occurs, any upload older than this threshold will be aborted.
Object Key The S3 Object Key to use. This is analogous to a filename for traditional file systems.
Object Tags Prefix Specifies the prefix which would be scanned against the incoming FlowFile 's attributes and the matching attribute's name and value would be considered as the outgoing S3 object 's Tag name and Tag value respectively. For Ex: If the incoming FlowFile carries the attributes tagS3country, tagS3PII, the tag prefix to be specified would be' tagS3'
Owner The Amazon ID to use for the object's owner
Read ACL User List A comma-separated list of Amazon User ID's or E-mail addresses that specifies who should have permissions to read the Access Control List for an object
Read Permission User List A comma-separated list of Amazon User ID's or E-mail addresses that specifies who should have Read Access for an object
Region The AWS Region to connect to.
Remove Tag Prefix If set to 'True', the value provided for 'Object Tags Prefix' will be removed from the attribute(s) and then considered as the Tag name. For ex: If the incoming FlowFile carries the attributes tagS3country, tagS3PII and the prefix is set to 'tagS3' then the corresponding tag values would be 'country' and 'PII'
Resource Transfer Source The source of the content to be transferred
SSL Context Service Specifies an optional SSL Context Service that, if provided, will be used to create connections
Server Side Encryption Specifies the algorithm used for server side encryption.
Signer Override The AWS S3 library uses Signature Version 4 by default but this property allows you to specify the Version 2 signer to support older S3-compatible services or even to plug in your own custom signer implementation.
Storage Class
Temporary Directory Multipart State Directory in which, for multipart uploads, the processor will locally save the state tracking the upload ID and parts uploaded which must both be provided to complete the upload.
Use Chunked Encoding Enables / disables chunked encoding for upload requests. Set it to false only if your endpoint does not support chunked uploading.
Use Path Style Access Path-style access can be enforced by setting this property to true. Set it to true if your endpoint does not support virtual-hosted-style requests, only path-style requests.
Write ACL User List A comma-separated list of Amazon User ID's or E-mail addresses that specifies who should have permissions to change the Access Control List for an object
Write Permission User List A comma-separated list of Amazon User ID's or E-mail addresses that specifies who should have Write Access for an object
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
failure If the Processor is unable to process a given FlowFile, it will be routed to this Relationship.
success FlowFiles are routed to this Relationship after they have been successfully processed.
Name Description
s3.url The URL that can be used to access the S3 object
s3.bucket The S3 bucket where the Object was put in S3
s3.key The S3 key within where the Object was put in S3
s3.contenttype The S3 content type of the S3 Object that put in S3
s3.version The version of the S3 Object that was put to S3
s3.exception The class name of the exception thrown during processor execution
s3.additionalDetails The S3 supplied detail from the failed operation
s3.statusCode The HTTP error code (if available) from the failed operation
s3.errorCode The S3 moniker of the failed operation
s3.errorMessage The S3 exception message from the failed operation
s3.etag The ETag of the S3 Object
s3.contentdisposition The content disposition of the S3 Object that put in S3
s3.cachecontrol The cache-control header of the S3 Object
s3.uploadId The uploadId used to upload the Object to S3
s3.expiration A human-readable form of the expiration date of the S3 object, if one is set
s3.sseAlgorithm The server side encryption algorithm of the object
s3.usermetadata A human-readable form of the User Metadata of the S3 object, if any was set
s3.encryptionStrategy The name of the encryption strategy, if any was set
Property Description
oauth2-access-token-provider Service providing OAuth2 Access Tokens for authenticating using the HTTP Authorization Header
read-timeout Maximum time allowed for reading a response from the Salesforce REST API
record-reader Specifies the Controller Service to use for parsing incoming data and determining the data's schema
salesforce-api-version The version number of the Salesforce REST API appended to the URL after the services/data path. See Salesforce documentation for supported versions
salesforce-url The URL of the Salesforce instance including the domain without additional path information, such as https://MyDomainName.my.salesforce.com (https://MyDomainName.my.salesforce.com)
Name Description
failure For FlowFiles created as a result of an execution error.
success For FlowFiles created as a result of a successful execution.
Name Description
error.message The error message returned by Salesforce.
Property Description
Algorithm Negotiation Configuration strategy for SSH algorithm negotiation
Batch Size The maximum number of FlowFiles to send in a single connection
Ciphers Allowed A comma-separated list of Ciphers allowed for SFTP connections. Leave unset to allow all. Available options are: 3des-cbc, aes128-cbc, aes128-ctr, [aes128-gcm@openssh.com](mailto:aes128-gcm@openssh.com), aes192-cbc, aes192-ctr, aes256-cbc, aes256-ctr, [aes256-gcm@openssh.com](mailto:aes256-gcm@openssh.com), arcfour128, arcfour256, blowfish-cbc, [chacha20-poly1305@openssh.com](mailto:chacha20-poly1305@openssh.com), none
Conflict Resolution Determines how to handle the problem of filename collisions
Connection Timeout Amount of time to wait before timing out while creating a connection
Create Directory Specifies whether or not the remote directory should be created if it does not exist.
Data Timeout When transferring a file between the local and remote system, this value specifies how long is allowed to elapse without any data being transferred between systems
Disable Directory Listing If set to 'true', directory listing is not performed prior to create missing directories. By default, this processor executes a directory listing command to see target directory existence before creating missing directories. However, there are situations that you might need to disable the directory listing such as the following. Directory listing might fail with some permission setups (e.g. chmod 100) on a directory. Also, if any other SFTP client created the directory after this processor performed a listing and before a directory creation request by this processor is finished, then an error is returned because the directory already exists.
Dot Rename If true, then the filename of the sent file is prepended with a "." and then renamed back to the original once the file is completely sent. Otherwise, there is no rename. This property is ignored if the Temporary Filename property is set.
Host Key File If supplied, the given file will be used as the Host Key; otherwise, if 'Strict Host Key Checking' property is applied (set to true) then uses the 'known_hosts' and 'known_hosts2' files from ~/.ssh directory else no host key file will be used
Hostname The fully qualified hostname or IP address of the remote system
Key Algorithms Allowed A comma-separated list of Key Algorithms allowed for SFTP connections. Leave unset to allow all. Available options are: ecdsa-sha2-nistp256, [ecdsa-sha2-nistp256-cert-v01@openssh.com](mailto:ecdsa-sha2-nistp256-cert-v01@openssh.com), ecdsa-sha2-nistp384, [ecdsa-sha2-nistp384-cert-v01@openssh.com](mailto:ecdsa-sha2-nistp384-cert-v01@openssh.com), ecdsa-sha2-nistp521, [ecdsa-sha2-nistp521-cert-v01@openssh.com](mailto:ecdsa-sha2-nistp521-cert-v01@openssh.com), rsa-sha2-256, [rsa-sha2-256-cert-v01@openssh.com](mailto:rsa-sha2-256-cert-v01@openssh.com), rsa-sha2-512, [rsa-sha2-512-cert-v01@openssh.com](mailto:rsa-sha2-512-cert-v01@openssh.com), [sk-ecdsa-sha2-nistp256@openssh.com](mailto:sk-ecdsa-sha2-nistp256@openssh.com), [sk-ssh-ed25519@openssh.com](mailto:sk-ssh-ed25519@openssh.com), ssh-dss, [ssh-dss-cert-v01@openssh.com](mailto:ssh-dss-cert-v01@openssh.com), ssh-ed25519, [ssh-ed25519-cert-v01@openssh.com](mailto:ssh-ed25519-cert-v01@openssh.com), ssh-rsa, [ssh-rsa-cert-v01@openssh.com](mailto:ssh-rsa-cert-v01@openssh.com)
Key Exchange Algorithms Allowed A comma-separated list of Key Exchange Algorithms allowed for SFTP connections. Leave unset to allow all. Available options are: curve25519-sha256, [curve25519-sha256@libssh.org](mailto:curve25519-sha256@libssh.org), curve448-sha512, diffie-hellman-group-exchange-sha1, diffie-hellman-group-exchange-sha256, diffie-hellman-group1-sha1, diffie-hellman-group14-sha1, diffie-hellman-group14-sha256, diffie-hellman-group15-sha512, diffie-hellman-group16-sha512, diffie-hellman-group17-sha512, diffie-hellman-group18-sha512, ecdh-sha2-nistp256, ecdh-sha2-nistp384, ecdh-sha2-nistp521, mlkem1024nistp384-sha384, mlkem768nistp256-sha256, mlkem768x25519-sha256, sntrup761x25519-sha512, [sntrup761x25519-sha512@openssh.com](mailto:sntrup761x25519-sha512@openssh.com)
Last Modified Time The lastModifiedTime to assign to the file after transferring it. If not set, the lastModifiedTime will not be changed. Format must be yyyy-MM-dd 'T'HH:mm:ssZ. You may also use expression language such as $\{file.lastModifiedTime\}. If the value is invalid, the processor will not be invalid but will fail to change lastModifiedTime of the file.
Message Authentication Codes Allowed A comma-separated list of Message Authentication Codes allowed for SFTP connections. Leave unset to allow all. Available options are: hmac-md5, hmac-md5-96, hmac-sha1, hmac-sha1-96, [hmac-sha1-etm@openssh.com](mailto:hmac-sha1-etm@openssh.com), hmac-sha2-256, [hmac-sha2-256-etm@openssh.com](mailto:hmac-sha2-256-etm@openssh.com), hmac-sha2-512, [hmac-sha2-512-etm@openssh.com](mailto:hmac-sha2-512-etm@openssh.com)
Password Password for the user account
Permissions The permissions to assign to the file after transferring it. Format must be either UNIX rwxrwxrwx with a - in place of denied permissions (e.g. rw-r–r–) or an octal number (e.g. 644). If not set, the permissions will not be changed. You may also use expression language such as $\{file.permissions\}. If the value is invalid, the processor will not be invalid but will fail to change permissions of the file.
Port The port that the remote system is listening on for file transfers
Private Key Passphrase Password for the private key
Private Key Path The fully qualified path to the Private Key file
Reject Zero-Byte Files Determines whether or not Zero-byte files should be rejected without attempting to transfer
Remote Group Integer value representing the Group ID to set on the file after transferring it. If not set, the group will not be set. You may also use expression language such as $\{file.group\}. If the value is invalid, the processor will not be invalid but will fail to change the group of the file.
Remote Owner Integer value representing the User ID to set on the file after transferring it. If not set, the owner will not be set. You may also use expression language such as $\{file.owner\}. If the value is invalid, the processor will not be invalid but will fail to change the owner of the file.
Remote Path The path on the remote system from which to pull or push files
Send Keep Alive On Timeout Send a Keep Alive message every 5 seconds up to 5 times for an overall timeout of 25 seconds.
Strict Host Key Checking Indicates whether or not strict enforcement of hosts keys should be applied
Temporary Filename If set, the filename of the sent file will be equal to the value specified during the transfer and after successful completion will be renamed to the original filename. If this value is set, the Dot Rename property is ignored.
Use Compression Indicates whether or not ZLIB compression should be used when transferring files
Username Username
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
failure FlowFiles that failed to send to the remote system; failure is usually looped back to this processor
reject FlowFiles that were rejected by the destination system
success FlowFiles that are successfully sent will be routed to success
Property Description
Batch Size The maximum number of files to put in each iteration
Conflict Resolution Strategy Indicates what should happen when a file with the same name already exists in the output directory
Create Missing Directories If true, then missing destination directories will be created. If false, flowfiles are penalized and sent to failure.
Directory The network folder to which files should be written. This is the remaining relative path after the share: \hostnameshare[dir1dir2]. You may use expression language.
Domain The domain used for authentication. Optional, in most cases username and password is sufficient.
Hostname The network host to which files should be written.
Password The password used for authentication. Required if Username is set.
Share The network share to which files should be written. This is the "first folder"after the hostname: \hostname[share]dir1dir2
Share Access Strategy Indicates which shared access are granted on the file during the write. None is the most restrictive, but the safest setting to prevent corruption.
Temporary Suffix A temporary suffix which will be appended to the filename while it's transferring. After the transfer is complete, the suffix will be removed.
Username The username used for authentication. If no username is set then anonymous authentication is attempted.
enable-dfs Enables accessing Distributed File System (DFS) and following DFS links during SMB operations.
smb-dialect The SMB dialect is negotiated between the client and the server by default to the highest common version supported by both end. In some rare cases, the client-server communication may fail with the automatically negotiated dialect. This property can be used to set the dialect explicitly (e.g. to downgrade to a lower version), when those situations would occur.
timeout Timeout for read and write operations.
use-encryption Turns on/off encrypted communication between the client and the server. The property's behavior is SMB dialect dependent: SMB 2.x does not support encryption and the property has no effect. In case of SMB 3.x, it is a hint/request to the server to turn encryption on if the server also supports it.
Name Description
failure Files that could not be written to the output network path for some reason are transferred to this relationship
success Files that have been successfully written to the output network path are transferred to this relationship
Property Description
Compression Enabled Set true to compress data before uploading the file
Database The database to use by default. The same as passing 'db=DATABASE_NAME' to the connection string.
File Name Destination file name to use.
File Prefix Path prefix under which the data should be uploaded on the stage.
Internal Stage Type The type of internal stage to use
Schema The schema to use by default. The same as passing 'schema=SCHEMA' to the connection string.
Snowflake Connection Service Database Connection Service for accessing Snowflake
Stage The name of the internal stage in the Snowflake account to put files into.
Table The name of the table in the Snowflake account.
Name Description
failure For FlowFiles of failed PUT operation
success For FlowFiles of successful PUT operation
Name Description
snowflake.staged.file.path Staged file path
Property Description
Account Snowflake Account Identifier with Organization Name and Account Name formatted as [organization-name]-[account-name]
Authentication Strategy Strategy for authenticating Snowflake connections
Client Lag The maximum amount of time that the client will wait before flushing records to Snowflake. A larger value can increase latency while sending to Snowflake, but for tables that are not constantly updated it can result in queries that are faster and more cost efficient.
Concurrency Group Allows specifying a 'Concurrency Group' that a given FlowFile belongs to, so that the number of Concurrent Tasks that write to tables in a given group can be limited.
Connection Strategy Strategy for connecting to Snowflake Snowpipe Streaming services
Database Snowflake Database destination for processed records
Delivery Guarantee Specifies the delivery guarantee for the records being sent to Snowflake.
Iceberg Enabled Specifies whether the processor ingests data into an Iceberg table. The processor fails if this property doesn’t match the actual table type.
Max Batch Size Maximum number of records to ingest in a single call. Multiple ingest calls will be made if the number of records exceeds the max batch size. Current guidance recommends batch sizes less than 16MB. The Max Batch Size can be tuned based on the average record size such that batches are generally less than 16MB.
Max Tasks Per Group The maximum number of channels to create for a given Snowpipe Channel Prefix. This allows limiting the number of concurrent tasks that can be writing to a given Snowflake table.
Private Key Service RSA Private Key Service for authenticating connections
Record Offset The Expression Language expression to use to determine the offset of the first record in a FlowFile.
Record Offset Record Path The Record Path expression to use to determine the offset of the first record in a FlowFile.
Record Offset Strategy Specifies the strategy for determining the offset of each record.
Record Reader The Record Reader to use for reading the input
Role Snowflake Role the user will assume when authenticating connections
Schema Snowflake Schema destination for processed records
Snowpipe Channel Index The index to use for the Snowpipe channel name. The full channel name will be constructed as openflow.[prefix].[index]. This is necessary in order to provide Exactly Once delivery to Snowflake, as any retry must be tried against the same channel as was previously used.
Snowpipe Channel Prefix The prefix to use for the Snowpipe channel name. The full channel name will be constructed as openflow.[prefix].[index]. The default value is $\{hostname(false)\}, which ensures that each NiFi node in the cluster writes to a unique channel by incorporating the hostname of the NiFi instance into the channel name.
Table Snowflake Table destination for processed records
User Snowflake User for authenticating connections
Name Description
failure For FlowFiles that failed to upload to Snowflake
success For FlowFiles successfully uploaded to Snowflake
Property Description
ARN Type The type of Amazon Resource Name that is being used.
AWS Credentials Provider service The Controller Service that is used to obtain AWS credentials provider
Amazon Resource Name (ARN) The name of the resource to which notifications should be published
Character Set The character set in which the FlowFile's content is encoded
Communications Timeout
Deduplication Message ID The token used for deduplication of sent messages
E-mail Subject The optional subject to use for any subscribers that are subscribed via E-mail
Endpoint Override URL Endpoint URL to use instead of the AWS default including scheme, host, port, and path. The AWS libraries select an endpoint URL based on the AWS region, but this property overrides the selected endpoint URL, allowing use with other S3-compatible endpoints.
Message Group ID If using FIFO, the message group to which the flowFile belongs
Region
SSL Context Service Specifies an optional SSL Context Service that, if provided, will be used to create connections
Use JSON Structure If true, the contents of the FlowFile must be JSON with a top-level element named 'default'. Additional elements can be used to send different messages to different protocols. See the Amazon SNS Documentation for more information.
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
failure FlowFiles are routed to failure relationship
success FlowFiles are routed to success relationship
Property Description
Character Set Specifies the character set of the data being sent.
Hostname Destination hostname or IP address
Idle Connection Expiration The amount of time a connection should be held open without being used before closing the connection. A value of 0 seconds will disable this feature.
Max Size of Socket Send Buffer The maximum size of the socket send buffer that should be used. This is a suggestion to the Operating System to indicate how big the socket buffer should be. If this value is set too low, the buffer may fill up before the data can be read, and incoming data will be dropped.
Message Delimiter Specifies the delimiter to use for splitting apart multiple messages within a single FlowFile. If not specified, the entire content of the FlowFile will be used as a single message. If specified, the contents of the FlowFile will be split on this delimiter and each section sent as a separate message. Note that if messages are delimited and some messages for a given FlowFile are transferred successfully while others are not, the messages will be split into individual FlowFiles, such that those messages that were successfully sent are routed to the 'success' relationship while other messages are sent to the 'failure' relationship.
Port Destination port number
Protocol The protocol for communication.
SSL Context Service Specifies the SSL Context Service to enable TLS socket communication
Timeout The timeout for connecting to and communicating with the destination. Does not apply to UDP
Name Description
failure FlowFiles that failed to send to the destination are sent out this relationship.
success FlowFiles that are sent successfully to the destination are sent out this relationship.
Property Description
Hostname The ip address or hostname of the Splunk server.
Owner The owner to pass to Splunk.
Password The password to authenticate to Splunk.
Port The HTTP Event Collector HTTP Port Number.
Scheme The scheme for connecting to Splunk.
Security Protocol The security protocol to use for communicating with Splunk.
Token HTTP Event Collector token starting with the string Splunk. For example 'Splunk 1234578-abcd-1234-abcd-1234abcd'
Username The username to authenticate to Splunk.
character-set The name of the character set.
content-type The media type of the event sent to Splunk. If not set, "mime.type" flow file attribute will be used. In case of neither of them is specified, this information will not be sent to the server.
host Specify with the host query string parameter. Sets a default for all events when unspecified.
index Index name. Specify with the index query string parameter. Sets a default for all events when unspecified.
request-channel Identifier of the used request channel.
source User-defined event source. Sets a default for all events when unspecified.
source-type User-defined event sourcetype. Sets a default for all events when unspecified.
Name Description
failure FlowFiles that failed to send to the destination are sent to this relationship.
success FlowFiles that are sent successfully to the destination are sent to this relationship.
Name Description
splunk.acknowledgement.id The indexing acknowledgement id provided by Splunk.
splunk.responded.at The time of the response of put request for Splunk.
Property Description
Batch Size The preferred number of FlowFiles to put to the database in a single transaction
JDBC Connection Pool Specifies the JDBC Connection Pool to use in order to convert the JSON message to a SQL statement. The Connection Pool is necessary in order to determine the appropriate database column types.
Obtain Generated Keys If true, any key that is automatically generated by the database will be added to the FlowFile that generated it using the sql.generate.key attribute. This may result in slightly slower performance and is not supported by all databases.
Rollback On Failure Specify how to handle error. By default (false), if an error occurs while processing a FlowFile, the FlowFile will be routed to 'failure' or 'retry' relationship based on error type, and processor can continue with next FlowFile. Instead, you may want to rollback currently processed FlowFiles and stop further processing immediately. In that case, you can do so by enabling this 'Rollback On Failure' property. If enabled, failed FlowFiles will stay in the input relationship without penalizing it and being processed repeatedly until it gets processed successfully or removed by other means. It is important to set adequate 'Yield Duration' to avoid retrying too frequently.
Support Fragmented Transactions If true, when a FlowFile is consumed by this Processor, the Processor will first check the fragment.identifier and fragment.count attributes of that FlowFile. If the fragment.count value is greater than 1, the Processor will not process any FlowFile with that fragment.identifier until all are available; at that point, it will process all FlowFiles with that fragment.identifier as a single transaction, in the order specified by the FlowFiles 'fragment.index attributes. This Provides atomicity of those SQL statements. Once any statement of this transaction throws exception when executing, this transaction will be rolled back. When transaction rollback happened, none of these FlowFiles would be routed to'success '. If the <Rollback On Failure> is set true, these FlowFiles will stay in the input relationship. When the <Rollback On Failure> is set false,, if any of these FlowFiles will be routed to' retry ', all of these FlowFiles will be routed to' retry '.Otherwise, they will be routed to' failure'. If this value is false, these attributes will be ignored and the updates will occur independent of one another.
Transaction Timeout If the <Support Fragmented Transactions> property is set to true, specifies how long to wait for all FlowFiles for a particular fragment.identifier attribute to arrive before just transferring all of the FlowFiles with that identifier to the 'failure' relationship
database-session-autocommit The autocommit mode to set on the database connection being used. If set to false, the operation(s) will be explicitly committed or rolled back (based on success or failure respectively), if set to true the driver/database handles the commit/rollback.
putsql-sql-statement The SQL statement to execute. The statement can be empty, a constant value, or built from attributes using Expression Language. If this property is specified, it will be used regardless of the content of incoming FlowFiles. If this property is empty, the content of the incoming FlowFile is expected to contain a valid SQL statement, to be issued by the processor to the database.
Name Description
failure A FlowFile is routed to this relationship if the database cannot be updated and retrying the operation will also fail, such as an invalid query or an integrity constraint violation
retry A FlowFile is routed to this relationship if the database cannot be updated but attempting the operation again may succeed
success A FlowFile is routed to this relationship after the database is successfully updated
Name Description
sql.generated.key If the database generated a key for an INSERT statement and the Obtain Generated Keys property is set to true, this attribute will be added to indicate the generated key, if possible. This feature is not supported by all database vendors.
Property Description
AWS Credentials Provider service The Controller Service that is used to obtain AWS credentials provider
Communications Timeout
Deduplication Message ID The token used for deduplication of sent messages
Delay The amount of time to delay the message before it becomes available to consumers
Endpoint Override URL Endpoint URL to use instead of the AWS default including scheme, host, port, and path. The AWS libraries select an endpoint URL based on the AWS region, but this property overrides the selected endpoint URL, allowing use with other S3-compatible endpoints.
Message Group ID If using FIFO, the message group to which the FlowFile belongs
Queue URL The URL of the queue to act upon
Region
SSL Context Service Specifies an optional SSL Context Service that, if provided, will be used to create connections
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
failure FlowFiles are routed to failure relationship
success FlowFiles are routed to success relationship
Property Description
Batch Size The number of incoming FlowFiles to process in a single execution of this processor.
Character Set Specifies the character set of the Syslog messages. Note that Expression language is not evaluated per FlowFile.
Hostname The IP address or hostname of the Syslog server.
Idle Connection Expiration The amount of time a connection should be held open without being used before closing the connection.
Max Size of Socket Send Buffer The maximum size of the socket send buffer that should be used. This is a suggestion to the Operating System to indicate how big the socket buffer should be. If this value is set too low, the buffer may fill up before the data can be read, and incoming data will be dropped.
Message Body The body for the Syslog messages.
Message Hostname The hostname for the Syslog messages.
Message Priority The priority for the Syslog messages, excluding < >.
Message Timestamp The timestamp for the Syslog messages. The timestamp can be an RFC5424 timestamp with a format of "yyyy-MM-dd 'T'HH:mm:ss. S 'Z'" or "yyyy-MM-dd 'T'HH:mm:ss. S+hh:mm", " or it can be an RFC3164 timestamp with a format of "MMM d HH:mm:ss".
Message Version The version for the Syslog messages.
Port The port for Syslog communication. Note that Expression language is not evaluated per FlowFile.
Protocol The protocol for Syslog communication.
SSL Context Service The Controller Service to use in order to obtain an SSL Context. If this property is set, syslog messages will be sent over a secure connection.
Timeout The timeout for connecting to and communicating with the syslog server. Does not apply to UDP. Note that Expression language is not evaluated per FlowFile.
Name Description
failure FlowFiles that failed to send to Syslog are sent out this relationship.
invalid FlowFiles that do not form a valid Syslog message are sent out this relationship.
success FlowFiles that are sent successfully to Syslog are sent out this relationship.
Property Description
Character Set Specifies the character set of the data being sent.
Connection Per FlowFile Specifies whether to send each FlowFile's content on an individual connection.
Hostname Destination hostname or IP address
Idle Connection Expiration The amount of time a connection should be held open without being used before closing the connection. A value of 0 seconds will disable this feature.
Max Size of Socket Send Buffer The maximum size of the socket send buffer that should be used. This is a suggestion to the Operating System to indicate how big the socket buffer should be. If this value is set too low, the buffer may fill up before the data can be read, and incoming data will be dropped.
Outgoing Message Delimiter Specifies the delimiter to use when sending messages out over the same TCP stream. The delimiter is appended to each FlowFile message that is transmitted over the stream so that the receiver can determine when one message ends and the next message begins. Users should ensure that the FlowFile content does not contain the delimiter character to avoid errors. In order to use a new line character you can enter 'n'. For a tab character use 't'. Finally for a carriage return use 'r'.
Port Destination port number
Record Reader Specifies the Controller Service to use for reading Records from input FlowFiles
Record Writer Specifies the Controller Service to use for writing Records to the configured socket address
SSL Context Service Specifies the SSL Context Service to enable TLS socket communication
Timeout The timeout for connecting to and communicating with the destination. Does not apply to UDP
Transmission Strategy Specifies the strategy used for reading input FlowFiles and transmitting messages to the destination socket address
Name Description
failure FlowFiles that failed to send to the destination are sent out this relationship.
success FlowFiles that are sent successfully to the destination are sent out this relationship.
Name Description
record.count.transmitted Count of records transmitted to configured destination address
Property Description
Hostname Destination hostname or IP address
Idle Connection Expiration The amount of time a connection should be held open without being used before closing the connection. A value of 0 seconds will disable this feature.
Max Size of Socket Send Buffer The maximum size of the socket send buffer that should be used. This is a suggestion to the Operating System to indicate how big the socket buffer should be. If this value is set too low, the buffer may fill up before the data can be read, and incoming data will be dropped.
Port Destination port number
Timeout The timeout for connecting to and communicating with the destination. Does not apply to UDP
Name Description
failure FlowFiles that failed to send to the destination are sent out this relationship.
success FlowFiles that are sent successfully to the destination are sent out this relationship.
Property Description
Databricks Client Databricks Client Service.
Unity Catalog File Path Unity Catalog file path e.g. /Volumes/catalog/schema/volume_name/file.txt
Name Description
failure Databricks failure relationship
success Databricks success relationship
Name Description
error.code The error code for the SQL statement if an error occurred.
error.message The error message for the SQL statement if an error occurred.
Property Description
Corpus ID Identifier of the Vectara corpus
Document Attributes A comma delimited list of NiFi attributes fields, which if present will be included in the document metadata.
Document Author Author of the document
Document Creation Time Timestamp in epoch seconds when the document was created
Document Date Date of document creation
Document Description Description of the document
Document ID A unique identifier for the document constructed either from the source path of the document or a hash of the document's content.
Document Source URL Source URL for document
Document Title Document Title
Index Input Format Input format for indexing service. JSON Object: Load FlowFile content directly as JSON payload. JSON Lines: Create a new section for each line of JSON. JSON Array: Load FlowFile content as a JSON array and create a new section for each element in the JSON array.
Section Custom Dimensions A comma delimited list of metadata fields, which if present in the metadata path will be included as a section's custom dimension. The values for custom dimensions must be valid numbers.
Section Filter Attributes A comma delimited list of metadata fields, which if present in the metadata path will be included as a section metadata filter.
Section ID Attribute The field for setting section id, which is populated if present in the metadata path.
Section Metadata Attributes A comma delimited list of metadata fields, which if present in the metadata path will be included will be included in the section metadata.
Section Metadata JSON Path A JSON Path expression to a metadata JSON Object. The JSON Object needs to contain the list of metadata fields. These fields will be included in Section metadata.
Section Text JSON Path A JSON Path expression to the text field.
Section Title Attribute The field for setting the section title, which is populated if present in the metadata path.
Vectara Client Vectara Client Service.
Name Description
failure Vectara failure relationship
original Original relationship
success Vectara success relationship
Property Description
Corpus ID Identifier of the Vectara corpus
Document Filter Attributes A comma delimited list of metadata fields, which if present in the FlowFile attributes will be included in as a document metadata filter.
Document ID A unique identifier for the document constructed either from the source path of the document or a hash of the document's content.
Document Metadata Attributes A comma delimited list of metadata fields, which if present in the FlowFile attributes will be included will be included in the document metadata.
Vectara Client Vectara Client Service.
Name Description
failure Vectara failure relationship
original Original relationship
success Vectara success relationship
Property Description
websocket-controller-service-id A NiFi Expression to retrieve the id of a WebSocket ControllerService.
websocket-endpoint-id A NiFi Expression to retrieve the endpoint id of a WebSocket ControllerService.
websocket-message-type The type of message content: TEXT or BINARY
websocket-session-id A NiFi Expression to retrieve the session id. If not specified, a message will be sent to all connected WebSocket peers for the WebSocket controller service endpoint.
Name Description
failure FlowFiles that failed to send to the destination are transferred to this relationship.
success FlowFiles that are sent successfully to the destination are transferred to this relationship.
Name Description
websocket.controller.service.id WebSocket Controller Service id.
websocket.session.id Established WebSocket session id.
websocket.endpoint.id WebSocket endpoint id.
websocket.message.type TEXT or BINARY.
websocket.local.address WebSocket server address.
websocket.remote.address WebSocket client address.
websocket.failure.detail Detail of the failure.
Property Description
web-client-service-provider Controller service for HTTP client operations.
zendesk-authentication-type-name Type of authentication to Zendesk API.
zendesk-authentication-value-name Password or authentication token for Zendesk login user.
zendesk-comment-body The content or the path to the comment body in the incoming record.
zendesk-priority The content or the path to the priority in the incoming record.
zendesk-record-reader Specifies the Controller Service to use for parsing incoming data and determining the data's schema.
zendesk-subdomain Name of the Zendesk subdomain.
zendesk-subject The content or the path to the subject in the incoming record.
zendesk-type The content or the path to the type in the incoming record.
zendesk-user Login user to Zendesk subdomain.
Name Description
failure A FlowFile is routed to this relationship if the operation failed and retrying the operation will also fail, such as an invalid data or schema.
success For FlowFiles created as a result of a successful HTTP request.
Name Description
record.count The number of records processed.
error.code The error code of from the response.
error.message The error message of from the response.
Property Description
Database Name Azure Data Explorer Database Name for querying
Kusto Query Service Azure Data Explorer Kusto Query Service
Query Query to be run against Azure Data Explorer
Name Description
failure FlowFiles containing original input associated with a failed Query
success FlowFiles containing results of a successful Query
Name Description
query.error.message Azure Data Explorer query error message on failures
query.executed Azure Data Explorer query executed
mime.type Content Type set to application/json
Property Description
Columns to Return A comma-separated list of column names to be used in the query. If your database requires special treatment of the names (quoting, e.g.), each name should include such treatment. If no column names are supplied, all columns in the specified table will be returned. NOTE: It is important to use consistent column names for a given table for incremental fetch to work properly.
Database Connection Pooling Service The Controller Service that is used to obtain a connection to the database.
Database Dialect Service Database Dialect Service for generating statements specific to a particular service or vendor.
Default Decimal Precision When a DECIMAL/NUMBER value is written as a 'decimal' Avro logical type, a specific 'precision' denoting number of available digits is required. Generally, precision is defined by column data type definition or database engines default. However undefined precision (0) can be returned from some database engines. 'Default Decimal Precision' is used when writing those undefined precision numbers.
Default Decimal Scale When a DECIMAL/NUMBER value is written as a 'decimal' Avro logical type, a specific 'scale' denoting number of available decimal digits is required. Generally, scale is defined by column data type definition or database engines default. However when undefined precision (0) is returned, scale can also be uncertain with some database engines. 'Default Decimal Scale' is used when writing those undefined numbers. If a value has more decimals than specified scale, then the value will be rounded-up, e.g. 1.53 becomes 2 with scale 0, and 1.5 with scale 1.
Fetch Size The number of result rows to be fetched from the result set at a time. This is a hint to the database driver and may not be honored and/or exact. If the value specified is zero, then the hint is ignored. If using PostgreSQL, then 'Set Auto Commit' must be equal to 'false' to cause 'Fetch Size' to take effect.
Max Wait Time The maximum amount of time allowed for a running SQL select query , zero means there is no limit. Max time less than 1 second will be equal to zero.
Maximum-value Columns A comma-separated list of column names. The processor will keep track of the maximum value for each column that has been returned since the processor started running. Using multiple columns implies an order to the column list, and each column 's values are expected to increase more slowly than the previous columns' values. Thus, using multiple columns implies a hierarchical structure of columns, which is usually used for partitioning tables. This processor can be used to retrieve only those rows that have been added/updated since the last retrieval. Note that some JDBC types such as bit/boolean are not conducive to maintaining maximum value, so columns of these types should not be listed in this property, and will result in error(s) during processing. If no columns are provided, all rows from the table will be considered, which could have a performance impact. NOTE: It is important to use consistent max-value column names for a given table for incremental fetch to work properly.
Normalize Table and Column Names Whether to change non-Avro-compatible characters in column names to Avro-compatible characters. For example, colons and periods will be changed to underscores in order to build a valid Avro record.
Set Auto Commit Allows enabling or disabling the auto commit functionality of the DB connection. Default value is 'No value set'. 'No value set' will leave the db connection 's auto commit mode unchanged. For some JDBC drivers such as PostgreSQL driver, it is required to disable the auto commit functionality to get the'Fetch Size 'setting to take effect. When auto commit is enabled, PostgreSQL driver ignores'Fetch Size'setting and loads all rows of the result set to memory at once. This could lead for a large amount of memory usage when executing queries which fetch large data sets. More Details of this behaviour in PostgreSQL driver can be found in https://jdbc.postgresql.org//documentation/head/query.html (https://jdbc.postgresql.org//documentation/head/query.html).
Table Name The name of the database table to be queried. When a custom query is used, this property is used to alias the query and appears as an attribute on the FlowFile.
Use Avro Logical Types Whether to use Avro Logical Types for DECIMAL/NUMBER, DATE, TIME and TIMESTAMP columns. If disabled, written as string. If enabled, Logical types are used and written as its underlying type, specifically, DECIMAL/NUMBER as logical 'decimal': written as bytes with additional precision and scale meta data, DATE as logical 'date-millis': written as int denoting days since Unix epoch (1970-01-01), TIME as logical 'time-millis': written as int denoting milliseconds since Unix epoch, and TIMESTAMP as logical 'timestamp-millis': written as long denoting milliseconds since Unix epoch. If a reader of written Avro records also knows these logical types, then these values can be deserialized with more context depending on reader implementation.
db-fetch-db-type Database Type for generating statements specific to a particular service or vendor. The Generic Type supports most cases but selecting a specific type enables optimal processing or additional features.
db-fetch-sql-query A custom SQL query used to retrieve data. Instead of building a SQL query from other properties, this query will be wrapped as a sub-query. Query must have no ORDER BY statement.
db-fetch-where-clause A custom clause to be added in the WHERE condition when building SQL queries.
initial-load-strategy How to handle existing rows in the database table when the processor is started for the first time (or its state has been cleared). The property will be ignored, if any 'initial.maxvalue.*' dynamic property has also been configured.
qdbt-max-frags The maximum number of fragments. If the value specified is zero, then all fragments are returned. This prevents OutOfMemoryError when this processor ingests huge table. NOTE: Setting this property can result in data loss, as the incoming results are not ordered, and fragments may end at arbitrary boundaries where rows are not included in the result set.
qdbt-max-rows The maximum number of result rows that will be included in a single FlowFile. This will allow you to break up very large result sets into multiple FlowFiles. If the value specified is zero, then all rows are returned in a single FlowFile.
qdbt-output-batch-size The number of output FlowFiles to queue before committing the process session. When set to zero, the session will be committed when all result set rows have been processed and the output FlowFiles are ready for transfer to the downstream relationship. For large result sets, this can cause a large burst of FlowFiles to be transferred at the end of processor execution. If this property is set, then when the specified number of FlowFiles are ready for transfer, then the session will be committed, thus releasing the FlowFiles to the downstream relationship. NOTE: The maxvalue.* and fragment.count attributes will not be set on FlowFiles when this property is set.
transaction-isolation-level This setting will set the transaction isolation level for the database connection for drivers that support this setting
Scopes Description
CLUSTER After performing a query on the specified table, the maximum values for the specified column(s) will be retained for use in future executions of the query. This allows the Processor to fetch only those records that have max values greater than the retained values. This can be used for incremental fetching, fetching of newly added rows, etc. To clear the maximum values, clear the state of the processor per the State Management documentation
Name Description
success Successfully created FlowFile from SQL query result set.
Name Description
tablename Name of the table being queried
querydbtable.row.count The number of rows selected by the query
fragment.identifier If 'Max Rows Per Flow File' is set then all FlowFiles from the same query result set will have the same value for the fragment.identifier attribute. This can then be used to correlate the results.
fragment.count If 'Max Rows Per Flow File' is set then this is the total number of FlowFiles produced by a single ResultSet. This can be used in conjunction with the fragment.identifier attribute in order to know how many FlowFiles belonged to the same incoming ResultSet. If Output Batch Size is set, then this attribute will not be populated.
fragment.index If 'Max Rows Per Flow File' is set then the position of this FlowFile in the list of outgoing FlowFiles that were all derived from the same result set FlowFile. This can be used in conjunction with the fragment.identifier attribute to know which FlowFiles originated from the same query result set and in what order FlowFiles were produced
maxvalue.* Each attribute contains the observed maximum value of a specified 'Maximum-value Column'. The suffix of the attribute is the name of the column. If Output Batch Size is set, then this attribute will not be populated.
Property Description
Columns to Return A comma-separated list of column names to be used in the query. If your database requires special treatment of the names (quoting, e.g.), each name should include such treatment. If no column names are supplied, all columns in the specified table will be returned. NOTE: It is important to use consistent column names for a given table for incremental fetch to work properly.
Database Connection Pooling Service The Controller Service that is used to obtain a connection to the database.
Database Dialect Service Database Dialect Service for generating statements specific to a particular service or vendor.
Default Decimal Precision When a DECIMAL/NUMBER value is written as a 'decimal' Avro logical type, a specific 'precision' denoting number of available digits is required. Generally, precision is defined by column data type definition or database engines default. However undefined precision (0) can be returned from some database engines. 'Default Decimal Precision' is used when writing those undefined precision numbers.
Default Decimal Scale When a DECIMAL/NUMBER value is written as a 'decimal' Avro logical type, a specific 'scale' denoting number of available decimal digits is required. Generally, scale is defined by column data type definition or database engines default. However when undefined precision (0) is returned, scale can also be uncertain with some database engines. 'Default Decimal Scale' is used when writing those undefined numbers. If a value has more decimals than specified scale, then the value will be rounded-up, e.g. 1.53 becomes 2 with scale 0, and 1.5 with scale 1.
Fetch Size The number of result rows to be fetched from the result set at a time. This is a hint to the database driver and may not be honored and/or exact. If the value specified is zero, then the hint is ignored. If using PostgreSQL, then 'Set Auto Commit' must be equal to 'false' to cause 'Fetch Size' to take effect.
Max Wait Time The maximum amount of time allowed for a running SQL select query , zero means there is no limit. Max time less than 1 second will be equal to zero.
Maximum-value Columns A comma-separated list of column names. The processor will keep track of the maximum value for each column that has been returned since the processor started running. Using multiple columns implies an order to the column list, and each column 's values are expected to increase more slowly than the previous columns' values. Thus, using multiple columns implies a hierarchical structure of columns, which is usually used for partitioning tables. This processor can be used to retrieve only those rows that have been added/updated since the last retrieval. Note that some JDBC types such as bit/boolean are not conducive to maintaining maximum value, so columns of these types should not be listed in this property, and will result in error(s) during processing. If no columns are provided, all rows from the table will be considered, which could have a performance impact. NOTE: It is important to use consistent max-value column names for a given table for incremental fetch to work properly.
Set Auto Commit Allows enabling or disabling the auto commit functionality of the DB connection. Default value is 'No value set'. 'No value set' will leave the db connection 's auto commit mode unchanged. For some JDBC drivers such as PostgreSQL driver, it is required to disable the auto commit functionality to get the'Fetch Size 'setting to take effect. When auto commit is enabled, PostgreSQL driver ignores'Fetch Size'setting and loads all rows of the result set to memory at once. This could lead for a large amount of memory usage when executing queries which fetch large data sets. More Details of this behaviour in PostgreSQL driver can be found in https://jdbc.postgresql.org//documentation/head/query.html (https://jdbc.postgresql.org//documentation/head/query.html).
Table Name The name of the database table to be queried. When a custom query is used, this property is used to alias the query and appears as an attribute on the FlowFile.
Use Avro Logical Types Whether to use Avro Logical Types for DECIMAL/NUMBER, DATE, TIME and TIMESTAMP columns. If disabled, written as string. If enabled, Logical types are used and written as its underlying type, specifically, DECIMAL/NUMBER as logical 'decimal': written as bytes with additional precision and scale meta data, DATE as logical 'date-millis': written as int denoting days since Unix epoch (1970-01-01), TIME as logical 'time-millis': written as int denoting milliseconds since Unix epoch, and TIMESTAMP as logical 'timestamp-millis': written as long denoting milliseconds since Unix epoch. If a reader of written Avro records also knows these logical types, then these values can be deserialized with more context depending on reader implementation.
db-fetch-db-type Database Type for generating statements specific to a particular service or vendor. The Generic Type supports most cases but selecting a specific type enables optimal processing or additional features.
db-fetch-sql-query A custom SQL query used to retrieve data. Instead of building a SQL query from other properties, this query will be wrapped as a sub-query. Query must have no ORDER BY statement.
db-fetch-where-clause A custom clause to be added in the WHERE condition when building SQL queries.
initial-load-strategy How to handle existing rows in the database table when the processor is started for the first time (or its state has been cleared). The property will be ignored, if any 'initial.maxvalue.*' dynamic property has also been configured.
qdbt-max-frags The maximum number of fragments. If the value specified is zero, then all fragments are returned. This prevents OutOfMemoryError when this processor ingests huge table. NOTE: Setting this property can result in data loss, as the incoming results are not ordered, and fragments may end at arbitrary boundaries where rows are not included in the result set.
qdbt-max-rows The maximum number of result rows that will be included in a single FlowFile. This will allow you to break up very large result sets into multiple FlowFiles. If the value specified is zero, then all rows are returned in a single FlowFile.
qdbt-output-batch-size The number of output FlowFiles to queue before committing the process session. When set to zero, the session will be committed when all result set rows have been processed and the output FlowFiles are ready for transfer to the downstream relationship. For large result sets, this can cause a large burst of FlowFiles to be transferred at the end of processor execution. If this property is set, then when the specified number of FlowFiles are ready for transfer, then the session will be committed, thus releasing the FlowFiles to the downstream relationship. NOTE: The maxvalue.* and fragment.count attributes will not be set on FlowFiles when this property is set.
qdbtr-normalize Whether to change characters in column names when creating the output schema. For example, colons and periods will be changed to underscores.
qdbtr-record-writer Specifies the Controller Service to use for writing results to a FlowFile. The Record Writer may use Inherit Schema to emulate the inferred schema behavior, i.e. an explicit schema need not be defined in the writer, and will be supplied by the same logic used to infer the schema from the column types.
Scopes Description
CLUSTER After performing a query on the specified table, the maximum values for the specified column(s) will be retained for use in future executions of the query. This allows the Processor to fetch only those records that have max values greater than the retained values. This can be used for incremental fetching, fetching of newly added rows, etc. To clear the maximum values, clear the state of the processor per the State Management documentation
Name Description
success Successfully created FlowFile from SQL query result set.
Name Description
tablename Name of the table being queried
querydbtable.row.count The number of rows selected by the query
fragment.identifier If 'Max Rows Per Flow File' is set then all FlowFiles from the same query result set will have the same value for the fragment.identifier attribute. This can then be used to correlate the results.
fragment.count If 'Max Rows Per Flow File' is set then this is the total number of FlowFiles produced by a single ResultSet. This can be used in conjunction with the fragment.identifier attribute in order to know how many FlowFiles belonged to the same incoming ResultSet. If Output Batch Size is set, then this attribute will not be populated.
fragment.index If 'Max Rows Per Flow File' is set then the position of this FlowFile in the list of outgoing FlowFiles that were all derived from the same result set FlowFile. This can be used in conjunction with the fragment.identifier attribute to know which FlowFiles originated from the same query result set and in what order FlowFiles were produced
maxvalue.* Each attribute contains the observed maximum value of a specified 'Maximum-value Column'. The suffix of the attribute is the name of the column. If Output Batch Size is set, then this attribute will not be populated.
mime.type Sets the mime.type attribute to the MIME Type specified by the Record Writer.
record.count The number of records output by the Record Writer.
Property Description
Collection Name The name of the Milvus collection name to use
Max Query Batch Size This is the number of vectors that are contained in a single request to Milvus during a query. Milvus is unable to support batch queries of more than 10 vectors at a time.
Maximum Results The maximum number of results to return (i.e., Top K)
Milvus Connection Service Connection Service for accessing Milvus Database
Output Search Fields Comma separated list of additional fields to return from a search against the Milvus database. Milvus will return the score and id fields by default.
Partition Partition of the vector database that you want to perform operations in. If the database has only one partition leave empty.
Record Reader The Record Reader to use for reading the FlowFile
Record Writer The Record Writer to use for writing the results
Reranking Smoothing Parameter Smoothing Parameter of the Reciprocal Rank Fusion (RRFRanker) during Hybrid Search
Results Record Path Specifies where in the record to place the results.
Sparse Vector Field Name The name of the field to use for storing the sparse vectors.
Sparse Vector Indices Path If, Sparse Vectors are to be provided, this RecordPath points to the indices of the sparse data to use.
Sparse Vector Values Path If, Sparse Vectors are to be provided, this RecordPath points to the values of the sparse data to use.
Vector Field Name The name of the field in Milvus to use for storing the vectors.
Vector Record Path The path to the vector field in the record
Name Description
failure FlowFiles that cannot be sent to Milvus, and for which a retry is not expected to be successful, are routed to this relationship
retry FlowFiles that fail to be sent to Milvus, but for which a retry may help, are routed to this relationship
success FlowFiles that are successfully sent to Milvus are routed to this relationship
Property Description
ID Record Path The path to the ID field in the record
Include Metadata Specifies whether to include metadata in the results
Include Vectors Specifies whether to include vectors in the results
Number of Results The number of results to return (i.e., Top K)
Pinecone API Key The API key for the Pinecone service
Pinecone Index The name of the Pinecone index to use
Pinecone Namespace The name of the Pinecone namespace to use
Query Filter A JSON representation of the query filter to use
Query Strategy The strategy to use for querying Pinecone
Record Reader The Record Reader to use for reading the FlowFile
Record Writer The Record Writer to use for writing the results
Results Record Path Specifies where in the record to place the results.
Sparse Dense Vector Weighting Ranges from 0.0 to 1.0. Weight to apply on dense and sparse vectors when doing an hybrid search. (1 - weight) will be applied to the values of the sparse vector and (weight) will be applied to the dense vector.
Sparse Vector Indices Path If, Sparse Vectors are to be provided, this RecordPath points to the indices of the sparse data to use.
Sparse Vector Values Path If, Sparse Vectors are to be provided, this RecordPath points to the values of the sparse data to use.
Vector Record Path The path to the vector field in the record
Web Client Service The Web Client Service to use for communicating with Pinecone
Name Description
failure FlowFiles that cannot be sent to Pinecone, and for which a retry is not expected to be successful, are routed to this relationship
retry FlowFiles that fail to be sent to Pinecone, but for which a retry may help, are routed to this relationship
success FlowFiles that are successfully sent to Pinecone are routed to this relationship
Property Description
Default Decimal Precision When a DECIMAL/NUMBER value is written as a 'decimal' Avro logical type, a specific 'precision' denoting number of available digits is required. Generally, precision is defined by column data type definition or database engines default. However undefined precision (0) can be returned from some database engines. 'Default Decimal Precision' is used when writing those undefined precision numbers.
Default Decimal Scale When a DECIMAL/NUMBER value is written as a 'decimal' Avro logical type, a specific 'scale' denoting number of available decimal digits is required. Generally, scale is defined by column data type definition or database engines default. However when undefined precision (0) is returned, scale can also be uncertain with some database engines. 'Default Decimal Scale' is used when writing those undefined numbers. If a value has more decimals than specified scale, then the value will be rounded-up, e.g. 1.53 becomes 2 with scale 0, and 1.5 with scale 1.
include-zero-record-flowfiles When running the SQL statement against an incoming FlowFile, if the result has no data, this property specifies whether or not a FlowFile will be sent to the corresponding relationship
record-reader Specifies the Controller Service to use for parsing incoming data and determining the data's schema
record-writer Specifies the Controller Service to use for writing results to a FlowFile
Name Description
failure If a FlowFile fails processing for any reason (for example, the SQL statement contains columns not present in input data), the original FlowFile it will be routed to this relationship
original The original FlowFile is routed to this relationship
Name Description
mime.type Sets the mime.type attribute to the MIME Type specified by the Record Writer
record.count The number of records selected by the query
QueryRecord.Route The relation to which the FlowFile was routed
Property Description
age-delay The ending timestamp of the time window will be adjusted earlier by the amount configured in this property. For example, with a property value of 10 seconds, an ending timestamp of 12:30:45 would be changed to 12:30:35.
age-field The name of a TIMESTAMP field that will be used to filter records using a bounded time window. The processor will return only those records with a timestamp value newer than the timestamp recorded after the last processor run.
create-zero-record-files Specifies whether or not to create a FlowFile when the Salesforce REST API does not return any records
custom-soql-query Specify the SOQL query to run.
custom-where-condition A custom expression to be added in the WHERE clause of the query
field-names Comma-separated list of field names requested from the sObject to be queried. When this field is left empty, all fields are queried.
include-deleted-records If true, the processor will include deleted records (IsDeleted = true) in the query results. When enabled, the processor will use the 'queryAll' API.
initial-age-filter This property specifies the start time that the processor applies when running the first query.
oauth2-access-token-provider Service providing OAuth2 Access Tokens for authenticating using the HTTP Authorization Header
query-type Choose to provide the query by parameters or a full custom query.
read-timeout Maximum time allowed for reading a response from the Salesforce REST API
record-writer Service used for writing records returned from the Salesforce REST API
salesforce-api-version The version number of the Salesforce REST API appended to the URL after the services/data path. See Salesforce documentation for supported versions
salesforce-url The URL of the Salesforce instance including the domain without additional path information, such as https://MyDomainName.my.salesforce.com (https://MyDomainName.my.salesforce.com)
sobject-name The Salesforce sObject to be queried
Scopes Description
CLUSTER When 'Age Field' is set, after performing a query the time of execution is stored. Subsequent queries will be augmented with an additional condition so that only records that are newer than the stored execution time (adjusted with the optional value of 'Age Delay') will be retrieved. State is stored across the cluster so that this Processor can be run on Primary Node only and if a new Primary Node is selected, the new node can pick up where the previous node left off, without duplicating the data.
Name Description
failure The input flowfile gets sent to this relationship when the query fails.
original The input flowfile gets sent to this relationship when the query succeeds.
success For FlowFiles created as a result of a successful query.
Name Description
mime.type Sets the mime.type attribute to the MIME Type specified by the Record Writer.
record.count Sets the number of records in the FlowFile.
total.record.count Sets the total number of records in the FlowFile.
Property Description
Hostname The ip address or hostname of the Splunk server.
Owner The owner to pass to Splunk.
Password The password to authenticate to Splunk.
Port The HTTP Event Collector HTTP Port Number.
Scheme The scheme for connecting to Splunk.
Security Protocol The security protocol to use for communicating with Splunk.
Token HTTP Event Collector token starting with the string Splunk. For example 'Splunk 1234578-abcd-1234-abcd-1234abcd'
Username The username to authenticate to Splunk.
max-query-size The maximum number of acknowledgement identifiers the outgoing query contains in one batch. It is recommended not to set it too low in order to reduce network communication.
request-channel Identifier of the used request channel.
ttl The maximum time the processor tries to acquire acknowledgement confirmation for an index, from the point of registration. After the given amount of time, the processor considers the index as not acknowledged and transfers the FlowFile to the "unacknowledged" relationship.
Name Description
failure A FlowFile is transferred to this relationship when the acknowledgement was not successful due to errors during the communication. FlowFiles are timing out or unknown by the Splunk server will transferred to "undetermined" relationship.
success A FlowFile is transferred to this relationship when the acknowledgement was successful.
unacknowledged A FlowFile is transferred to this relationship when the acknowledgement was not successful. This can happen when the acknowledgement did not happened within the time period set for Maximum Waiting Time. FlowFiles with acknowledgement id unknown for the Splunk server will be transferred to this relationship after the Maximum Waiting Time is reached.
undetermined A FlowFile is transferred to this relationship when the acknowledgement state is not determined. FlowFiles transferred to this relationship might be penalized. This happens when Splunk returns with HTTP 200 but with false response for the acknowledgement id in the flow file attribute.
Display Name API Name Default Value Allowable Values Description
Service to Use * Service to Use $\{recordreader.name\} Specifies the name of the user-defined property whose associated Controller Service should be used.
Display Name API Name Default Value Allowable Values Description
Service to Use * Service to Use $\{recordsetwriter.name\} Specifies the name of the user-defined property whose associated Controller Service should be used.
Display Name API Name Default Value Allowable Values Description
Cluster Max Redirects * Cluster Max Redirects 5 The maximum number of redirects that can be performed when clustered.
Communication Timeout * Communication Timeout 10 seconds The timeout to use when attempting to communicate with Redis.
Connection String * Connection String The connection string for Redis. In a standalone instance this value will be of the form hostname:port. In a sentinel instance this value will be the comma-separated list of sentinels, such as host1:port1,host2:port2,host3:port3. In a clustered instance this value will be the comma-separated list of cluster masters, such as host1:port,host2:port,host3:port.
Database Index * Database Index 0 The database index to be used by connections created from this connection pool. See the databases property in redis.conf, by default databases 0-15 will be available.
Password Password The password used to authenticate to the Redis server. See the 'requirepass' property in redis.conf.
Pool - Block When Exhausted * Pool - Block When Exhausted true - true - false Whether or not clients should block and wait when trying to obtain a connection from the pool when the pool has no available connections. Setting this to false means an error will occur immediately when a client requests a connection and none are available.
Pool - Max Idle * Pool - Max Idle 8 The maximum number of idle connections that can be held in the pool, or a negative value if there is no limit.
Pool - Max Total * Pool - Max Total 8 The maximum number of connections that can be allocated by the pool (checked out to clients, or idle awaiting checkout). A negative value indicates that there is no limit.
Pool - Max Wait Time * Pool - Max Wait Time 10 seconds The amount of time to wait for an available connection when Block When Exhausted is set to true.
Pool - Min Evictable Idle Time * Pool - Min Evictable Idle Time 60 seconds The minimum amount of time an object may sit idle in the pool before it is eligible for eviction.
Pool - Min Idle * Pool - Min Idle 0 The target for the minimum number of idle connections to maintain in the pool. If the configured value of Min Idle is greater than the configured value for Max Idle, then the value of Max Idle will be used instead.
Pool - Num Tests Per Eviction Run * Pool - Num Tests Per Eviction Run -1 The number of connections to tests per eviction attempt. A negative value indicates to test all connections.
Pool - Test On Borrow * Pool - Test On Borrow false - true - false Whether or not connections should be tested upon borrowing from the pool.
Pool - Test On Create * Pool - Test On Create false - true - false Whether or not connections should be tested upon creation.
Pool - Test On Return * Pool - Test On Return false - true - false Whether or not connections should be tested upon returning to the pool.
Pool - Test While Idle * Pool - Test While Idle true - true - false Whether or not connections should be tested while idle.
Pool - Time Between Eviction Runs * Pool - Time Between Eviction Runs 30 seconds The amount of time between attempting to evict idle connections from the pool.
Redis Mode * Redis Mode Standalone - Standalone - Sentinel - Cluster The type of Redis being communicated with - standalone, sentinel, or clustered.
SSL Context Service SSL Context Service If specified, this service will be used to create an SSL Context that will be used to secure communications; if not specified, communications will not be secure
Sentinel Master Sentinel Master The name of the sentinel master, require when Mode is set to Sentinel
Sentinel Password Sentinel Password The password used to authenticate to the Redis Sentinel server. See the 'requirepass' and 'sentinel sentinel-pass' properties in sentinel.conf.
Sentinel Username Sentinel Username The username used to authenticate to the Redis sentinel server.
Username Username The username used to authenticate to the Redis server.
Display Name API Name Default Value Allowable Values Description
TTL * redis-cache-ttl 0 secs Indicates how long the data should exist in Redis. Setting '0 secs' would mean the data would exist forever
Redis Connection Pool * redis-connection-pool
Display Name API Name Default Value Allowable Values Description
Record Reader * Record Reader The underlying RecordReaderFactory service that will be used to read records before filtering is applied.
Property Description
Record Reader Specifies the Controller Service to use for reading incoming data
Record Writer Specifies the Controller Service to use for writing out the records
Name Description
failure If a FlowFile cannot be transformed from the configured input format to the configured output format, the unchanged FlowFile will be routed to this relationship
success FlowFiles that are successfully transformed will be routed to this relationship
Name Description
record.error.message This attribute provides on failure the error message encountered by the Reader or Writer.
Property Description
Record Reader Specifies the Controller Service to use for reading incoming data
Record Writer Specifies the Controller Service to use for writing out the records
Name Description
failure If a FlowFile cannot be transformed from the configured input format to the configured output format, the unchanged FlowFile will be routed to this relationship
success FlowFiles that are successfully transformed will be routed to this relationship
Name Description
record.index This attribute provides the current row index and is only available inside the literal value expression.
Property Description
Character Set The Character Set in which the file is encoded
Evaluation Mode Run the 'Replacement Strategy' against each line separately (Line-by-Line) or buffer the entire file into memory (Entire Text) and run against that.
Line-by-Line Evaluation Mode Run the 'Replacement Strategy' against each line separately (Line-by-Line) for all lines in the FlowFile, First Line (Header) alone, Last Line (Footer) alone, Except the First Line (Header) or Except the Last Line (Footer).
Maximum Buffer Size Specifies the maximum amount of data to buffer (per file or per line, depending on the Evaluation Mode) in order to apply the replacement. If 'Entire Text' (in Evaluation Mode) is selected and the FlowFile is larger than this value, the FlowFile will be routed to 'failure'. In 'Line-by-Line' Mode, if a single line is larger than this value, the FlowFile will be routed to 'failure'. A default value of 1 MB is provided, primarily for 'Entire Text' mode. In 'Line-by-Line' Mode, a value such as 8 KB or 16 KB is suggested. This value is ignored if the <Replacement Strategy> property is set to one of: Append, Prepend, Always Replace
Regular Expression The Search Value to search for in the FlowFile content. Only used for 'Literal Replace' and 'Regex Replace' matching strategies
Replacement Strategy The strategy for how and what to replace within the FlowFile's text content.
Replacement Value The value to insert using the 'Replacement Strategy'. Using "Regex Replace" back-references to Regular Expression capturing groups are supported, but back-references that reference capturing groups that do not exist in the regular expression will be treated as literal value. Back References may also be referenced using the Expression Language, as '$1', '$2', etc. The single-tick marks MUST be included, as these variables are not "Standard" attribute names (attribute names must be quoted unless they contain only numbers, letters, and _).
Text to Append The text to append to the end of the FlowFile, or each line, depending on the configured value of the Evaluation Mode property
Text to Prepend The text to prepend to the start of the FlowFile, or each line, depending on the configured value of the Evaluation Mode property
Name Description
failure FlowFiles that could not be updated are routed to this relationship
success FlowFiles that have been successfully processed are routed to this relationship. This includes both FlowFiles that had text replaced and those that did not.
Property Description
Character Set The Character Set in which the file is encoded
Mapping File The name of the file (including the full path) containing the Mappings.
Mapping File Refresh Interval The polling interval to check for updates to the mapping file. The default is 60s.
Matching Group The number of the matching group of the provided regex to replace with the corresponding value from the mapping file (if it exists).
Maximum Buffer Size Specifies the maximum amount of data to buffer (per file) in order to apply the regular expressions. If a FlowFile is larger than this value, the FlowFile will be routed to 'failure'
Regular Expression The Regular Expression to search for in the FlowFile content
Name Description
failure FlowFiles that could not be updated are routed to this relationship
success FlowFiles that have been successfully updated are routed to this relationship, as well as FlowFiles whose content does not match the given Regular Expression
Display Name API Name Default Value Allowable Values Description
Proxy Configuration Service proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests. In case of SOCKS, it is not guaranteed that the selected SOCKS Version will be used by the processor.
Authentication Strategy * rest-lookup-authentication-strategy NONE - None - Basic - OAuth2 Authentication strategy to use with REST service.
Basic Authentication Password rest-lookup-basic-auth-password The password to be used by the client to authenticate against the Remote URL.
Basic Authentication Username rest-lookup-basic-auth-username The username to be used by the client to authenticate against the Remote URL. Cannot include control characters (0-31), ':', or DEL (127).
Connection Timeout * rest-lookup-connection-timeout 5 secs Max wait time for connection to remote service.
Use Digest Authentication rest-lookup-digest-auth false - true - false Whether to communicate with the website using Digest Authentication. 'Basic Authentication Username' and 'Basic Authentication Password' are used for authentication.
OAuth2 Access Token Provider * rest-lookup-oauth2-access-token-provider Enables managed retrieval of OAuth2 Bearer Token applied to HTTP requests using the Authorization Header.
Read Timeout * rest-lookup-read-timeout 15 secs Max wait time for response from remote service.
Record Path rest-lookup-record-path An optional record path that can be used to define where in a record to get the real data to merge into the record set to be enriched. See documentation for examples of when this might be useful.
Record Reader * rest-lookup-record-reader The record reader to use for loading the payload and handling it as a record set.
Response Handling Strategy * rest-lookup-response-handling-strategy RETURNED - Returned - Evaluated Whether to return all responses or throw errors for unsuccessful HTTP status codes.
SSL Context Service rest-lookup-ssl-context-service The SSL Context Service used to provide client certificate information for TLS/SSL connections.
URL * rest-lookup-url The URL for the REST endpoint. Expression language is evaluated against the lookup key/value pairs, not flowfile attributes.
Property Description
Fail on Non-numerical Overwrite If the FlowFile already has the attribute defined in 'Retry Attribute' that is *not* a number, fail the FlowFile instead of resetting that value to '1'
maximum-retries The maximum number of times a FlowFile can be retried before being passed to the 'retries_exceeded' relationship
penalize-retries If set to 'true', this Processor will penalize input FlowFiles before passing them to the 'retry' relationship. This does not apply to the 'retries_exceeded' relationship.
retry-attribute The name of the attribute that contains the current retry count for the FlowFile. WARNING: If the name matches an attribute already on the FlowFile that does not contain a numerical value, the processor will either overwrite that attribute with '1' or fail based on configuration.
reuse-mode Defines how the Processor behaves if the retry FlowFile has a different retry UUID than the instance that received the FlowFile. This generally means that the attribute was not reset after being successfully retried by a previous instance of this processor.
Name Description
failure The processor is configured such that a non-numerical value on 'Retry Attribute' results in a failure instead of resetting that value to '1'. This will immediately terminate the limited feedback loop. Might also include when 'Maximum Retries' contains attribute expression language that does not resolve to an Integer.
retries_exceeded Input FlowFile has exceeded the configured maximum retry count, do not pass this relationship back to the input Processor to terminate the limited feedback loop.
retry Input FlowFile has not exceeded the configured maximum retry count, pass this relationship back to the input Processor to create a limited feedback loop.
Name Description
Retry Attribute User defined retry attribute is updated with the current retry count
Retry Attribute .uuid User defined retry attribute with .uuid that determines what processor retried the FlowFile last
Property Description
Routing Strategy Specifies how to determine which relationship to use when evaluating the Expression Language
Name Description
unmatched FlowFiles that do not match any user-define expression will be routed here
Name Description
RouteOnAttribute.Route The relation to which the FlowFile was routed
Property Description
Character Set The Character Set in which the file is encoded
Content Buffer Size Specifies the maximum amount of data to buffer in order to apply the regular expressions. If the size of the FlowFile exceeds this value, any amount of this value will be ignored
Match Requirement Specifies whether the entire content of the file must match the regular expression exactly, or if any part of the file (up to Content Buffer Size) can contain the regular expression in order to be considered a match
Name Description
unmatched FlowFiles that do not match any of the user-supplied regular expressions will be routed to this relationship
Property Description
Character Set The Character Set in which the incoming text is encoded
Grouping Regular Expression Specifies a Regular Expression to evaluate against each line to determine which Group the line should be placed in. The Regular Expression must have at least one Capturing Group that defines the line's Group. If multiple Capturing Groups exist in the Regular Expression, the values from all Capturing Groups will be concatenated together. Two lines will not be placed into the same FlowFile unless they both have the same value for the Group (or neither line matches the Regular Expression). For example, to group together all lines in a CSV File by the first column, we can set this value to "(.*?),.*". Two lines that have the same Group but different Relationships will never be placed into the same FlowFile.
Ignore Case If true, capitalization will not be taken into account when comparing values. E.g., matching against 'HELLO' or 'hello' will have the same result. This property is ignored if the 'Matching Strategy' is set to 'Satisfies Expression'.
Ignore Leading/Trailing Whitespace Indicates whether or not the whitespace at the beginning and end of the lines should be ignored when evaluating the line.
Matching Strategy Specifies how to evaluate each line of incoming text against the user-defined properties.
Routing Strategy Specifies how to determine which Relationship(s) to use when evaluating the lines of incoming text against the 'Matching Strategy' and user-defined properties.
Name Description
original The original input file will be routed to this destination when the lines have been successfully routed to 1 or more relationships
unmatched Data that does not satisfy the required user-defined rules will be routed to this Relationship
Name Description
RouteText.Route The name of the relationship to which the FlowFile was routed.
RouteText.Group The value captured by all capturing groups in the 'Grouping Regular Expression' property. If this property is not set or contains no capturing groups, this attribute will not be added.
Property Description
Databricks Client Databricks Client Service.
Job ID Databricks Job ID
Job Name Databricks Job Name
Wait for Job Completion Wait for the Databricks job to complete before transferring the FlowFile to success
Name Description
failure Databricks failure relationship
success Databricks success relationship
Name Description
job.run.id The run id assigned to the invoked job
job.result.state The result state for the invoked job
error.code The error code for the SQL statement if an error occurred.
error.message The error message for the SQL statement if an error occurred.
Property Description
Batch Size The number of elements returned from the server in one batch.
Mongo Collection Name The name of the collection to use
Mongo Database Name The name of the database to use
allow-disk-use Set this to true to enable writing data to temporary files to prevent exceeding the maximum memory use limit during aggregation pipeline staged when handling large datasets.
json-type By default, MongoDB's Java driver returns "extended JSON". Some of the features of this variant of JSON may cause problems for other JSON parsers that expect only standard JSON types and conventions. This configuration setting controls whether to use extended JSON or provide a clean view that conforms to standard JSON.
mongo-agg-query The aggregation query to be executed.
mongo-charset Specifies the character set of the document data.
mongo-client-service If configured, this property will use the assigned client service for connection pooling.
mongo-date-format The date format string to use for formatting Date fields that are returned from Mongo. It is only applied when the JSON output format is set to Standard JSON.
mongo-query-attribute If set, the query will be written to a specified attribute on the output flowfiles.
results-per-flowfile How many results to put into a flowfile at once. The whole body will be treated as a JSON array of results.
Name Description
failure The input flowfile gets sent to this relationship when the query fails.
original The input flowfile gets sent to this relationship when the query succeeds.
results The result set of the aggregation will be sent to this relationship.
Display Name API Name Default Value Allowable Values Description
AWS Credentials Provider service * AWS Credentials Provider service The Controller Service that is used to obtain AWS credentials provider
Bucket * Bucket $\{s3.bucket\} The S3 Bucket to interact with
Object Key * Object Key $\{filename\} The S3 Object Key to use. This is analogous to a filename for traditional file systems.
Region * Region us-west-2 - AWS GovCloud (US) - AWS GovCloud (US-East) - US East (N. Virginia) - US East (Ohio) - US West (N. California) - US West (Oregon) - EU (Ireland) - EU (London) - EU (Paris) - EU (Frankfurt) - EU (Zurich) - EU (Stockholm) - EU (Milan) - EU (Spain) - Asia Pacific (Hong Kong) - Asia Pacific (Taipei) - Asia Pacific (Mumbai) - Asia Pacific (Hyderabad) - Asia Pacific (Singapore) - Asia Pacific (Sydney) - Asia Pacific (Jakarta) - Asia Pacific (Melbourne) - Asia Pacific (Malaysia) - Asia Pacific (Thailand) - Asia Pacific (Tokyo) - Asia Pacific (Seoul) - Asia Pacific (Osaka) - South America (Sao Paulo) - China (Beijing) - China (Ningxia) - Canada (Central) - Canada West (Calgary) - Middle East (UAE) - Middle East (Bahrain) - Africa (Cape Town) - US ISO East - US ISOB East (Ohio) - US ISO West - US ISOF East1 (California) - US ISOF South1 (Alpine) - Israel (Tel Aviv) - Mexico (Central) - EU ISOE West - Use 's3.region' Attribute The AWS Region to connect to.
Privilege Object Notes
`CREATE ZEROCOPY CONNECTOR` Schema Required to create a Zerocopy Connector. By default, the schema owner has this privilege.
`OPERATE` Zerocopy Connector Required to retrieve the connector configuration using `SYSTEM$GET_ZEROCOPY_CONNECTOR_CONFIG` and to disconnect the connector (`ALTER ... DISCONNECT`).
`USAGE` Zerocopy Connector Required to create a catalog-linked database from the connector (also requires `CREATE DATABASE` on the account).
`MODIFY` Zerocopy Connector Required to set or unset properties such as `COMMENT`.
`MONITOR` Zerocopy Connector Any privilege on the connector (for example, `MONITOR`) is sufficient to describe the connector, show connectors, or list shares.
`OWNERSHIP` Zerocopy Connector Required to rename or drop the connector.
`CREATE DATABASE` Account Required to create a catalog-linked database from a Zerocopy Connector (also requires `USAGE` on the connector).
State Description
`NEW` Initial state after the connector is created. No connection has been attempted yet.
`CONNECTING` A connection attempt is in progress. The connector enters this state after a Snowflake V2 Data Share Target is created in Salesforce Data Cloud.
`CONNECTED` The connection is established. Catalog-linked databases can only be created when the connector is in this state.
`CONNECT_ERROR` The connection attempt failed. The error message is persisted on the connector. You can retry the connection from this state.
`DISCONNECTING` A disconnection is in progress. The connector enters this state immediately after `ALTER ... DISCONNECT` is issued.
`DISCONNECTED` The connection has been dropped. You can reconnect from this state.
`DISCONNECT_ERROR` The disconnection attempt failed. The error message is persisted on the connector.
`DELETED` The connector has been dropped. This state is permanent — Zerocopy Connectors do not support `UNDROP`.
Display Name API Name Default Value Allowable Values Description
OAuth2 Access Token Provider * OAuth2 Access Token Provider JWT Token Provider to use in order to retrieve an access token from Salesforce that will be exchanged for a Data Cloud API token.
Refresh Window * Refresh Window 0 s The service will attempt to refresh tokens expiring within the refresh window, subtracting the configured duration from the token expiration.
Salesforce Instance * Salesforce Instance The hostname of the Salesforce instance including the domain such as MyDomainName.my.salesforce.com
Web Client Service * Web Client Service The Web Client Service to use for communicating with Salesforce
Property Description
record-reader Specifies the Controller Service to use for parsing incoming data and determining the data's schema
record-writer Specifies the Controller Service to use for writing results to a FlowFile
sample-record-interval Specifies the number of records to skip before writing a record to the outgoing FlowFile. This property is only used if Sampling Strategy is set to Interval Sampling. A value of zero (0) will cause no records to be included in theoutgoing FlowFile, a value of one (1) will cause all records to be included, and a value of two (2) will cause half the records to be included, and so on.
sample-record-probability Specifies the probability (as a percent from 0-100) of a record being included in the outgoing FlowFile. This property is only used if Sampling Strategy is set to Probabilistic Sampling. A value of zero (0) will cause no records to be included in theoutgoing FlowFile, and a value of 100 will cause all records to be included in the outgoing FlowFile..
sample-record-random-seed Specifies a particular number to use as the seed for the random number generator (used by probabilistic strategies). Setting this property will ensure the same records are selected even when using probabilistic strategies.
sample-record-range Specifies the range of records to include in the sample, from 1 to the total number of records. An example is '3,6-8,20-' which includes the third record, the sixth, seventh and eighth records, and all records from the twentieth record on. Commas separate intervals that don't overlap, and an interval can be between two numbers (i.e. 6-8) or up to a given number (i.e. -5), or from a number to the number of the last record (i.e. 20-). If this property is unset, all records will be included.
sample-record-reservoir Specifies the number of records to write to the outgoing FlowFile. This property is only used if Sampling Strategy is set to reservoir-based strategies such as Reservoir Sampling.
sample-record-sampling-strategy Specifies which method to use for sampling records from the incoming FlowFile
Name Description
failure If a FlowFile fails processing for any reason (for example, any record is not valid), the original FlowFile will be routed to this relationship
original The original FlowFile is routed to this relationship if sampling is successful
success The FlowFile is routed to this relationship if the sampling completed successfully
Name Description
mime.type The MIME type indicated by the record writer
record.count The number of records in the resulting flow file
Privilege Object Notes
`CREATE ZEROCOPY CONNECTOR` Schema Required to create a Zerocopy Connector. By default, the schema owner has this privilege.
`OPERATE` Zerocopy Connector Required to connect or disconnect (`ALTER ... CONNECT` / `ALTER ... DISCONNECT`) and to publish a data product (`SYSTEM$SAP_PUBLISH_DATA_PRODUCT`).
`USAGE` Zerocopy Connector Required to create a catalog-linked database from the connector (also requires `CREATE DATABASE` on the account) and to add or remove a share from the connector (also requires `OWNERSHIP` on the share).
`MODIFY` Zerocopy Connector Required to set or unset properties (comment, share_back, etc.).
`MONITOR` Zerocopy Connector Any privilege on the connector (e.g. `MONITOR`) is sufficient to describe the connector, show connectors, or list shares.
`OWNERSHIP` Zerocopy Connector Required to rename or drop the connector.
`CREATE DATABASE` Account Required to create a catalog-linked database from a Zerocopy Connector (also requires `USAGE` on the connector).
State Description
`NEW` Initial state after the connector is created. No connection has been attempted yet.
`CONNECTING` A connection attempt is in progress. The connector enters this state immediately after `ALTER ... CONNECT` is issued.
`CONNECTED` The connection is established. Catalog-linked databases can only be created when the connector is in this state. Sharing data between Snowflake and SAP® BDC is only allowed when the connector is in this state.
`CONNECT_ERROR` The connection attempt failed. The error message is persisted on the connector. You can retry the connection from this state.
`DISCONNECTING` A disconnection is in progress. The connector enters this state immediately after `ALTER ... DISCONNECT` is issued.
`DISCONNECTED` The connection has been dropped. You can reconnect from this state.
`DISCONNECT_ERROR` The disconnection attempt failed. The error message is persisted on the connector.
`DELETED` The connector has been dropped. This state is permanent — Zerocopy Connectors do not support `UNDROP`.
Property Description
Attribute Pattern Regular Expression that specifies the names of attributes whose values will be matched against the terms in the dictionary
Dictionary File A new-line-delimited text file that includes the terms that should trigger a match. Empty lines are ignored. The contents of the text file are loaded into memory when the processor is scheduled and reloaded when the contents are modified.
Dictionary Filter Pattern A Regular Expression that will be applied to each line in the dictionary file. If the regular expression does not match the line, the line will not be included in the list of terms to search for. If a Matching Group is specified, only the portion of the term that matches that Matching Group will be used instead of the entire term. If not specified, all terms in the dictionary will be used and each term will consist of the text of the entire line in the file
Match Criteria If set to All Must Match, then FlowFiles will be routed to 'matched' only if all specified attributes 'values are found in the dictionary. If set to At Least 1 Must Match, FlowFiles will be routed to' matched' if any attribute specified is found in the dictionary
Name Description
matched FlowFiles whose attributes are found in the dictionary will be routed to this relationship
unmatched FlowFiles whose attributes are not found in the dictionary will be routed to this relationship
Property Description
Dictionary Encoding Indicates how the dictionary is encoded. If 'text', dictionary terms are new-line delimited and UTF-8 encoded; if 'binary', dictionary terms are denoted by a 4-byte integer indicating the term length followed by the term itself
Dictionary File The filename of the terms dictionary
Name Description
matched FlowFiles that match at least one term in the dictionary are routed to this relationship
unmatched FlowFiles that do not match any term in the dictionary are routed to this relationship
Name Description
matching.term The term that caused the Processor to route the FlowFile to the 'matched' relationship; if FlowFile is routed to the 'unmatched' relationship, this attribute is not added
Property Description
Module Directory Comma-separated list of paths to files and/or directories which contain modules required by the script.
Record Reader The Record Reader to use parsing the incoming FlowFile into Records
Record Writer The Record Writer to use for serializing Records after they have been transformed
Script Body Body of script to execute. Only one of Script File or Script Body may be used
Script Engine The Language to use for the script
Script File Path to script file to execute. Only one of Script File or Script Body may be used
Required Permission Explanation
execute code Provides operator the ability to execute arbitrary code assuming all permissions that NiFi has.
Name Description
failure In case of any issue during processing the incoming FlowFile, the incoming FlowFile will be routed to this relationship.
original After successful processing, the incoming FlowFile will be transferred to this relationship. This happens regardless the number of filtered or remaining records.
success Matching records of the original FlowFile will be routed to this relationship. If there are no matching records, no FlowFile will be routed here.
Name Description
mime.type Sets the mime.type attribute to the MIME Type specified by the Record Writer
record.count The number of records within the flow file.
record.error.message This attribute provides on failure the error message encountered by the Reader or Writer.
Display Name API Name Default Value Allowable Values Description
Module Directory Module Directory Comma-separated list of paths to files and/or directories which contain modules required by the script.
Script Body Script Body Body of script to execute. Only one of Script File or Script Body may be used
Script Engine * Script Engine Groovy - Groovy Language Engine for executing scripts
Script File Script File Path to script file to execute. Only one of Script File or Script Body may be used
Required Permission Explanation
execute code Provides operator the ability to execute arbitrary code assuming all permissions that NiFi has.
Property Description
Module Directory Comma-separated list of paths to files and/or directories which contain modules required by the script.
Record Reader The Record Reader to use parsing the incoming FlowFile into Records
Record Writer The Record Writer to use for serializing Records after they have been transformed
Script Body Body of script to execute. Only one of Script File or Script Body may be used
Script Engine The Language to use for the script
Script File Path to script file to execute. Only one of Script File or Script Body may be used
Required Permission Explanation
execute code Provides operator the ability to execute arbitrary code assuming all permissions that NiFi has.
Name Description
failure If a FlowFile cannot be partitioned from the configured input format to the configured output format, the unchanged FlowFile will be routed to this relationship
original Once all records in an incoming FlowFile have been partitioned, the original FlowFile is routed to this relationship.
success FlowFiles that are successfully partitioned will be routed to this relationship
Name Description
partition The partition of the outgoing flow file. If the script indicates that the partition has a null value, the attribute will be set to the literal string "<null partition>" (without quotes). Otherwise, the attribute is set to the String representation of whatever value is returned by the script.
mime.type Sets the mime.type attribute to the MIME Type specified by the Record Writer
record.count The number of records within the flow file.
record.error.message This attribute provides on failure the error message encountered by the Reader or Writer.
fragment.index A one-up number that indicates the ordering of the partitioned FlowFiles that were created from a single parent FlowFile
fragment.count The number of partitioned FlowFiles generated from the parent FlowFile
Display Name API Name Default Value Allowable Values Description
Module Directory Module Directory Comma-separated list of paths to files and/or directories which contain modules required by the script.
Script Body Script Body Body of script to execute. Only one of Script File or Script Body may be used
Script Engine * Script Engine Groovy - Groovy Language Engine for executing scripts
Script File Script File Path to script file to execute. Only one of Script File or Script Body may be used
Required Permission Explanation
execute code Provides operator the ability to execute arbitrary code assuming all permissions that NiFi has.
Display Name API Name Default Value Allowable Values Description
Module Directory Module Directory Comma-separated list of paths to files and/or directories which contain modules required by the script.
Script Body Script Body Body of script to execute. Only one of Script File or Script Body may be used
Script Engine * Script Engine Groovy - Groovy Language Engine for executing scripts
Script File Script File Path to script file to execute. Only one of Script File or Script Body may be used
Required Permission Explanation
execute code Provides operator the ability to execute arbitrary code assuming all permissions that NiFi has.
Display Name API Name Default Value Allowable Values Description
Module Directory Module Directory Comma-separated list of paths to files and/or directories which contain modules required by the script.
Script Body Script Body Body of script to execute. Only one of Script File or Script Body may be used
Script Engine * Script Engine Groovy - Groovy Language Engine for executing scripts
Script File Script File Path to script file to execute. Only one of Script File or Script Body may be used
Required Permission Explanation
execute code Provides operator the ability to execute arbitrary code assuming all permissions that NiFi has.
Property Description
Module Directory Comma-separated list of paths to files and/or directories which contain modules required by the script.
Record Reader The Record Reader to use parsing the incoming FlowFile into Records
Record Writer The Record Writer to use for serializing Records after they have been transformed
Script Body Body of script to execute. Only one of Script File or Script Body may be used
Script Engine The Language to use for the script
Script File Path to script file to execute. Only one of Script File or Script Body may be used
Required Permission Explanation
execute code Provides operator the ability to execute arbitrary code assuming all permissions that NiFi has.
Name Description
failure Any FlowFile that cannot be transformed will be routed to this Relationship
success Each FlowFile that were successfully transformed will be routed to this Relationship
Name Description
mime.type Sets the mime.type attribute to the MIME Type specified by the Record Writer
record.count The number of records in the FlowFile
record.error.message This attribute provides on failure the error message encountered by the Reader or Writer.
Property Description
Module Directory Comma-separated list of paths to files and/or directories which contain modules required by the script.
Record Reader The Record Reader to use parsing the incoming FlowFile into Records
Record Writer The Record Writer to use for serializing Records after they have been transformed
Script Body Body of script to execute. Only one of Script File or Script Body may be used
Script Engine The Language to use for the script
Script File Path to script file to execute. Only one of Script File or Script Body may be used
Required Permission Explanation
execute code Provides operator the ability to execute arbitrary code assuming all permissions that NiFi has.
Name Description
failure In case of any issue during processing the incoming flow file, the incoming FlowFile will be routed to this relationship.
invalid FlowFile containing the invalid records from the incoming FlowFile will be routed to this relationship. If there are no invalid records, no FlowFile will be routed to this Relationship.
original After successful processing, the incoming FlowFile will be transferred to this relationship. This happens regardless the FlowFiles might routed to "valid" and "invalid" relationships.
valid FlowFile containing the valid records from the incoming FlowFile will be routed to this relationship. If there are no valid records, no FlowFile will be routed to this Relationship.
Name Description
mime.type Sets the mime.type attribute to the MIME Type specified by the Record Writer
record.count The number of records within the flow file.
record.error.message This attribute provides on failure the error message encountered by the Reader or Writer.
Property Description
Aggregation Results Format Format of Aggregation output.
Aggregation Results Split Output a flowfile containing all aggregations or one flowfile for each individual aggregation.
Aggregations One or more query aggregations (or "aggs"), in JSON syntax. Ex: \{"items": \{"terms": \{"field": "product", "size": 10\}\}\}
Client Service An Elasticsearch client service to use for running queries.
Fields Fields of indexed documents to be retrieved, in JSON syntax. Ex: ["user.id", "http.response.*", \{"field": "@timestamp", "format": "epoch_millis"\}]
Index The name of the index to use.
Max JSON Field String Length The maximum allowed length of a string value when parsing a JSON document or attribute.
Output No Hits Output a "hits" flowfile even if no hits found for query. If true, an empty "hits" flowfile will be output even if "aggregations" are output.
Pagination Keep Alive Pagination "keep_alive" period. Period Elasticsearch will keep the scroll/pit cursor alive in between requests (this is not the time expected for all pages to be returned, but the maximum allowed time for requests between page retrievals).
Pagination Type Pagination method to use. Not all types are available for all Elasticsearch versions, check the Elasticsearch docs to confirm which are applicable and recommended for your service.
Query A query in JSON syntax, not Lucene syntax. Ex: \{"query":\{"match":\{"somefield":"somevalue"\}\}\}. If the query is empty, a default JSON Object will be used, which will result in a "match_all" query in Elasticsearch.
Query Attribute If set, the executed query will be set on each result flowfile in the specified attribute.
Query Clause A "query" clause in JSON syntax, not Lucene syntax. Ex: \{"match":\{"somefield":"somevalue"\}\}. If the query is empty, a default JSON Object will be used, which will result in a "match_all" query in Elasticsearch.
Query Definition Style How the JSON Query will be defined for use by the processor.
Restart On Finish Whether the processor should start another search with the same query once a paginated search has completed.
Script Fields Fields to created using script evaluation at query runtime, in JSON syntax. Ex: \{"test1": \{"script": \{"lang": "painless", "source": "doc[ 'price'].value * 2"\}\}, "test2": \{"script": \{"lang": "painless", "source": "doc[ 'price'].value * params.factor", "params": \{"factor": 2.0\}\}\}\}
Search Results Format Format of Hits output.
Search Results Split Output a flowfile containing all hits or one flowfile for each individual hit or one flowfile containing all hits from all paged responses.
Size The maximum number of documents to retrieve in the query. If the query is paginated, this "size" applies to each page of the query, not the "size" of the entire result set.
Sort Sort results by one or more fields, in JSON syntax. Ex: [\{"price" : \{"order" : "asc", "mode" : "avg"\}\}, \{"post_date" : \{"format": "strict_date_optional_time_nanos"\}\}]
Type The type of this document (used by Elasticsearch for indexing and searching).
Scopes Description
LOCAL The pagination state (scrollId, searchAfter, pitId, hitCount, pageCount, pageExpirationTimestamp) is retained in between invocations of this processor until the Scroll/PiT has expired (when the current time is later than the last query execution plus the Pagination Keep Alive interval).
Name Description
aggregations Aggregations are routed to this relationship.
failure All flowfiles that fail for reasons unrelated to server availability go to this relationship.
hits Search hits are routed to this relationship.
retry All flowfiles that fail due to server/cluster availability go to this relationship.
Name Description
mime.type application/json
aggregation.name The name of the aggregation whose results are in the output flowfile
aggregation.number The number of the aggregation whose results are in the output flowfile
page.number The number of the page (request), starting from 1, in which the results were returned that are in the output flowfile
hit.count The number of hits that are in the output flowfile
elasticsearch.query.error The error message provided by Elasticsearch if there is an error querying the index.
Topic Description
[Openflow gen 1 and gen 2](/user-guide/data-integration/openflow/gen2/openflow-generations) Compare gen 1 and gen 2 deployments, runtimes, and connectors; authorization and lifecycle differences; how to identify resources and which documentation to follow.
[Quickstart: gen 2 Openflow](/user-guide/data-integration/openflow/gen2/quickstart) Prerequisites, privilege grants, and example commands to create gen 2 resources.
[gen 2 connector configuration and versioning](/user-guide/data-integration/openflow/gen2/connector-versioning) Versioned configuration for SQL, Git, and automation (optional background if you use the UI only). Stage access and Git workflow for reusing validated configs.
[Configure a connector with the setup wizard](/user-guide/data-integration/openflow/gen2/setup-connector-wizard) Step-by-step setup wizard for gen 2 connectors.
[Configure a gen 2 connector with SQL](/user-guide/data-integration/openflow/gen2/configure-connector-sql) Create and configure gen 2 connectors with SQL and stage commands (programmatic setup).
[Manage the gen 2 Openflow connector lifecycle](/user-guide/data-integration/openflow/gen2/manage-connector-lifecycle) Start, stop, and remove gen 2 connectors after installation.
[Monitor connectors using the Openflow Connectors Dashboard](/user-guide/data-integration/openflow/connectors-dashboard) Monitor gen 2 connector health, throughput, and ingestion status.
Migrate deployment and runtimes (Private Preview) Migrate an existing gen 1 deployment and all its runtimes to gen 2 objects. Covers prerequisites, the migration wizard, post-migration access grants, rollback constraints, and troubleshooting. Contact your Snowflake account representative for access.
Migrate connectors (Private Preview) Migrate individual gen 1 connectors to gen 2 connector instances. Covers prerequisites, Snowflake Secrets rewiring, the disabled source connector, and failure recovery. Contact your Snowflake account representative for access.
Property Description
Segment Size The maximum data size in bytes for each segment
Name Description
original The original FlowFile will be sent to this relationship
segments All segments will be sent to this relationship. If the file was small enough that it was not segmented, a copy of the original is sent to this relationship as well as original
Name Description
fragment.identifier All segments produced from the same parent FlowFile will have the same randomly generated UUID added for this attribute
fragment.index A one-up number that indicates the ordering of the segments that were created from a single parent FlowFile
fragment.count The number of segments generated from the parent FlowFile
segment.original.filename The filename of the parent FlowFile
segment.original.filename The filename will be updated to include the parent's filename, the segment index, and the segment count
Order Task Description Persona
1 [Setup core Snowflake](/user-guide/data-integration/openflow/setup-openflow-spcs-sf) Before creating a deployment, you must configure core Snowflake which include an Openflow admin role, required privileges, and network configuration. Snowflake administrator
2 Optionally [Set up PrivateLink UI access](/user-guide/data-integration/openflow/setup-openflow-spcs-configure-pr-ui) Configure PrivateLink to access the Snowflake Openflow Runtime UI using private connectivity. Snowflake administrator
3 [Create deployment](/user-guide/data-integration/openflow/setup-openflow-spcs-deployment) After configuring core Snowflake, you then create an Openflow deployment. Gen 2 uses `CREATE OPENFLOW DEPLOYMENT` (SQL); gen 1 uses the Openflow UI. Optionally, configure an Openflow-specific event table to store Openflow logs and metrics. Deployment engineer, Snowflake administrator for event table configuration
4 [Create the execute-as role and external access integrations](/user-guide/data-integration/openflow/setup-openflow-spcs-create-rr) Create the role that connectors use to access Snowflake resources. This is called the execute-as role. Both require external access integrations for Snowflake deployments. Data engineer
5 [Create runtime](/user-guide/data-integration/openflow/setup-openflow-spcs-create-runtime) Create a runtime associated with the previously created role. Gen 2 uses `CREATE OPENFLOW RUNTIME` (SQL); gen 1 uses the Openflow UI. Data engineer
6 [Configure allowed domains for Openflow connectors](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list) Configure access to external domains for Openflow connectors. Data engineer
7 [Connect your data sources using Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) Configure one or more connectors in the %ofsfspcs%. Gen 2 connectors can be created with SQL (`CREATE OPENFLOW CONNECTOR`) or the [setup wizard](/user-guide/data-integration/openflow/gen2/setup-connector-wizard). Gen 1 connectors are installed from the catalog on the runtime canvas. Data engineer
Option Use when What it does not cover
[Allowed domains](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list) The source is reachable from Snowflake on the public internet (or another path Snowflake already allows), and you only need to allowlist the source host and port. Private hostnames that Snowflake can't resolve or reach. Use [outbound private connectivity](/user-guide/private-connectivity-outbound) or DCP for those.
[Outbound private connectivity](/user-guide/private-connectivity-outbound) The source is a cloud service that offers a private endpoint, such as Amazon S3 or Azure Storage. You provision a private endpoint in Snowflake and create the network rule with `TYPE = PRIVATE_HOST_PORT`, so traffic uses the cloud provider's private connectivity instead of the public internet. Hosts in your own network with no cloud private endpoint service in front of them, such as an on-premises database. Snowflake accounts that aren't on Business Critical Edition. Use DCP for those.
[Data Connectivity Proxy](/user-guide/data-connectivity-proxy) You want to keep an %ofsfspcs% and still ingest from databases, Kafka brokers, or APIs that only your network can reach. Moving the runtime and data processing itself into your VPC. If that is a need, use [Openflow - BYOC](/user-guide/data-integration/openflow/about-byoc).
Symptom Likely cause What to check
Connector fails to connect; public allowlisted sources on the same runtime still work The DCP external access integration isn't on the runtime, or the runtime role lacks `USAGE` Confirm the DCP external access integration is selected on the runtime and granted to the runtime role
(gen 1 connectors) Your connector fails to run with the following error: `Caused by: org.postgresql.util.PSQLException: The connection attempt failed.` `Caused by: java.net.UnknownHostException` The external access integration attached to the runtime doesn't include the network rule that provides access to the source through DCP. The hostname and port defined in the network rule included in the EAI don't match the hostname and port in the connection string. Make sure your network rule is defined using the correct source hostname and port, is attached to the correct EAI, and matches the connection string that you are using in the connector.
(gen 2 connectors) Source connectivity validation fails with error message: There is no egress Network Rule in ``'s External Access Integration(s) (EAI) that allows access to `` The external access integration attached to the runtime doesn't include the network rule that provides access to the source through DCP. The hostname and port defined in the network rule included in the EAI don't match the hostname and port in the connection string. Make sure your network rule is defined using the correct source hostname and port, is attached to the correct EAI, and matches the connection string that you are using in the connector.
(gen 2 connectors) Source connectivity validation fails with error message: Failed to connect to the source database. Failed to establish Database Connection (gen 1 connectors) Your connector fails with error message: `Caused by: org.postgresql.util.PSQLException: The connection attempt failed.` `Caused by: java.net.SocketTimeoutException: Read timed out` The agent host can't reach the source, or the proxy object is disabled Verify agent-to-source reachability and that the proxy is enabled. See [](/user-guide/data-connectivity-proxy-troubleshoot#label-dcp-ts-cannot-reach-source).
Field Description
**Runtime Name** Enter a name for your runtime.
**Deployment** drop downChoose the deployment previously created in [](/user-guide/data-integration/openflow/setup-openflow-spcs-deployment)
**Node Type** Choose a node type from the **Node type** drop-down list. This specifies the size of y[Runtime sizing and packing for CDC connectors]r nodes. For guidance on choosing a size and node count, see [](/user-guide/data-integration/openflow/connectors/cdc-runtime-sizing).
**Min/Max node** In the **Min/Max node** range selector, select a range. The minimum value specifies the number of nodes that the runtime starts with when idle and the maximum value specifies the number of nodes that the runtime can scale up to, in the event of high data volume or CPU load.
Choose the execute-as role previously created in [](/user-guide/data-integration/openflow/setup-openflow-spcs-create-rr).
**Usage Roles** Optionally, select the roles created to grant usage to the runtime for required databases, schema, and table access.
**External Access Integrations** Optionally, select the previously created external access integrations to grant access to external resources.
Service Actions Resources (ARNs) Purpose
Amazon Kinesis Data Streams `kinesis:DescribeStream`, `kinesis:DescribeStreamConsumer`, `kinesis:GetRecords`, `kinesis:GetShardIterator`, `kinesis:ListShards`, `kinesis:RegisterStreamConsumer` `arn:aws:kinesis:${REGION}:${ACCOUNT_ID}:stream/${STREAM_NAME}` Discovers shards, reads records through shared-throughput polling, resolves the stream ARN, registers an Enhanced Fan-Out consumer, and polls consumer status during registration.
Amazon Kinesis Data Streams `kinesis:DeregisterStreamConsumer`, `kinesis:DescribeStreamConsumer`, `kinesis:SubscribeToShard` `arn:aws:kinesis:${REGION}:${ACCOUNT_ID}:stream/${STREAM_NAME}/consumer/*` Describes, subscribes to, and deregisters Enhanced Fan-Out consumers by consumer ARN.
Amazon DynamoDB `dynamodb:CreateTable`, `dynamodb:DeleteTable`, `dynamodb:DescribeTable`, `dynamodb:GetItem`, `dynamodb:PutItem`, `dynamodb:Query`, `dynamodb:Scan`, `dynamodb:UpdateItem` `arn:aws:dynamodb:${REGION}:${ACCOUNT_ID}:table/${APPLICATION_NAME}`, `arn:aws:dynamodb:${REGION}:${ACCOUNT_ID}:table/${APPLICATION_NAME}_migration` Creates and manages the checkpoint/lease table (shard leases, node heartbeats, checkpoints) and a temporary migration table used during one-time migration from legacy checkpoint tables.
Placeholder Description
`${REGION}` Your AWS region (for example, `us-east-1`)
`${ACCOUNT_ID}` Your AWS account ID (for example, `123456789012`)
`${STREAM_NAME}` The value of the **AWS Kinesis Stream Name** connector parameter
`${APPLICATION_NAME}` The value of the **AWS Kinesis Application Name** connector parameter. Used as the DynamoDB checkpoint table name and as the Enhanced Fan-Out registered consumer name.
Object Privilege Notes
Database USAGE
Schema USAGE
Table OWNERSHIP Required for the connector to ingest data into a table.
Service Purpose PrivateLink support
Amazon Kinesis Data Streams Reads stream records. Supported by this connector.
Amazon DynamoDB Stores checkpoint metadata for processed records. Not supported. Use the public endpoint.
Parameter Description Required
AWS Access Key ID The AWS Access Key ID to connect to your Kinesis Stream and DynamoDB. Yes
AWS Kinesis Region The AWS Region to connect to. Use regular AWS region format, for example: `us-west-2`, `ap-southeast-1`, `eu-west-1`. See the AWS Regions (https://docs.aws.amazon.com/general/latest/gr/rande.html#kinesis_region) page. Yes
AWS Secret Access Key The AWS Secret Access Key to connect to your Kinesis Stream and DynamoDB. Yes
AWS Kinesis Application Name The name that is used as the DynamoDB table name for tracking the application's progress on Kinesis Stream consumption. Yes
AWS Kinesis Consumer Type The strategy used to read records from a Kinesis Stream. Must be one of the following values: **SHARED_THROUGHPUT**, **ENHANCED_FAN_OUT**. For more information, see Differences between shared throughput consumer and enhanced fan-out consumer (https://docs.aws.amazon.com/streams/latest/dev/enhanced-consumers.html). Yes
AWS Kinesis Initial Stream Position The initial stream position from which the data starts replication. This takes effect only during the initial start for a given AWS Kinesis Application Name. Possible values are: **LATEST**: Latest stored record, **TRIM_HORIZON**: Earliest stored record. Yes
AWS Kinesis Stream Name The AWS Kinesis Stream Name to consume data from. Yes
Snowflake Destination Database The database where data will be persisted. It must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. Yes
Snowflake Destination Schema The schema where data will be persisted, which must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. See the following examples: `CREATE SCHEMA SCHEMA_NAME` or `CREATE SCHEMA schema_name`: use `SCHEMA_NAME`. `CREATE SCHEMA "schema_name"` or `CREATE SCHEMA "SCHEMA_NAME"`: use `schema_name` or `SCHEMA_NAME`, respectively. Yes
Snowflake Destination Table The table where data will be persisted. It must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. Yes
Field Name Field Type Example Value Description
stream String `stream-name` The name of the Kinesis stream the record came from.
shardId String `shardId-000000000001` The identifier of the shard in the stream the record came from.
approximateArrival Number `1782092074893` The approximate time that the record was inserted into the stream, as a Unix timestamp in epoch milliseconds.
partitionKey String `key-1234` The partition key specified by the data producer for the record.
sequenceNumber String `123456789` The unique sequence number assigned by Kinesis Data Streams to the record in the shard.
subSequenceNumber Number `2` The subsequence number for the record (used for aggregated records with the same sequence number).
shardedSequenceNumber String `12345678900002` A combination of the sequence number and the subsequence number for the record.
Column Description
`name` Name of the Zerocopy Connector.
`partner` The data partner (for example, `SAP_BDC`).
`config` The configuration of the data partner. For SAP® BDC, this contains the SAP® BDC Connector Endpoint.
`status` Current connector state. See [](#connector-states).
`connection_error` Error message if the connector is in `CONNECT_ERROR` or `DISCONNECT_ERROR` state; otherwise empty.
`catalog_linked_databases` Mounted catalog-linked databases that are visible to the current role.
`share_back` Whether sharing data from Snowflake to SAP® BDC is enabled for this connector.
`shares` Snowflake data shares that are associated with this connector.
`database_name` Database in which the connector resides.
`schema_name` Schema in which the connector resides.
`owner` Role that owns the connector.
`owner_role_type` Type of the owner role.
`comment` Optional comment set on the connector.
`created_on` Timestamp when the connector was created.
`updated_on` Timestamp when the connector was last updated.
Order Task Description Persona
1 Review [](#label-oracle-of-connector-prerequisites) Review and confirm all required prerequisites. **Snowflake account administrator**
2 [Enable the connector](#label-oracle-enable-service) Accept the Oracle XStream terms to make the connector visible in the list of available connectors. **Organization administrator (ORGADMIN)**
3 [Configure the Oracle database](/user-guide/data-integration/openflow/connectors/oracle/setup-oracledb) Configure the Oracle database for %oracleofc% including replication settings and credentials. **Oracle database administrator**
4 [Set up Snowflake](/user-guide/data-integration/openflow/connectors/oracle/setup-snowflake) Create the destination database, service user, role, warehouse, and key pair authentication for the %oracleofc%. **Snowflake account administrator**
5 [Configure the connector](/user-guide/data-integration/openflow/connectors/oracle/setup-connector) Install, configure, and run the %oracleofc% connector. **Snowflake account administrator**
6 [Set up licensing](#label-oracle-license-setup) Configure your licensing model after the connector detects your source database inventory. **Organization administrator (ORGADMIN)**
Table Classic scope (recommended when available) Granular scopes Jira API reference Notes
`BOARD` (always) `read:jira-work` (Get filter only) **Get all boards:** `read:board-scope:jira-software`, `read:project:jira`
**Get configuration:** `read:board-scope.admin:jira-software`, `read:project:jira`
**Get filter:** `read:filter:jira`, `read:group:jira`, `read:project:jira`, `read:project-role:jira`, `read:user:jira`, `read:jql:jira`, `read:application-role:jira`, `read:avatar:jira`, `read:issue-type-hierarchy:jira`
Get all boards (https://developer.atlassian.com/cloud/jira/software/rest/api-group-board/#api-rest-agile-1-0-board-get), Get configuration (https://developer.atlassian.com/cloud/jira/software/rest/api-group-board/#api-rest-agile-1-0-board-boardid-configuration-get), and Get filter (https://developer.atlassian.com/cloud/jira/platform/rest/v3/api-group-filters/#api-rest-api-3-filter-id-get) Get all boards and Get configuration are Jira Software endpoints and don't have classic scopes. Get filter is a Jira Platform endpoint.
`SPRINT` (populates `SPRINT` and `BOARD_SPRINT`) None. `read:sprint:jira-software` Get all sprints (https://developer.atlassian.com/cloud/jira/software/rest/api-group-board/#api-rest-agile-1-0-board-boardid-sprint-get) Atlassian documents only a granular Jira Software scope for this endpoint. The endpoint returns only sprints that the API token owner has permission to view.
`BOARD_PROJECT` None. `read:board-scope.admin:jira-software`, `read:project:jira` Get projects associated with the board (https://developer.atlassian.com/cloud/jira/software/rest/api-group-board/#api-rest-agile-1-0-board-boardid-project-get) Covered by the `BOARD` baseline. Atlassian documents only granular Jira Software scopes for this endpoint.
`BOARD_ISSUE` `read:jira-work` `read:issue-details:jira`, `read:field.default-value:jira`, `read:field.option:jira`, `read:field:jira`, `read:group:jira` Search for issues using JQL (https://developer.atlassian.com/cloud/jira/platform/rest/v3/api-group-issue-search/#api-rest-api-3-search-jql-post) **Browse projects** on the relevant projects. Issues that fail per-issue permission checks (for example, issue-level security) are skipped silently.
Parameter Description
Jira Email Email address for the Atlassian account used for authentication.
Jira API Token API access token for your Atlassian Jira account. See [Required API scopes](#label-jira-agile-api-scopes) for the scopes to configure.
Environment URL URL to the Atlassian Jira environment. For example, `https://your-domain.atlassian.net`.
Parameter Description Required
Destination Database The database where data will be persisted. It must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. Yes
Destination Schema The schema where data will be persisted, which must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. See the following examples:
- `CREATE SCHEMA SCHEMA_NAME` or `CREATE SCHEMA schema_name`: use `SCHEMA_NAME` - `CREATE SCHEMA "schema_name"` or `CREATE SCHEMA "SCHEMA_NAME"`: use `schema_name` or `SCHEMA_NAME`, respectively
Yes
Snowflake Authentication Strategy When using: - **Snowflake Openflow Deployment** or **BYOC**: Use SNOWFLAKE_MANAGED. This token is managed automatically by Snowflake. BYOC deployments must have previously configured [execute-as roles](#label-deployment-byoc-setup-runtime-role) to use SNOWFLAKE_MANAGED. - **BYOC**: Alternatively, BYOC can use KEY_PAIR as the value for the authentication strategy. Yes
Snowflake Account Identifier When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Snowflake account name formatted as [organization-name]-[account-name]. Yes
Snowflake Private Key When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. -
**KEY_PAIR**: Must be the RSA private key used for authentication.
The RSA key must be formatted according to PKCS8 standards and have standard PEM headers and footers. Note that either a Snowflake Private Key File or a Snowflake Private Key must be defined.
No
Snowflake Private Key File When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: The private key file must be blank. - **KEY_PAIR**: Upload the file that contains the RSA private key used for authentication to Snowflake, formatted according to PKCS8 standards and including standard PEM headers and footers. The header line begins with `-----BEGIN PRIVATE`. To upload the private key file, select the **Reference asset** checkbox. No
Snowflake Private Key Password When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the password associated with the Snowflake private key file. No
Snowflake Role When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Use the runtime's execute-as role (or a child role granted to it). You can find your execute-as role in the Openflow UI by navigating to **View Details** for your runtime. - **KEY_PAIR**: Use a valid role configured for your service user. Yes
Snowflake Username When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the username used to connect to the Snowflake instance. Yes
Snowflake Warehouse Snowflake warehouse used to run queries. Yes
Parameter Description
Enabled Tables Comma-separated list of optional tables to populate. Ingestion of `BOARD` is always enabled and can't be disabled. For the API scopes each table needs, see [](#label-jira-agile-api-scopes). Available values: - `BOARD_ISSUE` (issues associated with the board) - `BOARD_PROJECT` (projects associated with the boards) - `SPRINT` (sprints and board-sprint associations, populates both `SPRINT` and `BOARD_SPRINT`) Default value: `BOARD_ISSUE, BOARD_PROJECT, SPRINT`.
Merge Interval Time interval between journal-to-destination merge operations. When a merge runs, the Snowflake warehouse resumes. The merge is skipped if no new data has been loaded since the previous merge. Default value: `1 min`.
Table Classic scope (recommended) Granular scopes Jira API reference Additional Jira permission
`ISSUE` (always) `read:jira-work` `read:issue-details:jira`, `read:field.default-value:jira`, `read:field.option:jira`, `read:field:jira`, `read:group:jira`, `read:jql:jira`, `validate:jql:jira` Parse JQL query (https://developer.atlassian.com/cloud/jira/platform/rest/v3/api-group-jql/#api-rest-api-3-jql-parse-post) and Search for issues using JQL (https://developer.atlassian.com/cloud/jira/platform/rest/v3/api-group-issue-search/#api-rest-api-3-search-jql-post) **Browse projects** on the relevant projects.
`PROJECT` (always) `read:jira-work` `read:issue-type:jira`, `read:project:jira`, `read:project.property:jira`, `read:user:jira`, `read:application-role:jira`, `read:avatar:jira`, `read:group:jira`, `read:issue-type-hierarchy:jira`, `read:project-category:jira`, `read:project-version:jira`, `read:project.component:jira` Get projects paginated (https://developer.atlassian.com/cloud/jira/platform/rest/v3/api-group-projects/#api-rest-api-3-project-search-get) **Browse projects** on the relevant projects.
`USER` (always) `read:jira-user` `read:user:jira`, `read:application-role:jira`, `read:avatar:jira`, `read:group:jira` Get all users (default) (https://developer.atlassian.com/cloud/jira/platform/rest/v3/api-group-users/#api-rest-api-3-users-get) **Browse users and groups** (global).
`FIELD` (always) `read:jira-work` `read:field:jira`, `read:avatar:jira`, `read:project-category:jira`, `read:project:jira`, `read:field-configuration:jira` Get fields (https://developer.atlassian.com/cloud/jira/platform/rest/v3/api-group-issue-fields/#api-rest-api-3-field-get) None.
`CHANGELOG` `read:jira-work` `read:issue-meta:jira`, `read:avatar:jira`, `read:issue.changelog:jira` Bulk fetch changelogs (https://developer.atlassian.com/cloud/jira/platform/rest/v3/api-group-issues/#api-rest-api-3-changelog-bulkfetch-post) **Browse projects** on the relevant projects.
`COMMENT` `read:jira-work` `read:comment:jira`, `read:comment.property:jira`, `read:group:jira`, `read:project:jira`, `read:project-role:jira`, `read:user:jira`, `read:avatar:jira` Get comments (https://developer.atlassian.com/cloud/jira/platform/rest/v3/api-group-issue-comments/#api-rest-api-3-issue-issueidorkey-comment-get) **Browse projects** on the relevant projects.
`ISSUE_REMOTE_LINK` `read:jira-work` `read:issue.remote-link:jira`, `read:status:jira` Get remote issue links (https://developer.atlassian.com/cloud/jira/platform/rest/v3/api-group-issue-remote-links/#api-rest-api-3-issue-issueidorkey-remotelink-get) **Browse projects** on the relevant projects.
`ISSUE_SECURITY_SCHEME` `manage:jira-project` `read:issue-security-level:jira`, `read:issue-security-scheme:jira` Get issue security schemes (https://developer.atlassian.com/cloud/jira/platform/rest/v3/api-group-issue-security-schemes/#api-rest-api-3-issuesecurityschemes-get) **Administer Jira** (global).
`ISSUE_TYPE` `read:jira-work` `read:issue-type:jira`, `read:avatar:jira`, `read:project-category:jira`, `read:project:jira` Get all issue types for user (https://developer.atlassian.com/cloud/jira/platform/rest/v3/api-group-issue-types/#api-rest-api-3-issuetype-get) None.
`ISSUE_VOTE` `read:jira-work` `read:issue.vote:jira`, `read:user:jira`, `read:application-role:jira`, `read:avatar:jira`, `read:group:jira` Get votes (https://developer.atlassian.com/cloud/jira/platform/rest/v3/api-group-issue-votes/#api-rest-api-3-issue-issueidorkey-votes-get) **Browse projects** on the relevant projects. **View voters and watchers** is also required to return voter details.
`ISSUE_WATCHER` `read:jira-work` `read:issue.watcher:jira`, `read:user:jira`, `read:avatar:jira` Get issue watchers (https://developer.atlassian.com/cloud/jira/platform/rest/v3/api-group-issue-watchers/#api-rest-api-3-issue-issueidorkey-watchers-get) **Browse projects** on the relevant projects. **View voters and watchers** is also required to return details for watchers other than the API token owner.
`PERMISSION` `manage:jira-configuration` `read:permission:jira` Get all permissions (https://developer.atlassian.com/cloud/jira/platform/rest/v3/api-group-permissions/#api-rest-api-3-permissions-get) None.
`PRIORITY` `manage:jira-configuration` None. Search priorities (https://developer.atlassian.com/cloud/jira/platform/rest/v3/api-group-issue-priorities/#api-rest-api-3-priority-search-get) None.
`PROJECT_COMPONENT` `read:jira-work` `read:project:jira`, `read:project.component:jira`, `read:user:jira`, `read:application-role:jira`, `read:avatar:jira`, `read:group:jira` Get project components paginated (https://developer.atlassian.com/cloud/jira/platform/rest/v3/api-group-project-components/#api-rest-api-3-project-projectidorkey-component-get) **Browse projects** on the relevant projects.
`PROJECT_VERSION` `read:jira-work` `read:project-version:jira` Get project versions paginated (https://developer.atlassian.com/cloud/jira/platform/rest/v3/api-group-project-versions/#api-rest-api-3-project-projectidorkey-version-get) **Browse projects** on the relevant projects.
`RESOLUTION` `read:jira-work` `read:resolution:jira` Search resolutions (https://developer.atlassian.com/cloud/jira/platform/rest/v3/api-group-issue-resolutions/#api-rest-api-3-resolution-search-get) None.
`STATUS` `manage:jira-configuration` `read:workflow:jira` Search statuses paginated (https://developer.atlassian.com/cloud/jira/platform/rest/v3/api-group-status/#api-rest-api-3-statuses-search-get) **Administer projects** on the relevant projects or **Administer Jira** (global).
`USER_GROUP` `read:jira-user` `read:group:jira` Get user groups (https://developer.atlassian.com/cloud/jira/platform/rest/v3/api-group-users/#api-rest-api-3-user-groups-get) **Browse users and groups** (global).
`WORKLOG` `read:jira-work` `read:comment:jira`, `read:group:jira`, `read:issue-worklog:jira`, `read:issue-worklog.property:jira`, `read:project-role:jira`, `read:user:jira`, `read:avatar:jira` Get IDs of updated worklogs (https://developer.atlassian.com/cloud/jira/platform/rest/v3/api-group-issue-worklogs/#api-rest-api-3-worklog-updated-get) and Get worklogs (https://developer.atlassian.com/cloud/jira/platform/rest/v3/api-group-issue-worklogs/#api-rest-api-3-worklog-list-post) None. Restricted worklogs are returned only when the API token owner belongs to the permitted project role or group.
`DELETED_ISSUE` (`Deletes Fetch Strategy = AUDIT`) `manage:jira-configuration` `read:audit-log:jira`, `read:user:jira` Get audit records (https://developer.atlassian.com/cloud/jira/platform/rest/v3/api-group-audit-records/#api-rest-api-3-auditing-record-get) **Administer Jira** (global). Audit logs are available only when at least one Jira product is on a paid plan.
Parameter Description
Jira Email Email address for the Atlassian account used for authentication.
Jira API Token API access token for your Atlassian Jira account. See [Required API scopes](#label-jira-core-api-scopes) for the scopes to configure.
Environment URL URL to the Atlassian Jira environment. For example, `https://your-domain.atlassian.net`.
Parameter Description Required
Destination Database The database where data will be persisted. It must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. Yes
Destination Schema The schema where data will be persisted, which must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. See the following examples:
- `CREATE SCHEMA SCHEMA_NAME` or `CREATE SCHEMA schema_name`: use `SCHEMA_NAME` - `CREATE SCHEMA "schema_name"` or `CREATE SCHEMA "SCHEMA_NAME"`: use `schema_name` or `SCHEMA_NAME`, respectively
Yes
Snowflake Authentication Strategy When using: - **Snowflake Openflow Deployment** or **BYOC**: Use SNOWFLAKE_MANAGED. This token is managed automatically by Snowflake. BYOC deployments must have previously configured [execute-as roles](#label-deployment-byoc-setup-runtime-role) to use SNOWFLAKE_MANAGED. - **BYOC**: Alternatively, BYOC can use KEY_PAIR as the value for the authentication strategy. Yes
Snowflake Account Identifier When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Snowflake account name formatted as [organization-name]-[account-name]. Yes
Snowflake Private Key When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. -
**KEY_PAIR**: Must be the RSA private key used for authentication.
The RSA key must be formatted according to PKCS8 standards and have standard PEM headers and footers. Note that either a Snowflake Private Key File or a Snowflake Private Key must be defined.
No
Snowflake Private Key File When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: The private key file must be blank. - **KEY_PAIR**: Upload the file that contains the RSA private key used for authentication to Snowflake, formatted according to PKCS8 standards and including standard PEM headers and footers. The header line begins with `-----BEGIN PRIVATE`. To upload the private key file, select the **Reference asset** checkbox. No
Snowflake Private Key Password When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the password associated with the Snowflake private key file. No
Snowflake Role When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Use the runtime's execute-as role (or a child role granted to it). You can find your execute-as role in the Openflow UI by navigating to **View Details** for your runtime. - **KEY_PAIR**: Use a valid role configured for your service user. Yes
Snowflake Username When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the username used to connect to the Snowflake instance. Yes
Snowflake Warehouse Snowflake warehouse used to run queries. Yes
Parameter Description
Enabled Tables Comma-separated list of optional tables to populate. See [](#label-jira-core-enabled-tables) for the full list of values and guidance on which tables to enable. Default value: `CHANGELOG, COMMENT, ISSUE_TYPE, PRIORITY, RESOLUTION, STATUS, WORKLOG`.
Issue Fields A list of fields to return for each issue, used to retrieve a subset of fields. See [](#label-jira-core-issue-fields) for available values and custom field handling. Default value: `*standard`.
Project Keys Filter Optional comma-separated list of Jira project keys to limit ingestion to specific projects. If empty, all projects accessible by the API token owner are fetched. For example, `PROJ1, PROJ2`.
Deletes Fetch Strategy Strategy for fetching deleted issues. Set to `NONE` to skip delete tracking, or `AUDIT` to fetch deleted issues from the Jira audit log endpoint. The `AUDIT` strategy requires the API token owner to have the **Administer Jira** global permission and the `manage:jira-configuration` scope. Default value: `NONE`.
Merge Interval Time interval between journal-to-destination merge operations. When a merge runs, the Snowflake warehouse resumes. The merge is skipped if no new data has been loaded since the previous merge. Default value: `1 min`.
Jira field type Snowflake column type
`number` NUMBER
`array` ARRAY
`progress`, `votes`, `watches`, `timetracking` VARIANT
All other types VARCHAR
Parameter Description
Client ID Client ID of the Amazon Advertising account
Client Secret Client secret of the Amazon Advertising account
OAuth Base URL The URL of the authorization server that issues the access token
Possible values:
- https://api.amazon.com/auth/o2/token (https://api.amazon.com/auth/o2/token) - https://api.amazon.co.uk/auth/o2/token (https://api.amazon.co.uk/auth/o2/token) - https://api.amazon.co.jp/auth/o2/token (https://api.amazon.co.jp/auth/o2/token)
Refresh Token Refresh Token for Amazon Ads API
Region Environment from which the advertising data is downloaded
Possible values:
- NA - EU - FE
Parameter Description Required
Destination Database The database where data will be persisted. It must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. Yes
Destination Schema The schema where data will be persisted, which must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. See the following examples:
- `CREATE SCHEMA SCHEMA_NAME` or `CREATE SCHEMA schema_name`: use `SCHEMA_NAME` - `CREATE SCHEMA "schema_name"` or `CREATE SCHEMA "SCHEMA_NAME"`: use `schema_name` or `SCHEMA_NAME`, respectively
Yes
Snowflake Authentication Strategy When using: - **Snowflake Openflow Deployment** or **BYOC**: Use SNOWFLAKE_MANAGED. This token is managed automatically by Snowflake. BYOC deployments must have previously configured [execute-as roles](#label-deployment-byoc-setup-runtime-role) to use SNOWFLAKE_MANAGED. - **BYOC**: Alternatively, BYOC can use KEY_PAIR as the value for the authentication strategy. Yes
Snowflake Account Identifier When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Snowflake account name formatted as [organization-name]-[account-name]. Yes
Snowflake Private Key When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. -
**KEY_PAIR**: Must be the RSA private key used for authentication.
The RSA key must be formatted according to PKCS8 standards and have standard PEM headers and footers. Note that either a Snowflake Private Key File or a Snowflake Private Key must be defined.
No
Snowflake Private Key File When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: The private key file must be blank. - **KEY_PAIR**: Upload the file that contains the RSA private key used for authentication to Snowflake, formatted according to PKCS8 standards and including standard PEM headers and footers. The header line begins with `-----BEGIN PRIVATE`. To upload the private key file, select the **Reference asset** checkbox. No
Snowflake Private Key Password When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the password associated with the Snowflake private key file. No
Snowflake Role When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Use the runtime's execute-as role (or a child role granted to it). You can find your execute-as role in the Openflow UI by navigating to **View Details** for your runtime. - **KEY_PAIR**: Use a valid role configured for your service user. Yes
Snowflake Username When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the username used to connect to the Snowflake instance. Yes
Snowflake Warehouse Snowflake warehouse used to run queries. Yes
Parameter Description
Report Name Name of the report to be used as a destination table name. The name must be unique within the destination schema.
Report Ad Product Type of advertising product being reported
Possible values:
- SPONSORED_PRODUCTS - SPONSORED_BRANDS - SPONSORED_DISPLAY - SPONSORED_TELEVISION - DEMAND_SIDE_PLATFORM
Report Columns Set of columns which will be present in the end report. The list of available columns depends on the report type and can be found in the Amazon Ads API documentation (https://advertising.amazon.com/API/docs/en-us/guides/reporting/v3/report-types/overview). For example, for the `spCampaigns` report type, the list of available columns can be found in the Sponsored Products documentation (https://advertising.amazon.com/API/docs/en-us/guides/reporting/v3/report-types/campaign#sponsored-products).
Report Filters Set of filters used to trim the data returned. The list of available filters depends on the report type and can be found in the Amazon Ads API documentation (https://advertising.amazon.com/API/docs/en-us/guides/reporting/v3/report-types/overview). For example, for the `spCampaigns` report type, the list of available filters can be found in the Sponsored Products documentation (https://advertising.amazon.com/API/docs/en-us/guides/reporting/v3/report-types/campaign#sponsored-products). Filters must be in the format of `columnName=filterValue` and values must separated by a comma (`,`). For example, `campaignStatus=ENABLED,PAUSED`.
Report Group By Determines the level of granularity and how the data within the report will be aggregated and presented. The list of available group by columns depends on the report type and can be found in the Amazon Ads API documentation (https://advertising.amazon.com/API/docs/en-us/guides/reporting/v3/report-types/overview). For example, for the `spCampaigns` report type, the list of available group by columns can be found in the Sponsored Products documentation (https://advertising.amazon.com/API/docs/en-us/guides/reporting/v3/report-types/campaign#sponsored-products).
Report Ingestion Strategy Mode in which data is fetched, either snapshot or incremental
Possible values:
- `SNAPSHOT` - `INCREMENTAL`
Report Ingestion Window Specifies the number of days, data from which should be downloaded during incremental ingestion. For example, with a 30-day report ingestion window, an incremental load starts ingestion from 30 days prior to the last successful ingestion date, unless this calculated date falls before the overall start date, in which case ingestion begins from the overall start date. If the `SNAPSHOT` ingestion strategy is used, all available data from the start date to the present is downloaded, so there is no need to use a report ingestion window.
Report Profile ID The profile ID (https://advertising.amazon.com/API/docs/en-us/guides/get-started/retrieve-profiles) associated with an advertising account in a specific marketplace
Report Time Unit Date aggregation
Possible values:
- `DAILY`: Each day is represented by a one row - `SUMMARY`: The whole ingested date period is represented as one row
Report Type The Amazon Ads API supports a number of report types (https://advertising.amazon.com/API/docs/en-us/guides/reporting/v3/report-types/overview). For example: sbAds (https://advertising.amazon.com/API/docs/en-us/guides/reporting/v3/report-types/ad) and spCampaigns (https://advertising.amazon.com/API/docs/en-us/guides/reporting/v3/report-types/campaign). Copy value of `reportTypeId` from the documentation and paste it into the parameter value.
Report Start Date Start date from which the ingestion should happen. The date format is YYYY-MM-DD.
Report Schedule Schedule time for processor creating reports. For example: `8 h` or `1 d`. The `h` represents hours and `d` days.
Parameter Description
Box App Config JSON An application JSON configuration that was downloaded during the app creation.
Box App Config File An application JSON file that was downloaded during the app creation. Either "Box App Config File" or "Box App Config JSON" has to be set. Select the **Reference asset** checkbox to upload the config file.
Parameter Description Required
Destination Database The database where data will be persisted. It must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. Yes
Destination Schema The schema where data will be persisted, which must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. See the following examples:
- `CREATE SCHEMA SCHEMA_NAME` or `CREATE SCHEMA schema_name`: use `SCHEMA_NAME` - `CREATE SCHEMA "schema_name"` or `CREATE SCHEMA "SCHEMA_NAME"`: use `schema_name` or `SCHEMA_NAME`, respectively
Yes
Snowflake Authentication Strategy When using: - **Snowflake Openflow Deployment** or **BYOC**: Use SNOWFLAKE_MANAGED. This token is managed automatically by Snowflake. BYOC deployments must have previously configured [execute-as roles](#label-deployment-byoc-setup-runtime-role) to use SNOWFLAKE_MANAGED. - **BYOC**: Alternatively, BYOC can use KEY_PAIR as the value for the authentication strategy. Yes
Snowflake Account Identifier When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Snowflake account name formatted as [organization-name]-[account-name]. Yes
Snowflake Private Key When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. -
**KEY_PAIR**: Must be the RSA private key used for authentication.
The RSA key must be formatted according to PKCS8 standards and have standard PEM headers and footers. Note that either a Snowflake Private Key File or a Snowflake Private Key must be defined.
No
Snowflake Private Key File When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: The private key file must be blank. - **KEY_PAIR**: Upload the file that contains the RSA private key used for authentication to Snowflake, formatted according to PKCS8 standards and including standard PEM headers and footers. The header line begins with `-----BEGIN PRIVATE`. To upload the private key file, select the **Reference asset** checkbox. No
Snowflake Private Key Password When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the password associated with the Snowflake private key file. No
Snowflake Role When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Use the runtime's execute-as role (or a child role granted to it). You can find your execute-as role in the Openflow UI by navigating to **View Details** for your runtime. - **KEY_PAIR**: Use a valid role configured for your service user. Yes
Snowflake Username When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the username used to connect to the Snowflake instance. Yes
Snowflake Warehouse Snowflake warehouse used to run queries. Yes
Parameter Description
Box Folder ID The ID of the folder to read the files from. Set this to `0` to synchronize all folders the Box app has access to. It can be retrieved from the URL, for example https://app.box.com/folder/FOLDER_ID (https://app.box.com/folder/FOLDER_ID).
File Extensions To Ingest A comma-separated list that specifies file extensions to ingest. The connector tries to convert the files to PDF format first, if possible. Nonetheless, the extension check is performed on the original file extension. If some of the specified file extensions are not supported by Cortex Parse Document, then the connector ignores those files, logs a warning message in an event log, and continues processing other files.
Snowflake File Hash Table Name Name of the table to store file hashes to determine if the content has changed. This parameter should generally not be changed.
Parameter Description
Box App Config JSON An application JSON configuration that was downloaded during the app creation.
Box App Config File An application JSON file that was downloaded during the app creation. Either "Box App Config File" or "Box App Config JSON" has to be set. Select the **Reference asset** checkbox to upload the config file.
Parameter Description Required
Destination Database The database where data will be persisted. It must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. Yes
Destination Schema The schema where data will be persisted, which must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. See the following examples:
- `CREATE SCHEMA SCHEMA_NAME` or `CREATE SCHEMA schema_name`: use `SCHEMA_NAME` - `CREATE SCHEMA "schema_name"` or `CREATE SCHEMA "SCHEMA_NAME"`: use `schema_name` or `SCHEMA_NAME`, respectively
Yes
Snowflake Authentication Strategy When using: - **Snowflake Openflow Deployment** or **BYOC**: Use SNOWFLAKE_MANAGED. This token is managed automatically by Snowflake. BYOC deployments must have previously configured [execute-as roles](#label-deployment-byoc-setup-runtime-role) to use SNOWFLAKE_MANAGED. - **BYOC**: Alternatively, BYOC can use KEY_PAIR as the value for the authentication strategy. Yes
Snowflake Account Identifier When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Snowflake account name formatted as [organization-name]-[account-name]. Yes
Snowflake Private Key When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. -
**KEY_PAIR**: Must be the RSA private key used for authentication.
The RSA key must be formatted according to PKCS8 standards and have standard PEM headers and footers. Note that either a Snowflake Private Key File or a Snowflake Private Key must be defined.
No
Snowflake Private Key File When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: The private key file must be blank. - **KEY_PAIR**: Upload the file that contains the RSA private key used for authentication to Snowflake, formatted according to PKCS8 standards and including standard PEM headers and footers. The header line begins with `-----BEGIN PRIVATE`. To upload the private key file, select the **Reference asset** checkbox. No
Snowflake Private Key Password When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the password associated with the Snowflake private key file. No
Snowflake Role When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Use the runtime's execute-as role (or a child role granted to it). You can find your execute-as role in the Openflow UI by navigating to **View Details** for your runtime. - **KEY_PAIR**: Use a valid role configured for your service user. Yes
Snowflake Username When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the username used to connect to the Snowflake instance. Yes
Snowflake Warehouse Snowflake warehouse used to run queries. Yes
Parameter Description
Box Folder ID The ID of the folder to read the files from. Set this to `0` to synchronize all folders the Box app has access to. It can be retrieved from the URL, for example https://app.box.com/folder/FOLDER_ID (https://app.box.com/folder/FOLDER_ID).
File Extensions To Ingest A comma-separated list that specifies file extensions to ingest. The connector tries to convert the files to PDF format first, if possible. Nonetheless, the extension check is performed on the original file extension. If some of the specified file extensions are not supported by Cortex Parse Document, then the connector ignores those files, logs a warning message in an event log, and continues processing other files.
Snowflake File Hash Table Name Name of the table to store file hashes to determine if the content has changed. This parameter should generally not be changed.
OCR Mode The OCR mode to use when parsing files with [Parsing documents with AI_PARSE_DOCUMENT](/user-guide/snowflake-cortex/parse-document) function. The value can be `OCR` or `LAYOUT`.
Snowflake Cortex Search Service User Role An identifier of a role that is assigned usage permissions on the Cortex Search service.
Column name Type Description
`full_name` String A full path to the file from the Box folder root. Example: `folder_1/folder_2/file_name.pdf`.
`web_url` String A URL that displays an original Box file in a browser.
`last_modified_date_time` String Date and time when the item was most recently modified.
`chunk` String A piece of text from the document that matched the Cortex Search query.
`user_ids` Array An array of user IDs that have access to the document.
`user_emails` Array An array of user email IDs that have access to the document.
Parameter Description
Box App Config JSON An application JSON configuration that was downloaded during the app creation.
Box App Config File An application JSON file that was downloaded during the app creation. Either "Box App Config File" or "Box App Config JSON" has to be set. Select the **Reference asset** checkbox to upload the config file.
Parameter Description Required
Destination Database The database where data will be persisted. It must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. Yes
Destination Schema The schema where data will be persisted, which must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. See the following examples:
- `CREATE SCHEMA SCHEMA_NAME` or `CREATE SCHEMA schema_name`: use `SCHEMA_NAME` - `CREATE SCHEMA "schema_name"` or `CREATE SCHEMA "SCHEMA_NAME"`: use `schema_name` or `SCHEMA_NAME`, respectively
Yes
Snowflake Authentication Strategy When using: - **Snowflake Openflow Deployment** or **BYOC**: Use SNOWFLAKE_MANAGED. This token is managed automatically by Snowflake. BYOC deployments must have previously configured [execute-as roles](#label-deployment-byoc-setup-runtime-role) to use SNOWFLAKE_MANAGED. - **BYOC**: Alternatively, BYOC can use KEY_PAIR as the value for the authentication strategy. Yes
Snowflake Account Identifier When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Snowflake account name formatted as [organization-name]-[account-name]. Yes
Snowflake Private Key When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. -
**KEY_PAIR**: Must be the RSA private key used for authentication.
The RSA key must be formatted according to PKCS8 standards and have standard PEM headers and footers. Note that either a Snowflake Private Key File or a Snowflake Private Key must be defined.
No
Snowflake Private Key File When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: The private key file must be blank. - **KEY_PAIR**: Upload the file that contains the RSA private key used for authentication to Snowflake, formatted according to PKCS8 standards and including standard PEM headers and footers. The header line begins with `-----BEGIN PRIVATE`. To upload the private key file, select the **Reference asset** checkbox. No
Snowflake Private Key Password When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the password associated with the Snowflake private key file. No
Snowflake Role When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Use the runtime's execute-as role (or a child role granted to it). You can find your execute-as role in the Openflow UI by navigating to **View Details** for your runtime. - **KEY_PAIR**: Use a valid role configured for your service user. Yes
Snowflake Username When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the username used to connect to the Snowflake instance. Yes
Snowflake Warehouse Snowflake warehouse used to run queries. Yes
Parameter Description
Box Folder ID The ID of the folder to read the files from. Set this to `0` to synchronize all folders the Box app has access to. The ID can be retrieved from the URL, for example https://app.box.com/folder/FOLDER_ID (https://app.box.com/folder/FOLDER_ID).
Box File Identifier Column The column of the metadata table that will store the Box file ID to associate the given metadata with a file. This column must be of type VARCHAR and be part of the table created in [Create a Snowflake table for storing the Box metadata](#create-a-snowflake-table-for-storing-the-box-metadata).
Destination Metadata Table The Snowflake table you created in [Create a Snowflake table for storing the Box metadata](#create-a-snowflake-table-for-storing-the-box-metadata), which has the columns of the metadata you want to collect.
Parameter Description
Source Database Snowflake Database that contains the schema that contains the Snowflake Stream that ingests the changes.
Source Schema Schema that contains the Snowflake Stream that ingests the changes.
Snowflake Account Identifier Leave this blank when using SNOWFLAKE_MANAGED Authentication Strategy. When using KEY_PAIR, provide your Snowflake account name formatted as [organization-name]-[account-name] where data will be persisted.
Snowflake Authentication Strategy When using: - **Snowflake Openflow Deployment** or **BYOC**: Use SNOWFLAKE_MANAGED. This token is managed automatically by Snowflake. BYOC deployments must have previously configured [execute-as roles](#label-deployment-byoc-setup-runtime-role) to use SNOWFLAKE_MANAGED. - **BYOC**: Alternatively, BYOC can use KEY_PAIR as the value for the authentication strategy.
Snowflake Private Key Leave this blank when using SNOWFLAKE_MANAGED Authentication Strategy. When using KEY_PAIR, provide the RSA private key used for authentication. The RSA key must be formatted according to PKCS8 standards and have standard PEM headers and footers. Note that either Snowflake Private Key File or Snowflake Private Key must be defined.
Snowflake Private Key File Leave this blank when using SNOWFLAKE_MANAGED Authentication Strategy. When using KEY_PAIR, upload the file that contains the RSA Private Key used for authentication to Snowflake, formatted according to PKCS8 standards and having standard PEM headers and footers. The header line begins with `-----BEGIN PRIVATE`. Select the **Reference asset** checkbox to upload the private key file.
Snowflake Private Key Password Leave this blank when using SNOWFLAKE_MANAGED Authentication Strategy. When using KEY_PAIR, provide the password associated with the Snowflake Private Key File.
Snowflake Role When using SNOWFLAKE_MANAGED Authentication Strategy, use the runtime's execute-as role (or a child role granted to it). You can find your execute-as role in the Openflow UI by going to View Details for your runtime. When using Key Pair Authentication Strategy, use a valid role configured for your service user.
Snowflake Username Leave this blank when using SNOWFLAKE_MANAGED Authentication Strategy. When using KEY_PAIR, provide the user name used to connect to the Snowflake instance.
Snowflake Warehouse Snowflake warehouse used to run queries.
Snowflake Stream Name Snowflake stream name used for ingestion of changes from the source Snowflake table. You must create it before starting the connector and link to the table.
Parameter Description
Box App Config JSON An application JSON configuration that was downloaded during the app creation.
Box App Config File An application JSON file that was downloaded during the app creation. Either "Box App Config File" or "Box App Config JSON" has to be set. Select the **Reference asset** checkbox to upload the config file.
Parameter Description
Box File Identifier Column The column of the metadata table that will store the Box file ID to associate the given metadata with a file. This column must be of type VARCHAR and be part of the table created in [Create a Snowflake table for storing the Box metadata](#create-a-snowflake-table-for-storing-the-box-metadata).
Box Metadata Template Name Template name of the Box metadata template that will be added to the Box files. You don't need to manually create a template before starting the connector. If you enter a value in this parameter, a template is automatically created with this template name. The name provided should not overlap with any template that you have already created in your Box environment.
Box Metadata Template Key The Box template key of the Box metadata template that will be added to the Box files. This is the key that will be used to reference the template in the Box API. You don't need to manually create a template before starting the connector. If you enter a value in this parameter, a template is automatically created with this template key. The key provided should not overlap with any template that you have already created in your Box environment.
Parameter Description Required
Client Account ID ID of the account in the Google Ads for which given report should be ingested true
Login Customer ID Customer ID of the Google Ads manager account (MCC) for which the report should be ingested false
Google Ads Resource Name Name of the resource in Google Ads that is a source for the report true
Report Attributes Attributes of the selected resource true
Report Metrics Metrics collected in the context of a given resource false
Report Segments Buckets in which metrics should be grouped false
Report Start Date Start date from which the ingestion should happen. The date format is YYYY-MM-DD. false
Schedule Get Google Ads Report processor schedule true
Parameter Description Required
Google Developer Token Developer token required to query Google Ads API true
Google Service Account JSON Service Account JSON required for Google Ads authentication true
Parameter Description Required
Destination Database The database where data will be persisted. It must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. Yes
Destination Schema The schema where data will be persisted, which must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. See the following examples:
- `CREATE SCHEMA SCHEMA_NAME` or `CREATE SCHEMA schema_name`: use `SCHEMA_NAME` - `CREATE SCHEMA "schema_name"` or `CREATE SCHEMA "SCHEMA_NAME"`: use `schema_name` or `SCHEMA_NAME`, respectively
Yes
Snowflake Authentication Strategy When using: - **Snowflake Openflow Deployment** or **BYOC**: Use SNOWFLAKE_MANAGED. This token is managed automatically by Snowflake. BYOC deployments must have previously configured [execute-as roles](#label-deployment-byoc-setup-runtime-role) to use SNOWFLAKE_MANAGED. - **BYOC**: Alternatively, BYOC can use KEY_PAIR as the value for the authentication strategy. Yes
Snowflake Account Identifier When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Snowflake account name formatted as [organization-name]-[account-name]. Yes
Snowflake Private Key When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. -
**KEY_PAIR**: Must be the RSA private key used for authentication.
The RSA key must be formatted according to PKCS8 standards and have standard PEM headers and footers. Note that either a Snowflake Private Key File or a Snowflake Private Key must be defined.
No
Snowflake Private Key File When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: The private key file must be blank. - **KEY_PAIR**: Upload the file that contains the RSA private key used for authentication to Snowflake, formatted according to PKCS8 standards and including standard PEM headers and footers. The header line begins with `-----BEGIN PRIVATE`. To upload the private key file, select the **Reference asset** checkbox. No
Snowflake Private Key Password When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the password associated with the Snowflake private key file. No
Snowflake Role When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Use the runtime's execute-as role (or a child role granted to it). You can find your execute-as role in the Openflow UI by navigating to **View Details** for your runtime. - **KEY_PAIR**: Use a valid role configured for your service user. Yes
Snowflake Username When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the username used to connect to the Snowflake instance. Yes
Snowflake Warehouse Snowflake warehouse used to run queries. Yes
Parameter Description
Google Delegation User The user that is used by the service account
GCP Service Account JSON The service account JSON downloaded from Google Cloud Console to allow access to Google APIs in the connector
Parameter Description Required
Destination Database The database where data will be persisted. It must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. Yes
Destination Schema The schema where data will be persisted, which must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. See the following examples:
- `CREATE SCHEMA SCHEMA_NAME` or `CREATE SCHEMA schema_name`: use `SCHEMA_NAME` - `CREATE SCHEMA "schema_name"` or `CREATE SCHEMA "SCHEMA_NAME"`: use `schema_name` or `SCHEMA_NAME`, respectively
Yes
Snowflake Authentication Strategy When using: - **Snowflake Openflow Deployment** or **BYOC**: Use SNOWFLAKE_MANAGED. This token is managed automatically by Snowflake. BYOC deployments must have previously configured [execute-as roles](#label-deployment-byoc-setup-runtime-role) to use SNOWFLAKE_MANAGED. - **BYOC**: Alternatively, BYOC can use KEY_PAIR as the value for the authentication strategy. Yes
Snowflake Account Identifier When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Snowflake account name formatted as [organization-name]-[account-name]. Yes
Snowflake Private Key When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. -
**KEY_PAIR**: Must be the RSA private key used for authentication.
The RSA key must be formatted according to PKCS8 standards and have standard PEM headers and footers. Note that either a Snowflake Private Key File or a Snowflake Private Key must be defined.
No
Snowflake Private Key File When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: The private key file must be blank. - **KEY_PAIR**: Upload the file that contains the RSA private key used for authentication to Snowflake, formatted according to PKCS8 standards and including standard PEM headers and footers. The header line begins with `-----BEGIN PRIVATE`. To upload the private key file, select the **Reference asset** checkbox. No
Snowflake Private Key Password When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the password associated with the Snowflake private key file. No
Snowflake Role When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Use the runtime's execute-as role (or a child role granted to it). You can find your execute-as role in the Openflow UI by navigating to **View Details** for your runtime. - **KEY_PAIR**: Use a valid role configured for your service user. Yes
Snowflake Username When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the username used to connect to the Snowflake instance. Yes
Snowflake Warehouse Snowflake warehouse used to run queries. Yes
Parameter Description
Google Drive ID The Google Shared Drive to watch for content and updates
Google Folder Name Optionally, the Google Drive folder identifier (human-readable folder name) can be set to filter incoming files by. If all files are desired, then select "Set Empty String". When set, only files that are in the provided folder or subfolder will be retrieved. When blank or unset, no folder filtering is applied and all files under the drive are retrieved.
Google Domain The Google Workspace Domain that the Google Groups and Drive reside in.
File Extensions To Ingest A comma-separated list that specifies file extensions to ingest. The connector tries to convert the files to PDF format first, if possible. Nonetheless, the extension check is performed on the original file extension. If some of the specified file extensions are not supported by Cortex Parse Document, then the connector ignores those files, logs a warning message in an event log, and continues processing other files.
Snowflake File Hash Table Name Internal table used to store file content hashes to prevent updates to content when it has not changed.
Parameter Description
Google Delegation User The user that is used by the service account
GCP Service Account JSON The service account JSON downloaded from Google Cloud Console to allow access to Google APIs in the connector
Parameter Description
Destination Database The database where data will be persisted. It must already exist in Snowflake
Destination Schema The schema where data will be persisted. It must already exist in Snowflake
Snowflake Account Identifier Leave this blank when using SNOWFLAKE_MANAGED Authentication Strategy. When using KEY_PAIR, provide your Snowflake account name formatted as [organization-name]-[account-name] where data will be persisted.
Snowflake Authentication Strategy When using: - **Snowflake Openflow Deployment** or **BYOC**: Use SNOWFLAKE_MANAGED. This token is managed automatically by Snowflake. BYOC deployments must have previously configured [execute-as roles](#label-deployment-byoc-setup-runtime-role) to use SNOWFLAKE_MANAGED. - **BYOC**: Alternatively, BYOC can use KEY_PAIR as the value for the authentication strategy.
Snowflake Private Key Leave this blank when using SNOWFLAKE_MANAGED Authentication Strategy. When using KEY_PAIR, provide the RSA private key used for authentication. The RSA key must be formatted according to PKCS8 standards and have standard PEM headers and footers. Note that either Snowflake Private Key File or Snowflake Private Key must be defined.
Snowflake Private Key File Leave this blank when using SNOWFLAKE_MANAGED Authentication Strategy. When using KEY_PAIR, upload the file that contains the RSA Private Key used for authentication to Snowflake, formatted according to PKCS8 standards and having standard PEM headers and footers. The header line begins with `-----BEGIN PRIVATE`. Select the **Reference asset** checkbox to upload the private key file.
Snowflake Private Key Password Leave this blank when using SNOWFLAKE_MANAGED Authentication Strategy. When using KEY_PAIR, provide the password associated with the Snowflake Private Key File.
Snowflake Role When using SNOWFLAKE_MANAGED Authentication Strategy, use the runtime's execute-as role (or a child role granted to it). You can find your execute-as role in the Openflow UI by going to View Details for your runtime. When using Key Pair Authentication Strategy, use a valid role configured for your service user.
Snowflake Username Leave this blank when using SNOWFLAKE_MANAGED Authentication Strategy. When using KEY_PAIR, provide the user name used to connect to Snowflake instance.
Snowflake Warehouse Snowflake warehouse used to run queries
Parameter Description
Google Drive ID The Google Shared Drive to watch for content and updates
Google Folder Name
Optionally, the Google Drive folder identifier (human-readable folder name) can be set to filter incoming files by. If all files are desired, then select "Set Empty String".
When set, only files that are in the provided folder or subfolder will be retrieved. When blank or unset, no folder filtering is applied and all files under the drive are retrieved.
Google Domain The Google Workspace Domain that the Google Groups and Drive reside in.
OCR Mode The OCR mode to use when parsing files with [Parsing documents with AI_PARSE_DOCUMENT](/user-guide/snowflake-cortex/parse-document) function. The value can be `OCR` or `LAYOUT`.
File Extensions To Ingest A comma-separated list that specifies file extensions to ingest. The connector tries to convert the files to PDF format first, if possible. Nonetheless, the extension check is performed on the original file extension. If some of the specified file extensions are not supported by Cortex Parse Document, then the connector ignores those files, logs a warning message in an event log, and continues processing other files.
Snowflake File Hash Table Name Internal table used to store file content hashes to prevent updates to content when it has not changed.
Snowflake Cortex Search Service User Role An identifier of a role that is assigned usage permissions on the Cortex Search service.
Column name Type Description
`full_name` String A full path to the file from the Google Drive documents root. Example: `folder_1/folder_2/file_name.pdf`.
`web_url` String A URL that displays an original Google Drive file in a browser.
`last_modified_date_time` String Date and time when the item was most recently modified.
`chunk` String A piece of text from the document that matched the Cortex Search query.
`user_ids` Array An array of Google Drive user IDs that have access to the document. It also includes user IDs from all the Google Groups that are assigned to the document.
`user_emails` Array An array of Google Drive user email IDs that have access to the document. It also includes user email IDs from all the Google Groups that are assigned to the document.
Parameter Description Required
Destination Database The database where data will be persisted. It must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. Yes
Destination Schema The schema where data will be persisted, which must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. See the following examples:
- `CREATE SCHEMA SCHEMA_NAME` or `CREATE SCHEMA schema_name`: use `SCHEMA_NAME` - `CREATE SCHEMA "schema_name"` or `CREATE SCHEMA "SCHEMA_NAME"`: use `schema_name` or `SCHEMA_NAME`, respectively
Yes
Snowflake Authentication Strategy When using: - **Snowflake Openflow Deployment** or **BYOC**: Use SNOWFLAKE_MANAGED. This token is managed automatically by Snowflake. BYOC deployments must have previously configured [execute-as roles](#label-deployment-byoc-setup-runtime-role) to use SNOWFLAKE_MANAGED. - **BYOC**: Alternatively, BYOC can use KEY_PAIR as the value for the authentication strategy. Yes
Snowflake Account Identifier When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Snowflake account name formatted as [organization-name]-[account-name]. Yes
Snowflake Private Key When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. -
**KEY_PAIR**: Must be the RSA private key used for authentication.
The RSA key must be formatted according to PKCS8 standards and have standard PEM headers and footers. Note that either a Snowflake Private Key File or a Snowflake Private Key must be defined.
No
Snowflake Private Key File When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: The private key file must be blank. - **KEY_PAIR**: Upload the file that contains the RSA private key used for authentication to Snowflake, formatted according to PKCS8 standards and including standard PEM headers and footers. The header line begins with `-----BEGIN PRIVATE`. To upload the private key file, select the **Reference asset** checkbox. No
Snowflake Private Key Password When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the password associated with the Snowflake private key file. No
Snowflake Role When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Use the runtime's execute-as role (or a child role granted to it). You can find your execute-as role in the Openflow UI by navigating to **View Details** for your runtime. - **KEY_PAIR**: Use a valid role configured for your service user. Yes
Snowflake Username When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the username used to connect to the Snowflake instance. Yes
Snowflake Warehouse Snowflake warehouse used to run queries. Yes
Parameter Description
Service Account JSON Contents of the file containing Service Account credentials, such as client_id, client_email, and private_key. Copy the entire contents of the file.
Parameter Description
Date Time Render Option Determines how dates should be rendered in the output. You can select one of these options: `SERIAL_NUMBER` and `FORMATTED_STRING`. Select `SERIAL_NUMBER` only when the Value Render Option parameter is set to `UNFORMATTED_VALUE`. For more information, see DateTimeRenderOption (https://developers.google.com/sheets/api/reference/rest/v4/DateTimeRenderOption).
Destination Database The destination database in which the destination table is created.
Destination Schema The destination schema in which the destination table is created.
Destination Table Prefix The destination table prefix is where report data pulled from Google Sheets is stored. The connector creates one destination table for each range. If no ranges are provided then sheet names are used as table identifiers. The first row in a sheet represents the column names in the destination table.
Ranges The list of ranges to retrieve from the spreadsheet. If no range is specified, all sheets in the specified spreadsheet will be downloaded. Provide each range in either A1 or R1C1 notation (https://developers.google.com/sheets/api/guides/concepts#cell), separated by a comma. For example: `Sheet1!A1:B2,Sheet2!D4:E5,Sheet3`.
Run Schedule Run schedule on which data is retrieved from Google Sheets and saved in Snowflake. By default, the timer-driven scheduling strategy is used and here the user specifies an interval, for example, `8h`.
Spreadsheet ID The unique identifier (https://developers.google.com/sheets/api/guides/concepts) for a spreadsheet. You can find it in the URL of the spreadsheet.
Value Render Option Determines how values should be rendered in the output. You can select one of these options: `FORMATTED_VALUE` and `UNFORMATTED_VALUE`. If you select `FORMATTED_VALUE`, then all the columns in the destination table are of VARCHAR type. For more information, see ValueRenderOption (https://developers.google.com/sheets/api/reference/rest/v4/ValueRenderOption).
Parameter Description
HubSpot Access Token HubSpot Private Application access token.
Parameter Description Required
Destination Database The database where data will be persisted. It must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. Yes
Destination Schema The schema where data will be persisted, which must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. See the following examples:
- `CREATE SCHEMA SCHEMA_NAME` or `CREATE SCHEMA schema_name`: use `SCHEMA_NAME` - `CREATE SCHEMA "schema_name"` or `CREATE SCHEMA "SCHEMA_NAME"`: use `schema_name` or `SCHEMA_NAME`, respectively
Yes
Snowflake Authentication Strategy When using: - **Snowflake Openflow Deployment** or **BYOC**: Use SNOWFLAKE_MANAGED. This token is managed automatically by Snowflake. BYOC deployments must have previously configured [execute-as roles](#label-deployment-byoc-setup-runtime-role) to use SNOWFLAKE_MANAGED. - **BYOC**: Alternatively, BYOC can use KEY_PAIR as the value for the authentication strategy. Yes
Snowflake Account Identifier When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Snowflake account name formatted as [organization-name]-[account-name]. Yes
Snowflake Private Key When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. -
**KEY_PAIR**: Must be the RSA private key used for authentication.
The RSA key must be formatted according to PKCS8 standards and have standard PEM headers and footers. Note that either a Snowflake Private Key File or a Snowflake Private Key must be defined.
No
Snowflake Private Key File When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: The private key file must be blank. - **KEY_PAIR**: Upload the file that contains the RSA private key used for authentication to Snowflake, formatted according to PKCS8 standards and including standard PEM headers and footers. The header line begins with `-----BEGIN PRIVATE`. To upload the private key file, select the **Reference asset** checkbox. No
Snowflake Private Key Password When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the password associated with the Snowflake private key file. No
Snowflake Role When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Use the runtime's execute-as role (or a child role granted to it). You can find your execute-as role in the Openflow UI by navigating to **View Details** for your runtime. - **KEY_PAIR**: Use a valid role configured for your service user. Yes
Snowflake Username When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the username used to connect to the Snowflake instance. Yes
Snowflake Warehouse Snowflake warehouse used to run queries. Yes
Parameter Description
Object Types List of comma-separated HubSpot object types to ingest. Supported object type values are:
- Appointments - Calls - Campaigns - Carts - Commerce Payments - Communications - Companies - Contacts - Courses - Deals - Discounts - Emails - Fees - Feedback Submissions - Goals - Invoices - Leads - Line Items - Listings - Meetings - Notes - Orders - Postal Mail - Products - Quotes - Quote Templates - Services - Subscriptions - Tasks - Taxes - Tickets - Users
Updated After Filter objects updated after specified date or time. This parameter is optional.
Data Ingestion Schedule Time between the next schedule. It should have a valid time duration, such as 30 minutes or 1 hour.
Parameter Description
Jira Email Email address for the Atlassian account.
Jira API Token API access token for your Atlassian Jira account with the necessary scopes (`read:jira-work` and `read:jira-user`).
Environment URL URL to the Atlassian Jira environment. For example, `https://your-domain.atlassian.net`.
Connection Method Must be set to `DIRECT` unless otherwise instructed by Snowflake.
Parameter Description Required
Destination Database The database where data will be persisted. It must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. Yes
Destination Schema The schema where data will be persisted, which must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. See the following examples:
- `CREATE SCHEMA SCHEMA_NAME` or `CREATE SCHEMA schema_name`: use `SCHEMA_NAME` - `CREATE SCHEMA "schema_name"` or `CREATE SCHEMA "SCHEMA_NAME"`: use `schema_name` or `SCHEMA_NAME`, respectively
Yes
Snowflake Authentication Strategy When using: - **Snowflake Openflow Deployment** or **BYOC**: Use SNOWFLAKE_MANAGED. This token is managed automatically by Snowflake. BYOC deployments must have previously configured [execute-as roles](#label-deployment-byoc-setup-runtime-role) to use SNOWFLAKE_MANAGED. - **BYOC**: Alternatively, BYOC can use KEY_PAIR as the value for the authentication strategy. Yes
Snowflake Account Identifier When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Snowflake account name formatted as [organization-name]-[account-name]. Yes
Snowflake Private Key When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. -
**KEY_PAIR**: Must be the RSA private key used for authentication.
The RSA key must be formatted according to PKCS8 standards and have standard PEM headers and footers. Note that either a Snowflake Private Key File or a Snowflake Private Key must be defined.
No
Snowflake Private Key File When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: The private key file must be blank. - **KEY_PAIR**: Upload the file that contains the RSA private key used for authentication to Snowflake, formatted according to PKCS8 standards and including standard PEM headers and footers. The header line begins with `-----BEGIN PRIVATE`. To upload the private key file, select the **Reference asset** checkbox. No
Snowflake Private Key Password When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the password associated with the Snowflake private key file. No
Snowflake Role When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Use the runtime's execute-as role (or a child role granted to it). You can find your execute-as role in the Openflow UI by navigating to **View Details** for your runtime. - **KEY_PAIR**: Use a valid role configured for your service user. Yes
Snowflake Username When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the username used to connect to the Snowflake instance. Yes
Snowflake Warehouse Snowflake warehouse used to run queries. Yes
Parameter Description
Search Type Type of search to perform. It has one of these possible values `SIMPLE` and `JQL`. Default value: `SIMPLE`.
Destination Table The Snowflake table where data is stored. It will be created if it doesn't exist. The name of the table must be unquoted and must be provided in uppercase. Additionally to the destination table, a flattened view based on destination table is created. The view name is a concatenation of the table name and the suffix `_VIEW`
JQL Query A JQL query used to search for Jira issues to fetch. It should be used only when Search Type is `JQL`.
Project Names List of projects from which the issues should be fetched. You can search for issues belonging to a particular project by project name, project key, or project ID. It should be used only when Search Type is `SIMPLE`. Provide a list of items, separated by commas. For example: `Project1, Project2`.
Status Category Status category filter for simple search. It should be used only when Search Type is `SIMPLE`. Example values are: `Done`, `In Progress`, `To Do`.
Updated After Filter issues updated after a specified date and time. It should be used only when Search Type is `SIMPLE`. It should be in the yyyy-MM-dd format, such as 2023-10-01.
Created After Filter issues created after a specified date and time. It should be used only when Search Type is `SIMPLE`. It should be in the yyyy-MM-dd format, such as 2023-10-01.
Issue Fields A list of fields to return for each issue, which is used to retrieve a subset of fields. IDs of custom fields can be obtained by following this guide (https://confluence.atlassian.com/jirakb/get-custom-field-ids-for-jira-and-jira-service-management-744522503.html). This parameter accepts a comma-separated list. You can use special values: `*all` to fetch all fields, `*navigable` to fetch navigable fields, field prefixed with minus (`-`) to exclude field. For example, `*all,-description` returns all fields except description. Default value: `*all`.
Fetch All Worklogs Determines whether to fetch all worklogs for each issue. Default value: `false`. - When set to `true`, the connector enriches issues with all associated worklogs, beyond the default 20 worklogs per issue returned by the Jira Cloud REST API. - When set to `false`, only the first 20 worklogs per issue are fetched. Setting this parameter to `true` can impact performance due to the increased number of API calls required to fetch all worklogs for issues with more than 20 worklogs.
Maximum Page Size Maximum number of issues to return per request, with a default and maximum value of `1000`. Note that the Jira API may return fewer results depending on the total response size.
Object Privilege Notes
Database USAGE
Schema USAGE
Table OWNERSHIP Required for the connector to ingest data into a table.
Parameter Description Required
Kafka Auto Offset Reset Automatic offset configuration applied when no previous consumer offset is found corresponding to Kafka `auto.offset.reset` property. Possible values: **earliest**: automatically reset the offset to the earlier offset, **latest**: automatically reset the offset to the latest offset, **none**: throw exception to the consumer if no previous offset found for the consumer group. Default: latest Yes
Kafka Bootstrap Servers A comma-separated list of Kafka bootstrap servers, should contain a port, for example `kafka-broker:9092`. Yes
Kafka Consumer Group ID The ID of a consumer group used by the connector. Can be arbitrary but must be unique. Yes
Kafka SASL Password Password provided with configured password when using SASL512 SCRAM Mechanism
Kafka SASL Username Username provided with configured password when using SASL512 SCRAM Mechanism
Kafka Topic Format One of: names / pattern. Specifies whether the "Kafka Topics" provided are a comma separated list of names or a single regular expression. Yes
Kafka Topics A comma-separated list of Kafka topics or a regular expression. Yes
Snowflake Destination Database The database where data is persisted. It must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. Yes
Snowflake Destination Schema The schema where data is persisted, which must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. See the following examples: `CREATE SCHEMA SCHEMA_NAME` or `CREATE SCHEMA schema_name`: use `SCHEMA_NAME`. `CREATE SCHEMA "schema_name"` or `CREATE SCHEMA "SCHEMA_NAME"`: use `schema_name` or `SCHEMA_NAME`, respectively. Yes
Snowflake Destination Table The table where data is persisted. It must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. Yes
Field Data Type Description
topic String The name of the Kafka topic that the record came from.
partition number The number of the partition within the topic. (Note that this is the Kafka partition, not the Snowflake micro-partition.)
offset number The offset in that partition.
timestamp number Timestamp when the record was added to Kafka.
key String If the message is a Kafka KeyedMessage, this is the key for that message. In order for the connector to store the key in the RECORD_METADATA, the `key.converter` parameter in the Kafka configuration properties must be set to `org.apache.kafka.connect.storage.StringConverter`; otherwise, the connector ignores keys.
headers Object A header is a user-defined key-value pair associated with the record. Each record can have 0, 1, or multiple headers.
Parameter Description
Client ID The client ID of an application registered on LinkedIn
Client Secret The client secret related to the client ID
Refresh Token A user obtains the refresh token after the app registration process. They use it together with the client ID and the client secret to get an access token.
Token Endpoint The token endpoint is obtained by a user during the app registration process
Parameter Description Required
Destination Database The database where data will be persisted. It must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. Yes
Destination Schema The schema where data will be persisted, which must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. See the following examples:
- `CREATE SCHEMA SCHEMA_NAME` or `CREATE SCHEMA schema_name`: use `SCHEMA_NAME` - `CREATE SCHEMA "schema_name"` or `CREATE SCHEMA "SCHEMA_NAME"`: use `schema_name` or `SCHEMA_NAME`, respectively
Yes
Snowflake Authentication Strategy When using: - **Snowflake Openflow Deployment** or **BYOC**: Use SNOWFLAKE_MANAGED. This token is managed automatically by Snowflake. BYOC deployments must have previously configured [execute-as roles](#label-deployment-byoc-setup-runtime-role) to use SNOWFLAKE_MANAGED. - **BYOC**: Alternatively, BYOC can use KEY_PAIR as the value for the authentication strategy. Yes
Snowflake Account Identifier When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Snowflake account name formatted as [organization-name]-[account-name]. Yes
Snowflake Private Key When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. -
**KEY_PAIR**: Must be the RSA private key used for authentication.
The RSA key must be formatted according to PKCS8 standards and have standard PEM headers and footers. Note that either a Snowflake Private Key File or a Snowflake Private Key must be defined.
No
Snowflake Private Key File When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: The private key file must be blank. - **KEY_PAIR**: Upload the file that contains the RSA private key used for authentication to Snowflake, formatted according to PKCS8 standards and including standard PEM headers and footers. The header line begins with `-----BEGIN PRIVATE`. To upload the private key file, select the **Reference asset** checkbox. No
Snowflake Private Key Password When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the password associated with the Snowflake private key file. No
Snowflake Role When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Use the runtime's execute-as role (or a child role granted to it). You can find your execute-as role in the Openflow UI by navigating to **View Details** for your runtime. - **KEY_PAIR**: Use a valid role configured for your service user. Yes
Snowflake Username When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the username used to connect to the Snowflake instance. Yes
Snowflake Warehouse Snowflake warehouse used to run queries. Yes
Parameter Description
Report Name The unique name of the report. It is uppercased and used as the destination table name.
Start Date Start date from which ingestion should begin. Must be in the yyyy-MM-dd format.
Time Granularity Time granularity of results. Possible values: - `ALL`: Results grouped into a single result across the entire time range of the report. - `DAILY`: Results grouped by day. - `MONTHLY`: Results grouped by month. - `YEARLY`: Results grouped by year.
Conversion Window The timeframe for which data is refreshed during incremental load when `DAILY` time granularity is chosen. For example, if the conversion window is equal to 30 days, then during the INCREMENTAL load, the ingestion starts from the date of the last successful ingestion minus 30 days. Required when `DAILY` time granularity is specified. For other possible time granularities, such as `ALL`, `MONTHLY`, and `YEARLY`, the SNAPSHOT ingestion strategy is used. Data from the start date to the present is always downloaded, so there is no need to use a conversion window. The conversion window can be any number from 1 to 365.
Metrics Comma-separated list of metrics. Metrics are case-sensitive. For more information, see Reporting (https://learn.microsoft.com/en-us/linkedin/marketing/integrations/ads-reporting/ads-reporting?view=li-lms-2025-03&tabs=http#metrics-available). The `pivotValues` and `dateRange` metrics are mandatory and are automatically included by the connector. Up to 20 metrics can be specified, including the mandatory metrics.
Pivots Comma-separated list of pivots. The available pivots are as follows: - Analytics Finder (https://learn.microsoft.com/en-us/linkedin/marketing/integrations/ads-reporting/ads-reporting?view=li-lms-2025-03&tabs=http#analytics-finder) - Statistics Finder (https://learn.microsoft.com/en-us/linkedin/marketing/integrations/ads-reporting/ads-reporting?view=li-lms-2025-03&tabs=http#statistics-finder) The connector uses the Analytics Finder when zero or one pivot is specified, and switches to the Statistics Finder when two or three pivots are selected. You can use a maximum of three pivots.
Shares Comma-separated list of share IDs. This parameter can be used to filter results by share ID.
Campaigns Comma-separated list of campaign IDs. This parameter can be used to filter results by campaign ID.
Campaign Groups Comma-separated list of campaign group IDs. This parameter can be used to filter results by campaign group ID.
Accounts Comma-separated list of account IDs. This parameter can be used to filter results by account ID.
Companies Comma-separated list of company IDs. This parameter can be used to filter results by company ID.
Parameter Description
Access Token Token required to request Meta Ads Insights API
Parameter Description Required
Destination Database The database where data will be persisted. It must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. Yes
Destination Schema The schema where data will be persisted, which must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. See the following examples:
- `CREATE SCHEMA SCHEMA_NAME` or `CREATE SCHEMA schema_name`: use `SCHEMA_NAME` - `CREATE SCHEMA "schema_name"` or `CREATE SCHEMA "SCHEMA_NAME"`: use `schema_name` or `SCHEMA_NAME`, respectively
Yes
Snowflake Authentication Strategy When using: - **Snowflake Openflow Deployment** or **BYOC**: Use SNOWFLAKE_MANAGED. This token is managed automatically by Snowflake. BYOC deployments must have previously configured [execute-as roles](#label-deployment-byoc-setup-runtime-role) to use SNOWFLAKE_MANAGED. - **BYOC**: Alternatively, BYOC can use KEY_PAIR as the value for the authentication strategy. Yes
Snowflake Account Identifier When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Snowflake account name formatted as [organization-name]-[account-name]. Yes
Snowflake Private Key When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. -
**KEY_PAIR**: Must be the RSA private key used for authentication.
The RSA key must be formatted according to PKCS8 standards and have standard PEM headers and footers. Note that either a Snowflake Private Key File or a Snowflake Private Key must be defined.
No
Snowflake Private Key File When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: The private key file must be blank. - **KEY_PAIR**: Upload the file that contains the RSA private key used for authentication to Snowflake, formatted according to PKCS8 standards and including standard PEM headers and footers. The header line begins with `-----BEGIN PRIVATE`. To upload the private key file, select the **Reference asset** checkbox. No
Snowflake Private Key Password When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the password associated with the Snowflake private key file. No
Snowflake Role When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Use the runtime's execute-as role (or a child role granted to it). You can find your execute-as role in the Openflow UI by navigating to **View Details** for your runtime. - **KEY_PAIR**: Use a valid role configured for your service user. Yes
Snowflake Username When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the username used to connect to the Snowflake instance. Yes
Snowflake Warehouse Snowflake warehouse used to run queries. Yes
Parameter Description
Report Name Name of the report to be used as a destination table name. The name must be unique within the destination schema.
Report Object Id Identifier of the downloaded object from Meta Ads.
Reference to API listing different object ids:
- Ad Accounts (https://developers.facebook.com/docs/graph-api/reference/user/adaccounts) - Ad Sets (https://developers.facebook.com/docs/marketing-api/reference/ad-account/adsets/) - Ads (https://developers.facebook.com/docs/marketing-api/reference/ad-account/ads/) - Campaigns (https://developers.facebook.com/docs/marketing-api/reference/ad-account/campaigns/)
Report Ingestion Strategy Mode in which data is fetched, either snapshot or incremental
Meta Ads Version Version of Meta Ads API used for downloading reports. Allowed value: `v22.0`.
Report Level Presents the aggregation level of the result.
Possible values:
- `account` - `campaign` - `ad` - `adset`.
Report Fields Comma separated list of report fields
Report Breakdowns Comma separated list of report breakdowns. Full list of available breakdowns can be found here (https://developers.facebook.com/docs/marketing-api/insights/breakdowns).
Report Time Increment Level of aggregation based on the day count
Possible values:
- `1` - Daily - `3` - Every 3 days - `7` - Weekly - `monthly` - Monthly - `90` - Quarterly - `all_days` - All days; do not slice the result
Report Action Time Time of action stats
Possible values:
- `conversion` - Reports action based on conversion date - `impression` - Reports action based on impression date - `mixed` - Mixed approach between conversion and impression
Report Click Attribution Window Attribution window for the click action
Possible values:
- `1d_click` - `7d_click` - `28d_click`
Report View Attribution Window Attribution window for the view action
Possible values:
- `1d_view` - `7d_view` - `28d_view`
Report Schedule Schedule time for processor creating reports
Report Start Date Start date from which the ingestion should happen. The date format is YYYY-MM-DD.
Parameter Description
Source Dataverse Environment URL The main identifier of a source system to fetch data. The URL indicates a namespace where Dataverse tables exist. It also lets you create a scope parameter for OAuth.
Source Tenant ID Microsoft Azure Tenant ID. It's used to create OAuth URLs. Microsoft Dataverse Environment must belong to this tenant.
Source OAuth Client ID Microsoft Azure Client ID used to access Microsoft Dataverse API. Microsoft Dataverse Web API (https://learn.microsoft.com/en-us/power-apps/developer/data-platform/webapi/overview) uses OAuth authentication to secure access, and the connector uses the client credentials flow. To learn about client ID and how to find it in Microsoft Entra, see Application ID (client ID) (https://learn.microsoft.com/en-us/azure/healthcare-apis/register-application#application-id-client-id).
Source OAuth Client Secret Microsoft Azure Client Secret used to access Microsoft Dataverse API. Microsoft Dataverse Web API (https://learn.microsoft.com/en-us/power-apps/developer/data-platform/webapi/overview) uses OAuth authentication to secure access, and the connector uses the client credentials flow. To learn about client secret and how to find it in Microsoft Entra, see Certificates & secrets (https://learn.microsoft.com/en-us/azure/healthcare-apis/register-application#certificates--secrets).
Parameter Description Required
Destination Database The database where data will be persisted. It must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. Yes
Destination Schema The schema where data will be persisted, which must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. See the following examples:
- `CREATE SCHEMA SCHEMA_NAME` or `CREATE SCHEMA schema_name`: use `SCHEMA_NAME` - `CREATE SCHEMA "schema_name"` or `CREATE SCHEMA "SCHEMA_NAME"`: use `schema_name` or `SCHEMA_NAME`, respectively
Yes
Snowflake Authentication Strategy When using: - **Snowflake Openflow Deployment** or **BYOC**: Use SNOWFLAKE_MANAGED. This token is managed automatically by Snowflake. BYOC deployments must have previously configured [execute-as roles](#label-deployment-byoc-setup-runtime-role) to use SNOWFLAKE_MANAGED. - **BYOC**: Alternatively, BYOC can use KEY_PAIR as the value for the authentication strategy. Yes
Snowflake Account Identifier When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Snowflake account name formatted as [organization-name]-[account-name]. Yes
Snowflake Private Key When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. -
**KEY_PAIR**: Must be the RSA private key used for authentication.
The RSA key must be formatted according to PKCS8 standards and have standard PEM headers and footers. Note that either a Snowflake Private Key File or a Snowflake Private Key must be defined.
No
Snowflake Private Key File When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: The private key file must be blank. - **KEY_PAIR**: Upload the file that contains the RSA private key used for authentication to Snowflake, formatted according to PKCS8 standards and including standard PEM headers and footers. The header line begins with `-----BEGIN PRIVATE`. To upload the private key file, select the **Reference asset** checkbox. No
Snowflake Private Key Password When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the password associated with the Snowflake private key file. No
Snowflake Role When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Use the runtime's execute-as role (or a child role granted to it). You can find your execute-as role in the Openflow UI by navigating to **View Details** for your runtime. - **KEY_PAIR**: Use a valid role configured for your service user. Yes
Snowflake Username When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the username used to connect to the Snowflake instance. Yes
Snowflake Warehouse Snowflake warehouse used to run queries. Yes
Parameter Description
Ingestion Schedule Interval Interval used as the triggering interval for the processor that fetches the list of tables and initializes ingestion. The default is `300 s`.
Source Tables Filter Strategy Strategy for filtering tables to be ingested. Can be one of REGEXP and LIST.
Source Tables Filter Value Value of the tables filter. When Source Tables Filter Strategy is set to REGEXP - this is the regular expression to be matching selected tables. When LIST is provided, then it is a comma separated list of table names.
Column Filter JSON Optional. A JSON array specifying per-table column filters. Columns can be included or excluded by name (`included`, `excluded`) or by regular expression pattern (`includedPattern`, `excludedPattern`). The `table` value must be the **singular logical entity name** (e.g., `annotation`), not the plural entity set name used in `Source Tables Filter Value` (e.g., `annotations`). For example: `[ {"table": "mytable", "excluded": ["binarycolumn", "binarycolumn_binary"]} ]` excludes large binary columns from `mytable`. See [Replicate a subset of columns in a table](#replicate-a-subset-of-columns-in-a-table) for full details.
Max Page Size Number of records fetched from a Dataverse table in a single request. It can't be larger than 5000. A higher value can increase ingestion speed, but it can also cause timeouts. The default is `1000`.
Merge Task Schedule CRON CRON expression that defines when data is merged from the journal table into the destination table. The default is `* * * * * ?`, which merges continuously. Use a narrower schedule to reduce how long the warehouse runs. For example, `* 0 * * * ?` merges for one minute at the top of every hour.
Include Formatted Values Optional. Whether the connector also fetches Dataverse formatted values and writes them to the `_DATAVERSE_FORMATTED_VALUES` column of the destination table. The default is `false`. See [Include formatted values](#label-include-formatted-values).
Parameter Description
MongoDB Connection URI MongoURI, typically of the form: `mongodb://host1[:port1][,host2[:port2],...]/?[options]` Snowflake recommends that you include the `readPreference=secondaryPreferred` option in the URI. This directs read operations to the secondary nodes, reducing the overhead on the primary node of the replica set. Database username and password must not be provided in the URI as this is considered a security issue. Example: `mongodb://10.11.98.246:27017,10.11.104.58:27017/?replicaSet=myReplicaSet&readPreference=secondaryPreferred`
MongoDB Username The username for interacting with MongoDB. Example: `openflowUser`
MongoDB Password The password for interacting with MongoDB. Example: `myPassword123`
MongoDB Authentication Source The database containing user credentials. Example: `admin`
MongoDB Authentication Mechanism Authentication mechanism that MongoDB uses to authenticate the connection. Possible values are: - `None`: Connect without authentication. - `SCRAM-SHA-256`: Authentication mechanism that uses the SHA-256 hashing function.
Parameter Description
Destination Database The name of the destination database to replicate into. Mixed case is supported. Example: `MY_DESTINATION_DB`
Snowflake Account Identifier When using: - `SNOWFLAKE_MANAGED` Authentication Strategy: Must be blank. - `KEY_PAIR`: Snowflake account name where data will be persisted.
Snowflake Authentication Strategy When using: - SPCS, use `SNOWFLAKE_MANAGED` as the value for Authentication Strategy. - BYOC, use `KEY_PAIR` as the value for Authentication Strategy. Example: `KEY_PAIR`
Snowflake Connection Strategy When using: - `KEY_PAIR`: Specify the strategy for connecting to Snowflake. Possible values: `STANDARD`, `PRIVATE_CONNECTIVITY`.
Snowflake Private Key When using: - `SNOWFLAKE_MANAGED` Authentication Strategy: The private key must be blank. - `KEY_PAIR`: Copy the content of the RSA private key used for authentication to Snowflake, formatted according to PKCS8 standards and including standard PEM headers and footers. The header line begins with `-----BEGIN PRIVATE`.
Snowflake Private Key File When using: - `SNOWFLAKE_MANAGED` Authentication Strategy: The private key file must be blank. - `KEY_PAIR`: Upload the file that contains the RSA private key used for authentication to Snowflake, formatted according to PKCS8 standards and including standard PEM headers and footers. The header line begins with `-----BEGIN PRIVATE`. To upload the private key file, select the Reference asset checkbox.
Snowflake Private Key Password When using: - `SNOWFLAKE_MANAGED` Authentication Strategy: Must be blank. - `KEY_PAIR`: Provide the password associated with the Snowflake Private Key File.
Snowflake Role When using: - `SNOWFLAKE_MANAGED` Authentication Strategy: Use the runtime's execute-as role (or a child role granted to it). You can find your execute-as role in the Openflow UI by navigating to View Details for your runtime. - `KEY_PAIR` Authentication Strategy: Use a valid role configured for your service user. Example: `OPENFLOW__EXECUTE_AS_RL`
Snowflake Username When using: - `SNOWFLAKE_MANAGED` Authentication Strategy: Must be blank. - `KEY_PAIR`: Provide the username used to connect to the Snowflake instance. Example: `OPENFLOW_USER`
Snowflake Warehouse The name of the warehouse used by the connector. Example: `OPENFLOW_WH`
Parameter Description
Included Collection Names Comma-separated list of the collections to replicate. Example: `my_db.collection1,my_db.collection2`
Included Collection Regex Regular expression for specifying collection names to replicate. Example: `my_db.*`
Object Identifier Resolution The default for the %mongodbof% is `CASE_INSENSITIVE`. This differs from other Openflow database connectors (such as Postgres and MySQL), which default to `CASE_SENSITIVE` for backwards compatibility. Specifies how source object identifiers such as the names of schemas, tables, and columns are stored and queried in Snowflake. This setting specifies that you must use double quotes in SQL queries. Option 1: Default, case-sensitive. For backwards compatibility. - **Transformation**: Case is preserved. For example, `My_Table` remains `My_Table`. - **Queries**: SQL queries must use double quotes to match the exact case for database objects. For example, `SELECT * FROM "My_Table";`. Snowflake recommends using this option if you must preserve source casing for legacy or compatibility reasons. For example, if the source database includes table names that differ in case only–such as `MY_TABLE` and `my_table`–that would result in a name collision when using when using case-insensitive comparisons. Option 2: Recommended, case-insensitive - **Transformation**: All identifiers are converted to uppercase. For example, `My_Table` becomes `MY_TABLE`. - **Queries**: SQL queries are case-insensitive and don't require SQL double quotes. For example, `SELECT * FROM my_table;` returns the same results as `SELECT * FROM MY_TABLE;`. Snowflake recommends using this option if database objects are not expected to have mixed case names. Do not change this setting after the connector has begun ingesting data. Changing this setting after ingestion has begun breaks the existing ingestion. If you must change this setting, create a new connector instance.
Merge Task Schedule CRON CRON expression defining periods when merge operations from journal to destination table are triggered. Use `* * * * * ?` for continuous merge, or a time schedule to limit warehouse run time. For example: - The string `* 0 * * * ?` schedules merges at the full hour for one minute. - The string `* 20 14 ? * MON-FRI` schedules merges at 2:20 PM every Monday through Friday. For additional information and examples, see the cron triggers tutorial in the Quartz Documentation (https://www.quartz-scheduler.org/documentation/quartz-2.2.2/tutorials/tutorial-lesson-06.html). Example: `* * * * * ?`
`log_bin` Set to `on`. This enables the binary log that records structural and data changes.
`binlog_format` Set to `row`. The connector supports only row-based replication. MySQL 8.x versions may be the last ones to support this setting, and future versions will only support row-based replication. Not applicable in GCP Cloud SQL, where it is fixed at the right value.
`binlog_row_metadata` Set to `full`. The connector requires all row metadata to operate, most importantly, column names and primary key information. Under Microsoft Azure Database for MySQL the `binlog_row_metadata` field isn't user modifiable. Raise a Microsoft support ticket to change this value.
`binlog_row_image` Set to `full`. The connector requires that all columns be written into the binary log. Not applicable in Amazon Aurora, where it is fixed at the right value.
`binlog_row_value_options` Leave empty. This option only affects JSON columns, where it can be set to include only the modified parts of JSON documents for `UPDATE` statements. The connector requires that full documents are written into the binary log.
`binlog_expire_logs_seconds` Snowflake recommends setting the binary log expiration period (binlog_expire_logs_seconds) (https://dev.mysql.com/doc/refman/8.4/en/replication-options-binary-log.html#sysvar_binlog_expire_logs_seconds) to at least 72 hours (`259200`). Retention has to cover the entire window between a replication problem starting, someone noticing it, and the fix being applied. Once the expiration period elapses, MySQL can remove binary log files automatically, and Openflow can't replicate data from files that no longer exist, so the data is lost. Time spent paused counts toward that window, whether the pause is planned maintenance or an unnoticed failure. If you're using scheduled replication, the value needs to be longer than the configured schedule.
`binlog_legacy_event_pos` Set to `ON`. Required only when the source is MariaDB. The connector requires this flag to track binary log positions correctly during replication. Not applicable to MySQL.
TO ''@'%' ``` For more information on replication security, see Binary log (https://dev.mysql.com/doc/refman/8.4/en/binary-log.html). ### Snowflake account setup As an Openflow administrator, perform the following tasks for this connector. With the default `SNOWFLAKE_MANAGED` authentication strategy, the runtime's execute-as role is the identity the connector uses to access Snowflake, so you grant these privileges to that role rather than creating a separate service user. 1. Create a database to store the replicated data, and grant the execute-as role [USAGE and CREATE SCHEMA](#label-database-privileges) on it. The connector creates destination schemas automatically. Snowflake recommends a dedicated destination database per connector, to avoid collisions with other data sources including other connectors. Keep this destination database separate from the database that holds your Openflow infrastructure objects, such as the runtime, the connector, and any secrets. A connector creates destination objects based on the source schema and table names, so those names aren't under your control and can change as the source changes. ```sql CREATE DATABASE IF NOT EXISTS ; GRANT USAGE ON DATABASE TO ROLE ; GRANT CREATE SCHEMA ON DATABASE TO ROLE ; ``` 2. Designate a warehouse for the connector to use, and grant the execute-as role **USAGE** and **OPERATE** on it. Start with the `XSMALL` warehouse size, then experiment with size depending on the number of tables being replicated, and the amount of data transferred. Large table numbers typically scale better with [multi-cluster warehouses](/user-guide/warehouses-multicluster), rather than the warehouse size. ```sql CREATE WAREHOUSE WITH WAREHOUSE_SIZE = 'XSMALL' AUTO_SUSPEND = 300 AUTO_RESUME = TRUE; GRANT USAGE, OPERATE ON WAREHOUSE TO ROLE ; ``` 3. **Snowflake deployments only:** Make sure this connector's source host and port are permitted by a network rule that your runtime's external access integration (EAI) allows. The EAI itself belongs to the runtime, not to this connector. You create it once, attach it to the runtime, and grant the execute-as role `USAGE` on it. For those steps, see [Creating network rules and external access integrations](/user-guide/data-integration/openflow/setup-openflow-spcs-create-rr#label-create-network-rules-and-external-access-integrations). What is specific to this connector is getting its source host into a rule that EAI references. The rule takes the source's host and port as a single value, such as `db.example.com:`. That's the host and port from the connector's connection URL, without the `jdbc:` scheme, the driver name, or the database path. BYOC deployments handle outbound connectivity in the cloud environment and don't use EAIs or network rules. #### Additional setup for key-pair authentication (BYOC only) Key-pair authentication is available only for BYOC deployments, and is not required for the default `SNOWFLAKE_MANAGED` authentication strategy. Skip this section unless you set the connector's **Snowflake Authentication Strategy** parameter to `KEY_PAIR`. 1. Create a Snowflake user with the type as [SERVICE](#label-user-type-property), create a role for it, and grant that role the same destination database and warehouse privileges you granted the execute-as role: ```sql CREATE USER TYPE=SERVICE COMMENT='Service user for automated access of Openflow'; CREATE ROLE ; GRANT ROLE TO USER ; GRANT USAGE ON DATABASE TO ROLE ; GRANT CREATE SCHEMA ON DATABASE TO ROLE ; GRANT USAGE, OPERATE ON WAREHOUSE TO ROLE ; ``` 2. Create a pair of secure keys (public and private). Store the private key for the user in a file to supply to the connector's configuration. Assign the public key to the Snowflake service user: ```sql ALTER USER SET RSA_PUBLIC_KEY = 'thekey'; ``` For more information, see [pair of keys](/user-guide/key-pair-auth). When using `KEY_PAIR`, you must also set the connector's **Snowflake Account Identifier** and **Snowflake Connection Strategy** parameters. Both are left blank or ignored under `SNOWFLAKE_MANAGED`. ## Gather these before you install You can stop and collect any of these later, but having them on hand first lets you install and configure the connector in one pass: - **The MariaDB JDBC driver `.jar` file.** You supply the driver file itself, so download it beforehand. - **A JDBC connection URL**, which must use the `jdbc:mariadb` scheme because the connector connects through the MariaDB driver. SSL is configured in the URL itself rather than as a separate property, by appending an `sslMode` parameter. - **A source database user** with the privileges described in [Source database setup](#source-database-setup). - **The source database user's password.** - **Decisions on the settings that can't be changed later.** Destination schema naming, object identifier resolution (whether MySQL names are stored case-sensitively or uppercased), and table storage format are fixed once the connector has applied its configuration and begun ingesting. Changing them afterwards requires a new connector instance and a fresh snapshot. ## Install the connector ### Choose your generation This connector is available in both gen 1 and gen 2.
If you're unsure, see [Openflow gen 1 and gen 2](/user-guide/data-integration/openflow/gen2/openflow-generations) for a full comparison. The catalog lists two entries with the same name, **MySQL and MariaDB**. The gen 2 entry is the one marked with a **Gen 2** tag, and it also carries a **Preview** tag during public preview. The gen 1 entry has no tag. Install the connector from the Openflow connector catalog. To install the connector, do the following as a data engineer: 1. Navigate to the Openflow overview page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find the entry for the generation you chose and select **Install**. 3. Select the runtime to install the connector on. If you're prompted to authenticate, sign in with your Snowflake account credentials. What happens next depends on the generation you chose: - **Gen 2**: the setup wizard opens and collects the connector's configuration in one guided flow. Continue with Configure the connector below, which describes the values this connector needs. If you would rather configure the connector programmatically instead of using the wizard, see [Configure a gen 2 connector with SQL](/user-guide/data-integration/openflow/gen2/configure-connector-sql). - **Gen 1**: the Openflow canvas appears with the connector process group added to it. ## Configure the connector *Using gen 1? [Skip to Configure on the canvas.](#label-mysql-configure-gen1-canvas)* ### Configure with the setup wizard or SQL (gen 2) [CoCo](/user-guide/cortex-code/cortex-code) can help you make sure your prerequisites are in place. Try pasting this prompt into CoCo: > Please help me with the prerequisites for a gen 2 Openflow connector for MySQL and MariaDB. Use skill @(serverSkill:openflow). Gen 2 references the source database password as a Snowflake secret of type `GENERIC_STRING` rather than taking the password inline. Create the secret in the same database and schema that holds your Openflow infrastructure objects (the runtime and connector), keeping infrastructure separate from the destination database where replicated data is persisted: ```sql CREATE SECRET .. TYPE = GENERIC_STRING SECRET_STRING = ''; GRANT READ ON SECRET .. TO ROLE ; ``` If the execute-as role doesn't already have `USAGE` on the infrastructure database and schema (for example, if you deviated from the recommended setup path), grant it: ```sql GRANT USAGE ON DATABASE TO ROLE ; GRANT USAGE ON SCHEMA . TO ROLE ; ``` With the secret in place, configure the connector with the [setup wizard](/user-guide/data-integration/openflow/gen2/setup-connector-wizard) or, for automation, by editing the connector's `config.json` with SQL and stage file operations; see [Configure a gen 2 connector with SQL](/user-guide/data-integration/openflow/gen2/configure-connector-sql). ### Gen 2 parameters The following table lists the gen 2 connector parameters, grouped by the wizard step where you configure them. The wizard's **Step Documentation** panel describes each property in full; this table gives the parameter name and its purpose so you can prepare before entering the wizard.
*Using gen 2? [Skip to Run the flow.](#label-mysql-run-the-flow)* ### Configure on the canvas (gen 1) To configure the connector on the canvas, do the following as a data engineer: 1. Right-click on the imported process group and select **Parameters**. 2. Populate the required parameter values. For more information on the required parameter values, see the following sections: - [](#label-of-mysql-source-parameters): Used to establish a connection with MySQL. - [](#label-of-mysql-destination-parameters): Used to establish a connection with Snowflake. - [](#label-of-mysql-ingestion-parameters): Used to specify the tables to replicate. Start with setting the parameters of the MySQL Source Parameters context, then the MySQL Destination Parameters context. After this is done, you can enable the connector. The connector should connect to both MySQL and Snowflake and start running. However, the connector doesn't replicate any data until any tables to be replicated are explicitly added to its configuration. To configure specific tables for replication, edit the MySQL Ingestion Parameters context. After you apply the changes to the MySQL Ingestion Parameters context, the configuration is picked up by the connector, and the replication lifecycle starts for every table. To run multiple CDC connector instances on one runtime, see [](/user-guide/data-integration/openflow/connectors/cdc-runtime-sizing#run-multiple-connectors-on-one-runtime). ### MySQL Source Parameters
### MySQL Destination Parameters
### MySQL Ingestion Parameters
## Replicate a subset of columns in a table The following describes the gen 1 `Column Filter JSON` parameter. In gen 2, you select columns per table in the **Replication columns** step of the setup wizard; see [](#configure-with-the-setup-wizard-or-sql-gen-2) for that step. The connector can filter the data replicated per table to a subset of configured columns. Primary key columns are always included regardless of exclusions. To apply column filters, set the **Column Filter JSON** parameter in the Ingestion Parameters context to a JSON array of filter objects, one per table you want to filter. Columns can be included or excluded by name or by regular expression pattern. You can apply a single condition per table, or combine multiple conditions, with exclusions always taking precedence over inclusions. ## Syntax Each object in the array identifies a table and specifies which columns to include or exclude. ```javascript [ { "schema": "" | "schemaPattern": "", "table": "
Gen 2 (recommended) Gen 1
**Management** SQL commands + setup wizard Runtime canvas UI
**Configuration** Versioned config files, CI/CD-friendly Canvas parameters
**Release status** Public Preview Generally Available
Parameter Wizard step Description
Source Database Connection URL Source The JDBC URL to the MySQL or MariaDB source. It must start with `jdbc:mariadb://` and can include the SSL mode. For example: `jdbc:mariadb://db.example.com:3306/?sslMode=verify-full`.
Source Database Driver Source The MariaDB JDBC driver (https://mariadb.com/downloads/connectors/connectors-data-access/java8-connector/) `.jar`, uploaded in the wizard.
Source Database User Source The source database user with `REPLICATION SLAVE`, `REPLICATION CLIENT`, `SELECT`, and `RELOAD` privileges.
Source Database Password Source A Snowflake secret of type `GENERIC_STRING` holding the source user's password, with `READ` granted to the execute-as role.
Configure Logical Keys Source Whether to use default primary-key detection or declare custom logical keys for tables without a usable primary key.
Included Source Table Pattern Replication table schema The schemas and tables to replicate, selected manually or matched by a regular expression.
Replication Columns Replication columns Which columns to include per table, and whether newly added columns are included automatically.
Snowflake Destination Database Destination details The database where replicated data is persisted. The execute-as role needs `USAGE` and `CREATE SCHEMA` on it.
Snowflake Warehouse Destination details The warehouse used for merge operations. Start with `XSMALL`; for many tables, a multi-cluster warehouse scales better than a larger size.
Destination Schema Strategy Destination details How destination schemas are named, to avoid collisions when consolidating more than one source database into a single Snowflake database. Fixed after first apply.
Object Identifier Resolution Destination details Whether source object names are stored case-sensitively (default) or uppercased (recommended). Fixed after first apply.
Oversized Value Strategy Destination details How values exceeding the 16 MB limit are handled. Defaults to **Set Null**.
Error Handling Strategy Destination details How invalid rows are handled. Defaults to **Log Errors and Continue**.
Table Storage Format Destination details Standard Snowflake tables or Iceberg tables. Fixed after first apply.
Iceberg Version Destination details When using Iceberg, the table version (2 or 3, default 3).
Merge Task Schedule CRON Tuning CRON expression controlling when journal data is merged into destination tables, which is when warehouse cost accrues.
Concurrent Snapshot Queries Tuning How many tables to snapshot concurrently (default 2). Each holds a source database connection.
Ingestion Type Migration Whether new tables get a full snapshot before switching to CDC (default) or go straight to incremental.
Starting Binlog Position Migration Where in the binlog to start reading: Latest (default) or Earliest.
Parameter Description
MySQL Connection URL The full JDBC URL to the source database. The connector uses the MariaDB driver, which is compatible with MySQL and requires the `jdbc:mariadb` prefix in the URL. If the SSL is disabled, then the connection URL should have the `allowPublicKeyRetrieval` parameter set to `true`. Examples: - With SSL enabled: `jdbc:mariadb://example.com:3306` - With SSL disabled: `jdbc:mariadb://example.com:3306?allowPublicKeyRetrieval=true`
MySQL JDBC Driver The absolute path to the MariaDB JDBC driver jar (https://mariadb.com/downloads/connectors/connectors-data-access/java8-connector/). The connector uses the MariaDB driver, which is compatible with MySQL. Select the **Reference asset** checkbox to upload the MariaDB JDBC driver. Example: `/opt/resources/drivers/mariadb-java-client-3.5.2.jar`
MySQL Username The username for the connector.
MySQL Password The password for the connector.
Parameter Description Required
Destination Database The database where data is persisted. It must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. Yes
Destination Schema Pattern A pattern for the names of destination schemas where data is persisted. The connector creates the schemas if they don't exist. You can customize the pattern per ingested table using these optional variables: - `${source.schema.name}`: the source database (a database in MySQL maps to a schema in Snowflake). - `${source.table.name}`: a source table's name. For example, for a table `my_database.users`, the pattern `prefix_${source.schema.name}` evaluates to `prefix_my_database`. To ingest all tables into a single schema, provide a schema name without any variables, like `destination_schema`. Don't change this setting after the connector has begun ingesting data. Changing this setting after ingestion has begun breaks the existing ingestion. If you must change this setting, create a new connector instance. Yes
Snowflake Authentication Strategy When using: - **Snowflake Openflow Deployment** or **BYOC**: Use SNOWFLAKE_MANAGED. This token is managed automatically by Snowflake. BYOC deployments must have previously configured [execute-as roles](#label-deployment-byoc-setup-runtime-role) to use SNOWFLAKE_MANAGED. - **BYOC**: Alternatively, BYOC can use KEY_PAIR as the value for the authentication strategy. Yes
Snowflake Account Identifier When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Snowflake account name formatted as [organization-name]-[account-name]. Yes
Snowflake Connection Strategy When using KEY_PAIR, specify the strategy for connecting to Snowflake: - **STANDARD** (default): Connect using standard public routing to Snowflake services. - **PRIVATE_CONNECTIVITY**: Connect using private addresses associated with the supporting cloud platform such as AWS PrivateLink. Required for BYOC with KEY_PAIR only, otherwise ignored.
Snowflake Private Key When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. -
**KEY_PAIR**: Must be the RSA private key used for authentication.
The RSA key must be formatted according to PKCS8 standards and have standard PEM headers and footers. Note that either a Snowflake Private Key File or a Snowflake Private Key must be defined.
No
Snowflake Private Key File When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: The private key file must be blank. - **KEY_PAIR**: Upload the file that contains the RSA private key used for authentication to Snowflake, formatted according to PKCS8 standards and including standard PEM headers and footers. The header line begins with `-----BEGIN PRIVATE`. To upload the private key file, select the **Reference asset** checkbox. No
Snowflake Private Key Password When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the password associated with the Snowflake Private Key File. No
Snowflake Role When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Use the runtime's execute-as role (or a child role granted to it). You can find your execute-as role in the Openflow UI by navigating to **View Details** for your runtime. - **KEY_PAIR**: Use a valid role configured for your service user. Yes
Snowflake Username When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the user name used to connect to the Snowflake instance. Yes
Oversized Value Strategy Determines how the connector handles values that exceed its internal size limits (16 MB) during replication. Possible values are:
- **Fail Table** (default): The table is marked as permanently failed, and replication stops for that table. - **Set Null**: The value is replaced with `NULL` in the destination table. Use this to prevent table failures when it is acceptable to lose data in tables beyond the oversized value.
No
Error Handling Strategy Determines how the connector handles invalid rows that Snowflake rejects during ingestion. Possible values are:
- **Fail Table** (default): The table is marked as failed on the first invalid row, and replication stops for that table. - **Log Errors and Continue**: The connector keeps replicating the valid rows and records each rejected row in the table's error table.
No
Table Storage Format Standard Snowflake tables or Iceberg tables. Defaults to **STANDARD**. Don't change after the connector starts. Yes
Iceberg Version The Iceberg table version, 2 or 3 (default 3). Ignored unless Table Storage Format is **ICEBERG**. Don't change this value after ingestion begins. No
Snowflake Warehouse Snowflake warehouse used to run queries. Yes
Parameter Description
Included Table Names A comma-separated list of table paths, including their schemas. Example: `public.my_table, other_schema.other_table`
Included Table Regex A regular expression to match against table paths. Every path matching the expression will be replicated, and new tables matching the pattern that get created later will also be included automatically. Example: `public\.auto_.*`
Column Filter JSON Optional. A JSON array of filter objects specifying which columns to include or exclude per table. For syntax details and examples, see [Replicate a subset of columns in a table](#replicate-a-subset-of-columns-in-a-table).
Table Key Configuration Service Optional. A `JsonTableKeyConfigService` controller service that supplies a user-declared logical key for one or more tables. The service exposes a **Table Key Configuration JSON** property where you define the key mappings. When configured, the logical key takes the highest priority and overrides any primary key that the connector would otherwise auto-detect. For more information, see [](#label-mysql-logical-key).
Merge Task Schedule CRON A CRON expression defining when the connector merges journal data into destination tables, which is when warehouse cost accrues. The **Merge Journal to Destination** processor performs the merge on this schedule. With no new changes waiting, no merge runs and the warehouse is free to auto-suspend. Set it to `* * * * * ?` for continuous merges (lowest latency, highest cost), or schedule merges to limit warehouse run time. The connector evaluates the schedule in the UTC time zone. For example:
- The string `* 0 * * * ?` indicates that you want to schedule merges at the full hour for one minute. - The string `* 20 14 ? * MON-FRI` indicates that you want to schedule merges at 2:20 PM every Monday through Friday.
For additional information and examples, see the cron triggers tutorial in the Quartz Documentation (https://www.quartz-scheduler.org/documentation/quartz-2.5.x/tutorials/crontrigger.html).
Object Identifier Resolution Specifies how source object identifiers such as the names of schemas, tables, and columns are stored and queried in Snowflake. This setting specifies that you must use double quotes in SQL queries. Option 1: Default, case-sensitive. For backwards compatibility. - **Transformation**: Case is preserved. For example, `My_Table` remains `My_Table`. - **Queries**: SQL queries must use double quotes to match the exact case for database objects. For example, `SELECT * FROM "My_Table";`. Snowflake recommends using this option if you must preserve source casing for legacy or compatibility reasons. For example, if the source database includes table names that differ in case only–such as `MY_TABLE` and `my_table`–that would result in a name collision when using when using case-insensitive comparisons. Option 2: Recommended, case-insensitive - **Transformation**: All identifiers are converted to uppercase. For example, `My_Table` becomes `MY_TABLE`. - **Queries**: SQL queries are case-insensitive and don't require SQL double quotes. For example, `SELECT * FROM my_table;` returns the same results as `SELECT * FROM MY_TABLE;`. Snowflake recommends using this option if database objects are not expected to have mixed case names. Do not change this setting after the connector has begun ingesting data. Changing this setting after ingestion has begun breaks the existing ingestion. If you must change this setting, create a new connector instance.
Concurrent Snapshot Queries Maximum number of concurrent queries to the source database to run in the Snapshot flow. Increasing this can speed up snapshotting large numbers of tables, but will also increase the load on the source database.
" | "tablePattern": "", "included": ["", ""], "excluded": ["", ""], "includedPattern": "", "excludedPattern": "" } ] ``` The following rules apply: - Use `schema` and `table` for exact name matching, or `schemaPattern` and `tablePattern` for regex matching. You can't use both a field and its pattern variant in the same object (for example, `schema` and `schemaPattern` can't both appear). - At least one of `included`, `excluded`, `includedPattern`, or `excludedPattern` must be provided. - When both included and excluded filters are specified, exclusions take precedence. - When multiple filters match the same table, the last matching filter is used, with exact matches taking precedence over pattern-based filters. - The value can be an array of objects to apply different filters to different tables. ## Examples Include specific columns by name: ```javascript [ { "schema": "public", "table": "orders", "included": ["account_id", "status", "created_at"] } ] ``` Exclude specific columns by name: ```javascript [ { "schema": "public", "table": "orders", "excluded": ["internal_note", "debug_flag"] } ] ``` Combine an include pattern with a specific exclusion (for example, include all email columns except `admin_email`): ```javascript [ { "schema": "public", "table": "contacts", "includedPattern": ".*_email", "excluded": ["admin_email"] } ] ``` Mix a schema pattern with an exact table name to apply a filter across schemas: ```javascript [ { "schemaPattern": "data_.*", "table": "customers", "excluded": ["internal_note"] } ] ``` Pass multiple filter objects to apply different rules to different tables: ```javascript [ {"schema": "public", "table": "orders", "included": ["account_id", "status"]}, {"schema": "public", "table": "customers", "excludedPattern": ".*_internal"} ] ``` ### Including and excluding the same column Removing a column from a table's replicated set (by excluding it or by removing it from the included list) has the same effect on the destination as dropping the column at the source: the connector soft-deletes the column on the destination by renaming it with a suffix (by default, `__SNOWFLAKE_DELETED`). If you then add the column back to the replicated set and later remove it a second time, replication for the affected table fails because the soft-deleted column name is already taken. To recover, restart replication for the affected table. ## Specify a logical key for a table The connector requires a replication key for every table it replicates. By default, the connector uses the table's primary key. A *logical key* is a user-declared replacement for the auto-detected key. Configure a logical key when: - A table has no primary key, but one or more columns are unique in the data. - A specific column or set of columns should be used as the replication key, regardless of what the connector would auto-detect (for example, to override a synthetic primary key). A logical key takes the highest priority. When the connector finds a logical key for a table, it uses that key and ignores any primary key on the table. ### JSON syntax The **Table Key Configuration JSON** value is a JSON array. Each entry maps one table to its logical key columns: ```json [ { "schema": "", "table": "
", "logicalKey": ["", ""] } ] ``` The fields are:
The following rules apply: - `schema`, `table`, and `logicalKey` column matching is **case-sensitive**. Use the exact names as reported by MySQL. - An entry whose `schema` and `table` don't match any replicated table is silently ignored. ### Logical key configuration examples A single-column logical key on a table without a primary key: ```json [ { "schema": "sales", "table": "audit_log", "logicalKey": ["event_id"] } ] ``` A composite logical key: ```json [ { "schema": "sales", "table": "order_lines", "logicalKey": ["order_id", "line_item_id"] } ] ``` Logical keys for several tables in one JSON value: ```json [ { "schema": "sales", "table": "audit_log", "logicalKey": ["event_id"] }, { "schema": "sales", "table": "order_lines", "logicalKey": ["order_id", "line_item_id"] } ] ``` ### Restrictions The connector rejects the configuration when any of the following is true: - `logicalKey` is missing, empty, or not an array. - `logicalKey` contains duplicate column names. - `logicalKey` contains a nullable column. Logical key columns must be defined as `NOT NULL` to reliably identify rows. - `logicalKey` contains a column name that doesn't exist in the source table. When the configuration is rejected, the connector either fails to enable the controller service (for structural issues detected at enablement time) or holds the table in the `NEW` state (for issues detected when the table is initialized). After you fix the configuration, replication for the table resumes without resetting state. ### Warnings logged for risky configurations The connector accepts the following configurations but logs a warning at table initialization. When choosing logical-key columns, prefer columns with high cardinality and, where possible, monotonically increasing values. Low-cardinality or non-monotonic keys can degrade snapshot performance. - A logical-key column is a large-object type (`blob`, `tinyblob`, `mediumblob`, `longblob`, `text`, `tinytext`, `mediumtext`, `longtext`). Using large objects as keys severely degrades MERGE performance. - A logical-key column is a floating-point type (`float`, `double`). Floating-point comparisons can produce inconsistent results because of precision differences. - A logical-key column is a semi-structured type (`json`). Semi-structured values may produce non-deterministic equality comparisons. - The composite logical key includes more than five columns. Long composite keys often indicate a design issue and might degrade MERGE performance. - The logical key overrides an existing primary key on the table. Verify that the replacement key is intentional: the connector no longer uses the primary key for MERGE operations. If you observe data divergence after any of these warnings, run a periodic full reload to reconcile the destination with the source. ### Schema changes that affect a logical key Logical keys reference column names. The connector doesn't follow renames or drops of those columns: - If a logical-key column is dropped on the source, replication for the affected table fails. The table is marked `FAILED`. For more information, see [Restart table replication](#label-of-mysql-restart-table-replication). - If a logical-key column is renamed on the source, the configuration still references the old name and replication fails. Update the JSON to use the new name and restart table replication. ## Run the flow ### Gen 2 After you apply your configuration in the wizard, the connector's status moves to **Upgrading** and then to **Stopped** once upgrading finishes. Start it from the **Installed Connectors** tab: open the connector's menu and select **Start**. If the connector is still in **Draft** when you reach this step, its configuration hasn't been applied. Open the setup wizard and select **Apply** so your changes take effect before you start. After starting, open the connector's observability dashboard to confirm data is moving and there are no errors. To start, stop, or otherwise manage a gen 2 connector programmatically, see [Manage the gen 2 Openflow connector lifecycle](/user-guide/data-integration/openflow/gen2/manage-connector-lifecycle). ### Gen 1 1. Right-click on the canvas and select **Enable all Controller Services**. 2. Right-click on the imported process group and select **Start**. The connector starts the data ingestion. ## Set up alerts Snowflake recommends setting up alerts so that you're notified of ingestion errors or stalled replication without having to check the connector manually. This applies to both gen 1 and gen 2 connectors. Openflow writes telemetry, including logs and metrics, to an event table. Build an alert on that telemetry with a scheduled query: see [Monitor Openflow using telemetry data](/user-guide/data-integration/openflow/monitor) for the available telemetry and example queries, and [Setting up alerts based on data in Snowflake](/user-guide/alerts) for how to create an alert from a query. --- title: Set up the Openflow Connector for PostgreSQL source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/postgres/setup.md section: Loading & Unloading Data --- # Set up the %postgresql% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [About Openflow Connector for PostgreSQL](/user-guide/data-integration/openflow/connectors/postgres/about) - [Openflow Connector for PostgreSQL: Data mapping](/user-guide/data-integration/openflow/connectors/postgres/data-mapping) - [Openflow Connector for PostgreSQL Maintenance](/user-guide/data-integration/openflow/connectors/postgres/maintenance) This topic describes the steps to set up the %postgresql%. For details on the incremental load process, see [Incremental replication](/user-guide/data-integration/openflow/connectors/postgres/incremental-replication). For information about restarting replication for failed tables, see [Restart table replication](/user-guide/data-integration/openflow/connectors/postgres/maintenance#label-of-postgres-restart-table-replication). ## Prerequisites ### Before you begin 1. Ensure that you have reviewed [About Openflow Connector for PostgreSQL](/user-guide/data-integration/openflow/connectors/postgres/about). 2. Ensure that you have reviewed the [supported PostgreSQL versions](#label-supported-pg-versions). 3. Make sure you have an Openflow deployment and runtime for this connector. If you don't, see [Set up Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/setup-openflow-spcs) or [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc). A runtime's size is fixed when you create it, so decide on a size before you create the runtime. See [Runtime sizing and packing for CDC connectors](/user-guide/data-integration/openflow/connectors/cdc-runtime-sizing). 4. If using Snowflake deployments, ensure that you've reviewed [configuring required domains](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list) and have granted access to the required domains for the [](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list#label-openflow-domains-used-by-openflow-connectors-postgresql) connector. ### Source database setup As a database administrator, perform the following tasks: 1. [Configure wal_level](#configure-wal-level) 2. [Review other server settings](#label-postgres-review-server-settings) 3. [Create a publication](#create-a-publication) 4. Ensure that there is enough disk space on your PostgreSQL server for the WAL. This is because once created, a replication slot causes PostgreSQL to retain the WAL data from the position held by the replication slot, until the connector confirms and advances that position. 5. Ensure that every table enabled for replication has one of the following identity key configurations: - **Primary key**: The connector uses primary key columns as the identity key and requires the table's REPLICA IDENTITY to be set to `DEFAULT`. - **Unique index (for tables without a primary key)**: Use a unique index that meets the requirements in [](#label-postgres-configure-replica-identity-using-index) as the identity key. You must run `ALTER TABLE REPLICA IDENTITY USING INDEX ` before enabling replication. 6. For tables without a primary key, see [](#label-postgres-configure-replica-identity-using-index). 7. Create a user for the connector. The connector requires a user with the `REPLICATION` attribute and permissions to SELECT from every replicated table. Create that user with a password to enter into the connector's configuration. For more information on replication security, see Security (https://www.postgresql.org/docs/current/logical-replication-security.html). #### Configure wal_level %postgresql% requires wal_level (https://www.postgresql.org/docs/current/runtime-config-wal.html#GUC-WAL-LEVEL) to be set to `logical`. Depending on where your PostgreSQL server is hosted, you can configure the wal_level as follows:
#### Review server settings Aside from `wal_level`, review and adjust the following PostgreSQL server settings as required. Set each high enough to cover all %postgresql% instances on the server, plus any other replication traffic on the instance.
#### Create a publication %postgresql% requires a publication (https://www.postgresql.org/docs/current/logical-replication-publication.html#LOGICAL-REPLICATION-PUBLICATION) to be created and configured in PostgreSQL before replication starts. You can create it for all, or a subset of tables, as well as for specific tables with specified columns only. Make sure that every table and column that you plan to have replicated is included in the publication. You can also modify the publication later, while the connector is running. To create and configure a publication, do the following: 1. Log in as a user with the CREATE privilege on the database and run the following query: - For PostgreSQL 13 and later: ```sqlsyntax CREATE PUBLICATION WITH (publish_via_partition_root = true); ``` The additional `publish_via_partition_root` is needed for correct replication of partitioned tables. To learn more about ingestion of partitioned tables, see [](#label-postgres-connector-replicate-partitioned-table). - For PostgreSQL versions earlier than 13: ```sqlsyntax CREATE PUBLICATION ; ``` 2. Define tables that the database agent will be able to see using:
```sqlsyntax ALTER PUBLICATION ADD TABLE
Field Description
`schema` Required. The exact source schema name.
`table` Required. The exact source table name.
`logicalKey` Required. A non-empty array of source column names that uniquely identify rows in the table.
On-premises Execute the following query with a superuser or a user with the `ALTER SYSTEM` privilege:
```ini ALTER SYSTEM SET wal_level = logical; ```
RDS The user used by the agent needs to have the `rds_superuser` or `rds_replication` roles assigned. You also need to set:
- `rds.logical_replication` static parameter to 1. - `max_replication_slots`, `max_connections`, and `max_wal_senders` parameters according to your database and replication setup.
AWS Aurora Set the `rds.logical_replication` static parameter to 1.
GCP Set the following flags:
- `cloudsql.logical_decoding=on`. - `cloudsql.enable_pglogical=on`. For more information, see Google Cloud documentation (https://cloud.google.com/sql/docs/postgres/replication/configure-logical-replication#set-up-logical-replication-with-pglogical).
Azure Set the replication support to `Logical`. For more information, see Azure documentation (https://learn.microsoft.com/en-us/azure/postgresql/single-server/concepts-logical#set-up-your-server).
`max_replication_slots` Allow at least **1** logical replication slot per connector instance.
`max_wal_senders` Allow at least **1** WAL sender per connector instance.
`max_connections` Allow enough connections to cover each connector instance, in addition to your other database connections. Every connector instance uses 1 connection during regular operation, and up to 8 connections when snapshotting tables.
; ``` For partitioned tables, it's enough to just add the root partition table to the publication. See [](#label-postgres-connector-replicate-partitioned-table) for more details. **Important for PostgreSQL 15 and later:** If your PostgreSQL publication is configured to exclude any table columns, exclude those same columns in the connector replication configuration. Use the [column filtering settings](#label-postgres-connector-replication-subset-of-columns) so you don't ingest columns that the publication omits. Snapshot replication can still read columns that match the filter, but incremental ingestion only receives data for columns that are in the publication, so including columns in the filter that are excluded from the publication can cause those columns to be suffixed with `__DELETED`, or cause the table to permanently fail. For more information, see ALTER PUBLICATION (https://www.postgresql.org/docs/current/sql-alterpublication.html). #### Configure replica identity for tables without a primary key For tables without a primary key, you can use a unique index as the identity key by setting `REPLICA IDENTITY USING INDEX`: ```sqlsyntax ALTER TABLE REPLICA IDENTITY USING INDEX ; ``` The connector automatically detects this setting during schema discovery and uses the unique index columns for UPDATE and DELETE operations. The unique index must meet all of the following requirements. PostgreSQL validates these when you run the `ALTER TABLE` command and rejects any index that doesn't qualify:
To check the current REPLICA IDENTITY setting for a table, run: ```sqlsyntax SELECT n.nspname AS schema_name, c.relname AS table_name, CASE c.relreplident WHEN 'd' THEN 'DEFAULT' WHEN 'n' THEN 'NOTHING' WHEN 'f' THEN 'FULL' WHEN 'i' THEN 'USING INDEX: ' || i.relname END AS replica_identity FROM pg_class c JOIN pg_namespace n ON n.oid = c.relnamespace LEFT JOIN pg_index ix ON c.oid = ix.indrelid AND ix.indisreplident LEFT JOIN pg_class i ON ix.indexrelid = i.oid WHERE n.nspname = '' AND c.relname = '' AND c.relkind IN ('r','p'); ``` #### Replicate a partitioned table The connector supports replication of partitioned tables for PostgreSQL servers with version >= 15. A PostgreSQL partitioned table will be replicated into Snowflake as a single destination table. For example, if you have a partitioned table `orders`, with sub-partitions `orders_2023`, `orders_2024`, and configured the connector to ingest all tables matching `orders.*` pattern, then only the `orders` table will be replicated to Snowflake, and it will include data from all sub-partitions. To support replication of partitioned tables, ensure that [the publication](#label-postgres-connector-create-a-publication) created in PostgreSQL has the `publish_via_partition_root` option set to `true`. Ingestion of partitioned tables currently has the following limitations: - When a table is attached as a partition to a partitioned table after ingestion was started, the connector won't fetch data that existed in the partition table before attaching. - When a sub-partition table is detached from the partitioned table after ingestion was started, the connector won't mark the data from this sub-partition as deleted in the root partition table. - Truncate operation on sub-partitions won't mark affected records as deleted. ### Snowflake account setup As an Openflow administrator, perform the following tasks for this connector. With the default `SNOWFLAKE_MANAGED` authentication strategy, the runtime's execute-as role is the identity the connector uses to access Snowflake, so you grant these privileges to that role rather than creating a separate service user. 1. Create a database to store the replicated data, and grant the execute-as role [USAGE and CREATE SCHEMA](#label-database-privileges) on it. The connector creates destination schemas automatically. Snowflake recommends a dedicated destination database per connector, to avoid collisions with other data sources including other connectors. Keep this destination database separate from the database that holds your Openflow infrastructure objects, such as the runtime, the connector, and any secrets. A connector creates destination objects based on the source schema and table names, so those names aren't under your control and can change as the source changes. ```sql CREATE DATABASE IF NOT EXISTS ; GRANT USAGE ON DATABASE TO ROLE ; GRANT CREATE SCHEMA ON DATABASE TO ROLE ; ``` 2. Designate a warehouse for the connector to use, and grant the execute-as role **USAGE** and **OPERATE** on it. Start with the `XSMALL` warehouse size, then experiment with size depending on the number of tables being replicated, and the amount of data transferred. Large table numbers typically scale better with [multi-cluster warehouses](/user-guide/warehouses-multicluster), rather than the warehouse size. ```sql CREATE WAREHOUSE WITH WAREHOUSE_SIZE = 'XSMALL' AUTO_SUSPEND = 300 AUTO_RESUME = TRUE; GRANT USAGE, OPERATE ON WAREHOUSE TO ROLE ; ``` 3. **Snowflake deployments only:** Make sure this connector's source host and port are permitted by a network rule that your runtime's external access integration (EAI) allows. The EAI itself belongs to the runtime, not to this connector. You create it once, attach it to the runtime, and grant the execute-as role `USAGE` on it. For those steps, see [Creating network rules and external access integrations](/user-guide/data-integration/openflow/setup-openflow-spcs-create-rr#label-create-network-rules-and-external-access-integrations). What is specific to this connector is getting its source host into a rule that EAI references. The rule takes the source's host and port as a single value, such as `db.example.com:`. That's the host and port from the connector's connection URL, without the `jdbc:` scheme, the driver name, or the database path. BYOC deployments handle outbound connectivity in the cloud environment and don't use EAIs or network rules. #### Additional setup for key-pair authentication (BYOC only) Key-pair authentication is available only for BYOC deployments, and is not required for the default `SNOWFLAKE_MANAGED` authentication strategy. Skip this section unless you set the connector's **Snowflake Authentication Strategy** parameter to `KEY_PAIR`. 1. Create a Snowflake user with the type as [SERVICE](#label-user-type-property), create a role for it, and grant that role the same destination database and warehouse privileges you granted the execute-as role: ```sql CREATE USER TYPE=SERVICE COMMENT='Service user for automated access of Openflow'; CREATE ROLE ; GRANT ROLE TO USER ; GRANT USAGE ON DATABASE TO ROLE ; GRANT CREATE SCHEMA ON DATABASE TO ROLE ; GRANT USAGE, OPERATE ON WAREHOUSE TO ROLE ; ``` 2. Create a pair of secure keys (public and private). Store the private key for the user in a file to supply to the connector's configuration. Assign the public key to the Snowflake service user: ```sql ALTER USER SET RSA_PUBLIC_KEY = 'thekey'; ``` For more information, see [pair of keys](/user-guide/key-pair-auth). When using `KEY_PAIR`, you must also set the connector's **Snowflake Account Identifier** and **Snowflake Connection Strategy** parameters. Both are left blank or ignored under `SNOWFLAKE_MANAGED`. ## Gather these before you install You can stop and collect any of these later, but having them on hand first lets you install and configure the connector in one pass: - **The PostgreSQL JDBC driver `.jar`.** You supply the driver file itself, so download it beforehand. - **A JDBC connection URL** in the form `jdbc:postgresql://:/`. SSL is configured in the URL itself rather than as a separate field, by appending an `sslmode` parameter. - **A source database user** with the `REPLICATION` attribute and `SELECT` on every table you replicate, as described in [Source database setup](#source-database-setup). On AWS RDS and Aurora, grant the `rds_replication` role instead, because those services don't expose the native `REPLICATION` attribute. - **The source database user's password.** Both generations need it. - **A publication**, created as described in [](#label-postgres-connector-create-a-publication). You supply its name. Only tables in the publication are replicated: a table missing from it is skipped silently, even when it matches the tables you select for replication. - **Decisions on the settings that can't be changed later.** Destination schema naming, object identifier resolution (whether PostgreSQL names are stored case-sensitively or uppercased), and table storage format are fixed once the connector has applied its configuration and begun ingesting. Changing them afterwards requires a new connector instance and a fresh snapshot. ## Install the connector ### Choose your generation This connector is available in both gen 1 and gen 2.
If you're unsure, see [Openflow gen 1 and gen 2](/user-guide/data-integration/openflow/gen2/openflow-generations) for a full comparison. The catalog lists two entries with the same name, **PostgreSQL**. The gen 2 entry is the one marked with a **Gen 2** tag, and it also carries a **Preview** tag during public preview. The gen 1 entry has no tag. Install the connector from the Openflow connector catalog. To install the connector, do the following as a data engineer: 1. Navigate to the Openflow overview page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find the entry for the generation you chose and select **Install**. 3. Select the runtime to install the connector on. If you're prompted to authenticate, sign in with your Snowflake account credentials. What happens next depends on the generation you chose: - **Gen 2**: the setup wizard opens and collects the connector's configuration in one guided flow. Continue with Configure the connector below, which describes the values this connector needs. If you would rather configure the connector programmatically instead of using the wizard, see [Configure a gen 2 connector with SQL](/user-guide/data-integration/openflow/gen2/configure-connector-sql). - **Gen 1**: the Openflow canvas appears with the connector process group added to it. ## Configure the connector *Using gen 1? [Skip to Configure on the canvas.](#label-postgres-configure-gen1-canvas)* ### Configure with the setup wizard or SQL (gen 2) [CoCo](/user-guide/cortex-code/cortex-code) can help you make sure your prerequisites are in place. Try pasting this prompt into CoCo: > Please help me with the prerequisites for a gen 2 Openflow connector for PostgreSQL. Use skill @(serverSkill:openflow). Gen 2 references the source database password as a Snowflake secret of type `GENERIC_STRING` rather than taking the password inline. Create the secret in the same database and schema that holds your Openflow infrastructure objects (the runtime and connector), keeping infrastructure separate from the destination database where replicated data is persisted: ```sql CREATE SECRET .. TYPE = GENERIC_STRING SECRET_STRING = ''; GRANT READ ON SECRET .. TO ROLE ; ``` If the execute-as role doesn't already have `USAGE` on the infrastructure database and schema (for example, if you deviated from the recommended setup path), grant it: ```sql GRANT USAGE ON DATABASE TO ROLE ; GRANT USAGE ON SCHEMA . TO ROLE ; ``` With the secret in place, configure the connector with the [setup wizard](/user-guide/data-integration/openflow/gen2/setup-connector-wizard) or, for automation, by editing the connector's `config.json` with SQL and stage file operations; see [Configure a gen 2 connector with SQL](/user-guide/data-integration/openflow/gen2/configure-connector-sql). ### Gen 2 parameters The following table lists the gen 2 connector parameters, grouped by the wizard step where you configure them. The wizard's **Step Documentation** panel describes each property in full; this table gives the parameter name and its purpose so you can prepare before entering the wizard.
The gen 2 parameters are listed below, grouped by wizard step. The gen 1 parameter reference follows in the next section. *Using gen 2? [Skip to Run the flow.](#label-postgres-run-the-flow)* ### Configure on the canvas (gen 1) To configure the connector on the canvas, do the following as a data engineer: 1. Right-click on the imported process group and select **Parameters**. 2. Populate the required parameter values. For more information on the required parameter values, see the following sections: - [](#label-of-postgres-source-parameters): Used to establish a connection with PostgreSQL. - [](#label-of-postgres-destination-parameters): Used to establish a connection with Snowflake. - [](#label-of-postgres-ingestion-parameters): Used to specify the tables to replicate. Start with setting the parameters of the PostgreSQL Source Parameters context, then the PostgreSQL Destination Parameters context. Once this is done, you can enable the connector, and it should connect to both PostgreSQL and Snowflake and start running. However, it won't replicate any data until tables are explicitly added to its configuration. To configure specific tables for replication, edit the PostgreSQL Ingestion Parameters context. Shortly after you apply the changes to the Replication Parameters context, the configuration will be picked up by the connector, and the replication lifecycle will start for every table. To run multiple CDC connector instances on one runtime, see [](/user-guide/data-integration/openflow/connectors/cdc-runtime-sizing#run-multiple-connectors-on-one-runtime). ### PostgreSQL Source Parameters
### PostgreSQL Destination Parameters
### PostgreSQL Ingestion Parameters
## Replicate tables from a PostgreSQL replica server The connector can ingest data from a primary server, a hot standby replica (https://www.postgresql.org/docs/current/hot-standby.html), or a subscriber server using logical replication (https://www.postgresql.org/docs/current/logical-replication.html). Before configuring the connector to connect to a PostgreSQL replica, ensure that replication between primary and replica nodes works correctly. When investigating issues with missing data in the connector, first ensure that missing rows are present in the replica server used by the connector. Additional considerations when connecting to a standby replica:
- The PostgreSQL version of the server must be >= 16. Amazon Aurora is not supported because it doesn't offer logical decoding from read replicas (https://docs.aws.amazon.com/AmazonRDS/latest/AuroraUserGuide/AuroraPostgreSQL.Replication.Logical.html). - Only connecting to a hot standby replica is supported. Note that warm standby replicas can't accept connections from clients until they are promoted to a primary instance. - [The publication](#label-postgres-connector-create-a-publication) needed by the connector must be created on the primary server, not the standby server. The standby server is read-only and doesn't let you create a publication.
If you connect to a hot standby instance and see **Trying to create the replication slot '<replication slot>' timed out. If connecting to a standby instance, ensure there is some traffic on the primary PostgreSQL instance, otherwise the call to create a replication slot will never return.** error in the Openflow bulletin, or the **Read PostgreSQL CDC Stream** processor isn't starting, log in to the primary PostgreSQL instance and execute the following query: ```sqlsyntax SELECT pg_log_standby_snapshot(); ``` The error occurs when there are no data changes in the primary server. As such, the connector can stall while creating a replication slot on the replica server. This results from the replica server requiring information about running transactions from the primary server to be able to create a replication slot. Primary servers won't send the information while idle. The `pg_log_standby_snapshot()` function forces the primary server to send information about running transactions to the replica server. On PostgreSQL 17 and later, if you want the replication slot to survive a primary failover, the connector must connect to the primary rather than a standby. See [PostgreSQL 17+ failover slot support](/user-guide/data-integration/openflow/connectors/postgres/failover). ## Replicate a subset of columns in a table The following describes the gen 1 `Column Filter JSON` parameter. In gen 2, you select columns per table in the **Replication columns** step of the setup wizard; see [](#configure-with-the-setup-wizard-or-sql-gen-2) for that step. The connector can filter the data replicated per table to a subset of configured columns. Primary key columns are always included regardless of exclusions. To apply column filters, set the **Column Filter JSON** parameter in the Ingestion Parameters context to a JSON array of filter objects, one per table you want to filter. Columns can be included or excluded by name or by regular expression pattern. You can apply a single condition per table, or combine multiple conditions, with exclusions always taking precedence over inclusions. ## Syntax Each object in the array identifies a table and specifies which columns to include or exclude. ```javascript [ { "schema": "" | "schemaPattern": "", "table": "
Requirement Details
`Unique` The index must be unique so each row can be identified.
Covers all rows The index must cover all rows in the table. Partial indexes (those with a `WHERE` clause) aren't supported.
Non-deferrable The index can't be based on a deferrable unique constraint. Indexes created with `CREATE UNIQUE INDEX` are non-deferrable by default.
All columns `NOT NULL` Every column in the index must be defined as `NOT NULL`.
Plain columns only Expression indexes such as `LOWER(email)` aren't supported. Only plain column indexes are supported.
Gen 2 (recommended) Gen 1
**Management** SQL commands + setup wizard Runtime canvas UI
**Configuration** Versioned config files, CI/CD-friendly Canvas parameters
**Release status** Public Preview Generally Available
Parameter Wizard step Description
Source Database Connection URL Source The JDBC URL to the PostgreSQL source. It must start with `jdbc:postgresql://` and can include the SSL mode. For example: `jdbc:postgresql://db.example.com:5432/mydb?sslmode=require`.
Source Database Driver Source The PostgreSQL JDBC driver (https://jdbc.postgresql.org/) `.jar`, uploaded in the wizard.
Source Database User Source The source database user with the `REPLICATION` attribute and `SELECT` on replicated tables.
Source Database Password Source A Snowflake secret of type `GENERIC_STRING` holding the source user's password, with `READ` granted to the execute-as role.
Source Database Publication Name Source The publication you created in PostgreSQL. Only tables in the publication are replicated.
Configure Logical Keys Source Whether to use default primary-key detection or declare custom logical keys for tables without a usable primary key.
Included Source Table Pattern Replication table schema The schemas and tables to replicate, selected manually or matched by a regular expression.
Replication Columns Replication columns Which columns to include per table, and whether newly added columns are included automatically.
Snowflake Destination Database Destination details The database where replicated data is persisted. The execute-as role needs `USAGE` and `CREATE SCHEMA` on it.
Snowflake Warehouse Destination details The warehouse used for merge operations. Start with `XSMALL`; for many tables, a multi-cluster warehouse scales better than a larger size.
Destination Schema Strategy Destination details How destination schemas are named, to avoid collisions when consolidating more than one source database into a single Snowflake database. Includes presets using the source schema and database names. Fixed after first apply.
Object Identifier Resolution Destination details Whether source object names are stored case-sensitively (default) or uppercased (recommended). Fixed after first apply.
Oversized Value Strategy Destination details How values exceeding the 16 MB limit are handled. Defaults to **Set Null**.
Error Handling Strategy Destination details How invalid rows are handled. Defaults to **Log Errors and Continue**.
Table Storage Format Destination details Standard Snowflake tables or Iceberg tables. Fixed after first apply.
Iceberg Version Destination details When using Iceberg, the table version (2 or 3, default 3).
Merge Task Schedule CRON Tuning CRON expression controlling when journal data is merged into destination tables, which is when warehouse cost accrues.
Concurrent Snapshot Queries Tuning How many tables to snapshot concurrently (default 2). Each holds a source database connection.
Ingestion Type Migration Whether new tables get a full snapshot before switching to CDC (default) or go straight to incremental.
Replication Slot Name Migration Optional. If blank, the connector creates its own slot. An active slot retains WAL on the source until the connector advances it; deleting a connector doesn't drop its slot.
Parameter Description
PostgreSQL Connection URL The full JDBC URL to the source database. Example: `jdbc:postgresql://example.com:5432/public` If you are connecting to PostgreSQL replica server, see [](/user-guide/data-integration/openflow/connectors/postgres/about#replicate-tables-from-a-postgresql-replica-server).
PostgreSQL JDBC Driver The path to the PostgreSQL JDBC driver jar (https://jdbc.postgresql.org/). Download the jar from its website, then select the **Reference asset** checkbox to upload and attach it.
PostgreSQL Username The username for the connector.
PostgreSQL Password The password for the connector.
Publication Name The name of the publication you created earlier.
Replication Slot Name Optional. When no value is provided, the connector will create a new, uniquely-named slot. When given a value, the connector will use the existing slot, or create a new one with the provided name. Changing the value for a running connector will restart reading the incremental change data capture (CDC) stream from the updated slot's position.
Parameter Description Required
Destination Database The database where data is persisted. It must already exist in Snowflake and the connector's role must have `USAGE` and `CREATE SCHEMA` on it. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. Yes
Destination Schema Pattern A pattern for the names of destination schemas where data is persisted. The connector creates the schemas if they don't exist. You can customize the pattern per ingested table using these optional variables: - `${source.database.name}`: a source table's database. - `${source.schema.name}`: a source table's schema. - `${source.table.name}`: a source table's name. For example, for a table with the qualified name `source_db.tenant_a.data`, the pattern `prefix_${source.database.name}_${source.schema.name}` evaluates to `prefix_source_db_tenant_a`. To ingest all tables into a single schema, provide a schema name without any variables, like `destination_schema`. Don't change this setting after the connector has begun ingesting data. Changing this setting after ingestion has begun breaks the existing ingestion. If you must change this setting, create a new connector instance. Yes
Snowflake Authentication Strategy When using: - **Snowflake Openflow Deployment** or **BYOC**: Use SNOWFLAKE_MANAGED. This token is managed automatically by Snowflake. BYOC deployments must have previously configured [execute-as roles](#label-deployment-byoc-setup-runtime-role) to use SNOWFLAKE_MANAGED. - **BYOC**: Alternatively, BYOC can use KEY_PAIR as the value for the authentication strategy. Yes
Snowflake Account Identifier When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Snowflake account name formatted as [organization-name]-[account-name]. Yes
Snowflake Connection Strategy When using KEY_PAIR, specify the strategy for connecting to Snowflake: - **STANDARD** (default): Connect using standard public routing to Snowflake services. - **PRIVATE_CONNECTIVITY**: Connect using private addresses associated with the supporting cloud platform such as AWS PrivateLink. Required for BYOC with KEY_PAIR only, otherwise ignored.
Snowflake Private Key When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank.
**KEY_PAIR**: Must be the RSA private key used for authentication.
The RSA key must be formatted according to PKCS8 standards and have standard PEM headers and footers. Note that either a Snowflake Private Key File or a Snowflake Private Key must be defined.
No
Snowflake Private Key File When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: The private key file must be blank. - **KEY_PAIR**: Upload the file that contains the RSA private key used for authentication to Snowflake, formatted according to PKCS8 standards and including standard PEM headers and footers. The header line begins with `-----BEGIN PRIVATE`. To upload the private key file, select the **Reference asset** checkbox. No
Snowflake Private Key Password When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the password associated with the Snowflake Private Key File. No
Snowflake Role When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Use the runtime's execute-as role (or a child role granted to it). You can find your execute-as role in the Openflow UI by navigating to **View Details** for your runtime. - **KEY_PAIR**: Use a valid role configured for your service user. Yes
Snowflake Username When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the username used to connect to the Snowflake instance. Yes
Oversized Value Strategy Determines how the connector handles values that exceed its internal size limits (16 MB) during replication. Possible values are:
- **Fail Table** (default): The table is marked as permanently failed, and replication stops for that table. - **Set Null**: The value is replaced with `NULL` in the destination table. Use this to prevent table failures when it is acceptable to lose data in tables beyond the oversized value.
No
Error Handling Strategy Determines how the connector handles invalid rows that Snowflake rejects during ingestion. Possible values are:
- **Fail Table** (default): The table is marked as failed on the first invalid row, and replication stops for that table. - **Log Errors and Continue** : The connector keeps replicating the valid rows and records each rejected row in the table's error table.
No
Table Storage Format Standard Snowflake tables or Iceberg tables. Defaults to **STANDARD**. Don't change after the connector starts. Yes
Iceberg Version The Iceberg table version, 2 or 3 (default 3). Ignored unless Table Storage Format is **ICEBERG**. Don't change this value after ingestion begins. No
Snowflake Warehouse Snowflake warehouse used to run merge queries. Start with `XSMALL`; for many tables, a multi-cluster warehouse scales better than a larger size. Yes
Parameter Description
Included Table Names A comma-separated list of table paths, including their schemas. Example: `public.my_table, other_schema.other_table`. Select tables either by name or by Regex. If you use both, all matching tables from either option will be included. Sub-partition tables are always excluded from ingestion. See [](#label-postgres-connector-replicate-partitioned-table) for more information.
Included Table Regex A regular expression to match against table paths. Every path matching the expression will be replicated, and new tables matching the pattern that get created later will also be included automatically. Example: `public\.auto_.*` Select tables either by name or by Regex. If you use both, all matching tables from either option will be included. Sub-partition tables are always excluded from ingestion. See [](#label-postgres-connector-replicate-partitioned-table) for more information.
Column Filter JSON Optional. A JSON array of filter objects specifying which columns to include or exclude per table. For syntax details and examples, see [](#label-postgres-connector-replication-subset-of-columns).
Table Key Configuration Service Optional. A `JsonTableKeyConfigService` controller service that supplies a user-declared logical key for one or more tables. The service exposes a **Table Key Configuration JSON** property where you define the key mappings. When configured, the logical key takes the highest priority and overrides any primary key or unique index that the connector would otherwise auto-detect. For more information, see [](#label-postgres-logical-key).
Merge Task Schedule CRON A CRON expression defining when the connector merges journal data into destination tables, which is when warehouse cost accrues. The **Merge Journal to Destination** processor performs the merge on this schedule. With no new changes waiting, no merge runs and the warehouse is free to auto-suspend. Set it to `* * * * * ?` for continuous merges (lowest latency, highest cost), or schedule merges to limit warehouse run time. The connector evaluates the schedule in the UTC time zone. For example:
- The string `* 0 * * * ?` indicates that you want to schedule merges at the full hour for one minute. - The string `* 20 14 ? * MON-FRI` indicates that you want to schedule merges at 2:20 PM every Monday through Friday.
For additional information and examples, see the cron triggers tutorial in the Quartz Documentation (https://www.quartz-scheduler.org/documentation/quartz-2.5.x/tutorials/crontrigger.html).
Object Identifier Resolution Specifies how source object identifiers such as the names of schemas, tables, and columns are stored and queried in Snowflake. This setting specifies that you must use double quotes in SQL queries. Option 1: Default, case-sensitive. For backwards compatibility. - **Transformation**: Case is preserved. For example, `My_Table` remains `My_Table`. - **Queries**: SQL queries must use double quotes to match the exact case for database objects. For example, `SELECT * FROM "My_Table";`. Snowflake recommends using this option if you must preserve source casing for legacy or compatibility reasons. For example, if the source database includes table names that differ in case only–such as `MY_TABLE` and `my_table`–that would result in a name collision when using when using case-insensitive comparisons. Option 2: Recommended, case-insensitive - **Transformation**: All identifiers are converted to uppercase. For example, `My_Table` becomes `MY_TABLE`. - **Queries**: SQL queries are case-insensitive and don't require SQL double quotes. For example, `SELECT * FROM my_table;` returns the same results as `SELECT * FROM MY_TABLE;`. Snowflake recommends using this option if database objects are not expected to have mixed case names. Do not change this setting after the connector has begun ingesting data. Changing this setting after ingestion has begun breaks the existing ingestion. If you must change this setting, create a new connector instance.
Concurrent Snapshot Queries Maximum number of concurrent queries to the source database to run in the Snapshot flow. Increasing this can speed up snapshotting large numbers of tables, but will also increase the load on the source database.
" | "tablePattern": "", "included": ["", ""], "excluded": ["", ""], "includedPattern": "", "excludedPattern": "" } ] ``` The following rules apply: - Use `schema` and `table` for exact name matching, or `schemaPattern` and `tablePattern` for regex matching. You can't use both a field and its pattern variant in the same object (for example, `schema` and `schemaPattern` can't both appear). - At least one of `included`, `excluded`, `includedPattern`, or `excludedPattern` must be provided. - When both included and excluded filters are specified, exclusions take precedence. - When multiple filters match the same table, the last matching filter is used, with exact matches taking precedence over pattern-based filters. - The value can be an array of objects to apply different filters to different tables. ## Examples Include specific columns by name: ```javascript [ { "schema": "public", "table": "orders", "included": ["account_id", "status", "created_at"] } ] ``` Exclude specific columns by name: ```javascript [ { "schema": "public", "table": "orders", "excluded": ["internal_note", "debug_flag"] } ] ``` Combine an include pattern with a specific exclusion (for example, include all email columns except `admin_email`): ```javascript [ { "schema": "public", "table": "contacts", "includedPattern": ".*_email", "excluded": ["admin_email"] } ] ``` Mix a schema pattern with an exact table name to apply a filter across schemas: ```javascript [ { "schemaPattern": "data_.*", "table": "customers", "excluded": ["internal_note"] } ] ``` Pass multiple filter objects to apply different rules to different tables: ```javascript [ {"schema": "public", "table": "orders", "included": ["account_id", "status"]}, {"schema": "public", "table": "customers", "excludedPattern": ".*_internal"} ] ``` ### Including and excluding the same column Removing a column from a table's replicated set (by excluding it or by removing it from the included list) has the same effect on the destination as dropping the column at the source: the connector soft-deletes the column on the destination by renaming it with a suffix (by default, `__SNOWFLAKE_DELETED`). If you then add the column back to the replicated set and later remove it a second time, replication for the affected table fails because the soft-deleted column name is already taken. To recover, restart replication for the affected table. ## Specify a logical key for a table The connector requires a replication key for every table it replicates. By default, the connector picks the replication key automatically: first a primary key, then a qualifying unique index. A *logical key* is a user-declared replacement for the auto-detected key. Configure a logical key when: - A table has no primary key and no qualifying unique index, but one or more columns are unique in the data. - A specific column or set of columns should be used as the replication key, regardless of what the connector would auto-detect (for example, to override a synthetic primary key). A logical key takes the highest priority. When the connector finds a logical key for a table, it uses that key and ignores any primary key or unique index on the table. ### REPLICA IDENTITY requirement When the logical key columns don't match the table's primary key columns exactly (or the table has no primary key), PostgreSQL `DELETE` events in the WAL don't carry the logical-key column values. The connector can't identify which destination row to delete. Before you configure a logical key and enable replication for the table, set: ```sqlsyntax ALTER TABLE . REPLICA IDENTITY FULL; ``` If the table already has `REPLICA IDENTITY USING INDEX` and the logical key columns exactly match that index, setting `FULL` isn't required. ### JSON syntax The **Table Key Configuration JSON** value is a JSON array. Each entry maps one table to its logical key columns: ```json [ { "schema": "", "table": "
", "logicalKey": ["", ""] } ] ``` The fields are:
The following rules apply: - `schema`, `table`, and `logicalKey` column matching is **case-sensitive**. Use the exact names as reported by PostgreSQL. - An entry whose `schema` and `table` don't match any replicated table is silently ignored. ### Logical key configuration examples A single-column logical key on a table without a primary key: ```json [ { "schema": "sales", "table": "audit_log", "logicalKey": ["event_id"] } ] ``` A composite logical key: ```json [ { "schema": "sales", "table": "order_lines", "logicalKey": ["order_id", "line_item_id"] } ] ``` Logical keys for several tables in one JSON value: ```json [ { "schema": "sales", "table": "audit_log", "logicalKey": ["event_id"] }, { "schema": "sales", "table": "order_lines", "logicalKey": ["order_id", "line_item_id"] } ] ``` ### Restrictions The connector rejects the configuration when any of the following is true: - `logicalKey` is missing, empty, or not an array. - `logicalKey` contains duplicate column names. - `logicalKey` contains a nullable column. Logical key columns must be defined as `NOT NULL` to reliably identify rows. - `logicalKey` contains the PostgreSQL system column `ctid`. `ctid` isn't a reliable replication key because it's a physical row pointer that can change when a row is vacuumed or updated. - `logicalKey` contains a column name that doesn't exist in the source table. When the configuration is rejected, the connector either fails to enable the controller service (for structural issues detected at enablement time) or holds the table in the `NEW` state (for issues detected when the table is initialized). After you fix the configuration, replication for the table resumes without resetting state. ### Warnings logged for risky configurations The connector accepts the following configurations but logs a warning at table initialization. When choosing logical-key columns, prefer columns with high cardinality and, where possible, monotonically increasing values. Low-cardinality or non-monotonic keys can degrade snapshot performance. - A logical-key column is a large-object type (`bytea`). Using large objects as keys severely degrades MERGE performance. - A logical-key column is a floating-point type (`float4`, `float8`, `money`). Floating-point comparisons can produce inconsistent results because of precision differences. - A logical-key column is a semi-structured type (`json`, `jsonb`). Semi-structured values may produce non-deterministic equality comparisons. - The composite logical key includes more than five columns. Long composite keys often indicate a design issue and might degrade MERGE performance. - The logical key overrides an existing primary key on the table. Verify that the replacement key is intentional: the connector no longer uses the primary key for MERGE operations. If you observe data divergence after any of these warnings, run a periodic full reload to reconcile the destination with the source. ### Schema changes that affect a logical key Logical keys reference column names. The connector doesn't follow renames or drops of those columns: - If a logical-key column is dropped on the source, replication for the affected table fails. The table is marked `FAILED`. For more information, see [Restart table replication](/user-guide/data-integration/openflow/connectors/postgres/maintenance#label-of-postgres-restart-table-replication). - If a logical-key column is renamed on the source, the configuration still references the old name and replication fails. Update the JSON to use the new name and restart table replication. ## Run the flow ### Gen 2 After you apply your configuration in the wizard, the connector's status moves to **Upgrading** and then to **Stopped** once upgrading finishes. Start it from the **Installed Connectors** tab: open the connector's menu and select **Start**. If the connector is still in **Draft** when you reach this step, its configuration hasn't been applied. Open the setup wizard and select **Apply** so your changes take effect before you start. After starting, open the connector's observability dashboard to confirm data is moving and there are no errors. To start, stop, or otherwise manage a gen 2 connector programmatically, see [Manage the gen 2 Openflow connector lifecycle](/user-guide/data-integration/openflow/gen2/manage-connector-lifecycle). ### Gen 1 1. Right-click on the canvas and select **Enable all Controller Services**. 2. Right-click on the imported process group and select **Start**. The connector starts the data ingestion. ## Set up alerts Snowflake recommends setting up alerts so that you're notified of ingestion errors or stalled replication without having to check the connector manually. This applies to both gen 1 and gen 2 connectors. Openflow writes telemetry, including logs and metrics, to an event table. Build an alert on that telemetry with a scheduled query: see [Monitor Openflow using telemetry data](/user-guide/data-integration/openflow/monitor) for the available telemetry and example queries, and [Setting up alerts based on data in Snowflake](/user-guide/alerts) for how to create an alert from a query. --- title: Set up the Openflow Connector for SharePoint source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/sharepoint/setup.md section: Loading & Unloading Data --- # Set up the Openflow Connector for SharePoint This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) This topic describes the steps to set up the Openflow Connector for SharePoint. ## Prerequisites 1. Ensure that you have reviewed [About Openflow Connector for SharePoint](/user-guide/data-integration/openflow/connectors/sharepoint/about). 2. Ensure that you have [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) or [Set up Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/setup-openflow-spcs). 3. If using %ofsfspcs-plural%, ensure that you've reviewed [configuring required domains](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list) and have granted access to the required domains for the [](#label-openflow-domains-used-by-openflow-connectors-sharepoint) connector. ## Set up access to your SharePoint site As an Azure or Office 365 account administrator, perform the following actions: 1. Ensure that you have a Microsoft Graph (https://learn.microsoft.com/en-us/graph/overview) application registered and that it is configured with the following application permissions (https://learn.microsoft.com/en-us/graph/permissions-overview?tabs=http#application-permissions) based on your requirements:
**For Microsoft SharePoint (Cortex Search, document ACLs) and Microsoft SharePoint (Simple Ingest, document ACLs):** -
`Sites.Selected`: Limits access to only specified sites.
For more information, see Sites.Selected (https://learn.microsoft.com/en-us/graph/permissions-reference#sitesselected).
-
`GroupMember.Read.All`: Used for resolving SharePoint group permissions.
For more information, see GroupMember.Read.All (https://learn.microsoft.com/en-us/graph/permissions-reference#groupmemberreadall).
-
`User.ReadBasic.All`: Used for resolving Microsoft 365 user emails.
For more information, see User.ReadBasic.All (https://learn.microsoft.com/en-us/graph/permissions-reference#userreadbasicall).
**For Microsoft SharePoint (Cortex Search, no document ACLs) and Microsoft SharePoint (Simple Ingest, no document ACLs):** -
`Sites.Selected`: Limits access to only specified sites.
For more information, see Sites.Selected (https://learn.microsoft.com/en-us/graph/permissions-reference#sitesselected).
1. Grant the `fullcontrol` role to the application in the selected sites. This role handles folder access changes during CDC ingestion. Grant it using the Grant-PnPAzureADAppSitePermission (https://github.com/pnp/powershell/blob/dev/documentation/Grant-PnPAzureADAppSitePermission.md) cmdlet, or by calling the GraphAPI permission endpoint (https://learn.microsoft.com/en-us/graph/api/site-post-permissions), e.g. using `curl`. For more information, see Roles (https://learn.microsoft.com/en-us/graph/permissions-selected-overview?tabs=http#roles). If you cannot grant the `fullcontrol` role, grant the narrower `read` role to the application instead. However, if access to a folder in the ingested site changes, the connector may enter an irreparable state and will require a full re-ingestion of data. Snowflake recommends granting the `fullcontrol` role to fully mitigate this issue. 2. Configure application credentials based on your use case: **For Microsoft SharePoint (Cortex Search, document ACLs) and Microsoft SharePoint (Simple Ingest, document ACLs):** - Add a new certificate or ensure that you have access to the existing certificate file and its private key. For more information, see Option 1: Add a certificate (https://learn.microsoft.com/en-us/graph/auth-register-app-v2#option-1-add-a-certificate). -
Create a new client secret and record the secret's value.
For more information, see Option 2: Add a client secret (https://learn.microsoft.com/en-us/graph/auth-register-app-v2#option-2-add-a-client-secret).
**For Microsoft SharePoint (Cortex Search, no document ACLs) and Microsoft SharePoint (Simple Ingest, no document ACLs):** -
Create a new client secret and record the secret's value.
For more information, see Option 2: Add a client secret (https://learn.microsoft.com/en-us/graph/auth-register-app-v2#option-2-add-a-client-secret).
3. Record the following information from your Microsoft Graph application: -
The client ID of your application.
For more information, see Application ID (client ID) (https://learn.microsoft.com/en-us/azure/healthcare-apis/register-application#application-id-client-id).
-
The tenant ID of your application.
For more information, see Find your Microsoft 365 tenant ID (https://learn.microsoft.com/en-us/sharepoint/find-your-office-365-tenant-id).
- The site URL of the Microsoft 365 SharePoint site with the files or folders that you want to ingest into Snowflake; for example, `https://yourtenant.sharepoint.com/sites/YourSite`. ## Set up your Snowflake account As a Snowflake account administrator, perform the following tasks manually or by using the script included below: 1. Create a new role or use an existing role and grant the [](#label-database-privileges). 2. Create a new Snowflake service user with the type as [SERVICE](#label-user-type-property). 3. Grant the Snowflake service user the role you created in the previous steps. 4. Configure with [key-pair auth](/user-guide/key-pair-auth) for the Snowflake SERVICE user from step 2. 5. Snowflake strongly recommends this step. Configure a secrets manager supported by Openflow, for example, AWS, Azure, and Hashicorp, and store the public and private keys in the secret store. If for any reason, you do not wish to use a secrets manager, then you are responsible for safeguarding the public key and private key files used for key-pair authentication according to the security policies of your organization. 1. Once the secrets manager is configured, determine how you will authenticate to it. On AWS, it's recommended that you the EC2 instance role associated with Openflow as this way no other secrets have to be persisted. 2. In Openflow, configure a Parameter Provider associated with this Secrets Manager, from the hamburger menu in the upper right. Navigate to **Controller Settings** %raa% **Parameter Provider** and then fetch your parameter values. 3. At this point all credentials can be referenced with the associated parameter paths and no sensitive values need to be persisted within Openflow. 6. If any other Snowflake users require access to the raw ingested documents and tables ingested by the connector (for example, for custom processing in Snowflake), then grant those users the role created in step 1. 7. Designate a warehouse for the connector to use. Start with the smallest warehouse size, then experiment with size depending on the number of tables being replicated, and the amount of data transferred. Large table numbers typically scale better with [multi-cluster warehouses](/user-guide/warehouses-multicluster), rather than larger warehouse sizes. ### Example setup
```sql --The following script assumes you'll need to create all required roles, users, and objects. --However, you may want to reuse some that are already in existence. --Create a Snowflake service user to manage the connector USE ROLE USERADMIN; CREATE USER TYPE=SERVICE COMMENT='Service user for Openflow automation'; --Create a pair of secure keys (public and private). For more information, see --key-pair authentication. Store the private key for the user in a file to supply --to the connector’s configuration. Assign the public key to the Snowflake service user: ALTER USER SET RSA_PUBLIC_KEY = ''; --Create a role to manage the connector and the associated data and --grant it to that user USE ROLE SECURITYADMIN; CREATE ROLE ; GRANT ROLE TO USER ; --The following block is for USE CASE 2 (Cortex connect) ONLY --Create a role for read access to the cortex search service created by this connector. --This role should be granted to any role that will use the service CREATE ROLE ; GRANT ROLE TO ROLE ; --Create the database the data will be stored in and grant usage to the roles created USE ROLE ACCOUNTADMIN; --use whatever role you want to own your DB CREATE DATABASE IF NOT EXISTS ; GRANT USAGE ON DATABASE TO ROLE ; --Create the schema the data will be stored in and grant the necessary privileges --on that schema to the connector admin role: USE DATABASE ; CREATE SCHEMA IF NOT EXISTS ; GRANT USAGE ON SCHEMA TO ROLE ; GRANT CREATE TABLE, CREATE DYNAMIC TABLE, CREATE STAGE, CREATE SEQUENCE, CREATE CORTEX SEARCH SERVICE ON SCHEMA TO ROLE ; --The following block is for CASE 2 (Cortex connect) ONLY --Grant the Cortex read-only role access to the database and schema GRANT USAGE ON DATABASE TO ROLE ; GRANT USAGE ON SCHEMA TO ROLE ; --Create the warehouse this connector will use if it doesn't already exist. Grant the --appropriate privileges to the connector admin role. Adjust the size according to your needs. CREATE WAREHOUSE WITH WAREHOUSE_SIZE = 'MEDIUM' AUTO_SUSPEND = 300 AUTO_RESUME = TRUE; GRANT USAGE, OPERATE ON WAREHOUSE TO ROLE ; ```
## Use case 1: Ingest files only Use a connector to: - Ingest and continuously update Sharepoint files for custom processing within Snowflake - Optionally ingest file permissions (ACL connectors) to persist access controls downstream ### Set up the connector As a data engineer, perform the following tasks to configure the connector: #### Install the connector There are multiple variants of the SharePoint connector. Choose the variant that best fits your use case as described in [](#label-sharepoint-overview-use-cases). To install the connector, do the following as a data engineer: 1. Navigate to the Openflow overview page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find the connector and select **Install**. 3. In the **Select runtime** dialog, select your runtime from the **Available runtimes** drop-down list and click **Install**. Before you install the connector, ensure that you have created a database and schema in Snowflake for the connector to store ingested data. 4. Authenticate to the deployment with your Snowflake account credentials and select **Allow** when prompted to allow the runtime application to access your Snowflake account. The connector installation process takes a few minutes to complete. 5. Authenticate to the runtime with your Snowflake account credentials. The Openflow canvas appears with the connector process group added to it. #### Configure the connector 1. Populate the process group parameters 1. Right-click on the imported process group and select **Parameters**. 2. Enter the required parameter values as described in [Sharepoint Ingestion Parameters](#sharepoint-ingestion-parameters), [Sharepoint Destination Parameters](#sharepoint-destination-parameters) and [Sharepoint Source Parameters](#sharepoint-source-parameters). ##### Sharepoint Source Parameters **For all connectors:**
**For ACL connectors only:**
##### Sharepoint Destination Parameters
##### Sharepoint Ingestion Parameters **For all connectors:**
**For ACL connectors only:**
1. Run the flow. 1. Start the process group. The flow will create all required objects inside of Snowflake. 2. Right click on the imported process group and select **Start**. ## Use case 2: Ingest files and perform processing with Cortex Use the predefined flow definition to: - Create AI assistants for documents within your organization's SharePoint site - Enable your AI assistants to adhere to access controls specified in your organization's SharePoint site ### Set up the connector As a data engineer, perform the following tasks to configure the connector: #### Install the connector 1. Create a database and schema in Snowflake for the connector to store ingested data. Grant required [](#label-database-privileges) to the role created in the first step. Substitute the role placeholder with the actual value and use the following SQL commands: ```sql CREATE DATABASE DESTINATION_DB; CREATE SCHEMA DESTINATION_DB.DESTINATION_SCHEMA; GRANT USAGE ON DATABASE DESTINATION_DB TO ROLE ; GRANT USAGE ON SCHEMA DESTINATION_DB.DESTINATION_SCHEMA TO ROLE ; GRANT CREATE TABLE ON SCHEMA DESTINATION_DB.DESTINATION_SCHEMA TO ROLE ; ``` To install the connector, do the following as a data engineer: 1. Navigate to the Openflow overview page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find the connector and select **Install**. 3. In the **Select runtime** dialog, select your runtime from the **Available runtimes** drop-down list and click **Install**. Before you install the connector, ensure that you have created a database and schema in Snowflake for the connector to store ingested data. 4. Authenticate to the deployment with your Snowflake account credentials and select **Allow** when prompted to allow the runtime application to access your Snowflake account. The connector installation process takes a few minutes to complete. 5. Authenticate to the runtime with your Snowflake account credentials. The Openflow canvas appears with the connector process group added to it. #### Configure the connector 1. Populate the process group parameters 1. Right click on the imported process group and select **Parameters**. 2. Enter the required parameter values as described in [Sharepoint Cortex Connect Source Parameters](#sharepoint-cortex-connect-source-parameters), [Sharepoint Cortex Connect Destination Parameters](#sharepoint-cortex-connect-destination-parameters) and [Sharepoint Cortex Connect Ingestion Parameters](#sharepoint-cortex-connect-ingestion-parameters). ##### Sharepoint Cortex Connect Source Parameters **For all connectors:**
**For ACL connectors only:**
##### Sharepoint Cortex Connect Destination Parameters
##### Sharepoint Cortex Connect Ingestion Parameters **For all connectors:**
**For ACL connectors only:**
1. Right-click on the plane and select **Enable all Controller Services**. 2. Right-click on the imported process group and select **Start**. The connector starts the data ingestion. 3. [Query the Cortex Search service](#query-the-cortex-search-service). ## Use case 3: Customise the connector definition Customize the connector definition to perform custom processing on ingested files. ### Set up the connector As a data engineer, perform the following tasks to configure the connector: #### Install the connector To install the connector, do the following as a data engineer: 1. Navigate to the Openflow overview page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find the connector and select **Install**. 3. In the **Select runtime** dialog, select your runtime from the **Available runtimes** drop-down list and click **Install**. Before you install the connector, ensure that you have created a database and schema in Snowflake for the connector to store ingested data. 4. Authenticate to the deployment with your Snowflake account credentials and select **Allow** when prompted to allow the runtime application to access your Snowflake account. The connector installation process takes a few minutes to complete. 5. Authenticate to the runtime with your Snowflake account credentials. The Openflow canvas appears with the connector process group added to it. #### Configure the connector 1. Customize the connector definition. 1. Remove the following process groups: - Check If Duplicate Content - Snowflake Stage and Parse PDF - Update Snowflake Cortex - (Optional) Process Microsoft365 Groups 2. Attach any custom processing to the output of the `Process SharePoint Metadata` process group. Each flow file represents a single SharePoint file change. 2. Populate the process group parameters. Follow the same process as for the use case 1. Note that after modifying the connector definition, not all parameters might be required. 3. Run the flow. 1. Start the process group. The flow will create all required objects inside of Snowflake. 2. Right click on the imported process group and select **Start**. 4. [Query the Cortex Search service](#query-the-cortex-search-service). ## Enabling Sharepoint site groups ### Microsoft Graph application for site groups In addition to the steps specified in [](#label-openflow-sharepoint-setup-access), do the following: 1. Add Sites.Selected (https://learn.microsoft.com/en-us/graph/permissions-reference#sitesselected) SharePoint permission. You should see *Sites.Selected* in both Microsoft Graph and SharePoint permissions. 2. Generate a key pair (https://learn.microsoft.com/en-us/entra/identity-platform/howto-create-self-signed-certificate). Alternatively, you can create a self-signed certificate with *openssl* by running the following command: ```bash openssl req -x509 -nodes -newkey rsa:2048 -keyout key.pem -out cert.pem -days 365 ``` The command above doesn't encrypt the generated private key. Remove the *-nodes* argument if you want to generate an encrypted key. 3. Attach the certificate (https://learn.microsoft.com/en-us/graph/applications-how-to-add-certificate?tabs=http) to the Microsoft Graph application. ## Query the Cortex Search service You can use the [Cortex Search](/user-guide/snowflake-cortex/cortex-search/cortex-search-overview) service to build chat and search applications to chat with or query your documents in SharePoint. After you install and configure the connector and it begins ingesting content from Sharepoint, you can query the Cortex Search service. For more information about using Cortex Search, see [Query a Cortex Search service](/user-guide/snowflake-cortex/cortex-search/query-cortex-search-service). **Filter responses** To restrict responses from the Cortex Search service to documents that a specific user has access to in SharePoint, you can specify a filter containing the user ID or email address of the user when you query Cortex Search. For example, `filter.@contains.user_ids` or `filter.@contains.user_emails`. The name of the Cortex Search service created by the connector is `search_service` in the schema `Cortex`. Run the following SQL code in a SQL worksheet to query the Cortex Search service with files ingested from your SharePoint site. Replace the following: - application_instance_name: Name of your database and connector application instance. - user_emailID: Email ID of the user who you want to filter the responses for. - your_question: The question that you want to get responses for. - number_of_results: Maximum number of results to return in the response. The maximum value is 1000 and the default value is 10. ```sql SELECT PARSE_JSON( SNOWFLAKE.CORTEX.SEARCH_PREVIEW( '.cortex.search_service', '{ "query": "", "columns": ["chunk", "web_url"], "filter": {"@contains": {"user_emails": ""} }, "limit": }' ) )['results'] AS results ``` Here's a complete list of values that you can enter for `columns`: **For all connectors:**
**For ACL connectors only:**
**Example: Query an AI assistant for human resources (HR) information** You can use Cortex Search to query an AI assistant for employees to chat with the latest versions of HR information, such as onboarding, code of conduct, team processes, and organization policies. Using response filters, you can also allow HR team members to query employee contracts while adhering to access controls configured in SharePoint.
Run the following in a [SQL worksheet](#label-snowsight-worksheets-create-file) to query the Cortex Search service with files ingested from SharePoint. Select the database as your application instance name and schema as **Cortex**. Replace the following: - application_instance_name: Name of your database and connector application instance. - user_emailID: Email ID of the user who you want to filter the responses for. ```sql SELECT PARSE_JSON( SNOWFLAKE.CORTEX.SEARCH_PREVIEW( '.cortex.search_service', '{ "query": "What is my vacation carry over policy?", "columns": ["chunk", "web_url"], "filter": {"@contains": {"user_emails": ""} }, "limit": 1 }' ) )['results'] AS results ```
**Python:** Run the following code in a [Python worksheet](#label-snowsight-worksheets-create) to query the Cortex Search service with files ingested from SharePoint. Ensure that you add the `snowflake.core` package to your database. Replace the following: - application_instance_name: Name of your database and connector application instance. - user_emailID: Email ID of the user who you want to filter the responses for. ```python from snowflake.snowpark import Session from snowflake.core import Root def main(session: snowpark.Session): root = Root(session) # fetch service my_service = (root .databases[""] .schemas["cortex"] .cortex_search_services["search_service"] ) # query service resp = my_service.search( query="What is my vacation carry over policy?", columns = ["chunk", "web_url"], filter = {"@contains": {"user_emails": ""} }, limit=1 ) return (resp.to_json()) ``` **REST API:** Execute the following code in a command-line interface to query the Cortex Search service with files ingested from your SharePoint. You will need to authentication through key pair authentication and OAuth to access the Snowflake REST APIs. For more information, see [](#label-cortex-search-query-syntax-rest) and [Authenticating Snowflake REST APIs with Snowflake](/developer-guide/snowflake-rest-api/authentication). Replace the following: - application_instance_name: Name of your database and connector application instance. - account_url: Your Snowflake account URL. For instructions on finding your account URL, see [](#label-account-name-find). ```bash curl --location "https:///api/v2/databases//schemas/cortex/cortex-search-services/search_service" \ --header 'Content-Type: application/json' \ --header 'Accept: application/json' \ --header "Authorization: Bearer " \ --data '{ "query": "What is my vacation carry over policy?", "columns": ["chunk", "web_url"], "limit": 1 }' ``` Sample response: ```text { "results" : [ { "web_url" : "https://.sharepoint.com/sites//", "chunk" : "Answer to the question asked." } ] } ``` ## Finding files in stage Files stored in the stage may have unreadable names. To find specific files, use the metadata tables as your source of truth. These tables contain the mapping between file names and their corresponding file IDs in the stage. For Cortex-enabled setups, use the following query to find files: ```sql SELECT DISTINCT METADATA:id FROM DOCS_CHUNKS WHERE METADATA:fullName LIKE '%%'; ``` For non-Cortex setups, use the following query: ```sql SELECT FILE_ID FROM DOC_METADATA WHERE FILE_NAME = ''; ``` Replace `` with the name or partial name of the file you're looking for. The files in the stage start with the ID returned from these queries. --- title: Set up the Openflow Connector for Shopify source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/shopify/setup.md section: Loading & Unloading Data --- # Set up the %shopifyof% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About the Openflow Connector for Shopify](/user-guide/data-integration/openflow/connectors/shopify/about) - [Object definition overrides for the Openflow Connector for Shopify](/user-guide/data-integration/openflow/connectors/shopify/object-definitions) - [Maintain the Openflow Connector for Shopify](/user-guide/data-integration/openflow/connectors/shopify/maintain) - [Troubleshoot the Openflow Connector for Shopify](/user-guide/data-integration/openflow/connectors/shopify/troubleshoot) This topic describes the steps to set up the %shopifyof%. ## Prerequisites 1. Review [About the Openflow Connector for Shopify](/user-guide/data-integration/openflow/connectors/shopify/about). 2. Set up your runtime deployment. - [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) - [Set up Openflow - Snowflake Deployment - Task overview](/user-guide/data-integration/openflow/setup-openflow-spcs) 3. If you're using %ofsfspcs-plural%, ensure that you have reviewed [the required domain configuration](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list) and have granted access to the [domains](#label-shopify-req-domains) required by the connector. 4. Ensure you have access to the Openflow admin role or a similar role you use to manage Openflow. 5. If you're creating a Snowflake service user to manage the connector, set up key pair authentication. For more information, see [key pair authentication](/user-guide/key-pair-auth). ## Required endpoints The following endpoints are required for the connector to function: - `.myshopify.com:443` (for example, `mystore.myshopify.com:443`): Shopify Admin GraphQL API - `storage.googleapis.com:443`: Shopify bulk-operation result downloads. When a bulk query completes, Shopify returns a signed Google Cloud Storage URL for the JSONL result file. The connector must be able to reach this host to download the file. If you're using %ofbyoc-plural%, configure your cloud network egress to allow HTTPS (port 443) access to both endpoints. If you're using %ofsfspcs-plural%, you must create a network rule and an external access integration (EAI). For more information, see [Create a network rule (Openflow - Snowflake Deployments only)](#label-create-network-rule). ## Set up Shopify A Shopify store administrator must create a Shopify dev app and configure API scopes for the connector to authenticate. 1. Log in to the Shopify Dev Dashboard (https://dev.shopify.com/dashboard/). 2. Select **Create app** and provide an app name. 3. In the **Access** section of your new app, select the `read_*` scopes for the objects you want to replicate: - `read_orders`: orders, transactions, fulfillments (access limited to the last 60 days by default; `read_all_orders` extends this to full order history but requires a separate Shopify access request; for details, see the note below) - `read_products`: products, product variants, collections - `read_customers`: customers, segments - `read_inventory`: inventory items, locations - `read_merchant_managed_fulfillment_orders`: fulfillment orders For the full list of available scopes, see the Shopify access scopes reference (https://shopify.dev/docs/api/usage/access-scopes). Some scopes require Shopify approval before your app can use them: - **`read_all_orders`**: Required to access orders older than 60 days. Submit an access request through your app's **API access** settings in the Dev Dashboard. - **Protected customer data**: The `read_customers` scope includes customer fields (name, address, email, and phone) that Shopify classifies as protected customer data. Apps that read these fields must request access to protected customer data and meet Shopify's data protection requirements. Submit an access request through your app's **API access** settings in the Dev Dashboard. For more information, see Protected customer data (https://shopify.dev/docs/apps/launch/protected-customer-data) in the Shopify developer documentation. Grant only the scopes required for the objects you intend to replicate. Some GraphQL fields require write scopes to read (for example, `marketingUnsubscribeUrl` on the `Customer` object requires `write_customers`). If you don't grant the corresponding write scope, the Shopify API returns an error for that field. To avoid this, either omit the field from the `graphqlFields` list in the **Object Definitions Override** parameter, or add it to `ignoredFields`. Note that `ignoredFields` works on top-level field names only. For nested fields, you must remove them from the `graphqlFields` sub-selection. 4. Select **Release**. Optionally provide a version name and message, then confirm by selecting **Release** again. 5. On the app **Overview** page, select **Install app**. You are redirected to your store. Select **Install** to confirm the installation. If you change the app's scopes later, you must release a new app version and reinstall the app on your store to apply the updated permissions. 6. Navigate to **Settings** %ra% **Credentials** to find your **Client ID** and **Client Secret**. Copy both values: you need them when configuring the **Shopify Client ID** and **Shopify Client Secret** connector parameters. For more information, see Client secrets (https://shopify.dev/docs/apps/build/authentication-authorization/client-secrets) in the Shopify developer documentation. ## Set up your Snowflake account As an Openflow administrator, perform the following tasks to set up your Snowflake account. ### Create a Snowflake service user (Openflow - BYOC Deployments only) This step is only required if you're deploying the connector in %ofbyoc-plural%. It isn't needed for %ofsfspcs-plural%. 1. Create a service user: ```sql USE ROLE USERADMIN; CREATE USER TYPE=SERVICE COMMENT='Service user for the Shopify connector'; ``` 2. Store the private key in a file. When configuring the connector, specify the file path. For more information, see [key pair authentication](/user-guide/key-pair-auth). ```sql ALTER USER SET RSA_PUBLIC_KEY = ''; ``` ### Create database, schema, and warehouse 1. Create the destination database: ```sql USE ROLE ACCOUNTADMIN; CREATE DATABASE IF NOT EXISTS ; ``` 2. Create the destination schema: ```sql CREATE SCHEMA IF NOT EXISTS .; ``` 3. Create a role for the connector and grant the required privileges: ```sql CREATE ROLE IF NOT EXISTS ; GRANT USAGE ON DATABASE TO ROLE ; GRANT USAGE ON SCHEMA . TO ROLE ; GRANT CREATE TABLE ON SCHEMA . TO ROLE ; ``` 4. Create a warehouse (or use an existing one) and grant usage privileges: ```sql CREATE WAREHOUSE IF NOT EXISTS WITH WAREHOUSE_SIZE = 'SMALL' AUTO_SUSPEND = 300 AUTO_RESUME = TRUE; GRANT USAGE, OPERATE ON WAREHOUSE TO ROLE ; ``` 5. If using %ofbyoc-plural%, assign the role to the service user: ```sql GRANT ROLE TO USER ; ALTER USER SET DEFAULT_ROLE = ; ``` ### Create a network rule (Openflow - Snowflake Deployments only) If your runtime executes in %ofbyoc-plural%, you don't need to create an External Access Integration (EAI). Instead, configure your cloud network egress to allow HTTPS (port 443) access to your Shopify store domain. To allow the connector to call the Shopify API from a Snowflake-hosted runtime, create a network rule and an external access integration (EAI), and then grant the execute-as role usage privileges on the EAI. 1. Create a network rule: ```sql USE ROLE ACCOUNTADMIN; CREATE OR REPLACE NETWORK RULE openflow__shopify_network_rule TYPE = HOST_PORT MODE = EGRESS VALUE_LIST = ( '.myshopify.com:443', 'storage.googleapis.com:443' ); ``` 2. Create an External Access Integration: ```sql CREATE OR REPLACE EXTERNAL ACCESS INTEGRATION openflow__shopify_eai ALLOWED_NETWORK_RULES = (openflow__shopify_network_rule) ENABLED = TRUE; ``` 3. Grant your execute-as role USAGE on the integration: ```sql GRANT USAGE ON INTEGRATION openflow__shopify_eai TO ROLE OPENFLOW__EXECUTE_AS_RL; ``` ## Install the connector To install the connector, do the following as a data engineer: 1. Navigate to the Openflow overview page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find the connector and select **Install**. 3. In the **Select runtime** dialog, select your runtime from the **Available runtimes** drop-down list and click **Install**. Before you install the connector, ensure that you have created a database and schema in Snowflake for the connector to store ingested data. 4. Authenticate to the deployment with your Snowflake account credentials and select **Allow** when prompted to allow the runtime application to access your Snowflake account. The connector installation process takes a few minutes to complete. 5. Authenticate to the runtime with your Snowflake account credentials. The Openflow canvas appears with the connector process group added to it. ## Configure the connector To configure the connector, perform the following steps: 1. Right-click on the added connector process group and select **Parameters**. 2. Populate the required parameter values as described in the following sections. ### Shopify parameters The following parameters configure the Shopify source connection:
### Snowflake destination parameters The following parameters configure the Snowflake destination:
## Run the flow 1. Right-click on an empty area of the canvas and select **Enable all Controller Services**. 2. Right-click on the connector process group and select **Start**. The connector starts querying the Shopify Admin API and loading data into Snowflake. ## Next steps - For more information about customizing which fields are extracted and registering custom object types, see [Object definition overrides for the Openflow Connector for Shopify](/user-guide/data-integration/openflow/connectors/shopify/object-definitions). - For more information about resetting connector state, see [Maintain the Openflow Connector for Shopify](/user-guide/data-integration/openflow/connectors/shopify/maintain). - For more information about monitoring the flow, see [Monitor Openflow using telemetry data](/user-guide/data-integration/openflow/monitor). --- title: Set up the Openflow Connector for Slack source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/slack/setup.md section: Loading & Unloading Data --- # Set up the Openflow Connector for Slack This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Set up the Openflow Connector for Slack](/user-guide/data-integration/openflow/connectors/slack/setup) This topic describes the steps to set up the Openflow Connector for Slack. ## Prerequisites 1. Ensure that you have reviewed [About Openflow Connector for Slack](/user-guide/data-integration/openflow/connectors/slack/about). 2. Ensure that you have [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) or [Set up Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/setup-openflow-spcs). 3. If using %ofsfspcs-plural%, ensure that you've reviewed [configuring required domains](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list) and have granted access to the required domains for the [](#label-openflow-domains-used-by-openflow-connectors-slack) connector. ## Set up a Slack App Set up a Slack App in your Slack workspace. A Slack Admin is needed to set up access to the Slack Workspace. This is done by creating or supplying credentials to a Slack App and installing the App to the Slack workspace and channels. You can create a Slack App by using the JSON configuration: 1. Update the JSON manifest. Copy the JSON manifest text below. Change the name and display name properties from `EXAMPLE_NAME_CHANGE_THIS` to the desired name of your Slack App. It is recommended to use the same name and display name for your App. ```json { "display_information": { "name": "EXAMPLE_NAME_CHANGE_THIS" }, "features": { "bot_user": { "display_name": "EXAMPLE_NAME_CHANGE_THIS", "always_online": false } }, "oauth_config": { "scopes": { "bot": [ "channels:history", "channels:read", "groups:history", "groups:read", "im:history", "im:read", "mpim:history", "mpim:read", "users.profile:read", "users:read", "users:read.email", "files:read", "app_mentions:read", "reactions:read" ] } }, "settings": { "event_subscriptions": { "bot_events": [ "message.channels", "message.groups", "message.im", "message.mpim", "reaction_added", "reaction_removed", "file_created", "file_deleted", "file_change" ] }, "interactivity": { "is_enabled": true }, "org_deploy_enabled": false, "socket_mode_enabled": true, "token_rotation_enabled": false } } ``` 2. Create a Slack app through the Apps page (https://api.slack.com/apps). 1. On the **Your Apps** page, select **Create New App**. 2. Select **From a manifest**. 3. Select the **Workspace** where you'll be developing your app. You'll be able to distribute your app (https://api.slack.com/distribution) to other workspaces later if you choose. 4. Copy the updated manifest JSON from step 1. 3. Generate an app-level token. You need to create an app-level token even after using the JSON manifest. Under **Basic Information**, scroll to the **App-level tokens** section and click the button to generate an app-level token (https://api.slack.com/concepts/token-types#app). Include the *connections:write* scope to the token. 4. Install and authorize the app. 1. Return to the **Basic Information** section of the app management page. 2. Install your app by selecting the **Install to Workspace** button. 3. You'll now be sent through the Slack OAuth flow. Select **Allow** on the following screen. If you want to add your app to a different workspace besides your own, these steps would need to be performed by a user from that workspace. After installation, navigate back to the **OAuth & Permissions** page. You'll see an **access token** under **OAuth Tokens**. Access tokens represent the permissions delegated to your app by the installing user. Keep it safe and secure. Avoid checking them into public version control. Instead, access them through an environment variable. 5. Adding the App to channels. Your app isn't a member of any channels yet, so pick a channel to add some test messages in and `/invite` your app. For example, `/invite @Grocery Reminders`. Restart the processors to load the new channels. After the App is added to a new channel, the `Consume Slack Conversation` processor in the OpenFlow Runtime needs to be stopped and restarted. ## Setup necessary ingress rules A Snowflake Admin should follow the [egress guide](#label-working-with-services-jobs-egress) to apply egress rules to the endpoint `https://slack.com/api` and enable WebSocket egress on `wss://wss.slack.com`. This is easiest done by adding a rule to enable egress on the “slack.com” domain. ## Set up Snowflake account As a Snowflake account administrator, perform the following tasks: 1. Create a new role or use an existing role and grant the [](#label-database-privileges). 2. Create a new Snowflake service user with the type as [SERVICE](#label-user-type-property). 3. Grant the Snowflake service user the role you created in the previous steps. 4. Configure with [key-pair auth](/user-guide/key-pair-auth) for the Snowflake SERVICE user from step 2. 5. Snowflake strongly recommends this step. Configure a secrets manager supported by Openflow, for example, AWS, Azure, and Hashicorp, and store the public and private keys in the secret store. If for any reason, you do not wish to use a secrets manager, then you are responsible for safeguarding the public key and private key files used for key-pair authentication according to the security policies of your organization. 1. Once the secrets manager is configured, determine how you will authenticate to it. On AWS, it's recommended that you the EC2 instance role associated with Openflow as this way no other secrets have to be persisted. 2. In Openflow, configure a Parameter Provider associated with this Secrets Manager, from the hamburger menu in the upper right. Navigate to **Controller Settings** %raa% **Parameter Provider** and then fetch your parameter values. 3. At this point all credentials can be referenced with the associated parameter paths and no sensitive values need to be persisted within Openflow. 6. If any other Snowflake users require access to the raw ingested documents and tables ingested by the connector (for example, for custom processing in Snowflake), then grant those users the role created in step 1. 7. Designate a warehouse for the connector to use. Start with the smallest warehouse size, then experiment with size depending on the number of tables being replicated, and the amount of data transferred. Large table numbers typically scale better with [multi-cluster warehouses](/user-guide/warehouses-multicluster), rather than larger warehouse sizes. ## Use case 1: Ingest Slack content only Use the connector definition to:
- Perform custom analysis on ingested Slack data (no Cortex Search processing). - Ingest Slack messages, reactions, file attachments, and member lists into Snowflake, and keep them up to date.
### Set up the connector As a data engineer, perform the following tasks to configure the connector: #### Install the connector 1. Create a database and schema in Snowflake for the connector to store ingested data. Grant required [](#label-database-privileges) to the role created in the first step. Substitute the role placeholder with the actual value and use the following SQL commands: ```sql CREATE DATABASE DESTINATION_DB; CREATE SCHEMA DESTINATION_DB.DESTINATION_SCHEMA; GRANT USAGE ON DATABASE DESTINATION_DB TO ROLE ; GRANT USAGE ON SCHEMA DESTINATION_DB.DESTINATION_SCHEMA TO ROLE ; GRANT CREATE TABLE ON SCHEMA DESTINATION_DB.DESTINATION_SCHEMA TO ROLE ; ``` To install the connector, do the following as a data engineer: 1. Navigate to the Openflow overview page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find the connector and select **Install**. 3. In the **Select runtime** dialog, select your runtime from the **Available runtimes** drop-down list and click **Install**. Before you install the connector, ensure that you have created a database and schema in Snowflake for the connector to store ingested data. 4. Authenticate to the deployment with your Snowflake account credentials and select **Allow** when prompted to allow the runtime application to access your Snowflake account. The connector installation process takes a few minutes to complete. 5. Authenticate to the runtime with your Snowflake account credentials. The Openflow canvas appears with the connector process group added to it. #### Configure the connector 1. Right-click on the imported process group and select **Parameters**. 2. Enter the required parameter values as described in **Flow parameters: Ingest content only** below. 3. Right-click on the canvas and select **Enable all controller services**. 4. Right-click on the imported process group and select **Start**. The flow creates all required Snowflake objects and begins ingesting Slack data. ##### Flow parameters: Ingest content only
## Use case 2: Ingest Slack content and enable Cortex Use the connector definition to:
- Make Slack data ready for conversational search with Snowflake Cortex. - Ensure Slack channel access controls are respected in search results.
### Set up the connector As a data engineer, perform the following tasks to configure the connector: #### Install the connector 1. Create a database and schema in Snowflake for the connector to store ingested data. Grant required [](#label-database-privileges) to the role created in the first step. Substitute the role placeholder with the actual value and use the following SQL commands: ```sql CREATE DATABASE DESTINATION_DB; CREATE SCHEMA DESTINATION_DB.DESTINATION_SCHEMA; GRANT USAGE ON DATABASE DESTINATION_DB TO ROLE ; GRANT USAGE ON SCHEMA DESTINATION_DB.DESTINATION_SCHEMA TO ROLE ; GRANT CREATE TABLE ON SCHEMA DESTINATION_DB.DESTINATION_SCHEMA TO ROLE ; ``` To install the connector, do the following as a data engineer: 1. Navigate to the Openflow overview page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find the connector and select **Install**. 3. In the **Select runtime** dialog, select your runtime from the **Available runtimes** drop-down list and click **Install**. Before you install the connector, ensure that you have created a database and schema in Snowflake for the connector to store ingested data. 4. Authenticate to the deployment with your Snowflake account credentials and select **Allow** when prompted to allow the runtime application to access your Snowflake account. The connector installation process takes a few minutes to complete. 5. Authenticate to the runtime with your Snowflake account credentials. The Openflow canvas appears with the connector process group added to it. #### Configure the connector 1. Right-click on the imported process group and select **Parameters**. 2. Enter the required parameter values as described in **Flow parameters: Ingest content and enable Cortex** below. 3. Right-click on the canvas and select **Enable all controller services**. 4. Right-click on the imported process group and select **Start**. 5. Once the flow is running, proceed to [Query the Cortex Search service](#query-the-cortex-search-service) for testing. ##### Flow parameters: Ingest content and enable Cortex
## Enabling private-channel ACLs No extra steps are required beyond **inviting the Slack App** to each private channel. The connector automatically refreshes the member list and stores it in the membership table at each **Refresh Slack Members** interval. ## Query the Cortex Search service After Use case 2 is running and the Cortex Search service has been created, you can query it as follows: ```sql SELECT PARSE_JSON( SNOWFLAKE.CORTEX.SEARCH_PREVIEW( '..<', '{ "query": "What is my vacation carry over policy?", "columns": ["text","channel","ts","username"], "filter": {"@contains": {"memberemails": "alice@example.com"}}, "limit": 10 }' ) )['results'] AS results; ``` **Common searchable columns** `text`, `type`, `subtype`, `channel`, `user`, `username`, `connectorId`, `workspaceId`, `ts`, `threadTs` **Example: Query an AI assistant for human resources (HR) information** You can use Cortex Search to query an AI assistant for employees to chat about the latest Slack posts. The messages that are searched can come from informative Slack channels such as general or it-help.
Run the following in a [SQL worksheet](#label-snowsight-worksheets-create-file) to query the Cortex Search service over messages ingested from Slack. Replace the following: - cortex_db: Name of the database containing the cortex search service, specified by the *Destination Database* parameter. - cortex_schema: Name of the schema containing the cortex search service, specified by the *Destination Schema* parameter. - cortex_search_service_name: Name of the cortex search service, specified by the *Cortex Search Name* parameter. - user_emailID: Email ID of the user who you want to filter the responses for. ```sql SELECT PARSE_JSON( SNOWFLAKE.CORTEX.SEARCH_PREVIEW( '..', '{ "query": "What is my vacation carry over policy?", "columns": ["text", "channel", “ts”,”username”], "filter": {"@contains": {"memberemails": ""} }, "limit": 1 }' ) )['results'] AS results ```
**Python:** Run the following code in a [Python worksheet](#label-snowsight-worksheets-create) to query the Cortex Search service over messages ingested from Slack Ensure that you add the `snowflake.core` package to your database. Replace the following: - cortex_db: Name of the database containing the cortex search service, specified by the *Destination Database* parameter. - cortex_schema: Name of the schema containing the cortex search service, specified by the *Destination Schema* parameter. - cortex_search_service_name: Name of the cortex search service, specified by the *Cortex Search Name* parameter. - user_emailID: Email ID of the user who you want to filter the responses for. ```python from snowflake.snowpark import Session from snowflake.core import Root def main(session: snowpark.Session): root = Root(session) # fetch service my_service = (root .databases[""] .schemas[""] .cortex_search_services[""] ) # query service resp = my_service.search( query="What is my vacation carry over policy?", columns = ["text", "channel", "ts","username"], filter = {"@contains": {"memberemails": ""} }, limit=1 ) return (resp.to_json()) ``` **REST API:** Execute the following code in a command-line interface to query the Cortex Search service over messages ingested from Slack. You will need to authentication through key pair authentication and OAuth to access the Snowflake REST APIs. For more information, see [](#label-cortex-search-query-syntax-rest) and [Authenticating Snowflake REST APIs with Snowflake](/developer-guide/snowflake-rest-api/authentication). Replace the following: - cortex_db: Name of the database containing the cortex search service, specified by the *Destination Database* parameter. - cortex_schema: Name of the schema containing the cortex search service, specified by the *Destination Schema* parameter. - cortex_search_service_name: Name of the cortex search service, specified by the *Cortex Search Name* parameter. - account_url: Your Snowflake account URL. For instructions on finding your account URL, see [](#label-account-name-find). ```bash curl --location "https:///api/v2/databases//schemas//cortex-search-services/" \ --header 'Content-Type: application/json' \ --header 'Accept: application/json' \ --header "Authorization: Bearer " \ --data '{ "query": "What is my vacation carry over policy?", "columns": ["text", "channel"], "limit": 1 }' ``` Sample response: ```text { "results" : [ { "channel" : "dev notes", "text" : "Answer to the question asked." } ] } ``` --- title: Set up the Openflow Connector for Snowflake to Kafka source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/snowflake-to-kafka/setup.md section: Loading & Unloading Data --- # Set up the %sf-kafka% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) This topic describes the steps to set up the %sf-kafka%. ## Prerequisites 1. Ensure that you have reviewed [About Openflow Connector for Snowflake to Kafka](/user-guide/data-integration/openflow/connectors/snowflake-to-kafka/about). 2. Ensure that you have [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) or [Set up Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/setup-openflow-spcs). 3. Create a Snowflake stream that will be queried for the changes. 4. Create a Kafka topic that will receive CDC messages from the Snowflake stream. ## Set up Snowflake account As a Snowflake account administrator, perform the following tasks: 1. Create the database, source table, and the stream object that the connector will use for reading CDC events. For example: ```sql create database stream_db; use database stream_db; create table stream_source (user_id varchar, data varchar); create stream stream_on_table on table stream_source; ``` 2. Create a new role or use an existing role, and grant the SELECT privilege on the stream and the source object for the stream. The connector will also need the USAGE privilege on the database and schema containing the stream and source object for the stream. For example: ```sql create role stream_reader; grant usage on database stream_db to role stream_reader; grant usage on schema stream_db.public to role stream_reader; grant select on stream_source to role stream_reader; grant select on stream_on_table to role stream_reader; ``` 3. Create a new Snowflake service user with the type as [SERVICE](#label-user-type-property). For example: ```sql create user stream_user type = service; ``` 4. Grant the Snowflake service user the role you created in the previous steps. For example: ```sql grant role stream_reader to user stream_user; ``` 5. Configure [key-pair auth](/user-guide/key-pair-auth) for the Snowflake SERVICE user from step 3. 6. Snowflake strongly recommends this step. Configure a secrets manager supported by Openflow, such as AWS, Azure, and HashiCorp, and store the public and private keys in the secret store. However, note that the private key generated in step 5 can be used directly as a configuration parameter for the connector configuration. In such a case, the private key is stored in Openflow runtime configuration. If for any reason, you do not wish to use a secrets manager, then you are responsible for safeguarding the public key and private key files used for key-pair authentication according to the security policies of your organization. 1. Once the secrets manager is configured, determine how you will authenticate to it. On AWS, it's recommended that you use the EC2 instance role associated with Openflow, so that no other secrets have to be persisted. 2. In Openflow, configure a Parameter Provider associated with this Secrets Manager, from the hamburger menu in the upper right. Navigate to **Controller Settings** %raa% **Parameter Provider** and then fetch your parameter values. 3. At this point all credentials can be referenced with the associated parameter paths and no sensitive values need to be persisted within Openflow. 7. Designate a warehouse for the connector to use. One connector can replicate a single table to a single Kafka topic. For this kind of processing, you can select the smallest warehouse. ## Set up the connector As a data engineer, perform the following tasks to install and configure a connector: 1. Navigate to the Openflow Overview page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find and choose the connector depending on what kind of Kafka broker instance the connector should communicate with. - mTLS version: Choose this connector if you are using the SSL (mutual TLS) security protocol, or if you are using the SASL_SSL protocol and connecting to the broker that is using self-signed certificates. - SASL version: Choose this connector if you are using any other security protocol. 3. Select **Install**. 4. In the **Select runtime** dialog, select your runtime from the **Available runtimes** drop-down list. 5. Select **Add**. 6. Authenticate to the deployment with your Snowflake account credentials and select **Allow** when prompted to allow the runtime application to access your Snowflake account. The connector installation process takes a few minutes to complete. 7. Authenticate to the runtime with your Snowflake account credentials. The Openflow canvas appears with the connector process group added to it. 8. Right-click on the imported process group and select **Parameters**. 9. Populate the required parameter values as described in [Flow parameters](#flow-parameters). ### Flow parameters This section describes the flow parameters that you can configure based on the following parameter contexts: - [Kafka Sink Source Parameters](#kafka-sink-source-parameters) - [Kafka Sink Destination Parameters](#kafka-sink-destination-parameters) - [Kafka Sink Ingestion Parameters](#kafka-sink-ingestion-parameters) #### Kafka Sink Source Parameters
#### Kafka Sink Destination Parameters
#### Kafka Sink Ingestion Parameters
## Run the flow 1. Right-click on the canvas and select **Enable all Controller Services**. 2. Right-click on the imported process group and select **Start**. The connector starts the data ingestion. --- title: Set up the Openflow Connector for SQL Server source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/sql-server/setup.md section: Loading & Unloading Data --- # Set up the %sqlserver% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Monitor Openflow using telemetry data](/user-guide/data-integration/openflow/monitor) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [About Openflow Connector for SQL Server](/user-guide/data-integration/openflow/connectors/sql-server/about) - [Openflow connectors for SQL Server: Data mapping](/user-guide/data-integration/openflow/connectors/sql-server/data-mapping) This topic describes how to set up the %sqlserver%. For information on the incremental load process, see [Incremental replication](/user-guide/data-integration/openflow/connectors/sql-server/incremental-replication). ## Prerequisites Before setting up the connector, ensure that you have completed the following prerequisites: 1. Ensure that you have reviewed [About Openflow Connector for SQL Server](/user-guide/data-integration/openflow/connectors/sql-server/about). 2. Ensure that you have reviewed [](#label-sql-server-versions). 3. Ensure that you have set up your runtime deployment. For more information, see the following topics: - [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) - [Set up Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/setup-openflow-spcs). 4. If you use %ofsfspcs-plural%, ensure that you have reviewed [configuring required domains](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list) and have granted access to the required domains for the [](#label-openflow-domains-used-by-openflow-connectors-sqlserver) connector. ## Set up your SQL Server instance Before setting up the connector, perform the following tasks in your SQL Server environment: You must perform these tasks as a database administrator. 1. Enable change tracking on the databases (https://learn.microsoft.com/en-us/sql/relational-databases/track-changes/enable-and-disable-change-tracking-sql-server?view=sql-server-ver16#enable-change-tracking-for-a-database) and tables (https://learn.microsoft.com/en-us/sql/relational-databases/track-changes/enable-and-disable-change-tracking-sql-server?view=sql-server-ver16#enable-change-tracking-for-a-table) that you plan to replicate, as shown in the following SQL Server example: ```sql ALTER DATABASE SET CHANGE_TRACKING = ON (CHANGE_RETENTION = 5 DAYS, AUTO_CLEANUP = ON); ALTER TABLE .
Field Description
`schema` Required. The exact source schema name.
`table` Required. The exact source table name.
`logicalKey` Required. A non-empty array of source column names that uniquely identify rows in the table.
Parameter Description
SharePoint Site URL URL or SharePoint site from which the connector will ingest content
SharePoint Client ID Microsoft Entra client ID. To learn about client ID and how to find it in Microsoft Entra, see Application ID (client ID) (https://learn.microsoft.com/en-us/azure/healthcare-apis/register-application#application-id-client-id).
SharePoint Client Secret Microsoft Entra Client Secret. To learn about a client secret and how to find it in Microsoft Entra, see Certificates & secrets (https://learn.microsoft.com/en-us/azure/healthcare-apis/register-application#certificates--secrets).
SharePoint Tenant ID Microsoft Entra Tenant ID. To learn about tenant ID and how to find it in Microsoft Entra, see Find your Microsoft 365 tenant ID (https://learn.microsoft.com/en-us/sharepoint/find-your-office-365-tenant-id).
Parameter Description
Sharepoint Application Private Key A generated application private key in PEM format. The key must be unencrypted.
Sharepoint Site Domain A domain name of the synchronized Sharepoint site.
Sharepoint Application Certificate A generated application certificate in PEM format.
Parameter Description Required
Destination Database The database where data will be persisted. It must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. Yes
Destination Schema The schema where data will be persisted, which must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. See the following examples:
- `CREATE SCHEMA SCHEMA_NAME` or `CREATE SCHEMA schema_name`: use `SCHEMA_NAME` - `CREATE SCHEMA "schema_name"` or `CREATE SCHEMA "SCHEMA_NAME"`: use `schema_name` or `SCHEMA_NAME`, respectively
Yes
Snowflake Authentication Strategy When using: - **Snowflake Openflow Deployment** or **BYOC**: Use SNOWFLAKE_MANAGED. This token is managed automatically by Snowflake. BYOC deployments must have previously configured [execute-as roles](#label-deployment-byoc-setup-runtime-role) to use SNOWFLAKE_MANAGED. - **BYOC**: Alternatively, BYOC can use KEY_PAIR as the value for the authentication strategy. Yes
Snowflake Account Identifier When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Snowflake account name formatted as [organization-name]-[account-name]. Yes
Snowflake Private Key When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. -
**KEY_PAIR**: Must be the RSA private key used for authentication.
The RSA key must be formatted according to PKCS8 standards and have standard PEM headers and footers. Note that either a Snowflake Private Key File or a Snowflake Private Key must be defined.
No
Snowflake Private Key File When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: The private key file must be blank. - **KEY_PAIR**: Upload the file that contains the RSA private key used for authentication to Snowflake, formatted according to PKCS8 standards and including standard PEM headers and footers. The header line begins with `-----BEGIN PRIVATE`. To upload the private key file, select the **Reference asset** checkbox. No
Snowflake Private Key Password When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the password associated with the Snowflake private key file. No
Snowflake Role When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Use the runtime's execute-as role (or a child role granted to it). You can find your execute-as role in the Openflow UI by navigating to **View Details** for your runtime. - **KEY_PAIR**: Use a valid role configured for your service user. Yes
Snowflake Username When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the username used to connect to the Snowflake instance. Yes
Snowflake Warehouse Snowflake warehouse used to run queries. Yes
Parameter Description
SharePoint Source Folder Supported files from this folder and all its subfolders is ingested into Snowflake. The folder path is relative to a Shared Documents library.
File Extensions To Ingest A comma-separated list that specifies file extensions to ingest. The connector tries to convert the files to PDF format first, if possible. Nonetheless, the extension check is performed on the original file extension. To learn about the formats that can be converted, see Format options (https://learn.microsoft.com/en-us/graph/api/driveitem-get-content-format?view=graph-rest-1.0&tabs=http#format-options) If some of the specified file extensions are not supported by Cortex Parse Document, then the connector ignores those files, logs a warning message in an event log, and continues processing other files.
Sharepoint Document Library Name A library in the SharePoint Site to ingest files from.
Snowflake File Hash Table Name Name of the table to store file hashes to determine if the content has changed. This parameter should generally not be changed.
Parameter Description
Sharepoint Site Groups Enabled Specifies whether the Site Groups functionality is enabled.
Parameter Description
SharePoint Site URL URL or SharePoint site from which the connector will ingest content
SharePoint Client ID Microsoft Entra client ID. To learn about client ID and how to find it in Microsoft Entra, see Application ID (client ID) (https://learn.microsoft.com/en-us/azure/healthcare-apis/register-application#application-id-client-id).
SharePoint Client Secret Microsoft Entra Client Secret. To learn about a client secret and how to find it in Microsoft Entra, see Certificates & secrets (https://learn.microsoft.com/en-us/azure/healthcare-apis/register-application#certificates--secrets).
SharePoint Tenant ID Microsoft Entra Tenant ID. To learn about tenant ID and how to find it in Microsoft Entra, see Find your Microsoft 365 tenant ID (https://learn.microsoft.com/en-us/sharepoint/find-your-office-365-tenant-id).
Parameter Description
Sharepoint Application Private Key A generated application private key in PEM format. The key must be unencrypted.
Sharepoint Site Domain A domain name of the synchronized Sharepoint site.
Sharepoint Application Certificate A generated application certificate in PEM format.
Parameter Description Required
Destination Database The database where data will be persisted. It must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. Yes
Destination Schema The schema where data will be persisted, which must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. See the following examples:
- `CREATE SCHEMA SCHEMA_NAME` or `CREATE SCHEMA schema_name`: use `SCHEMA_NAME` - `CREATE SCHEMA "schema_name"` or `CREATE SCHEMA "SCHEMA_NAME"`: use `schema_name` or `SCHEMA_NAME`, respectively
Yes
Snowflake Authentication Strategy When using: - **Snowflake Openflow Deployment** or **BYOC**: Use SNOWFLAKE_MANAGED. This token is managed automatically by Snowflake. BYOC deployments must have previously configured [execute-as roles](#label-deployment-byoc-setup-runtime-role) to use SNOWFLAKE_MANAGED. - **BYOC**: Alternatively, BYOC can use KEY_PAIR as the value for the authentication strategy. Yes
Snowflake Account Identifier When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Snowflake account name formatted as [organization-name]-[account-name]. Yes
Snowflake Private Key When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. -
**KEY_PAIR**: Must be the RSA private key used for authentication.
The RSA key must be formatted according to PKCS8 standards and have standard PEM headers and footers. Note that either a Snowflake Private Key File or a Snowflake Private Key must be defined.
No
Snowflake Private Key File When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: The private key file must be blank. - **KEY_PAIR**: Upload the file that contains the RSA private key used for authentication to Snowflake, formatted according to PKCS8 standards and including standard PEM headers and footers. The header line begins with `-----BEGIN PRIVATE`. To upload the private key file, select the **Reference asset** checkbox. No
Snowflake Private Key Password When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the password associated with the Snowflake private key file. No
Snowflake Role When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Use the runtime's execute-as role (or a child role granted to it). You can find your execute-as role in the Openflow UI by navigating to **View Details** for your runtime. - **KEY_PAIR**: Use a valid role configured for your service user. Yes
Snowflake Username When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the username used to connect to the Snowflake instance. Yes
Snowflake Warehouse Snowflake warehouse used to run queries. Yes
Parameter Description
SharePoint Source Folder Supported files from this folder and all its subfolders is ingested into Snowflake. The folder path is relative to a Shared Documents library.
File Extensions To Ingest A comma-separated list that specifies file extensions to ingest. The connector tries to convert the files to PDF format first, if possible. Nonetheless, the extension check is performed on the original file extension. To learn about the formats that can be converted, see Format options (https://learn.microsoft.com/en-us/graph/api/driveitem-get-content-format?view=graph-rest-1.0&tabs=http#format-options) If some of the specified file extensions are not supported by Cortex Parse Document, then the connector ignores those files, logs a warning message in an event log, and continues processing other files.
Sharepoint Document Library Name A library in the SharePoint Site to ingest files from.
Snowflake File Hash Table Name Name of the table to store file hashes to determine if the content has changed. This parameter should generally not be changed.
OCR Mode The OCR mode to use when parsing files with [Parsing documents with AI_PARSE_DOCUMENT](/user-guide/snowflake-cortex/parse-document) function. The value can be `OCR` or `LAYOUT`. In `OCR` mode, only raw text content is extracted, ignoring formatting and table structures. In `LAYOUT` mode, the output preserves table structures as Markdown.
Snowflake Cortex Search Service User Role An identifier of a role that is assigned usage permissions on the Cortex Search service.
Parameter Description
Sharepoint Site Groups Enabled Specifies whether the Site Groups functionality is enabled.
Column name Type Description
`full_name` String A full path to the file from the Sharepoint site documents root. Example: `folder_1/folder_2/file_name.pdf`.
`web_url` String A URL that displays an original Sharepoint file in a browser.
`last_modified_date_time` String Date and time when the item was most recently modified.
`chunk` String A piece of text from the document that matched the Cortex Search query.
Column name Type Description
`user_ids` Array An array of Microsoft 365 user IDs that have access to the document. It also includes user IDs from all the Microsoft 365 groups that are assigned to the document. To find a specific user ID, see Get a user (https://learn.microsoft.com/en-us/graph/api/user-get?view=graph-rest-1.0&tabs=http).
`user_emails` Array An array of Microsoft 365 user email IDs that have access to the document. It also includes user email IDs from all the Microsoft 365 groups that are assigned to the document.
Parameter Description
Shop Domain The `myshopify.com` domain for your store. **Example:** `mystore.myshopify.com`
Shopify Client ID Client ID from your Shopify dev app.
Shopify Client Secret Client Secret from your Shopify dev app. Stored securely as a sensitive parameter.
Shopify API Version The Shopify Admin API version to use for requests. **Default:** `2026-04`
Objects to Sync Comma-separated or newline-separated list of Shopify object types to replicate. Case-insensitive. Each value must correspond to a query endpoint in the Shopify Admin GraphQL API (for example, `orders` corresponds to the `orders` query, `products` to the `products` query). Types not found in the built-in catalog are skipped unless a custom definition is provided through the **Object Definitions Override** parameter or **Enable Introspection** is `true`. **Default:** `orders,products,customers,productVariants,inventoryItems,collections`
Objects to Track for Deletes Comma-separated or newline-separated list of Shopify object types to monitor for deletions through the Events API. Each type is polled independently. Types not found in the registry are skipped. Leave empty to disable delete tracking entirely. **Example:** `products, customers, collections`
Sync Schedule How frequently the connector polls Shopify for new or updated data. Uses NiFi scheduling syntax. **Default:** `30 min`
Deletes Schedule How frequently the connector polls the Shopify Events API for deletion events. Uses NiFi scheduling syntax. Increase this interval to reduce API cost if delete detection latency isn't critical. **Default:** `15 min`
Object Definitions Override Optional JSON array to add new object definitions or override existing ones in the built-in catalog. Each element fully replaces the catalog entry for that `apiType`. Use this parameter to customize which fields are extracted, define promoted columns, or register custom object types. For more information, see [Object definition overrides](/user-guide/data-integration/openflow/connectors/shopify/object-definitions#label-shopify-object-override).
Enable Introspection When `true`, unknown object types are auto-discovered by querying the Shopify Admin GraphQL introspection endpoint. Discovered definitions are cached for 24 hours. **Default:** `true`
Ignore Deprecated Fields When `true`, deprecated GraphQL fields are excluded from introspection-generated queries. Only applicable when **Enable Introspection** is `true`. **Default:** `true`
Parameter Description
Snowflake Authentication Strategy Authentication strategy for the connector to connect to Snowflake. - `SNOWFLAKE_MANAGED` (default): Uses the Snowflake-managed token associated with the runtime's execute-as role. Snowflake recommends this option for both %ofsfspcs-plural% and %ofbyoc-plural%. - `KEY_PAIR`: Uses a user-provided RSA key pair. Available only on %ofbyoc-plural%, for cross-account scenarios.
Snowflake Account Identifier Snowflake account identifier, formatted as `-`. Required when the authentication strategy is `KEY_PAIR`. **Example:** `MYORG-MYACCOUNT`
Snowflake Username The Snowflake user for authentication. Required when the authentication strategy is `KEY_PAIR`.
Snowflake Private Key PEM-encoded private key content (PKCS8 format) for Snowflake key pair authentication. Required when the authentication strategy is `KEY_PAIR`. Stored securely as a sensitive parameter. Either this parameter or **Snowflake Private Key File** must be defined.
Snowflake Private Key File Alternative to **Snowflake Private Key**. Upload the private key file by selecting the **Reference asset** checkbox, uploading the file as an asset, and selecting the asset as the value for the parameter. Either this parameter or **Snowflake Private Key** must be defined.
Snowflake Private Key Password Password to decrypt the Snowflake private key, if the key is encrypted. Only applicable when the authentication strategy is `KEY_PAIR`.
Snowflake Role The execute-as role used for table creation, data ingestion, and access verification.
Destination Database Name of the destination database in Snowflake. The database must already exist before starting the connector.
Destination Schema Name of the destination schema in Snowflake. The schema must already exist before starting the connector.
Snowflake Warehouse The Snowflake warehouse used for table management operations such as `CREATE TABLE` and `MERGE`.
Parameter Description
App Token Slack *App-level token* generated in the Slack App.
Bot Token Slack *Bot token* generated in the Slack App.
Destination Database Database to contain all connector objects (created if absent).
Destination Schema Schema inside the database (created if absent).
Snowflake Account Snowflake account identifier.
Snowflake Role Role the flow assumes after authentication.
Snowflake User Username the flow uses to connect.
Snowflake Private Key RSA private key used for authentication (PKCS8 PEM format). Note that either Snowflake Private Key or Snowflake Private Key File must be defined.
Snowflake Private Key Password Password for the encrypted private key (leave blank if unencrypted).
Snowflake Private Key File File containing the RSA Private Key (PKCS8 PEM format). The header line starts with `-----BEGIN PRIVATE`.
Snowflake Warehouse Warehouse used for SQL executed by the flow.
Upload Interval Time to gather data before pushing to Snowflake. A longer interval reduces load on Snowflake but may increase latency and memory usage.
Refresh Slack Members Minutes between Slack membership (ACL) refreshes.
Parameter Description
App Token Slack *App-level token* generated in the Slack App.
Bot Token Slack *Bot token* generated in the Slack App.
Destination Database Database to contain all connector objects (created if absent).
Destination Schema Schema inside the database (created if absent).
Upload Interval Time to gather data before pushing to Snowflake. A larger value reduces load but increases data latency.
Snowflake Account Snowflake account identifier.
Snowflake Role Role the flow assumes after authentication.
Snowflake User Username the flow uses to connect.
Snowflake Private Key PEM-formatted private key for key-pair authentication.
Snowflake Private Key Password Password for the encrypted private key (blank if unencrypted).
Snowflake Warehouse Warehouse used for all SQL executed by the flow **and** by Cortex.
Refresh Slack Members Minutes between Slack membership (ACL) refreshes.
Parameter Description Required
Snowflake Account Identifier When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Snowflake account name formatted as [organization-name]-[account-name] where data will be persisted. Yes
Snowflake Authentication Strategy When using: - **Snowflake Openflow Deployment** or **BYOC**: Use SNOWFLAKE_MANAGED. This token is managed automatically by Snowflake. BYOC deployments must have previously configured [execute-as roles](#label-deployment-byoc-setup-runtime-role) to use SNOWFLAKE_MANAGED. - **BYOC**: Alternatively, BYOC can use KEY_PAIR as the value for the authentication strategy. Yes
Source Database Source database. This database should contain the Snowflake Stream object that will be consumed. Yes
Snowflake Private Key Password When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the password associated with the Snowflake Private Key File. No
Snowflake Role When using - **SNOWFLAKE_MANAGED** Authentication Strategy: Use the runtime's execute-as role (or a child role granted to it). You can find your execute-as role in the Openflow UI by navigating to **View Details** for your runtime. - **KEY_PAIR** Authentication Strategy: Use a valid role configured for your service user. Yes
Snowflake Username When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the user name used to connect to the Snowflake instance. Yes
Snowflake Private Key Leave this blank when using SNOWFLAKE_MANAGED Authentication Strategy. When using KEY_PAIR, provide the RSA private key used for authentication. The RSA key must be formatted according to PKCS8 standards and have standard PEM headers and footers. Note that either Snowflake Private Key File or Snowflake Private Key must be defined. Yes
Snowflake Private Key File Leave this blank when using SNOWFLAKE_MANAGED Authentication Strategy. When using KEY_PAIR, upload the file that contains the RSA Private Key used for authentication to Snowflake, formatted according to PKCS8 standards and having standard PEM headers and footers. The header line begins with `-----BEGIN PRIVATE`. Select the **Reference asset** checkbox to upload the private key file. No
Source Schema The source schema. This schema should contain the Snowflake Stream object that will be consumed. Yes
Snowflake Warehouse Snowflake warehouse used to run queries. Yes
Parameter Description Required
Kafka Bootstrap Servers A comma-separated list of Kafka brokers to send data to. Yes
Kafka SASL Mechanism SASL mechanism used for authentication. Corresponds to the Kafka Client `sasl.mechanism` property. Possible values: - `PLAIN` - `SCRAM-SHA-256` - `SCRAM-SHA-512` - `AWS_MSK_IAM` Yes
Kafka SASL Username The username to authenticate to Kafka. Yes
Kafka SASL Password The password to authenticate to Kafka. Yes
Kafka Security Protocol Security protocol used to communicate with brokers. Corresponds to the Kafka Client `security.protocol` property. Possible values: - `PLAINTEXT` - `SASL_PLAINTEXT` - `SASL_SSL` - `SSL` Yes
Kafka Topic The Kafka topic where CDC messages from the Snowflake Stream will be sent. Yes
Kafka Message Key Field Specify the database column name that will be used as the Kafka message key. If not specified, the message key will not be set. If specified, the value of this column will be used as a message key. The value of this parameter is case-sensitive. No
Kafka Keystore Filename A full path to a keystore storing a client key and certificate for mTLS authentication method. Required for mTLS authentication and when the security protocol is SSL. No
Kafka Keystore Type The type of keystore. Required for mTLS authentication. Possible values: - `PKCS12` - `JKS` - `BCFKS` No
Kafka Keystore Password The password used to secure the keystore file. No
Kafka Key Password A password for the private key stored in the keystore. Required for mTLS authentication. No
Kafka Truststore Filename A full path to a truststore storing broker certificates. The client will use the certificate from this truststore to verify broker identity. No
Kafka Truststore Type The type of truststore file. Possible values: - `PKCS12` - `JKS` - `BCFKS` No
Kafka Truststore Password A password for the truststore file. No
Parameter Description Required
Snowflake FQN Stream Name Fully qualified Snowflake stream name. Yes
ENABLE CHANGE_TRACKING WITH (TRACK_COLUMNS_UPDATED = OFF); ``` Run the `ALTER DATABASE` command only once per database to enable change tracking on that database. Run the `ALTER TABLE` command for every table that you plan to replicate in that database. Keep the column tracking feature off by setting `TRACK_COLUMNS_UPDATED = OFF` (the default) when you enable change tracking on a table. The connector doesn't use column-level change information, so enabling `TRACK_COLUMNS_UPDATED = ON` adds unnecessary storage and per-DML overhead on the source without providing any benefit to replication. Each table must have change tracking enabled before the connector can replicate it. Enable change tracking on every table you want to replicate before you start replication. Set `CHANGE_RETENTION` to a window that's long enough to keep change data available for data continuity. SQL Server removes tracked changes once they're older than the retention period, so if the connector can't read changes before they expire, it can't replicate them incrementally and the affected tables require a full reload. A longer retention window, such as 5 days, gives you time to detect and react to problems, such as a paused connector, a network outage, or a failed replication cycle, and to mitigate them without reloading entire tables. Choose a value that covers the longest interruption you expect to recover from, balanced against the additional storage that retained change data consumes in SQL Server. 2. Create a login for the SQL Server instance: ```sql CREATE LOGIN WITH PASSWORD = ''; ``` This login is used to create users for the databases you plan to replicate. 3. Create a user for each database you are replicating by running the following SQL Server command in each database: ```sql USE ; CREATE USER FOR LOGIN ; ``` 4. Grant the SELECT and VIEW CHANGE TRACKING permissions to the user for each database that you are replicating: ```sql GRANT SELECT ON ..
TO ; GRANT VIEW CHANGE TRACKING ON ..
TO ; ``` Run these commands in each database for every table that you plan to replicate. These permissions must be granted to the user of each database that you created in a previous step. 5. (Optional) Grant the VIEW DEFINITION privilege on the User Defined Data Types (UDDT). If your tables contain columns that use User Defined Data Types (UDDT), and the UDDT is owned by a different user than the connector user, you must grant the VIEW DEFINITION permission to the connector user as shown in the following SQL Server example: ```sql GRANT VIEW DEFINITION TO ; ``` Without this permission, columns using UDDT are silently excluded from replication. 6. (Optional) Configure SSL connection. If you use an SSL connection to connect to SQL Server, create the root certificate for your database server. This is required when configuring the connector. ## Set up your Snowflake environment As an Openflow administrator, perform the following tasks for this connector. With the default `SNOWFLAKE_MANAGED` authentication strategy, the runtime's execute-as role is the identity the connector uses to access Snowflake, so you grant these privileges to that role rather than creating a separate service user. 1. Create a database to store the replicated data, and grant the execute-as role [USAGE and CREATE SCHEMA](#label-database-privileges) on it. The connector creates destination schemas automatically. Snowflake recommends a dedicated destination database per connector, to avoid collisions with other data sources including other connectors. Keep this destination database separate from the database that holds your Openflow infrastructure objects, such as the runtime, the connector, and any secrets. A connector creates destination objects based on the source schema and table names, so those names aren't under your control and can change as the source changes. ```sql CREATE DATABASE IF NOT EXISTS ; GRANT USAGE ON DATABASE TO ROLE ; GRANT CREATE SCHEMA ON DATABASE TO ROLE ; ``` 2. Designate a warehouse for the connector to use, and grant the execute-as role **USAGE** and **OPERATE** on it. Start with the `XSMALL` warehouse size, then experiment with size depending on the number of tables being replicated, and the amount of data transferred. Large table numbers typically scale better with [multi-cluster warehouses](/user-guide/warehouses-multicluster), rather than the warehouse size. ```sql CREATE WAREHOUSE WITH WAREHOUSE_SIZE = 'XSMALL' AUTO_SUSPEND = 300 AUTO_RESUME = TRUE; GRANT USAGE, OPERATE ON WAREHOUSE TO ROLE ; ``` 3. **Snowflake deployments only:** Make sure this connector's source host and port are permitted by a network rule that your runtime's external access integration (EAI) allows. The EAI itself belongs to the runtime, not to this connector. You create it once, attach it to the runtime, and grant the execute-as role `USAGE` on it. For those steps, see [Creating network rules and external access integrations](/user-guide/data-integration/openflow/setup-openflow-spcs-create-rr#label-create-network-rules-and-external-access-integrations). What is specific to this connector is getting its source host into a rule that EAI references. The rule takes the source's host and port as a single value, such as `db.example.com:`. That's the host and port from the connector's connection URL, without the `jdbc:` scheme, the driver name, or the database path. BYOC deployments handle outbound connectivity in the cloud environment and don't use EAIs or network rules. For additional setup when you use key-pair authentication with BYOC: Key-pair authentication is available only for BYOC deployments, and is not required for the default `SNOWFLAKE_MANAGED` authentication strategy. Skip this section unless you set the connector's **Snowflake Authentication Strategy** parameter to `KEY_PAIR`. 1. Create a Snowflake user with the type as [SERVICE](#label-user-type-property), create a role for it, and grant that role the same destination database and warehouse privileges you granted the execute-as role: ```sql CREATE USER TYPE=SERVICE COMMENT='Service user for automated access of Openflow'; CREATE ROLE ; GRANT ROLE TO USER ; GRANT USAGE ON DATABASE TO ROLE ; GRANT CREATE SCHEMA ON DATABASE TO ROLE ; GRANT USAGE, OPERATE ON WAREHOUSE TO ROLE ; ``` 2. Create a pair of secure keys (public and private). Store the private key for the user in a file to supply to the connector's configuration. Assign the public key to the Snowflake service user: ```sql ALTER USER SET RSA_PUBLIC_KEY = 'thekey'; ``` For more information, see [pair of keys](/user-guide/key-pair-auth). When using `KEY_PAIR`, you must also set the connector's **Snowflake Account Identifier** and **Snowflake Connection Strategy** parameters. Both are left blank or ignored under `SNOWFLAKE_MANAGED`. ## Install the connector To install the connector, do the following as a data engineer: 1. Navigate to the Openflow overview page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find the connector and select **Install**. 3. In the **Select runtime** dialog, select your runtime from the **Available runtimes** drop-down list and click **Install**. Before you install the connector, ensure that you have created a database and schema in Snowflake for the connector to store ingested data. 4. Authenticate to the deployment with your Snowflake account credentials and select **Allow** when prompted to allow the runtime application to access your Snowflake account. The connector installation process takes a few minutes to complete. 5. Authenticate to the runtime with your Snowflake account credentials. The Openflow canvas appears with the connector process group added to it. ## Runtime sizing The runtime size determines the CPU, memory, and disk available to the connector. The available sizes are Small, Medium, and Large. Choose the size when you create the runtime: you can't change the size of an existing runtime in place. Size the runtime based on the sustained workload it needs to handle across all connectors running on it. Sustained means typical steady-state throughput, not peak. Peak load can temporarily increase connector queues and end-to-end replication latency; the workload catches up when the load drops back to the steady-state level. The following ranges are starting points based on internal benchmarks and production customer data. They aren't service guarantees. Your fit depends on row size, event distribution, schema width, and source burstiness. Start at the lower bound, measure runtime CPU, memory, queue depth, and end-to-end replication latency in production, then increase from there. - Light workload (aggregate sustained throughput below approximately 1,000 events per second, fewer than approximately 100 actively changing tables): a Small runtime can host a single low-volume connector. Pack additional connectors on Small only when each source is genuinely light. - Moderate workload (approximately 1,000 to 5,000 events per second, hundreds of actively changing tables): a Medium runtime can typically host 5 to 8 connectors. - Heavy workload (approximately 5,000 to 15,000 events per second, hundreds to low thousands of actively changing tables): a Large runtime can typically host 15 or more connectors. If you want a smaller blast radius, split across two Medium runtimes instead. ## Running multiple connectors on one runtime You can run multiple CDC connector instances on a single runtime. This is useful for replicating many small databases, for example a multi-tenant SaaS with one database per tenant, or a fleet of operational databases per business unit or region. When you run multiple CDC connector instances of the same type on one runtime, keep their shared Source and Destination parameter contexts intact and override only the per-connector values in each Ingestion context. For the recommended process, see [](#run-multiple-connectors-on-one-runtime). Run a connector on a dedicated runtime, not packed with others, when any of the following applies: - A single source sustains more than approximately 15,000 events per second. - You need sub-1-minute end-to-end replication latency under load. - You can't tolerate noisy-neighbor effects from other sources sharing the runtime. Each replicated table can consume two Snowpipe Streaming pipes: one for snapshot replication and one for incremental replication. As you pack more tables onto a runtime, check your account's [Snowpipe Streaming pipe limit](/user-guide/snowpipe-streaming/snowpipe-streaming-high-performance-limitations#pipe-limits) and raise it before you approach the cap. ## Resize a runtime Runtime size is fixed at creation, so to change size you run the connector on a different runtime. You have two options depending on whether you want to preserve the current replication progress. If you don't need to keep the progress of the current connector, the simplest path is to create a new runtime at the size you need and install a new connector instance on it. The new connector starts from scratch: it snapshots all configured tables and then captures ongoing changes from that point. The replication progress of the existing connector is discarded. To keep the progress of the current connector, for example to avoid re-snapshotting tables that took a long time to snapshot initially, migrate the connector to the new runtime. This reuses the existing destination tables and resumes incremental replication from where it left off. For migration instructions, see [Reinstall the connector](#label-sql-server-reinstall-connector). ## Configure the connector To configure the connector, do the following as a data engineer: 1. Right-click on the imported process group and select **Parameters**. 2. Populate the required parameter values. For more information on the required parameter values, see the following sections: - [](#label-of-sqlserver-source-parameters): Used to establish a connection with SQL Server. - [](#label-of-sqlserver-destination-parameters): Used to establish a connection with Snowflake. - [](#label-of-sqlserver-ingestion-parameters): Used to specify the tables to replicate. Start by setting the parameters of the SQLServer Source Parameters context, then the SQLServer Destination Parameters context. After you complete this, enable the connector. The connector connects to both SQLServer and Snowflake and starts running. However, the connector doesn't replicate any data until any tables to be replicated are explicitly added to its configuration. To configure specific tables for replication, edit the SQLServer Ingestion Parameters context. After you apply the changes to the SQLServer Ingestion Parameters context, the configuration is picked up by the connector, and the replication lifecycle starts for every table. To run multiple CDC connector instances on one runtime, see [](/user-guide/data-integration/openflow/connectors/cdc-runtime-sizing#run-multiple-connectors-on-one-runtime). ### SQLServer Source Parameters
To connect with Windows authentication using NTLMv2, configure the SQL Server source parameters as follows: - **SQLServer Connection URL**: `jdbc:sqlserver://:1433;databaseName=;integratedSecurity=true;authenticationScheme=NTLM;domain=;` - **SQLServer JDBC Driver**: Upload the `mssql-jdbc` JAR. The driver class name is `com.microsoft.sqlserver.jdbc.SQLServerDriver`. - **SQLServer Username**: Enter the domain user. - **SQLServer Password**: Enter the domain password. Azure SQL Database refers to the single-database PaaS offering, not Azure SQL Managed Instance. ### Always On Availability Groups Configure the connector to connect through the availability group **listener** (the virtual network name for the group), not through an individual replica node. Set the listener hostname in the **SQLServer Connection URL** parameter in the SQLServer Source Parameters context. Always On Availability Groups (https://learn.microsoft.com/sql/database-engine/availability-groups/windows/overview-of-always-on-availability-groups-sql-server) provide high availability through a shared listener and automatic failover between replicas. Always On Availability Groups are separate from SQL Server transactional replication. Do not change the connection target after replication has started. Each database maintains its own replication position independently, so switching to a different server or listener can cause the connector to lose track of which changes have already been processed. This might result in data loss. For failover behavior, see [Always On Availability Groups and source failover](/user-guide/data-integration/openflow/connectors/sql-server/about#label-sqlserver-source-failover-resilience). ### SQLServer Destination Parameters
The following destination parameter controls how the connector handles invalid rows:
### SQLServer Ingestion Parameters
## Read the source under SNAPSHOT isolation The connector reads the source tables during both snapshot and incremental replication. Under SQL Server's default READ COMMITTED isolation level, these reads acquire shared locks that can deadlock with concurrent writes from other database clients. To avoid these deadlocks without affecting the isolation level that other applications use, configure the connector to read under SNAPSHOT isolation (https://learn.microsoft.com/en-us/dotnet/framework/data/adonet/sql/snapshot-isolation-in-sql-server). For background, see [Source database locking behavior](/user-guide/data-integration/openflow/connectors/sql-server/about#label-sql-server-source-database-locking-behavior). Enable SNAPSHOT isolation for the connector in two steps: 1. On each source database, allow snapshot isolation: ```sql ALTER DATABASE SET ALLOW_SNAPSHOT_ISOLATION ON; ``` 2. Add a dynamic property named **Use Snapshot Isolation** with the value `true` to the connector's processors. Because the connector reads the source tables during both snapshot and incremental replication, add this dynamic property to both the `MultiDatabaseFetchTableSnapshot` processor and the `MultiDatabaseCaptureChangeSqlServer` processor. The connector checks each source database when it starts and uses SNAPSHOT isolation only for databases that have `ALLOW_SNAPSHOT_ISOLATION` enabled. For a database that doesn't have it enabled, the connector falls back to the default isolation level. Because this check runs at startup, restart the processors after you change `ALLOW_SNAPSHOT_ISOLATION`. `ALLOW_SNAPSHOT_ISOLATION` only makes SNAPSHOT isolation available to sessions that explicitly request it, such as the connector. It doesn't change the default READ COMMITTED isolation level, so other applications that use the source database are unaffected. Don't use `READ_COMMITTED_SNAPSHOT` (RCSI) for this purpose. Although RCSI also removes the shared locks, it redefines the default READ COMMITTED isolation level for every connection to the database. Applications that rely on the default lock-based READ COMMITTED behavior (for example, expecting readers to block on concurrent uncommitted writes) can see different results after the change. ## Replicate tables from a SQL Server replica server The connector can ingest data from a primary server or from a subscriber server using transactional replication (https://learn.microsoft.com/en-us/sql/relational-databases/replication/transactional/transactional-replication). Before configuring the connector to connect to a SQL Server replica, ensure that replication between the primary and replica nodes works correctly. For instructions on setting up transactional replication, see Tutorial: Configure transactional replication (https://learn.microsoft.com/en-us/sql/relational-databases/replication/tutorial-replicating-data-between-continuously-connected-servers). When investigating issues with missing data in the connector, first ensure that missing rows and change tracking events are present in the replica server used by the connector. When using a replica server, the connector setup differs from the standard primary server configuration. The connection user and change tracking don't need to be configured on the primary server. Instead, make sure that the connection user is available on the replica server and has access to the data and change tracking tables there. To configure the connector to read from a subscriber server instead of the publisher, specify the subscriber server URL in the **SQLServer Connection URL** parameter. Do not change the database server after replication has started. Each database maintains its own change tracking state independently, so switching to a different server would cause the connector to lose track of which changes have already been processed, and may result in data loss. ## Replicate a subset of columns in a table The connector can filter the data replicated per table to a subset of configured columns. Primary key columns are always included regardless of exclusions. To apply column filters, set the **Column Filter JSON** parameter in the Ingestion Parameters context to a JSON array of filter objects, one per table you want to filter. Columns can be included or excluded by name or by regular expression pattern. You can apply a single condition per table, or combine multiple conditions, with exclusions always taking precedence over inclusions. ## Syntax Each object in the array identifies a table and specifies which columns to include or exclude. Because this connector uses three-part fully qualified names (database, schema, and table), each object can include a `database` or `databasePattern` field in addition to the schema and table fields. ```javascript [ { "database": "" | "databasePattern": "", "schema": "" | "schemaPattern": "", "table": "
Parameter Description
SQLServer Connection URL The full JDBC URL used to connect to the source. For a standalone SQL Server instance or Azure SQL Managed Instance, point the URL at the instance. The connector discovers the databases to replicate from that instance. - `jdbc:sqlserver://example.com:1433;encrypt=false` For Always On Availability Groups, see [Always On Availability Groups](#label-sql-server-availability-groups). For Azure SQL Database, point the URL at a specific database using the `databaseName` property. Use one connector instance per database you want to replicate. - `jdbc:sqlserver://your-server.database.windows.net:1433;encrypt=true;databaseName=your_database`
SQLServer JDBC Driver Select the **Reference asset** checkbox to upload the SQL Server JDBC driver (https://learn.microsoft.com/sql/connect/jdbc/download-microsoft-jdbc-driver-for-sql-server).
SQLServer Username The username for the connector.
SQLServer Password The password for the connector.
SQLServer Query Interval The minimum time interval that must elapse before scheduling the next query for table changes. This controls the frequency of database polling during incremental replication to prevent excessive querying. Default: `10 sec`.
Parameter Description Required
Destination Database The database where data is persisted. It must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. Yes
Destination Schema Pattern A pattern for the names of destination schemas where data is persisted. The connector creates the schemas if they don't exist. You can customize the pattern per ingested table using these optional variables: - `${source.database.name}`: a source table's database. - `${source.schema.name}`: a source table's schema. - `${source.table.name}`: a source table's name. For example, for a table with the qualified name `source_db.tenant_a.data`, the pattern `prefix_${source.database.name}_${source.schema.name}` evaluates to `prefix_source_db_tenant_a`. To ingest all tables into a single schema, provide a schema name without any variables, like `destination_schema`. Don't change this setting after the connector has begun ingesting data. Changing this setting after ingestion has begun breaks the existing ingestion. If you must change this setting, create a new connector instance. Yes
Snowflake Authentication Strategy When using: - **Snowflake Openflow Deployment** or **BYOC**: Use SNOWFLAKE_MANAGED. This token is managed automatically by Snowflake. BYOC deployments must have previously configured [execute-as roles](#label-deployment-byoc-setup-runtime-role) to use SNOWFLAKE_MANAGED. - **BYOC**: Alternatively, BYOC can use KEY_PAIR as the value for the authentication strategy. Yes
Snowflake Account Identifier When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Snowflake account name formatted as [organization-name]-[account-name]. Yes
Snowflake Connection Strategy When using KEY_PAIR, specify the strategy for connecting to Snowflake: - **STANDARD** (default): Connect using standard public routing to Snowflake services. - **PRIVATE_CONNECTIVITY**: Connect using private addresses associated with the supporting cloud platform such as AWS PrivateLink. Required for BYOC with KEY_PAIR only, otherwise ignored.
Snowflake Object Identifier Resolution Specifies how source object identifiers such as schemas, tables, and column names are stored and queried in Snowflake. This setting dictates whether you must use double quotes in SQL queries.

Option 1: Default, case-insensitive (recommended).

- **Transformation**: All identifiers are converted to uppercase. For example, `My_Table` becomes `MY_TABLE`. - **Queries**: SQL queries are case-insensitive and don't require SQL double quotes. For example, `SELECT * FROM my_table;` returns the same results as `SELECT * FROM MY_TABLE;`. Snowflake recommends using this option if database objects are not expected to have mixed case names. Do not change this setting after connector ingestion has begun. Changing this setting after ingestion has begun breaks the existing ingestion. If you must change this setting, create a new connector instance.

Option 2: Case-sensitive.

- **Transformation**: Case is preserved. For example, `My_Table` remains `My_Table`. - **Queries**: SQL queries must use double quotes to match the exact case for database objects. For example, `SELECT * FROM "My_Table";`. Snowflake recommends using this option if you must preserve source casing for legacy or compatibility reasons. For example, the source database includes table names that differ in case only, such as `MY_TABLE` and `my_table`, which result in a name collision when using case-insensitive comparisons.
Yes
Snowflake Private Key When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. -
**KEY_PAIR**: Must be the RSA private key used for authentication.
The RSA key must be formatted according to PKCS8 standards and have standard PEM headers and footers. Note that either a Snowflake Private Key File or a Snowflake Private Key must be defined.
No
Snowflake Private Key File When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: The private key file must be blank. - **KEY_PAIR**: Upload the file that contains the RSA private key used for authentication to Snowflake, formatted according to PKCS8 standards and including standard PEM headers and footers. The header line begins with `-----BEGIN PRIVATE`. To upload the private key file, select the **Reference asset** checkbox. No
Snowflake Private Key Password When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the password associated with the Snowflake Private Key File. No
Snowflake Role When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Use the runtime's execute-as role (or a child role granted to it). You can find your execute-as role in the Openflow UI by navigating to **View Details** for your runtime. - **KEY_PAIR**: Use a valid role configured for your service user. Yes
Snowflake Username When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the user name used to connect to the Snowflake instance. Yes
Oversized Value Strategy Determines how the connector handles values that exceed its internal size limits (16 MB) during replication. Possible values are:
- **Fail Table** (default): The table is marked as permanently failed, and replication stops for that table. - **Set Null**: The value is replaced with `NULL` in the destination table. Use this to prevent table failures when it is acceptable to lose data in tables beyond the oversized value.
No
Table Storage Format Standard Snowflake tables or Iceberg tables. Defaults to **STANDARD**. Don't change after the connector starts. Yes
Iceberg Version The Iceberg table version, 2 or 3 (default 3). Ignored unless Table Storage Format is **ICEBERG**. Don't change this value after ingestion begins. No
Snowflake Warehouse Snowflake warehouse used to run queries. Yes
Parameter Description Required
Error Handling Strategy Determines how the connector handles invalid rows that Snowflake rejects during ingestion. Possible values are:
- **Fail Table** (default): The table is marked as failed on the first invalid row, and replication stops for that table. - **Log Errors and Continue**: The connector keeps replicating the valid rows and records each rejected row in the table's error table.
For more information, see [](/user-guide/data-integration/openflow/connectors/sql-server/about#label-sql-server-error-handling).
No
Parameter Description
Column Filter JSON Optional. A JSON array of filter objects specifying which columns to include or exclude per table. For syntax details and examples, see [Replicate a subset of columns in a table](#replicate-a-subset-of-columns-in-a-table).
Concurrent Select Queries For Incremental Maximum number of concurrent SELECT queries to run against the source database during incremental replication. Default: `1`, maximum: `8`. Increasing this can speed up replication when many tables are active, but will also increase the load on the source database.
Concurrent Select Queries For Snapshot Maximum number of concurrent queries to the source database to run in the Snapshot flow. Increasing this can speed up snapshotting large numbers of tables, but will also increase the load on the source database.
Included Table Names A comma-separated list of source table paths, including their databases and schemas, for example: `database_1.public.table_1, database_2.schema_2.table_2`
Included Table Regex A regular expression to match against table paths, including database and schema names. Every path matching the expression is replicated, and new tables matching the pattern that are created later are also included automatically, for example: `database_name\.public\.auto_.*`
Ingestion Type Controls whether newly added tables go through a full initial snapshot before switching to incremental replication, or skip straight to incremental replication. Set to `full` (default) for snapshot followed by incremental replication. Set to `incremental` to skip the snapshot for newly added tables and replicate only subsequent changes. Changing this value does not affect tables that have already begun replicating. For usage notes, see [Set up incremental replication without snapshots](/user-guide/data-integration/openflow/connectors/sql-server/incremental-replication).
Max Batch Size The maximum number of rows to fetch in a single batch. Default: `100000`.
Merge Task Schedule CRON CRON expression defining periods when merge operations from Journal to Destination Table will be triggered. Set it to `* * * * * ?` if you want continuous merges, or configure a time schedule to limit warehouse run time. The connector evaluates the schedule in the UTC time zone. For example:
- The string `* 0 * * * ?` indicates that you want to schedule merges at the full hour for one minute. - The string `* 20 14 ? * MON-FRI` indicates that you want to schedule merges at 2:20 PM every Monday through Friday.
For additional information and examples, see the cron triggers tutorial in the Quartz Documentation (https://www.quartz-scheduler.org/documentation/quartz-2.5.x/tutorials/crontrigger.html).
Re-read Tables in State Only applicable when **Starting Change Tracking Position** is `Earliest`.
- `New` (default): Only new tables, added after the starting position was switched to `Earliest`, will have their change tracking tables read from the earliest available positions. Tables that started replication before the configuration change will continue reading from their last positions. - `Any active`: Re-read and re-process changes from any table currently in replication.
For more information, see [Specify load from change tracking table position](/user-guide/data-integration/openflow/connectors/sql-server/maintenance#label-sql-server-connector-start-restart-incremental-load-from-earliest-available-change-tracking-position).
Re-snapshot Table Exclusions A comma-separated list of fully qualified table names that should not be replicated, from among tables matching the included criteria. Use the same format and quoting rules as **Included Table Names**, for example: `database_1.public.table_1`.
SQL Server Read Timeout Read timeout in milliseconds applied to both snapshot and incremental queries. A query that runs longer than this value is closed by SQL Server. Default: `60000`.
Starting Change Tracking Position
- `Latest` (default): Change tracking table reading starts at the latest available position and continues from there. - `Earliest`: Switches the incremental load to start, or restart reading from the earliest available change tracking table positions.
For more information, see [Specify load from change tracking table position](/user-guide/data-integration/openflow/connectors/sql-server/maintenance#label-sql-server-connector-start-restart-incremental-load-from-earliest-available-change-tracking-position).
" | "tablePattern": "", "included": ["", ""], "excluded": ["", ""], "includedPattern": "", "excludedPattern": "" } ] ``` The following rules apply: - Use `database`, `schema`, and `table` for exact name matching, or `databasePattern`, `schemaPattern`, and `tablePattern` for regex matching. You can't use both a field and its pattern variant in the same object (for example, `schema` and `schemaPattern` can't both appear). - At least one of `included`, `excluded`, `includedPattern`, or `excludedPattern` must be provided. - When both included and excluded filters are specified, exclusions take precedence. - When multiple filters match the same table, the last matching filter is used, with exact matches taking precedence over pattern-based filters. - The value can be an array of objects to apply different filters to different tables. ## Examples Include specific columns by name: ```javascript [ { "database": "my_db", "schema": "dbo", "table": "orders", "included": ["account_id", "status", "created_at"] } ] ``` Exclude specific columns by name: ```javascript [ { "database": "my_db", "schema": "dbo", "table": "orders", "excluded": ["internal_note", "debug_flag"] } ] ``` Combine an include pattern with a specific exclusion (for example, include all email columns except `admin_email`): ```javascript [ { "database": "my_db", "schema": "dbo", "table": "contacts", "includedPattern": ".*_email", "excluded": ["admin_email"] } ] ``` Mix a database pattern with an exact schema and table name to apply a filter across databases: ```javascript [ { "databasePattern": "prod_.*", "schema": "dbo", "table": "customers", "excluded": ["internal_note"] } ] ``` Pass multiple filter objects to apply different rules to different tables: ```javascript [ {"database": "my_db", "schema": "dbo", "table": "orders", "included": ["account_id", "status"]}, {"database": "my_db", "schema": "dbo", "table": "customers", "excludedPattern": ".*_internal"} ] ``` ### Including and excluding the same column Removing a column from a table's replicated set (by excluding it or by removing it from the included list) has the same effect on the destination as dropping the column at the source: the connector soft-deletes the column on the destination by renaming it with a suffix (by default, `__SNOWFLAKE_DELETED`). If you then add the column back to the replicated set and later remove it a second time, replication for the affected table fails because the soft-deleted column name is already taken. To recover, restart replication for the affected table. ## Replicate a partitioned table The connector supports replication of partitioned tables. A SQL Server partitioned table is replicated into Snowflake as a single destination table, containing data from all partitions. To replicate a partitioned table, ensure that change tracking is enabled on the partitioned table, as described in [](#label-sql-server-connector-setup-instance). For more information about how the connector handles snapshots of large partitioned tables, see [Snapshot of partitioned tables](/user-guide/data-integration/openflow/connectors/sql-server/about#label-sql-server-partitioned-snapshot). ## Track data changes in tables The connector replicates the current state of data from the source tables, as well as detected changes from each polling interval. This data is stored in journal tables created in the same schema as the destination table. Because the connector uses SQL Server Change Tracking, multiple updates to the same row between polling intervals are rolled up into a single change. Journal tables reflect the net result of changes, not every intermediate state. For more information, see [About Openflow Connector for SQL Server](/user-guide/data-integration/openflow/connectors/sql-server/about). The journal table names are formatted as: `_JOURNAL__` where `` is the value of epoch seconds when the source table was added to replication, and `` is an integer increasing with every schema change on the source table. As a result, source tables that undergo schema changes will have multiple journal tables. When you remove a table from replication, then add it back, the `` value changes, and `` starts again from `1`. Snowflake recommends not altering the structure of journal tables in any way. The connector uses them to update the destination table as part of the replication process. The connector never drops journal tables, but uses the latest journal for every replicated source table, only reading append-only streams on top of journals. To reclaim the storage, you can: - Truncate all journal tables at any time. - Drop the journal tables related to source tables that were removed from replication. - Drop all but the latest generation journal tables for actively replicated tables. For example, if your connector is set to actively replicate source table `orders`, and you have earlier removed table `customers` from replication, you may have the following journal tables. In this case you can drop all of them *except* `orders_5678_2`. ```text customers_1234_1 customers_1234_2 orders_5678_1 orders_5678_2 ``` ## Configure scheduling of merge tasks The connector uses a warehouse to merge change data capture (CDC) data into destination tables. The processor named Merge Journal to Destination triggers this operation. When there are no new changes, or when no new FlowFiles are waiting in the Merge Journal to Destination queue, no merge is triggered and the warehouse is available for auto-suspension. To limit warehouse cost and restrict merges to scheduled times, use the CRON expression in the Merge Task Schedule CRON parameter. It throttles the FlowFiles that reach the Merge Journal to Destination processor, so merges are triggered only during the specified period. The connector evaluates the schedule in the UTC time zone. For additional information and examples, see the cron triggers tutorial in the Quartz Documentation (https://www.quartz-scheduler.org/documentation/quartz-2.5.x/tutorials/crontrigger.html). ## Run the flow 1. Right-click on the canvas and select **Enable all Controller Services**. 2. Right-click on the imported process group and select **Start**. The connector starts the data ingestion. --- title: Set up the Openflow Connector for SQL Server (CDC) source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/sql-server-cdc/setup.md section: Loading & Unloading Data --- # Set up the %sqlservercdc% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Monitor Openflow using telemetry data](/user-guide/data-integration/openflow/monitor) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [About Openflow Connector for SQL Server (CDC)](/user-guide/data-integration/openflow/connectors/sql-server-cdc/about) - [Openflow connectors for SQL Server: Data mapping](/user-guide/data-integration/openflow/connectors/sql-server/data-mapping) This topic describes how to set up the %sqlservercdc%. For information on the incremental load process, see [Incremental replication](/user-guide/data-integration/openflow/connectors/sql-server-cdc/incremental-replication). ## Prerequisites Before setting up the connector, ensure that you have completed the following prerequisites: 1. Ensure that you have reviewed [About Openflow Connector for SQL Server (CDC)](/user-guide/data-integration/openflow/connectors/sql-server-cdc/about). 2. Ensure that you have reviewed [](#label-sql-server-cdc-versions). 3. Ensure that you have set up your runtime deployment. For more information, see the following topics: - [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) - [Set up Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/setup-openflow-spcs). 4. If you use %ofsfspcs-plural%, ensure that you have reviewed [configuring required domains](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list) and have granted access to the required domains for the [](#label-openflow-domains-used-by-openflow-connectors-sqlserver) connector. ## Set up your SQL Server instance Before setting up the connector, perform the following tasks in your SQL Server environment: You must perform these tasks as a database administrator. 1. Enable Change Data Capture on the databases (https://learn.microsoft.com/en-us/sql/relational-databases/track-changes/enable-and-disable-change-data-capture-sql-server) and tables that you plan to replicate: ```sql USE ; EXEC sys.sp_cdc_enable_db; EXEC sys.sp_cdc_enable_table @source_schema = N'', @source_name = N'
', @role_name = NULL; ``` Run the `sp_cdc_enable_table` procedure for every table that you plan to replicate. Run `sp_cdc_enable_db` once per database. The connector requires that CDC is enabled on the databases and tables before replication starts. You can also enable CDC on additional tables while the connector is running. **Platform-specific variants for enabling CDC at the database level.** The `sp_cdc_enable_table` call shown above is the same on every platform; only the database-level enable procedure differs. - **AWS RDS for SQL Server.** You can't call `sys.sp_cdc_enable_db` directly on RDS because RDS doesn't expose the `sysadmin` server role. Use the RDS-provided wrapper instead: ```sql EXEC msdb.dbo.rds_cdc_enable_db ''; ``` See Using change data capture for Amazon RDS for SQL Server (https://docs.aws.amazon.com/AmazonRDS/latest/UserGuide/Appendix.SQLServer.CommonDBATasks.CDC.html). CDC isn't supported on the Web edition of RDS for SQL Server. - **Google Cloud SQL for SQL Server.** You can't call `sys.sp_cdc_enable_db` directly. Use the Cloud SQL-provided wrapper instead: ```sql EXEC msdb.dbo.gcloudsql_cdc_enable_db ''; ``` See Enable change data capture (CDC) on Cloud SQL for SQL Server (https://cloud.google.com/sql/docs/sqlserver/replication/enable-cdc). Cloud SQL for SQL Server currently offers SQL Server 2017, 2019, and 2022 only. - **Azure SQL Database (single database).** Use the standard `sys.sp_cdc_enable_db` procedure. On the DTU-based purchasing model, CDC requires the S3 service tier or higher (CDC isn't supported on Basic, S0, S1, or S2). On the vCore-based purchasing model, CDC is supported on any tier. See Change data capture with Azure SQL Database (https://learn.microsoft.com/en-us/azure/azure-sql/database/change-data-capture-overview?view=azuresql). - **Azure SQL Managed Instance.** Use the standard `sys.sp_cdc_enable_db` procedure. Enabling CDC requires membership in the `sysadmin` server role. **Raise max text repl size for large LOB columns** If replicated tables contain LOB columns (such as `VARCHAR(MAX)`, `NVARCHAR(MAX)`, or `VARBINARY(MAX)`) with values larger than 64 KB, raise the SQL Server `max text repl size` setting on the source instance. SQL Server CDC defaults this setting to 65536 bytes (64 KB), which is lower than the connector's 16 MB per-value limit. Without raising it, replication can fail with an error such as the following: > *Length of LOB data (N) to be replicated exceeds configured maximum 65536. Use the stored procedure sp_configure to increase the configured maximum value for max text repl size option.* Set the value based on the largest LOB sizes in your source data. It must be at least as large as the biggest value SQL Server CDC needs to replicate, including when **Oversized Value Strategy** is set to **Set Null** (the connector still reads the full value before replacing it with `NULL`). Raising `max text repl size` allows SQL Server CDC to capture larger LOB values, but those values are written to the transaction log and copied into CDC change tables. Capturing very large values can increase transaction log generation, storage consumption, and latency in CDC capture and cleanup jobs. Set the limit to match the LOB sizes you actually need rather than the maximum, unless you require that headroom. How you change this setting depends on your platform: - **On-premises SQL Server, Azure SQL Managed Instance, and Google Cloud SQL for SQL Server.** Use `sp_configure`. The example below sets the maximum allowed value of `2147483647` (~2 GB): ```sql EXEC sp_configure 'show advanced options', 1; RECONFIGURE; EXEC sp_configure 'max text repl size', 2147483647; RECONFIGURE; ``` For more information, see Configure the max text repl size server configuration option (https://learn.microsoft.com/en-us/sql/database-engine/configure-windows/configure-the-max-text-repl-size-server-configuration-option). - **AWS RDS for SQL Server.** You can't change this setting with `sp_configure` or `msdb.dbo.rds_set_configuration`. Configure it through an RDS DB parameter group instead: 1. Create a custom DB parameter group for your SQL Server version family (for example, `sqlserver-se-16.0`): ```shell aws rds create-db-parameter-group \ --db-parameter-group-name \ --db-parameter-group-family sqlserver-se-16.0 \ --description "Custom SQL Server params" ``` 2. Set `max text repl size (b)` (note the exact parameter name, including `(b)` in lowercase). The example below uses `2147483647` (~2 GB), the maximum allowed value: ```shell aws rds modify-db-parameter-group \ --db-parameter-group-name \ --parameters "ParameterName='max text repl size (b)',ParameterValue=2147483647,ApplyMethod=immediate" ``` 3. Attach the parameter group to the RDS instance: ```shell aws rds modify-db-instance \ --db-instance-identifier \ --db-parameter-group-name \ --apply-immediately ``` 4. Reboot the RDS instance. This parameter requires a reboot to take effect on RDS for SQL Server. - **Azure SQL Database (single database).** Open a query window connected to the specific database and run: ```sql EXEC sp_configure 'max text repl size', 2147483647; RECONFIGURE; ``` A value of `-1` is also supported and removes the size limit other than the limit imposed by the column data type. 2. Create a login for the SQL Server instance: ```sql CREATE LOGIN WITH PASSWORD = ''; ``` This login is used to create users for the databases you plan to replicate. 3. Create a user for each database you are replicating by running the following SQL Server command in each database: ```sql USE ; CREATE USER FOR LOGIN ; ``` 4. Grant the required permissions to the user for each database that you are replicating. Add the user to the `db_datareader` role and grant SELECT on the `cdc` schema so the connector can read both the source tables and the CDC change tables: ```sql ALTER ROLE db_datareader ADD MEMBER ; GRANT SELECT ON SCHEMA::cdc TO ; ``` Run these commands in each database that you plan to replicate. These permissions give the connector read access to every user table in the database. To scope access more tightly, grant `SELECT` only on the specific tables being replicated and on `SCHEMA::cdc` instead of adding the user to the `db_datareader` role. **Azure SQL Database (single database) only — database owner before deploying wrapper scripts.** The wrapper procedures use `EXECUTE AS OWNER`. If the database owner is a Microsoft Entra ID principal (common after importing a database from a `.bacpac` file) and the connector authenticates with SQL Server authentication, calls to `dbo.sf_openflow_cdc_enable_table` and `dbo.sf_openflow_cdc_disable_table` fail with an error such as `Only active directory users can impersonate other active directory users` (error 33171). The connector does not receive extra privileges from this step; it only changes who owns the database. Before deploying the Openflow CDC wrapper scripts in step 5, connect to each replicated database as the server administrator and run: ```sql ALTER AUTHORIZATION ON DATABASE::[] TO []; ``` Use the SQL Server authentication login that administers the logical server (for example, the login you specified when you created the server), not the connector login. 5. Deploy the Openflow CDC wrapper procedures so the connector can rotate capture instances when supported schema changes occur. For deployment instructions, see [Deploy the Openflow CDC wrapper procedures](#label-sql-server-cdc-wrapper-procedures). If permissions or internal policy blocks deployment, see [When the wrapper procedures aren't deployed](/user-guide/data-integration/openflow/connectors/sql-server-cdc/about#label-sql-server-cdc-wrapper-procedures-missing). 6. (Optional) Grant the VIEW DEFINITION privilege on the User Defined Data Types (UDDT). If your tables contain columns that use User Defined Data Types (UDDT), and the UDDT is owned by a different user than the connector user, you must grant the VIEW DEFINITION permission to the connector user as shown in the following SQL Server example: ```sql GRANT VIEW DEFINITION TO ; ``` Without this permission, columns using UDDT are silently excluded from replication. 7. (Optional) Configure SSL connection. If you use an SSL connection to connect SQL Server, create the root certificate for your database server. This is required when configuring the connector. ## Deploy the Openflow CDC wrapper procedures Deploy these procedures during connector setup (step 5). Without them, replication runs normally until a supported schema change occurs; at that point a DBA must run the SQL from the WARN bulletin on the **MultiDatabaseCaptureChangeCdcSqlServer** processor for each change. Only take that path when permissions or internal policy blocks deployment. For what to look for, see [When the wrapper procedures aren't deployed](/user-guide/data-integration/openflow/connectors/sql-server-cdc/about#label-sql-server-cdc-wrapper-procedures-missing). The connector applies supported source table schema changes (DDL) without stopping replication or requiring a manual re-snapshot. To do this, the connector manages SQL Server capture instances autonomously: when a tracked table's schema changes, the connector creates a new capture instance for the updated schema and drops the old one after it finishes the transition. For an overview of the process, see [Schema changes](/user-guide/data-integration/openflow/connectors/sql-server-cdc/about#label-sql-server-cdc-schema-changes). Creating and dropping capture instances normally requires `db_owner`. Rather than granting the connector that level of access, deploy a small set of wrapper procedures that perform these operations on the connector's behalf and grant the connector permission to run only those two procedures. This design has the following properties: - **The connector can run only the two wrapper procedures.** For capture-instance management, the connector is granted `EXECUTE` on only `dbo.sf_openflow_cdc_enable_table` and `dbo.sf_openflow_cdc_disable_table`. It doesn't hold `db_owner` and can't call the underlying `sys.sp_cdc_enable_table` or `sys.sp_cdc_disable_table` procedures directly. The wrapper procedures run with `EXECUTE AS OWNER`, so they supply the elevated privileges only for the specific, audited operation. - **Every operation is recorded in an audit table.** Each invocation of a wrapper procedure writes an `attempt` row to the `dbo.openflow_cdc_audit` table before it calls the engine, then a `success` or `failure` row (including the SQL Server error number and message on failure) after the call. The rows are append-only: the wrappers never update or delete audit rows. Deploy the procedures as a database administrator. Run the following scripts, in order, in each CDC-enabled database being replicated. Run them as a principal that already holds `db_owner`. Perform these tasks as a database administrator, after creating the connector's database user as described in [](#label-sql-server-cdc-connector-setup-instance). 1. **`openflow_cdc_audit_setup.sql`**: Creates the append-only `dbo.openflow_cdc_audit` table that the wrapper procedures write to. ```sql SET NOCOUNT ON; -- Audit log. Each wrapper invocation writes one 'attempt' row before delegating to -- sys.sp_cdc_*, then either a 'success' or 'failure' row sharing the same attempt_id. -- Rows are append-only. IF OBJECT_ID(N'dbo.openflow_cdc_audit', N'U') IS NULL BEGIN CREATE TABLE dbo.openflow_cdc_audit ( audit_id bigint IDENTITY(1,1) NOT NULL CONSTRAINT pk_openflow_cdc_audit PRIMARY KEY, attempt_id uniqueidentifier NOT NULL, event_time datetime2(3) NOT NULL, event_kind varchar(16) NOT NULL, action varchar(16) NOT NULL, source_schema sysname NOT NULL, source_name sysname NOT NULL, capture_instance sysname NOT NULL, caller sysname NOT NULL, error_number int NULL, error_message nvarchar(4000) NULL, CONSTRAINT ck_openflow_cdc_audit_event_kind CHECK (event_kind IN ('attempt', 'success', 'failure')), CONSTRAINT ck_openflow_cdc_audit_action CHECK (action IN ('enable', 'disable')) ); CREATE INDEX ix_openflow_cdc_audit_attempt ON dbo.openflow_cdc_audit(attempt_id); CREATE INDEX ix_openflow_cdc_audit_event_time ON dbo.openflow_cdc_audit(event_time); END; GO ``` 2. **`sf_openflow_cdc_enable_table.sql`**: Creates the wrapper procedure that the connector calls to add a new capture instance during a schema transition. ```sql CREATE OR ALTER PROCEDURE dbo.sf_openflow_cdc_enable_table @source_schema sysname, @source_name sysname, @capture_instance sysname WITH EXECUTE AS OWNER AS BEGIN SET NOCOUNT ON; -- 1. Table must exist and not be a system table. IF OBJECT_ID(QUOTENAME(@source_schema) + N'.' + QUOTENAME(@source_name), N'U') IS NULL THROW 50001, 'Source table does not exist or is not a user table.', 1; -- 2. The connector supplies the full capture instance name. Validate that -- it is present and fits within the 100-character limit imposed by CDC. IF @capture_instance IS NULL OR LEN(@capture_instance) = 0 THROW 50002, 'Capture instance name must be provided.', 1; IF LEN(@capture_instance) > 100 THROW 50003, 'Capture instance name exceeds the 100-character limit.', 1; -- 3. Record the attempt. DECLARE @attempt_id uniqueidentifier = NEWID(); DECLARE @caller sysname = ORIGINAL_LOGIN(); INSERT INTO dbo.openflow_cdc_audit (attempt_id, event_time, event_kind, action, source_schema, source_name, capture_instance, caller) VALUES (@attempt_id, SYSUTCDATETIME(), 'attempt', 'enable', @source_schema, @source_name, @capture_instance, @caller); -- 4. Delegate to the engine procedure and record the outcome. BEGIN TRY EXEC sys.sp_cdc_enable_table @source_schema = @source_schema, @source_name = @source_name, @capture_instance = @capture_instance, @role_name = NULL; INSERT INTO dbo.openflow_cdc_audit (attempt_id, event_time, event_kind, action, source_schema, source_name, capture_instance, caller) VALUES (@attempt_id, SYSUTCDATETIME(), 'success', 'enable', @source_schema, @source_name, @capture_instance, @caller); END TRY BEGIN CATCH DECLARE @err_num int = ERROR_NUMBER(); DECLARE @err_msg nvarchar(4000) = ERROR_MESSAGE(); INSERT INTO dbo.openflow_cdc_audit (attempt_id, event_time, event_kind, action, source_schema, source_name, capture_instance, caller, error_number, error_message) VALUES (@attempt_id, SYSUTCDATETIME(), 'failure', 'enable', @source_schema, @source_name, @capture_instance, @caller, @err_num, @err_msg); ;THROW; END CATCH END; GO ``` 3. **`sf_openflow_cdc_disable_table.sql`**: Creates the wrapper procedure that the connector calls to drop the old capture instance after a schema transition completes. ```sql CREATE OR ALTER PROCEDURE dbo.sf_openflow_cdc_disable_table @source_schema sysname, @source_name sysname, @capture_instance sysname WITH EXECUTE AS OWNER AS BEGIN SET NOCOUNT ON; -- 1. The connector supplies the full capture instance name. Validate that it is present. IF @capture_instance IS NULL OR LEN(@capture_instance) = 0 THROW 50002, 'Capture instance name must be provided.', 1; -- 2. Record the attempt. DECLARE @attempt_id uniqueidentifier = NEWID(); DECLARE @caller sysname = ORIGINAL_LOGIN(); INSERT INTO dbo.openflow_cdc_audit (attempt_id, event_time, event_kind, action, source_schema, source_name, capture_instance, caller) VALUES (@attempt_id, SYSUTCDATETIME(), 'attempt', 'disable', @source_schema, @source_name, @capture_instance, @caller); -- 3. Delegate to the engine procedure and record the outcome. BEGIN TRY EXEC sys.sp_cdc_disable_table @source_schema = @source_schema, @source_name = @source_name, @capture_instance = @capture_instance; INSERT INTO dbo.openflow_cdc_audit (attempt_id, event_time, event_kind, action, source_schema, source_name, capture_instance, caller) VALUES (@attempt_id, SYSUTCDATETIME(), 'success', 'disable', @source_schema, @source_name, @capture_instance, @caller); END TRY BEGIN CATCH DECLARE @err_num int = ERROR_NUMBER(); DECLARE @err_msg nvarchar(4000) = ERROR_MESSAGE(); INSERT INTO dbo.openflow_cdc_audit (attempt_id, event_time, event_kind, action, source_schema, source_name, capture_instance, caller, error_number, error_message) VALUES (@attempt_id, SYSUTCDATETIME(), 'failure', 'disable', @source_schema, @source_name, @capture_instance, @caller, @err_num, @err_msg); ;THROW; END CATCH END; GO ``` 4. **`openflow_cdc_grants.sql`**: Grants the connector's database user permission to run the two wrapper procedures and to read the CDC metadata, change tables, and audit trail. Replace `` with the connector's database user created in [](#label-sql-server-cdc-connector-setup-instance), then run the script. ```sql SET NOCOUNT ON; -- Replace with the connector's SQL Server database user. DECLARE @connector sysname = N''; -- The principal must already exist in this database. IF DATABASE_PRINCIPAL_ID(@connector) IS NULL THROW 50100, 'Connector principal does not exist in this database. Create the user first, then re-run this script.', 1; DECLARE @sql nvarchar(max); -- 1. Allow the connector to call the two wrapper procedures. All CDC management -- goes through these wrappers, so no elevated role is required. SET @sql = N'GRANT EXECUTE ON dbo.sf_openflow_cdc_enable_table TO ' + QUOTENAME(@connector); EXEC sys.sp_executesql @sql; SET @sql = N'GRANT EXECUTE ON dbo.sf_openflow_cdc_disable_table TO ' + QUOTENAME(@connector); EXEC sys.sp_executesql @sql; -- 2. Allow the connector to read its own audit trail. SET @sql = N'GRANT SELECT ON dbo.openflow_cdc_audit TO ' + QUOTENAME(@connector); EXEC sys.sp_executesql @sql; -- 3. Allow the connector to enumerate capture instances and read CDC change tables. SET @sql = N'GRANT SELECT ON SCHEMA::cdc TO ' + QUOTENAME(@connector); EXEC sys.sp_executesql @sql; GO ``` The connector also needs `SELECT` on each replicated source table. SQL Server applies row-level filtering to `cdc.change_tables` for callers that don't hold `db_owner`, returning only rows for source tables that the caller can read. The `db_datareader` role granted in [](#label-sql-server-cdc-connector-setup-instance) satisfies this requirement. If access was scoped more tightly instead of using `db_datareader`, make sure the connector has `SELECT` on every source table that it replicates. 5. **Verify the deployment.** Confirm that the two wrapper procedures exist and that the audit table is queryable: ```sql SELECT name FROM sys.procedures WHERE name LIKE 'sf_openflow%'; SELECT TOP 1 1 FROM dbo.openflow_cdc_audit; ``` The first query returns both `sf_openflow_cdc_enable_table` and `sf_openflow_cdc_disable_table`. The second query confirms that the audit table exists and is readable. ## Set up your Snowflake environment As an Openflow administrator, perform the following tasks for this connector. With the default `SNOWFLAKE_MANAGED` authentication strategy, the runtime's execute-as role is the identity the connector uses to access Snowflake, so you grant these privileges to that role rather than creating a separate service user. 1. Create a database to store the replicated data, and grant the execute-as role [USAGE and CREATE SCHEMA](#label-database-privileges) on it. The connector creates destination schemas automatically. Snowflake recommends a dedicated destination database per connector, to avoid collisions with other data sources including other connectors. Keep this destination database separate from the database that holds your Openflow infrastructure objects, such as the runtime, the connector, and any secrets. A connector creates destination objects based on the source schema and table names, so those names aren't under your control and can change as the source changes. ```sql CREATE DATABASE IF NOT EXISTS ; GRANT USAGE ON DATABASE TO ROLE ; GRANT CREATE SCHEMA ON DATABASE TO ROLE ; ``` 2. Designate a warehouse for the connector to use, and grant the execute-as role **USAGE** and **OPERATE** on it. Start with the `XSMALL` warehouse size, then experiment with size depending on the number of tables being replicated, and the amount of data transferred. Large table numbers typically scale better with [multi-cluster warehouses](/user-guide/warehouses-multicluster), rather than the warehouse size. ```sql CREATE WAREHOUSE WITH WAREHOUSE_SIZE = 'XSMALL' AUTO_SUSPEND = 300 AUTO_RESUME = TRUE; GRANT USAGE, OPERATE ON WAREHOUSE TO ROLE ; ``` 3. **Snowflake deployments only:** Make sure this connector's source host and port are permitted by a network rule that your runtime's external access integration (EAI) allows. The EAI itself belongs to the runtime, not to this connector. You create it once, attach it to the runtime, and grant the execute-as role `USAGE` on it. For those steps, see [Creating network rules and external access integrations](/user-guide/data-integration/openflow/setup-openflow-spcs-create-rr#label-create-network-rules-and-external-access-integrations). What is specific to this connector is getting its source host into a rule that EAI references. The rule takes the source's host and port as a single value, such as `db.example.com:`. That's the host and port from the connector's connection URL, without the `jdbc:` scheme, the driver name, or the database path. BYOC deployments handle outbound connectivity in the cloud environment and don't use EAIs or network rules. For additional setup when you use key-pair authentication with BYOC: Key-pair authentication is available only for BYOC deployments, and is not required for the default `SNOWFLAKE_MANAGED` authentication strategy. Skip this section unless you set the connector's **Snowflake Authentication Strategy** parameter to `KEY_PAIR`. 1. Create a Snowflake user with the type as [SERVICE](#label-user-type-property), create a role for it, and grant that role the same destination database and warehouse privileges you granted the execute-as role: ```sql CREATE USER TYPE=SERVICE COMMENT='Service user for automated access of Openflow'; CREATE ROLE ; GRANT ROLE TO USER ; GRANT USAGE ON DATABASE TO ROLE ; GRANT CREATE SCHEMA ON DATABASE TO ROLE ; GRANT USAGE, OPERATE ON WAREHOUSE TO ROLE ; ``` 2. Create a pair of secure keys (public and private). Store the private key for the user in a file to supply to the connector's configuration. Assign the public key to the Snowflake service user: ```sql ALTER USER SET RSA_PUBLIC_KEY = 'thekey'; ``` For more information, see [pair of keys](/user-guide/key-pair-auth). When using `KEY_PAIR`, you must also set the connector's **Snowflake Account Identifier** and **Snowflake Connection Strategy** parameters. Both are left blank or ignored under `SNOWFLAKE_MANAGED`. ## Install the connector To install the connector, do the following as a data engineer: 1. Navigate to the Openflow overview page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find the connector and select **Install**. 3. In the **Select runtime** dialog, select your runtime from the **Available runtimes** drop-down list and click **Install**. Before you install the connector, ensure that you have created a database and schema in Snowflake for the connector to store ingested data. 4. Authenticate to the deployment with your Snowflake account credentials and select **Allow** when prompted to allow the runtime application to access your Snowflake account. The connector installation process takes a few minutes to complete. 5. Authenticate to the runtime with your Snowflake account credentials. The Openflow canvas appears with the connector process group added to it. ## Runtime sizing The runtime size determines the CPU, memory, and disk available to the connector. The available sizes are Small, Medium, and Large. Choose the size when you create the runtime: you can't change the size of an existing runtime in place. Size the runtime based on the sustained workload it needs to handle across all connectors running on it. Sustained means typical steady-state throughput, not peak. Peak load can temporarily increase connector queues and end-to-end replication latency; the workload catches up when the load drops back to the steady-state level. The following ranges are starting points based on internal benchmarks and production customer data. They aren't service guarantees. Your fit depends on row size, event distribution, schema width, and source burstiness. Start at the lower bound, measure runtime CPU, memory, queue depth, and end-to-end replication latency in production, then increase from there. - Light workload (aggregate sustained throughput below approximately 1,000 events per second, fewer than approximately 100 actively changing tables): a Small runtime can host a single low-volume connector. Pack additional connectors on Small only when each source is genuinely light. - Moderate workload (approximately 1,000 to 5,000 events per second, hundreds of actively changing tables): a Medium runtime can typically host 5 to 8 connectors. - Heavy workload (approximately 5,000 to 15,000 events per second, hundreds to low thousands of actively changing tables): a Large runtime can typically host 15 or more connectors. If you want a smaller blast radius, split across two Medium runtimes instead. ## Running multiple connectors on one runtime You can run multiple CDC connector instances on a single runtime. This is useful for replicating many small databases, for example a multi-tenant SaaS with one database per tenant, or a fleet of operational databases per business unit or region. When you run multiple CDC connector instances of the same type on one runtime, keep their shared Source and Destination parameter contexts intact and override only the per-connector values in each Ingestion context. For the recommended process, see [](#run-multiple-connectors-on-one-runtime). Run a connector on a dedicated runtime, not packed with others, when any of the following applies: - A single source sustains more than approximately 15,000 events per second. - You need sub-1-minute end-to-end replication latency under load. - You can't tolerate noisy-neighbor effects from other sources sharing the runtime. Each replicated table can consume two Snowpipe Streaming pipes: one for snapshot replication and one for incremental replication. As you pack more tables onto a runtime, check your account's [Snowpipe Streaming pipe limit](/user-guide/snowpipe-streaming/snowpipe-streaming-high-performance-limitations#pipe-limits) and raise it before you approach the cap. ## Resize a runtime Runtime size is fixed at creation, so to change size you run the connector on a different runtime. You have two options depending on whether you want to preserve the current replication progress. If you don't need to keep the progress of the current connector, the simplest path is to create a new runtime at the size you need and install a new connector instance on it. The new connector starts from scratch: it snapshots all configured tables and then captures ongoing changes from that point. The replication progress of the existing connector is discarded. To keep the progress of the current connector, for example to avoid re-snapshotting tables that took a long time to snapshot initially, migrate the connector to the new runtime. This reuses the existing destination tables and resumes incremental replication from where it left off. For migration instructions, see [Reinstall the connector](#label-sql-server-cdc-reinstall-connector). ## Configure the connector To configure the connector, do the following as a data engineer: 1. Right-click on the imported process group and select **Parameters**. 2. Populate the required parameter values. For more information on the required parameter values, see the following sections: - [](#label-of-sqlserver-cdc-source-parameters): Used to establish a connection with SQL Server. - [](#label-of-sqlserver-cdc-destination-parameters): Used to establish a connection with Snowflake. - [](#label-of-sqlserver-cdc-ingestion-parameters): Used to specify the tables to replicate. Start by setting the parameters of the SQLServer Source Parameters context, then the SQLServer Destination Parameters context. After you complete this, enable the connector. The connector connects to both SQL Server and Snowflake and starts running. However, the connector doesn't replicate any data until tables to be replicated are explicitly added to its configuration. To configure specific tables for replication, edit the SQLServer Ingestion Parameters context. After you apply the changes to the SQLServer Ingestion Parameters context, the configuration is picked up by the connector, and the replication lifecycle starts for every table. To run multiple CDC connector instances on one runtime, see [](/user-guide/data-integration/openflow/connectors/cdc-runtime-sizing#run-multiple-connectors-on-one-runtime). ### SQLServer Source Parameters
To connect with Windows authentication using NTLMv2, configure the SQL Server source parameters as follows: - **SQLServer Connection URL**: `jdbc:sqlserver://:1433;databaseName=;integratedSecurity=true;authenticationScheme=NTLM;domain=;` - **SQLServer JDBC Driver**: Upload the `mssql-jdbc` JAR. The driver class name is `com.microsoft.sqlserver.jdbc.SQLServerDriver`. - **SQLServer Username**: Enter the domain user. - **SQLServer Password**: Enter the domain password. Azure SQL Database refers to the single-database PaaS offering, not Azure SQL Managed Instance. ### Always On Availability Groups Configure the connector to connect through the availability group **listener** (the virtual network name for the group), not through an individual replica node. Set the listener hostname in the **SQLServer Connection URL** parameter in the SQLServer Source Parameters context. Always On Availability Groups (https://learn.microsoft.com/sql/database-engine/availability-groups/windows/overview-of-always-on-availability-groups-sql-server) provide high availability through a shared listener and automatic failover between replicas. Always On Availability Groups are separate from SQL Server transactional replication. Do not change the connection target after replication has started. Each database maintains its own replication position independently, so switching to a different server or listener can cause the connector to lose track of which changes have already been processed. This might result in data loss. For `ApplicationIntent` in the JDBC URL on Always On Availability Groups: To route reads to a readable secondary, append `;ApplicationIntent=ReadOnly` to the **SQLServer Connection URL** when read-only routing is configured on the availability group listener. On topologies that do not expose a readable secondary (for example, AWS RDS Multi-AZ with a single endpoint), the driver connects to the primary even when `ApplicationIntent=ReadOnly` is set. When connections are routed to a readable secondary, the connector reads from CDC change tables on that replica. Those tables reflect changes only after capture lag and redo lag on the primary, so replication latency can be higher than when you connect to the primary. To reduce lag, tune SQL Server CDC capture and availability group redo settings on the primary. During availability group failovers, replication resumes automatically and tables are not moved to `FAILED`. During each failover window, the connector logs a transient error that the database is not accessible for queries while data movement is suspended or a replica is not enabled for read access. This error is expected during the transition; the connector retries and recovers once failover completes. To connect to the primary through the listener without read-only routing, omit `ApplicationIntent` or use the default `ReadWrite` intent. For failover behavior, see [Always On Availability Groups and source failover](/user-guide/data-integration/openflow/connectors/sql-server-cdc/about#label-sqlserver-source-failover-resilience). ### SQLServer Destination Parameters
### SQLServer Ingestion Parameters
## Read the source under SNAPSHOT isolation During the snapshot phase, the connector reads directly from the source tables to perform the initial full copy. Under SQL Server's default READ COMMITTED isolation level, these reads acquire shared locks that can deadlock with concurrent writes from other database clients. During incremental replication, the connector reads from dedicated CDC change tables instead of the source tables, so it doesn't take these locks. To avoid deadlocks during the snapshot phase without affecting the isolation level that other applications use, configure the connector to read under SNAPSHOT isolation (https://learn.microsoft.com/en-us/dotnet/framework/data/adonet/sql/snapshot-isolation-in-sql-server). For background, see [Source database locking behavior](/user-guide/data-integration/openflow/connectors/sql-server-cdc/about#label-sql-server-cdc-source-database-locking-behavior). Enable SNAPSHOT isolation for the connector in two steps: 1. On each source database, allow snapshot isolation: ```sql ALTER DATABASE SET ALLOW_SNAPSHOT_ISOLATION ON; ``` 2. Add a dynamic property named **Use Snapshot Isolation** with the value `true` to the `MultiDatabaseFetchTableSnapshot` processor. Only the snapshot phase takes shared locks on the source tables, so incremental replication doesn't require the **Use Snapshot Isolation** property. The connector checks each source database when it starts and uses SNAPSHOT isolation only for databases that have `ALLOW_SNAPSHOT_ISOLATION` enabled. For a database that doesn't have it enabled, the connector falls back to the default isolation level. Because this check runs at startup, restart the processor after you change `ALLOW_SNAPSHOT_ISOLATION`. `ALLOW_SNAPSHOT_ISOLATION` only makes SNAPSHOT isolation available to sessions that explicitly request it, such as the connector. It doesn't change the default READ COMMITTED isolation level, so other applications that use the source database are unaffected. Don't use `READ_COMMITTED_SNAPSHOT` (RCSI) for this purpose. Although RCSI also removes the shared locks, it redefines the default READ COMMITTED isolation level for every connection to the database. Applications that rely on the default lock-based READ COMMITTED behavior (for example, expecting readers to block on concurrent uncommitted writes) can see different results after the change. ## Replicate a subset of columns in a table The connector can filter the data replicated per table to a subset of configured columns. Primary key columns are always included regardless of exclusions. To apply column filters, set the **Column Filter JSON** parameter in the Ingestion Parameters context to a JSON array of filter objects, one per table you want to filter. Columns can be included or excluded by name or by regular expression pattern. You can apply a single condition per table, or combine multiple conditions, with exclusions always taking precedence over inclusions. ## Syntax Each object in the array identifies a table and specifies which columns to include or exclude. Because this connector uses three-part fully qualified names (database, schema, and table), each object can include a `database` or `databasePattern` field in addition to the schema and table fields. ```javascript [ { "database": "" | "databasePattern": "", "schema": "" | "schemaPattern": "", "table": "
Parameter Description
SQLServer Connection URL The full JDBC URL used to connect to the source. For a standalone SQL Server instance or Azure SQL Managed Instance, point the URL at the instance. The connector discovers the databases to replicate from that instance. - `jdbc:sqlserver://example.com:1433;encrypt=false` For Always On Availability Groups, see [Always On Availability Groups](#label-sql-server-availability-groups). For Azure SQL Database, point the URL at a specific database using the `databaseName` property. Use one connector instance per database you want to replicate. - `jdbc:sqlserver://your-server.database.windows.net:1433;encrypt=true;databaseName=your_database`
SQLServer JDBC Driver Select the **Reference asset** checkbox to upload the SQL Server JDBC driver (https://learn.microsoft.com/sql/connect/jdbc/download-microsoft-jdbc-driver-for-sql-server).
SQLServer Username The username for the connector.
SQLServer Password The password for the connector.
SQLServer Query Interval The minimum time interval that must elapse before scheduling the next query for table changes. This controls the frequency of database polling during incremental replication to prevent excessive querying. Default: `10 sec`.
Parameter Description Required
Destination Database The database where data is persisted. It must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. Yes
Destination Schema Pattern A pattern for the names of destination schemas where data is persisted. The connector creates the schemas if they don't exist. You can customize the pattern per ingested table using these optional variables: - `${source.database.name}`: a source table's database. - `${source.schema.name}`: a source table's schema. - `${source.table.name}`: a source table's name. For example, for a table with the qualified name `source_db.tenant_a.data`, the pattern `prefix_${source.database.name}_${source.schema.name}` evaluates to `prefix_source_db_tenant_a`. To ingest all tables into a single schema, provide a schema name without any variables, like `destination_schema`. Don't change this setting after the connector has begun ingesting data. Changing this setting after ingestion has begun breaks the existing ingestion. If you must change this setting, create a new connector instance. Yes
Snowflake Authentication Strategy When using: - **Snowflake Openflow Deployment** or **BYOC**: Use SNOWFLAKE_MANAGED. This token is managed automatically by Snowflake. BYOC deployments must have previously configured [execute-as roles](#label-deployment-byoc-setup-runtime-role) to use SNOWFLAKE_MANAGED. - **BYOC**: Alternatively, BYOC can use KEY_PAIR as the value for the authentication strategy. Yes
Snowflake Account Identifier When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Snowflake account name formatted as [organization-name]-[account-name]. Yes
Snowflake Connection Strategy When using KEY_PAIR, specify the strategy for connecting to Snowflake: - **STANDARD** (default): Connect using standard public routing to Snowflake services. - **PRIVATE_CONNECTIVITY**: Connect using private addresses associated with the supporting cloud platform such as AWS PrivateLink. Required for BYOC with KEY_PAIR only, otherwise ignored.
Snowflake Object Identifier Resolution Specifies how source object identifiers such as schemas, tables, and column names are stored and queried in Snowflake. This setting dictates whether you must use double quotes in SQL queries.

Option 1: Default, case-insensitive (recommended).

- **Transformation**: All identifiers are converted to uppercase. For example, `My_Table` becomes `MY_TABLE`. - **Queries**: SQL queries are case-insensitive and don't require SQL double quotes. For example, `SELECT * FROM my_table;` returns the same results as `SELECT * FROM MY_TABLE;`. Snowflake recommends using this option if database objects are not expected to have mixed case names. Do not change this setting after connector ingestion has begun. Changing this setting after ingestion has begun breaks the existing ingestion. If you must change this setting, create a new connector instance.

Option 2: Case-sensitive.

- **Transformation**: Case is preserved. For example, `My_Table` remains `My_Table`. - **Queries**: SQL queries must use double quotes to match the exact case for database objects. For example, `SELECT * FROM "My_Table";`. Snowflake recommends using this option if you must preserve source casing for legacy or compatibility reasons. For example, the source database includes table names that differ in case only, such as `MY_TABLE` and `my_table`, which result in a name collision when using case-insensitive comparisons.
Yes
Snowflake Private Key When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. -
**KEY_PAIR**: Must be the RSA private key used for authentication.
The RSA key must be formatted according to PKCS8 standards and have standard PEM headers and footers. Note that either a Snowflake Private Key File or a Snowflake Private Key must be defined.
No
Snowflake Private Key File When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: The private key file must be blank. - **KEY_PAIR**: Upload the file that contains the RSA private key used for authentication to Snowflake, formatted according to PKCS8 standards and including standard PEM headers and footers. The header line begins with `-----BEGIN PRIVATE`. To upload the private key file, select the **Reference asset** checkbox. No
Snowflake Private Key Password When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the password associated with the Snowflake Private Key File. No
Snowflake Role When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Use the runtime's execute-as role (or a child role granted to it). You can find your execute-as role in the Openflow UI by navigating to **View Details** for your runtime. - **KEY_PAIR**: Use a valid role configured for your service user. Yes
Snowflake Username When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the user name used to connect to the Snowflake instance. Yes
Oversized Value Strategy Determines how the connector handles values that exceed its internal size limits (16 MB) during replication. Possible values are:
- **Fail Table** (default): The table is marked as permanently failed, and replication stops for that table. - **Set Null**: The value is replaced with `NULL` in the destination table. Use this to prevent table failures when it is acceptable to lose data in tables beyond the oversized value.
No
Table Storage Format Standard Snowflake tables or Iceberg tables. Defaults to **STANDARD**. Don't change after the connector starts. Yes
Iceberg Version The Iceberg table version, 2 or 3 (default 3). Ignored unless Table Storage Format is **ICEBERG**. Don't change this value after ingestion begins. No
Snowflake Warehouse Snowflake warehouse used to run queries. Yes
Parameter Description
Column Filter JSON Optional. A JSON array of filter objects specifying which columns to include or exclude per table. For syntax details and examples, see [Replicate a subset of columns in a table](#replicate-a-subset-of-columns-in-a-table).
Concurrent Select Queries For Incremental Maximum number of concurrent SELECT queries to run against the source database during incremental replication. Default: `1`, maximum: `8`. Increasing this can speed up replication when many tables are active, but will also increase the load on the source database.
Concurrent Select Queries For Snapshot Maximum number of concurrent queries to the source database to run in the Snapshot flow. Increasing this can speed up snapshotting large numbers of tables, but will also increase the load on the source database.
Included Table Names A comma-separated list of source table paths, including their databases and schemas, for example: `database_1.public.table_1, database_2.schema_2.table_2`
Included Table Regex A regular expression to match against table paths, including database and schema names. Every path matching the expression is replicated, and new tables matching the pattern that are created later are also included automatically, for example: `database_name\.public\.auto_.*`
Ingestion Type Controls whether newly added tables go through a full initial snapshot before switching to incremental CDC replication, or skip the snapshot and begin incremental CDC replication only. Set to `full` (default) for snapshot followed by incremental replication. Set to `incremental` to skip the snapshot for newly added tables and replicate only subsequent changes. Changing this value does not affect tables that have already begun replicating. For usage notes, see [Set up incremental replication without snapshots](/user-guide/data-integration/openflow/connectors/sql-server-cdc/incremental-replication).
Merge Task Schedule CRON CRON expression defining periods when merge operations from Journal to Destination Table will be triggered. Set it to `* * * * * ?` if you want continuous merges, or configure a time schedule to limit warehouse run time. The connector evaluates the schedule in the UTC time zone. For example:
- The string `* 0 * * * ?` indicates that you want to schedule merges at the full hour for one minute. - The string `* 20 14 ? * MON-FRI` indicates that you want to schedule merges at 2:20 PM every Monday through Friday.
For additional information and examples, see the cron triggers tutorial in the Quartz Documentation (https://www.quartz-scheduler.org/documentation/quartz-2.5.x/tutorials/crontrigger.html).
Re-read Tables in State Only applicable when **Starting CDC Position** is `Earliest`.
- `New` (default): Only new tables, added after the starting position was switched to `Earliest`, will have their CDC change tables read from the earliest available positions. Tables that started replication before the configuration change will continue reading from their last positions. - `Any active`: Re-read and re-process changes from any table currently in replication.
For more information, see [Specify load from CDC position](/user-guide/data-integration/openflow/connectors/sql-server-cdc/maintenance#label-sql-server-cdc-connector-start-restart-incremental-load-from-earliest-available-position).
Re-snapshot Table Exclusions A comma-separated list of fully qualified table names that should not be replicated, from among tables matching the included criteria. Use the same format and quoting rules as **Included Table Names**, for example: `database_1.public.table_1`.
SQL Server Read Timeout Read timeout in milliseconds applied to both snapshot and incremental queries. A query that runs longer than this value is closed by SQL Server. Default: `60000`.
Starting CDC Position
- `Latest` (default): CDC change table reading starts at the latest available position and continues from there. - `Earliest`: Switches the incremental load to start, or restart reading from the earliest available CDC change table positions.
For more information, see [Specify load from CDC position](/user-guide/data-integration/openflow/connectors/sql-server-cdc/maintenance#label-sql-server-cdc-connector-start-restart-incremental-load-from-earliest-available-position).
Table Key Configuration JSON Optional. A JSON array that declares a logical key for one or more tables. When set, the logical key takes the highest priority and overrides any primary key, unique constraint, or unique index that the connector would otherwise auto-detect. The connector reads this parameter through its `MultiDatabaseJsonTableKeyConfigService` controller service. For syntax details and examples, see [](#label-sqlserver-cdc-logical-key).
" | "tablePattern": "", "included": ["", ""], "excluded": ["", ""], "includedPattern": "", "excludedPattern": "" } ] ``` The following rules apply: - Use `database`, `schema`, and `table` for exact name matching, or `databasePattern`, `schemaPattern`, and `tablePattern` for regex matching. You can't use both a field and its pattern variant in the same object (for example, `schema` and `schemaPattern` can't both appear). - At least one of `included`, `excluded`, `includedPattern`, or `excludedPattern` must be provided. - When both included and excluded filters are specified, exclusions take precedence. - When multiple filters match the same table, the last matching filter is used, with exact matches taking precedence over pattern-based filters. - The value can be an array of objects to apply different filters to different tables. ## Examples Include specific columns by name: ```javascript [ { "database": "my_db", "schema": "dbo", "table": "orders", "included": ["account_id", "status", "created_at"] } ] ``` Exclude specific columns by name: ```javascript [ { "database": "my_db", "schema": "dbo", "table": "orders", "excluded": ["internal_note", "debug_flag"] } ] ``` Combine an include pattern with a specific exclusion (for example, include all email columns except `admin_email`): ```javascript [ { "database": "my_db", "schema": "dbo", "table": "contacts", "includedPattern": ".*_email", "excluded": ["admin_email"] } ] ``` Mix a database pattern with an exact schema and table name to apply a filter across databases: ```javascript [ { "databasePattern": "prod_.*", "schema": "dbo", "table": "customers", "excluded": ["internal_note"] } ] ``` Pass multiple filter objects to apply different rules to different tables: ```javascript [ {"database": "my_db", "schema": "dbo", "table": "orders", "included": ["account_id", "status"]}, {"database": "my_db", "schema": "dbo", "table": "customers", "excludedPattern": ".*_internal"} ] ``` ### Including and excluding the same column Removing a column from a table's replicated set (by excluding it or by removing it from the included list) has the same effect on the destination as dropping the column at the source: the connector soft-deletes the column on the destination by renaming it with a suffix (by default, `__SNOWFLAKE_DELETED`). If you then add the column back to the replicated set and later remove it a second time, replication for the affected table fails because the soft-deleted column name is already taken. To recover, restart replication for the affected table. ## Replicate a partitioned table The connector supports replication of partitioned tables. A SQL Server partitioned table is replicated into Snowflake as a single destination table, containing data from all partitions. To replicate a partitioned table, ensure that CDC is enabled on the partitioned table, as described in [](#label-sql-server-cdc-connector-setup-instance). For more information about how the connector handles snapshots of large partitioned tables, see [Snapshot of partitioned tables](/user-guide/data-integration/openflow/connectors/sql-server-cdc/about#label-sql-server-cdc-partitioned-snapshot). ## Specify a logical key for a table The connector requires a replication key for every table it replicates. By default, the connector uses the table's primary key, or falls back to a qualifying unique constraint or unique index if no primary key exists. For the full priority order the connector uses to choose a key, see [How the connector chooses a replication key](/user-guide/data-integration/openflow/connectors/sql-server-cdc/about#label-sqlserver-cdc-replication-key-selection). A *logical key* is a user-declared replacement for the auto-detected key. Configure a logical key when: - A table has no primary key, but one or more columns are unique in the data. - A specific column or set of columns should be used as the replication key, regardless of what the connector would auto-detect (for example, to override a synthetic primary key). A logical key takes the highest priority. When the connector finds a logical key for a table, it uses that key and ignores any primary key on the table. ### JSON syntax The **Table Key Configuration JSON** value is a JSON array. Each entry maps one table to its logical key columns: ```json [ { "database": "", "schema": "", "table": "
", "logicalKey": ["", ""] } ] ``` The fields are:
The following rules apply: - `database`, `schema`, and `table` matching is **case-sensitive**. Use the exact names as reported by SQL Server. - `logicalKey` column names are matched **case-insensitively**: the connector lowercases both the configured names and the source column names before comparing them. On a case-sensitive SQL Server collation this matching is lenient. A key whose case differs from the actual column is still accepted, and two source columns that differ only by letter case are treated as the same key column. Use the exact column case to avoid ambiguity. - An entry whose `database`, `schema`, and `table` don't match any replicated table is silently ignored. ### Logical key configuration examples A single-column logical key on a table without a primary key: ```json [ { "database": "SalesDB", "schema": "dbo", "table": "audit_log", "logicalKey": ["event_id"] } ] ``` A composite logical key: ```json [ { "database": "SalesDB", "schema": "dbo", "table": "order_lines", "logicalKey": ["order_id", "line_item_id"] } ] ``` Logical keys for several tables in one JSON value: ```json [ { "database": "SalesDB", "schema": "dbo", "table": "audit_log", "logicalKey": ["event_id"] }, { "database": "SalesDB", "schema": "dbo", "table": "order_lines", "logicalKey": ["order_id", "line_item_id"] } ] ``` ### Restrictions The connector rejects the configuration when any of the following is true: - `logicalKey` is missing, empty, or not an array. - `logicalKey` contains duplicate column names. - `logicalKey` contains a nullable column. Logical key columns must be defined as `NOT NULL` to reliably identify rows. - `logicalKey` contains a column name that doesn't exist in the source table. When the configuration is rejected, verification surfaces a clear error and the table stays in the `NEW` state (never `FAILED`). After you fix the configuration, replication for the table resumes without resetting state. ### Warnings logged for risky configurations The connector accepts the following configurations but logs a warning at table initialization. When choosing logical-key columns, prefer columns with high cardinality and, where possible, monotonically increasing values. Low-cardinality or non-monotonic keys can degrade snapshot performance. - A logical-key column is a floating-point type (`float`, `real`). Floating-point comparisons can produce inconsistent results because of precision differences. - A logical-key column is a large-object type (`text`, `image`, `varbinary(max)`). Using large objects as keys severely degrades MERGE performance. - The composite logical key includes more than five columns. Long composite keys often indicate a design issue and might degrade MERGE performance. - The logical key overrides an existing primary key on the table. Verify that the replacement key is intentional: the connector no longer uses the primary key for MERGE operations. If you observe data divergence after any of these warnings, run a periodic full reload to reconcile the destination with the source. ### Schema changes that affect a logical key The connector doesn't track schema evolution of the unique or logical key columns after the CDC capture instance exists. Dropping or altering a logical-key column isn't detected at runtime: - If a logical-key column is dropped on the source, replication for the affected table fails. Restart table replication to recover. For more information, see [Restart table replication](/user-guide/data-integration/openflow/connectors/sql-server-cdc/maintenance#label-of-sql-server-cdc-restart-table-replication). - If a logical-key column is renamed on the source, the configuration still references the old name and replication fails. Update the JSON to use the new name and restart table replication. ## Track data changes in tables The connector replicates the current state of data from the source tables, as well as detected changes from each polling interval. This data is stored in journal tables created in the same schema as the destination table. The journal table names are formatted as: `_JOURNAL__` where `` is the value of epoch seconds when the source table was added to replication, and `` is an integer increasing with every schema change on the source table. As a result, source tables that undergo schema changes will have multiple journal tables. When you remove a table from replication, then add it back, the `` value changes, and `` starts again from `1`. Snowflake recommends not altering the structure of journal tables in any way. The connector uses them to update the destination table as part of the replication process. The connector never drops journal tables, but uses the latest journal for every replicated source table, only reading append-only streams on top of journals. To reclaim the storage, you can: - Truncate all journal tables at any time. - Drop the journal tables related to source tables that were removed from replication. - Drop all but the latest generation journal tables for actively replicated tables. For example, if your connector is set to actively replicate source table `orders`, and you have earlier removed table `customers` from replication, you may have the following journal tables. In this case you can drop all of them *except* `orders_5678_2`. ```text customers_1234_1 customers_1234_2 orders_5678_1 orders_5678_2 ``` ## Configure scheduling of merge tasks The connector uses a warehouse to merge change data capture (CDC) data into destination tables. The processor named Merge Journal to Destination triggers this operation. When there are no new changes, or when no new FlowFiles are waiting in the Merge Journal to Destination queue, no merge is triggered and the warehouse is available for auto-suspension. To limit warehouse cost and restrict merges to scheduled times, use the CRON expression in the Merge Task Schedule CRON parameter. It throttles the FlowFiles that reach the Merge Journal to Destination processor, so merges are triggered only during the specified period. The connector evaluates the schedule in the UTC time zone. For additional information and examples, see the cron triggers tutorial in the Quartz Documentation (https://www.quartz-scheduler.org/documentation/quartz-2.5.x/tutorials/crontrigger.html). ## Run the flow 1. Right-click on the canvas and select **Enable all Controller Services**. 2. Right-click on the imported process group and select **Start**. The connector starts the data ingestion. --- title: Set up the Openflow Connector for Workday source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/workday/setup.md section: Loading & Unloading Data --- # Set up the Openflow Connector for Workday This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) This topic describes the steps to set up the Openflow Connector for Workday. ## Prerequisites 1. Ensure that you have reviewed [About Openflow Connector for Workday](/user-guide/data-integration/openflow/connectors/workday/about). 2. Ensure that you have [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) or [Set up Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/setup-openflow-spcs). 3. If using %ofsfspcs-plural%, ensure that you've reviewed [configuring required domains](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list) and have granted access to the required domains for the [](#label-openflow-domains-used-by-openflow-connectors-workday) connector. ## Get the credentials As a Workday administrator, perform the following actions: 1. Create a user in Workday: 1. Go to Workday and log in as an administrator. In the Workday search bar, type **Create user**. 2. Click **Create Integration System User: Task**. 3. Enter a username and password. 2. Create a security group and add the user from step 1 to it: 1. In the Workday search bar, type **Create Security Group**. 2. Click **Create Security Group: Task**. 3. Set the type to **Integration System Security Group (Unconstrained)**. 4. Enter a Security Group Name and click **OK**. 5. In the **Edit Integration System Security Group (Unconstrained)** window, add the integration system user created in Step 1 in the **Integration System Users** field. 3. Add domain security policies to the security group created on step 2: 1. In the Workday search bar, type **View Security Group**. 2. Go to **Security Group Settings** %raa% **Maintain Domain Permissions for Security Group**. 3. In the **Integration Permissions** section, in the Domain Security Policies permitting Get access field, select the security domains associated with the reports you want to sync. 4. Go to the **Activate Pending Security Policy Changes** page and click **OK**. 4. Create an OAuth client app: 1. In the Workday search bar, type **Register API Client**, and click **Register API Client for Integrations: Task**. 2. Enter a Client Name. 3. Click **Non-Expiring Refresh Token**. 4. In the Scope search bar, type **System** and select it. 5. Click **OK**. 6. Copy the Client ID and Client Secret, then click **Done**. 5. In the **View Integration System Security Group** page, note the functional areas under Domain Security Policies. Then, add these as Scopes/Functional Areas in the API Client: 1. In the search bar, type **View API Client**. 2. Choose your API client from the list. 3. In the top blue bar, click the three dots, then select **API Client** %raa% **API Clients for Integrations**. 4. In the **Scope (Functional Areas)** field, search for and add the functional areas that you noted. 6. In the same menu as before (5c), select **Manage Refresh Tokens for Integrations**. 1. In the form, search for the ISU user and select it. 2. Click **OK**. 3. Click **Generate new token** and copy the refresh token details which will be used later. ## Set up Snowflake account As a Snowflake account administrator, perform the following tasks: 1. Create a new role or use an existing role and grant the [](#label-database-privileges). 2. Create a new Snowflake service user with the type as [SERVICE](#label-user-type-property). 3. Grant the Snowflake service user the role you created in the previous steps. 4. Configure with [key-pair auth](/user-guide/key-pair-auth) for the Snowflake SERVICE user from step 2. 5. Snowflake strongly recommends this step. Configure a secrets manager supported by Openflow, for example, AWS, Azure, and Hashicorp, and store the public and private keys in the secret store. If for any reason, you do not wish to use a secrets manager, then you are responsible for safeguarding the public key and private key files used for key-pair authentication according to the security policies of your organization. 1. Once the secrets manager is configured, determine how you will authenticate to it. On AWS, it's recommended that you the EC2 instance role associated with Openflow as this way no other secrets have to be persisted. 2. In Openflow, configure a Parameter Provider associated with this Secrets Manager, from the hamburger menu in the upper right. Navigate to **Controller Settings** %raa% **Parameter Provider** and then fetch your parameter values. 3. At this point all credentials can be referenced with the associated parameter paths and no sensitive values need to be persisted within Openflow. 6. If any other Snowflake users require access to the raw ingested documents and tables ingested by the connector (for example, for custom processing in Snowflake), then grant those users the role created in step 1. 7. Designate a warehouse for the connector to use. Start with the smallest warehouse size, then experiment with size depending on the number of tables being replicated, and the amount of data transferred. Large table numbers typically scale better with [multi-cluster warehouses](/user-guide/warehouses-multicluster), rather than larger warehouse sizes. ## Set up the connector As a data engineer, perform the following tasks to configure the connector: ### Install the connector 1. Create a database and schema in Snowflake for the connector to store ingested data. Grant required [](#label-database-privileges) to the role created in the first step. Substitute the role placeholder with the actual value and use the following SQL commands: ```sql CREATE DATABASE DESTINATION_DB; CREATE SCHEMA DESTINATION_DB.DESTINATION_SCHEMA; GRANT USAGE ON DATABASE DESTINATION_DB TO ROLE ; GRANT USAGE ON SCHEMA DESTINATION_DB.DESTINATION_SCHEMA TO ROLE ; GRANT CREATE TABLE, CREATE PIPE ON SCHEMA DESTINATION_DB.DESTINATION_SCHEMA TO ROLE ; ``` To install the connector, do the following as a data engineer: 1. Navigate to the Openflow overview page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find the connector and select **Install**. 3. In the **Select runtime** dialog, select your runtime from the **Available runtimes** drop-down list and click **Install**. Before you install the connector, ensure that you have created a database and schema in Snowflake for the connector to store ingested data. 4. Authenticate to the deployment with your Snowflake account credentials and select **Allow** when prompted to allow the runtime application to access your Snowflake account. The connector installation process takes a few minutes to complete. 5. Authenticate to the runtime with your Snowflake account credentials. The Openflow canvas appears with the connector process group added to it. ### Configure the connector 1. Right-click on the imported process group and select **Parameters**. 2. Populate the required parameter values as described in [Flow parameters](#flow-parameters). #### Flow parameters The configuration is divided into three parameter contexts. The *Workday Destination Parameters* and *Workday Source Parameters* contexts are responsible for connecting with Snowflake and Workday. The *Workday Ingestion Parameters* contains all parameters from both configs and other parameters specific to a given report (e.g., *Report URL*). Because the *Workday Ingestion Parameters* parameter context contains report-specific details, new parameter contexts must be created for each new report and process group. To create a new parameter context, go to the menu, select **Parameter Contexts**, and add a new context. It should inherit from both the *Workday Destination Parameters* and *Workday Source Parameters* parameter contexts. **Workday Destination Parameters** **parameter context**
**Workday Source Parameters** **parameter context**
**Workday Ingestion Parameters** **parameter context**
## Run the flow 1. Right-click on the plane and select **Enable all Controller Services**. 2. Right-click on the imported process group and select **Start**. The connector starts the data ingestion. --- title: Set up the Salesforce Data Cloud Zerocopy Connector source: https://docs.snowflake.cn/en/user-guide/data-integration/zero-copy/salesforce/setup.md section: Loading & Unloading Data --- # Set up the Salesforce Data Cloud Zerocopy Connector - [About Salesforce Data Cloud and Snowflake](/user-guide/data-integration/zero-copy/about-salesforce-datacloud) - [Set up Salesforce Data Cloud for Zero-Copy](/user-guide/data-integration/zero-copy/salesforce/setup-salesforce) - [Salesforce Data Cloud Zerocopy Connector: Security and privileges](/user-guide/data-integration/zero-copy/salesforce/security) - [Explore data products from Salesforce Data Cloud](/user-guide/data-integration/zero-copy/salesforce/explore-data-products) This topic describes how to create the Zerocopy Connector for Salesforce Data Cloud on the Snowflake side and retrieve the Enrollment ID needed to authorize the connection. Complete these steps first. Once you have the Enrollment ID, provide it to your Salesforce administrator to complete the Salesforce-side setup. See [Set up Salesforce Data Cloud for Zero-Copy](/user-guide/data-integration/zero-copy/salesforce/setup-salesforce). For the privileges required for each operation, see [Security and privileges](/user-guide/data-integration/zero-copy/salesforce/security). ## Prerequisites The role used to create the connector must have `CREATE ZEROCOPY CONNECTOR` on the target schema. By default, the owner role of a schema has this privilege. ## Create a database and schema A Zerocopy Connector is a schema-level object. Before creating one, ensure you have a target database and schema, or create new ones. For reference, see [CREATE DATABASE](/sql-reference/sql/create-database) and [CREATE SCHEMA](/sql-reference/sql/create-schema). ```sql CREATE DATABASE IF NOT EXISTS my_db; CREATE SCHEMA IF NOT EXISTS my_db.my_schema; ``` ## Create a Zerocopy Connector You can create the connector using the Snowsight UI or SQL. ### Using Snowsight 1. In Snowsight, navigate to **Ingestion** %raa% **Zero-Copy**. 2. Select the **Overview** tab. 3. On the **Salesforce Data 360 Connect for Snowflake** card, click **Connect**. 4. In the **Connection details** panel: - **Connector name**: Enter a name, or use the auto-generated name (for example, `SALESFORCE_CONNECT_1785545041895`). - **Connector location**: Select the schema where the connector will be installed. 5. Click **Create connector**. After creation, Snowsight displays an **Enrollment ID** in the **Establish connection to Salesforce** panel. Copy this value — you will provide it to your Salesforce administrator in the next step. ### Using SQL ```sql CREATE ZEROCOPY CONNECTOR IF NOT EXISTS my_db.my_schema.my_sfdc_connector PARTNER = SALESFORCE; ``` After creation, the connector is in `NEW` state. Retrieve the Enrollment ID using: ```sql SELECT SYSTEM$GET_ZEROCOPY_CONNECTOR_CONFIG('my_db.my_schema.my_sfdc_connector'); ``` The output includes an `enrollment_code` value. Copy it and provide it to your Salesforce administrator. ## Provide the Enrollment ID to Salesforce Share the Enrollment ID with your Salesforce administrator. They use it to create a **Data Share Target** in Salesforce Data Cloud, which establishes the authorized connection back to your Snowflake account. See [Set up Salesforce Data Cloud for Zero-Copy](/user-guide/data-integration/zero-copy/salesforce/setup-salesforce) for the Salesforce-side steps. After the Salesforce administrator creates the Data Share Target using the Enrollment ID, the connector transitions from `NEW` to `CONNECTING` and then to `CONNECTED` automatically. No additional action is required on the Snowflake side to establish the connection. Use `DESC ZEROCOPY CONNECTOR` to monitor progress while waiting: ```sql DESC ZEROCOPY CONNECTOR my_db.my_schema.my_sfdc_connector; -- check state ``` The connector is ready when `status` shows `CONNECTED`. ## Verify connector state Use `DESCRIBE` to check the full details of a connector: ```sql DESC ZEROCOPY CONNECTOR my_db.my_schema.my_sfdc_connector; ``` ### Output
To list all connectors visible to the current role: ```sql SHOW ZEROCOPY CONNECTORS IN SCHEMA my_db.my_schema; SHOW ZEROCOPY CONNECTORS IN DATABASE my_db; SHOW ZEROCOPY CONNECTORS IN ACCOUNT; ``` ## Set properties You can set optional properties on a connector using `ALTER ... SET`: ```sql ALTER ZEROCOPY CONNECTOR IF EXISTS my_db.my_schema.my_sfdc_connector SET COMMENT = 'Salesforce Data Cloud connector for CRM data products'; ``` To unset a property and restore its default value: ```sql ALTER ZEROCOPY CONNECTOR IF EXISTS my_db.my_schema.my_sfdc_connector UNSET COMMENT; ``` ## Disconnect the connector All catalog-linked databases created from the connector must be dropped before disconnecting. The connector must be in `CONNECTED` or `DISCONNECT_ERROR` state. ```sql ALTER ZEROCOPY CONNECTOR IF EXISTS my_db.my_schema.my_sfdc_connector DISCONNECT; ``` The connector immediately enters `DISCONNECTING` state while the connection is dropped asynchronously. When successful, it transitions to `DISCONNECTED`. ## Drop the connector You can only drop a connector that is in `NEW`, `CONNECT_ERROR`, `DISCONNECT_ERROR`, or `DISCONNECTED` state. Zerocopy Connectors do not support `UNDROP`. ```sql DROP ZEROCOPY CONNECTOR IF EXISTS my_db.my_schema.my_sfdc_connector; ``` ## Next steps Once the connector is in `CONNECTED` state, your Salesforce administrator can share data products. See [Set up Salesforce Data Cloud for Zero-Copy](/user-guide/data-integration/zero-copy/salesforce/setup-salesforce) to complete the Salesforce-side setup, then [Explore data products from Salesforce Data Cloud](/user-guide/data-integration/zero-copy/salesforce/explore-data-products) to list and query the shared data. --- title: SetCacheClientService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/setcacheclientservice.md section: Loading & Unloading Data --- # SetCacheClientService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides the ability to communicate with a SetCacheServer. This can be used in order to share a Set between nodes in a NiFi cluster ## Tags cache, cluster, distributed, set, state ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: SetCacheServer source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/setcacheserver.md section: Loading & Unloading Data --- # SetCacheServer This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides a set (collection of unique values) cache that can be accessed over a socket. Interaction with this service is typically accomplished via a DistributedSetCacheClient service. ## Tags cache, distinct, distributed, server, set ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: Setting Up the Openflow Connector for Google BigQuery source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/google-big-query/setup.md section: Loading & Unloading Data --- # Setting Up the %bigqueryof% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About the Openflow Connector for Google BigQuery](/user-guide/data-integration/openflow/connectors/google-big-query/about) - [Use the Openflow Connector for Google BigQuery](/user-guide/data-integration/openflow/connectors/google-big-query/use) This topic describes the steps to set up the %bigqueryof%. ## Prerequisites 1. Review [About the Openflow Connector for Google BigQuery](/user-guide/data-integration/openflow/connectors/google-big-query/about). 2. Set up your runtime deployment. - [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) - [Set up Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/setup-openflow-spcs) 3. If you are using %ofsfspcs-plural%, ensure that you have reviewed [configuring required domains](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list) and have granted access to the [domains](#label-of-bq-req-domains) required by the connector. 4. You have access to the Openflow admin role or similar role you use to manage Openflow. 5. If you are creating a Snowflake service user to manage the connector, you have created a key pair authentication. For more information, see [key-pair authentication](/user-guide/key-pair-auth). ## Required endpoints The following endpoints are required for the connector to function: - `bigquery.googleapis.com:443` - `bigquerystorage.googleapis.com:443` - `oauth2.googleapis.com:443` If you are using Openflow - BYOC, you need to configure your cloud network egress to allow TLS 443 access to the endpoints listed above. If you are using %ofsfspcs-plural%, you need to create a network rule and an external access integration (EAI). Then, grant the execute-as role usage privileges on the EAI. ## Set up BigQuery 1. Create a Google Cloud Service account and grant it the necessary permissions to read BigQuery data. The connector uses this account for authentication. This account must have the following permissions: - BigQuery User (https://docs.cloud.google.com/bigquery/docs/access-control#bigquery.user) - BigQuery Data Editor (https://docs.cloud.google.com/bigquery/docs/access-control#bigquery.dataEditor)
`BigQuery Data Editor` must be granted at the **project level**, not at individual datasets. The connector queries `{project}.{region}.INFORMATION_SCHEMA.TABLES` to discover tables across all configured regions - a region-scoped view that requires project-level access. The connector also queries `{project}.{dataset}.INFORMATION_SCHEMA.KEY_COLUMN_USAGE` to determine primary keys for each replicated table. Without project-level access, the query fails with a `Access Denied` error and the connector does not run correctly.
1. Generate and download the corresponding JSON key file for the service account. You will need the full contents of this file for the connector's configuration. 2. Enable change history on each source table to allow the connector to perform incremental replication. This feature allows BigQuery to track row-level changes (inserts, updates, and deletes), which the connector uses to sync data efficiently. Run the following query in the BigQuery console for each table: ```sql ALTER TABLE `project.dataset.table` SET OPTIONS (enable_change_history = TRUE); ``` ## Set up your Snowflake account As an Openflow administrator, perform the following tasks to set up your Snowflake account: 1. Create a Snowflake service user: ```sql USE ROLE USERADMIN; CREATE USER TYPE=SERVICE COMMENT='Service user for Openflow automation'; ``` 2. Store the private key for that user in a file to supply to the connector’s configuration. For more information, see [key-pair authentication](/user-guide/key-pair-auth). ```sql ALTER USER SET RSA_PUBLIC_KEY = ''; ``` 3. Create a database that stores the replicated data, and set up permissions for the Snowflake user to create objects in that database by granting USAGE and CREATE SCHEMA privileges. ```sql USE ROLE ACCOUNTADMIN; CREATE DATABASE IF NOT EXISTS ; GRANT USAGE ON DATABASE TO USER ; GRANT CREATE SCHEMA ON DATABASE TO USER ; ``` 4. Create a new warehouse or use an existing warehouse for the connector. To create a new warehouse: ```sql CREATE WAREHOUSE WITH WAREHOUSE_SIZE = 'MEDIUM' AUTO_SUSPEND = 300 AUTO_RESUME = TRUE; GRANT USAGE, OPERATE ON WAREHOUSE TO USER ; ``` Start with the MEDIUM warehouse size, then experiment with size depending on the amount of tables being replicated, and the amount of data transferred. To determine if you should increase, monitor the connector and database while data replication is in progress. If you observe significant delays during incremental replication, experiment with a larger warehouse size. However large table numbers typically scale better using [multi-cluster warehouses](/user-guide/warehouses-multicluster) instead of increasing the warehouse size. 5. Create an external access integration to enable network access outside of Snowflake. If your runtime executes in Openflow - BYOC, you do not need to create an External Access Integration (EAI). Instead, configure your cloud network egress to allow TLS 443 access to the endpoints listed below. Required host:port endpoints are listed in [](#label-of-bq-req-domains). To allow the connector to call the required Google APIs from a Snowflake-hosted runtime, you must create a network rule and an external access integration (EAI). Then, grant the execute-as role usage privileges on the EAI. To create the external access integration and network rule and grant access, perform the following steps: 1. Create a network rule to allow the connector to access the required Google APIs: ```sql USE ROLE ACCOUNTADMIN; USE DATABASE ; CREATE OR REPLACE NETWORK RULE openflow__network_rule TYPE = HOST_PORT MODE = EGRESS VALUE_LIST = ( 'bigquery.googleapis.com:443', 'bigquerystorage.googleapis.com:443', 'oauth2.googleapis.com:443' ); ``` 2. Create an External Access Integration that references the network rule: ```sql CREATE OR REPLACE EXTERNAL ACCESS INTEGRATION openflow__eai ALLOWED_NETWORK_RULES = (openflow__network_rule) ENABLED = TRUE; ``` 3. Grant your execute-as role USAGE on the integration: ```sql GRANT USAGE ON INTEGRATION openflow__eai TO ROLE OPENFLOW__EXECUTE_AS_RL; ``` ## Install the connector To install the connector, do the following as a data engineer: 1. Navigate to the Openflow overview page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find the connector and select **Install**. 3. In the **Select runtime** dialog, select your runtime from the **Available runtimes** drop-down list and click **Install**. Before you install the connector, ensure that you have created a database and schema in Snowflake for the connector to store ingested data. 4. Authenticate to the deployment with your Snowflake account credentials and select **Allow** when prompted to allow the runtime application to access your Snowflake account. The connector installation process takes a few minutes to complete. 5. Authenticate to the runtime with your Snowflake account credentials. The Openflow canvas appears with the connector process group added to it. ## Configure the connector To configure the connector, perform the following steps: 1. Right-click on the added runtime and select **Parameters**. 2. Populate the required parameter values as described in [](#label-specify-bq-connector-flow-parameters). ### Specify flow parameters This section describes the flow parameters that you can configure based on the following parameter contexts: - [BigQuery Source Parameters](#bigquery-source-parameters): Used to define the configuration for reading data from BigQuery. - [BigQuery Destination Parameters](#bigquery-destination-parameters): Used to establish connection with Snowflake. - [BigQuery Ingestion Parameters](#bigquery-ingestion-parameters): Used to specify the tables and views to replicate. #### BigQuery Source Parameters
#### BigQuery Destination Parameters
#### BigQuery Ingestion Parameters
## Run the flow 1. Right-click on the plane and select **Enable all Controller Services**. 2. Right-click on the imported process group and select **Start**. The connector starts the data ingestion. ## Next steps - For information on tasks you can perform after installing the connector, see [Use the connector](/user-guide/data-integration/openflow/connectors/google-big-query/use) - For information on monitoring the flow, see [Monitor the flow](/user-guide/data-integration/openflow/monitor) --- title: Setting up the Openflow Connector for Veeva Vault source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/veeva-vault/setup.md section: Loading & Unloading Data --- # Setting up the %veevavaultof% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About the Openflow Connector for Veeva Vault](/user-guide/data-integration/openflow/connectors/veeva-vault/about) - [Use the Openflow Connector for Veeva Vault](/user-guide/data-integration/openflow/connectors/veeva-vault/use) This topic describes the steps to set up the %veevavaultof%. ## Prerequisites 1. Review [About the Openflow Connector for Veeva Vault](/user-guide/data-integration/openflow/connectors/veeva-vault/about). 2. Set up your runtime deployment. - [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) - [Set up Openflow - Snowflake Deployments](/user-guide/data-integration/openflow/setup-openflow-spcs) 3. If you are using %ofsfspcs-plural%, ensure that you have reviewed [configuring required domains](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list) and have granted access to the [domains](#label-of-veeva-req-domains) required by the connector. 4. You have access to the Openflow admin role or a similar role you use to manage Openflow. 5. If you are creating a Snowflake service user to manage the connector, you have created key pair authentication. For more information, see [key-pair authentication](/user-guide/key-pair-auth). ## Required endpoints The following endpoint is required for the connector to function: - `:443` (for example, `myvault.veevavault.com:443`) If you are using %ofbyoc-plural%, configure your cloud network egress to allow TLS 443 access to this endpoint. If you are using %ofsfspcs-plural%, you must create a network rule and an external access integration (EAI). See [Create a network rule (Openflow Snowflake Deployments only)](#create-a-network-rule-openflow-snowflake-deployments-only) for details. ## Set up Veeva Vault The connector uses Direct Data API to retrieve data. Before you can use the connector, your Vault administrator must complete the following tasks. ### Enable Direct Data Direct Data must be enabled on your Vault. This is a Vault-level feature that allows external systems to retrieve data exports via the Direct Data API. To verify that Direct Data is enabled, your Vault administrator can check **Admin** %ra% **Settings** %ra% **General Settings** %ra% **Direct Data** in the Veeva Vault UI. For more information, see the Direct Data API documentation (https://general.veevavault.dev/direct-data-api). ### Create a service account Create a dedicated Veeva Vault user account for the connector. Refer to the Direct Data API permissions documentation (https://general.veevavault.dev/direct-data-api/references/direct-data-permissions) for configuring this account. Record the username and password for this service account. You need these values when configuring the connector. Snowflake recommends using a dedicated service account rather than a personal user account. This ensures that the connector continues to function if a personal account is disabled or its password is changed. ## Set up your Snowflake account As an Openflow administrator, perform the following tasks to set up your Snowflake account. ### Create a Snowflake service user (Openflow BYOC only) This step is only required if you are deploying the connector in %ofbyoc-plural%. It isn't needed for %ofsfspcs-plural%. 1. Create a service user: ```sql USE ROLE USERADMIN; CREATE USER TYPE=SERVICE COMMENT='Service user for the Veeva Vault connector'; ``` 2. Store the private key for that user in a file to supply to the connector's configuration. For more information, see [key-pair authentication](/user-guide/key-pair-auth). ```sql ALTER USER SET RSA_PUBLIC_KEY = ''; ``` ### Create database, schema, and warehouse 1. Create the destination database: ```sql USE ROLE ACCOUNTADMIN; CREATE DATABASE IF NOT EXISTS ; ``` 2. Create the destination schema: ```sql CREATE SCHEMA IF NOT EXISTS .; ``` 3. Create a role for the connector and grant the required privileges: ```sql CREATE ROLE IF NOT EXISTS ; GRANT USAGE ON DATABASE TO ROLE ; GRANT USAGE ON SCHEMA . TO ROLE ; GRANT CREATE TABLE ON SCHEMA . TO ROLE ; ``` 4. Create a warehouse (or use an existing one) and grant usage privileges: ```sql CREATE WAREHOUSE IF NOT EXISTS WITH WAREHOUSE_SIZE = 'SMALL' AUTO_SUSPEND = 300 AUTO_RESUME = TRUE; GRANT USAGE, OPERATE ON WAREHOUSE TO ROLE ; ``` 5. If using %ofbyoc-plural%, assign the role to the service user: ```sql GRANT ROLE TO USER ; ALTER USER SET DEFAULT_ROLE = ; ``` ### Create a network rule (Openflow Snowflake Deployments only) If your runtime executes in %ofbyoc-plural%, you don't need to create an External Access Integration (EAI). Instead, configure your cloud network egress to allow TLS 443 access to your Veeva Vault hostname. To allow the connector to call the Veeva Vault API from a Snowflake-hosted runtime, create a network rule and an external access integration (EAI), and then grant the execute-as role usage privileges on the EAI. 1. Create a network rule: ```sql USE ROLE ACCOUNTADMIN; CREATE OR REPLACE NETWORK RULE openflow__veeva_network_rule TYPE = HOST_PORT MODE = EGRESS VALUE_LIST = (':443'); ``` 2. Create an External Access Integration: ```sql CREATE OR REPLACE EXTERNAL ACCESS INTEGRATION openflow__veeva_eai ALLOWED_NETWORK_RULES = (openflow__veeva_network_rule) ENABLED = TRUE; ``` 3. Grant your execute-as role USAGE on the integration: ```sql GRANT USAGE ON INTEGRATION openflow__veeva_eai TO ROLE OPENFLOW__EXECUTE_AS_RL; ``` ## Install the connector To install the connector, do the following as a data engineer: 1. Navigate to the Openflow overview page. In the **Featured connectors** section, select **View more connectors**. 2. On the Openflow connectors page, find the connector and select **Install**. 3. In the **Select runtime** dialog, select your runtime from the **Available runtimes** drop-down list and click **Install**. Before you install the connector, ensure that you have created a database and schema in Snowflake for the connector to store ingested data. 4. Authenticate to the deployment with your Snowflake account credentials and select **Allow** when prompted to allow the runtime application to access your Snowflake account. The connector installation process takes a few minutes to complete. 5. Authenticate to the runtime with your Snowflake account credentials. The Openflow canvas appears with the connector process group added to it. ## Configure the connector To configure the connector, perform the following steps: 1. Right-click on the added connector process group and select **Parameters**. 2. Populate the required parameter values as described in the sections below. ### Veeva Vault parameters
### Snowflake destination parameters
### Schema evolution parameters
## Run the flow 1. Right-click on an empty area of the canvas and select **Enable all Controller Services**. 2. Right-click on the connector process group and select **Start**. The connector starts polling Veeva Vault for Direct Data files and loading data into Snowflake. ## Next steps - For information on tasks you can perform after installing the connector, see [Use the connector](/user-guide/data-integration/openflow/connectors/veeva-vault/use). - For information on monitoring the flow, see [Monitor the flow](/user-guide/data-integration/openflow/monitor). --- title: Setup tasks for SAP® Snowflake and SAP® BDC Connect for Snowflake source: https://docs.snowflake.cn/en/user-guide/data-integration/zero-copy/sap-sql/setup-tasks.md section: Loading & Unloading Data --- # Setup tasks for %sapsnowflake% and %sapbdc% - [About Snowflake and SAP® Zero-Copy Integration](/user-guide/data-integration/zero-copy/about-sap-snowflake) This topic describes the overall tasks required to set up, configure, and run either %sapsnowflake% or %sapbdc%. ## Prerequisites 1. Ensure that you have reviewed [About Snowflake and SAP® Zero-Copy Integration](/user-guide/data-integration/zero-copy/about-sap-snowflake). ## Tasks Perform the following tasks to set up, configure, and run %sapsnowflake% or %sapbdc%.
--- title: SignContentPGP 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/signcontentpgp.md section: Loading & Unloading Data --- # SignContentPGP 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-pgp-nar ## Description Sign content using OpenPGP Private Keys ## Tags Encryption, GPG, OpenPGP, PGP, RFC 4880, Signing ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.pgp.DecryptContentPGP](/user-guide/data-integration/openflow/processors/decryptcontentpgp) - [org.apache.nifi.processors.pgp.EncryptContentPGP](/user-guide/data-integration/openflow/processors/encryptcontentpgp) - [org.apache.nifi.processors.pgp.VerifyContentPGP](/user-guide/data-integration/openflow/processors/verifycontentpgp) --- title: SimpleCsvFileLookupService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/simplecsvfilelookupservice.md section: Loading & Unloading Data --- # SimpleCsvFileLookupService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description A reloadable CSV file-based lookup service. The first line of the csv file is considered as header. ## Tags cache, csv, enrich, join, key, lookup, reloadable, value ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted ## Restrictions
## System Resource Considerations This component does not specify system resource considerations. --- title: SimpleDatabaseLookupService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/simpledatabaselookupservice.md section: Loading & Unloading Data --- # SimpleDatabaseLookupService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description A relational-database-based lookup service. When the lookup key is found in the database, the specified lookup value column is returned. Only one value will be returned for each lookup, duplicate database entries are ignored. ## Tags cache, database, enrich, join, key, lookup, rdbms, reloadable, value ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: SimpleKeyValueLookupService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/simplekeyvaluelookupservice.md section: Loading & Unloading Data --- # SimpleKeyValueLookupService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Allows users to add key/value pairs as User-defined Properties. Each property that is added can be looked up by Property Name. The coordinates that are passed to the lookup must contain the key 'key'. ## Tags enrich, key, lookup, value ## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: SimpleRedisDistributedMapCacheClientService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/simpleredisdistributedmapcacheclientservice.md section: Loading & Unloading Data --- # SimpleRedisDistributedMapCacheClientService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description An implementation of DistributedMapCacheClient that uses Redis as the backing cache. This service is intended to be used when a non-atomic DistributedMapCacheClient is required. ## Tags cache, distributed, map, redis ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: SimpleScriptedLookupService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/simplescriptedlookupservice.md section: Loading & Unloading Data --- # SimpleScriptedLookupService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Allows the user to provide a scripted LookupService instance in order to enrich records from an incoming flow file. The script is expected to return an optional string value rather than an arbitrary object (record, e.g.). Also the scripted lookup service should implement StringLookupService, otherwise the getValueType() method must be implemented even though it will be ignored, as SimpleScriptedLookupService returns String as the value type on the script's behalf. ## Tags groovy, invoke, lookup, script ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted ## Restrictions
## System Resource Considerations This component does not specify system resource considerations. --- title: SlackRecordSink source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/slackrecordsink.md section: Loading & Unloading Data --- # SlackRecordSink This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Format and send Records to a configured Channel using the Slack Post Message API. The service requires a Slack App with a Bot User configured for access to a Slack workspace. The Bot User OAuth Bearer Token is required for posting messages to Slack. ## Tags record, sink, slack ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: SmbjClientProviderService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/smbjclientproviderservice.md section: Loading & Unloading Data --- # SmbjClientProviderService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides access to SMB Sessions with shared authentication credentials. ## Tags samba, smb, cifs, files ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: Snowflake Openflow Connector for Kafka source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/kafka/about.md section: Loading & Unloading Data --- This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) # Snowflake Openflow Connector for Kafka This topic describes the basic concepts of the Openflow Connector for Kafka and its limitations. The Openflow Connector for Kafka reads data from Kafka topics and writes it into Snowflake tables using the [Snowpipe Streaming High Performance](/user-guide/snowpipe-streaming/snowpipe-streaming-high-performance-overview) architecture. Use this connector if you're looking to do the following: - Ingest real-time events from Apache Kafka into Snowflake for near real-time analytics - Ingest real-time events from Apache Kafka into Snowflake-managed Iceberg™ tables - Accelerate your ingestion even more by combining Openflow speed with the Interactive Tables feature - Do Single Message Transforms for data enrichments or filtering before data lands in Snowflake. ## Limitations - Autoscaling isn't supported. The number of Openflow runtime min and max nodes should be constant for the runtime where the Openflow Connector for Kafka is deployed. - The Kafka cluster must be running version 0.10.0.0 or later. Prior versions of Kafka aren't supported. ## Using different authentication options, data types or data manipulation The connector is configured to work with the JSON data type and the SASL_SSL authentication method. The connector can be modified and extended in many ways. See the dedicated sub-pages in the setup section for guidance on making necessary changes. The following shared streaming customization guides apply to this connector: - [Configuring Avro data type ingestion](/user-guide/data-integration/openflow/connectors/streaming/configuring-avro-data-type-ingestion) - [Configuring Protobuf data type ingestion](/user-guide/data-integration/openflow/connectors/streaming/configuring-protobuf-data-type-ingestion) - [Configuring custom transformations](/user-guide/data-integration/openflow/connectors/streaming/configuring-custom-transformations) - [Configuring Dead Letter Queue (DLQ) handling](/user-guide/data-integration/openflow/connectors/streaming/configuring-dead-letter-queue-handling) and the Kafka-specific [Kafka as destination for DLQ messages](configuring-dead-letter-queue-handling) - [Configuring Private Key Authentication](/user-guide/data-integration/openflow/connectors/streaming/configuring-private-key-authentication) ### Supported Data types The Openflow Connector for Kafka supports the following data types: - **JSON (available by default in the connector)** - [Avro](/user-guide/data-integration/openflow/connectors/streaming/configuring-avro-data-type-ingestion) (extra configuration required) - [Protobuf](/user-guide/data-integration/openflow/connectors/streaming/configuring-protobuf-data-type-ingestion) (extra configuration required) ### Supported Authentication Methods The Openflow Connector for Kafka supports the following authentication mechanisms: - SASL with the following SASL mechanisms: - PLAIN - SCRAM-SHA-256 - **SCRAM-SHA-512 (available by default in the connector)** - OAUTHBEARER - [SASL with AWS MSK IAM](/user-guide/data-integration/openflow/connectors/kafka/aws-msk-iam-auth) (extra configuration required via controller services) - [mTLS](/user-guide/data-integration/openflow/connectors/kafka/mtls-auth) (extra configuration required via controller services) ## Next steps [Set up the Openflow Connector for Kafka](/user-guide/data-integration/openflow/connectors/kafka/setup) --- title: Snowflake Openflow Connector for Kafka: Configuring AWS MSK IAM Authentication source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/kafka/aws-msk-iam-auth.md section: Loading & Unloading Data --- This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) # Snowflake Openflow Connector for Kafka: Configuring AWS MSK IAM Authentication AWS MSK IAM authentication allows you to use AWS Identity and Access Management (IAM) to authenticate to Amazon Managed Streaming for Apache Kafka (MSK). ## Prerequisites - Your Kafka cluster must be Amazon MSK with IAM authentication enabled. - You need to provide IAM credentials in Openflow with BYOC (bring your own cloud) configurations, deployed in your cloud. - The IAM role or user must have the necessary MSK permissions. ## Step 1: Create AmazonMSKConnectionService From the Openflow canvas, access the Controller Services configuration: 1. Double-click on the connector's processing group. 2. Right-click on the canvas and select Controller Services. Add a new AmazonMSKConnectionService: 1. Select **+** to add a new controller service. 2. Select **AmazonMSKConnectionService** from the list. 3. Select **Add**. Configure the AmazonMSKConnectionService properties:
Verify the AmazonMSKConnectionService: 1. Select **Verify** for the service. 2. Confirm that the service status shows as **Verified**. ## Step 2: Configure ConsumeKafka Processor 1. In your Kafka connector locate the ConsumeKafka processor. 2. Configure the processor to use the new connection service: Set the **Kafka Connection Service** property to the AmazonMSKConnectionService you created in [](#label-openflow-kafka-aws-msk-iam-auth-step1). ## Step 3 (Optional): Remove Old Kafka Connection Service 1. In the Controller Services tab, locate the old Kafka3Connection service. 2. Disable and remove the old service: 1. Select **Disable** for the old service. 2. After it's disabled, select **Delete** to remove the old service. --- title: Snowflake Openflow Connector for Kafka: Configuring DLQ handling source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/kafka/configuring-dead-letter-queue-handling.md section: Loading & Unloading Data --- This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About the connector](about) - [Set up the connector](setup) - [Configuring Dead Letter Queue (DLQ) handling](/user-guide/data-integration/openflow/connectors/streaming/configuring-dead-letter-queue-handling) # Snowflake Openflow Connector for Kafka: Configuring DLQ handling This topic explains how to configure a **Kafka topic** as a destination for Dead Letter Queue (DLQ) messages on the **Kafka high-performance connector**, plus the other Kafka-specific parts of DLQ handling (the source processor, parse-failure relationship, and connection reuse). DLQ handling is shared between the streaming connectors. Read the general guide first --- [Configuring Dead Letter Queue (DLQ) handling](/user-guide/data-integration/openflow/connectors/streaming/configuring-dead-letter-queue-handling) --- for the common concepts: the failure envelope, the Snowflake-table route, the raw/structured branches, funnels, and DLQ sink failure handling. This page covers only what is specific to Kafka. You don't have to apply this customization by hand. The **Openflow skill in Snowflake CoCo** can perform it for you --- describe the change you want and it edits the flow following the steps on this page. We recommend using the skill instead of configuring the components manually. ## Connector grounding
## Route the parse failure into the DLQ On a fresh connector the `ConsumeKafka` `parse failure` relationship is auto-terminated. Remove the auto-termination and connect `parse failure` to the **RAW funnel** described in the [common guide](/user-guide/data-integration/openflow/connectors/streaming/configuring-dead-letter-queue-handling). ## Kafka topic as destination for DLQ messages Use this route to publish failed records back to a Kafka topic. **Publish the original failed payload as-is --- there is no envelope and no record wrapping.** Connect the failure sources directly to a `PublishKafka` sink; the envelope (`raw_payload` / `structured_payload`) is only for the Snowflake-table route, because a Kafka consumer wants the original bytes. Error context travels out-of-band as Kafka **headers** (via the FlowFile Attribute Header Pattern), not inside the message body. **Connection reuse:** The DLQ publisher reuses the same `Kafka3ConnectionService` as `ConsumeKafka` --- that is, the **same cluster**. If your DLQ topic lives on a **different** Kafka cluster, create a separate `Kafka3ConnectionService` configured for that cluster and point `PublishKafka` at it. The same connector can write DLQ messages to any Kafka cluster and to any Snowflake environment. Otherwise the existing connection is reused. ### Step 1: Create the PublishKafka processor 1. Add a `PublishKafka` processor to the connector's process group. 2. Set the following properties:
### Step 2: Wire the failure sources to the publisher - Connect the failure sources (the `parse failure` relationship, and any transformation/error relationships) **directly** to this publisher --- no raw/structured branches are built for the stream route. - Route the publisher's `failure`, `invalid` relationships to the [DLQ sink failure handling](/user-guide/data-integration/openflow/connectors/streaming/configuring-dead-letter-queue-handling#label-openflow-streaming-dlq-sink-failure). Use a **bounded** `failure` retry (for example, retry count 3) so transient broker issues recover but persistent failures still reach the parking-lot. Do **not** use an effectively-infinite retry (for example, 9999). ## Snowflake table as destination for DLQ messages Identical to both connectors. See [Route B --- Snowflake table](/user-guide/data-integration/openflow/connectors/streaming/configuring-dead-letter-queue-handling#label-openflow-streaming-dlq-route-b) in the common guide. ## Troubleshooting
For shared symptoms (raw branch, `structured_payload`, grants, parking-lot funnel), see the [common troubleshooting table](/user-guide/data-integration/openflow/connectors/streaming/configuring-dead-letter-queue-handling). --- title: Snowflake Openflow Connector for Kafka: Configuring mTLS Authentication source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/kafka/mtls-auth.md section: Loading & Unloading Data --- This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About Openflow](/user-guide/data-integration/openflow/about) - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) # Snowflake Openflow Connector for Kafka: Configuring mTLS Authentication mTLS (mutual Transport Layer Security) authentication requires both the client and server to present certificates for mutual authentication. ## Prerequisites Before configuring mTLS authentication, ensure you have: 1. Generated and configured the necessary certificates for both the connector and the Kafka broker. 2. Created a keystore containing the connector's private key and certificate. 3. (Optional) Created a truststore containing the Kafka broker certificate or a certificate in the certification chain. This step is only required if the broker certificate is not signed by a trusted Certificate Authority (CA). 4. The supported keystore/truststore formats are PKCS12, JKS, and BCFKS. ## Step 1: Configure SSL Context Service From the Openflow NiFi canvas, access the Controller Services configuration: 1. Double-click on the connector's processing group. 2. Right-click on the canvas and select **Controller Services**. Add a new **StandardSSLContextService**: 1. Select **+** to add a new controller service. 2. Select **StandardSSLContextService** from the list. 3. Select **Add**. Configure the SSL Context Service properties:
Enable the SSL Context Service: 1. Select **Enable** for the service. 2. Confirm that the service status shows as **Enabled**. ## Configuring PEM-encoded SSL context If your certificates and keys are in PEM format (`.pem`, `.crt`, `.key`) rather than in a JKS or PKCS12 keystore, use the `PEMEncodedSSLContextProvider` controller service instead of `StandardSSLContextService`. 1. In the **Controller Services** tab, select **+** to add a new controller service. 2. Select **PEMEncodedSSLContextProvider** from the list. 3. Select **Add**. 4. Configure the service properties:
5. **Enable** the service. 6. In [Step 2](#label-openflow-kafka-mtls-auth-step2), set **SSL Context Service** to this `PEMEncodedSSLContextProvider` instead of the `StandardSSLContextService`. ## Step 2: Configure Kafka3Connection Service 1. In the same **Controller Services** tab, locate the [Kafka3Connection service](/user-guide/data-integration/openflow/controllers/kafka3connectionservice). 2. Configure the following properties:
3. Keep all other [Kafka3Connection service](/user-guide/data-integration/openflow/controllers/kafka3connectionservice) settings unchanged. 4. Verify the Kafka3Connection service: 1. Select **Verify** for the service. 2. Confirm that the service status shows as **Verified**. --- title: Snowflake Openflow version history source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/version-history.md section: Loading & Unloading Data --- # Snowflake Openflow version history This topic provides version history for [Snowflake Openflow](/user-guide/data-integration/openflow/about). To apply the latest updates to your deployment, runtimes, or connectors, see [Manage Openflow](/user-guide/data-integration/openflow/manage). [/^AWS Data Plane Agent\b/i, ['deployment']], [/^SPCS Data Plane Agent\b/i, ['deployment']], [/^Runtime Operator\b/i, ['deployment']], [/^Data Plane Service\b/i, ['deployment']], [/^Data Plane UI\b/i, ['deployment']], [/^(Openflow\s+)?Ingress Controller\b/i, ['deployment']], [/^(Openflow\s+)?Token Refresher\b/i, ['deployment']], [/^(Openflow\s+)?Runtime Gateway\b/i, ['deployment', 'runtime']], [/^Runtime Oracle Extensions\b/i, ['runtime']], [/^Runtime Extensions\b/i, ['runtime']], [/^Runtime Server\b/i, ['runtime']], [/^Connectors\b/i, ['runtime']], [/^Control Plane Core\b/i, ['controlplane']], [/^Control Plane UI\b/i, ['controlplane']], ]; const trimmed = (text || '').trim(); for (const [pattern, cats] of openflowVhPatterns) { if (pattern.test(trimmed)) return cats; } return null; }; if (!filter) return; let listeners = []; let componentBlocks = []; let dateSections = []; const wire = () => { // `rehypeSectionize` only wraps H2-level groups in
, // so the filter lives in the preamble section and every H3 on the page is a flat // sibling under the H2 date section it belongs to. Anchor up at the
// root so we can see the sibling date sections. const article = filter.closest('article') || filter.closest('[data-testid="article-content"]') || filter.ownerDocument.body; // Build per-H3 "component blocks": the H3 plus its following siblings up to the // next H3/H2 or the next label anchor (which belongs to the *next* block). article.querySelectorAll('h3').forEach((h3) => { const cats = classifyOpenflowVhHeading(h3.textContent); if (!cats) return; const nodes = [h3]; let next = h3.nextElementSibling; while (next) { if (next.tagName === 'H3' || next.tagName === 'H2') break; if ( next.tagName === 'A' && typeof next.id === 'string' && next.id.startsWith('label-') ) { break; } nodes.push(next); next = next.nextElementSibling; } componentBlocks.push({ categories: cats, nodes }); }); // Collect date sections (each H2's
) and remember // which component blocks live inside each one, so we can hide an entire date // when all its component blocks are filtered out. const dateBlocks = new Map(); article.querySelectorAll('section[data-section]').forEach((sec) => { if (!sec.querySelector(':scope > h2')) return; dateSections.push(sec); dateBlocks.set( sec, componentBlocks.filter((b) => sec.contains(b.nodes[0])), ); }); const checkboxes = filter.querySelectorAll( 'input[type="checkbox"][data-ofvh-cat]', ); const summary = filter.querySelector('.ofvh-summary'); const totalCategories = checkboxes.length; const totalComponents = componentBlocks.length; const apply = () => { const active = Object.create(null); let activeCount = 0; checkboxes.forEach((cb) => { if (cb.checked) { active[cb.dataset.ofvhCat] = true; activeCount++; } }); let visibleComponents = 0; componentBlocks.forEach((block) => { let show = false; for (const c of block.categories) { if (active[c]) { show = true; break; } } block.nodes.forEach((n) => { n.hidden = !show; }); if (show) visibleComponents++; }); let hiddenDates = 0; dateSections.forEach((sec) => { const blocks = dateBlocks.get(sec) || []; // Hide the date heading only if it has classified blocks AND all are hidden. // If a date has no classified blocks at all (shouldn't happen here, but be // defensive), leave it visible. const anyVisible = blocks.length === 0 || blocks.some((b) => !b.nodes[0].hidden); sec.hidden = !anyVisible; if (!anyVisible) hiddenDates++; }); if (summary) { if (activeCount === totalCategories) { summary.textContent = ''; } else if (activeCount === 0) { summary.textContent = 'All categories are hidden. Select at least one to see entries.'; } else { summary.textContent = 'Showing ' + visibleComponents + ' of ' + totalComponents + ' component entries.' + (hiddenDates ? ' ' + hiddenDates + ' empty date heading(s) hidden.' : ''); } } }; checkboxes.forEach((cb) => { const handler = () => apply(); cb.addEventListener('change', handler); listeners.push([cb, handler]); }); apply(); }; if (typeof queueMicrotask === 'function') { queueMicrotask(wire); } else { setTimeout(wire, 0); } return () => { listeners.forEach(([cb, handler]) => cb.removeEventListener('change', handler), ); componentBlocks.forEach((block) => { block.nodes.forEach((n) => { n.hidden = false; }); }); dateSections.forEach((sec) => { sec.hidden = false; }); listeners = []; componentBlocks = []; dateSections = []; }; };
Show entries for:
## September 7, 2026 ### Runtime Server 2026.9.5.13 - Security patches and dependency upgrades. - Allowed existing flows containing legacy and/or invalid parameter names to load. ### Runtime Extensions 2026.9.5.13 - CDC MySQL: Fixed GTID restart tracking so stopping `CaptureChangeMySQL` cannot permanently skip transactions that were queued but not yet processed. - Snowpipe Streaming: Logged DNS resolution failures from `PublishSnowpipeStreaming` at the error level. - CDC Oracle: Added a warning and incremented the `Unsupported LOB Events Ignored` counter for unsupported partial LOB operations, including the source table and replication keys so operators can identify affected rows. Partial LOB operations continued to be unsupported. ### Connectors 2026.9.5.12 - Oracle Embedded License 0.48.0: - Configured the Oracle connection pool to present the client certificate from the configured wallet, enabling mutual TLS for snapshot and schema operations. - Oracle Embedded License Public Sector 0.47.0: - Configured the Oracle connection pool to present the client certificate from the configured wallet, enabling mutual TLS for snapshot and schema operations. - Oracle Independent License 0.47.0: - Configured the Oracle connection pool to present the client certificate from the configured wallet, enabling mutual TLS for snapshot and schema operations. - CDC PostgreSQL 0.66.0: - Separated changes committed while a snapshot is running into a snapshot change log and compacted them by primary key before merging, preventing duplicate destination rows and preserving values needed for TOAST updates. - Table Consolidation 0.7.0: - Gated merge events until provisioning DDL commits so a merge cannot run before its destination stream exists. - Ran Consolidate Table Data with four concurrent tasks so independent consolidated tables can merge in parallel. ## September 4, 2026 ### Control Plane Core 0.131.0 - Removed the Public Preview label from the Jira Cloud (Core) connector in the connector catalog, following its move to general availability. - Gen2 CDC MySQL and PostgreSQL: These connectors now require Runtime Extensions 2026.8.25.11 or later. - Fixed a rare issue affecting Openflow when a Snowflake account was dropped and then recreated with the same name. - Improved control plane responsiveness when listing runtimes, particularly on accounts with many runtimes. - Security patches and dependency upgrades. ### Data Plane Service 0.131.0 - Increased timeouts for long-running runtime operations, improving success rates on larger runtimes. - Security patches and dependency upgrades. ### Control Plane UI 0.90.0 - Added a Connector library tab to the connector catalog. - SharePoint: Added file type filters to the connector setup wizard. - Security patches and dependency upgrades. ### Data Plane UI 0.22.0 - SharePoint: Added file type filters to the connector setup wizard. - Updated Connector library tab naming. - Security patches and dependency upgrades. ### Runtime Operator 0.76.0 - Improved runtime startup times by copying connector extensions in parallel. - Security patches and dependency upgrades. ### Ingress Controller 2026.9.3-0 - Security patches and dependency upgrades. ### SPCS Data Plane Agent 1.47.0 - Security patches and dependency upgrades. ### AWS Data Plane Agent 1.63.1 - Fixed deployment agent out-of-memory failures during large infrastructure operations. These failures could interrupt deployment creation or deletion and leave deployment state inconsistent. - Deployment deletion is now cleaner, faster, and more reliable, addressing several conditions that could block or complicate teardown. - Security patches and dependency upgrades. ## September 3, 2026 ### Runtime Server 2026.9.3.2 - Security patches and dependency upgrades. ### Runtime Extensions 2026.9.3.12 - CDC SQL Server: The connector no longer stops discovering tables across the source instance when one CDC-enabled database cannot be read. The unreadable database is reported as unavailable and skipped while discovery continues for the others. - CDC Oracle: Adds mutual TLS support for thin JDBC connections by presenting the client certificate from the configured Oracle wallet. - CDC Oracle: The CaptureChangeOracle processor can keep table schemas in memory when `OPENFLOW_ORACLE_CDC_CONNECTOR_STATE_STORAGE` is set to `IN_MEMORY`. Existing deployments retain the default NiFi-state behavior. - Gen 2 CDC MySQL and PostgreSQL: Changes the default merge schedule to once every minute, matching the existing gen 1 connector behavior. ### Connectors 2026.9.3.1 - Jira Core 0.9.0: - Orders duplicate Jira issue updates by the `UPDATED` timestamp so the replicated issue table retains the newest values instead of an arbitrary stale version. - Oracle Embedded License 0.47.0: - Wires the `Concurrent Snapshot Queries` parameter to row-ID snapshot fetching so customers can control snapshot concurrency without editing the flow. - Oracle Embedded License Public Sector 0.46.0: - Wires the `Concurrent Snapshot Queries` parameter to row-ID snapshot fetching so customers can control snapshot concurrency without editing the flow. - Oracle Independent License 0.46.0: - Wires the `Concurrent Snapshot Queries` parameter to row-ID snapshot fetching so customers can control snapshot concurrency without editing the flow. - SQL Server CDC 0.50.0: - Adds clone, truncate, and archive re-snapshot handling when the destination table already exists. - SQL Server CT 0.53.0: - Adds clone, truncate, and archive re-snapshot handling when the destination table already exists. ## September 1, 2026 ### Runtime Server 2026.9.1.2 - Security patches and dependency upgrades. - Upgraded the Runtime UI to version 0.88.0. - Gen2 Database CDC: Preserves column-filter configurations that the wizard cannot model by providing a validated raw JSON editor instead of silently dropping or reformatting them. - Gen2 Database CDC migration: Re-evaluates destination authentication visibility after migration and waits for the result before allowing the wizard to advance. - Gen2 connector configuration: Distinguishes missing connector configuration and asset files from transient Snowflake stage failures, and retries transient stage operations instead of silently returning an empty configuration. - GCP deployments: Enables internal connector stage uploads and downloads through bucket-scoped GCS endpoints, avoiding connector `START_FAILED` errors caused by inaccessible public GCS endpoints. - Fixed clustered Parameter Context updates when adding provider-backed inheritance. ### Runtime Extensions 2026.9.1.15 - CDC MySQL: Fixed automatic migration from binlog-file position tracking to GTID tracking when the source has purged older binary logs. If purged history cannot be verified safely, migration is deferred and replication continues using binlog positions. - Gen2 CDC MySQL and PostgreSQL: Connectors now add Snowflake primary key metadata when creating destination tables for source tables with primary keys, except when user-defined logical keys are used. - Gen2 CDC MySQL and PostgreSQL: Connectors now start correctly on runtimes with a custom NAR installed. Previously, a newly created connector could have an empty flow that could not start. - CDC Databases: Merge scheduling no longer starts an additional small merge for data queued after the scheduled merge boundary, reducing unexpected warehouse activity and credit consumption. - Gen2 CDC MySQL and PostgreSQL: After migrating a connector that uses `KEY_PAIR` authentication to a managed-token runtime, `KEY_PAIR` remains selectable so the private key can be re-entered. Switching to `SNOWFLAKE_MANAGED` hides the `KEY_PAIR`-only fields on the next configuration fetch. - CDC SQL Server: Publishes each table's committed capture position independently and only after the corresponding NiFi session commits. State publication retries without advancing capture, preventing stale durable positions and missed changes when local-state persistence is delayed or temporarily unavailable. ### Connectors 2026.9.1.1 - Jira Core 0.8.0: - Consolidates duplicated per-endpoint ingestion paths into shared run-scoped processing, reducing flow complexity while isolating concurrent ingestion runs. - Advances the audit-deletes checkpoint from the latest deletion timestamp fetched instead of the current time, preventing deletion events from being skipped. - Table Consolidation 0.4.0: - Groups consolidated SQL Server tables by resolved source schema and table so equivalent tables from multiple source databases land in one consolidated table with source lineage. - Reconciles consolidated table schemas additively when source tables differ, adding missing columns without dropping existing columns so rows from every source can be merged safely. - Google Drive No Cortex/DWD 0.22.0, No Cortex/No DWD 0.4.0, Cortex/DWD 0.28.0, Cortex/No DWD 0.5.0: - Preserves connector ID sequences across runtime restarts, preventing sequence resets and resulting ID conflicts. ## August 28, 2026 ### Runtime Operator 0.75.0 - Security patches and dependency upgrades. ### Ingress Controller 2026.8.25-18 - Security patches and dependency upgrades. ### Control Plane Core 0.130.0 - Diagnostic bundle generation is now more reliable — transient failures are automatically retried rather than requiring manual intervention. - Security patches and dependency upgrades. ### Data Plane Service 0.130.0 - Fixed an issue where connectors were incorrectly shown as idle when activity data was temporarily unavailable. - Security patches and dependency upgrades. ### Control Plane UI 0.89.0 - Security patches and dependency upgrades. ### Data Plane UI 0.21.0 - Security patches and dependency upgrades. ### Openflow Token Refresher 1.19.0 - Security patches and dependency upgrades. ### AWS Data Plane Agent 1.62.0 - Improved deployment reliability across several common failure scenarios, including slow IAM propagation, certificate drift after upgrades, and Terraform state inconsistencies with custom ingress rules. - Deployments now automatically recover from membership ring issues that could previously cause stuck or degraded runtime states. - Security patches and dependency upgrades. ### SPCS Data Plane Agent 1.46.0 - Security patches and dependency upgrades. ## August 25, 2026 ### Runtime Server 2026.8.24.20 - Security patches and dependency upgrades. - Upgraded the Runtime UI to version 0.87.0. - Database CDC: Shows the backend-provided failure reason for failed tables in the Reload tables dialog. - Connector migration: Gates the Gen1-to-Gen2 Migrate wizard step with the migration runtime setting. - Connector migration: Keeps migration discoverable and shows unmet prerequisites when migration is blocked. - Connector wizard: Displays stored false values correctly in Boolean toggles and immediately refreshes dependent steps and properties. - Connector installation: Adds an in-context prompt that users can copy into CoCo when installing a Gen2 connector. - Connector migration: Clarifies why a flow cannot be migrated and simplifies post-migration success feedback. - Preserves unsaved Parameter Context changes when navigating to an inherited Parameter Context. - Connector migration: Records the source Gen1 process group when migration completes, enabling connector-scoped alerts to be migrated to the Gen2 connector. - Runtime storage and recovery: Caps local-state write-ahead journals at 1 GB to limit disk growth and improve recovery under sustained updates. - Applies auto-termination changes when a versioned-flow update disconnects a previously connected relationship. - Validates versioned Parameter names and allows invalid Parameters to be removed. - Corrects partition-rebalancing lifecycle handling. - Reloads parameter-driven Connector method classpaths when parameters change. ### Runtime Extensions 2026.8.25.11 - Kafka: Adds FlowFile grouping strategy support to Kafka consumption. - Table Consolidation: Backfills a table's existing rows as soon as consolidation is enabled when that table has already reached incremental replication, instead of requiring a subsequent merge. - CDC PostgreSQL: Fixes CTID snapshots for rows updated during the snapshot. Earlier versions could produce rows with duplicate primary keys under specific PostgreSQL storage conditions. - CDC Databases: Preserves the earliest commit timestamp during journal compaction so end-to-end replication latency remains accurate. - CDC PostgreSQL Gen2: Adds a Logical key configuration wizard step for declaring key columns on tables without a primary key or overriding the default key. Configured logical keys cause CDC updates to use MERGE instead of INSERT, preventing duplicate rows. - MongoDB: Adds opt-in replication of change events larger than 16 MiB on MongoDB 6.0.9 and later. Amazon DocumentDB does not support this mode. - CDC MySQL Gen2: Adds a Table key configuration wizard step for declaring key columns on tables without a primary key or overriding the default key. Configured logical keys cause CDC updates to use MERGE instead of INSERT, preventing duplicate rows. - CDC PostgreSQL: Replicates incremental changes for tables and columns with non-ASCII names. Previously, the snapshot succeeded but subsequent inserts, updates, and deletes were silently omitted. - Snowpipe Streaming: Removes the deprecated `PutSnowpipeStreaming2` processor in favor of `PublishSnowpipeStreaming`. - CDC PostgreSQL: Prevents connector validation from hanging on the table schema step by removing publication-table validation from that flow-building path. - CDC MySQL and CDC PostgreSQL: Resolves Execute As Role in every flow-building path, allowing connectors to start correctly after exiting troubleshooting mode. - Table Consolidation: Groups consolidated rows by source schema and table, allowing the same logical table across tenant databases to be consolidated together while keeping different source schemas separate. This applies to the preview Table Consolidation feature. - CDC MySQL: Adds an Error Handling Strategy for rows rejected by Snowflake. The default records rejected rows and continues valid-row replication; `Fail Table` stops that table on the first rejected row. - CDC SQL Server: Retries table listing when SQL Server reports a transient deadlock instead of routing immediately to failure, preventing replication from stalling when connectors enumerate the same source databases concurrently. - BigQuery: Preserves microsecond precision for TIMESTAMP values ingested by `FetchBigQueryStream` with a Record Writer instead of truncating them to milliseconds. - CDC PostgreSQL: `SplitPostgreSQLTable` no longer reports an error when it starts against an older PostgreSQL database. If a table is actually split against an unsupported source, that FlowFile is routed to `invalid`. The processor requires PostgreSQL 13 or higher. - Salesforce Bulk API: Uses a soft target of 500,000 records and subdivides dense query windows before job submission. Subdivision stops at a minimum 24-hour window, so the target is not a hard limit. - Snowpipe Streaming: Processes a large change-data FlowFile separately when adding it to an existing batch would exceed the configured batch target. ### Connectors 2026.8.25.1 - CDC MySQL 0.58.0: Removes a duplicated failure processor, adjusts queue backpressure, and adds destination primary-key metadata for source tables with real primary keys. - Oracle Embedded License 0.46.0: Uses `CountTableRows` during snapshot planning and adds destination primary-key metadata for source tables with real primary keys. - Oracle Embedded License Public Sector 0.45.0: Uses `CountTableRows` during snapshot planning and adds destination primary-key metadata for source tables with real primary keys. - Oracle Independent License 0.45.0: Uses `CountTableRows` during snapshot planning and adds destination primary-key metadata for source tables with real primary keys. - CDC PostgreSQL 0.64.0: Uses `CountTableRows` for CTID snapshot planning and adds destination primary-key metadata for source tables with real primary keys. - CDC SQL Server CDC 0.49.0: Adds destination primary-key metadata for source tables with real primary keys. - CDC SQL Server CT 0.51.0: Backfills tables that were already in incremental replication when Table Consolidation is enabled. - Table Consolidation 0.2.0: Backfills tables that were already in incremental replication when consolidation is enabled. ## August 20, 2026 ### Control Plane Core 0.129.0 - Security patches and dependency upgrades. - Tightened permissions on runtime diagnostic bundle download: OWNERSHIP privilege is now required. - DB CDC connectors can now be deployed on small runtimes with Snowpipe Streaming v2 enabled. - Fixed a rare issue where a Runtime restart could show success before all pods were healthy. ### Data Plane Service 0.129.0 - Security patches and dependency upgrades. - Fixed a rare issue where a Runtime restart could show success before all pods were healthy. ### Control Plane UI 0.88.0 - Security patches and dependency upgrades. - Fixed keyboard usability for searchable select controls with grouped options. ### Runtime Operator 0.74.0 - Security patches and dependency upgrades. ### Ingress Controller 2026.8.18-17 - Security patches and dependency upgrades. ### SPCS Data Plane Agent 1.45.0 - Security patches and dependency upgrades. ### AWS Data Plane Agent 1.61.0 - Security patches and dependency upgrades. - Fixed an intermittent deployment creation failure caused by IAM role availability delays due to eventual consistency. - Fixed a rare deployment deletion failure that occurred when Custom Resource Definitions (CRDs) were absent at destroy time. ## August 18, 2026 ### Runtime Server 2026.8.18.9 - Security patches and dependency upgrades. - Upgraded the Runtime UI to version 0.86.0. - Prompted users to save or discard unsaved edits before navigating to an inherited Parameter Context, preventing silent loss of configuration changes. ### Runtime Extensions 2026.8.18.9 - Databases: Added a `CountTableRows` processor that counts rows in a SQL table and stores the result in a configured FlowFile attribute. - Salesforce: Selected the latest staged snapshot for each Salesforce record during deduplication, preventing stale values from being merged when staging contains multiple snapshots. - CDC SQL Server: Fixed a rare data-loss window where a captured batch could be silently skipped if the destination commit failed after the batch was read. - Snowflake: Added an opt-in stream-existence cache to `UpdateSnowflakeStream`, avoiding a redundant DDL statement per FlowFile when using `Create Stream If Not Exists`. ### Connectors 2026.8.18.1 - MongoDB 0.27.0: Used a 60-second Snowpipe Streaming offset-tracking timeout to reduce transient polling failures while data continues flowing. - CDC MySQL 0.57.0: Used a 60-second Snowpipe Streaming offset-tracking timeout to reduce transient polling failures while data continues flowing. - Oracle Embedded License 0.45.0: Increased the default snapshot fetch size from 100 to 5,000 rows and used a 60-second offset-tracking timeout. - Oracle Embedded License Public Sector 0.44.0: Increased the default snapshot fetch size from 100 to 5,000 rows and used a 60-second offset-tracking timeout. - Oracle Independent License 0.44.0: Increased the default snapshot fetch size from 100 to 5,000 rows and used a 60-second offset-tracking timeout. - CDC PostgreSQL 0.62.0: Used a 60-second Snowpipe Streaming offset-tracking timeout to reduce transient polling failures while data continues flowing. - CDC SQL Server 0.48.0: Used a 60-second Snowpipe Streaming offset-tracking timeout to reduce transient polling failures while data continues flowing. - SQL Server CT 0.49.0: Added optional connector-event publishing for table consolidation and used a 60-second offset-tracking timeout. - Table Consolidation 0.1.0: Added a flow that consumes connector events and merges snapshot and CDC rows into consolidated destination tables. ## August 13, 2026 ### Runtime Extensions 2026.8.17.9 - Oracle CDC: Restored merge performance for tables with user-defined logical keys by reverting to plain equality for key comparison, fixing a full-target-table-scan regression. - Salesforce: Failed Bulk jobs now included Salesforce's failure reason in the processor bulletin, making job failures diagnosable without inspecting Salesforce separately. - CDC PostgreSQL: Added an Error Handling Strategy for rows Snowflake rejects during ingestion. The default `Log Errors and Continue` strategy records rejected rows in the table's error table while valid rows continue replicating; `Fail Table` stops replication for that table on the first rejected row. - CDC MySQL and PostgreSQL: Used a 60-second Snowpipe Streaming offset-tracking timeout to reduce transient, self-healing `Polling Failed after 30000 ms` errors while data continues flowing. ### Runtime Server 2026.8.13.16 - Security patches and dependency upgrades. ### Runtime Extensions 2026.8.13.17 - Openflow connectors: Fixed Gen 2 connector configuration for quoted connector names so `DESCRIBE CONNECTOR` no longer adds a second pair of quotes and reports the connector as missing or unauthorized. - CDC Iceberg: Created integer columns as `LONG` so source integer widening does not require an unsupported Iceberg type change and 64-bit values are represented safely. - CDC Gen 2 connectors: Connector configuration verification now reports the actual Snowflake error when an External Access Integration cannot be evaluated, instead of incorrectly reporting that no egress Network Rule allows access to the source endpoint. - CDC MySQL: `CaptureChangeMySQL` can now be switched from Binlog Position to GTID position tracking without losing or replaying events. The connector completes the switch automatically at the next binlog rotation; no manual state cleanup or re-snapshot is required. - CDC SQL Server: Fixed a rare data-loss window where a Change Tracking batch could be silently skipped if the destination commit failed after the batch was read. - CDC SQL Server: Snapshot loads of tables with very large rows no longer risk filling runtime disk. Batches stop at a bounded data volume and subsequent batches resume from the exact remaining rows without configuration changes. - CDC SQL Server: Drains large single-version Change Tracking batches with `Max Batch Size = -1` using one bounded query without an unnecessary sort, reducing `tempdb` pressure during bulk updates. - CDC PostgreSQL: Fixed replication of large hour-based `INTERVAL` values so Snowflake receives correct ISO-8601 duration strings instead of corrupted negative values. - Jira: Jira connector record fingerprints now use SHA-256 instead of MD5. Existing records may receive a one-time update after upgrading. ### Connectors 2026.8.13.7 - Veeva Vault 0.7.0: Clarified Direct Data audit-log and ingestion-mode parameter descriptions. - Salesforce 1.14.0: Removed downstream back pressure after batched Snowpipe Streaming publishing to prevent the Salesforce connector from deadlocking when Snowpipe Streaming errors occur. ## August 11, 2026 ### Runtime Server 2026.8.11.2 - Security patches and dependency upgrades. - Moved from Java 21 to Java 25. - Upgraded the Runtime UI to version 0.85.0. ### Runtime Extensions 2026.8.11.10 - CDC SQL Server: Added `Max Batch Size = -1` to disable Change Tracking pagination, reducing repeated `CHANGETABLE` evaluation for large backlogs. Enabling `Use Snapshot Isolation` is recommended when using this mode. - CDC SQL Server: Prevented brief source outages during Azure SQL Managed Instance maintenance or similar failover windows from removing all tables from replication; empty database discovery now retries. - CDC Oracle: Added multi-PDB replication for users granted `SET CONTAINER`, while preserving existing single-PDB behavior otherwise. - Salesforce: Formula views now return typed NULL values for formulas referencing unreplicated relationship lookup fields instead of failing view creation. - CDC SQL Server: Fixed a concurrency race that could cause Change Tracking to silently skip changes for idle tables. ### Connectors 2026.8.11.1 - Dataverse 0.32.0: Added an `Include Formatted Values` parameter so ingestion can include display-friendly formatted values while preserving the original raw values. - Dataverse 0.32.0: Fixed incorrect `_SNOWFLAKE_ID` values by copying the resolved primary-key value instead of the primary-key field name. - Salesforce 1.13.0: Special objects now use `queryAll` to ingest archived Task and Event records and soft-deleted records. Existing objects require a connector state reset and full reload to retrieve historical records. - Salesforce 1.13.0: Retained failed Bulk API query jobs so they remain available for troubleshooting. ## August 6, 2026 ### Runtime Server 2026.8.6.2 - Security patches and dependency upgrades. - Upgraded the Runtime UI to version 0.84.0. - Flow Designer: Fixed the load-balance icon rendering outside the connection label box when a connection is actively load-balancing. - Flow Designer: Fixed validation-error and comment tooltips closing before the cursor reaches them on the Controller Services, Reporting Tasks, Parameter Providers, and Connectors listings, so users can move onto the tooltip and scroll the full text. ### Runtime Extensions 2026.8.6.2 - Added external assertion (`client_assertion_type` and `client_assertion`) support to `JWTBearerOAuth2AccessTokenProvider` for OAuth2 JWT bearer flows. This unblocks scenarios where Snowflake Workload Identity Federation is used in Openflow to authenticate against services running in AWS while identities are managed in Microsoft Entra. - Snowflake Connection Service: No longer returns `COPY INTO` result metadata by default. Configure the dynamic property `enableCopyResultSet=true` to opt in to `COPY INTO` result metadata. - Salesforce: `QuerySFDCObject` can now use Salesforce `queryAll` to retrieve archived Task and Event records and soft-deleted records. Direct processor usage is supported in this release; standard connector-flow wiring ships separately. - CDC PostgreSQL: Emits a WARN bulletin after creating a replication slot on PostgreSQL 17+ if `synchronized_standby_slots` is not configured on the primary while standbys are connected, or if the created slot unexpectedly lacks `failover=true`. Standalone deployments do not trigger the warning. - CDC Oracle: Added support for Oracle multi-PDB table listing on AWS RDS Multi-Tenant by routing `MultiDatabaseListTableNames` across multiple Oracle Pluggable Databases when `MultiPdbOracleConnectionPool` from the separately installed Oracle via DMS NAR is configured. - Oracle via DMS: Introduced a standalone installable `runtime-oracle-dms-processors-nar` with `ProcessChangeFromOracleDMS` and `MultiPdbOracleConnectionPool` for Oracle-to-DMS-to-MSK-to-Openflow pipelines. This NAR requires separate installation and is not shipped in the standard runtime image. - CDC MySQL: Reads source `TIMESTAMP` values as `LocalDateTime` instead of through the server-timezone-dependent JDBC timestamp path, preventing shifted values in Snowflake snapshots from non-UTC MySQL servers. - CDC SQL Server: Preserves the original per-row time zone offset of `datetimeoffset` columns when writing to Snowflake `TIMESTAMP_TZ`, instead of converting them to UTC. Values replicated before this change remain in UTC; re-snapshot the table to correct historical rows. - Dataverse: Microsoft Dataverse table ingestion can now optionally include display-friendly formatted values for choice, status, lookup, currency, and date fields in the `_DATAVERSE_FORMATTED_VALUES` object while preserving the original raw values. - CDC SQL Server: Logs a repeated WARN with manual remediation SQL when capture-instance rotation is blocked by a missing or non-executable `sf_openflow_cdc_enable_table` or `sf_openflow_cdc_disable_table` wrapper procedure, instead of failing the incremental run. ### Connectors 2026.8.6.1 - CDC MySQL 0.56.0: Set `connectionTimeZone=UTC` and `forceConnectionTimeZoneToSession=true` as JDBC dynamic properties in the connector flow so snapshot timestamps are normalized to UTC regardless of the MySQL server configuration. - Workday 0.15.0: Fixed intermittent column and data misalignment in Workday RaaS ingestion caused by the API returning fields in non-deterministic order. The `INSERT` now uses column-name matching (`UNION ALL BY NAME`) instead of positional `SELECT *`, preventing data from landing in the wrong columns. ## August 4, 2026 ### Runtime Server 2026.8.4.2 - Security patches and dependency upgrades. ### Runtime Extensions 2026.8.4.8 - CDC SQL Server: Fixed a rare data-loss condition where, under concurrent writes and multi-threaded processing, some committed change rows could be skipped. Change reads are now bounded by the committed log watermark so every committed change is captured. - CDC SQL Server: Fixed an issue where data committed shortly before a schema change could be silently dropped when the connector rotated to a new capture instance. - CDC SQL Server: Fixed O(n^2) change-table drain performance by making keyset pagination seekable. Users with large or busy tables may have seen steadily increasing end-to-end CDC lag as the change table grew. - CDC SQL Server: Fixed an issue where lifting a column exclusion filter did not restore the column in downstream replication without restarting the processor. - CDC SQL Server: Fixed an issue where re-adding a table after schema changes while it was excluded from replication could fail with a data continuity gap. - CDC SQL Server: The connector now emits an actionable WARN bulletin with manual CDC guidance when automatic capture-instance rotation fails. - CDC Oracle: Tables replicated with a user-defined logical key whose key columns contain NULLs now merge correctly — updates and deletes match NULL-valued keys instead of missing them. - CDC Oracle: Tables replicated with a user-defined logical key whose key columns contain NULLs no longer force those columns to NOT NULL in the destination, allowing such rows to load. - Snowflake: Connectors using the placeholders_snowflake_managed merge strategy now use a single-pass journal read for tables with 10 or fewer changed columns, reducing merge compilation time and eliminating a class of internal query errors. - CDC PostgreSQL: The connector now emits a WARN bulletin when a replication slot is created against a PostgreSQL 17+ standby, indicating that the slot was created without the failover flag and will need to be recreated if the primary fails over. - CDC Databases: Removed a noisy WARN bulletin that CDC Merge processors could emit when a parameter has not yet been rolled out to a deployment. - Amazon Ads: The connector now honors Amazon's rate-limit (HTTP 429) responses. Report status checks that are rate-limited are retried instead of failing, preventing in-progress reports from being abandoned during transient rate limiting. - MongoDB: Added StandardDocumentDB Service with initial support for connecting to Amazon DocumentDB using an Access Key. ### Connectors 2026.8.4.1 - Salesforce: Removed backpressure before WaitForBulkJobs processor. Backpressure may have caused issues in the gate releasing mechanism that is in place for cost optimization of the warehouse usage when running the merge queries. - Jira: Standard merge path now takes the _SNOWFLAKE_HASH column into account, preventing unnecessary updates when only hash differs. - Salesforce: Added parameter to enable detailed per-object record operation metrics (created, updated, deleted) for the merge query. ## August 11, 2026 ### Control Plane Core 0.128.0 - Security patches and dependency upgrades. ### Data Plane Service 0.128.0 - Security patches and dependency upgrades. ### Control Plane UI 0.87.0 - Security patches and dependency upgrades. ### Data Plane UI 0.20.0 - Security patches and dependency upgrades. ### Runtime Operator 0.73.0 - Security patches and dependency upgrades. ### Ingress Controller 2026.8.10-2 - Security patches and dependency upgrades. ### SPCS Data Plane Agent 1.44.0 - Security patches and dependency upgrades. ### AWS Data Plane Agent 1.60.0 - A requested Deployment upgrade now triggers as soon as possible instead of waiting up to 10 minutes. - Fixed issues that occasionally cause Deployment upgrades and teardowns to fail. - Security patches and dependency upgrades. ## August 3, 2026 ### Control Plane Core 0.127.0 - Security patches and dependency upgrades. ### Data Plane Service 0.127.0 - Fixed an issue causing false Upgrade Failed results when resizing a multi-node Runtime. - Security patches and dependency upgrades. ### Control Plane UI 0.86.0 - Fixed textareas sometimes displaying as a single line. - Security patches and dependency upgrades. ### Runtime Operator 0.72.0 - Security patches and dependency upgrades. ### Openflow Runtime Gateway 2026.7.29.14 - Security patches and dependency upgrades. ### Ingress Controller 2026.7.29-14 - Security patches and dependency upgrades. ### Openflow Token Refresher 1.18.0 - Security patches and dependency upgrades. ### SPCS Data Plane Agent 1.43.0 - Improved diagnostic bundle to include runtime certificate and truststore metadata. - Security patches and dependency upgrades. ### AWS Data Plane Agent 1.59.0 - Fixed a permission issue that caused upgrade failures for deployments using a custom Ingress. - Improved security group configuration for BYOC Custom Ingress. - Improved diagnostic bundle to include runtime certificate and truststore metadata. - Added support for optional recursive DNS nameservers in cert-manager configurations. - Security patches and dependency upgrades. ## July 30, 2026 ### Runtime Server 2026.7.30.2 - Security patches and dependency upgrades. - Applied `autoResumeState` when scheduling Controller Services so recovery mode can enable controller services. ### Runtime Extensions 2026.7.30.2 - Snowflake: Exposed COPY INTO result metadata through an opt-in connection property and allowed ExecuteSQLStatement to write query result sets as FlowFile content. - Jira: Added ingestion-completion marker FlowFiles on the `last.page` relationship so Jira connector flows can reliably detect successful completion, including empty result sets. ### Connectors 2026.7.30.1 - Amazon Ads: Fixed incremental ingestion so overlapping report windows delete prior rows before inserting refreshed data, preventing duplicate rows from accumulating. ## July 29, 2026 ### Runtime Extensions 2026.7.29.18 - CDC Databases: Added a Max-by aggregate merge strategy for tables without primary-key changes, reducing Snowflake merge compilation time on wide tables by using MAX_BY aggregation instead of per-column window functions. - CDC Databases: Fixed runtime restart delays where Table State Services could delay controller-service enablement, causing connector flow synchronization failures after upgrades or restarts. - CDC PostgreSQL: Accounted for PostgreSQL TOAST data when splitting snapshot reads into CTID chunks, preventing oversized chunks from running for minutes on wide tables with large text or binary columns. ## July 28, 2026 ### Runtime Server 2026.7.28.2 - Security patches and dependency upgrades. - Upgraded the Runtime UI to version 0.83.0. - Handled migration-created Controller Services as environmental changes in Versioned Flows. ### Runtime Extensions 2026.7.28.12 - CDC SQL Server (CDC): Uses the committed database watermark for idle checkpoints to prevent potential data loss when no changes are flowing. - CDC Oracle: Allows schema-fetch connection errors to recover gracefully instead of stalling the connector indefinitely. - Jira Cloud: Skips boards that Jira's API cannot serve (HTTP 422) instead of failing the entire sync. - Salesforce: Translates the string + operator as SQL concatenation and resolves cross-object formula operand types from the destination schema. - CDC Databases: Adaptive insert-only fast path that bypasses MERGE and uses direct INSERT when a batch contains only inserts, improving throughput. - CDC SQL Server: Exposes replication.key.source property so Change Tracking connectors can derive destination PK metadata from the source. - CDC SQL Server: Supports tables without primary keys using logical key configuration and unique-key fallback strategy. - CDC MySQL: GTID position encoding enabling fine-grained deduplication to prevent duplicate rows after restarts. - CDC MySQL: Server UUID failover detection that automatically detects replica promotion and adjusts replication position. - CDC MySQL: GTID availability detection that selects binlog or GTID-based replication automatically from the first connection. - Corrected paging for Branches in BitBucket Flow Registry Client. ### Connectors 2026.7.28.1 - CDC SQL Server (CDC): Wires the Table Key Configuration Service into the connector so customers can declare a logical replication key. - CDC Oracle, MySQL, & SQL Server: Adds configurable Error Handling Strategy parameter allowing invalid rows to be logged and skipped instead of failing the table. ## July 24, 2026 ### Data Plane Service 0.125.1 - Fixed an issue where changing the minimum or maximum number of nodes for a Runtime would incorrectly mark it as "Update Failed" when it actually succeeded. ### AWS Data Plane Agent 1.55.1 - Security patches and dependency upgrades. ### SPCS Data Plane Agent 1.40.1 - Security patches and dependency upgrades. ## July 23, 2026 ### Runtime Server 2026.7.23.7 - Upgraded the Runtime UI to version 0.82.0: - Fixed create endpoint target form field alignment issues. - Sanitized route and query-derived segments in NiFi API URLs to prevent path injection. - Included eventId in provenance lineage requests. - Addressed security findings: log injection via unvalidated URL params, StoreDevtools exposed in production builds, and sensitive data in error telemetry. - Fixed textareas clamped to one line under Angular Material 21. ### Runtime Extensions 2026.7.23.16 - CDC SQL Server: Downgraded transient source-connection failure logs from ERROR to a descriptive WARN with the attached root cause, reducing alert noise during brief network interruptions. - CDC MySQL: Added support for MariaDB legacy column types that were previously unrecognized during replication. - CDC Databases (multi-database): Fixed an issue where the Table State Store could run incorrectly on multi-node environments. - CDC Oracle: Switched ResultSet column access from name-based to index-based lookup to avoid ambiguous column errors. - Security patches and dependency upgrades. ### Connectors 2026.7.23.1 - Salesforce Bulk API: Added an "Iceberg Version" parameter to the connector flow, allowing users to select Iceberg version 2 or 3 when using Iceberg as the table storage format. ## July 22, 2026 ### Control Plane Core 0.125.0 - Enabled Oracle PubSec Connector for eligible accounts. - Promoted SQL Server CDC to GA. - Security patches and dependency upgrades. ### Control Plane UI 0.85.0 - Security patches and dependency upgrades. ### Data Plane UI 0.19.0 - Fix alignment in Create Endpoint Target form. - Enhancements and usability improvements for Gen 2 Connectors and Runtimes (Private Preview). ### AWS Data Plane Agent 1.55.0 - Hardened the Terraform state S3 bucket (`byoc-tf-state-{key}-{Region}`) on every reconcile: enforces AES256 default encryption, blocks public access, and applies a restrictive bucket policy that denies non-TLS access. The agent's Terraform-managed IAM policy is updated automatically on upgrade to grant the required S3 actions (`s3:PutEncryptionConfiguration`, `s3:PutBucketPublicAccessBlock`, `s3:PutBucketPolicy`, and their Get/Delete counterparts). **Note:** If your AWS account is governed by an AWS Organizations Service Control Policy (SCP) that explicitly denies `s3:PutEncryptionConfiguration`, `s3:PutBucketPublicAccessBlock`, or `s3:PutBucketPolicy` on the state bucket, the upgrade will fail with a 403 AccessDenied error. An SCP explicit deny overrides IAM allows, so you must add a scoped SCP exception for the Openflow agent role `openflow-agent-role-{key}` on the state bucket resource (or an equivalent SCP exception) before upgrading to 1.55.0. - Fixed intermittent installation failures in regions with slower IAM propagation, preventing AccessDenied errors on secretsmanager:GetRandomPassword during fresh installs. - Security patches and dependency upgrades. ### SPCS Data Plane Agent 1.40.0 - Security patches and dependency upgrades. ### Runtime Operator 0.69.0 - Fixed an issue that prevented updates for multi-node Runtimes using custom NARs. ### Data Plane Service 0.125.0 - Security patches and dependency upgrades. ### Ingress Controller 2026.7.22-0 - Security patches and dependency upgrades. ### Openflow Runtime Gateway 2026.7.22-0 - Security patches and dependency upgrades. ### Openflow Token Refresher 1.17.0 - Security patches and dependency upgrades. ## July 20, 2026 ### Control Plane Core 0.124.0 - Fixed case where a Snowflake Deployment can get stuck in UPGRADING state. - Fixed issue where a Snowflake Deployment won't heal from Upgrade Failed to Active if its version already matches the latest available version. - Fixed case where a Runtime in Upgrade Failed state doesn't refresh its upgrade available flag if a new version is released. - Renamed SQL Server connector to SQL Server CT. - Security patches and dependency upgrades. ### Data Plane Service 0.124.0 - Improved Runtime Upgrade reliability by waiting for NiFi cluster connected nodes before creating Snowflake Connection Service during the upgrade. - Security patches and dependency upgrades. ### Control Plane UI 0.84.0 - Conditional recovery mode option for Upgrade and Resume dialogs. - Security patches and dependency upgrades. ### Data Plane UI 0.18.0 - Security patches and dependency upgrades. ### Runtime Operator 0.68.0 - Security patches and dependency upgrades. ### Openflow Runtime Gateway 2026.7.14.19 - Security patches and dependency upgrades. ### Ingress Controller 2026.7.17-19 - Security patches and dependency upgrades. ### Openflow Token Refresher 1.16.0 - Security patches and dependency upgrades. ### SPCS Data Plane Agent 1.39.0 - Fixed race condition during upgrade readiness checks to improve reliability of Deployment upgrade. - Reduced agent heartbeat frequency from 30 seconds to 1 minute to reduce load and align with AWS agent frequency. - Security patches and dependency upgrades. ### AWS Data Plane Agent 1.54.0 - Refreshed diagnostic bundle script to capture the latest components including Openflow Ingress Controller. - Supported Agent Host OS refresh during upgrade flow. - Security patches and dependency upgrades. ## July 21, 2026 ### Runtime Server 2026.7.21.8 - Security patches and dependency upgrades. - Increased the CDC metrics cardinality limit from 50,000 to 75,000 time-series entries, preventing metric ingestion failures for customers with high numbers of replicated tables. - Upgraded the Runtime UI to version 0.81.0: - Adds support for creating a new branch directly from the UI when saving a flow version via Flow Registry Clients. - Adds a Flow Version Diff View in the change-version dialog, letting users compare what changed between two flow versions before upgrading. ### Runtime Extensions 2026.7.21.11 - Snowflake: The Snowflake Parameter Provider can now resolve external secrets stored in Azure Key Vault via a Snowflake security integration, in addition to the existing AWS Secrets Manager support. - CDC SQL Server CT: Fixes a bug where the primary-key cursor value for one table could leak into a different table's Change Tracking position query. When the leaking table had a bigint primary key and the target table had an int key, the connector would bind an out-of-range value into an integer predicate and fail with SQL Server error 8115 ("Arithmetic overflow error converting expression to data type int"), causing affected tables to be permanently marked FAILED. - CDC SQL Server CDC: Fixes an infinite retry loop triggered when a SQL Server CDC column undergoes an incompatible type change applied via a CDC disable → ALTER COLUMN → re-enable cycle. The connector now detects the schema change, emits a DDL event with the new column definition, and resumes replication. - CDC Databases: Tables that fail replication permanently (for example, tables missing a primary key) now remain in the FAILED state and are no longer inadvertently re-queued for snapshot replication by concurrent processors. - CDC SQL Server & Oracle: Batches multiple table-state removal operations into a single write during cleanup, reducing state I/O overhead when many tables are removed at once. - Salesforce: Adds a new FetchSFDCBlobContent processor that resolves Salesforce URL sentinels in blob fields (such as Attachment.Body and ContentVersion.VersionData) by calling the Salesforce content endpoint and replacing each sentinel with base64-encoded binary content. - Salesforce: Extends the formula view to support chained formula fields — formula fields that reference other formula fields, including cross-object chains. - Salesforce: Formula view columns that could not be translated now include the original Salesforce formula expression in their failure comment, making it easier to understand which construct was unsupported. ### Connectors 2026.7.21.1 - CDC MySQL, CDC PostgreSQL, CDC SQL Server, and Oracle: Adds an "Iceberg Version" parameter to database connector flows. When using Iceberg as the table storage format, users can now select Iceberg version 2 or 3. - Salesforce Bulk API: Adds support for capturing and ingesting binary blob fields (such as Attachment.Body and ContentVersion.VersionData) from Salesforce objects. - Atlassian Jira Core: Adds four lookup tables (STATUS, PRIORITY, RESOLUTION, and ISSUE_TYPE) alongside the existing ISSUE fact table, containing human-readable names for the numeric IDs previously stored on ISSUE. This unblocks customers who need to join Jira reference data to issue records. ## July 16, 2026 ### Runtime Server 2026.7.16.2 - Security patches and dependency upgrades. ### Runtime Extensions 2026.7.16.14 - CDC SQL Server: Verifies at startup that the required CDC wrapper stored procedures exist and the configured role has `EXECUTE` permission, providing actionable errors instead of runtime failures. - CDC SQL Server: Hardened SQL Server CDC enable and disable wrapper scripts to work correctly in Azure singleton configurations. - Jira: Fixed the default field value in `FetchJiraResolutions` so the correct field is selected on first run without manual configuration. - CDC PostgreSQL: Stopped setting the `failover` flag on replication slots on standby servers where that flag is not permitted, preventing slot creation failures. - CDC MySQL, CDC PostgreSQL: Verifies at startup that the execute-as role has write permission on the destination database, surfacing access issues before replication begins. - Snowflake Processors: Added an Iceberg Version property to `UpdateSnowflakeTable` to control which Iceberg format version is written. - CDC SQL Server: Detects when the SQL Server CDC retention purge removes unconsumed records and triggers an inventory refresh to recover automatically. - Snowpipe Streaming: Changed HTTP 429 and 503 throttling responses from error to info level, reducing alert noise during normal Snowflake backpressure. - CDC PostgreSQL: Disconnects the replication stream on SQL exception, preventing the connector from hanging on a broken connection. ### Connectors 2026.7.16.1 - CDC MySQL, CDC PostgreSQL, CDC SQL Server, CDC Oracle: Changed the default merge schedule from once per hour to once per minute for all database connectors, reducing data latency with default settings. - CDC MySQL, CDC PostgreSQL: Removed the "Schedule Warehouse" processor step from MySQL and PostgreSQL connector flows, simplifying the pipeline. - CDC PostgreSQL: Added a Dead Letter Queue (DLQ) to the PostgreSQL CDC connector, routing failed records to a separate queue instead of blocking replication. - Salesforce: Fixed view creation for Salesforce formula fields with cross-object references that previously caused incorrect or failed view generation. ## July 14, 2026 ### Runtime Server 2026.7.14.2 - Security patches and dependency upgrades. - Fixed a load-balanced connection desynchronizing socket after an in-flight transaction was unregistered. - Added Flow Registry Client Synchronization Interval property. ### Runtime Extensions 2026.7.14.2 - Salesforce — Fixed formula view compilation failures that occurred when a formula field references a non-replicated column or related object. - Salesforce — Fixed incorrect SQL generated by the ISBLANK and BLANKVALUE operators for DATE, TIMESTAMP, and numeric formula fields. - CDC Oracle — Fixed an issue where CaptureChangeOracle stalled after encountering invalid log positions following a node restart. - CDC Oracle — Isolated per-table schema conversion failures in CaptureChangeOracle so that an error on one table no longer halts incremental ingestion for all other tables. ### Connectors 2026.7.14.1 - Salesforce — Fixed jobs not being marked as FAILED when the Salesforce Bulk API is unreachable during result retrieval. - Salesforce — Split large outbound FlowFiles into bounded chunks to prevent oversized Snowpipe Streaming v2 fragments during replication. ## July 9, 2026 ### Runtime Server 2026.7.9.19 - Security patches and dependency upgrades. - Fixed a flow synchronization failure that occurred when a Parameter Provider-backed Parameter Context contained a parameter not flagged as provided. ### Runtime Extensions 2026.7.9.19 - CDC Databases — Reconciled single-database and multi-database TableStateChangeReason handling. As a result, some error codes between 4025 and 4035 might indicate different failure reasons than they did before. - CDC PostgreSQL — Added support for PostgreSQL 17+ major-version upgrades and failovers. - CDC Databases (multi-database) — Added a configurable merge schedule to the multi-database journal merge processor. - CDC Databases — Added merge schedule configuration to the MergeSnowflakeJournalTable processor. - CDC Oracle — Oracle's unbounded NUMBER type is now mapped to DECFLOAT. ### Connectors 2026.7.9.18 - Salesforce — Added Snowflake Managed Iceberg table format support to the Salesforce Bulk API connector (preview). - BigQuery — Improved column selection for the BigQuery journal. ## July 7, 2026 ### Control Plane Core 0.122.0 - Fixed automatic upgrades of Snowflake Deployments prematurely transitioning to Active while an upgrade is still progressing. - Fixed automatic upgrades of Snowflake Deployments incorrectly moving to Not Reporting state instead of Upgrade Failed when the Deployment is unhealthy. - Security patches and dependency upgrades. ## July 6, 2026 ### Runtime Server 2026.7.6.18 - Security patches and dependency upgrades. - Newly added Controller Services are now enabled automatically when you upgrade a version-controlled flow. ### Runtime Extensions 2026.7.6.18 - Kinesis — Fixed a lingering rename lock that could remain after an error in ConsumeKinesis. - CDC SQL Server — Large partitioned tables can now be snapshotted partition by partition, so initial loads run faster and a failure affects only one partition. - CDC SQL Server — Snapshot fetch automatically uses a partition-aware strategy when partition information is available. - CDC SQL Server — Snapshot completion tracking is now configurable (count- or marker-based) to support partition-aware loading. - CDC SQL Server — Transient Change Tracking errors are now retried before a table is marked failed, avoiding manual re-snapshots. - CDC PostgreSQL — Re-snapshotting a table that already exists in Snowflake now refreshes it in place instead of failing. - CDC PostgreSQL and Oracle — Dates with years outside Snowflake's supported range are now adjusted to the nearest valid value instead of failing the load. - CDC Oracle — Fixed a slow schema-discovery query on databases with very large numbers of tables. - CDC Databases — Added a Snowflake-managed option that automatically selects the best merge strategy per table based on its column count. - Dataverse — Restored the last-page indicator on the Fetch Microsoft Dataverse Table processor. ### Connectors 2026.7.6.17 - CDC SQL Server — Connector flows now use partition-aware snapshot loading for faster initial loads of large partitioned tables. - Oracle — Added an Oracle connector variant for public-sector deployments (embedded license). - Salesforce — Migrated the Salesforce Bulk API connector to the newer, more reliable ingestion path (Snowpipe Streaming v2). - CDC MySQL, Oracle, and PostgreSQL — Tuned connection pool sizing to prevent connection exhaustion during snapshots. ## June 30, 2026 ### Control Plane Core 0.121.1 - Fixed an issue causing Runtime deletion failures in some old AWS deployments. ### Runtime Operator 0.65.0 - Fixed an issue that blocked Runtime upgrades when a scaling-down cluster node reconnected to the cluster before being fully stopped. - Security patches and dependency upgrades. ### AWS Data Plane Agent 1.51.0 - Fixed an issue that blocked upgrades of older BYOC deployments due to conflicts with the metrics server deployment. - Security patches and dependency upgrades. ### SPCS Data Plane Agent 1.36.0 - Improved resource utilization for high telemetry use cases. ### Runtime Server 2026.6.30.15 - Security patches and dependency upgrades. - Gen 2 Connectors: You can now use secrets stored in AWS Secrets Manager (through Snowflake) for connector credentials. ### Runtime Extensions 2026.6.30.15 - CDC MySQL — You can now tell the MySQL connector which column(s) uniquely identify each row, so change capture works on tables that don't have a primary key. - Shopify — Added a new sign-in option (client-credentials / custom app) for connecting to Shopify. - CDC SQL Server — When the connector hits a SQL Server error it can't retry, it now records clearer details so you can understand why ingestion stopped. - CDC Databases — Large rows are now compressed as they are read, lowering memory use and improving performance when capturing wide tables. - CDC Oracle — Fixed a problem where checking an Oracle connection could fail because the database driver wasn't loaded; validation now works reliably. - CDC PostgreSQL — You can now tell the PostgreSQL connector which column(s) uniquely identify each row, so change capture works on tables without a primary key. - Snowpipe Streaming — Added support for Elastic Channels, which scale automatically to handle higher streaming volumes. - Snowpipe Streaming — Compressed (zstd) input is now detected and handled automatically, so no extra setup is needed. - CDC Databases — When capturing from multiple databases, you can now choose how changes are merged into Snowflake (Snowflake-managed or adaptive). ### Connectors 2026.6.30.15 - CDC MySQL and PostgreSQL — Connector flows now support user-declared keys end to end, so you can capture changes from tables without a primary key. - Shopify — Connector flow now supports the new client-credentials sign-in option. - CDC Oracle — Fixed setup so the tracking-table creation step runs in the right order, avoiding occasional setup failures. - CDC Oracle — Made the connector faster by increasing parallelism and tuning how data is fetched. ## June 29, 2026 ### Runtime Server 2026.6.29.22 - Fixed an issue that prevented Runtimes on versions 2026.6.22 - 2026.6.25 from scaling down properly. ## June 26, 2026 ### Control Plane Core 0.121.0 - Oracle CDC connector with an upfront payment option is now available in the connector catalog (Private Preview). - MongoDB connector is now available in the connector catalog (Public Preview). - Force-delete support for Gen 2 connectors: operators can now terminate connectors stuck in a failed state via a force flag on the delete API, triggering a full NiFi queue drain and purge before resource removal. - Security patches and dependency upgrades. ### Control Plane UI 0.83.0 - New connector troubleshooting states and task types are now recognized and surfaced in the UI. - "Go to Observability" shortcut from the connector listing navigates directly to Snowsight monitoring. - Fixed an issue where the Snowsight deep-link URL was malformed on accounts whose account URL carries the SPA hash prefix. - "Add" button renamed to "Install" in the Select Runtime connector dialog for clarity. - Security patches and dependency upgrades. ### Data Plane Service 0.121.0 - Enabled Gen 2 connector troubleshooting workflow using NiFi troubleshooting mode. - Connector deletion now purges NiFi queues and drains active processing before removing resources. - Improved support for installing Gen 1 connectors for users with many roles. - Security patches and dependency upgrades. ### Data Plane UI 0.17.0 - Security patches and dependency upgrades. ### Runtime Operator 0.64.0 - Security patches and dependency upgrades. ### Openflow Runtime Gateway 2026.6.25.18 - Security patches and dependency upgrades. ### AWS Data Plane Agent 1.50.0 - Fixed an issue where a deployment upgrade that eventually succeeds would prematurely report an upgrade failure due to transient AWS API errors during the EKS upgrade process. - Security patches and dependency upgrades. ### SPCS Data Plane Agent 1.35.0 - Security patches and dependency upgrades. ## June 25, 2026 ### Runtime Server 2026.6.25.16 - Security patches and dependency upgrades. ### Runtime Extensions 2026.6.25.16 - CDC MySQL, CDC PostgreSQL: Fixed a silent data-loss issue where re-running an initial snapshot could reuse a stale streaming channel and skip rows; snapshot channels are now uniquely identified per run. - CDC MySQL: Fixed a crash where an empty binary JSON value in the MySQL binlog permanently failed the entire table; the connector now maps empty binary JSON values to NULL and continues replication. - CDC Databases: Removed spurious schema-checksum error log entries that appeared after a source table was dropped. ### Connectors 2026.6.25.16 - SharePoint: Made page-splitting during OCR of multi-page documents a configurable parameter on the SharePoint connectors. - SharePoint: Added chunk size and chunk overlap parameters to the SharePoint Cortex AI connectors for controlling how document text is segmented before embedding, enabling tuning for RAG and vector-search retrieval quality. - CDC PostgreSQL: Added a CTID-based snapshot strategy for PostgreSQL 14+ that enables faster initial snapshots on large tables and tables without a primary key. - CDC MySQL: Snapshots against an existing Snowflake table now archive the table as a zero-copy clone, then truncate and reload in place instead of failing, preserving attached Snowflake streams so CDC resumes automatically after the snapshot. ## June 23, 2026 ### Runtime Server 2026.6.23.15 - Security patches and dependency upgrades. ### Runtime Extensions 2026.6.23.15 - Added Hex header encoding option to `ConsumeKafka`. - Jira: Adds `FetchJiraIssueTypes`, `FetchJiraPriorities`, `FetchJiraResolutions`, and `FetchJiraStatuses` processors for looking up Jira metadata dictionaries in flows. - CDC SQL Server: Fixes tables being permanently evicted to `FAILED` during SQL Server Multi-AZ/AG failover by marking inaccessible databases as `UNAVAILABLE` instead of dropping them. - CDC Oracle: Fixes list-tables and license-validation queries to be compatible with Oracle 11.2.0.4. - CDC PostgreSQL: Adjusts partition size limits, timeout settings, and query generation in `SplitPostgreSQLTable` and `FetchRowsByCtid`. - CDC SQL Server: Fixes a permanent arithmetic overflow (8115) when computing the last-row commit time by executing the timestamp lookup in a separate standalone query. - CDC Databases (multi-database): Fixes an out-of-memory error in snapshot by deferring catalog restore until after the ResultSet is fully consumed. - Snowpipe Streaming: Fixes `ALTER TABLE` statements in `UpdateSnowflakeTable` being routed to "table exists"; they are now correctly routed to "failure". - CDC Oracle: Fixes license validation to look up historical database IDs so connectors remain valid after a database migration. - CDC PostgreSQL: Adds `SplitPostgreSQLTable` and `FetchRowsByCtid` processors enabling CTID-based parallel table snapshot. - CDC PostgreSQL and CDC MySQL 2nd Gen: Connector verification only attaches error messages to a field when the error is directly caused by that field. ### Connectors 2026.6.23.15 - CDC PostgreSQL: Adds a group-snapshot-by-primary-key step to the connector flow. - CDC PostgreSQL: Adds clone-and-truncate snapshot promotion strategy to the connector flow. ## June 18, 2026 ### Runtime Extensions 2026.6.18.9 - Snowpipe Streaming: Added per-batch error and invalid row counts as FlowFile attributes in Snowpipe Streaming v2 processors, allowing downstream flows to react to partial delivery failures. - CDC Oracle (multi-database): Added support for Oracle 11.2.0.4 by handling the absence of the `USER_GENERATED` column in `ALL_TAB_COLS` when listing columns for replication. - CDC Databases: Added rows-inserted and rows-updated counters to MergeSnowflakeJournal processors so throughput metrics are visible per processor. - CDC SQL Server (multi-database): Fixed slow keyset pagination scans on busy change tables by aligning the CDC query ordering with the SQL Server clustered index key order. - CDC Databases: Fixed missing failure reasons for clone-and-truncate snapshot promotion failures. `SCHEMA_RECONCILE_FAILED`, `CLONE_TO_ARCHIVE_FAILED`, and `TRUNCATE_DESTINATION_FAILED` are now correctly persisted in the table state. - Jira: Fixed column names for Jira custom fields whose display names start with a digit; the leading digit was previously dropped from the resulting column name. - CDC Oracle (multi-database): Reduced the XStream batch acknowledgment interval to improve progress tracking speed and allow faster detach during pauses. - CDC SQL Server: Reduced memory overhead when replicating binary column types (`binary`, `varbinary`, `image`, `hierarchyid`) by avoiding large intermediate allocations during JSON serialization. ### Connectors 2026.6.18.9 - CDC SQL Server (multi-database): Added Iceberg table storage format support to the SQL Server multi-database CDC connector, enabling Iceberg-format destination tables. ## June 17, 2026 ### Control Plane Core 0.120.0 - Added support for upgrading runtimes in Recovery Mode, which skips automatically starting the flow when it is preventing the runtime from fully upgrading. - Security patches and dependency upgrades. ### Control Plane UI 0.82.0 - Introduced Gen 2 indicators and filters throughout the UI to differentiate between Gen 1 and Gen 2 resources. - Added Recovery Mode option during the Upgrade Runtime action. - Fixed manage access dialog privilege label wrapping and row misalignment. - Updated text for disabled Deployment options to "Not available". - Filtered out non-Gen 2 Runtimes when installing Gen 2 Connectors. - Security patches and dependency upgrades. ### Data Plane Service 0.120.0 - Added support for upgrading runtimes in Recovery Mode, which skips automatically starting the flow when it is preventing the runtime from fully upgrading. - Security patches and dependency upgrades. ### Runtime Operator 0.63.0 - Security patches and dependency upgrades. ### Openflow Runtime Gateway 2026.6.12.19 - Security patches and dependency upgrades. ### Ingress Controller 2026.6.11-13 - Security patches and dependency upgrades. ### Openflow Token Refresher 1.15.0 - Security patches and dependency upgrades. ### AWS Data Plane Agent 1.49.0 - Improved diagnostics bundle to include directory walk and system service status. - Increased metrics support for CDC Connectors with large numbers of tables in replication. - Upgraded Openflow BYOC to use the latest AWS EKS 1.36. - Security patches and dependency upgrades. ### SPCS Data Plane Agent 1.34.0 - Security patches and dependency upgrades. ## June 16, 2026 ### Runtime Server 2026.6.16.13 - Upgraded the Openflow UI frontend from 0.76.0 to 0.78.0. Notable improvements include: - Added the ability to run, stop, and change the run status of individual components via the context menu in connector troubleshooting mode. - Added support for upgrading connectors in recovery mode from the runtime canvas. - Added a "View Documentation" action for processors directly from the connector canvas. - Enabled editing component configuration from the canvas configure dialogs. - Added support for dragging a connection endpoint to a new destination processor. - Added "Go to Source" and "Go to Destination" navigation actions for connections on the canvas. - Added access to Processor Advanced custom UI in connector troubleshooting mode. - Fixed canvas SVG transform producing `scale(Infinity)` when two components are placed at the same position, causing them to overlap. - Fixed an issue preventing deselection of a currently selected component. ### Runtime Extensions 2026.6.16.10 - SharePoint: Added optional extended metadata fetching, allowing additional SharePoint item properties to be included in the data extracted by the connector. - CDC MySQL, CDC PostgreSQL: Capped the number of concurrent queries at 8 to prevent resource exhaustion under heavy load. - CDC Oracle: Fixed a CaptureChangeOracle processor failure during connection verification when SSL is enabled. - CDC MongoDB: Fixed a snapshot and CDC ID mismatch for MongoDB Date and Binary BSON types that could cause data inconsistencies. - CDC Databases: Fixed a stray SQL comma in the JOURNAL\_CHANGES CTE generated when all payload columns are primary key columns, preventing merge query failures. - CDC PostgreSQL: Added validation in the Summary setup step to ensure all configured tables exist in the PostgreSQL publication. - CDC PostgreSQL: Added WAL level validation during connector setup with clearer error messages when the replication level is insufficient. - CDC MySQL: Added a TableStorageFormat configuration option to the Gen 2 MySQL Connector for controlling the destination table storage format. ### Connectors 2026.6.16.9 - CDC PostgreSQL, CDC MySQL, CDC Oracle, CDC SQL Server: Updated snapshot channel groups to use the `table.state.created` event, improving snapshot lifecycle reliability. - CDC Oracle — Adds a TableStorageFormat configuration option to the Oracle Connector for controlling destination table storage format. This adds support for snowflake managed catalog iceberg destination. ## June 12, 2026 ### Runtime Server 2026.6.12.19 - Security patches and dependency upgrades. ### Runtime Extensions 2026.6.12.19 - CDC MySQL: Added a configurable Destination Schema Strategy, allowing users to control how source schemas map to Snowflake destination schemas (for example, use only the source schema name, add a prefix or suffix, or apply a custom pattern), matching the capability already available in the CDC PostgreSQL connector. - Snowpipe Streaming: Fixed spurious "Invalid Rows" warnings and incorrect routing of FlowFiles to the INVALID relationship caused by the error count not being initialized from the streaming channel when creating a status placeholder. - CDC PostgreSQL: Improved cron schedule validation error messages to be accurate and user-friendly, and added support for cron macros such as @hourly and @daily. ### Connectors 2026.6.12.17 - MongoDB: Removed the separate AddSnowflakeSpecificColumns processor from the Snapshot flow, integrating that behavior directly into FetchMongoDBConnectionSnapshot for improved performance. ## June 11, 2026 ### Runtime Server 2026.6.11.18 - Security patches and dependency upgrades. ### Runtime Extensions 2026.6.11.18 - Jira: Reduced memory consumption in all Jira processors by streaming API responses rather than loading entire paginated results into memory at once. - Shopify: Applied code-review fixes and cleanup to the Shopify connector, including improvements to schema derivation, rate-limit handling, and sync state management. - MongoDB CDC: Added record metadata fields to the FetchMongoDBCollectionSnapshot processor output, including source information such as namespace, timestamp, and operation type. - Snowpipe Streaming: Fixed an incorrect date conversion caused by Julian calendar arithmetic in the Snowflake type converter, ensuring dates are consistently handled using the proleptic Gregorian calendar. ### Connectors 2026.6.11.16 - Excel: Added a staging table step to Excel (S3 and SharePoint) connector flows, enabling more reliable data loading before the final merge into the target table. - MongoDB: Migrated the MongoDB connector to Snowpipe Streaming v2 and removed the deprecated "Merge into Bigger" feature flag. - MongoDB CDC: Enabled the WaitForSnapshotCompletion processor in both snapshot and incremental flow phases, improving coordination when a snapshot must complete before incremental processing begins. - CDC SQL Server (multi-database): Set the ListDatabaseTables processor output data format to Grouped, fixing an inconsistency with the expected connector behavior. - Google Drive: Added automatic retry logic for transient Google Drive API failures, reducing connector errors caused by intermittent API unavailability. ## June 9, 2026 ### Runtime Server 2026.6.9.14 - Security patches and dependency upgrades. ### Runtime Extensions 2026.6.9.17 - CDC PostgreSQL: Added a Destination Schema Strategy option, giving users control over how source database schemas map to Snowflake destination schemas (for example, use only the schema name, prefix with the database name, or apply a fixed custom name), matching the capability available in the MySQL CDC connector. - CDC Databases: Added a `table.state.created` timestamp attribute to FlowFiles produced when a new table is added to CDC replication state, enabling downstream processors to distinguish newly-tracked tables and supporting stable Snowpipe Streaming channel naming across table removal and re-add operations. - Security patches and dependency upgrades. ### Connectors 2026.6.9.9 - CDC Oracle and SQL Server: Flattened Oracle (embedded and independent license) and SQL Server multi-database connector flows to simplify the flow structure and remove obsolete parameters. ## June 4, 2026 ### Runtime Server 2026.6.4.18 - Security patches and dependency upgrades. - Fixed date conversion for consistent use of the Proleptic Gregorian Calendar. - Added a size limit to the Standard Content Viewer. - Upgraded the UI frontend to version 0.76.0: - Added support for import/export of flow definitions including component state. ### Runtime Extensions 2026.6.4.18 - Added Parsing Strategy to `JsonTreeReader` and `JsonPathReader` with a Lenient option. - CDC MySQL: Introduced the initial MySQL CDC Connector based on the same architecture as the PostgreSQL CDC connector. - Shopify: Introduced a new Shopify source connector. - CDC Databases: Added a `SNOWFLAKE_MANAGED` merge strategy for the FULL journal type (`ReducedJournalRead` mode), reducing compile time and bytes scanned. - CDC Oracle and SQL Server: Flattened DML record structure to skip the Enrich processor, simplifying the pipeline. - CDC Databases: Added aggregate table status metrics reporting so operators can monitor the health of multiple CDC tables in one view. - CDC MongoDB: Migrated to `DirectJsonRecordWriter`, improving record writing performance and consistency. - Snowpipe Streaming: Deprecated the legacy `PutSnowpipeStreaming2` processor in favor of `PublishSnowpipeStreaming`. - CDC Databases: Increased fetch size in `MultiDatabaseListTableNames` to improve performance when listing a large number of tables. - CDC Databases: Ported sub-chunk part counting to `WaitForSnapshotCompletion`, improving snapshot progress tracking. - Dataverse: Refactored pagination loop for more efficient flow file handling. - SharePoint: Fixed a `NullPointerException` in `FetchSharepointFile` when the `Retry-After` response header is absent. - CDC Databases: Fixed error handling in `getConnection()` within `MergeSnowflakeJournalTable` to prevent silent failures. - CDC SQL Server: Added graceful handling of Change Tracking expiration for inactive databases, preventing pipeline failures. - CDC SQL Server: Added proper non-retryable exception handling to prevent CDC tables from being stuck in an error loop. - CDC Oracle: Excluded index-organized table segments from Oracle table listing to prevent spurious tables from appearing in the connector. - CDC Databases: Added missing query status handling in explicit response processing to prevent unhandled state transitions. ### Connectors 2026.6.4.15 - Shopify: Added versioned flows for the new Shopify source connector. - Dataverse: Tables are now moved to a FAILED status when an error does not recover, preventing silent data loss and alerting operators to problems. - Dataverse: Improved merge scheduling by adding a `GateFlowFile` processor to handle scheduling, reducing unnecessary flow file releases. ## May 22, 2026 ### Runtime Extensions 2026.5.22.12 - CDC SQL Server: Added configurable properties to control which metrics are logged during change tracking capture. - Snowpipe Streaming: Fixed a `NoClassDefFoundError` when using HTTP/HTTPS proxies or Azure internal stages by restoring Netty proxy classes to the Snowflake JDBC NAR. - CDC MySQL: Added Iceberg type override support with unsigned integer handling and proper bit-width mapping for MySQL source columns. - Snowflake: Added a Snowflake Provenance Reporting Task that streams Openflow provenance events to Snowflake via Snowpipe Streaming v2. - Snowpipe Streaming: Reduced log message size for PutSnowpipeStreaming failures by logging FlowFile IDs instead of full object references. - CDC PostgreSQL: Added proper Iceberg type mapping for PostgreSQL integer types using bit-width and temporal precision fields. - CDC Databases: Added bitWidth and temporalPrecision fields to Column for improved schema fingerprinting (v2) without affecting existing v1 connectors. ## May 21, 2026 ### Runtime Server 2026.5.21.15 - Security patches and dependency upgrades. ### Runtime Extensions 2026.5.21.16 - CDC Oracle: Adds support for multiple databases in Oracle CDC connector. - CDC Databases: Adds an adaptive placeholder merge strategy that optimizes merge query performance by reducing journal reads. - CDC SQL Server: Throws a permanent failure when the change tracking version expires due to retention, providing a clear error and marking the table as failed. - Salesforce: Allows currency fields to be treated as float type in the Salesforce describe object operation. - Snowpipe Streaming: Adds wait time information to retry log messages for better troubleshooting. - All connectors: Fixes managed authentication for BYOC deployments in the Snowflake Connection Service. ### Connectors 2026.5.21.15 - Dataverse: Increases max retry attempts on the Dataverse API to improve resilience. - Jira: Fixes the handling of deleted issues in the Jira Core connector. - CDC SQL Server: Adds parameters for Metrics Enabled, Max Batch Size, and Read Timeout. - MongoDB: Changes Schema Access Strategy to infer schema in the MongoDB connector. - CDC Oracle: Strips table selection criteria attributes for Oracle connectors to fix upgrade issues. ## May 20, 2026 ### Control Plane Core 0.116.1 - Improved reliability of Deployment and Runtime actions. - Security patches and dependency upgrades. ### Data Plane Service 0.116.0 - Fixed rare case of Runtime Upgrade Failure determination happening too soon while the upgrade is still processing. - Security patches and dependency upgrades. ### Control Plane UI 0.81.0 - Changed "Snowflake Role" label to "Execute as role" terminology. - Fixed hint for runtimes in the connector install dialog. - Fixed error not shown when querying for the listing of Connectors. - Preserve original route when user is redirected to authenticate. - Fixed issue preventing the link in the hint from opening in connector install dialog. - Security patches and dependency upgrades. ### Data Plane UI 0.16.0 - Security patches and dependency upgrades. ### AWS Data Plane Agent 1.44.0 - Fixed internal certificate renewal process for Openflow Ingress Controller. All customers running BYOC Deployments 1.31.2 - 1.42.0 should upgrade before June 15, 2026. - Improved upgrade reliability by fixing an IAM issue with "DescribeAddonVersions" that temporarily marked deployments as "Upgrade Failed" before automatically recovering. - Fixed redaction of sensitive values in telemetry to allow Key values from the LogAttributes processor to pass through as-is. - Security patches and dependency upgrades. ### SPCS Data Plane Agent 1.30.0 - Improved upgrade reliability by identifying unhealthy PostgreSQL deployment blocking the upgrade process. - Security patches and dependency upgrades. ### Runtime Operator 0.61.0 - Security patches and dependency upgrades. ### Openflow Runtime Gateway 2026.5.13.18 - Security patches and dependency upgrades. ### Openflow Ingress Controller 2026.5.13-18 - Security patches and dependency upgrades. ### Openflow Token Refresher 1.12.0 - Security patches and dependency upgrades. ## May 19, 2026 ### Runtime Server 2026.5.19.16 - Increased the web request timeout from the default to 5 minutes, preventing timeout errors when the runtime is under heavy load or processing large configuration changes. - Fixed connector flow URI pattern matching in cluster response merging that could cause incorrect flow resolution when multiple connectors share similar URI patterns. - Fixed an issue where adding parameters to a Parameter Context with multiple suffixed variants incorrectly applied changes to the wrong context during flow upgrades. - Enabled parameter value expressions to reference parameters defined in inherited parameter contexts. ### Runtime Extensions 2026.5.19.17 - CDC SQL Server (CT): When a Change Tracking query fails for a specific table, the connector now applies a backoff delay to that individual table instead of failing the entire connector run, and includes the table name in the error message for easier troubleshooting. - CDC SQL Server: Fixed a race condition where removing a table from replication and re-adding it before the next scheduler cycle caused the table to silently stop being processed until a full connector restart. - CDC SQL Server (CDC): Proactively detects source-table schema changes (DDL) by polling cdc.ddl_history, and detects when CDC is disabled mid-replication; affected tables are now moved to FAILED state instead of looping indefinitely on transient errors or producing rows against a stale schema. - CDC SQL Server (CT): Adds the table name to the error message when change tracking is found to be disabled on a table, making it clear which table needs attention. - CDC MySQL: Adds defensive type validation during binary log parsing to prevent corrupted records when a MySQL column returns an unexpected data type (for example, after an undetected schema change). - Snowpipe Streaming: Fixed URI path segment encoding so that database, schema, or table names containing special characters (spaces, hyphens, mixed case) no longer cause channel-open failures; uses RFC 3986 compliant encoding instead of URL form encoding. - Snowpipe Streaming: Added detailed error logging (including FlowFile attributes and exception details) immediately before routing records to the FAILURE relationship, improving diagnostics when ingestion errors occur. - CDC Oracle: Treats database connection reset exceptions as warnings instead of errors; the connection is rarely used (once daily for license checks and schema fetches), is often stale, and the connector recovers automatically on the next cycle — this prevents false "Unhealthy" status on the connector dashboard. - CDC Databases: Added a dedicated SCHEMA_NOT_FOUND failure reason when a source table disappears or its schema cannot be fetched after retries are exhausted, providing operators with a clear indication of why a table stopped replicating instead of a generic error. - SharePoint: Fixed handling of HTTP 410 (Gone) errors when the SharePoint delta link expires, and added additional logging around delta link resolution to help troubleshoot synchronization issues with large document libraries. - CDC SQL Server: Improved snapshot performance for partitioned tables by placing the partition column first in the ORDER BY and keyset WHERE clauses, enabling SQL Server partition elimination during keyset pagination and significantly reducing query execution time for large partitioned tables. ### Connectors 2026.5.19.16 - CDC Oracle & SQL Server (CDC): Added a stale-streams filter parameter that automatically excludes journal streams nearing their staleness threshold from CDC processing, preventing failures when streams expire during long-running replication cycles. - SharePoint: Added an auto re-sync parameter to all SharePoint CDC connector variants that automatically re-synchronizes the full document library when the delta link expires or becomes invalid, instead of requiring manual intervention. - CDC Databases: Fixed a connection leak where some connections were not routed through Private Link; ensures all database connections from the connector (including internal health-check and metadata queries) go through the configured private link endpoint. - CDC Oracle & SQL Server: Adopted the enhanced MultiDatabaseWaitForSnapshotCompletion processor in incremental-only mode, which provides better coordination between snapshot and incremental phases and reduces the window where tables can miss changes during the transition. - CDC Oracle: Added an Oversized Value Strategy parameter to Oracle connectors, allowing operators to choose how to handle column values that exceed Snowflake's maximum column size (truncate, route to failure, or skip the column). - MongoDB: Strips internal collection selection criteria attributes from FlowFile metadata before sending to Snowflake, preventing unnecessary attribute pollution in the destination. - MongoDB: Improved failure reason reporting to distinguish between different types of ingestion errors (schema mismatch, connection timeout, authentication failure) for better operator visibility. ## May 14, 2026 ### Runtime Server 2026.5.14.16 - Added support for loading asset configurations when connectors are created via SQL. ### Runtime Extensions 2026.5.14.16 - CDC SQL Server (CT version): Added source commit time, row count, and per-cycle phase instrumentation for SQL Server Change Tracking. - Dataverse: Added FAILED table status tracking and a processor for managing table ingestion state. - Added GateFlowFile processor for flow control. - CDC Databases: Made the CDC schema registry resilient to TableSchema class changes, preventing failures on connector upgrades. - CDC Databases: Fixed NullPointerException on dynamic-property initialization in RouteOnSnowflakeParameter processors. - CDC SQL Server: Fixed keyset pagination failures by properly casting int/smallint/tinyint primary key placeholders. - Kafka: Refactored Kafka3ConnectionService to use SSLContextProvider for cleaner SSL handling and possibility to use PEM-based authentication. - AWS: Added Token Request Endpoint property to AwsRdsIamDatabasePasswordProvider for custom STS endpoints. ### Connectors 2026.5.14.16 - CDC Oracle: Added Concurrent Snapshot Queries parameter to allow parallel snapshot fetching. - CDC Oracle: Adjusted Oracle connector flows to comply with FlowFile size limits. - CDC MySQL, PostgreSQL, SQL Server: Removed tables listing FlowFile attributes to reduce pressure on Provenance Repository when syncing thousands of tables. - CDC MongoDB: Improved stream staleness prevention to reduce unnecessary restarts. ## May 12, 2026 ### Runtime Server 2026.5.12.16 - Fixed potential corruption with modify-after-write on Local State Provider. - Flow import/export with stateful components state. ### Runtime Extensions 2026.5.12.16 - Snowpipe Streaming: Added PrivateLink support to Snowpipe Streaming v2 processors. - CDC Databases: Added STALE_AFTER flow-file attribute to GetSnowflakeJournalStreams and MultiDatabaseGetSnowflakeJournalStreams for stream staleness monitoring. - CDC Databases (multi-database): Added Incremental strategy to MultiDatabaseWaitForSnapshotCompletion processor. - CDC SQL Server: Widened CdcStreamPosition to BigInteger to support 10-byte SQL Server Log Sequence Numbers. - CDC Oracle: Reduced the number of row ID ranges generated by SplitOracleTable to improve snapshot performance. - CDC Oracle: Added oversized value support to FetchRowsByRowId processor. - Dataverse: Fixed backpressure on success queue deadlocking FetchMicrosoftDataverseTable by only listing idle tables during long snapshots. - CDC PostgreSQL: Changed publication verification fall-through outcome from FAILED to SKIPPED to prevent false failures. ### Connectors 2026.5.12.16 - CDC MySQL, PostgreSQL, SQL Server: Added filter for streams nearing staleness within 7 days. - CDC MySQL: Replaced WaitForTableState processor with enhanced version in Incremental flow. - MongoDB: Added object identifier resolution. ## May 8, 2026 ### Runtime Server 2026.5.8.5 - CDC SQL Server: INFO-level logging for MultiDatabaseCaptureChangeSqlServer are now captured in the event table. - Fixed Repository Record creation for S2S and Load-Balanced Connections. ### Runtime Extensions 2026.5.8.8 - CDC PostgreSQL: Added Table Storage Format (Standard/Iceberg) option to the Postgres CDC connector wizard. - CDC SQL Server: Added logging for CT query performance tracking if Metrics Enabled property is set to true. - Dataverse: Enabled reingestion of all tables by allowing empty Tables Filter Value. - Dataverse: Added ability to drop individual table state records for selective reingestion. - CDC SQL Server: Reports capture metrics on empty fetches for better observability. - CDC PostgreSQL: Separated replication and non-replication connections to prevent connection pool exhaustion. - Snowpipe Streaming: Fixed GCS object transfer on SPCS for Snowpipe Streaming v2. - CDC SQL Server: Added FlowFile size limit to MultiDatabaseFetchRowsByRowId to prevent memory issues. - BigQuery: Automatically retries on transient gRPC exceptions instead of failing the flow. - BigQuery: Fixed case-insensitive database merge query failures. ### Connectors 2026.5.7.18 - Jira: Fixed duplicate issues when project has changed. - CDC SQL Server: Bumped concurrent tasks to 2 on MultiDatabaseEnrichCdcStream for improved throughput. - CDC SQL Server: Added Concurrent Select Queries parameter for incremental loads in multi-database mode. ## May 5, 2026 ### Control Plane Core 0.114.0 - Updated SQL Server connector CDC preview documentation link. - Replaced legacy Jira connector with Core and Agile versions. - Fixed intermittent issue with the available Deployment list missing some Deployment options when creating a new Runtime. - Security patches and dependency upgrades. ### Data Plane Service 0.113.0 - Improved reliability of Runtime Upgrade by handling a case where the Runtime StatefulSet is stuck waiting on unhealthy pods prior to upgrade. - Security patches and dependency upgrades. ### Control Plane UI 0.80.0 - Upgraded to Stellar 0.31.3 for consistency across Snowflake products. ### AWS Data Plane Agent 1.42.0 - Security patches and dependency upgrades. ### SPCS Data Plane Agent 1.28.0 - Security patches and dependency upgrades. ### Runtime Operator 0.59.0 - Improved reliability of Runtime scale down by disallowing a node to reconnect to the cluster while waiting on decommissioning. - Security patches and dependency upgrades. ### Openflow Runtime Gateway 2026.5.1.10 - Security patches and dependency upgrades. ### Openflow Ingress Controller 2026.5.1-10 - Security patches and dependency upgrades. ### Openflow Token Refresher 1.11.0 - Security patches and dependency upgrades. ### Runtime Server 2026.5.5.17 - Fixed handling of PROPERTY_PARAMETERIZATION_REMOVED as a local change during versioned Process Group upgrades. - Fixed lineage start index tracking in Session.create(). ### Runtime Extensions 2026.5.5.19 - CDC Oracle: Added support for user-declared logical keys, allowing custom replication key columns instead of relying on auto-detected primary keys. - CDC Databases (multi-DB): Prioritized newly added tables in the table scheduler so they begin replicating sooner. - Veeva Vault: Switched to STREAM-based change tracking in MergeVeevaVaultStagingTable for more efficient incremental processing. - CDC SQL Server: Fixed an off-by-one error at the LATEST starting position that could cause the first change event to be missed. ### Connectors 2026.5.5.16 - CDC Oracle: Added logical-key (user-declared) Oracle connector flows. - CDC PostgreSQL: Added Iceberg table support for PostgreSQL CDC connector. - Veeva Vault: Set Offset Tracking Resolution to DISABLED for PublishSnowpipeStreaming in Veeva Vault connector. - CDC MySQL: Switched to Snowflake journal record structure for MySQL Capture processor. - Salesforce Bulk API: Added Object Identifier Resolution parameter to Describe SFDC Object processors. - Confluence: Switched to documentId as the stage file name to prevent duplicate pages on connector restart. - BigQuery: Improved BigQuery incremental failure handling. ## May 1, 2026 ### Runtime Server 2026.5.1.1 - Fixed node offload handling for Processors like PublishSnowpipeStreaming and MergeContent that create and manage multiple process sessions. - Added metrics collection for Jira Processors. ### Runtime Extensions 2026.5.1.1 - Added support for Iceberg Tables to UpdateSnowflakeTable Processor. - Improved merge handling in MergeVeevaVaultStagingTable Processor. - Added DML Record Structure property to CaptureChangeMySQL Processor. ## April 28, 2026 ### AWS Data Plane Agent 1.41.0 - Enabled logs from the Openflow Agent in your Snowflake Event Table, improving support and reducing triage time for support cases. - Fixed an upgrade issue for older deployments that use Custom Ingress with multiple Custom Ingress Security Groups. - Improved support for adding observability agents in the EKS cluster alongside Openflow services. - Security patches and dependency upgrades. ### Runtime Server 2026.4.28.17 - Security patches and dependency upgrades. ### Runtime Extensions 2026.4.28.15 - CDC PostgreSQL: Added configuration verification to CaptureChangePostgreSQL. - CDC Databases: Added SNOWFLAKE_OPENFLOW application tag to CDC Merge queries. - CDC Google BigQuery: Added support for up to 7 days of history for CDC with Google BigQuery. - CDC Oracle: Improved Oracle table splitting performance. ## April 24, 2026 ### Runtime Server 2026.4.24.16 - Excluded Parameter Description from Flow Version change determination. - Added configurable Content Claim Truncation to FileSystemRepository. - Added Registered Flow ID Version Path to MDC Attributes. - Preserved prioritizer order in Git flow Registry serialization. ### Runtime Extensions 2026.4.24.16 - CDC SQL Server: Added CDC-based change capture processor as an alternative to Change Tracking. - CDC SQL Server: Added Snapshot Isolation support for consistent reads during change capture and table snapshots. - Jira v2: Added Agile components including boards, board configuration, board projects, board sprints, and filters. - CDC Oracle: Added Oversized Values handling, allowing truncation or rejection of values exceeding a configurable size limit. - CDC Databases: Added Incremental strategy to WaitForSnapshotCompletion so high-traffic tables no longer block other tables. - Veeva: Added connector and components to sync data from Veeva Vault. - CDC SQL Server: Fixed empty-string primary key handling where CAST caused infinite retry loops during keyset pagination. - CDC Databases (multi-DB): Fixed journal stream prefix collision bug where tables sharing the same bare name were incorrectly matched. - Dataverse: Fixed deadlock in FetchMicrosoftDataverseTable where a table stuck in FETCHING state after a non-retryable error would never recover. - Snowpipe Streaming: Fixed MergeSnowflakeJournalTable incorrectly handling failed merge queries, causing silent data loss. ### Connectors 2026.4.24.16 - Jira: Added Jira v2 core connector with improved entity coverage, custom fields, user groups, worklogs, issue relations, and project filtering. - Jira: Added Jira Agile connector for boards, sprints, sprint-to-board, and sprint-to-issue ingestion. - CDC MySQL & PostgreSQL: Added destination schema mapping support for routing source schemas to custom Snowflake destination schemas. - CDC SQL Server: Added multi-database CDC connector flow definition using Change Data Capture mode. - CDC PostgreSQL: Switched to flattened DML record output, approximately doubling ingestion throughput. - CDC PostgreSQL: Replaced WaitForTableState with WaitForSnapshotCompletion in incremental mode to reduce unnecessary queuing during snapshot phases. - CDC Databases: Fixed scheduling stuck issue for connectors with more than 10,000 tables by increasing backpressure queue limit. - Dataverse: Replaced PutSQL with ExecuteSQL for merge step, simplified flow, and added automatic cleanup of deprecated columns. - Veeva: Added connector and components to sync data from Veeva Vault. - CDC PostgreSQL: Reverted UpdateTableState property changes that could cause data loss during snapshot with concurrent channels. ## April 17, 2026 ### AWS Data Plane Agent 1.38.0 - Security patches and dependency upgrades. ### SPCS Data Plane Agent 1.27.0 - Security patches and dependency upgrades. ### Control Plane Core 0.111.0 - Security patches and dependency upgrades. - Improved performance when listing and interacting with Deployments and Runtimes. - HubSpot connector is now available in public preview. ### Data Plane Service 0.110.0 - Security patches and dependency upgrades. ### Ingress Controller 2026.4.14-17 - Security patches and dependency upgrades. ### Openflow Runtime Gateway 2026.4.14.17 - Security patches and dependency upgrades. ### Openflow Token Refresher 1.10.0 - Security patches and dependency upgrades. ### Control Plane UI 0.78.0 - Security patches and dependency upgrades. ### Data Plane UI 0.15.0 - Security patches and dependency upgrades. ## April 16, 2026 ### Runtime Extensions 2026.4.16.18 - CDC Oracle: Auto-detects UNIQUE key constraints as replication keys when no primary key is defined. - CDC SQL Server: Fixed `sysname` columns causing infinite schema-mismatch loop. - CDC SQL Server: Fixed duplicate DDL emission for unchanged tables by disambiguating `EARLIEST` position. - CDC Databases: Made `CdcSchemaRegistry` resilient to internal `TableSchema` class changes during upgrades. - Removed preview labels from UpdateSnowflake* processors. ### Connectors 2026.4.16.16 - CDC MySQL: Added Oversized Value Strategy parameter. - Dataverse: Fixed inability to change type of _SNOWFLAKE_DELETED column. - CDC SQL Server: Increased incremental load batch size to 100K rows. ## April 14, 2026 ### Runtime Server 2026.4.14.16 - Fixed local change detection for versioned flows when updating a property that was not set previously. - Runtime UI: Allows users to resume a suspended runtime in recovery mode. ### Runtime Extensions 2026.4.14.16 - Jira (Atlassian): Added Jira v2 core components including new processors for ingesting comments, changelogs, deleted issues, projects, permissions, users, worklogs, and other Jira entities. - CDC Databases: Introduced a configurable Oversized Value Limit property (default 16 MB) on CDC and snapshot processors. - CDC Oracle: Removed unnecessary Oracle database privileges from configuration scripts. - Snowpipe Streaming: Removed Preview tags from PublishSnowpipeStreaming processors, marking them as generally available. ### Connectors 2026.4.14.15 - Kafka: Disabled flow-file-based offset tracking to prevent data loss during downscaling. - Kafka: Added a new high-performance Kafka connector flow with PublishSnowpipeStreaming. - CDC Oracle and SQL Server: Exposed table exclusion parameter for multi-database connectors. - CDC Oracle: Added Snowpipe Streaming v2 routing with automatic v1 fallback. - Salesforce: Explicitly set warehouse in MERGE pre-query to prevent failures when no default warehouse is configured. ## April 13, 2026 ### AWS Data Plane Agent 1.37.0 - Improved custom ingress to simultaneously support load balancer security groups managed by both Openflow and deployment-specific configurations. - Removed duplicate ingress rules for default custom ingress security group. ## April 10, 2026 ### AWS Data Plane Agent 1.36.0 - Security patches and dependency upgrades. - Improved resiliency of new Deployments and upgrades related to how AWS IAM permissions are created and refreshed. - Improved cost efficiency of telemetry by removing unused or low-value metrics from being exported to Event Tables. ### SPCS Data Plane Agent 1.26.0 - Security patches and dependency upgrades. - Improved cost efficiency of telemetry by removing unused or low-value metrics from being exported to Event Tables. ### Control Plane Core 0.109.1 - Security patches and dependency upgrades. - Oracle Embedded License Connector added to Featured Connectors. ### Data Plane Service 0.109.0 - Security patches and dependency upgrades. ### Ingress Controller 2026.4.7 - Security patches and dependency upgrades. ### Runtime Operator 0.58.0 - Security patches and dependency upgrades. ### Control Plane UI 0.77.0 - Added third-party icons for Atlassian, Salesforce, and Microsoft SQL Server connector cards. - Added support for resuming suspended Runtimes in recovery mode. - Hide gateway version in Runtime upgrade dialog when appropriate. - Improved warnings and guidance when users lack permissions to create a Deployment. - Improved Connector installation process to no longer wait for available Runtimes to load before opening the dialog. ### Data Plane UI 0.14.0 - Security patches and dependency upgrades. ## April 9, 2026 ### Runtime Server 2026.4.9.16 - Fixed Parameter and Parameter Context descriptions being lost during versioned flow upgrades. - Fixed record path functions (`toBytes`, `toDate`, `toString`, and `format`) to return the correct types. - Snowpipe Streaming: Exports metrics from `PublishChangeDataSnowpipeStreaming` to the event table for better observability. ### Runtime Extensions 2026.4.9.16 - CDC SQL Server: Improved error visibility during connection setup by fixing exception masking in `CatalogHelper` and unifying `setCatalog` usage. - CDC SQL Server and Oracle: Switched to `DirectJsonRecordWriter` for storing change data as JSON in VARIANT columns, improving Snowflake ingestion efficiency. - CDC MySQL: Fixed composite primary key column ordering by reading from `KEY_COLUMN_USAGE`, ensuring correct row identification during snapshot. ### Connectors 2026.4.9.15 - Dataverse: Updated merge journal process to include `SNOWFLAKE_ID` in the Dataverse schema. - Box, Confluence, Google Drive, SharePoint, and Slack: Fixed Cortex-enabled connectors to preserve existing CORTEX SEARCH SERVICE configuration instead of overwriting it. - CDC MySQL, PostgreSQL, Oracle, and SQL Server: Increased run duration on CPU-bound processors in incremental flows to reduce backpressure. - CDC Oracle: Added staleness prevention to keep pipelines active during periods of low data volume. ## April 7, 2026 ### Runtime Extensions 2026.4.7.16 - Kafka: Fixed duplicate message delivery in ConsumeKafka when consumers rejoin a consumer group during rebalance. - CDC MySQL: Fixed data corruption when a MySQL server restart reassigns table IDs to different tables, preventing stale schema mappings from causing type mismatch errors during data ingestion. - CDC Oracle: Fixed Oracle XStream CDC failing to read the LCR version when the XStream outbound server is configured on a different database instance (PDB vs CDB). - CDC Databases: Reduced unnecessary Snowpipe Streaming query retries by penalizing the MergeSnowflakeJournalTable processor when no new data is available or the connection is disconnected, improving throughput. - CDC SQL Server: Added table draining to ensure tables with large change backlogs are fully consumed before the connector moves to the next table. ### Connectors 2026.4.7.16 - CDC MySQL and PostgreSQL: Added a `Re-snapshot Table Exclusions` parameter to allow specific tables to be excluded from replication, enabling re-snapshotting use cases. ## April 6, 2026 ### AWS Data Plane Agent 1.34.0 - Improved deployment upgrade time for customers with many Runtimes. - Improved speed and reliability of upgrades from Openflow Deployments running EKS 1.32 to EKS 1.35. ## April 2, 2026 ### Runtime Server 2026.4.2.16 - Increased the CDC connector metrics table row limit for observability dashboards from 30,000 to 40,000. - Fixed inherited Parameter Context synchronization on versioned Process Group upgrades when new parameters are added. - Fixed the provenance repository to honor the configured maximum attribute character size when reading entries. - Fixed component bundle resolution and rollback behavior on versioned flow changes. - Updated to Runtime UI 0.70.0. ### Runtime Extensions 2026.4.2.16 - Added Google Cloud Storage Provider for Iceberg. - Fixed empty Private Key check for PGP Secret Key. - CDC Databases: Added a new `MultiDatabaseGetSnowflakeJournalStreams` processor that supports multi-source CDC replication by mapping 3-part source table names (database + schema + table) to Snowflake destination schemas using a configurable naming pattern. - CDC PostgreSQL: Added a "Flatten DML Records" option to `CaptureChangePostgreSQL` that writes change events in the final flat format at capture time, eliminating the intermediate file read-and-rewrite step in `EnrichCdcStream` and reducing disk I/O. - Snowpipe Streaming 2: Added a "Destination Type" property to `PublishSnowpipeStreaming` that allows users to target either a named Pipe or a Table directly, with automatic migration to preserve existing Pipe-based configurations. - CDC Databases: Added an "Excluded Comma Separated Source Table Names" property to `ListTableNames` (and its multi-database equivalent) that lets users exclude specific tables from replication. - BigQuery: Fixed a property migration bug in `CreateReadSession` that caused incorrect processor configuration when upgrading from older flow versions. - CDC PostgreSQL: Fixed `FetchTableSnapshot` failures on tables containing `bytea` columns by using a more compatible JDBC method to read binary data. - CDC Databases: Updated the `DESTINATION_SCHEMA_NAME_PATTERN` placeholders from `{database}`, `{schema}` to `${source.database.name}`, `${source.schema.name}`, and `${source.table.name}`. A fixed schema name is now valid (the validator constraint requiring at least one placeholder has been removed). - All connectors: Added a `Validation Mode` property to the `SetAttributesValidatingReferences` processor, allowing configuration of how attribute reference validation is enforced. ### Connectors 2026.4.2.16 - BigQuery: Reduced the concurrency of parallel streaming jobs (PSS) to prevent resource contention issues. - SharePoint: Fixed a file removal pattern bug for customers with the `ENABLE_FIX_209969` account parameter set to false, where the pattern would fail to match and remove processed files. - BigQuery: Prevented CDC and view ingestion from starting when the required temporary dataset parameter is not configured, avoiding accidental table failures. - CDC MySQL, PostgreSQL, and SQL Server: Configured the source database connection pool with validation-on-borrow and periodic eviction of idle connections, preventing misleading "connection reset" errors caused by stale connections being reused after a server-side timeout. - Dataverse: Added a `_SNOWFLAKE_ID` column to replicated records by mapping the source primary key, allowing downstream consumers to uniquely identify each record in Snowflake. - CDC SQL Server, MySQL, and PostgreSQL: Added the new stream staleness prevention mechanism to the connector. - Jira: Fixed an incorrect merge query in the Jira connector. ## April 1, 2026 ### AWS Data Plane Agent 1.33.0 - Upgraded to AWS EKS 1.35. - Added the EKS kube-proxy add-on for automated, managed upgrades of networking components. - Improved auto-healing when EKS node groups are down or offline for extended periods. - Improved cost efficiency of telemetry collection by ignoring low-value metrics. ## March 31, 2026 ### AWS Data Plane Agent 1.31.3 - Security patches and dependency upgrades. ### SPCS Data Plane Agent 1.24.1 - Security patches and dependency upgrades. ### Control Plane Core 0.108.2 - Security patches and dependency upgrades. - Fixed Oracle Connector License syncing for accounts with renamed organizations. ### Data Plane Service 0.108.2 - Security patches and dependency upgrades. ## March 30, 2026 ### Runtime Server 2026.3.27.21 - Added `isValidDate` and `isValidInstant` Expression Language functions. - Fixed inherited parameter context preservation during `KEEP_EXISTING` versioned flow deployment. - **Behavior change:** When upgrading a running versioned flow to a new version, new components added in the new version are automatically started. ### Runtime Extensions 2026.3.27.21 - AWS: Fixed AWS connection pool shutdown on EKS with STS credential refresh. - Google Drive: Reverted to correct default scopes in Google Drive components, with a new property to use the Google Cloud Platform scope when using Workload Identity Federation with impersonation. - Kinesis: Handled `ResourceNotFoundException` in `ConsumeKinesis` when shards are not found or removed. - Oracle: Added support for LCR positions V1 and separate connection and XStream attach, adding support for 12.1 and 12.0. - Dataverse: Unknown Dataverse attribute types fall back to STRING. - Salesforce: Fixed Salesforce formula field translation producing invalid SQL for date arithmetic. - Snowflake: Fixed `PublishSnowpipeStreaming` skipping FlowFiles after pipe recreation due to a stale offset. - Dataverse: Added a parameter to configure maximum fetched column size in `FetchMicrosoftDataverseTable`. - Dataverse: Added table-level removal to the Dataverse connector. - Snowflake: Fixed Workload Identity Federation token header format for Snowpipe Streaming 2. ### Connectors 2026.3.26.19 - CDC database connectors: Added metrics collection for observability dashboards. - CDC SQL Server: Switched from Snowpipe Streaming v1 to v2. ## March 27, 2026 ### AWS Data Plane Agent 1.31.2 - Replaced Ingress-Nginx with Openflow Ingress Controller. - Switched TLS certificate validation for Snowflake managed ingress from HTTP-01 to DNS-01. This introduces new network requirements for BYOC deployments using Snowflake managed ingress. For more information, see [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc#prerequisites-for-byo-vpc-existing-vpc). - Fixed an issue with load balancer security group rules when multiple deployments share the same private security group. - Security patches and dependency upgrades. - Improved support for adding many Runtimes to a Deployment at once. - Removed the need for ingress on port 80. All Deployment and Runtime ingress uses port 443. ### SPCS Data Plane Agent 1.24.0 - Security patches and dependency upgrades. ### Control Plane Core 0.108.0 - Security patches and dependency upgrades. - Improved handling for users with large sets of roles when they need to provide this list of roles for creating and managing resources. - Salesforce Bulk API connector is now generally available (GA). ### Control Plane UI 0.74.0 - Upgraded to Stellar 0.28.0. - The Create Runtime and EAIs dialog can open while EAIs are still loading. ### Data Plane Service 0.108.0 - Security patches and dependency upgrades. ### Openflow Runtime Gateway 2026.3.25.14 - Security patches and dependency upgrades. ## March 24, 2026 ### Runtime Server 2026.3.24.18 - Improved layout of vertical space in the Runtime UI for longer lists of tables and schemas. ### Runtime Extensions 2026.3.24.20 - SQL Server: CDC components are now generally available (GA). - Oracle: Fixed `TIMESTAMPTZ` mapping for named time zones. - Added processors to support Snowpipe Streaming v2 in CDC database connectors. - Improved `UpdateSnowflakeTable` caching and query batching for better performance. ### Connectors 2026.3.24.18 - CDC database connectors: Added metrics collection for observability dashboards. - MySQL: Switched CDC connector from Snowpipe Streaming v1 to v2. - PostgreSQL: Switched CDC connector from Snowpipe Streaming v1 to v2. - Salesforce: Salesforce Bulk API connector is now generally available (GA) and includes a parameter to control warehouse cost optimization. ## March 20, 2026 ### Control Plane Core 0.107.1 - Improved role picker for users with a large number of available roles. ### Runtime Server 2026.3.19.18 - Fixed Content Repository defragmentation. - Improved reloading behavior for Scripted Record Reader and Writer processors. ### Runtime Extensions 2026.3.19.20 - PostgreSQL and MySQL: Set explicit field sizes for `VARCHAR` and `BINARY` columns to support larger values. - PostgreSQL: Fixed cursor-based fetching by disabling `autoCommit` to prevent out-of-memory errors on large rows. - Salesforce: Salesforce Bulk API components are now generally available (GA). - Salesforce: Fixed Salesforce Upsert Lookup failing when field values contain a `+` sign. - SQL Server: Improved handling of source database failover to prevent table sync failures. - SQL Server: Improved snapshot performance for clustered and partitioned tables. ### Connectors 2026.3.19.15 - Dataverse: Added Table State Service to the Dataverse connector flow. - Oracle: Parallelized Snowpipe Streaming v1 snapshot by primary key for improved performance. - Slack: Added option to ignore channels from historical load in the Slack connector. ## March 17, 2026 ### AWS Data Plane Agent 1.30.0 - Added support for recovering a deployment after Snowflake organization or account rename via an `update-account.sh` script. - Improved Runtime metrics collection for larger data flows and Connectors handling large numbers of tables. - Preparing for dedicated Openflow Ingress Controller to replace Nginx for BYOC runtime traffic. - Added memory limiter and metrics routing in the OTEL collector for stability and separate pipelines. - Security patches and dependency upgrades, including OTEL Collector 0.146.1. ### SPCS Data Plane Agent 1.23.0 - Improved Runtime metrics collection for larger data flows and Connectors handling large numbers of tables. - Security patches and dependency upgrades. ### Control Plane UI 0.73.0 - Upgraded to Stellar icons. - Fixed a condition that could have prevented the splash screen from hiding when an unhandled error occurs. ### Control Plane Core 0.107.0 - Reliability improvements for Deployments when an account or organization is renamed. ### Data Plane Service 0.107.0 - Security patches and dependency upgrades. ### Runtime Operator 0.57.0 - Security patches and dependency upgrades. ### Openflow Ingress Controller 2026.3.16-17 - Security patches and dependency upgrades. - Preparing for replacement of Nginx as the ingress controller for BYOC runtime traffic. ### Runtime Server 2026.3.17.13 - New Runtime UI 0.68.0. - Fixed splash screen which may stay visible under specific conditions. - Improved content viewer to improve MIME type support. - Track Content and truncate large resource claims in FileSystemRepository. - Performance improvements for OpenTelemetry data collection. ### Runtime Extensions 2026.3.17.13 - Updated log configuration to capture INFO level logs for DescribeSFDCObject processor. - Added Session Header handling to Snowpipe Streaming 2. - Reduced default batch size and handle query timeout for SQL Server table name fetching. - Kinesis: Significantly improved the `ConsumeKinesis` processor, removing use of the Kinesis Client Library. - MySQL: Fixed `NullPointerException` in `CaptureChangeMySQL.disconnectBinlogClient` when `tableMapStore` is `null`. - MySQL: Added TLS support for JDBC in `CaptureChangeMySQL`. - SQL Server: Fixed `VARCHAR/NVARCHAR` sorting issue that may cause duplicate rows during batched paging. - SQL Server: Reduced default batch size and improved query timeout handling table name fetching. - Added `MultiDatabaseRouteOnSnowflakeParameter` and `MultiDatabaseExitRouteOnSnowflakeParameter` processors. - Added `GetActiveSnowflakeStreams` processor for stream staleness prevention. ## March 13, 2026 ### Control Plane Core 0.106.0 - Oracle connector is now generally available (GA). - Registered preview of new PostgreSQL CDC SOM connector in the control plane catalog. - Added data plane configuration options for CDC Snowpipe Streaming v2 rollout across MySQL, PostgreSQL, SQL Server, and Oracle connectors. ## March 12, 2026 ### Runtime Server 2026.3.12.13 - Fixed 409 Conflict in Azure DevOps and Bitbucket flow registry clients for multiple Flows with shared branch. - Fixed Flow Comparison showing changes for nested child components when using nesting flow versioning. ### Runtime Extensions 2026.3.12.15 - Iceberg: Added Storage Class to S3FileIOProvider. - Salesforce: Use FQN database/schema for Salesforce Merge queries. - Salesforce: Improved Salesforce formula parsing and logging. - Salesforce: Fixed ListSFDCObjects becoming invalid after upgrade with dynamic relationships. - MySQL: Escalate binlog communication failure log from WARN to ERROR. ### Connectors 2026.3.12.15 - Salesforce: Use FQN database/schema for Salesforce Merge queries. - Salesforce: Do not emit bulletin on suspend warehouse attempts. ## March 11, 2026 ### Runtime Server 2026.3.10.21 - New Runtime UI 0.67.0. - Fixed flicker of overlapping connection warning in connector canvas. - Aligned reusable canvas renderers for borders around PGs and RPGs. - Fixed support for floating point numbers in connection flow file expiration. - Restored special treatment of trigger serially processors (no concurrent tasks). ### Runtime Extensions 2026.3.10.20 - AWS Secrets Manager Parameter Provider now supports plain text secrets. - ListS3: Fixed V1 pagination failing when delimiter is not set, which caused an infinite loop. - MultiDatabaseFetchTableSnapshot: Added FlowFile size limiting. - Slack: ConsumeSlackHistory now has an option to ignore channels from historical load. - MySQL: Fixed PutSnowpipeStreaming storing JSON in VARIANT columns as strings by directly writing JSON records in CaptureChangeMySQL. - Dataverse: Added `SNOWFLAKE_ID` column to the schema. - Snowpipe Streaming: Improved channel error handling in PublishSnowpipeStreaming. - Snowpipe Streaming v2: Fixed error when streaming `timestamp_tz` with seconds in offset. - CDC Databases: Fixed tables transitioning to FAILED during snapshot load by adding buffer for lineageStartDate comparison. ### Connectors 2026.3.10.20 - CDC SQL Server: Added Oversized Value Strategy parameter. - Salesforce Bulk API: Added initial support for formulas. - Salesforce Bulk API: Warehouse suspension now occurs immediately after all merge queries are executed. ## March 6, 2026 ### Runtime Extensions 2026.3.6.12 - UpdateSnowflakeView: Added support for raw SQL. - PostgreSQL: Fixed PutSnowpipeStreaming storing JSON in VARIANT columns as strings by directly writing JSON records in CaptureChangePostgreSQL and FetchTableSnapshot. - HubSpot: Added missing CRM object types and fixed API compatibility. - CDC Oracle: Fixed partitioned tables support during snapshot. - Snowpipe Streaming v1: Fixed empty FlowFile handling in PutSnowpipeStreaming when configured to use exactly-once delivery. ## March 5, 2026 ### AWS Data Plane Agent 1.26.0 - Security patches and dependency upgrades. ### SPCS Data Plane Agent 1.20.0 - Security patches and dependency upgrades. - Added per-connector error metrics, improving speed and reliability of the Openflow Observability dashboard. ### Control Plane UI 0.72.0 - Introduced a Connector listing for managing Connector Snowflake Objects (hidden by a feature flag until verified and ready). - Updated the Connector installation process for Connector Snowflake Objects (hidden by a feature flag until verified and ready). - Added MongoDB Connector Definition icon. - Updated the Oracle Connector terms dialog to account for the new independent (BYOL) Oracle connector. - Updated the user-facing action for "Rename" to "Set display name". ### Control Plane Core 0.105.0 - Snowflake deployments can now heal from `UPGRADE_FAILED` state if they report a healthy status and version. - Added MongoDB connector flow. - Added support for `OPENFLOW_INGRESS_NAME` parameter when creating the URL to access Snowflake Deployments. ### Data Plane Service 0.105.0 - **Behavior change:** Runtime Python processor properties are now set based on Runtime node size (Small: disabled, Medium: <=2, Large: <=4). - Security patches and dependency upgrades. ### Runtime Operator 0.56.0 - **Behavior change:** Python processors are now disabled by default to improve Runtime stability. Python processor usage is controlled by Runtime size (Small: disallowed, Medium: <=2, Large: <=4). - Security patches and dependency upgrades. ## March 3, 2026 ### AWS Data Plane Agent 1.25.0 - Reduced downtime for Openflow Runtimes when upgrading the AMI for BYOC Deployments. - Added support for upcoming EKS 1.35 upgrade, though BYOC is still using EKS 1.34. ### Runtime Server 2026.3.4.15 - Expression Language: Added `compactDelimitedList()` and `trimDelimitedList()` functions. - New Runtime UI 0.66.0. - Hidden environmental changes in show/revert local changes. - Connections now avoid overlapping, and warnings are shown for existing overlaps. ### Runtime Extensions 2026.3.4.16 - Snowpipe Streaming: Added optional Role property. - CDC Databases: Fixed JSON column filtering in incremental load. - CDC Databases: Fixed `clearSession()` removing already-transferred FlowFiles in FetchTableSnapshot. - CDC Databases: Fixed `SEEN_AT` value being interpreted as seconds instead of milliseconds in incremental mode. - CDC Databases: Minimized the risk of filling up the waiting queue in EnforceOrder processor. - CDC Databases: Added "Oversized Value Strategy" to MultiDatabaseFetchTableSnapshot. - CDC Oracle: Fixed verification in CaptureChangeOracle. - CDC SQL Server: Added "Oversized Value Strategy" to MultiDatabaseCaptureChangeSqlServer processor. - CDC SQL Server: Fixed DESC primary key handling in MultidatabaseFetchTableSnapshot. - Salesforce: Fixed two bulletins in SubmitQueryJob for non-supported objects. - Snowpipe Streaming: Added "Disabled" option for Offset Token Resolution in PublishSnowpipeStreaming. - Snowpipe Streaming: Added channel error message on invalid rows log. ### Connectors 2026.3.4.15 - Added customer-facing metrics for MySQL connectors. - Added customer-facing metrics for PostgreSQL connectors. - Added customer-facing metrics for Oracle connectors. - Confluence: Fixed user emails with quotes breaking the connector. - Salesforce Bulk API: Added WaitForBulkJobs for warehouse usage cost optimization. ## February 26, 2026 ### AWS Data Plane Agent 1.24.0 - Improved upgrade speed and reliability from EKS 1.32 to 1.34, fixing the temporary "Upgrade Failed" status for BYOC and BYO-VPC deployments. ### Runtime Server 2026.2.26.15 - Expression Language: Added `unique()` function for removing duplicates from delimited strings. ### Runtime Extensions 2026.2.26.16 - CDC Oracle: Added configurable starting position in CaptureChangeOracle to control where CDC begins reading. - CDC Oracle: Added SSL/TLS connection support for CaptureChangeOracle. - CDC Oracle: Removed preview tags from multi-database Oracle CDC processors (now generally available). - CDC SQL Server: Fixed ChangeTrackingPosition parsing. - CDC Databases: Removed stale entries from IncrementGroupAttribute processor to prevent unbounded state growth. - Salesforce Bulk API: Fixed Merge Query failing when containing reserved keywords. - Salesforce Bulk API: Moved row deduplication in the Merge Query to fix an error and remove the need for the pre-SQL query DELETE. - Salesforce: Populated `sErrorMessage` when duplicate error occurs in `UpsertSFDCObjects` processor. ### Connectors 2026.2.26.15 - CDC Oracle: Added SSL/TLS connection support in Oracle connector. - CDC Oracle: Added schema name mapping in Oracle connector. - CDC Oracle: Parameterized starting position properties in Oracle connector. - CDC Oracle: Fixed missing log in concurrent snapshot. - Salesforce Bulk API: Ignore changes on not null constraints to prevent ingestion failures. ## February 25, 2026 ### Runtime Server 2026.2.24.16 - Security patches and dependency upgrades. - Improved observability for Connectors and custom groovy scripts. ### Runtime Extensions 2026.2.24.20 - Salesforce Bulk API: Added SubmitDeleteJob processor to delete data using Bulk API. - Snowpipe Streaming: Added PublishSnowpipeStreaming processor. - CDC SQL Server: MultiDatabaseCaptureChangeSqlServer now has parameterized concurrency level. - CDC Oracle: Fixed CaptureChangeOracle processor blocking during license validation. - CDC Oracle: Added source state verification in CaptureChangeOracle to detect source database issues. - CDC PostgreSQL: Added support for enum primary key in PostgreSQL. - CDC PostgreSQL: Map PostgreSQL `DOUBLE PRECISION` and `MONEY` types to `RecordFieldType.DOUBLE`. - Snowpipe Streaming v2: Added Snowflake Managed Authentication to PutSnowpipeStreaming2. - CDC PostgreSQL: Added Password Provider support to CaptureChangePostgreSQL, which gives support for AWS IAM Authentication with AWS RDS. ### Connectors 2026.2.24.20 - Salesforce Bulk API: Added `CLUSTER BY ("ID")` on table creation for better query performance. - Salesforce Bulk API: Disabled NOT NULL constraints on Alter Table processors to prevent ingestion failures. - Salesforce Bulk API: Added description for 'Enable Journal Tables' parameter. - Slack: Connector performance optimizations. - CDC SQL Server: Fixed EnforceOrder processor being triggered every second instead of on flow file arrival. ## February 20, 2026 ### AWS Data Plane Agent 1.23.0 - Fixed CloudFormation template formatting that could cause false drift detection by Terraform. - Fixed a rare issue with custom ingress and PrivateLink where EKS control plane nodes couldn't communicate with worker nodes. ### Control Plane UI 0.70.0 - Runtime diagnostic bundles are now sorted consistently. ### Control Plane Core 0.104.0 - Deployments and runtimes remain accessible after an organization or account name change. - Removed the temporary restriction that limited Snowflake deployment upgrades to deployment owners whose active role matched the deployment owner role. ### Data Plane Service 0.104.0 - Deployments and runtimes remain accessible after an organization or account name change. ### Runtime Server 2026.2.19.16 - Fixed an issue where the flow version changed unexpectedly when the flow contains a ghosted parameter provider. - New Runtime UI 0.65.0. - The provenance lineage view now displays the component type alongside the event type. - Diagnostic bundles are now sorted and ordered consistently. ### Runtime Extensions 2026.2.19.20 - Azure: Added support for Azure federated identity credentials. - Google Ads: GetGoogleAdsReport now supports batch ingestion with configurable date range batching. - CDC Oracle: Fixed ALTER TABLE parsing for integer-type columns (INT, SMALLINT, INTEGER, DEC, DECIMAL, NUMERIC) that incorrectly defaulted the scale to 19 instead of 0 when precision wasn't specified. - Fixed S3 processors using the global endpoint for `us-east-1`. - Fixed an error in DBCPConnectionPool when a dynamic property has a null value. - Kafka: ConsumeKafka now includes a `kafka.timestamp` attribute on FlowFiles emitted with the `Record` processing strategy. - Kinesis: ConsumeKinesis now supports a `Demarcator` processing strategy. - Snowpipe Streaming v1: PutSnowpipeStreaming now includes a `Binary Encoding Format` property for HEX binary string data. - CDC SQL Server: MultiDatabaseCaptureChangeSqlServer now uses dynamic backoff when there are no new changes. - CDC Multi-Database: MultiDatabaseFetchTableSnapshot can now run multiple select statements concurrently. - CDC SQL Server: Fixed an ingestion failure when a table is re-added with a different schema. - CDC Oracle: Fixed handling of license changes in a duplicated database. - CDC Databases: Improved error handling for DML operations in the EnrichCdcStream and MultiDatabaseEnrichCdcStream processors. - SharePoint: Fixed file path decoding for folders containing percent signs. - CDC Databases: Warnings are now logged when oversized values are set to null, making it easier to identify data truncation. - CDC Databases: Added a `CLEARING_FLOWFILE_FAILED` failure reason for table state tracking. - **Behavior change:** Removed the Vectara, Pinecone, RAG evaluation, Milvus, and Cohere bundles. ### Connectors 2026.2.19.20 - CDC Oracle: The default snapshot fetching strategy is now `CONCURRENT_BY_ROWID` instead of `SEQUENTIAL_BY_PRIMARY_KEY`, improving snapshot performance. - CDC SQL Server: Added customer-facing metrics for the SQL Server multi-database connector. - Slack: Thread broadcast replies are now filtered from Slack collection to prevent duplicate messages. - Salesforce Bulk API: The staging table is now truncated instead of deleted, preventing channel invalidation errors with Snowpipe Streaming. - Salesforce Bulk API: Object filters are no longer case-sensitive. - Salesforce Bulk API: Merge queries are no longer executed when no data has been captured. - Salesforce Bulk API: Added an `Enable Journal Tables` parameter (default: false) that creates a `JOURNAL_Object` table where data changes are appended. - CDC SQL Server: Snapshots now use multiple channels per table to improve throughput. - CDC PostgreSQL: The oversized value strategy is now configurable in the PostgreSQL connector. ## February 13, 2026 ### AWS Data Plane Agent 1.20.0 - Fixed an upgrade issue for older BYOC deployments where permissions failures occurred for tags on IAM OpenID Connect providers. - BYOC deployments now more clearly report their `Upgrading` status. ## February 11, 2026 ### Control Plane Core 0.102.0 - BYOC deployments now automatically restore access to runtimes when their AWS load balancers are recreated with a new DNS. - Improved upgrade reliability for deployments and runtimes. ### Openflow Runtime Gateway 2026.2.10.21 - Fixed connector installation failures in Snowflake deployments with PrivateLink enabled. ### AWS Data Plane Agent 1.19.0 - Fixed an upgrade issue for older BYOC deployments caused by an `eks:ListTagsForResource` permissions failure. ### Runtime Server 2026.2.10.18 - Python: Fixed an issue where NAR deletion could block indefinitely while a Python processor was initializing. - Fixed Parameter Provider version fallback when importing a flow. - Fixed Parameter Context binding for new process groups during version upgrades. ### Runtime Extensions 2026.2.11.9 - Kafka: Fixed an issue where ConsumeKafka could create duplicate messages during a consumer group rebalance. - Parquet: Fixed a ParquetReader error (`ClassCastException`) for `java.time` logical types. - MongoDB: Added components for the upcoming private preview of the MongoDB CDC connector. - Slack: Fixed duplicate messages caused by thread broadcast replies. - MySQL: Added an oversized data property to the CaptureChangeMySQL processor. - MySQL & PostgreSQL: Fixed FetchTableSnapshot incorrectly flagging interim FlowFiles as the final snapshot. - MySQL & PostgreSQL: You can now configure how values larger than 16 MB are handled when they exceed the supported limit. - Confluence Data Center: Added support for the export page permission. ### Connectors 2026.2.10.18 - Box: Removed the concurrency limit on stage inserts, improving overall performance. - MultiDB MS SQL Server: Added schema name mapping. ## February 6, 2026 ### Runtime Operator 0.54.0 - Fixed asset synchronization in runtimes when parameter providers are used. ### AWS Data Plane Agent 1.18.0 - Fixed an issue where migrating secrets during an upgrade caused failures for AWS deployments between versions 0.55.0 and 1.1.0. ## February 4, 2026 ### Runtime Server 2026.2.3.19 - Python: Fixed an issue where imported properties couldn't be used as `PropertyDependency` parameters in Python processors. - Records: Added timestamp truncation support in the RecordPath DSL. - New Runtime UI 0.64.0. ### Runtime Extensions 2026.2.4.10 - Iceberg: Added `Endpoint URL` and `Path Style Access` properties to the S3 FileIO Iceberg Provider. - Avro: Added a `Fast Reader Enabled` property to the Avro Reader. - CDC Databases: MultiDatabaseFetchTableSnapshot now numbers outgoing FlowFiles with a 1-based `chunk.index` attribute. - CDC Databases: The EnrichCdcStream and MultiDatabaseEnrichCdcStream processors now write `min(seenAt)` to FlowFile attributes. - CDC Databases: FlowFile attributes now include the number of rows inserted and updated during journal merge. - CDC Oracle: Oracle DML/DDL FlowFiles now include index attributes, consistent with other CDC database components. - CDC MySQL: Fixed replication failures for zero-date datetime values (such as 0000-00-00) by aligning snapshot and CDC mapping. - Salesforce Bulk API: Base64 fields (Blobs) are now automatically skipped for synced objects because this type isn't supported by the Bulk API. ### Connectors 2026.2.3.18 - Kafka: New Kafka to Snowflake connector with Kafka OAuth authentication support. - CDC Databases: Non-CDC processors in CDC connectors now include a table state change reason. - Salesforce Bulk API: Reduced the default `Max Batch Size` in PutSnowpipeStreaming to lower memory pressure for records with large fields. - Salesforce Bulk API: Added a parameter to disable incremental offloading, allowing full object syncs each execution to account for formula fields. - Salesforce Bulk API: Added support for non-Bulk API compatible objects such as Knowledge data. ## February 3, 2026 ### Control Plane Core 0.101.2 - Temporarily restricting Snowflake deployment upgrades to users whose active role matches the deployment owner role until a related issue is resolved. ## February 2, 2026 ### Control Plane Core 0.101.1 - Temporarily limiting Snowflake deployment upgrades to the deployment owner while an issue preventing roles with `OPERATE` privilege from upgrading is resolved. ## January 30, 2026 ### Control Plane UI 0.69.0 - Fixed an issue where some actions weren't reevaluated on the current page after an active role change. - BYOC deployments running the latest version now show their current status while processing actions like creating, upgrading, and deleting, including reporting failures when they occur. - Added a `Download validator` button to the deployment creation dialog. ### Control Plane Core 0.101.0 - Fixed an issue where Snowflake deployments briefly showed a `Not Healthy` status while creating, just before becoming active. - BYOC deployments running the latest version now show their current status while processing actions like creating, upgrading, and deleting, including reporting failures when they occur. - Improved the logic for showing the Private Link option when creating SPCS deployments to avoid failures when the option isn't fully supported. - Added an API to generate and download CloudFormation templates for BYOC and BYO-VPC validators. ### Data Plane Service 0.101.0 - Fixed runtime creation on newly active Snowflake deployments. Previously, the latest available runtime versions weren't always used. ### AWS Data Plane Agent 1.16.0 - Snowflake-hosted container images are now pulled directly from Snowflake registries into the deployment EC2 agent host and EKS cluster. Upgrade existing Openflow runtimes to switch entirely to Snowflake-hosted images. - The agent now reports its current status to Openflow while processing user-requested actions, so it can be reflected in the Control Plane UI. - Security patches and dependency upgrades. - Added quick validation tools for BYOC and BYO-VPC deployments that report common errors to resolve before installing a full Openflow cluster. - Improved reliability of deployment upgrades by automatically resolving issues where services were blocked from starting. - Improved reliability of deleting deployments that had been upgraded multiple times. ### Runtime Server 2026.1.29.22 - Upgraded JDK to 21.0.10. - Upgraded Apache NiFi API to 2.6.0, adding support for the `Record Gauge` method in ProcessSession. ### Runtime Extensions 2026.1.29.23 - Added the UpdateGauge processor with configurable `Gauge Name` and `Gauge Value` recording. - Improved JSON Schema validation in GenerateJSON to address potential edge cases for nested fields. - Added the PutIcebergRecord processor and Iceberg REST Catalog controller services, supporting both AWS and Azure storage FileIO providers. - Deprecated the PutIcebergTable processor in favor of PutIcebergRecord. ## January 23, 2026 ### Runtime Server 2026.1.22.19 - Resolved an issue where simultaneous commits to a Git-based Flow Registry Client could cause one user's changes to overwrite another's. - New Runtime UI 0.63.0. ### Runtime Extensions 2026.1.22.19 - Salesforce Bulk API: Fixed an edge case where the initial snapshot might not create the destination table as expected. - BigQuery: Processor properties now reference FlowFile attributes, making it easier to understand component behavior. - Snowpipe Streaming v2: PutSnowpipeStreaming2 now tracks request IDs and automatically terminates empty relationships. - CDC SQL Server: You can now set a maximum FlowFile size in CaptureChangeSQLServer. - Jira: Components now include a verification feature to confirm that your configuration is correct. - Confluence: Components now include a verification feature to confirm that your configuration is correct. ## January 21, 2026 ### Runtime Server 2026.1.20.19 - You can now configure custom SSL certificates in GitHub and GitLab Flow Registry Clients. ### Runtime Extensions 2026.1.20.21 - Enhanced PerformSnowflakeCortexOCR with page splitting and filtering features. - BigQuery: Fixed time travel timestamp handling in TriggerBigQueryCdcOnState processor. - Jira: Better handling of API rate limiting. - CDC Oracle: You can now set a maximum FlowFile size in CaptureChangeOracle. - CDC MySQL: Added logging in CaptureChangeMysql processor to log the retention period for binlog on start. - Confluence: The connector can now ingest file attachments and embedded images. - CDC MySQL and PostgreSQL: FetchTableSnapshot now includes partition chunk attributes to enable multi-channel streaming. ### Connectors 2026.1.20.18 - All Connectors: The default Snowflake Authentication Strategy is now SNOWFLAKE_MANAGED, a token-based method that works in both SPCS and BYOC deployments. - Salesforce Bulk API: Added new parameter, Initial Load Chunking. This option lets you split large initial data loads into time-based chunks (MONTHLY, QUARTERLY, YEARLY) to avoid timeouts and API limits. When set, the initial data load is split into multiple jobs based on the interval. On the first run for an object, the connector queries Salesforce to find the oldest record and uses that as the starting point. Each subsequent job queries the next time chunk until caught up to the current time. Once caught up, the processor continues with normal incremental offload behavior. - Oracle: Initial snapshot loads can now run with multiple concurrent threads for faster performance. - SharePoint: The connector now logs when it encounters and processes empty files. - Confluence: A new connector version is available that does not fetch access control lists (ACLs). ## January 16, 2026 ### Runtime Server 2026.1.15.20 - New Runtime UI 0.62.0. - The copy button in the Bulletin tooltip has been moved so it's always visible. ### Runtime Extensions 2026.1.15.20 - SQL: Added support for Pre-Queries and Post-Queries in PutDatabaseRecord processor. - CDC PostgreSQL: You can now set a maximum FlowFile size in CaptureChangePostgreSQL. - CDC PostgreSQL and MySQL: FlowFiles now include start.row.index and last.row.index attributes. - CDC MySQL: CaptureChangeMySQL now reads the event position from the header instead of from the binlog client. - CDC Connectors: Splitting FetchTableSnapshot output FlowFiles into chunks of MAX_OUTPUT_FLOWFILE_SIZE size. - Snowpipe Streaming: PutSnowpipeStreaming2 now has dedicated handling for empty FlowFiles. - Salesforce Bulk API: Added support for Objects without SystemModStamp field. - Salesforce Bulk API: You can now configure how the initial snapshot is split into time-based chunks. ### Connectors 2026.1.15.18 - Salesforce Bulk API: Added support for Objects with Tracking History enabled. - Salesforce Bulk API: Added support for Objects without SystemModStamp field. - CDC Connectors: Clearer log messages when a table enters a failed replication state. - Google Ads: New "Login Customer ID" parameter lets you specify which manager account (MCC) to fetch reports for. - Dataverse: The COPY GRANTS option is now applied to destination tables. ## January 15, 2026 ### AWS Data Plane Agent 1.15.0 - Resolved an issue where some IAM policies were not deleted when a Deployment was deleted. ## January 14, 2026 ### Runtime Server 2026.1.13.18 - Resolved an issue with how validation was triggered when Flow Registry Clients were configured. ### Runtime Extensions 2026.1.13.19 - Google Ads: The connector now works with manager accounts and their subaccounts. - Oracle: Added new processors designed to accelerate initial snapshot loads. - Snowpipe Streaming: PutSnowpipeStreaming2 now includes a counter for each destination. - SQL: PutDatabaseRecord now uses setBytes binding for BINARY SQL types. ### Connectors 2026.1.13.16 - Slack: Improved handling of file attachments with Slack messages. - Unstructured Connectors: Resolved Null Pointer Exceptions that occurred when parameters were left empty. - Google Drive: You can now specify multiple folders by using a comma-separated list in the "Folder Name" parameter. - Google Drive: New Simple Ingest and Cortex connectors that don't require domain-wide delegation. - Streaming Destination Modules: PutSnowpipeStreaming now limits channel concurrency for streaming destinations. ## January 12, 2026 ### Control Plane UI 0.68.0 - You no longer need OWNERSHIP privilege on the Snowflake Role when configuring BYOC and SPCS Runtimes. - You no longer need CREATE USER privilege to create a BYOC Runtime. - **Behavior change:** Starting with AWS Data Plane Agent 0.37.0, you must specify a Snowflake Role when creating a Runtime. ## January 8, 2026 ### Control Plane UI 0.67.0 - The Deployment details dialog now correctly shows Private Link and End User Auth over Private Link settings. - The SAP connector card now displays an updated icon. - The Runtime and Deployment details dialogs now display the SQL name when available. - The Create Runtime dialog now requires a Snowflake role. It no longer requires CREATE USER privilege. ### Data Plane Service 0.98.0 - The system now polls less frequently for new Runtime versions, reducing query costs. - Runtime Upgrades are now more reliable because all related components are discovered and upgraded together. ### AWS Data Plane Agent 1.13.0 - Resolved an upgrade failure affecting older Deployments that pulled helm charts from AWS OCI Repository. ### SPCS Data Plane Agent 1.11.0 - The deployment creation sequence has been optimized to reduce wait time. ## January 6, 2026 ### Runtime Server 2026.1.5.14 - When you clear bulletins on a process group, bulletins for its scoped controller services are also cleared. - Registry Clients no longer log confusing WARN messages when you commit the first version of a flow. ### Runtime Extensions 2026.1.5.19 - Oracle: Archive logs are now properly removed even when database traffic isn't captured by XStream Out server. - JIRA: Resolved a resource leak triggered by certain HTTP error codes and improved log messages. - Azure components: Fixed NoClassDefFoundError: io/netty/handler/codec/quic/Quic. - Kafka: The verification process is improved and now returns information about the Kafka Connection Controller Service. - MS SQL Server: Database names with special characters are now properly quoted when available tables are fetched. ### Connectors 2026.1.5.13 - All Database CDC Connectors: The snapshot completion log now shows the correct total number of rows ingested. - All Unstructured Connectors: The Cortex service name parameter is now correctly applied to documents. - MySQL & PostgreSQL: You can now configure concurrency settings for Snapshot loads. - JIRA: Performance is improved by reducing small FlowFiles and batching data sent via Snowpipe Streaming. - Google Drive: Inserts via Snowpipe Streaming can now run in parallel instead of sequentially. ## December 19, 2025 ### Runtime Oracle Extensions 2025.12.19.8 - Fixed an issue validating Oracle licenses that prevented the OracleCapture processor from starting. - Improved change detection for large schemas. ## December 17, 2025 ### Runtime Server 2025.12.16.19 - Improved how invalid controller services are handled when you enable or disable them. - Included Registry Clients in the Runtime documentation. ### Runtime Extensions 2025.12.16.19 - PostgreSQL: Fixed ordering of composite key columns. ### Connectors 2025.12.16.19 - Salesforce Bulk API: Added a new parameter to control case sensitivity for object identifiers created in Snowflake. By default, column names remain case sensitive for backward compatibility. This default may change at public preview or general availability. - Confluence Data Center: New connector to integrate with Confluence Data Center edition. ## December 16, 2025 ### AWS Data Plane Agent 1.12.0 - Fixed an issue where BYOC deployment upgrades failed due to a mismatch between the machine image and Kubernetes cluster versions. - Fixed an issue where BYOC deployment upgrades failed with the error message "OCI Registry Login Failed". ## December 11, 2025 ### Control Plane Core 0.95.0 - Fixed an issue where the Runtime Run As Role couldn't be set for roles containing Snowflake-restricted characters, such as hyphens. ### Runtime Server 2025.12.11.21 - Improved behavior when enabling controller services that are invalid and shouldn't be enabled. - New Runtime UI 0.59.0. - Registry clients now support property verification. ### Runtime Extensions 2025.12.11.21 - AWS Secrets Manager: Parameter Provider now considers non-string values as valid parameters. - RenameRecordField processor now properly handles multiple records per FlowFile. - Kinesis: Fixed an issue where the ConsumeKinesis processor throttled new records even when buffers were empty. - Snowflake: Added a default network timeout to the Snowflake Connection Service. - Confluence: Fixed handling of page deletion. - Confluence Data Center: Fixed the HTTP response decoder for the client. - MySQL: Improved logging for table mapping when consuming binlog events. - CDC Databases Connectors: Observability dashboards now display the failure reason when a table's replication status changes to failed. ### Connectors 2025.12.11.18 - SQL Server: Exposed new parameters (Re-read Tables in State and Starting Change Tracking Position) for starting position. - Oracle: Set CASE_INSENSITIVE as the default for created Snowflake objects. - Jira: Added support for App Forge authentication method. - Confluence: Added support for App Forge authentication method. - Oracle: Fixed missing service name in XStream URL in default parameter values. - Oracle: Added support for internationalization. - Unstructured Connectors: Added a parameter to specify the Cortex Search Service name. - Slack Connectors: Added a parameter to control whether user names are resolved. ## December 9, 2025 ### Control Plane Core 0.94.0 - Added support for accessing and using Openflow with an organization or account that has been renamed. ## December 8, 2025 ### AWS Data Plane Agent 1.11.0 - Fixed issue upgrading older deployments with non-critical "inconsistent result after apply" error message. ## December 5, 2025 ### Runtime Server 2025.12.4.19 - New Runtime UI 0.58.0. - Added new action to clear bulletins. - Improved error handling when launching the Status History dialog. ### Runtime Extensions 2025.12.4.19 - Kinesis: Fixed checkpoint committed records in ConsumeKinesis that could previously cause data loss. - PostgreSQL: Fixed issue where CaptureChangePostgreSQL ignored events when data was loaded via COPY FROM STDIN. ### Connectors 2025.12.4.17 - CDC SQL Server MultiDB: Added and exposed support for case sensitivity for created Snowflake objects. ## December 3, 2025 ### AWS Data Plane Agent 1.10.0 - Added support for encrypting EBS volumes across the entire Openflow Deployment. ### SPCS Data Plane Agent 1.9.0 - Snowflake Deployments encountering internal certificate authority mismatch issues are now auto-healed on upgrade. ### Control Plane Core 0.93.0 - Retained visibility and use of resources when an account name or organization is changed. - Improved resource utilization efficiency for Small size runtimes in Snowflake Deployments, allowing 3 runtime pods per node instead of 2. - Added Manage endpoints action for SPCS deployments (requires account parameter). - Improved external access integration (EAI) list to only show those EAIs the user has access to when creating a runtime in a Snowflake Deployment. ### Data Plane Service 0.93.0 - Improved resiliency of automatic diagnostic bundling and cleanup behavior when a runtime fails to create. - Added management capabilities for Openflow endpoints in a deployment accessible via new API methods. - Extended wait time for runtime upgrade failures in SPCS deployments to avoid premature timeout and failure. ### Control Plane UI 0.65.0 - Added Manage endpoints action for SPCS deployments (requires account parameter). ### Data Plane UI 0.11.0 - Added Openflow endpoints management view for SPCS deployments (requires account parameter). ### Openflow Ingress Controller 2025.12.2-17 - Added support for routing to Openflow endpoints attached to Openflow runtimes. - Fixed client IP address forwarding when evaluating Snowflake privileges for Openflow runtimes. - Fixed request header propagation to support deployments with Private Link enabled. ### Runtime Server 2025.12.3.16 - Added support for discovering listen ports from Openflow runtime processors to provide users as available targets for Openflow endpoints. - Controller Services: Fixed validation and enabling that could take too long and cause the runtime to not start. ### Runtime Extensions 2025.12.3.16 - Kinesis: Introduced Shared Throughput consumer in ConsumeKinesis and removed concurrency limits in the HTTP client. - Kafka: Added support for specifying custom SASL Extensions. - EventHub: Added support for OAuth authentication in EventHub processors. - AWS RDS: Added support for AWS RDS IAM Authentication in the DBCP Connection Pool to access databases over JDBC. - Listen* Processors (Examples: ListenHTTP, HandleHttpRequest, ListenOTLP): Added support for new ListenComponent and ListenPortDefinition NiFi APIs to allow discovery of listen ports for use with Openflow endpoints. - OpenflowRuntimeSSLContextProvider: Added new control service for use with Listen* Processors to integrate with Openflow endpoints. - Oracle: Fixed handling of case sensitivity on column names when using lower casing. - Oracle: Fixed support for internationalization. - MySQL: Fixed filtering of Azure-specific system tables. - BigQuery: Added new components for the Google BigQuery Change Data Capture (CDC) connector. - SQL Server: Added ability to choose the starting position when reading the stream. - Confluence Data Center: Improved support for Audit Records ingestion. - Confluence: Improved performance to retrieve Confluence page IDs. - Confluence: Added support for Forge App authentication method. - Google Drive: Improved recursive listing efficiency when listing the content of a drive. - Slack: Fixed fetching information of users for large workspaces with a large number of users. ### Connectors 2025.12.3.15 - Google Drive: Fixed potential NullPointerException when Google Drive Folder parameter is not set. - Slack: Added check to verify files have content before uploading to Snowflake. - CDC PostgreSQL: Increased backpressure settings to better support large number of synced tables. - Dataverse: Improved the query for the deletes in the Journal Table. ## December 2, 2025 ### Control Plane Core 0.92.0 - Fixed a thread contention issue in Snowflake Deployments that could cause some Runtime actions triggered from Control Plane to time out and fail. ### Data Plane Service 0.92.0 - Fixed a thread contention issue in Snowflake Deployments that could cause some Runtime actions triggered from Control Plane to time out and fail. ### Openflow Ingress Controller 2025.11.20-18 - Added support for Programmatic Access Token authentication and authorization. ### Openflow Runtime Gateway 2025.11.19.22 - Added support for Programmatic Access Token authentication and authorization. ## November 21, 2025 ### AWS Data Plane Agent 1.8.0 - Restores support for private Openflow BYOC Deployments by removing all dependencies on URLs outside of Snowflake and AWS, addressing an issue introduced in 1.6.0 ### Control Plane Core 0.91.0 - Fixed a rare issue that prevented a Runtime from being activated after it had been suspended ### Data Plane Service 0.91.0 - Fixed an issue causing connector installations to fail on new Runtimes when bulletins are present ## November 20, 2025 ### Runtime Server 2025.11.20.20 - Improved visibility of Runtime operations with new metrics for Connectors ### Runtime Extensions 2025.11.20.19 - New components to interact with SAP Business Data Cloud and mapping of CSNs into Snowflake Semantic Views - CDC MySQL - Improved reliability by clearing out the table map prior to CDC reconnects - CDC Databases - Fixed a potential deadlock issue with MergeSnowflakeJournalTable when "poll query result" is cleared during operation - CDC MariaDB - Added support for MariaDB in the MySQL components - CDC PostgreSQL - Added support for primary keys of type `numeric` ### Connectors 2025.11.20.17 - CDC Databases - Adjusted backpressure thresholds on some connections when processing a lot of data - Salesforce - Gracefully handle scenarios where we insert duplicate rows in the staging table - CDC Databases - Exposed parameter to enable private connectivity in the PutSnowpipeStreaming processor for data ingest - CDC PostgreSQL - Adjusted yield duration on CaptureChangePostgreSQL to not overuse replication connections ## November 19, 2025 ### Runtime Extensions 2025.11.18.22 - SQL Server - Performance improvement in Snapshot query - Dataverse - Schemas are no longer filtered when no column filtering value is provided - Telemetry - "Bytes Received" is now available for many Snowflake processors after fixing the file size for provenance events - Azure components - Fix ConsumeAzureEventHub by excluding netty-codec-http3 dependency - Google Cloud - Added support for Workload Identity Federation - Azure Blob Storage - Added support for uploading files larger than 200 GB ### Connectors 2025.11.18.17 - Google Ads - Set the new Authentication Strategy property of the GCP Credentials Controller Service - Multi Database SQL Server - Fix `source.table.fqn` value handling - Salesforce - Add logging for successful sync operations to ease monitoring via the events table ### AWS Data Plane Agent 1.6.0 - Improves security by removing unused inbound ports on Load Balancers configured for "Custom Ingress." You can further limit access with your own Security Group for these Openflow Deployments. - Improves security and eased configuration of Runtimes with an optional Deployment-level IAM Role to securely access AWS resources like RDS, MSK, Kinesis, and S3. You can now attach IAM Policies to Openflow's "NodeInstanceRole" that are granted to all Runtimes in that Openflow Deployment. - Upgrades EKS Cluster from 1.32 to 1.34 for long-term maintenance and security patching - Resolves an issue where restarting some EC2 nodes frequently caused the Openflow Deployment to freeze - Security patches and upgrades to third party libraries ### SPCS Data Plane Agent 1.4.0 - A missing event table will no longer cause failure when creating an Openflow Snowflake Deployment. - Fixed certificate based issues accessing Runtimes and deploying Connectors into Deployments older than 60 days - Security patches and upgrades to third party libraries ### Control Plane UI 0.64.0 - Adding support for the new Cleaning Up Runtime state - Adding support for terms accepted trial not started or active trial ### Control Plane Core 0.90.0 - If a Runtime fails to create, it will automatically generate a diagnostics bundle and clean up any partially created resources in the cluster. ### Data Plane Service 0.90.0 - If a Runtime fails to create, it will automatically generate a diagnostics bundle and clean up any partially created resources in the cluster. ### Openflow Ingress Controller 2025.11.12-18 - Security patches and upgrades to third party libraries ## November 15, 2025 ### Runtime Extensions 2025.11.16.2 - Improved reliability for high volume deployments by relocating state tracking for replication position and journal versioning in CDC Connectors ## November 14, 2025 ### Runtime Server 2025.11.14.17 - Easier debugging with an updated Bulletin Board that can expand stack traces - Fixed bug when rendering Documentation for extensions that lack tags - Viewing component state now supports showing 5,000 local entries and 5,000 cluster entries, up from 500 each ### Runtime Extensions 2025.11.14.17 - Reduced costs by removing the validation query in the Snowflake Connection Service ### Connectors 2025.11.14.14 - Google Drive and Google Sheet - Set the new Authentication Strategy property of the GCP Credentials Controller Service ## November 13, 2025 ### Runtime Extensions 2025.11.13.19 - Added support for Web Identity authentication to AWS MSK IAM Connection Service in Kafka components - Added support for Web Identity authentication to AWS Credentials Controller Service for all AWS components - Added Flow Registry Client support for Bitbucket Data Center edition - Fixed Worker ID generation in ConsumeKinesis and added provenance data - Added support for nested paths in HashiCorpVaultParameterProvider - Dataverse - Added retry-after mechanism - Added Snowflake Secrets Parameter Provider - CDC Database Connectors - Improved reliability and performance on state management - JIRA - Enriched issues with email addresses - HubSpot - Fixed handling of 414 error code responses while fetching objects ### Connectors 2025.11.12.21 - Dataverse - Add Column JSON Filtering parameter - PostgreSQL - Added FIFO FlowFile prioritizer on queues in Postgres Snapshot Load - MySQL - Expose parameter for the starting position of the replication - Dataverse - Added updated_at and deleted columns - Salesforce - Switched the CSV Reader to RFC 4180 - Salesforce - Fixed configuration to capture soft deletes ## October 31, 2025 ### AWS Data Plane Agent 1.1.0 - Security patches and upgrades to third party libraries ### SPCS Data Plane Agent 1.1.0 - Security patches and upgrades to third party libraries ### Control Plane Core 0.88.0 - Enable Openflow Oracle Connector in Snowflake Deployments ### Data Plane Service 0.88.0 - Security patches and upgrades to third party libraries ### Runtime Operator 0.45.0 - Security patches and upgrades to third party libraries ### Runtime Extensions 2025.10.31.13 - Improved reliability of high volume CDC Connectors ## October 30, 2025 ### Runtime Extensions 2025.10.30.21 - CDC Database Connectors - New components for multi-databases support are now included in the runtime image - JIRA - Added support for Forge App authentication method - New OAuth2 controller service to get Snowflake issued JWTs for Workload Identity Federation ### Connectors 2025.10.30.20 - PostgreSQL - Added First In First Out (FIFO) connection prioritizer in PostgreSQL Snapshot load - CDC Database Connectors - Disabled load balancing in the incremental flow to ensure single node processing of the data - Dataverse - Added parameter for the new JSON Column Filtering property ## October 29, 2025 ### Runtime Server 2025.10.28.18 - Fixed bug in Summary table formatting Process Group task time ### Runtime Extensions 2025.10.28.20 - Kinesis - Support Output Strategy property in ConsumeKinesis processor - Kinesis - Added the new Kinesis components leveraging the latest AWS client library - SQL Server - Added support for multiple databases - MySQL - Added the possibility to specify the binlog starting position for reading the CDC stream - PostgreSQL - Added support for negative scale in numeric types - SQL Server - Improved the ordering of the ORDER BY clause - Snowpipe Streaming - Improved Input Buffer Handling in PutSnowpipeStreaming2 - PostgreSQL - Improved performances in FetchTableSnapshot on large tables with composite primary key - MySQL - Fixed incorrectly replicated DATEs pre 1582-10-15 (Julian calendar) ### Connectors 2025.10.28.9 - Oracle - support for multiple logical databases - MySQL, PostgreSQL, SQL Server - no longer writing the unused avro.schema FlowFile attribute - Jira - support for fetching Worklogs ## October 28, 2025 ### AWS Data Plane Agent 0.61.0 - Security patches and upgrades to third party libraries ## October 27, 2025 ### Control Plane UI 0.63.0 - Security patches and upgrades to third party libraries ## October 24, 2025 ### Control Plane Core 0.86.0 - Fixed issue where a user can't log into Openflow if their most recently selected active role was revoked. - Disable creating a Snowflake Deployment if the user's role is not granted CREATE COMPUTE POOL privilege. ### Control Plane UI 0.62.0 - Improved display for Upgrade Failed, Inactive, and Activate Failed states - Always show the current "Run As" role even if it's not in the current user's set of account roles - Fixed issue with "Run As" role validation in Create Runtime dialog ## October 23, 2025 ### Runtime Server 2025.10.23.16 - Bulletin icons now reflect the severity of the message - Parameters can now be edited by double clicking on the row in the Parameter Context - Included state of system diagnostics API call in the loading skeleton and spinner in the Cluster Listing - Improved awareness of errors through the global banner when extension types fail to load - Updated styling for unset, blank, empty styles throughout the Runtime UI ### Runtime Extensions 2025.10.23.11 - Fixed incorrect handling of Drop Table actions in UpdateSnowflakeTable processor - Oracle - Improved performance by moving metadata generation in FetchSnapshot processor - Oracle - Fixed handling of column filters DDL - Dataverse - Added optional configuration to filter columns being fetched - Cortex - Improved error message when there is an issue calling Cortex in PromptSnowflakeCortex processor - MySQL - Fixed the filtering out of the "user" table - Salesforce Data Cloud - Added support for detecting deletions of Data Shares and linked Objects in the shares - MySQL - Fixed skipping compressed transaction DDLs and DMLs spanning over the transaction - JIRA - Enrich Jira Worklogs processor - Confluence - Support for Confluence Data Center edition - Added Offset Tracking Resolution to PutSnowpipeStreaming2 processor - Sharepoint - Fixed pagination handling when listing more than 200 items - Salesforce - Added optional lookup key in UpsertSFDCObjects processor allowing user to specify a field other than ID for retrieving the record to upsert ### Connectors 2025.10.22.17 - Excel - Added missing SPCS related configuration options - HubSpot - Added support for new object types: Notes, Orders and Carts - Salesforce - Added missing configuration for authentication strategy for usage of the connector in Openflow Snowflake Deployments - PostgreSQL - Migrated the connector to standard identifiers for better management of case sensitivity on object naming - Oracle - Removed the addition of Snowflake Specific Columns to leverage FetchSnapshot processor instead and improve performances - Sharepoint - New Simple Ingest connector that does not fetch the ACLs associated to the data - Salesforce - Added support for specifying the object fields that should be included/excluded when retrieving the data ## October 20, 2025 ### Control Plane Core 0.84.1 - Released Control Plane Core version 0.84.1. ## October 17, 2025 ### AWS Data Plane Agent 0.60.0 - Fixed certificate issues that blocked access to runtimes and connector deployments in deployments older than 60 days. ### Control Plane Core 0.84.0 - Fixed input validation issues when filtering in role selection menus. - Fixed an issue where links to runtimes were shown to users without access privileges. - Fixed an issue where users with only USAGE privilege on a runtime couldn't create connectors in that runtime. - Fixed an issue for users accessing Openflow over PrivateLink with a network policy enforcing the VPCE ID. - Added support for suspending and activating runtimes in Snowflake deployments. - Snowflake deployments now display their current version immediately after creation is initiated. ### Control Plane UI 0.60.0 - Warns users before navigating to a deployment or runtime where VPN connectivity may be required when using custom ingress. - Keeps the selection panel open for multi-select components after a selection is made. - Enforces user permissions for viewing the runtime canvas and hides links if permissions are missing. - Improves setup experience by considering total counts of runtimes and deployments, not just those in the ACTIVE state. - Makes the Snowflake role optional when creating a runtime in a BYOC deployment. - Improves text overflow handling for connector cards. ### Openflow Ingress Controller 2025.10.16-17 - Fixed an issue that prevented access to runtimes over PrivateLink. - Fixed an issue where a new runtime couldn't be accessed if its name matched that of a previously deleted runtime. ## October 15, 2025 ### Runtime Extensions 2025.10.14.22 - Added Snowflake Managed Authentication Strategy to SnowflakeConnectionService and PutSnowpipeStreaming. ### Runtime Oracle Extensions 2025.10.14.22 - Improved snapshot query performance by correcting ORDER BY column sorting. ### Runtime Server 2025.10.14.12 - Fixed missing Process Group identifier information in Processor and Controller Service log records. ## October 08, 2025 ### AWS Data Plane Agent 0.59.0 - Added support for workarounds when using self-managed certificates in AWS. - Fixed issues that caused BYOC deployment upgrades to get stuck with invalid image references and job cleanup. - Restored support for adding customer-managed IAM policies to Openflow's IAM roles. ## October 03, 2025 ### Connectors 2025.9.30.17 - Updated the Dataverse connector to set empty collation for the Dataverse journal table. ### Runtime Extensions 2025.10.2.19 - Added better support for case sensitivity on Snowflake objects in `MergeSnowflakeJournalTable`. - Improved HubSpot pagination handling when retrieving more than 10,000 records. - Unstructured Processing - `PerformSnowflakeCortexOCR` now uses the `AI_PARSE_DOCUMENT` function instead of `PARSE_DOCUMENT`. - Added better support for case sensitivity on Snowflake objects in PutSnowpipeStreaming. - PostgreSQL - Fixed unsigned handling of type OIDs in the CaptureChangePostgreSQL processor. ### Runtime Server 2025.9.30.19 - New Runtime UI 0.53.0. - Fixed a regression that prevented tabbed dialogs from remembering the previously active tab. - Fixed balto icon regressions and selected radio button display issues. - Fixed an issue where Parameter Context update requests weren't deleted when users canceled the request. - Fixed an issue that caused double scroll bars to appear in the asset upload dialog. - Fixed an issue where the selected asset count could get out of sync. ## September 26, 2025 ### AWS Data Plane Agent 0.52.0 - Improved efficiency of private IP addresses used by EKS cluster nodes, reducing the total number required for scaling out to many Runtime nodes. - Fixed issue with Runtime logs that incorrectly redacted some component IDs. ### Connectors 2025.9.25.17 - Confluence connector - Better failure handling and retries when facing API rate limits. ### Control Plane Core 0.80.0 - Support for deploying Oracle Runtime Extensions to Runtimes in BYOC Deployments for PrPr customers who have accepted the Terms of Service. - Fixed an issue where Snowflake deployment moved into an active state prematurely during an upgrade. - Fixed a rare issue where Snowflake deployment deletions could get stuck and need manual intervention. ### Control Plane UI 0.57.0 - Introduced new deployment upgrade dialog that shows the version mapping. ### Data Plane Service 0.80.0 - Support for deploying Oracle Runtime Extensions to Runtimes in BYOC Deployments for PrPr customers who have accepted the Terms of Service. ### Runtime Extensions 2025.9.25.19 - CDC database connectors: Removed Record Reader from MergeSnowflakeJournalTable processor. - All connectors log the Query ID whenever a connector executes a query in Snowflake. ### Runtime Oracle Extensions 2025.9.23.19 - PrPr release of Oracle Extension for Openflow Runtimes. ### Runtime Server 2025.9.25.19 - Improved the Openflow Connectors upgrade user experience. ## September 23, 2025 ### Connectors 2025.9.23.17 - PostgreSQL connector now includes a new parameter so you can set the replication slot name. - The PostgreSQL, MySQL, and SQL Server connectors now support column names that include special characters. ### Runtime Extensions 2025.9.23.19 - Added compression to rows added using the Insert Rows method through PutSnowpipeStreaming2. - MySQL: Added support for compressed bin log events. - Added new processors, UpdateSnowflakeSchema and UpdateSnowflakeStream, to better manage object lifecycles and support case sensitivity. - HubSpot: Added support for new "Notes," "Orders," and "Carts" object types. - Slack: Fixed Null Pointer Exception when trying to verify the configuration of ConsumeSlackConservations processor. ### Runtime Server 2025.9.23.19 - Using latest Apache NiFi 2.6.0 release. - Improved the flow upgrade user experience by improving Flow Differences Filters to handle renameProperty, removeProperty, and createControllerService. - New Runtime UI 0.52.0. - Fixed bug allowing default values for dynamic properties. - Improved the performance of the searchable select used in the Property combo editor. ## September 19, 2025 ### AWS Data Plane Agent 0.50.0 - Openflow now supports VPCs with DHCP Option Sets, making it easier to connect to private data sources. - You can now secure Openflow deployments with PrivateLink, while still allowing browser-based authentication to runtimes without PrivateLink. - Fixed an issue during upgrades where IAM inline policies failed by exceeding maximum character limits. ### Control Plane Core 0.78.0 - Improved error messages for Snowflake deployment failures to show the root causes. - Fixed a case where BYOC deployment ends up in Not Healthy state but can't be deleted from Openflow Control Plane. ### Control Plane UI 0.55.0 - Removed unnecessary title on **Runtime and Deployment state** columns. ### Openflow Runtime Gateway 2025.9.18.22 - Improved cookie session handling to allow users to remain logged in, even when Runtime is open in an inactive browser tab. ## September 18, 2025 ### Connectors 2025.9.17.18 - Addition of the 2 new Oracle CDC connectors. - Confluence connector - The introduction of a new controller service to handle API rate limits will show the connector as a process group with local changes. This can be ignored and will be resolved when upgrading the connector to the next version, when available. ### Runtime Extensions 2025.9.18.18 - Introduced the `UpdateSnowflakeTable` processor, which is like `UpdateSnowflakeDatabase`, but designed for tables and improved case sensitivity. ## September 16, 2025 ### Connectors 2025.9.16.18 - SQL Server connector: Exposed the new SQL Server query interval property as a parameter. - The new controller service for API rate limits in the Jira connector causes the connector to appear as a process group with local changes. You can safely ignore this; it will be fixed in a future connector upgrade. ### Control Plane UI 0.54.0 - Allow users to optionally configure whether end users authenticate over PrivateLink. - The **Estimated time to completion** shown when creating Snowflake Deployments and Runtimes is now more accurate. ### Openflow Ingress Controller 2025.9.15-14 - Initial release offering privilege isolation for Openflow runtime authentication and authorization to Snowflake deployments. ### Runtime Extensions 2025.9.16.20 - Added support for DATETIME columns with PutBigQuery processor. - You can now specify the HTTP protocol version in **StandardWebClientServiceProvider**. - Better logging and increased timeouts for FetchSharepointFile processor. - Added the option to set the replication slot name in CaptureChangePostgreSQL processor. - You can now use `-infinity` and `+infinity` with Postgres TIMESTAMPTZ values. - New controller service StandardAtlassianRequestRateManager to deal with API rate limits for the Jira connector. - Fixed exceptions thrown from ListMicrosoftDataverseTables when table schema isn't returned by API. ### Runtime Operator 0.40.0 - Support deploying the new Openflow ingress controller for PuPr release of Snowflake deployments. ### Runtime Server 2025.9.16.19 - New Runtime UI 0.51.0. - You can now delete individual entries in the component state if the component allows it. - Improved tooltips for Property and Parameter values, especially when values are long or reference external resources. ## September 15, 2025 ### AWS Data Plane Agent 0.41.1 - Fixed an issue from AWS Data Plane Agent 0.39.0 that blocked the first install of an Openflow deployment into a new AWS region. ## September 11, 2025 ### Control Plane Core 0.73.0 - Fixed issue preventing runtime deletion in Snowflake deployments when a network policy is present. ### Data Plane Service 0.73.0 - Fixed an issue that prevented runtime deletion in Snowflake deployments when a network policy was present. - Fixed an issue that prevented new versions of runtime extensions from being used when runtimes were created or upgraded. ### Runtime Extensions 2025.9.11.18 - CaptureChangeSQLServer: A new setting, `Table Changes Query Interval`, is introduced to reduce the resource pressure on the source database. Now, the processor queries the source database every 10 seconds (`10 sec`) by default. To restore the original behavior, change the setting to `0 sec`. ## September 10, 2025 ### AWS Data Plane Agent 0.40.0 - Resolved an issue where deployments were left partially upgraded after AWS Data Plane Agent 0.39.0 was used. ### Connectors 2025.9.9.18 - Unstructured connectors: Improved reporting on `ChunkText` failures. ### Runtime Extensions 2025.9.10.7 - Microsoft Dataverse: Fixed handling of schemas that include the `Edm.Date` type. - Fixed attribute prefix handling in the XML Reader. - Fixed MongoDB controller service for certain authentication methods when information is provided through the URI. - Added Azure DevOps Flow Registry Client for Git integration with Azure DevOps to version flows. ### Runtime Server 2025.9.9.20 - Added the ability to change the version of a ghosted component if a bundle with the same coordinates and a different version exists. ## September 8, 2025 ### AWS Data Plane Agent 0.37.0 - Added support for AWS Data Plane Agent deployments that have DHCP Option Sets configured on the account. - Upgraded all EKS nodes from Amazon Linux 2 to Amazon Linux 2023. ### AWS Data Plane Agent 0.38.0 - Added support for AWS accounts that require encrypted EBS volumes by default, even if an unencrypted EBS volume is requested. Customers can enable this by adding IAM Policies to the `*-eks-role IAM Role` that grant access to their KMS keys. ### Control Plane Core 0.72.0 - Error messages are now clearer and more informative when runtime-related failures occur. - Fixed a rare case where an older deployment version disallowed creating a runtime with the same name as a previously deleted runtime. ### Control Plane UI 0.52.0 - Deployment listing and details now include the deployment version number. - Control Plane logout page now offers a link back to Snowsight - Searchable select control (used in **Create Runtime** and **Manage Access**) now offers improved behavior when text overflows available space. - Fixed a bug that temporarily showed duplicate roles when revoking privileges through the **Manage Access** dialog. ### Data Plane Service 0.70.0 - Added support for AWS Data Plane Agent deployments that have DHCP Option Sets configured on the account. - Allowed customers to delete a runtime and create a new one with the same name shortly thereafter. ## September 5, 2025 ### Connectors 2025.9.4.19 - Confluence Connector: Refresh frequency is now set to 1 minute and is no longer exposed as a parameter. ### Runtime Extensions 2025.9.4.20 - Resolved an incompatibility between the Github Registry Client and the latest Jackson release. - Fixed attribute prefix handling in XML Reader - Added `StandardProtobufReader` controller service for Protobuf record processing - `ListTableName` won't fail the entire FlowFile if partial input is incorrect. ### Runtime Server 2025.9.4.20 - Introduced Runtime UI 0.50.0 - Added a new logout page that provides users options for logging back in or navigating to the Control Plane. - Enhanced the searchable select control to display options more clearly when text exceeds available space. - Fixed casing and icon issues when inputting attributes during extension verification. - Fixed header styling applied to additionalDetails markdown files. ## September 2, 2025 ### AWS Data Plane Agent 0.35.0 - Support for AWS Tags with dots in the Tag key. ### Connectors 2025.9.2.16 - MySQL CDC: Always create a new table (and fail if the table already exists) when replication mode is set to `full`. ### Runtime Extensions 2025.9.2.17 - The GitLab Flow Registry Client now supports versioning flows larger than 2 MB. - Fixed issue in the MongoDB Controller Service preventing users to authenticate using X509. - Fixed irrelevant error logs about schema hash in `UpdateSnowflakeDatabase` processor. - Confluence: Fixed a bug that prevented users from being added to authorized users even though they had permissions to the space from the group level. - Fixed `NoSuchElementException` thrown in ChunkText processor and better failure handling with dedicated relationship. - HubSpot: Fixed bug preventing the List processors to properly go through all the pages. ### Runtime Server 2025.9.2.20 - New Runtime UI 0.48.0. - Upgraded to the latest version of CodeMirror and updated usage throughout the application. ## August 28, 2025 ### Connectors 2025.8.28.17 - MS SQL CDC Connector: Added support for incremental only mode. - HubSpot connector: Fixed table creation on invalid object type. ### Runtime Extensions 2025.8.28.19 - Added StandardProtobufReader Controller Service for Protobuf record processing ## August 27, 2025 ### AWS Data Plane Agent 0.33.0 - Fixes health checks for Load Balancer Target Groups, so everything shows green in the AWS Console. ### Control Plane Core v0.68.0 - Supports a finer-grained privilege model for deployments and runtimes including MONITOR and OPERATE privileges. ### Control Plane UI v0.51.0 - Supports a finer-grained privilege model for deployments and runtimes including MONITOR and OPERATE privileges. ### Runtime Operator 0.39.0 - Supports a finer-grained privilege model for deployments and runtimes including MONITOR and OPERATE privileges. ## August 26, 2025 ### Runtime Extensions 2025.8.26.18 - MS SQL Server: Fixes handling of datetime when used as a primary key. ## August 21, 2025 ### Connectors 2025.8.21.16 - PostgreSQL connector: Supports TOASTed values. ### Runtime Extensions 2025.8.21.17 - Uses Google Ads API v21 (Note, v18 is no longer supported). ### Runtime Server 2025.8.21.17 - New Runtime UI 0.47.0. ## August 20, 2025 ### Connectors 2025.8.19.17 - Slack connectors: Fixes handling of attachments by appending the File ID to the filename for the files stored in the stage. ### Runtime Extensions 2025.8.20.10 - Adds Google Cloud support to PutSnowpipeStreaming2. - Adds support for Incremental Only mode in PostgreSQL CDC connector. - Fixes error when trying to verify configuration in List Azure processors. ### Runtime Server 2025.8.19.18 - Supports unquoted parameter references with spaces in their names within an expression language. ## August 15, 2025 ### Control Plane Core 0.64.0 - Resolves an issue that sometimes caused runtime deletion to fail in Snowflake deployments. ### Runtime Operator 0.38.0 - Resolves an issue facilitating runtime autoscaling in Snowflake deployments. ### Runtime Server 2025.8.14.18 - Improves readability in Provenance Event dialog. ## August 13, 2025 ### Control Plane Core 0.62.0 - New AWS BYO-VPC deployments now add the "Private Security Group" to the EKS cluster, making it easier to configure connections to data sources. - Resolves an issue for new Deployments with a private security group configuration that couldn't pull images from Snowflake over PrivateLink. ### Control Plane UI 0.49.0 - Runtime and Deployment action menus now have separators to help group actions. - Account roles show in a searchable selection with virtual scrolling. ### Data Plane Service 0.62.0 - Runtime flows no longer disappear after suspend and reactivate due to a conflicting auto scaling operation. ### Runtime Extensions 2025.8.12.20 - Adds FlowFile attributes support for Database and Schema properties in PutSnowflakeInternalStageFile. - New GetConfluenceSpaces processor. - PostgreSQL CDC now properly handles DATE, TIME, TIMESTAMP primary keys. ### Runtime Server 2025.8.12.20 - New Runtime UI 0.45.0: Minor improvements to the Component State dialog to improve readability of state entries. ## August 12, 2025 ### AWS Data Plane Agent 0.32.0 - Fixes issue destroying BYOC deployments that was introduced with 0.29.0. - Fixes issue from 0.29.0 release where BYOC deployments in AWS Regions with longer names may fail due to IAM Policy length limitations. ## August 7, 2025 ### AWS Data Plane Agent 0.30.0 - Upgrades the AMI of EKS nodes when the deployment is upgraded. - Removes unnecessary IPv6 Security Group rules for ingress and egress. ### Runtime Extensions 2025.8.7.20 - Improves ConsumeKafka by introducing an Inject Offset Output strategy to add a field kafkaOffset to the records. - Adds the preview tag for Salesforce, Confluence and HubSpot components. - Better configuration validation in UpdateSnowflakeDatabase to avoid using empty parameters. - Adds GetConfluencePageContent and GetConfluencePageIds processors for Confluence. - Fixes UpdateSnowflakeDatabase to properly redirect to the failure relationship when schema is not specified or does not exist. - Improves error handling of non-authorized calls in HubSpot processors. ### Runtime Server 2025.8.7.20 - New Runtime UI 0.44.0: Improves ConsumeKinesisStream by introducing a schema difference handling strategy to specify how records using the same schema should be grouped. - Fixes issue in rendering the canvas that surfaced on initial page load. ## August 6, 2025 ### Runtime Extensions 2025.8.5.19 - Adds Pipe Info Counter and Channel Error Message to PutSnowpipeStreaming2. - MySQL connector: Supports enabling the connector in Incremental mode only. - HubSpot connector: Improves handling of non-supported object types and fixed processing ordering of the events. ### Runtime Server 2025.8.5.19 - New Runtime UI 0.43.0: The Runtime UI now supports labeling extensions in Preview. The badge is shown in the create dialog, on the canvas, in the operate palette, in the edit dialog, and in listings for extensions not on the canvas. ## August 5, 2025 ### AWS Data Plane Agent 0.29.0 - Private deployments: All images and binaries are provided by Snowflake instead of various internet sources. - Custom Ingress for "Bring Your Own VPC" deployments: Supports enterprise customers who use VPNs to access their cloud infrastructure and self-managed TLS certificates. - Adds end-to-end support for PrivateLink. Previously, data and management communications were available over PrivateLink. Now, the deployment can install over PrivateLink, too. ### Control Plane Core 0.60.0 - Adds improvements necessary to support BYOC private deployments. - Improves handling of outbound grants when transferring ownership of a runtime or deployment. - Trial accounts are now permitted to use Openflow with relevant parameter enabled. - Fixes an issue that disrupted use of Control Plane for customers with a large number of Snowflake roles. ### Control Plane UI 0.48.0 - In runtime and deployment listings, more actions in the menus are disabled rather than hidden. - Removes a link to accept terms. This change prevents problems when the user doesn't have an active Snowsight session. - When a new version is detected, prompts the user to reload the CP UI. - Disallows changing ownership of runtimes in Snowflake deployments. - Fixes bug that required a Snowflake role, even when the field was hidden. ### Data Plane Service 0.60.0 - Includes improvements necessary to support BYOC private deployments. - Fixes an issue that disrupted Connector deployment for customers with a large number of Snowflake roles. ### Openflow Runtime Gateway 2025.8.1.14 - Fixes an issue with certificate refresh upon renewal which prevented users from logging into older runtimes. ## July 31, 2025 ### Connectors 2025.7.31.17 - Jira: Improved readability of the flow. The scheduling is now exposed via a parameter. ### Runtime Extensions 2025.7.31.18 - Adds File Fragment Size and Count to PutSnowpipeStreaming2. - Introduces new Confluence processors for the upcoming connector GetConfluenceGroupUsers, GetConfluencePagePermissions, GetConfluenceSpacePermissions, ListConfluenceGroups. - Adds support for TOASTed value in PostgreSQL CDC. - Fixes initial rendering of canvas when fonts may load slowly. - Fixes parameter removal in Parameter Contexts owned by a Parameter Provider. ### Runtime Server 2025.7.31.18 - New Runtime UI 0.42.0: Improves formatting in Status History dialog when values are lengthy. ## July 29, 2025 ### Runtime Server 2025.7.29.9 - Fixes an issue with scaling that left some nodes in a disconnected state. ## July 24, 2025 ### Connectors 2025.7.24.17 - Kafka Connectors: Fixes referenced readers when writing to Iceberg formatted tables. ### Runtime Extensions 2025.7.24.18 - Fixes S3 Location Type in PutSnowpipeStreaming2. ### Runtime Server 2025.7.24.18 - Adds support for users to reset all Counters in a single action. - Fixes an issue that caused upgrade failure for runtimes with more than 1 node present. ## July 23, 2025 ### Control Plane Core 0.58.0 - Adds support for selecting an active role to use in the application, rather than relying on a default role and secondary role inheritance. - Adds support for considering Snowflake role hierarchy during authorization controls. ### Control Plane UI 0.47.0 - Adds support for selecting an active role to use in the application, rather than relying on a default role and secondary role inheritance. ### Data Plane Service 0.58.0 - Adds support for considering Snowflake role hierarchy during authorization controls. ### Openflow Runtime Gateway 2025.7.22.20 - Adds support for considering Snowflake role hierarchy during authorization controls. ## July 22, 2025 ### Runtime Extensions 2025.7.22.19 - A new controller service better supports Slack API rate limits. - Fixes SnowflakeSignJWT controller service. ## July 16, 2025 ### AWS Data Plane Agent 0.25.1 - Fixes upgrades to pull and use the latest host scripts. This change enables Openflow to more easily make changes to the agent itself during an upgrade. ## July 15, 2025 ### Connectors 2025.7.15.14 - Confluence JIRA connector: Improves type mapping for the JIRA issues. Uses the new processor for managing lifecycle of views. - Slack connectors: Changes defaults for run schedule properties to avoid rate limiting errors. ### Control Plane Core 0.53.0 - Adds support for generating and downloading runtime diagnostic bundles. ### Control Plane UI 0.46.0 - Adds support for generating and downloading runtime diagnostic bundles. ### Data Plane Service 0.53.0 - Adds support for generating and downloading runtime diagnostic bundles. ### Runtime Extensions 2025.7.15.16 - Adds the PutSnowpipeStreaming2 processor using SSv2. ### Runtime Server 2025.7.15.16 - New Runtime UI 0.40.0: Fixes a bug that prevented tooltips from closing on the canvas. ## July 10, 2025 ### Control Plane UI 0.45.2 - Adds support for PrivateLink redirects for the Launch Openflow button. - Fixes an issue where logout doesn't log the user out if the user revisits soon after. ## July 9, 2025 ### Connectors 2025.7.8.14 - PostgreSQL, SQL Server and MySQL Connectors: Change to Journal creation process group to remove the false positive error bulletin for PutSnowpipeStreaming when it was asked to create channels on tables/streams that don't yet exist. ### Control Plane Core 0.52.0 - Users must have proper privileges before they can list or view a runtime. ### Control Plane UI 0.45.1 - Fixes a bug that caused runtime and deployment listings not to show and prevented creation of new resources. ### Runtime Extensions 2025.7.9.14 - Git Registry clients have the option to ignore parameter changes when versioning a new version of a flow. - New HubSpot processor to retrieve the schema of HubSpot objects. - New processor UpdateSnowflakeView to manage lifecycle of Snowflake views. - New controller service RemoveFieldRecordReader to drop fields on read. - Supports PostgreSQL Aurora. - CaptureChangeSQLServer generates a valid query when the primary key consists of multiple columns. - UpdateSnowflakeDatabase now checks only column types when required. ### Runtime Server 2025.7.9.14 - New Runtime UI 0.39.0 - Improves colors in canvas for Process Group version control status. - Improves styling for better alignment with Balto colors. - Assets are no longer prevented from being re-uploaded in the Manage Assets dialog. - When using form control to increment a numeric value, output from a dirty Edit Processor form is no longer prevented. ## July 3, 2025 ### AWS Data Plane Agent 0.22.2 - Upgrades no longer get stuck when upgrading due to a missing Data Plane UI 0.7.0 image. ## July 1, 2025 ### AWS Data Plane Agent 0.22.1 - New deployments no longer fail to install due to mid-handling failure code when checking for the presence of AWS ECR repositories. ### Runtime Extensions 2025.7.1.18 - Google Ads: Limits the numbers of calls to Google Ads API when validating the components to avoid rate limit errors. ## June 28, 2025 ### Runtime Extensions 2025.6.27.21 - Fixes NullPointerException in PutSnowpipeStreaming when empty flow files are being processed and Delivery Guarantee is set to `Exactly once`. ## June 27, 2025 ### Control Plane Core 0.51.0 - New terms of service flow: Customers can use Control Plane to create Snowflake-managed deployments without accepting BYOC and Connector terms. ### Control Plane UI 0.43.0 - New terms of service flow: Customers can use Control Plane to create Snowflake-managed deployments without accepting BYOC and Connector terms. ## June 26, 2025 ### Connectors 2025.6.26.15 - Kafka Connectors: Ignore column type mismatch in UpdateSnowflakeDatabase for Kafka connectors is more resilient in case of issue with schema inference. - Google Drive & SharePoint Connectors: Improves the flow to avoid a race condition where group synchronization kicks off but PERMS_GROUPS has not been created yet - Kafka Connectors: Warehouse is no longer needed. The corresponding parameter is removed. ### Runtime Extensions 2025.6.26.16 - Tables without primary keys are retried instead of failed. - New Alter Strategy in UpdateSnowflakeDatabase processor has the option to ignore column type changes. - Fixes fetching of HubSpot archived records. ## June 24, 2025 ### Control Plane Core 0.50.0 - New deployments send status updates to Openflow Control Plane indicating when upgrades are present. - The PrPr tag is included on some new connectors. ### Control Plane UI 0.42.0 - New deployments now surface when an upgrade is available, with a link to documentation. Earlier deployments can also use this functionality after a migration to a newer version. ### Data Plane Service 0.50.0 - Fixes Create runtime failures where the minimum node count is greater than one. ### Data Plane UI 0.7.0 - Active role now displays in the current user menu. ## June 20, 2025 ### AWS Data Plane Agent 0.21.0 - Deployments created with AWS Data Plane Agent 0.20.0 are no longer prevented from adopting future updates to EC2 Agent Host scripts. ## June 18, 2025 ### AWS Data Plane Agent 0.19.0 - Supports tagging all AWS resources created and managed by Openflow. Enables deployments governed by security controls like AWS SCP and cost controls like AWS MAP. ### AWS Data Plane Agent 0.20.0 - New Openflow BYOC deployments and upgrades of existing deployments are no longer blocked by an "Unsupported block type" error. ### Connectors 2025.6.17.15 - JIRA: Multi-projects support flattened views in Snowflake destination. ### Runtime Server 2025.6.17.16 - Process Group metrics are now visible when using the Stateless engine. - The toolbar renders properly when font size is scaled in the browser settings. - The UnpackContent shows the TAR option again. ## June 12, 2025 ### Connectors 2025.6.12.19 - Google Sheets: Improves failure handling by retrying when ingesting data into Snowflake. - Workday: Uses TRUNCATE instead of REPLACE when possible on the destination table. - Sharepoint / Google Drive: Improves failure handling with proper retry / logging in case of failures. - SQL Server: Prevents stream staleness. - Box: Properly reflects permissions when groups are removed from files permissions in Box. - Google Drive (Simple Ingest) - Fixes handling of files being deleted. - Workday: Fixes clustering configuration to have the first processor run on the primary node only. ### Control Plane UI 0.41.0 - Skeleton loaders are now shown in the deployment and runtime listings when permissions are evaluated. - Skeleton loaders are now shown in **Create Runtime** and **Add Connector to Runtime** dialogs while options are loaded and permissions are evaluated. ### Runtime Extensions 2025.6.12.21 - Adds the possibility to specify multiple projects to fetch JIRA issues when using 'Simple Search'. - Improves handling of all fields in the JIRA connector. Improves mapping into destination table by using an individual column per field. - Adds support for the PuPr of Snowflake Structured Maps/Arrays/Objects. - Google Sheets connector now supports Boolean and numbers to be used in the same column. - MySQL: Properly handles a changes in the column filtering parameter during replication. - MySQL: Fixes potential connection leakage when being disconnected from the binlog. - SQL Server: Fixes column ordering handling in the Journal Log table. ### Runtime Server 2025.6.12.21 - Error reporting now shows in banners instead of toast notifications. - Adds support for different ranges in the Status History dialog by selecting different start timestamps. - Introduces a Process Group column to the Parameter Context table to more efficiently see bound Process Groups. ## June 8, 2025 ### Runtime Extensions 2025.6.6.16 - Upgrades Snowflake JDBC Driver to 3.24.2 - Resolves an issue that prevented newer runtimes from installing the latest Microsoft Dataverse Connector. - Removes Microsoft SQL Server replication of logical databases. ### Runtime Gateway 2025.6.8.2 - Adds support for logging in to Openflow runtimes using role names with dashes. ### Runtime Server 2025.6.6.19 - Adds pre-configured version control support for custom flows. - Gracefully shuts down processors and controller services for stateless process groups. ## May 31, 2025 ### Runtime Extensions 2025.5.31.15 - Add kafka.max.offset attribute to Records produced by ConsumeKafka --- title: SnowflakeConnectionService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/snowflakeconnectionservice.md section: Loading & Unloading Data --- # SnowflakeConnectionService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides pooled database connections to Snowflake services ## Tags connection, database, jdbc, openflow, snowflake ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: SnowflakeDatabaseDialectService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/snowflakedatabasedialectservice.md section: Loading & Unloading Data --- # SnowflakeDatabaseDialectService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Database Dialect Service supporting Snowflake. Supported Statement Types: ALTER, CREATE, SELECT, UPSERT (MERGE INTO) ## Tags Database, JDBC, Relational, SQL ## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: SnowflakeDetectDuplicate 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/snowflakedetectduplicate.md section: Loading & Unloading Data --- # SnowflakeDetectDuplicate 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-snowflake-processors-nar ## Description Checks if a FlowFile 's hash (provided as a FlowFile attribute) is already in a Snowflake table, and routes the FlowFile to' duplicate 'if found,'distinct 'if not found, or' failure' on errors. ## Tags database, detect, duplicates, hash, snowflake ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: SnowflakeSignJWTService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/snowflakesignjwtservice.md section: Loading & Unloading Data --- # SnowflakeSignJWTService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides OAuth2 access token using a JWT signed with a secret stored in Snowflake. The JWT is signed using the SYSTEM$SIGN_JWT_USING_SECRET function, which requires a valid Snowflake connection. ## Tags jwt, preview, snowflake ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: SnowflakeTableSchemaRegistry source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/snowflaketableschemaregistry.md section: Loading & Unloading Data --- # SnowflakeTableSchemaRegistry This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Uses Snowflake tables as the source of schema — utilises Snowpipe Streaming REST API. Requires a fully qualified table name as the schema name. ## Tags openflow, registry, schema, snowflake ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: SplitAvro 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/splitavro.md section: Loading & Unloading Data --- # SplitAvro 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-avro-nar ## Description Splits a binary encoded Avro datafile into smaller files based on the configured Output Size. The Output Strategy determines if the smaller files will be Avro datafiles, or bare Avro records with metadata in the FlowFile attributes. The output will always be binary encoded. ## Tags avro, split ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: SplitContent 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/splitcontent.md section: Loading & Unloading Data --- # SplitContent 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Splits incoming FlowFiles by a specified byte sequence ## Tags binary, content, split ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.standard.MergeContent](/user-guide/data-integration/openflow/processors/mergecontent) --- title: SplitExcel 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/splitexcel.md section: Loading & Unloading Data --- # SplitExcel 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-poi-nar ## Description This processor splits a multi sheet Microsoft Excel spreadsheet into multiple Microsoft Excel spreadsheets where each sheet from the original file is converted to an individual spreadsheet in its own flow file. Currently this processor is only capable of processing .xlsx (XSSF 2007 OOXML file format) Excel documents and not older .xls (HSSF '97(-2007) file format) documents. Please note all original cell styles are dropped and formulas are removed leaving only the calculated values. Even a single sheet Microsoft Excel spreadsheet is converted to its own flow file with all the original cell styles dropped and formulas removed. ## Tags split, text ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: SplitJson 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/splitjson.md section: Loading & Unloading Data --- # SplitJson 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Splits a JSON File into multiple, separate FlowFiles for an array element specified by a JsonPath expression. Each generated FlowFile is comprised of an element of the specified array and transferred to relationship 'split,' with the original file transferred to the 'original' relationship. If the specified JsonPath is not found or does not evaluate to an array element, the original file is routed to 'failure' and no files are generated. ## Tags json, jsonpath, split ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: SplitRecord 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/splitrecord.md section: Loading & Unloading Data --- # SplitRecord 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Splits up an input FlowFile that is in a record-oriented data format into multiple smaller FlowFiles ## Tags avro, csv, freeform, generic, json, log, logs, schema, split, text ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: SplitText 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/splittext.md section: Loading & Unloading Data --- # SplitText 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Splits a text file into multiple smaller text files on line boundaries limited by maximum number of lines or total size of fragment. Each output split file will contain no more than the configured number of lines or bytes. If both Line Split Count and Maximum Fragment Size are specified, the split occurs at whichever limit is reached first. If the first line of a fragment exceeds the Maximum Fragment Size, that line will be output in a single split file which exceeds the configured maximum size limit. This component also allows one to specify that each split should include a header lines. Header lines can be computed by either specifying the amount of lines that should constitute a header or by using header marker to match against the read lines. If such match happens then the corresponding line will be treated as header. Keep in mind that upon the first failure of header marker match, no more matches will be performed and the rest of the data will be parsed as regular lines for a given split. If after computation of the header there are no more data, the resulting split will consists of only header lines. ## Tags split, text ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.standard.MergeContent](/user-guide/data-integration/openflow/processors/mergecontent) --- title: SplitXml 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/splitxml.md section: Loading & Unloading Data --- # SplitXml 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Splits an XML File into multiple separate FlowFiles, each comprising a child or descendant of the original root element ## Tags split, xml ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: StandardAnthropicLLMService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/standardanthropicllmservice.md section: Loading & Unloading Data --- # StandardAnthropicLLMService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description A Controller Service that provides integration with Anthropic's Claude AI models through their Messages API. Supports configurable parameters including model selection, response generation settings (temperature, top_p, top_k), token limits, and retry behavior. ## Tags ai, anthropic, api, claude, language model, llm, openflow ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: StandardAtlassianRequestRateManager source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/standardatlassianrequestratemanager.md section: Loading & Unloading Data --- # StandardAtlassianRequestRateManager This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides rate limiting coordination for Atlassian API calls across processors to prevent cascading rate limit issues. Throttles when limit is reached (HTTP 429). ## Tags api, atlassian, confluence, jira, limit, openflow, rate ## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: StandardAzureCredentialsControllerService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/standardazurecredentialscontrollerservice.md section: Loading & Unloading Data --- # StandardAzureCredentialsControllerService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provide credentials to use with an Azure client. ## Tags azure, credentials, provider, security, session ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: StandardConfluenceClientService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/standardconfluenceclientservice.md section: Loading & Unloading Data --- # StandardConfluenceClientService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides connection service to Confluence APIs ## Tags Preview, atlassian, confluence ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: StandardDatabricksWorkspaceClientService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/standarddatabricksworkspaceclientservice.md section: Loading & Unloading Data --- # StandardDatabricksWorkspaceClientService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Databricks client. ## Tags databricks, openflow ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: StandardDropboxCredentialService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/standarddropboxcredentialservice.md section: Loading & Unloading Data --- # StandardDropboxCredentialService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Defines credentials for Dropbox processors. ## Tags credentials, dropbox, provider ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: StandardFileResourceService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/standardfileresourceservice.md section: Loading & Unloading Data --- # StandardFileResourceService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides a file resource for other components. The file needs to be available locally by Nifi (e.g. local disk or mounted storage). NiFi needs to have read permission to the file. ## Tags file, resource ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted ## Restrictions
## System Resource Considerations This component does not specify system resource considerations. --- title: StandardHashiCorpVaultClientService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/standardhashicorpvaultclientservice.md section: Loading & Unloading Data --- # StandardHashiCorpVaultClientService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description A controller service for interacting with HashiCorp Vault. ## Tags client, hashicorp, vault ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: StandardHttpContextMap source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/standardhttpcontextmap.md section: Loading & Unloading Data --- # StandardHttpContextMap This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides the ability to store and retrieve HTTP requests and responses external to a Processor, so that multiple Processors can interact with the same HTTP request. ## Tags http, request, response ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: StandardHubSpotClientService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/standardhubspotclientservice.md section: Loading & Unloading Data --- # StandardHubSpotClientService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description HubSpot Controller Service to integrate with HubSpot HTTP api. ## Tags Preview, hubSpot ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: StandardJsonSchemaRegistry source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/standardjsonschemaregistry.md section: Loading & Unloading Data --- # StandardJsonSchemaRegistry This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides a service for registering and accessing JSON schemas. One can register a schema as a dynamic property where 'name' represents the schema name and 'value' represents the textual representation of the actual schema following the syntax and semantics of the JSON Schema format. Empty schemas and schemas only consisting of whitespace are not acceptable schemas. The registry is heterogeneous registry as it can store schemas of different schema draft versions. By default the registry is configured to store schemas of Draft 2020-12. When a schema is added, the version which is currently is set, is what the schema is saved as. ## Tags json, registry, schema ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: StandardKustoIngestService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/standardkustoingestservice.md section: Loading & Unloading Data --- # StandardKustoIngestService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Sends batches of flowfile content or stream flowfile content to an Azure ADX cluster. ## Tags ADX, Azure, Data, Explorer, Kusto, azure, ingest ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: StandardKustoQueryService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/standardkustoqueryservice.md section: Loading & Unloading Data --- # StandardKustoQueryService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Standard implementation of Kusto Query Service for Azure Data Explorer ## Tags ADX, Azure, Data, Explorer, Kusto ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: StandardMilvusConnectionService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/standardmilvusconnectionservice.md section: Loading & Unloading Data --- # StandardMilvusConnectionService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides connection service to a Milvus instance ## Tags connection, database, milvus, openflow, vector ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: StandardOauth2AccessTokenProvider source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/standardoauth2accesstokenprovider.md section: Loading & Unloading Data --- # StandardOauth2AccessTokenProvider This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides OAuth 2.0 access tokens that can be used as Bearer authorization header in HTTP requests. Can use either Resource Owner Password Credentials Grant or Client Credentials Grant. Client authentication can be done with either HTTP Basic authentication or in the request body. ## Tags access token, authorization, http, oauth2, provider ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: StandardOCRService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/standardocrservice.md section: Loading & Unloading Data --- # StandardOCRService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides integration to Openflow OCR Service ## Tags extract, image, ocr, openflow, tesseract, text ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: StandardOpenAILLMService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/standardopenaillmservice.md section: Loading & Unloading Data --- # StandardOpenAILLMService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description A Controller Service that provides integration with OpenAI's Chat Completion API. Supports configurable parameters including model selection, temperature, top_p, max tokens, and retry behavior. Handles API authentication, request retries with exponential backoff, and error handling. ## Tags ai, chat completion, chatgpt, large language model, llm, openai, openflow ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: StandardPGPPrivateKeyService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/standardpgpprivatekeyservice.md section: Loading & Unloading Data --- # StandardPGPPrivateKeyService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description PGP Private Key Service provides Private Keys loaded from files or properties ## Tags Encryption, GPG, Key, OpenPGP, PGP, Private, RFC 4880 ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: StandardPGPPublicKeyService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/standardpgppublickeyservice.md section: Loading & Unloading Data --- # StandardPGPPublicKeyService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description PGP Public Key Service providing Public Keys loaded from files ## Tags Encryption, GPG, Key, OpenPGP, PGP, Private, RFC 4880 ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: StandardPrivateKeyService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/standardprivatekeyservice.md section: Loading & Unloading Data --- # StandardPrivateKeyService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Private Key Service provides access to a Private Key loaded from configured sources ## Tags PEM, PKCS8 ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: StandardProtobufReader source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/standardprotobufreader.md section: Loading & Unloading Data --- # StandardProtobufReader This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Parses Protocol Buffers messages from binary format into NiFi Records. Supports multiple schema access strategies including inline schema text, schema registry lookup, and schema reference readers. Protobuf reader needs to know the Proto schema message name in order to deserialize the binary payload correctly. The name of this message can be determined statically using 'Message Name' property, or dynamically, using a Message Name Resolver service. ## Tags parser, protobuf, reader, record ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: StandardProxyConfigurationService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/standardproxyconfigurationservice.md section: Loading & Unloading Data --- # StandardProxyConfigurationService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides a set of configurations for different NiFi components to use a proxy server. ## Tags Proxy ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: StandardRestrictedSSLContextService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/standardrestrictedsslcontextservice.md section: Loading & Unloading Data --- # StandardRestrictedSSLContextService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Restricted implementation of the SSLContextService. Provides the ability to configure keystore and/or truststore properties once and reuse that configuration throughout the application, but only allows a restricted set of TLS/SSL protocols to be chosen (no SSL protocols are supported). The set of protocols selectable will evolve over time as new protocols emerge and older protocols are deprecated. This service is recommended over StandardSSLContextService if a component doesn't expect to communicate with legacy systems since it is unlikely that legacy systems will support these protocols. ## Tags certificate, jks, keystore, p12, pkcs, pkcs12, secure, ssl, tls, truststore ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: StandardS3EncryptionService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/standards3encryptionservice.md section: Loading & Unloading Data --- # StandardS3EncryptionService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Adds configurable encryption to S3 Put and S3 Fetch operations. ## Tags aws, decrypt, decryption, encrypt, encryption, key, s3, service ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: StandardSalesforceBulkJobsStateService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/standardsalesforcebulkjobsstateservice.md section: Loading & Unloading Data --- # StandardSalesforceBulkJobsStateService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Stores Salesforce Bulk Jobs state per object type at cluster scope ## Tags bulk, preview, salesforce, state ## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: StandardSalesforceClientService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/standardsalesforceclientservice.md section: Loading & Unloading Data --- # StandardSalesforceClientService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides connection service to Salesforce APIs ## Tags preview, salesforce ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: StandardSalesforceDataCloudClientService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/standardsalesforcedatacloudclientservice.md section: Loading & Unloading Data --- # StandardSalesforceDataCloudClientService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides connection service to Salesforce Data Cloud APIs ## Tags daas, data cloud, preview, salesforce ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: StandardSlackRateLimiterService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/standardslackratelimiterservice.md section: Loading & Unloading Data --- # StandardSlackRateLimiterService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides rate limiting coordination for Slack API calls across processors to prevent cascading rate limit issues ## Tags api, limit, openflow, rate, slack ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: StandardSSLContextService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/standardsslcontextservice.md section: Loading & Unloading Data --- # StandardSSLContextService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Standard implementation of the SSLContextService. Provides the ability to configure keystore and/or truststore properties once and reuse that configuration throughout the application. This service can be used to communicate with both legacy and modern systems. If you only need to communicate with non-legacy systems, then the StandardRestrictedSSLContextService is recommended as it only allows a specific set of SSL protocols to be chosen. ## Tags certificate, jks, keystore, p12, pkcs, pkcs12, secure, ssl, tls, truststore ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: StandardTableStateService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/standardtablestateservice.md section: Loading & Unloading Data --- # StandardTableStateService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description A controller Service that provides and manages table state. The state is cached and refreshed only when one of set table state method is invoked. This caching method requires that getting or setting state for a given table must be done on the same node. The Tables processing can be partitioned between NiFi nodes, but the get and set state operations for a single table must be associated with a single NiFi node. ## Tags ## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: StandardVectaraClientService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/standardvectaraclientservice.md section: Loading & Unloading Data --- # StandardVectaraClientService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Vectara Controller Service to integrate with Vectara HTTP Api. ## Tags ai, llm, openflow, rag, vectara ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: StandardWebClientServiceProvider source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/standardwebclientserviceprovider.md section: Loading & Unloading Data --- # StandardWebClientServiceProvider This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Web Client Service Provider with support for configuring standard HTTP connection properties ## Tags Client, HTTP, Web ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: StartAwsPollyJob 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/startawspollyjob.md section: Loading & Unloading Data --- # StartAwsPollyJob 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-aws-nar ## Description Trigger a AWS Polly job. It should be followed by GetAwsPollyJobStatus processor in order to monitor job status. ## Tags AWS, Amazon, ML, Machine Learning, Polly ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.aws.ml.polly.GetAwsPollyJobStatus](/user-guide/data-integration/openflow/processors/getawspollyjobstatus) --- title: StartAwsTextractJob 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/startawstextractjob.md section: Loading & Unloading Data --- # StartAwsTextractJob 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-aws-nar ## Description Trigger an AWS Textract job. It should be followed by GetAwsTextractJobStatus processor in order to monitor job status. ## Tags AWS, Amazon, ML, Machine Learning, Textract ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.aws.ml.textract.GetAwsTextractJobStatus](/user-guide/data-integration/openflow/processors/getawstextractjobstatus) --- title: StartAwsTranscribeJob 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/startawstranscribejob.md section: Loading & Unloading Data --- # StartAwsTranscribeJob 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-aws-nar ## Description Trigger a AWS Transcribe job. It should be followed by GetAwsTranscribeStatus processor in order to monitor job status. ## Tags AWS, Amazon, ML, Machine Learning, Transcribe ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.aws.ml.transcribe.GetAwsTranscribeJobStatus](/user-guide/data-integration/openflow/processors/getawstranscribejobstatus) --- title: StartAwsTranslateJob 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/startawstranslatejob.md section: Loading & Unloading Data --- # StartAwsTranslateJob 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-aws-nar ## Description Trigger a AWS Translate job. It should be followed by GetAwsTranslateJobStatus processor in order to monitor job status. ## Tags AWS, Amazon, ML, Machine Learning, Translate ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.aws.ml.translate.GetAwsTranslateJobStatus](/user-guide/data-integration/openflow/processors/getawstranslatejobstatus) --- title: StartGcpVisionAnnotateFilesOperation 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/startgcpvisionannotatefilesoperation.md section: Loading & Unloading Data --- # StartGcpVisionAnnotateFilesOperation 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-gcp-nar ## Description Trigger a Vision operation on file input. It should be followed by GetGcpVisionAnnotateFilesOperationStatus processor in order to monitor operation status. ## Tags Cloud, Google, Machine Learning, Vision ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.gcp.vision.GetGcpVisionAnnotateFilesOperationStatus](/user-guide/data-integration/openflow/processors/getgcpvisionannotatefilesoperationstatus) --- title: StartGcpVisionAnnotateImagesOperation 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/startgcpvisionannotateimagesoperation.md section: Loading & Unloading Data --- # StartGcpVisionAnnotateImagesOperation 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-gcp-nar ## Description Trigger a Vision operation on image input. It should be followed by GetGcpVisionAnnotateImagesOperationStatus processor in order to monitor operation status. ## Tags Cloud, Google, Machine Learning, Vision ## Input Requirement ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.gcp.vision.GetGcpVisionAnnotateImagesOperationStatus](/user-guide/data-integration/openflow/processors/getgcpvisionannotateimagesoperationstatus) --- title: StateManagedCdcSchemaRegistry source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/statemanagedcdcschemaregistry.md section: Loading & Unloading Data --- # StateManagedCdcSchemaRegistry This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Uses the in-built NiFi State Management to store the hashes of table schemas. This allows for a relatively high performance, low latency, low memory utilization mechanism for storing and comparing table schemas with no external dependencies. ## Tags CDC, Database, Schema, Snowflake ## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: SubmitQueryJob 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/submitqueryjob.md section: Loading & Unloading Data --- # SubmitQueryJob 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-salesforce-processors-nar ## Description Submits a Query Job to Salesforce using the Bulk API 2.0. In SIMPLE mode, per-object state (previousLast/currentLast and status) is stored in the configured controller service. In ADVANCED mode, a single 'last' timestamp is stored at processor scope to support incremental queries across objects. ## Tags bulk, job, preview, query, salesforce ## Input Requirement ALLOWED ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
## Use cases | Submits a Query Job to Salesforce using the Bulk API 2.0. | | --------------------------------------------------------- | ## See also - [com.snowflake.openflow.runtime.processors.salesforce.AbortQueryJob](/user-guide/data-integration/openflow/processors/abortqueryjob) - [com.snowflake.openflow.runtime.processors.salesforce.DeleteQueryJob](/user-guide/data-integration/openflow/processors/deletequeryjob) - [com.snowflake.openflow.runtime.processors.salesforce.GetQueryJobResult](/user-guide/data-integration/openflow/processors/getqueryjobresult) - [com.snowflake.openflow.runtime.processors.salesforce.GetQueryJobStatus](/user-guide/data-integration/openflow/processors/getqueryjobstatus) --- title: SummarizeText 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/summarizetext.md section: Loading & Unloading Data --- # SummarizeText 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-llm-processors-nar ## Description This processor uses a Large Language Model (LLM) to summarize the content of a FlowFile. It sends the content to an LLM service and writes the summary back to the FlowFile or as an attribute. ## Tags ai, llm, openflow, summarization, text processing ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: Syslog5424Reader source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/syslog5424reader.md section: Loading & Unloading Data --- # Syslog5424Reader This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides a mechanism for reading RFC 5424 compliant Syslog data, such as log files, and structuring the data so that it can be processed. ## Tags logfiles, logs, parse, reader, record, syslog, syslog 5424, text ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: SyslogReader source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/syslogreader.md section: Loading & Unloading Data --- # SyslogReader This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Attempts to parses the contents of a Syslog message in accordance to RFC5424 and RFC3164. In the case of RFC5424 formatted messages, structured data is not supported, and will be returned as part of the message. Note: Be mindful that RFC3164 is informational and a wide range of different implementations are present in the wild. ## Tags logfiles, logs, parse, reader, record, syslog, text ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: TagS3Object 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/tags3object.md section: Loading & Unloading Data --- # TagS3Object 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-aws-nar ## Description Adds or updates a tag on an Amazon S3 Object. ## Tags AWS, Amazon, Archive, S3, Tag ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.aws.s3.CopyS3Object](/user-guide/data-integration/openflow/processors/copys3object) - [org.apache.nifi.processors.aws.s3.DeleteS3Object](/user-guide/data-integration/openflow/processors/deletes3object) - [org.apache.nifi.processors.aws.s3.FetchS3Object](/user-guide/data-integration/openflow/processors/fetchs3object) - [org.apache.nifi.processors.aws.s3.GetS3ObjectMetadata](/user-guide/data-integration/openflow/processors/gets3objectmetadata) - [org.apache.nifi.processors.aws.s3.GetS3ObjectTags](/user-guide/data-integration/openflow/processors/gets3objecttags) - [org.apache.nifi.processors.aws.s3.ListS3](/user-guide/data-integration/openflow/processors/lists3) - [org.apache.nifi.processors.aws.s3.PutS3Object](/user-guide/data-integration/openflow/processors/puts3object) --- title: TailFile 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/tailfile.md section: Loading & Unloading Data --- # TailFile 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description "Tails" a file, or a list of files, ingesting data from the file as it is written to the file. The file is expected to be textual. Data is ingested only when a new line is encountered (carriage return or new-line character or combination). If the file to tail is periodically "rolled over", as is generally the case with log files, an optional Rolling Filename Pattern can be used to retrieve data from files that have rolled over, even if the rollover occurred while NiFi was not running (provided that the data still exists upon restart of NiFi). It is generally advisable to set the Run Schedule to a few seconds, rather than running with the default value of 0 secs, as this Processor will consume a lot of resources if scheduled very aggressively. At this time, this Processor does not support ingesting files that have been compressed when 'rolled over'. ## Tags file, log, source, tail, text ## Input Requirement FORBIDDEN ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Restrictions
## Relationships
## Writes attributes
--- title: TransformXml 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/transformxml.md section: Loading & Unloading Data --- # TransformXml 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Applies the provided XSLT file to the FlowFile XML payload. A new FlowFile is created with transformed content and is routed to the 'success' relationship. If the XSL transform fails, the original FlowFile is routed to the 'failure' relationship ## Tags transform, xml, xslt ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: Troubleshoot Openflow source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/troubleshoot.md section: Loading & Unloading Data --- # Troubleshoot Openflow This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions). - [About Openflow](/user-guide/data-integration/openflow/about) - [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) - [Openflow BYOC - Set up custom ingress](/user-guide/data-integration/openflow/setup-openflow-byoc-custom-ingress) - [Monitor Openflow using telemetry data](/user-guide/data-integration/openflow/monitor) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) This topic describes the steps to troubleshoot the Openflow components. ## Openflow BYOC troubleshooting ### BYOC custom ingress troubleshooting For help with BYOC custom ingress, see [Custom ingress troubleshooting](#label-openflow-byoc-custom-ingress-troubleshooting). ### General BYOC troubleshooting If any part of a deployment, connector, or runtime is causing problems, you can use a built-in tool to generate a diagnostic bundle. This bundle includes the information necessary to keep your Openflow BYOC deployment secure while allowing the [Snowflake Support](https://docs.snowflake.cn/user-guide/contacting-support) team to troubleshoot the issue. To share the diagnostic bundle with [Snowflake Support](https://docs.snowflake.cn/user-guide/contacting-support), attach it to your support case. 1. From the AWS Console UI for EC2, right-click on the **openflow-agent-\{deployment-key\}** instance with your Deployment Key. 2. In the context menu, click the **Connect** button. 3. Switch from **EC2 Instance Connect** to **Connect using EC2 Instance Connect Endpoint**. Leave the default **EC2 Instance Connect Endpoint** in place. 4. Click the **Connect** button. A new browser tab or window will appear with a command-line interface. 5. Run `./diagnostics.sh` from this browser-based CLI. Follow a few simple prompts to confirm that you want to create the bundle, and then optionally create a shareable link. The diagnostic utility will upload the file to an S3 bucket created for the Deployment using the Deployment Key. For example, `s3china://byoc-tf-state-{deployment-key}/diagnostics/openflow_20250131123456.tar.gz` With the pre-signed URL, you can safely share temporary access to the diagnostic bundle with the Snowflake team for up to 1 hour. Your S3 bucket and all of its contents remain private. --- title: Troubleshoot the Openflow Connector for Shopify source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/shopify/troubleshoot.md section: Loading & Unloading Data --- # Troubleshoot the %shopifyof% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About the Openflow Connector for Shopify](/user-guide/data-integration/openflow/connectors/shopify/about) - [Set up the Openflow Connector for Shopify](/user-guide/data-integration/openflow/connectors/shopify/setup) - [Object definition overrides for the Openflow Connector for Shopify](/user-guide/data-integration/openflow/connectors/shopify/object-definitions) - [Maintain the Openflow Connector for Shopify](/user-guide/data-integration/openflow/connectors/shopify/maintain) This topic describes how to troubleshoot the %shopifyof%. ## A table never appears or is empty 1. Confirm the `apiType` is listed in the **Objects to Sync** parameter and spelled correctly (matching is case-insensitive, but the value must correspond to a query root in the Shopify Admin GraphQL API). 2. Confirm the Shopify dev app has the matching read scope for that object type. For example, `orders` requires `read_orders`. A missing scope produces access errors or empty results for that object type only, without affecting other objects. 3. If you're using a custom object definition, confirm the **Object Definitions Override** value is valid JSON and a top-level array. Then re-enable the controller services. 4. If you're relying on auto-discovery, confirm **Enable Introspection** is set to `true`. ## Connector fails with `UnknownHostException` on OAuth2 token request If the connector logs an error such as `OAuth2 access token request failed` caused by `java.net.UnknownHostException: .myshopify.com`, the runtime can't reach the Shopify domain. This means the External Access Integration (EAI) for the connector hasn't been created, or USAGE on the EAI hasn't been granted to the runtime's execute-as role. Follow the steps in [](/user-guide/data-integration/openflow/connectors/shopify/setup#label-create-network-rule) to create the network rule and EAI, and grant the execute-as role USAGE on the integration. ## Connector fails with `UnresolvedAddressException` when downloading bulk results If the connector logs a `WebClientServiceException` with `java.net.ConnectException` or `java.nio.channels.UnresolvedAddressException` when accessing a `storage.googleapis.com` URL, the EAI network rule is missing `storage.googleapis.com:443` in its `VALUE_LIST`. After a bulk operation completes, Shopify returns a signed Google Cloud Storage URL for the result file, and the connector must be able to reach that host to download it. Update the network rule to include both required endpoints: ```sql title="Syntax" CREATE OR REPLACE NETWORK RULE openflow__shopify_network_rule TYPE = HOST_PORT MODE = EGRESS VALUE_LIST = ( '.myshopify.com:443', 'storage.googleapis.com:443' ); ``` ## Connector fails with HTTP 401 Unauthorized If the connector receives an HTTP 401 response with the error `[API] Invalid API key or access token (unrecognized login or wrong password)`, the OAuth2 access token is invalid or has been revoked. Check the following: 1. Confirm the **Shopify Client ID** and **Shopify Client Secret** parameters match the credentials in your app's **Settings** %ra% **Credentials** in the Dev Dashboard. 2. Confirm the app is installed on the store. If the app was uninstalled at any point, the existing token is revoked. Reinstall the app if needed, then restart the connector to obtain a new token. 3. Confirm the app has been released. Unreleased apps can't authenticate. ## A query fails with `ACCESS_DENIED` on an object type The connector can receive a GraphQL `ACCESS_DENIED` error on an object type for two reasons: - **Missing scope:** The error message is `Access denied for field.` The app doesn't have the required read scope. Add the corresponding scope in the Dev Dashboard (for example, `read_orders` for `orders`), release the updated app version, and reinstall the app on your store. - **Protected customer data not approved:** The error message is `This app is not approved to access the object.` The object requires Shopify's protected customer data approval. Submit an access request through your app's **API access** settings in the Dev Dashboard. For more information, see Protected customer data (https://shopify.dev/docs/apps/launch/protected-customer-data) in the Shopify developer documentation. If the error occurs on a single field rather than the entire object type, see [A query fails with an access-denied error on one field](#label-shopify-access-denied-one-field). ## A query fails with an access-denied error on one field Some Shopify Admin GraphQL fields require a write scope to be read. For example, the customer marketing URL fields (`marketingUnsubscribeUrl`, `openTrackingUrl`) require `write_customers`. When the app lacks the required scope, the Shopify API returns an error for that field and the entire object's query fails. The fix is to remove the field from the query rather than grant a write scope. Note that `ignoredFields` matches only the leading name of top-level entries and doesn't apply to nested sub-selections: - **Top-level field** (a direct entry in `graphqlFields`): remove it from `graphqlFields`, or add its name to `ignoredFields`. - **Nested field** (inside a sub-selection, for example `marketingUnsubscribeUrl` inside `defaultEmailAddress { ... }`): edit the parent entry's sub-selection in `graphqlFields` to remove the offending field. Supply the corrected definition through the **Object Definitions Override** parameter. For more information, see [Object definition overrides for the Openflow Connector for Shopify](/user-guide/data-integration/openflow/connectors/shopify/object-definitions). ## Orders are missing older history (only approximately 60 days present) The `read_orders` scope limits access to orders created in the last 60 days by default. To backfill the full order history, your Shopify app must also be granted `read_all_orders`. This scope requires an access request through your app's **API access** settings in the Dev Dashboard. After granting `read_all_orders`, [reset the `orders` object state](/user-guide/data-integration/openflow/connectors/shopify/maintain#label-reload-a-specific-object) so the bulk load reruns and captures the full history. ## Connector won't start or Object Registry service is INVALID This is almost always caused by an invalid **Object Definitions Override** value. The value must be syntactically valid JSON and a top-level array. An invalid value or a non-array value prevents the `StandardShopifyObjectRegistryService` from enabling, and the connector fails to start. To diagnose: 1. Open the **Controller Services** panel and select the `StandardShopifyObjectRegistryService`. 2. Check the service bulletin for the parse error, such as "Invalid JSON" or "Must be a JSON array of object definitions". 3. Fix the JSON, re-apply the parameter, and re-enable the service. You can validate the JSON before applying it: ```bash python3 -c "import json, sys; d = json.load(open('override.json')); sys.exit(0 if isinstance(d, list) else 1)" ``` ## Bulk operation fails immediately The following scenarios can cause a bulk operation to fail immediately or stall. ### Wrong sort key An unsupported value in `sortKeys` fails the entire bulk operation. Remove the sort key from the object definition or correct it. Omitting `sortKeys` is always safe. ### Bulk operation already in progress Shopify allows only one bulk operation per shop at a time. The processor retries automatically on the next cycle. If the in-flight operation never clears, another integration on the same shop may be holding the bulk slot. ### Too many or too deeply nested connections The Shopify Bulk Operations API allows a maximum of 5 connections per query and 2 levels of nesting. If **Include Metafields** is enabled, it consumes one connection. Reduce or flatten child connections to stay within these limits. ### Bulk operation stuck with no progress Very large datasets can take significant time to complete. If a bulk operation shows no progress after an extended period, it may be stalled. Check the Shopify admin for the status of the bulk operation, or [reset the affected object](/user-guide/data-integration/openflow/connectors/shopify/maintain#label-reload-a-specific-object) to resubmit. ## Duplicate or missing records in Snowflake **Duplicates immediately after the initial load** are expected during the bulk-to-incremental handoff. The merge uses the compound key `(ID, SHOP_URL)`, so the target table converges after the first incremental run. No action is required. **Records missing or not updating:** The incremental watermark may have advanced past the affected records. Inspect the per-object state to check the high watermark. If the watermark is incorrect, [reset the object](/user-guide/data-integration/openflow/connectors/shopify/maintain#label-reload-a-specific-object) to rerun the bulk load. For `orders` specifically, also confirm that the 60-day order history window isn't the cause. For more information, see [Orders are missing older history](#label-shopify-orders-history). ## Incremental processor routes to retry or failure on first run The `GetShopifyIncremental` processor routes to retry or failure until the one-time bulk load for each object type completes. This is expected behavior on the first run. Let the bulk load finish before investigating further. ## Incremental fails with "Invalid search field: \" This error appears in the `GetShopifyIncremental` bulletin when the object's `incrementalField` exists on the returned type but isn't accepted as a filter by the query root's `query:` argument. Fix: in the object's **Object Definitions Override** entry, set `supportsIncremental` to `false` and `refreshStrategy` to `FULL_PERIODIC`. The object will perform a bulk load once and won't poll incrementally. To refresh it, reset the object state. Common objects affected: `codeDiscountNodes`, `automaticDiscountNodes`. For discount syncing with incremental support, use the `discountNodes` query root instead. After editing the override JSON, re-enable the `StandardShopifyObjectRegistryService`. ## Schema changed in Shopify Schema evolution isn't supported. If a Shopify object's fields change (fields added or removed), [reset the connector state for the affected object](/user-guide/data-integration/openflow/connectors/shopify/maintain#label-reload-a-specific-object) and drop the corresponding Snowflake table to re-snapshot with the updated schema. ## Deletes aren't appearing in Snowflake Check the following in order: 1. The object type must support delete detection. Only object types that emit destroy events in the Shopify Events API can be tracked. For more information, see [How deletes are handled](/user-guide/data-integration/openflow/connectors/shopify/about#label-shopify-how-deletes-are-handled). 2. The object type must be listed in the **Objects to Track for Deletes** parameter. 3. The initial bulk load for that object type must be complete before delete polling begins. 4. Delete events younger than the safety buffer (default 5 minutes) are intentionally deferred. 5. Delete polling yields when API credits fall below the rate limit threshold (default 500 points). Check the processor bulletin for messages indicating the connector is below the rate limit threshold and yielding. ## Error: "first cannot exceed 250" This error occurs when a regular (incremental) query sets `first:` above Shopify's hard limit of 250. The full error is: *"first cannot exceed 250. To query larger amounts of data with fewer limits, bulk operations should be used instead."* Check the **Page Size** parameter and the `pageSize` value in any `childFields` definitions in the **Object Definitions Override**. Both must be 250 or lower. Note that this limit doesn't apply to the initial bulk load: the Shopify Bulk Operations API ignores the `first:` argument and returns all records. For parent objects with more children than the `pageSize` value, only the initial bulk load captures the full child set; incremental runs are capped at `pageSize` per parent. ## Sustained throttling High-volume stores with many objects can remain rate-limited for extended periods. To reduce API usage: - Increase the **Sync Schedule** and **Deletes Schedule** intervals. - Reduce the number of entries in **Objects to Sync**. - Disable **Include Metafields** if metafield data isn't required. ## StandardPrivateKeyService shows INVALID on SPCS or SNOWFLAKE_MANAGED deployments The `StandardPrivateKeyService` controller is only used for BYOC deployments with `KEY_PAIR` authentication. On SPCS deployments, and on BYOC deployments using `SNOWFLAKE_MANAGED` authentication, this controller is unused and may display an INVALID status. This is expected behavior and has no impact on the connector. The connector works correctly regardless of this controller's status. Deleting the controller causes local modifications to the flow definition, so Snowflake recommends leaving it in place. --- title: Troubleshoot Workday Live Data Query source: https://docs.snowflake.cn/en/user-guide/data-integration/zero-copy/workday/troubleshooting.md section: Loading & Unloading Data --- # Troubleshoot Workday Live Data Query Available to all accounts. - [About Workday Live Data Query for Snowflake](/user-guide/data-integration/zero-copy/about-workday-ldq) - [Set up Snowflake for Workday Live Data Query](/user-guide/data-integration/zero-copy/workday/snowflake-setup) - [Connect to Workday and query data from Snowflake](/user-guide/data-integration/zero-copy/workday/connect-and-query) This topic describes common errors you might encounter when setting up or using Workday Live Data Query (LDQ) from Snowflake, along with their causes and fixes. ## HTTP 404: queries fail after a successful connection **Symptom:** The connection succeeds, but subsequent queries fail with an HTTP 404 error. **Cause:** The port number in the connection configuration is incorrect. **Fix:** Confirm that `"wd.port": "443"` is set in your `DataServiceConfig` dictionary. See [Connect to Workday and query data from Snowflake](/user-guide/data-integration/zero-copy/workday/connect-and-query). --- ## HTTP 400: authentication request rejected **Symptom:** The authentication request is rejected by the Workday Authorization Server. **Cause:** The ISU username in `DataServiceConfig` doesn't match the ISU registered in Workday. **Fix:** Verify that `wd.authn.isu` in your `DataServiceConfig` exactly matches the username shown in the **View Integration System User** task in Workday. This value is case-sensitive. --- ## HTTP 401: authentication fails at the token endpoint **Symptom:** Authentication fails at the token endpoint. **Cause:** The Client ID in your configuration doesn't match the one generated in Workday. **Fix:** Confirm that `wd.authn.clientId` matches the value on the **Register API Client** page in Workday. --- ## Access token request failed: network error **Symptom:** Python raises a connection error before authentication completes. **Cause:** The notebook can't reach the Workday token endpoint. Either the EAI isn't attached or the network rule is misconfigured. **Fix:** 1. Confirm the external access integration is attached to the notebook. See [Connect to Workday and query data from Snowflake](/user-guide/data-integration/zero-copy/workday/connect-and-query). 2. Verify the network rule `VALUE_LIST` includes the correct hostname and port (`host:443`). 3. Confirm the EAI has `ENABLED = TRUE`. 4. Confirm that `ALLOWED_AUTHENTICATION_SECRETS` in the EAI includes `WORKDAY_LDQ_TEST.LIVEDATA.WORKDAY_PRIVATE_KEY`. Without this, `_snowflake.get_generic_secret_string()` also fails. See [Set up Snowflake for Workday Live Data Query](/user-guide/data-integration/zero-copy/workday/snowflake-setup). --- ## Failed to obtain access token: 404 **Symptom:** The connector reaches the server, but the token endpoint path returns a 404. **Cause:** The token endpoint URL is incorrect, typically because of a wrong tenant ID or environment name. **Fix:** Double-check `wd.authn.accessTokenEndpoint`. The expected format is: ``` https:///ccx/oauth2//token ``` Confirm the tenant name matches your Workday tenant exactly. --- ## Failed to obtain access token: 401 (cryptographic failure) **Symptom:** The token request reaches Workday but authentication is rejected with a cryptographic error. **Cause:** The private key in use doesn't match the public key registered in Workday's API Client. **Fix:** 1. Confirm that the Snowflake Secret `WORKDAY_LDQ_TEST.LIVEDATA.WORKDAY_PRIVATE_KEY` contains the private key that corresponds to the public key registered in Workday's API Client. 2. If keys have been rotated or regenerated, recreate the secret with the new private key content and re-register the API Client in Workday with the corresponding public key. --- ## `ModuleNotFoundError: No module named 'workday_ldq'` **Symptom:** The import fails after a notebook restart. **Cause:** The wheel is installed per-session and doesn't persist across notebook restarts. **Fix:** Re-run the `pip install` cell (Step 3 of [Connect to Workday and query data from Snowflake](/user-guide/data-integration/zero-copy/workday/connect-and-query)) after every notebook restart. Keeping it as the very first cell ensures it always runs first. --- ## `Exception: No secret found` or `PermissionError` when retrieving the secret **Symptom:** The temporary UDF in the notebook setup fails with a secret-related error. **Cause:** One of the following: - The secret name is incorrect, or the secret doesn't exist in `WORKDAY_LDQ_TEST.LIVEDATA`. - The secret isn't listed in `ALLOWED_AUTHENTICATION_SECRETS` on the EAI. - The EAI isn't attached to the notebook. **Fix:** 1. Verify the secret exists by running the following in a Snowflake Worksheet: ```sql SHOW SECRETS IN SCHEMA WORKDAY_LDQ_TEST.LIVEDATA; ``` 2. Confirm the EAI includes the secret and is attached to the notebook. See [Set up Snowflake for Workday Live Data Query](/user-guide/data-integration/zero-copy/workday/snowflake-setup) and [Connect to Workday and query data from Snowflake](/user-guide/data-integration/zero-copy/workday/connect-and-query). 3. Ensure the secret name in the `secrets` parameter of the `@udf` decorator matches the fully qualified name exactly (for example, `'WORKDAY_LDQ_TEST.LIVEDATA.WORKDAY_PRIVATE_KEY'`). --- ## Queries return no rows or table not found **Symptom:** `SELECT COUNT(*) FROM workday_core.public.worker` returns `0` or a "table not found" error. **Cause:** The ISU doesn't have the correct security group permissions in Workday, or the Workday tenant hasn't provisioned the Workday Data Cloud environment. **Fix:** 1. Confirm the ISU belongs to an **Integration System Security Group (Unconstrained)** in Workday. 2. Confirm the ISU's security group has **View Only** permission on the required Workday catalog domains. 3. Confirm that **Activate Pending Security Policy Changes** was run in Workday after setting up permissions. 4. Run `SHOW SCHEMAS` or `SHOW TABLES` through the connector to verify what's accessible to the ISU. --- title: Troubleshooting the Openflow Connector for Amazon Kinesis Data Streams source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/kinesis/troubleshoot.md section: Loading & Unloading Data --- # Troubleshooting the %kinesis% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) - [Openflow Connector for Amazon Kinesis Data Streams](/user-guide/data-integration/openflow/connectors/kinesis/about) - [Set up Openflow Connector for Amazon Kinesis Data Streams](/user-guide/data-integration/openflow/connectors/kinesis/setup) - [Maintain Openflow Connector for Amazon Kinesis Data Streams](/user-guide/data-integration/openflow/connectors/kinesis/maintenance) - [Performance tuning of the Openflow Connector for Amazon Kinesis Data Streams](/user-guide/data-integration/openflow/connectors/kinesis/performance-tuning) This topic describes how to troubleshoot common issues with the %kinesis%. ## Common errors ### Error: UnknownHostException **Error message** ```text java.net.UnknownHostException: dynamodb.eu-west-1.amazonaws.com ``` **Cause** If the runtime is using a Snowflake Deployment, the network rule is most likely misconfigured. **Solution** Make sure the required AWS domains are allowlisted in your network rule. For the list of required domains, see [Set up Openflow - Snowflake Deployment: Configure allowed domains for Openflow connectors](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list). ### Error: Connect timed out to DynamoDB **Error message** ```text software.amazon.awssdk.core.exception.SdkClientException: Unable to execute HTTP request: Connect to https://dynamodb.us-east-1.amazonaws.com:443 failed: Connect timed out ``` **Cause** This occurs when the AWS PrivateLink configuration uses `PRIVATE_HOST_PORT` for `dynamodb.us-east-1.amazonaws.com`. DNS resolves to the PrivateLink endpoint IP, but the TCP connection can't be established because Amazon DynamoDB doesn't support Private DNS for its PrivateLink endpoints. **Solution** Use `HOST_PORT` for DynamoDB instead of `PRIVATE_HOST_PORT`. Only checkpoint metadata flows through DynamoDB; stream records continue through the Kinesis PrivateLink endpoints. For the full PrivateLink configuration, see [](#label-kinesis-configure-aws-privatelink). --- title: Troubleshooting the Openflow Connector for Oracle source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/oracle/troubleshoot.md section: Loading & Unloading Data --- # Troubleshooting the %oracleofc% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). The %oracleofc% is also subject to additional terms of service beyond the standard connector terms of service. For more information, see the [Openflow Connector for Oracle Addendum](https://www.snowflake.cn/en/legal/optional-offerings/offering-specific-terms/openflow-oracle-terms/). - [About Openflow Connector for Oracle](/user-guide/data-integration/openflow/connectors/oracle/about) - [Openflow Connector for Oracle: Configure the Oracle database](/user-guide/data-integration/openflow/connectors/oracle/setup-oracledb) - [Install and configure the Openflow Connector for Oracle](/user-guide/data-integration/openflow/connectors/oracle/setup-connector) - [Openflow Connector for Oracle: Maintenance](/user-guide/data-integration/openflow/connectors/oracle/maintenance) This topic describes how to troubleshoot common issues with the %oracleofc%. ## A table was added to replication but doesn't appear in Snowflake The table's fully qualified name (FQN) might be incorrectly specified in the connector configuration. **Solution** - Check the format of the FQN in `Oracle Ingestion Parameters`. It should be `..` (note the database prefix). - Check the database name in `Oracle Source Parameters` %raa% `Oracle Connection URL`. While FQNs support specifying the name of the database, currently data must reside in the same database instance as the one used for this connection. - Verify that you have provided the full database name including the domain name in the connector configuration. For example, use `MYDB.EXAMPLE.COM` instead of just `MYDB`. To find the correct database name, run the following query on your Oracle database: ```sql SELECT property_value FROM database_properties WHERE property_name = 'GLOBAL_DB_NAME'; ``` In general, `property_value` is the same as the service name of the database. However, the returned database name might include an appended domain name (for example, for service name `FOO`, the query might return `FOO.EXAMPLE.COM`). In that case, use the full name with the domain (double-quoted, because it contains dots). ## A table fails because the connector can't find a replication key The connector reports that a table can't be replicated because no primary key, unique constraint, or unique index qualifies as a replication key. The connector evaluates candidates as described in [](#label-oracle-replication-key-selection). **Solution** 1. Confirm the table has no primary key: ```sql SELECT constraint_name, status FROM all_constraints WHERE owner = 'YOUR_SCHEMA' AND table_name = 'YOUR_TABLE' AND constraint_type = 'P'; ``` 2. Find unique constraints that the connector skipped, and check why they didn't qualify (`STATUS != ENABLED`, `DEFERRED != IMMEDIATE`, or any column nullable): ```sql SELECT c.constraint_name, c.status, c.deferred, acc.column_name, atc.nullable FROM all_constraints c JOIN all_cons_columns acc ON acc.owner = c.owner AND acc.constraint_name = c.constraint_name JOIN all_tab_cols atc ON atc.owner = acc.owner AND atc.table_name = acc.table_name AND atc.column_name = acc.column_name WHERE c.owner = 'YOUR_SCHEMA' AND c.table_name = 'YOUR_TABLE' AND c.constraint_type = 'U'; ``` 3. Find unique indexes that the connector skipped, and check why they didn't qualify (`STATUS = UNUSABLE`, `INDEX_TYPE != NORMAL`, the index backs a constraint, or any column is nullable): ```sql SELECT i.index_name, i.uniqueness, i.status, i.index_type, ic.column_name, atc.nullable FROM all_indexes i JOIN all_ind_columns ic ON i.owner = ic.index_owner AND i.index_name = ic.index_name JOIN all_tab_cols atc ON atc.owner = ic.table_owner AND atc.table_name = ic.table_name AND atc.column_name = ic.column_name WHERE ic.table_owner = 'YOUR_SCHEMA' AND ic.table_name = 'YOUR_TABLE' AND i.uniqueness = 'UNIQUE'; ``` Resolve the issue by one of the following: - Add a primary key, or modify an existing constraint or index so it qualifies (enable it, change `DEFERRABLE INITIALLY DEFERRED` to `DEFERRABLE INITIALLY IMMEDIATE`, rebuild an unusable index, or add `NOT NULL` to the relevant columns). - Specify a logical key for the table. For more information, see [](#label-oracle-logical-key). After you make the change, restart replication for the affected table: see [](#label-of-oracle-restart-table-replication). ## The CDC processor doesn't start after editing Table Key Configuration JSON The **Read Oracle CDC Stream** processor stays invalid or fails to start after you configure or update the **Table Key Configuration JSON** value on a `MultiDatabaseJsonTableKeyConfigService` controller service. The controller service itself fails to enable because the JSON value is malformed, which keeps the CDC processor invalid because it depends on the service. **Solution** 1. Open the controller service properties and review the validation message on the **Table Key Configuration JSON** field. 2. Correct the JSON. For the expected format, see [](#label-oracle-logical-key). 3. Enable the controller service. Once it's enabled, start the CDC processor. ## A logical-key column was dropped or renamed on the source A table that uses a user-declared logical key is marked `FAILED` after a column listed in `logicalKey` is dropped or renamed on the source. The connector can't continue replicating the table because the configured key columns no longer match the live schema. **Solution** 1. Update the **Table Key Configuration JSON** value on the `MultiDatabaseJsonTableKeyConfigService` controller service so that `logicalKey` uses the current column names. Disable and re-enable the service for the change to take effect. 2. Restart replication for the affected table: see [](#label-of-oracle-restart-table-replication). ## A logical-key configuration references a column that doesn't exist A table stays in the `NEW` state and the connector log shows a message such as "`Logical key column '' does not exist in table schema`". The **Table Key Configuration JSON** value lists a column name that the connector can't find on the source table. **Solution** 1. Confirm the column exists and check its name in `ALL_TAB_COLS`: ```sql SELECT column_name FROM all_tab_cols WHERE owner = 'YOUR_SCHEMA' AND table_name = 'YOUR_TABLE' AND user_generated = 'YES'; ``` 2. Correct the column name in the **Table Key Configuration JSON** value. Disable and re-enable the controller service for the change to take effect. You don't need to remove and re-add the table: the connector retries schema initialization on the next poll, and replication resumes from `NEW`. ## A logical-key column contains duplicate values in the source A column declared in the **Table Key Configuration JSON** as part of the logical key doesn't actually contain unique values in the source table. The connector doesn't validate data-level uniqueness of logical-key values, so this condition doesn't produce an error. **Impact** The connector's MERGE operation deduplicates rows by logical-key value using a last-write-wins strategy. When multiple source rows share the same logical-key value: - During the snapshot, only one row per key value reaches the destination. The other rows are silently dropped. - During incremental replication, change events for different source rows that share a key value overwrite each other in the destination. This results in silent data loss with no error in the connector log. **Solution** 1. Verify whether the logical-key columns contain duplicates: ```sql SELECT COUNT(*) AS total_rows, COUNT(DISTINCT ) AS distinct_keys FROM .
Field Description
`database` Required. The exact source database name.
`schema` Required. The exact source schema name.
`table` Required. The exact source table name.
`logicalKey` Required. A non-empty array of source column names that uniquely identify rows in the table.
Parameter Description Required
Destination Database The database where data will be persisted. It must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. Yes
Destination Schema The schema where data will be persisted, which must already exist in Snowflake. The name is case-sensitive. For unquoted identifiers, provide the name in uppercase. See the following examples:
- `CREATE SCHEMA SCHEMA_NAME` or `CREATE SCHEMA schema_name`: use `SCHEMA_NAME` - `CREATE SCHEMA "schema_name"` or `CREATE SCHEMA "SCHEMA_NAME"`: use `schema_name` or `SCHEMA_NAME`, respectively
Yes
Snowflake Authentication Strategy When using: - **Snowflake Openflow Deployment** or **BYOC**: Use SNOWFLAKE_MANAGED. This token is managed automatically by Snowflake. BYOC deployments must have previously configured [execute-as roles](#label-deployment-byoc-setup-runtime-role) to use SNOWFLAKE_MANAGED. - **BYOC**: Alternatively, BYOC can use KEY_PAIR as the value for the authentication strategy. Yes
Snowflake Account Identifier When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Snowflake account name formatted as [organization-name]-[account-name]. Yes
Snowflake Private Key When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. -
**KEY_PAIR**: Must be the RSA private key used for authentication.
The RSA key must be formatted according to PKCS8 standards and have standard PEM headers and footers. Note that either a Snowflake Private Key File or a Snowflake Private Key must be defined.
No
Snowflake Private Key File When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: The private key file must be blank. - **KEY_PAIR**: Upload the file that contains the RSA private key used for authentication to Snowflake, formatted according to PKCS8 standards and including standard PEM headers and footers. The header line begins with `-----BEGIN PRIVATE`. To upload the private key file, select the **Reference asset** checkbox. No
Snowflake Private Key Password When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the password associated with the Snowflake private key file. No
Snowflake Role When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Use the runtime's execute-as role (or a child role granted to it). You can find your execute-as role in the Openflow UI by navigating to **View Details** for your runtime. - **KEY_PAIR**: Use a valid role configured for your service user. Yes
Snowflake Username When using: - **SNOWFLAKE_MANAGED** Authentication Strategy: Must be blank. - **KEY_PAIR**: Provide the username used to connect to the Snowflake instance. Yes
Snowflake Warehouse Snowflake warehouse used to run queries. Yes
Parameter Description
Authorization Type Choose between *OAUTH* or *BASIC_AUTH*. If *OAUTH* is chosen, then *OAuth Client ID, OAuth Client Secret, OAuth Refresh Token* and *OAuth Token Endpoint* must be defined. If *BASIC_AUTH* is chosen, then *Workday Username* and *Workday Password* must be defined.
OAuth Client ID The client ID of an application registered in Workday.
OAuth Client Secret The client secret related to the Client ID.
OAuth Refresh Token The refresh token is obtained by a user during the app registration process. It is used together with the client ID and the client secret to get an access token.
OAuth Token Endpoint The token endpoint is obtained by a user during the app registration process.
Workday Username The username is used to log into a Workday account. Must be set only when *BASIC_AUTH* is chosen.
Workday Password The password is associated with the Workday username. Must be set only when *BASIC_AUTH* is chosen.
Parameter Description
Destination Table The destination table where report data pulled from Workday is stored. It is created by the connector if it does not exist.
Report URL A RaaS API URL to a report created in Workday.
Run Schedule Run schedule on which data is retrieved from Workday and saved in Snowflake. This value is a time duration specified by a number followed by a time unit. For example, **1 second** or **5 mins**.
Column Description
`name` Name of the Zerocopy Connector.
`partner` The data partner (`SALESFORCE`).
`config` Configuration for the connector, including the Salesforce tenant endpoint and tenant ID.
`status` Current connector state. See [Salesforce Data Cloud Zerocopy Connector: Security and privileges](/user-guide/data-integration/zero-copy/salesforce/security) for the full state machine.
`connection_error` Error message if the connector is in `CONNECT_ERROR` or `DISCONNECT_ERROR` state; otherwise empty.
`catalog_linked_databases` Mounted catalog-linked databases visible to the current role.
`database_name` Database in which the connector resides.
`schema_name` Schema in which the connector resides.
`owner` Role that owns the connector.
`owner_role_type` Type of the owner role.
`comment` Optional comment set on the connector.
`created_on` Timestamp when the connector was created.
`updated_on` Timestamp when the connector was last updated.
Display Name API Name Default Value Allowable Values Description
Communications Timeout * Communications Timeout 30 secs Specifies how long to wait when communicating with the remote server before determining that there is a communications failure if data cannot be sent or received
SSL Context Service SSL Context Service If specified, indicates the SSL Context Service that is used to communicate with the remote server. If not specified, communications will not be encrypted
Server Hostname * Server Hostname The name of the server that is running the DistributedSetCacheServer service
Server Port * Server Port 4557 The port on the remote server that is to be used when communicating with the DistributedSetCacheServer service
Display Name API Name Default Value Allowable Values Description
Eviction Strategy * Eviction Strategy Least Frequently Used - Least Frequently Used - Least Recently Used - First In, First Out Determines which strategy should be used to evict values from the cache to make room for new entries
Maximum Cache Entries * Maximum Cache Entries 10000 The maximum number of cache entries that the cache can hold
Persistence Directory Persistence Directory If specified, the cache will be persisted in the given directory; if not specified, the cache will be in-memory only
Port * Port 4557 The port to listen on for incoming connections
SSL Context Service SSL Context Service If specified, this service will be used to create an SSL Context that will be used to secure communications; if not specified, communications will not be secure
Maximum Read Size maximum-read-size 1 MB The maximum number of network bytes to read for a single cache item
Parameter Description
BigQuery Project Name The unique identifier of the Google Cloud Project that contains BigQuery datasets and tables. Where to find: open BigQuery Studio (Google Cloud Console > BigQuery) and in the left Explorer pane hover over your project to see the Project ID. **Example:** `example-team-gcp`
GCP Service Account JSON The entire content of the JSON key file for the Google Cloud Platform Service Account used for authentication. Ensure the service account has the necessary IAM permissions to perform BigQuery operations, such as the BigQuery Job User and BigQuery Data Viewer roles. Where to get it: Google Cloud Console > IAM & Admin > Service Accounts > select the service account > Keys tab > Add key > Create new key > JSON. This downloads a .json file—open it and paste the entire file content (including braces) into this field.
Parameter Description
Snowflake Authentication Strategy When using SPCS, use `SNOWFLAKE_MANAGED` as the value for Authentication Strategy. When using BYOC, use `KEY_PAIR` as the value for Authentication Strategy. **Example:** `KEY_PAIR`
Snowflake Account Identifier When using: - `SNOWFLAKE_MANAGED` Authentication Strategy: Must be blank. - `KEY_PAIR`: Snowflake account name where data will be persisted.
Destination Database The name of the destination database to replicate into. Mixed case is supported.
Snowflake Private Key File When using: - `SNOWFLAKE_MANAGED` Authentication Strategy: The private key file must be blank. - `KEY_PAIR`: Upload the file that contains the RSA private key used for authentication to Snowflake, formatted according to PKCS8 standards and including standard PEM headers and footers. The header line begins with `-----BEGIN PRIVATE`. To upload the private key file, select the Reference asset checkbox.
Snowflake Private Key Password When using: - `SNOWFLAKE_MANAGED` Authentication Strategy: Must be blank. - `KEY_PAIR`: Provide the password associated with the Snowflake Private Key File.
Snowflake Role When using: - `SNOWFLAKE_MANAGED` Authentication Strategy: Use the runtime's execute-as role (or a child role granted to it). You can find your execute-as role in the Openflow UI by navigating to View Details for your runtime. - `KEY_PAIR` Authentication Strategy: Use a valid role configured for your service user.
Snowflake Username When using: - `SNOWFLAKE_MANAGED` Authentication Strategy: Must be blank. - `KEY_PAIR`: Provide the user name used to connect to the Snowflake instance.
Snowflake Warehouse The name of the warehouse to use by the connector.
Parameter Description
BigQuery Regions Specifies a comma-separated list of the locations to query for BigQuery datasets. You can combine both regional and multi-regional locations in the same list. **Example:** `us,eu,us-west1`
Included Dataset Names Comma-separated list of datasets to replicate (queried across all selected regions). **Example:** `sales_data,marketing_leads`
Included Dataset Names Regex Regular expression for specifying dataset names to replicate (queried across all selected regions). Combined with the Included Dataset Names to include any matching dataset. Note: REGEXP expression should match Google's RE2 syntax. **Example:** `^sales_.*`
Included Table Names Comma-separated list of tables to replicate across datasets. **Example:** `transactions,customers`
Included Table Names Regex Regular expression for specifying table names to replicate across datasets. Combined with the Included Table Names to include any matching table. Note: REGEXP expression should match Google's RE2 syntax. **Example:** `^revenue_.*`
Included View Names Comma-separated list of views to replicate across datasets. **Example:** `customer_summary,revenue_report`
Included View Names Regex Regular expression for specifying view names to replicate across datasets. Combined with the Included View Names to include any matching view. Note: REGEXP expression should match Google's RE2 syntax. **Example:** `^report_.*`
Incremental Sync Frequency How often the connector runs incremental synchronization for each table. Runs do not overlap if a cycle takes longer than the configured interval, the next run waits for the prior one to finish. Because BigQuery limits max size of window to 24h, schedule must be more frequent than this value. **Example:** `10m`
View Sync Frequency How often the connector runs synchronization for each view. Runs do not overlap, if a cycle takes longer than the configured interval, the next run waits for the prior one to finish. View ingestion does not support CDC, only truncate and load. **Example:** `1h`
Temporary Table Dataset Dataset in which necessary temporary tables are created, such as CDC journal tables or temporary tables for view ingestion. Snowflake recommends having a separate dataset for temporary tables and not using the ingested dataset for this purpose. **Example:** `openflow_temp`
Parameter Description
Veeva Vault Base URL Base URL for the Veeva Vault environment. Must be a valid URL including the protocol. **Example:** `https://myvault.veevavault.com`
Veeva Vault Username Service account username for Veeva Vault authentication.
Veeva Vault Password Service account password for Veeva Vault authentication. Stored securely as a sensitive parameter.
Veeva Vault Ingestion Mode Determines how Direct Data files are consumed. Allowed values: - `SNAPSHOT_AND_INCREMENTAL` (default): Load the latest full archive first, then continue with incremental archives. - `SNAPSHOT`: Poll for the latest full archive only. - `INCREMENTAL`: Poll for incremental archives only.
Veeva Vault Incremental Start Time Optional starting timestamp for incremental polling. Only applicable when the ingestion mode is `INCREMENTAL`. If not set, incremental polling starts from the current time. Expected format: `yyyy-MM-dd'T'HH:mmZ`. **Example:** `2025-01-15T08:30Z`
Veeva Vault Include Audit Logs Whether to also ingest Direct Data audit log files. **Default:** `true`
Parameter Description
Snowflake Authentication Strategy Authentication strategy for the connector to connect to Snowflake. - `SNOWFLAKE_MANAGED` (default): Uses the Snowflake-managed token associated with the runtime's execute-as role. This is the recommended strategy for both %ofsfspcs-plural% and %ofbyoc-plural%. - `KEY_PAIR`: Uses a user-provided RSA key pair. Available only on %ofbyoc-plural%, for cross-account scenarios where the connector writes to a Snowflake account different from the one hosting the Openflow runtime.
Snowflake Account Snowflake account identifier, formatted as `-`. Required when the authentication strategy is `KEY_PAIR`. **Example:** `MYORG-MYACCOUNT`
Snowflake Username The Snowflake user for authentication. Required when the authentication strategy is `KEY_PAIR`.
Snowflake Private Key PEM-encoded private key content for Snowflake key pair authentication. Required when the authentication strategy is `KEY_PAIR`. This value is stored securely as a sensitive parameter. You can also upload the private key file by selecting the **Reference asset** checkbox, uploading the file as an asset, and selecting the asset as the value for the parameter.
Snowflake Private Key Password Password to decrypt the Snowflake private key, if the key is encrypted. Only applicable when the authentication strategy is `KEY_PAIR`.
Snowflake Role The execute-as role used for table creation, data ingestion, and access verification. When using `SNOWFLAKE_MANAGED`, this is the execute-as role for Openflow runtimes. When using `KEY_PAIR`, this is the role assigned to the specified Snowflake user.
Snowflake Database Name of the destination database in Snowflake. The database must already exist before starting the connector.
Snowflake Schema Name of the destination schema in Snowflake. The schema must already exist before starting the connector.
Snowflake Warehouse The Snowflake warehouse used for table management operations such as `CREATE TABLE` and `MERGE`.
Snowflake Table Prefix Optional prefix applied to all destination table names in Snowflake. Use this to namespace tables when multiple connectors write to the same schema.
Snowflake Delete Strategy How to apply Veeva delete extracts in Snowflake. - `Hard Delete` (default): Permanently remove rows from the table. - `Soft Delete`: Set `__SNOWFLAKE_DELETED` to `TRUE` and `__SNOWFLAKE_DELETED_AT` to the current timestamp. The columns are added automatically if they don't exist.
Parameter Description
Column Removal Strategy Defines the strategy when a column should be removed from the destination table based on the latest received schema. - `Drop Column` (default): Drop the column from the Snowflake table. - `Rename Column`: Rename the column in the Snowflake table by appending the suffix defined in the **Removed Column Name Suffix** parameter. - `Ignore Column`: Leave the column as-is in the Snowflake table.
Removed Column Name Suffix Suffix appended to the column name when the **Column Removal Strategy** is set to `Rename Column`. **Default:** `__deleted`
Order Task Description Persona
1 Review [SAP® Snowflake](/user-guide/data-integration/zero-copy/sap-sql/setup-sap-snowflake) Setup for %sapsnowflake%. SAP® administrator
1 Review [SAP® BDC Connect for Snowflake](/user-guide/data-integration/zero-copy/sap-sql/setup-sap-bdc) Setup for %sapbdc%. SAP® administrator
2 Review [Set Up SAP® BDC Connect for Snowflake Zerocopy Connector](/user-guide/data-integration/zero-copy/sap-sql/setup) Set up the Zerocopy Connector on the Snowflake side. Snowflake account administrator
3 Review [SAP® BDC Connect for Snowflake Zerocopy Connector — Security and Privileges](/user-guide/data-integration/zero-copy/sap-sql/security) Review security requirements and privileges for Snowflake management. Snowflake account administrator
4 [Explore Data Products from SAP® BDC Connect for Snowflake](/user-guide/data-integration/zero-copy/sap-sql/explore-data-products) Explore data products shared from %sapbdc% to Snowflake. Snowflake account administrator and data engineer
5 [Publish Data from Snowflake to SAP® BDC Connect for Snowflake](/user-guide/data-integration/zero-copy/sap-sql/publish-data) Publish Snowflake data back to %sapbdc%. Snowflake account administrator and data engineer
Property Description
file-encoding File Encoding for signing
hash-algorithm Hash Algorithm for signing
private-key-id PGP Private Key Identifier formatted as uppercase hexadecimal string of 16 characters used for signing
private-key-service PGP Private Key Service for generating content signatures
signing-strategy Strategy for writing files to success after signing
Name Description
failure Content signing failed
success Content signing succeeded
Name Description
pgp.compression.algorithm Compression Algorithm
pgp.compression.algorithm.id Compression Algorithm Identifier
pgp.file.encoding File Encoding
pgp.signature.algorithm Signature Algorithm including key and hash algorithm names
pgp.signature.hash.algorithm.id Signature Hash Algorithm Identifier
pgp.signature.key.algorithm.id Signature Key Algorithm Identifier
pgp.signature.key.id Signature Public Key Identifier
pgp.signature.type.id Signature Type Identifier
pgp.signature.version Signature Version Number
Display Name API Name Default Value Allowable Values Description
CSV Format * CSV Format default - Custom Format - RFC 4180 - Microsoft Excel - Tab-Delimited - MySQL Format - Informix Unload - Informix Unload Escape Disabled - Default Format - RFC4180 Specifies which "format" the CSV data is in, or specifies if custom formatting should be used.
Character Set * Character Set UTF-8 The Character Encoding that is used to decode the CSV file.
Comment Marker Comment Marker The character that is used to denote the start of a comment. Any line that begins with this comment will be ignored.
Escape Character * Escape Character The character that is used to escape characters that would otherwise have a specific meaning to the CSV Parser. If the property has been specified via Expression Language but the expression gets evaluated to an invalid Escape Character at runtime, then it will be skipped and the default Escape Character will be used. Setting it to an empty string means no escape character should be used.
Quote Character * Quote Character " The character that is used to quote values so that escape characters do not have to be used. If the property has been specified via Expression Language but the expression gets evaluated to an invalid Quote Character at runtime, then it will be skipped and the default Quote Character will be used.
Quote Mode * Quote Mode MINIMAL - Quote All Values - Quote Minimal - Quote Non-Numeric Values - Do Not Quote Values Specifies how fields should be quoted when they are written
Trim Fields * Trim Fields true - true - false Whether or not white space should be removed from the beginning and end of fields
Value Separator * Value Separator , The character that is used to separate values/fields in a CSV Record. If the property has been specified via Expression Language but the expression gets evaluated to an invalid Value Separator at runtime, then it will be skipped and the default Value Separator will be used.
CSV File * csv-file Path to a CSV File in which the key value pairs can be looked up.
Ignore Duplicates * ignore-duplicates true - true - false Ignore duplicate keys for records in the CSV file.
Lookup Key Column * lookup-key-column The field in the CSV file that will serve as the lookup key. This is the field that will be matched against the property specified in the lookup processor.
Lookup Value Column * lookup-value-column Lookup value column.
Required Permission Explanation
read filesystem Provides operator the ability to read from any file that NiFi has access to.
Display Name API Name Default Value Allowable Values Description
Cache Expiration Cache Expiration Time interval to clear all cache entries. If the Cache Size is zero then this property is ignored.
Cache Size * dbrecord-lookup-cache-size 0 Specifies how many lookup values/records should be cached. The cache is shared for all tables and keeps a map of lookup values to records. Setting this property to zero means no caching will be done and the table will be queried for each lookup value in each record. If the lookup table changes often or the most recent data must be retrieved, do not use the cache.
Clear Cache on Enabled * dbrecord-lookup-clear-cache-on-enabled true - true - false Whether to clear the cache when this service is enabled. If the Cache Size is zero then this property is ignored. Clearing the cache when the service is enabled ensures that the service will first go to the database to get the most recent data.
Database Connection Pooling Service * dbrecord-lookup-dbcp-service The Controller Service that is used to obtain connection to database
Lookup Key Column * dbrecord-lookup-key-column The column in the table that will serve as the lookup key. This is the column that will be matched against the property specified in the lookup processor. Note that this may be case-sensitive depending on the database.
Table Name * dbrecord-lookup-table-name The name of the database table to be queried. Note that this may be case-sensitive depending on the database.
Lookup Value Column * lookup-value-column The column whose value will be returned when the Lookup value is matched
Display Name API Name Default Value Allowable Values Description
TTL * redis-cache-ttl 0 secs Indicates how long the data should exist in Redis. Setting '0 secs' would mean the data would exist forever
Redis Connection Pool * redis-connection-pool
Display Name API Name Default Value Allowable Values Description
Module Directory Module Directory Comma-separated list of paths to files and/or directories which contain modules required by the script.
Script Body Script Body Body of script to execute. Only one of Script File or Script Body may be used
Script Engine * Script Engine Groovy - Groovy Language Engine for executing scripts
Script File Script File Path to script file to execute. Only one of Script File or Script Body may be used
Required Permission Explanation
execute code Provides operator the ability to execute arbitrary code assuming all permissions that NiFi has.
Display Name API Name Default Value Allowable Values Description
Access Token * access-token Bot OAuth Token used for authenticating and authorizing the Slack request sent by NiFi.
API URL * api-url https://slack.com/api (https://slack.com/api) Slack Web API URL for posting text messages to channels. It only needs to be changed if Slack changes its API URL.
Channel ID * channel-id Slack channel, private group, or IM channel to send the message to. Use Channel ID instead of the name.
Input Character Set * input-character-set UTF-8 Specifies the character set of the records used to generate the Slack message.
Record Writer * record-sink-record-writer Specifies the Controller Service to use for writing out the records.
Web Service Client Provider * web-service-client-provider Controller service to provide HTTP client for communicating with Slack API
Display Name API Name Default Value Allowable Values Description
Domain domain The domain used for authentication. Optional, in most cases username and password is sufficient.
Enable DFS * enable-dfs false - true - false Enables accessing Distributed File System (DFS) and following DFS links during SMB operations.
Hostname * hostname The network host of the SMB file server.
Password password The password used for authentication.
Port * port 445 Port to use for connection.
Share * share The network share to which files should be listed from. This is the "first folder"after the hostname: [smb://hostname:port/[share]/dir1/dir2](smb://hostname:port/[share]/dir1/dir2)
SMB Dialect * smb-dialect AUTO - AUTO - SMB 2.0.2 - SMB 2.1 - SMB 3.0 - SMB 3.0.2 - SMB 3.1.1 The SMB dialect is negotiated between the client and the server by default to the highest common version supported by both end. In some rare cases, the client-server communication may fail with the automatically negotiated dialect. This property can be used to set the dialect explicitly (e.g. to downgrade to a lower version), when those situations would occur.
Timeout * timeout 5 sec Timeout for read and write operations.
Use Encryption * use-encryption false - true - false Turns on/off encrypted communication between the client and the server. The property's behavior is SMB dialect dependent: SMB 2.x does not support encryption and the property has no effect. In case of SMB 3.x, it is a hint/request to the server to turn encryption on if the server also supports it.
Username username Guest The username used for authentication.
Property Value
SASL Mechanism `AWS_MSK_IAM`
Security Protocol `#{Kafka Security Protocol}`
Bootstrap Servers `#{Kafka Bootstrap Servers}`
Item Kafka high-performance
Source processor `ConsumeKafka`
Parse-failure relationship `parse failure`
Connection / credentials to reuse `Kafka3ConnectionService`
Stream-route publisher `PublishKafka`
Record reader / writer `JsonTreeReader` / `JsonRecordSetWriter`
Destination processor `PublishSnowpipeStreaming`
Property Value
Topic Name Your DLQ topic name.
Kafka Connection Service The same `Kafka3ConnectionService` used by `ConsumeKafka`.
Failure Strategy `Route to Failure`
FlowFile Attribute Header Pattern `kafka\..*`
Symptom Likely cause
DLQ publisher writes to the wrong cluster `PublishKafka` reuses the `Kafka3ConnectionService` of `ConsumeKafka` --- a different cluster needs a separate connection service.
Property Value
Keystore Filename Full path to your keystore file (for example, `/path/to/client-keystore.p12`), or Asset reference
Keystore Password Password for the keystore
Keystore Type Keystore format (`PKCS12`, `JKS`, or `BCFKS`)
Key Password Password for the private key (if the key is encrypted)
Truststore Filename Full path to your truststore file (for example, `/path/to/client-truststore.p12`), or Asset reference
Truststore Password Password for the truststore
Truststore Type Truststore format (`PKCS12`, `JKS`, or `BCFKS`)
Property Value
Certificate Path to your PEM-encoded certificate file (`.pem`, `.crt`), or Asset reference (see [Ops parameters and assets](/user-guide/data-integration/openflow/ops-parameters-assets))
Private Key Path to your PEM-encoded private key file (`.key`), or Asset reference
CA Certificate Path to the CA certificate file, or Asset reference. Required only if the broker certificate is not signed by a trusted CA.
Property Value
Security Protocol `SSL`
SSL Context Service Select the SSL Context Service you created in [](#label-openflow-kafka-mtls-auth-step1)
Display Name API Name Default Value Allowable Values Description
Account * Account Snowflake Account Identifier with Organization Name and Account Name formatted as [organization-name]-[account-name]
Authentication Strategy * Authentication Strategy PASSWORD - Password - Key Pair - Snowflake Session Token Strategy for authenticating Snowflake connections
Connection Strategy * Connection Strategy STANDARD - Standard - Private Connectivity Strategy for connecting to Snowflake services
Connection Timeout * Connection Timeout 30 seconds Maximum amount of time to wait for a connection from a reusable pool
Database Name Database Name Default Snowflake Database for connections
Idle Timeout * Idle Timeout 10 minutes Maximum amount of time for a connection to remain idle in a reusable pool
Maximum Connections * Maximum Connections 10 Maximum number of connections created and managed in a reusable pool
Maximum Lifetime * Maximum Lifetime 30 minutes Maximum lifetime for each connection in a reusable pool
Password * Password Snowflake Password for authenticating connections
Private Key Service * Private Key Service RSA Private Key Service for authenticating connections
Role Role Default Snowflake Role for connections
Schema Schema Default Snowflake Schema for connections
User * User Snowflake User for authenticating connections
Warehouse Warehouse Default Snowflake Warehouse for connections
Property Description
Content Hash The name of the FlowFile attribute that holds the pre-computed hash. Supports Expression Language.
Document Source Identifier Specifies the document source identifier (doc ID). Supports Expression Language.
Document Source Name Specifies the document source system name. Supports Expression Language.
Snowflake Connection Service The DBCPService that provides connection to Snowflake.
Snowflake Table Name The Snowflake table name that stores the file hashes. The table name is case-insensitive. Database and schema must be configured prior in the Snowflake Connection Service.
Name Description
distinct FlowFiles that do not match an existing document are routed here (new hash inserted).
duplicate FlowFiles that match an existing document (same hash) are routed here.
failure FlowFiles that encounter an error or exception during processing are routed here.
Name Description
snowflake.detect.duplicate A 'true' or 'false' attribute indicating if the FlowFile was detected as a duplicate.
Display Name API Name Default Value Allowable Values Description
Audience * Audience The audience claim (aud) for the JWT.
Connection Pooling Service * Connection Pooling Service The Connection Pooling Service that is used to obtain a connection to the database
JWT Expiration Time * JWT Expiration Time 5 minutes Expiration time used to set the corresponding claim of the JWT.
Snowflake Secret Name * Snowflake Secret Name Name of the JWT Key Pair secret in Snowflake that will be used to sign the JWT.
Subject * Subject The subject claim (sub) for the JWT.
Display Name API Name Default Value Allowable Values Description
Account * Account Snowflake Account Identifier with Organization Name and Account Name formatted as [organization-name]-[account-name]
Private Key Service * Private Key Service RSA Private Key Service for authenticating connections
User * User Snowflake User for authenticating connections
Web Client Service Provider * Web Client Service Provider Web Client Service Provider to make connections
Property Description
Output Size The number of Avro records to include per split file. In cases where the incoming file has less records than the Output Size, or when the total number of records does not divide evenly by the Output Size, it is possible to get a split file with less records.
Output Strategy Determines the format of the output. Either Avro Datafile, or bare record. Bare record output is only intended for use with systems that already require it, and shouldn't be needed for normal use.
Split Strategy The strategy for splitting the incoming datafile. The Record strategy will read the incoming datafile by de-serializing each record.
Transfer Metadata Whether or not to transfer metadata from the parent datafile to the children. If the Output Strategy is Bare Record, then the metadata will be stored as FlowFile attributes, otherwise it will be in the Datafile header.
Name Description
failure If a FlowFile fails processing for any reason (for example, the FlowFile is not valid Avro), it will be routed to this relationship
original The original FlowFile that was split. If the FlowFile fails processing, nothing will be sent to this relationship
split All new files split from the original FlowFile will be routed to this relationship
Name Description
fragment.identifier All split FlowFiles produced from the same parent FlowFile will have the same randomly generated UUID added for this attribute
fragment.index A one-up number that indicates the ordering of the split FlowFiles that were created from a single parent FlowFile
fragment.count The number of split FlowFiles generated from the parent FlowFile
segment.original.filename The filename of the parent FlowFile
Property Description
Byte Sequence A representation of bytes to look for and upon which to split the source file into separate files
Byte Sequence Format Specifies how the <Byte Sequence> property should be interpreted
Byte Sequence Location If <Keep Byte Sequence> is set to true, specifies whether the byte sequence should be added to the end of the first split or the beginning of the second; if <Keep Byte Sequence> is false, this property is ignored.
Keep Byte Sequence Determines whether or not the Byte Sequence should be included with each Split
Name Description
original The original file
splits All Splits will be routed to the splits relationship
Name Description
fragment.identifier All split FlowFiles produced from the same parent FlowFile will have the same randomly generated UUID added for this attribute
fragment.index A one-up number that indicates the ordering of the split FlowFiles that were created from a single parent FlowFile
fragment.count The number of split FlowFiles generated from the parent FlowFile
segment.original.filename The filename of the parent FlowFile
Property Description
Password The password for a password protected Excel spreadsheet
Protection Type Specifies whether an Excel spreadsheet is protected by a password or not.
Name Description
failure If a FlowFile cannot be transformed from the configured input format to the configured output format, the unchanged FlowFile will be routed to this relationship.
original The original FlowFile that was split into segments. If the FlowFile fails processing, nothing will be sent to this relationship
split The individual Excel 'segments' of the original Excel FlowFile will be routed to this relationship.
Name Description
fragment.identifier All split Excel FlowFiles produced from the same parent Excel FlowFile will have the same randomly generated UUID added for this attribute
fragment.index A one-up number that indicates the ordering of the split Excel FlowFiles that were created from a single parent Excel FlowFile
fragment.count The number of split Excel FlowFiles generated from the parent Excel FlowFile
segment.original.filename The filename of the parent Excel FlowFile
sheetname The name of the Excel sheet from the original spreadsheet.
total.rows The number of rows in the Excel sheet from the original spreadsheet.
Property Description
JsonPath Expression A JsonPath expression that indicates the array element to split into JSON/scalar fragments.
Max String Length The maximum allowed length of a string value when parsing the JSON document
Null Value Representation Indicates the desired representation of JSON Path expressions resulting in a null value.
Name Description
failure If a FlowFile fails processing for any reason (for example, the FlowFile is not valid JSON or the specified path does not exist), it will be routed to this relationship
original The original FlowFile that was split into segments. If the FlowFile fails processing, nothing will be sent to this relationship
split All segments of the original FlowFile will be routed to this relationship
Name Description
fragment.identifier All split FlowFiles produced from the same parent FlowFile will have the same randomly generated UUID added for this attribute
fragment.index A one-up number that indicates the ordering of the split FlowFiles that were created from a single parent FlowFile
fragment.count The number of split FlowFiles generated from the parent FlowFile
segment.original.filename The filename of the parent FlowFile
Property Description
Record Reader Specifies the Controller Service to use for reading incoming data
Record Writer Specifies the Controller Service to use for writing out the records
Records Per Split Specifies how many records should be written to each 'split' or 'segment' FlowFile
Name Description
failure If a FlowFile cannot be transformed from the configured input format to the configured output format, the unchanged FlowFile will be routed to this relationship.
original Upon successfully splitting an input FlowFile, the original FlowFile will be sent to this relationship.
splits The individual 'segments' of the original FlowFile will be routed to this relationship.
Name Description
mime.type Sets the mime.type attribute to the MIME Type specified by the Record Writer for the FlowFiles routed to the 'splits' Relationship.
record.count The number of records in the FlowFile. This is added to FlowFiles that are routed to the 'splits' Relationship.
fragment.identifier All split FlowFiles produced from the same parent FlowFile will have the same randomly generated UUID added for this attribute
fragment.index A one-up number that indicates the ordering of the split FlowFiles that were created from a single parent FlowFile
fragment.count The number of split FlowFiles generated from the parent FlowFile
segment.original.filename The filename of the parent FlowFile
Property Description
Header Line Count The number of lines that should be considered part of the header; the header lines will be duplicated to all split files
Header Line Marker Characters The first character(s) on the line of the datafile which signifies a header line. This value is ignored when Header Line Count is non-zero. The first line not containing the Header Line Marker Characters and all subsequent lines are considered non-header
Line Split Count The number of lines that will be added to each split file, excluding header lines. A value of zero requires Maximum Fragment Size to be set, and line count will not be considered in determining splits.
Maximum Fragment Size The maximum size of each split file, including header lines. NOTE: in the case where a single line exceeds this property (including headers, if applicable), that line will be output in a split of its own which exceeds this Maximum Fragment Size setting.
Remove Trailing Newlines Whether to remove newlines at the end of each split file. This should be false if you intend to merge the split files later. If this is set to 'true' and a FlowFile is generated that contains only 'empty lines' (i.e., consists only of r and n characters), the FlowFile will not be emitted. Note, however, that if header lines are specified, the resultant FlowFile will never be empty as it will consist of the header lines, so a FlowFile may be emitted that contains only the header lines.
Name Description
failure If a file cannot be split for some reason, the original file will be routed to this destination and nothing will be routed elsewhere
original The original input file will be routed to this destination when it has been successfully split into 1 or more files
splits The split files will be routed to this destination when an input file is successfully split into 1 or more split files
Name Description
text.line.count The number of lines of text from the original FlowFile that were copied to this FlowFile
fragment.size The number of bytes from the original FlowFile that were copied to this FlowFile, including header, if applicable, which is duplicated in each split FlowFile
fragment.identifier All split FlowFiles produced from the same parent FlowFile will have the same randomly generated UUID added for this attribute
fragment.index A one-up number that indicates the ordering of the split FlowFiles that were created from a single parent FlowFile
fragment.count The number of split FlowFiles generated from the parent FlowFile
segment.original.filename The filename of the parent FlowFile
Property Description
Split Depth Indicates the XML-nesting depth to start splitting XML fragments. A depth of 1 means split the root 's children, whereas a depth of 2 means split the root's children's children and so forth.
Name Description
failure If a FlowFile fails processing for any reason (for example, the FlowFile is not valid XML), it will be routed to this relationship
original The original FlowFile that was split into segments. If the FlowFile fails processing, nothing will be sent to this relationship
split All segments of the original FlowFile will be routed to this relationship
Name Description
fragment.identifier All split FlowFiles produced from the same parent FlowFile will have the same randomly generated UUID added for this attribute
fragment.index A one-up number that indicates the ordering of the split FlowFiles that were created from a single parent FlowFile
fragment.count The number of split FlowFiles generated from the parent FlowFile
segment.original.filename The filename of the parent FlowFile
Display Name API Name Default Value Allowable Values Description
Anthropic API Key * Anthropic API Key The API Key for authenticating to Anthropic
Backoff Base Delay (ms) * Backoff Base Delay (ms) 1000 The base delay in milliseconds for exponential backoff between retries
Max Response Tokens * Max Response Tokens 1000 The maximum number of tokens to generate in the response.
Max Retries * Max Retries 3 The maximum number of retry attempts for API calls
Model Name * Model Name claude-3-5-sonnet-latest The name of the Anthropic model
Temperature Temperature The temperature to use for generating the response.
Top K Top K The top K value to use for generating the response. Only sample from the top K options for each subsequent token. Recommended for advanced use cases only. You usually only need to use temperature.
Top P Top P The top_p value for nucleus sampling. It controls the diversity of the generated responses.
User ID User ID The user id to set in the request metadata
Web Client Service * Web Client Service The Web Client Service to use for communicating with the LLM provider.
Display Name API Name Default Value Allowable Values Description
Credential Configuration Strategy * Credential Configuration Strategy default-credential - Default Credential - Managed Identity
Managed Identity Client ID Managed Identity Client ID Client ID of the managed identity. The property is required when User Assigned Managed Identity is used for authentication. It must be empty in case of System Assigned Managed Identity.
Display Name API Name Default Value Allowable Values Description
API Token * API Token Token used for API authentication
Environment URL * Environment URL URL to the Atlassian Confluence Environment ie. https://domain.atlassian.net (https://domain.atlassian.net)
Request Rate Manager * Request Rate Manager Controller service for keeping track of rate limits for Atlassian APIs
User Email * User Email Confluence user email
Web Client Service * Web Client Service The Web Client Service to use for communicating with Confluence
Display Name API Name Default Value Allowable Values Description
Authentication Method * Authentication Method OAUTH_M2M - OAuth M2M - PAT Method to authenticate with Databricks
OAuth Client ID * OAuth Client ID Databricks OAuth Client ID, also known as an application ID
OAuth Client Secret * OAuth Client Secret Databricks Service Principal's OAuth Client Secret.
Personal Access Token * Personal Access Token Databricks Personal Access Token
Workspace ID * Workspace ID Databricks Workspace ID
Proxy Configuration Service proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Display Name API Name Default Value Allowable Values Description
Access Token * Access Token Access Token of the user's Dropbox app. See Additional Details for more information about Access Token generation.
App Key * App Key App Key of the user's Dropbox app. See Additional Details for more information.
App Secret * App Secret App Secret of the user's Dropbox app. See Additional Details for more information.
Refresh Token * Refresh Token Refresh Token of the user's Dropbox app. See Additional Details for more information about Refresh Token generation.
Display Name API Name Default Value Allowable Values Description
File Path * file-path $\{absolute.path\}/$\{filename\} Path to a file that can be accessed locally.
Required Permission Explanation
read filesystem Provides operator the ability to read from any file that NiFi has access to.
Display Name API Name Default Value Allowable Values Description
Configuration Strategy * configuration-strategy direct-properties - Direct Properties - Properties Files Specifies the source of the configuration properties.
Vault Authentication * vault.authentication TOKEN - TOKEN - APPID - APPROLE - AWS_EC2 - AZURE - CERT - CUBBYHOLE - KUBERNETES Vault authentication method, as described in the Spring Vault Environment Configuration documentation (https://docs.spring.io/spring-vault/docs/2.3.x/reference/html/#vault.core.environment-vault-configuration (https://docs.spring.io/spring-vault/docs/2.3.x/reference/html/#vault.core.environment-vault-configuration)).
Connection Timeout * vault.connection.timeout 5 sec The connection timeout for the HashiCorp Vault client
Vault Properties Files * vault.properties.files A comma-separated list of files containing HashiCorp Vault configuration properties, as described in the Spring Vault Environment Configuration documentation (https://docs.spring.io/spring-vault/docs/2.3.x/reference/html/#vault.core.environment-vault-configuration (https://docs.spring.io/spring-vault/docs/2.3.x/reference/html/#vault.core.environment-vault-configuration)). All of the Spring property keys and authentication-specific property keys are supported.
Read Timeout * vault.read.timeout 15 sec The read timeout for the HashiCorp Vault client
SSL Context Service vault.ssl.context.service The SSL Context Service used to provide client certificate information for TLS/SSL connections to the HashiCorp Vault server.
Vault URI * vault.uri The URI of the HashiCorp Vault server (e.g., http://localhost:8200 (http://localhost:8200)). Required if not specified in the Bootstrap HashiCorp Vault Configuration File.
Display Name API Name Default Value Allowable Values Description
Maximum Outstanding Requests * Maximum Outstanding Requests 5000 The maximum number of HTTP requests that can be outstanding at any one time. Any attempt to register an additional HTTP Request will cause an error
Request Expiration * Request Expiration 1 min Specifies how long an HTTP Request should be left unanswered before being evicted from the cache and being responded to with a Service Unavailable status code
Display Name API Name Default Value Allowable Values Description
HubSpot Access Token * HubSpot Access Token HubSpot Access Token
Web Client Service Provider * Web Client Service Provider The Web Client Service to use for communicating with HubSpot
Display Name API Name Default Value Allowable Values Description
JSON Schema Version * JSON Schema Version DRAFT_2020_12 - Draft 4 - Draft 6 - Draft 7 - Draft 2019-09 - Draft 2020-12 The JSON schema specification
Display Name API Name Default Value Allowable Values Description
Application Client ID * Application Client ID Azure Data Explorer Application Client Identifier for Authentication
Application Key * Application Key Azure Data Explorer Application Key for Authentication
Application Tenant ID * Application Tenant ID Azure Data Explorer Application Tenant Identifier for Authentication
Authentication Strategy * Authentication Strategy MANAGED_IDENTITY - Application Credentials - Managed Identity - Azure CLI (Dev Only) Authentication method for access to Azure Data Explorer
Cluster URI * Cluster URI Azure Data Explorer Cluster URI
Display Name API Name Default Value Allowable Values Description
Application Client ID * Application Client ID Azure Data Explorer Application Client Identifier for Authentication
Application Key * Application Key Azure Data Explorer Application Key for Authentication
Application Tenant ID * Application Tenant ID Azure Data Explorer Application Tenant Identifier for Authentication
Authentication Strategy * Authentication Strategy MANAGED_IDENTITY - Application Credentials - Managed Identity - Azure CLI (Dev Only) Authentication method for access to Azure Data Explorer
Cluster URI * Cluster URI Azure Data Explorer Cluster URI
Display Name API Name Default Value Allowable Values Description
API Key * API Key Milvus API Key for authenticating connections
Authentication Strategy * Authentication Strategy PASSWORD - Password - API Key Strategy for authenticating Milvus connections
Connection Timeout * Connection Timeout 30 seconds Maximum amount of time to wait for a connection from a reusable pool
Idle Timeout * Idle Timeout 10 minutes Maximum amount of time for a connection to remain idle in a reusable pool
Password * Password Milvus password for authenticating connections
SSL Context Service SSL Context Service The SSL Context Service used to provide client certificate information for TLS/SSL connections.
Service URI * Service URI The URI to use to communicate with Milvus
User * User Milvus username for authenticating connections
Display Name API Name Default Value Allowable Values Description
Audience Audience Audience for the access token request defined in RFC 8693 Section 2.1
Authorization Server URL * Authorization Server URL The URL of the authorization server that issues access tokens.
Client Authentication Strategy * Client Authentication Strategy REQUEST_BODY - REQUEST_BODY - BASIC_AUTHENTICATION Strategy for authenticating the client against the OAuth2 token provider service.
Client ID Client ID
Client secret * Client secret
Grant Type * Grant Type password - User Password - Client Credentials - Refresh Token The OAuth2 Grant Type to be used when acquiring an access token.
HTTP Protocols * HTTP Protocols H2_HTTP_1_1 - http/1.1 - h2 http/1.1 - h2 HTTP Protocols supported for Application Layer Protocol Negotiation with TLS
Password * Password Password for the username on the service that is being accessed.
Refresh Token * Refresh Token Refresh Token supports retrieving a new Access Token when configured
Refresh Window * Refresh Window 0 s The service will attempt to refresh tokens expiring within the refresh window, subtracting the configured duration from the token expiration.
Resource Resource Resource URI for the access token request defined in RFC 8707 Section 2
SSL Context Service SSL Context Service
Scope Scope Space-delimited, case-sensitive list of scopes of the access request (as per the OAuth 2.0 specification)
Username * Username Username on the service that is being accessed.
Proxy Configuration Service proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Display Name API Name Default Value Allowable Values Description
Communications Timeout * Communications Timeout 60 secs The amount of time to wait for a response from the OCR Service.
Custom Service URL * Custom Service URL The Custom URL of the Openflow Tesseract OCR Service.
OCR Languages * OCR Languages ENGLISH The Languages to use when performing OCR if none are provided by the caller.This is a commma separated list of the following Valid Values:ENGLISH, KOREAN, KOREAN_VERT, HEBREW
Service Location Strategy * Service Location Strategy Default - Default - Custom Determines how Service Locations configured within this Controller for the Openflow Tesseract OCR Service.
Display Name API Name Default Value Allowable Values Description
Backoff Base Delay (ms) * Backoff Base Delay (ms) 1000 The base delay in milliseconds for exponential backoff between retries
Max Response Tokens Max Response Tokens The maximum number of tokens to generate in the response.
Max Retries * Max Retries 3 The maximum number of retry attempts for API calls
Model Name * Model Name gpt-4o-mini The name of the OpenAI model.
OpenAI API Key * OpenAI API Key The API Key for authenticating to OpenAI.
Seed Seed The seed to use for generating the response
Temperature Temperature The temperature to use for generating the response.
Top P Top P The top_p value for nucleus sampling. It controls the diversity of the generated responses.
User User Your end user, sent to OpenAI for monitoring and detection of abuse
Web Client Service * Web Client Service The Web Client Service to use for communicating with the LLM provider.
Display Name API Name Default Value Allowable Values Description
Key Password * key-password Password used for decrypting Private Keys
Keyring keyring PGP Keyring or Secret Key encoded in ASCII Armor
Keyring File keyring-file File path to PGP Keyring or Secret Key encoded in binary or ASCII Armor
Display Name API Name Default Value Allowable Values Description
Keyring keyring PGP Keyring or Public Key encoded in ASCII Armor
Keyring File keyring-file File path to PGP Keyring or Public Key encoded in binary or ASCII Armor
Display Name API Name Default Value Allowable Values Description
Key key Private Key structured using PKCS8 and encoded as PEM
Key File key-file File path to Private Key structured using PKCS8 and encoded as PEM
Key Password key-password Password used for decrypting Private Keys
Display Name API Name Default Value Allowable Values Description
Message Name * Message Name Fully qualified name of the Protocol Buffers message including its package (eg. mypackage.MyMessage).
Message Name Resolution Strategy * Message Name Resolution Strategy MESSAGE_NAME_PROPERTY - Message Name Property - Message Name Resolver Strategy for determining the Protocol Buffers message name for processing
Message Name Resolver * Message Name Resolver Service that dynamically resolves Protocol Buffer message names from FlowFile content or attributes
Schema Access Strategy * Schema Access Strategy schema-name - Use 'Schema Name' Property - Use 'Schema Text' Property - Schema Reference Reader Specifies how to obtain the schema that is to be used for interpreting the data.
Schema Branch Schema Branch Specifies the name of the branch to use when looking up the schema in the Schema Registry property. If the chosen Schema Registry does not support branching, this value will be ignored.
Schema Name Schema Name $\{schema.name\} Specifies the name of the schema to lookup in the Schema Registry property
Schema Reference Reader * Schema Reference Reader Service implementation responsible for reading FlowFile attributes or content to determine the Schema Reference Identifier
Schema Registry Schema Registry Specifies the Controller Service to use for the Schema Registry
Schema Text * Schema Text $\{proto.schema\} The text of a Proto 3 formatted Schema
Schema Version Schema Version Specifies the version of the schema to lookup in the Schema Registry. If not specified then the latest version of the schema will be retrieved.
Display Name API Name Default Value Allowable Values Description
Proxy Server Host proxy-server-host Proxy server hostname or ip-address.
Proxy Server Port proxy-server-port Proxy server port number.
Proxy Type * proxy-type DIRECT - DIRECT - HTTP - SOCKS Proxy type.
Proxy User Name proxy-user-name The name of the proxy client for user authentication.
Proxy User Password proxy-user-password The password of the proxy client for user authentication.
SOCKS Version * socks-version SOCKS5 - SOCKS4 - SOCKS5 SOCKS Protocol Version
Display Name API Name Default Value Allowable Values Description
Keystore Filename Keystore Filename The fully-qualified filename of the Keystore
Keystore Password Keystore Password The password for the Keystore
Keystore Type Keystore Type - BCFKS - PKCS12 - JKS The Type of the Keystore
TLS Protocol SSL Protocol TLS - TLS - TLSv1.3 - TLSv1.2 TLS Protocol Version for encrypted connections. Supported versions depend on the specific version of Java used.
Truststore Filename Truststore Filename The fully-qualified filename of the Truststore
Truststore Password Truststore Password The password for the Truststore
Truststore Type Truststore Type - BCFKS - PKCS12 - JKS The Type of the Truststore
Key Password key-password The password for the key. If this is not specified, but the Keystore Filename, Password, and Type are specified, then the Keystore Password will be assumed to be the same as the Key Password.
Display Name API Name Default Value Allowable Values Description
Encryption Strategy * Encryption Strategy NONE - None - Server-side S3 - Server-side KMS - Server-side Customer Key - Client-side KMS - Client-side Customer Key Strategy to use for S3 data encryption and decryption.
KMS Region KMS Region us-west-2 - AWS GovCloud (US) - AWS GovCloud (US-East) - US East (N. Virginia) - US East (Ohio) - US West (N. California) - US West (Oregon) - EU (Ireland) - EU (London) - EU (Paris) - EU (Frankfurt) - EU (Zurich) - EU (Stockholm) - EU (Milan) - EU (Spain) - Asia Pacific (Hong Kong) - Asia Pacific (Taipei) - Asia Pacific (Mumbai) - Asia Pacific (Hyderabad) - Asia Pacific (Singapore) - Asia Pacific (Sydney) - Asia Pacific (Jakarta) - Asia Pacific (Melbourne) - Asia Pacific (Malaysia) - Asia Pacific (Thailand) - Asia Pacific (Tokyo) - Asia Pacific (Seoul) - Asia Pacific (Osaka) - South America (Sao Paulo) - China (Beijing) - China (Ningxia) - Canada (Central) - Canada West (Calgary) - Middle East (UAE) - Middle East (Bahrain) - Africa (Cape Town) - US ISO East - US ISOB East (Ohio) - US ISO West - US ISOF East1 (California) - US ISOF South1 (Alpine) - Israel (Tel Aviv) - Mexico (Central) - EU ISOE West The Region of the AWS Key Management Service. Only used in case of Client-side KMS.
Key ID or Key Material Key ID or Key Material For None and Server-side S3: not used. For Server-side KMS and Client-side KMS: the KMS Key ID must be configured. For Server-side Customer Key and Client-side Customer Key: the Key Material must be specified in Base64 encoded form. In case of Server-side Customer Key, the key must be an AES-256 key. In case of Client-side Customer Key, it can be an AES-256, AES-192 or AES-128 key.
Display Name API Name Default Value Allowable Values Description
API Version * API Version 63.0 The version number of the Salesforce REST API appended to the URL after the services/data path. See Salesforce documentation for supported versions.
OAuth2 Access Token Provider * OAuth2 Access Token Provider Service providing OAuth2 Access Tokens for authenticating using the HTTP Authorization Header
Salesforce Instance * Salesforce Instance The hostname of the Salesforce instance including the domain such as MyDomainName.my.salesforce.com
Web Client Service * Web Client Service The Web Client Service to use for communicating with Salesforce
Display Name API Name Default Value Allowable Values Description
Data Cloud Instance Data Cloud Instance The hostname of the Salesforce instance including the domain such as MyDomainName.my.salesforce.com
Data Cloud Token Provider * Data Cloud Token Provider Service providing OAuth2 Access Tokens for authenticating using the HTTP Authorization Header
Web Client Service * Web Client Service The Web Client Service to use for communicating with Salesforce
Display Name API Name Default Value Allowable Values Description
Enable Rate Limiting * Enable Rate Limiting true - true - false Enable or disable rate limiting functionality
Display Name API Name Default Value Allowable Values Description
Keystore Filename Keystore Filename The fully-qualified filename of the Keystore
Keystore Password Keystore Password The password for the Keystore
Keystore Type Keystore Type - BCFKS - PKCS12 - JKS The Type of the Keystore
TLS Protocol SSL Protocol TLS - SSL - TLS - TLSv1.3 - TLSv1.2 - TLSv1.1 - TLSv1 SSL or TLS Protocol Version for encrypted connections. Supported versions include insecure legacy options and depend on the specific version of Java used.
Truststore Filename Truststore Filename The fully-qualified filename of the Truststore
Truststore Password Truststore Password The password for the Truststore
Truststore Type Truststore Type - BCFKS - PKCS12 - JKS The Type of the Truststore
Key Password key-password The password for the key. If this is not specified, but the Keystore Filename, Password, and Type are specified, then the Keystore Password will be assumed to be the same as the Key Password.
Display Name API Name Default Value Allowable Values Description
API Key * API Key Vectara API Key
Customer ID * Customer ID Vectara Customer ID
Display Name API Name Default Value Allowable Values Description
Connect Timeout * Connect Timeout 10 secs Maximum amount of time to wait before failing during initial socket connection
HTTP Protocol Version * HTTP Protocol Version HTTP_2 - HTTP_1_1 - HTTP_2 Preferred HTTP protocol version for requests
Read Timeout * Read Timeout 10 secs Maximum amount of time to wait before failing while reading socket responses
Redirect Handling Strategy * Redirect Handling Strategy FOLLOWED - FOLLOWED - IGNORED Handling strategy for responding to HTTP 301 or 302 redirects received with a Location header
SSL Context Service SSL Context Service SSL Context Service overrides system default TLS settings for HTTPS communication
Write Timeout * Write Timeout 10 secs Maximum amount of time to wait before failing while writing socket requests
Proxy Configuration Service proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Property Description
AWS Credentials Provider service The Controller Service that is used to obtain AWS credentials provider
Communications Timeout
Endpoint Override URL Endpoint URL to use instead of the AWS default including scheme, host, port, and path. The AWS libraries select an endpoint URL based on the AWS region, but this property overrides the selected endpoint URL, allowing use with other S3-compatible endpoints.
JSON Payload JSON request for AWS Machine Learning services. The Processor will use FlowFile content for the request when this property is not specified.
Region
SSL Context Service Specifies an optional SSL Context Service that, if provided, will be used to create connections
Name Description
failure FlowFiles are routed to failure relationship
original Upon successful completion, the original FlowFile will be routed to this relationship.
success FlowFiles are routed to success relationship
Name Description
awsTaskId The task ID that can be used to poll for Job completion in GetAwsPollyJobStatus
Property Description
AWS Credentials Provider service The Controller Service that is used to obtain AWS credentials provider
Communications Timeout
Endpoint Override URL Endpoint URL to use instead of the AWS default including scheme, host, port, and path. The AWS libraries select an endpoint URL based on the AWS region, but this property overrides the selected endpoint URL, allowing use with other S3-compatible endpoints.
JSON Payload JSON request for AWS Machine Learning services. The Processor will use FlowFile content for the request when this property is not specified.
Region
SSL Context Service Specifies an optional SSL Context Service that, if provided, will be used to create connections
Textract Type Supported values: "Document Analysis", "Document Text Detection", "Expense Analysis"
Name Description
failure FlowFiles are routed to failure relationship
original Upon successful completion, the original FlowFile will be routed to this relationship.
success FlowFiles are routed to success relationship
Name Description
awsTaskId The task ID that can be used to poll for Job completion in GetAwsTextractJobStatus
awsTextractType The selected Textract type, which can be used in GetAwsTextractJobStatus
Property Description
AWS Credentials Provider service The Controller Service that is used to obtain AWS credentials provider
Communications Timeout
Endpoint Override URL Endpoint URL to use instead of the AWS default including scheme, host, port, and path. The AWS libraries select an endpoint URL based on the AWS region, but this property overrides the selected endpoint URL, allowing use with other S3-compatible endpoints.
JSON Payload JSON request for AWS Machine Learning services. The Processor will use FlowFile content for the request when this property is not specified.
Region
SSL Context Service Specifies an optional SSL Context Service that, if provided, will be used to create connections
Name Description
failure FlowFiles are routed to failure relationship
original Upon successful completion, the original FlowFile will be routed to this relationship.
success FlowFiles are routed to success relationship
Name Description
awsTaskId The task ID that can be used to poll for Job completion in GetAwsTranscribeJobStatus
Property Description
AWS Credentials Provider service The Controller Service that is used to obtain AWS credentials provider
Communications Timeout
Endpoint Override URL Endpoint URL to use instead of the AWS default including scheme, host, port, and path. The AWS libraries select an endpoint URL based on the AWS region, but this property overrides the selected endpoint URL, allowing use with other S3-compatible endpoints.
JSON Payload JSON request for AWS Machine Learning services. The Processor will use FlowFile content for the request when this property is not specified.
Region
SSL Context Service Specifies an optional SSL Context Service that, if provided, will be used to create connections
Name Description
failure FlowFiles are routed to failure relationship
original Upon successful completion, the original FlowFile will be routed to this relationship.
success FlowFiles are routed to success relationship
Name Description
awsTaskId The task ID that can be used to poll for Job completion in GetAwsTranslateJobStatus
Property Description
gcp-credentials-provider-service The Controller Service used to obtain Google Cloud Platform credentials.
json-payload JSON request for AWS Machine Learning services. The Processor will use FlowFile content for the request when this property is not specified.
output-bucket Name of the GCS bucket where the output of the Vision job will be persisted. The value of this property applies when the JSON Payload property is configured. The JSON Payload property value can use Expression Language to reference the value of $\{output-bucket\}
vision-feature-type Type of GCP Vision Feature. The value of this property applies when the JSON Payload property is configured. The JSON Payload property value can use Expression Language to reference the value of $\{vision-feature-type\}
Name Description
failure FlowFiles are routed to failure relationship
success FlowFiles are routed to success relationship
Name Description
operationKey A unique identifier of the operation returned by the Vision server.
Property Description
gcp-credentials-provider-service The Controller Service used to obtain Google Cloud Platform credentials.
json-payload JSON request for AWS Machine Learning services. The Processor will use FlowFile content for the request when this property is not specified.
output-bucket Name of the GCS bucket where the output of the Vision job will be persisted. The value of this property applies when the JSON Payload property is configured. The JSON Payload property value can use Expression Language to reference the value of $\{output-bucket\}
vision-feature-type Type of GCP Vision Feature. The value of this property applies when the JSON Payload property is configured. The JSON Payload property value can use Expression Language to reference the value of $\{vision-feature-type\}
Name Description
failure FlowFiles are routed to failure relationship
success FlowFiles are routed to success relationship
Name Description
operationKey A unique identifier of the operation returned by the Vision server.
Property Description
Column Delimiter The column delimiter used for CSV job data.
Configuration Mode The configuration mode for configuring this processor. If using advanced mode, the SOQL query has to be provided and the processor 's state will only store the timestamp of the last query job submission regardless of the object queried. If using simple mode, the object name and the fields to be queried have to be provided and the processor's state will store the timestamp of the last query job submission for each object queried.
Incremental Offload Whether the processor should perform incremental offload. If true, the processor will only fetch the records that have been modified since the last query job submission by using a WHERE clause on the SystemModstamp field.
Line Ending The line ending used for CSV job data, marking the end of a data row.
Object Fields Comma separated list of the name of the fields to be queried for the specified object.
Object Name The name of the object to be queried.
Operation The type of query to submit.
Query The query to be performed. In order to perform incremental retrieval (ie. only the added/modified/deleted elements since the last submission of the query are retrieved), this processor exposes two attributes: $\{nowTs\} and $\{lastJobTimestamp\}. It is possible to use those placeholders like SELECT Id FROM Account WHERE SystemModstamp > $\{lastJobTimestamp\} AND SystemModstamp <= $\{nowTs\}.
Result Format The format to be used for the results. Currently the only supported value is CSV.
Salesforce Bulk Job State Service Controller Service to store Bulk Jobs state per object type (used in SIMPLE mode). In ADVANCED mode, the processor stores a single 'last' timestamp in processor state.
Salesforce Client Salesforce Client to interact with the APIs
Scopes Description
CLUSTER In case the placeholders for incremental retrieval are used in the query field, the timestamp of the last Query Job submission time minus 30 seconds will be stored in the state.
Name Description
comms.failure An incoming FlowFile is routed to this relationship if the Query Job could not be submitted but the operation might be retried
failure An incoming FlowFile is routed to this relationship if the Query Job could not be submitted
in.progress An incoming FlowFile is routed to this relationship when a previous job for the same object is still IN_PROGRESS
success When a Query Job is successfully submitted, a FlowFile is routed to this relationship
Name Description
jobId The unique ID for this job.
operationType The type of query.
objectType The object type being queried.
createdById The ID of the user who created the job.
createdDate The UTC date and time when the job was created.
systemModstamp The UTC date and time when the API last updated the job information.
jobState The current state of processing for the job.
concurrencyMode How the request is processed.
contentType The format to be used for the results.
apiVersion The API version that the job was created in.
lineEnding The line ending used for CSV job data, marking the end of a data row.
columnDelimiter The column delimiter used for CSV job data.
nowTs Upper limit of the time range used in the WHERE close to construct the Query Job.
lastJobTimestamp Lower limit of the time range used in the WHERE close to construct the Query Job.
Property Description
Content The content to be summarized. FlowFile attributes may be referenced via Expression Language, and the contents of the FlowFile may be referenced via the flowfile_content variable. E.g., $\{flowfile_content\}
LLM Provider Service The provider service for sending evaluation prompts to LLM
Max File Size The maximum size of a FlowFile that can be summarized. If the FlowFile is larger than this, it will be routed to 'failure'.
Output Strategy Determines response output destination
Results Attribute The name of the attribute to write the response to.
Name Description
failure FlowFiles that cannot be processed are routed to this relationship
success FlowFiles that are successfully processed are routed to this relationship
Display Name API Name Default Value Allowable Values Description
Character Set * Character Set UTF-8 Specifies which character set of the Syslog messages
Raw message * syslog-5424-reader-raw-message false - true - false If true, the record will have a _raw field containing the raw message
Display Name API Name Default Value Allowable Values Description
Character Set * Character Set UTF-8 Specifies which character set of the Syslog messages
Raw message * syslog-5424-reader-raw-message false - true - false If true, the record will have a _raw field containing the raw message
Property Description
AWS Credentials Provider service The Controller Service that is used to obtain AWS credentials provider
Append Tag If set to true, the tag will be appended to the existing set of tags on the S3 object. Any existing tags with the same key as the new tag will be updated with the specified value. If set to false, the existing tags will be removed and the new tag will be set on the S3 object.
Bucket The S3 Bucket to interact with
Communications Timeout The amount of time to wait in order to establish a connection to AWS or receive data from AWS before timing out.
Custom Signer Class Name Fully qualified class name of the custom signer class. The signer must implement com.amazonaws.auth. Signer interface.
Custom Signer Module Location Comma-separated list of paths to files and/or directories which contain the custom signer's JAR file and its dependencies (if any).
Endpoint Override URL Endpoint URL to use instead of the AWS default including scheme, host, port, and path. The AWS libraries select an endpoint URL based on the AWS region, but this property overrides the selected endpoint URL, allowing use with other S3-compatible endpoints.
Object Key The S3 Object Key to use. This is analogous to a filename for traditional file systems.
Region The AWS Region to connect to.
SSL Context Service Specifies an optional SSL Context Service that, if provided, will be used to create connections
Signer Override The AWS S3 library uses Signature Version 4 by default but this property allows you to specify the Version 2 signer to support older S3-compatible services or even to plug in your own custom signer implementation.
Tag Key The key of the tag that will be set on the S3 Object
Tag Value The value of the tag that will be set on the S3 Object
Version The Version of the Object to tag
proxy-configuration-service Specifies the Proxy Configuration Controller Service to proxy network requests.
Name Description
failure If the Processor is unable to process a given FlowFile, it will be routed to this Relationship.
success FlowFiles are routed to this Relationship after they have been successfully processed.
Name Description
s3.tag.___ The tags associated with the S3 object will be written as part of the FlowFile attributes
s3.exception The class name of the exception thrown during processor execution
s3.additionalDetails The S3 supplied detail from the failed operation
s3.statusCode The HTTP error code (if available) from the failed operation
s3.errorCode The S3 moniker of the failed operation
s3.errorMessage The S3 exception message from the failed operation
Property Description
File Location Specifies where the state is located either local or cluster so that state can be stored appropriately in order to ensure that all data is consumed without duplicating data upon restart of NiFi
File to Tail Path of the file to tail in case of single file mode. If using multifile mode, regular expression to find files to tail in the base directory. In case recursivity is set to true, the regular expression will be used to match the path starting from the base directory (see additional details for examples).
Initial Start Position When the Processor first begins to tail data, this property specifies where the Processor should begin reading data. Once data has been ingested from a file, the Processor will continue from the last point from which it has received data.
Line Start Pattern A Regular Expression to match against the start of a log line. If specified, any line that matches the expression, and any following lines, will be buffered until another line matches the Expression. In doing this, we can avoid splitting apart multi-line messages in the file. This assumes that the data is in UTF-8 format.
Max Buffer Size When using the Line Start Pattern, there may be situations in which the data in the file being tailed never matches the Regular Expression. This would result in the processor buffering all data from the tailed file, which can quickly exhaust the heap. To avoid this, the Processor will buffer only up to this amount of data before flushing the buffer, even if it means ingesting partial data from the file.
Post-Rollover Tail Period When a file is rolled over, the processor will continue tailing the rolled over file until it has not been modified for this amount of time. This allows for another process to rollover a file, and then flush out any buffered data. Note that when this value is set, and the tailed file rolls over, the new file will not be tailed until the old file has not been modified for the configured amount of time. Additionally, when using this capability, in order to avoid data duplication, this period must be set longer than the Processor's Run Schedule, and the Processor must not be stopped after the file being tailed has been rolled over and before the data has been fully consumed. Otherwise, the data may be duplicated, as the entire file may be written out as the contents of a single FlowFile.
Rolling Filename Pattern If the file to tail "rolls over" as would be the case with log files, this filename pattern will be used to identify files that have rolled over so that if NiFi is restarted, and the file has rolled over, it will be able to pick up where it left off. This pattern supports wildcard characters * and ?, it also supports the notation $\{filename\} to specify a pattern based on the name of the file (without extension), and will assume that the files that have rolled over live in the same directory as the file being tailed. The same glob pattern will be used for all files.
pre-allocated-buffer-size Sets the amount of memory that is pre-allocated for each tailed file.
reread-on-nul If this option is set to 'true', when a NUL character is read, the processor will yield and try to read the same part again later. (Note: Yielding may delay the processing of other files tailed by this processor, not just the one with the NUL character.) The purpose of this flag is to allow users to handle cases where reading a file may return temporary NUL values. NFS for example may send file contents out of order. In this case the missing parts are temporarily replaced by NUL values. CAUTION! If the file contains legitimate NUL values, setting this flag causes this processor to get stuck indefinitely. For this reason users should refrain from using this feature if they can help it and try to avoid having the target file on a file system where reads are unreliable.
tail-base-directory Base directory used to look for files to tail. This property is required when using Multifile mode.
tail-mode Mode to use: single file will tail only one file, multiple file will look for a list of file. In Multiple mode the Base directory is required.
tailfile-lookup-frequency Only used in Multiple files mode. It specifies the minimum duration the processor will wait before listing again the files to tail.
tailfile-maximum-age Only used in Multiple files mode. It specifies the necessary minimum duration to consider that no new messages will be appended in a file regarding its last modification date. This should not be set too low to avoid duplication of data in case new messages are appended at a lower frequency.
tailfile-recursive-lookup When using Multiple files mode, this property defines if files must be listed recursively or not in the base directory.
Scopes Description
LOCAL Stores state about where in the Tailed File it left off so that on restart it does not have to duplicate data. State is stored either local or clustered depend on the <File Location> property.
CLUSTER Stores state about where in the Tailed File it left off so that on restart it does not have to duplicate data. State is stored either local or clustered depend on the <File Location> property.
Required Permission Explanation
read filesystem Provides operator the ability to read from any file that NiFi has access to.
Name Description
success All FlowFiles are routed to this Relationship.
Name Description
tailfile.original.path Path of the original file the flow file comes from.
Property Description
XSLT file name Provides the name (including full path) of the XSLT file to apply to the FlowFile XML content. One of the 'XSLT file name' and 'XSLT Lookup' properties must be defined.
cache-size Maximum number of stylesheets to cache. Zero disables the cache.
cache-ttl-after-last-access The cache TTL (time-to-live) or how long to keep stylesheets in the cache after last access.
indent-output Whether or not to indent the output.
secure-processing Whether or not to mitigate various XML-related attacks like XXE (XML External Entity) attacks.
xslt-controller Controller lookup used to store XSLT definitions. One of the 'XSLT file name' and 'XSLT Lookup' properties must be defined. WARNING: note that the lookup controller service should not be used to store large XSLT files.
xslt-controller-key Key used to retrieve the XSLT definition from the XSLT lookup controller. This property must be set when using the XSLT controller property.
Name Description
failure If a FlowFile fails processing for any reason (for example, the FlowFile is not valid XML), it will be routed to this relationship
success The FlowFile with transformed content will be routed to this relationship
; ``` If `total_rows` differs from `distinct_keys`, the columns aren't suitable as a logical key. 2. Correct the key configuration (choose columns that are unique, or add a primary key to the table) and run a full reload for the affected table to reconcile the destination. To avoid this issue, verify uniqueness before declaring a logical key. On large tables, consider running the verification query during a low-traffic window or sampling with a `WHERE` clause. ## No changes in incremental load The incremental load isn't capturing or applying changes from the source database. **Solution** Run the verification for the **Read Oracle CDC Stream** processor: 1. In your Openflow runtime, double-click the **Oracle** flow. 2. Double-click the process group named **Incremental Load**. 3. Find the **Read Oracle CDC Stream** processor. 1. If it is running, right-click and select **Stop**. The processor must be stopped before you can verify its configuration. 4. Right-click **Read Oracle CDC Stream** again, then select **Configure**. 5. Select the **Properties** tab. 6. Select the **Verification** checkmark icon in the upper-right corner. 7. In the popup window that appears, select **Verify** in the lower-right corner. The results of the verification procedure appear below. The procedure validates database connectivity and checks the status of the components required for incremental load to work. If any of the verification steps fail, view the error message, fix the issue, and run the verification again. The following sections describe specific issues and solutions. ## The connector stops reading changes after a network interruption with no errors The **Read Oracle CDC Stream** processor stops producing data but reports no errors. The processor appears to be running, yet no new changes are ingested, and it recovers only after the runtime is restarted. This occurs only when the connection to the Oracle database is dropped silently and no read timeout is configured: for example, a firewall or load balancer that drops an idle connection without notifying either side. The connector keeps waiting to read from a connection that is no longer alive, with no error to trigger a reconnect. Interruptions that close the connection cleanly surface an error and the connector recovers on its own. **Solution** Configure read timeouts on both connection URLs in `Oracle Source Parameters`. The following examples use a 5-minute timeout: - `Oracle Connection URL` (thin driver): add the `oracle.jdbc.ReadTimeout` property (in milliseconds) to the URL query string. You can use either URL form: - Easy Connect: `jdbc:oracle:thin:@//:/DB?oracle.jdbc.ReadTimeout=300000` - TNS connect descriptor: `jdbc:oracle:thin:@(DESCRIPTION=(ADDRESS=...)(CONNECT_DATA=...))?oracle.jdbc.ReadTimeout=300000` - `XStream Out Server URL` (OCI driver): add the `RECV_TIMEOUT` parameter (in seconds) inside the TNS connect descriptor. The OCI driver honors `RECV_TIMEOUT` only in the TNS connect descriptor form, not in the short Easy Connect form: - TNS connect descriptor: `jdbc:oracle:oci:@(DESCRIPTION=(RECV_TIMEOUT=300)(ADDRESS=...)(CONNECT_DATA=...))` With these timeouts set, a dropped connection surfaces an error instead of hanging, and the connector reconnects automatically. The error depends on which connection times out: `ORA-12609: TNS: Receive timeout occurred` for the `XStream Out Server URL` (OCI driver), or `ORA-18730: Socket read timed out` for the `Oracle Connection URL` (thin driver). ## Capture Status not ENABLED The capture process status is `DISABLED` or `ABORTED`. A `DISABLED` status means the capture process was stopped manually (with `DBMS_XSTREAM_ADM.STOP_OUTBOUND`) or the database was restarted. An `ABORTED` status means the capture encountered an error, usually because redo logs needed for the capture process have been deleted. You can confirm this by checking the System Change Number (SCN) position or querying the capture status. **Solution** Start the outbound server: ```sql BEGIN DBMS_XSTREAM_ADM.START_OUTBOUND('XOUT1'); END; / ``` ## UNKNOWN status of LogMiner session The LogMiner status is `UNKNOWN`, which means that archived logs that LogMiner depended on were deleted. You can confirm this by querying `V$ARCHIVED_LOG` and checking for rows where the DELETED column has the value `YES`. **Solution** Recreate the XStream outbound server. For more information, see [](#label-recreate-xstream-outbound-server). ## WAITING FOR REDO status of XStream capture The XStream capture status shows `WAITING FOR REDO: FILE NA, THREAD 1, SEQUENCE 47, SCN 0x0000000000190ac4`. This means LogMiner is waiting for an archived log file that isn't available because it was deleted. You can confirm this by querying `V$ARCHIVED_LOG` and checking for rows where the DELETED column has the value `YES`. **Solution** Recreate the XStream outbound server. For more information, see [](#label-recreate-xstream-outbound-server). ## XStream capture rules are incorrect XStream isn't configured to capture changes from the expected schemas or tables. **Solution** Verify the capture rules by running the following query: ```sql SELECT STREAMS_NAME, SCHEMA_NAME, OBJECT_NAME, RULE_TYPE FROM DBA_XSTREAM_RULES WHERE STREAMS_NAME = 'XOUT1'; ``` You can also query the capture status and error message directly: ```sql SELECT CLIENT_NAME, STATUS, ERROR_MESSAGE FROM ALL_CAPTURE; ``` This query returns: - `CLIENT_NAME`: The name of the XStream client (outbound server). - `STATUS`: The current status of the capture process (for example, `ENABLED`, `DISABLED`, `ABORTED`). - `ERROR_MESSAGE`: Any error message associated with the capture process. ## Error ORA-21560: argument last_position is null, invalid, or out of range The connector attempted to connect to an SCN position for which redo logs are no longer available. **Solution** Confirm the issue by running the following query. The SCN for `Last SCN processed by XStream` must be higher than the lowest SCN for which redo logs exist. ```sql SELECT min(FIRST_CHANGE#) as SCN, 'Lowest SCN for which redo logs still exist' AS DESCRIPTION FROM V$ARCHIVED_LOG WHERE DELETED = 'NO' UNION ALL SELECT PROCESSED_LOW_SCN, 'Last SCN processed by XStream' FROM DBA_XSTREAM_OUTBOUND_PROGRESS WHERE SERVER_NAME = 'XOUT1' ORDER BY SCN; ``` To recover from this error, recreate the XStream outbound server. For more information, see [](#label-recreate-xstream-outbound-server). ## Error ORA-26701: Streams process XOUT1 does not exist The XStream outbound server can't be found on the database instance. **Solution** Verify the following: - The database name in `Oracle Source Parameters` %ra% `XStream Out Server URL` points to the database instance with the XStream outbound server, not a different PDB. - XStream has been created on this instance and has the same name. ## Insufficient privileges error in an Oracle RAC environment The connector reports an insufficient privileges error even though the Oracle user has the required permissions. In an Oracle RAC environment, this can happen when the connection is routed to a node that doesn't host the XStream outbound server. To confirm, first check which RAC instance the connector is connected to. You can run this query directly from the Openflow UI by adding a temporary **ExecuteSQL** processor that uses the same JDBC connection as the connector, then comparing the result with the same query run on the Oracle server. This `SYS_CONTEXT` check only tells you which node the connector landed on; the `V$` vs `GV$` check further down confirms which node XStream actually runs on: ```sql SELECT SYS_CONTEXT('USERENV', 'INSTANCE_NAME') AS instance_name, SYS_CONTEXT('USERENV', 'INSTANCE') AS instance_number, SYS_CONTEXT('USERENV', 'SERVER_HOST') AS host_name, SYS_CONTEXT('USERENV', 'SERVICE_NAME') AS service_name FROM DUAL; ``` If the values differ between the two, the connector is connecting to a different node than expected. Alternatively, run the following queries directly on the Oracle node that the runtime is connected to. Query the local view, which returns a row only on the node hosting the XStream capture process: ```sql SELECT STATE FROM V$XSTREAM_CAPTURE WHERE CAPTURE_NAME = (SELECT CAPTURE_NAME FROM DBA_CAPTURE WHERE CLIENT_NAME = 'XOUT1'); ``` Query the global view, which spans all RAC nodes: ```sql SELECT STATE, INST_ID FROM GV$XSTREAM_CAPTURE WHERE CAPTURE_NAME = (SELECT CAPTURE_NAME FROM DBA_CAPTURE WHERE CLIENT_NAME = 'XOUT1'); ``` If `GV$XSTREAM_CAPTURE` returns a row but `V$XSTREAM_CAPTURE` returns nothing, the XStream outbound server is running on a different RAC node than the one the connector is connected to. Querying `GV$` views requires `SELECT ANY DICTIONARY` or an explicit grant on the view. If the query returns a privileges error, ask your DBA to grant the privilege or run the query as a DBA. **Solution** Use Oracle Connection Manager (CMAN) as a proxy between the connector and the Oracle RAC cluster. CMAN routes connections to the correct RAC node transparently and supports failover. Update both `Oracle Connection URL` and `XStream Out Server URL` in `Oracle Source Parameters` to point to your CMAN host and port. ## Error ORA-16224: Database Guard is enabled Connecting to or reading from the XStream outbound server fails with: ``` oracle.streams.StreamsException: ORA-16224: Database Guard is enabled ``` This error occurs on a logical standby when Database Guard is set to `ALL` (the default). With that setting, the XStream client can't read the outbound server. **Solution** On the logical standby, set Database Guard to `STANDBY`: ```sql ALTER DATABASE GUARD STANDBY; ``` For more information, see [](/user-guide/data-integration/openflow/connectors/oracle/setup-oracledb#label-oracle-logical-standby-requirements). ## Error ORA-01722: invalid number when creating the outbound server Executing `DBMS_XSTREAM_ADM.CREATE_OUTBOUND` fails with: ```sql ORA-01722: invalid number ORA-06512: at "SYS.DBMS_LOGREP_UTIL", line 582 ORA-06512: at "SYS.DBMS_LOGREP_UTIL", line 636 ORA-06512: at "SYS.DBMS_XSTREAM_ADM_UTL", line 440 ORA-06512: at "SYS.DBMS_XSTREAM_UTL_IVK", line 2094 ORA-06512: at "SYS.DBMS_XSTREAM_UTL_IVK", line 2302 ORA-06512: at "SYS.DBMS_XSTREAM_ADM", line 44 ORA-06512: at line 8 ``` This error is misleading. The outbound server already exists. **Solution** No action is needed. Use the existing outbound server. ## Problems occur with the XStream outbound server Multiple issues, such as deleted redo logs or corrupted LogMiner state, can be resolved by recreating the XStream outbound server. **Solution** 1. Drop the existing outbound server: ```sql BEGIN DBMS_XSTREAM_ADM.DROP_OUTBOUND('XOUT1'); END; / ``` 2. Create the outbound server again. For more information, see [](#label-create-xstream-outbound-server). --- title: Troubleshooting the Openflow Connector for Salesforce Bulk API source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/troubleshoot.md section: Loading & Unloading Data --- # Troubleshooting the %salesforcebulkapiof% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About the Openflow Connector for Salesforce Bulk API](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/about) - [Openflow Connector for Salesforce Bulk API: Set up Snowflake](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/setup-snowflake) - [Openflow Connector for Salesforce Bulk API: Set up Salesforce](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/setup-salesforce) - [Openflow Connector for Salesforce Bulk API: Configure the connector](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/configure-connector) - [Monitor the Openflow Connector for Salesforce Bulk API](/user-guide/data-integration/openflow/connectors/salesforce-bulk-api/monitor) This topic describes how to troubleshoot the %salesforcebulkapiof%. Use the following information to troubleshoot issues with the connector. ## Authentication and OAuth errors The connector uses the OAuth 2.0 JWT Bearer Flow to authenticate with Salesforce. Authentication errors typically occur during initial setup and can be diagnosed using the [Verification feature](#salesforce-verify-connection) on the controller service before starting the connector. ### `invalid_grant` error The `invalid_grant` error indicates that Salesforce rejected the OAuth token request. Common causes include: - **Wrong OAuth flow type.** The external client app in Salesforce does not have the **Enable JWT Bearer Flow** checkbox selected. The connector requires this specific flow. Other OAuth flows (such as Authorization Code Flow) are not supported. See [](#salesforce-create-external-client-app). - **Mismatched private key and certificate.** The private key configured in the connector (the **Connected App Key** parameter) does not match the public certificate uploaded to the external client app in Salesforce. - **Wrong Consumer Key.** The **OAuth2 Client ID** parameter does not match the **Consumer Key** of the external client app where the certificate was uploaded. - **Mixed credentials from multiple apps.** If you have created multiple external client apps or experimented with different configurations, the Client ID, certificate, and private key might belong to different apps. All three must come from the same external client app. - **Deprecated Connected App.** Salesforce has deprecated Connected Apps in favor of External Client Apps. If you are using a Connected App, Snowflake recommends creating a new external client app instead. - **Incorrect token endpoint URL.** The **OAuth2 Token Endpoint URL** parameter must point to the correct Salesforce instance. For example: `https://myCompany.my.salesforce.com/services/oauth2/token`. - **Incorrect audience.** The **OAuth2 Audience** parameter must be set to `https://login.salesforce.com` for production environments or `https://test.salesforce.com` for sandboxes and test environments. ### Permission errors If the JWT token is successfully generated but the user lacks permissions, you see a permission or authorization error. This means the JWT Bearer Flow is working, but the Salesforce user (the OAuth2 Subject) is not authorized to use the external client app. To resolve this issue: 1. In Salesforce, go to the **Policies** tab of the external client app. 2. Verify that **Permitted Users** is set to **Admin approved users are pre-authorized**. 3. Verify that the profiles or permission sets assigned in the **App Policies** section include the user specified in the **OAuth2 Subject** parameter of the connector. For more details, see [](#salesforce-approve-client-app). ## Check the connector state You can examine the connector state to ensure that data is being replicated as expected. The connector maintains a state of current and past operations to ensure no Salesforce changes are missed and to retry bulk job queries if failures occur. To view the state: 1. Right-click on the canvas and select **Controller services**. 2. Locate the controller service named **Salesforce Bulk Jobs State**. 3. In the **Salesforce Bulk Jobs State** menu, click **View state**. The state is a set of key/value pairs where the key is the Salesforce Object type. For example, the state for the `Account` object might look like the following example: ```json {"previousLast":"2025-09-30T09:41:23.484406926Z","currentLast":"2025-09-30T09:41:23.484406926Z","status":"COMPLETED"} ``` The `status` can be one of the following: - `IN_PROGRESS` - `COMPLETED` - `FAILED` - `ABORTED` If the status is `IN_PROGRESS`, a FlowFile is still being processed for that object type. Do not delete FlowFiles manually. This can cause a job to remain in the `IN_PROGRESS` status indefinitely because the state cannot be manually updated. If this occurs, you must perform a full reload for that object type. ## Force a full load for a given object type To force the connector to perform a full refresh for one or more object types: 1. Stop all processors in the flow. 2. Ensure that no in-flight FlowFiles are being processed. 3. Right-click on the canvas and select **Disable all controller services**. 4. Go to **Controller services** and open the state of the controller service named **Salesforce Bulk Jobs State**. 5. Perform one of the following actions: - Select **Clear state** to clear the entire state. This forces a full load for **all** configured Object types fetched by the connector. - Select the trash icon next to a specific Object type to clear the state for a specific object type only. This forces a full load of that specific object type during the next execution of the connector. 6. In the canvas, right-click, select **Enable all controller services**, and then start all processors. ## If an object type remains in status IN_PROGRESS If the state for a given object type is stuck in `IN_PROGRESS` and there are no in-flight FlowFiles for that object type, a FlowFile may have been manually deleted before it could update the status. In this case, you must perform a full load for that object type to ensure the connector captures all events. If the state is stuck in `IN_PROGRESS` but no FlowFiles were manually deleted, contact [Snowflake Support](/user-guide/contacting-support). --- title: UDPEventRecordSink source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/udpeventrecordsink.md section: Loading & Unloading Data --- # UDPEventRecordSink This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Format and send Records as UDP Datagram Packets to a configurable destination ## Tags UDP, event, record, sink ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: UnpackContent 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/unpackcontent.md section: Loading & Unloading Data --- # UnpackContent 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Unpacks the content of FlowFiles that have been packaged with one of several different Packaging Formats, emitting one to many FlowFiles for each input FlowFile. Supported formats are TAR, ZIP, and FlowFile Stream packages. ## Tags Unpack, archive, flowfile-stream, flowfile-stream-v3, tar, un-merge, zip ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## Use cases | Unpack Zip containing filenames with special characters, created on Windows with filename charset 'Cp437' or 'IBM437'. | | ---------------------------------------------------------------------------------------------------------------------- | ## See also - [org.apache.nifi.processors.standard.MergeContent](/user-guide/data-integration/openflow/processors/mergecontent) --- title: UpdateAttribute 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/updateattribute.md section: Loading & Unloading Data --- # UpdateAttribute 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-update-attribute-nar ## Description Updates the Attributes for a FlowFile by using the Attribute Expression Language and/or deletes the attributes based on a regular expression ## Tags Attribute Expression Language, attributes, delete, modification, state, update ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## State management
## Relationships
## Writes attributes
## Use cases | Add a new FlowFile attribute | | ----------------------------------------------- | | Overwrite a FlowFile attribute with a new value | | Rename a file | --- title: UpdateBoxFileMetadataInstance 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/updateboxfilemetadatainstance.md section: Loading & Unloading Data --- # UpdateBoxFileMetadataInstance 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-box-nar ## Description Updates metadata template values for a Box file using the record in the given flowFile. This record represents the desired end state of the template after the update. The processor will calculate the necessary changes (add/replace/remove) to transform the current metadata to the desired state. The input record should be a flat key-value object. ## Tags box, metadata, storage, templates, update ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.box.FetchBoxFile](/user-guide/data-integration/openflow/processors/fetchboxfile) - [org.apache.nifi.processors.box.ListBoxFile](/user-guide/data-integration/openflow/processors/listboxfile) - [org.apache.nifi.processors.box.ListBoxFileMetadataTemplates](/user-guide/data-integration/openflow/processors/listboxfilemetadatatemplates) --- title: UpdateBulkJobState 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/updatebulkjobstate.md section: Loading & Unloading Data --- # UpdateBulkJobState 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-salesforce-processors-nar ## Description Updates the status of a Salesforce Bulk Job in the shared state service for a specific object type ## Tags bulk, preview, salesforce, state ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: UpdateByQueryElasticsearch 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/updatebyqueryelasticsearch.md section: Loading & Unloading Data --- # UpdateByQueryElasticsearch 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-elasticsearch-restapi-nar ## Description Update documents in an Elasticsearch index using a query. The query can be loaded from a flowfile body or from the Query parameter. The loaded Query can contain any JSON accepted by Elasticsearch's _update_by_query API, for example a "query" object to identify what documents are to be updated, plus a "script" to define the updates to perform. ## Tags elastic, elasticsearch, elasticsearch7, elasticsearch8, elasticsearch9, query, update ## Input Requirement ALLOWED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: UpdateCounter 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/updatecounter.md section: Loading & Unloading Data --- # UpdateCounter 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description This processor allows users to set specific counters and key points in their flow. It is useful for debugging and basic counting functions. ## Tags counter, debug, instrumentation ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: UpdateDatabaseTable 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/updatedatabasetable.md section: Loading & Unloading Data --- # UpdateDatabaseTable 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description This processor uses a JDBC connection and incoming records to generate any database table changes needed to support the incoming records. It expects a 'flat' record layout, meaning none of the top-level record fields has nested fields that are intended to become columns themselves. ## Tags alter, database, jdbc, metadata, table, update ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: UpdateRecord 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/updaterecord.md section: Loading & Unloading Data --- # UpdateRecord 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Updates the contents of a FlowFile that contains Record-oriented data (i.e., data that can be read via a RecordReader and written by a RecordWriter). This Processor requires that at least one user-defined Property be added. The name of the Property should indicate a RecordPath that determines the field that should be updated. The value of the Property is either a replacement value (optionally making use of the Expression Language) or is itself a RecordPath that extracts a value from the Record. Whether the Property value is determined to be a RecordPath or a literal value depends on the configuration of the <Replacement Value Strategy> Property. ## Tags avro, csv, freeform, generic, json, log, logs, record, schema, text, update ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## Use cases | Combine multiple fields into a single field. | | -------------------------------------------------------------------- | | Change the value of a record field to an explicit value. | | Copy the value of one record field to another record field. | | Enrich data by injecting the value of an attribute into each Record. | | Change the format of a record field's value. | ## See also - [org.apache.nifi.processors.standard.ConvertRecord](/user-guide/data-integration/openflow/processors/convertrecord) --- title: UpdateSnowflakeDatabase 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/updatesnowflakedatabase.md section: Loading & Unloading Data --- # UpdateSnowflakeDatabase 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-snowflake-processors-nar ## Description Updates the definition of a Snowflake table based on the schema provided in the incoming FlowFile. The schema is expected to be in JSON with the following format, regardless of whether it is provided via FlowFile content or specified as a property: \{ "columns": [ \{ "name": "<column name>", "type": "<column type>", "nullable": <true/false>, "precision": <precision, only for numeric type>, "scale": <scale, only for numeric type> \}, ... ], "primaryKeys": ["<name of first primary key column>", "<name of second primary key column>", ...] \} ## Tags ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: UpdateSnowflakeIcebergDatabase 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/updatesnowflakeicebergdatabase.md section: Loading & Unloading Data --- # UpdateSnowflakeIcebergDatabase 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-snowflake-processors-nar ## Description Updates the definition of a Snowflake Iceberg table. A target schema can be inferred from a RecordReader or defined explicitly using the format below: \{ "columns": [ \{ "name": "<column name>", "type": "<iceberg data type>" \}, ... ] \} where <iceberg data type> can be one of: - primitive iceberg type ("string", "int", "boolean",...) - decimal with given precision and scale ("decimal(P,S)") - \{"type": "list", "element": <iceberg data type>\} - \{"type": "map", "key": <iceberg data type>, "value": <iceberg data type>\} - \{"type": "struct", "fields":[<list of struct fields>] \} ## Tags iceberg ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: UpdateSnowflakeSchema 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/updatesnowflakeschema.md section: Loading & Unloading Data --- # UpdateSnowflakeSchema 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-snowflake-processors-nar ## Description Creates Snowflake database schema if it does not exist. ## Tags create, ddl, preview, schema, snowflake ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: UpdateSnowflakeStream 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/updatesnowflakestream.md section: Loading & Unloading Data --- # UpdateSnowflakeStream 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-snowflake-processors-nar ## Description Manages Snowflake streams by creating, dropping, or replacing them based on the configured operation. Streams in Snowflake capture data change for tables and can be used to track DML changes over time. ## Tags cdc, create, drop, preview, replace, snowflake, stream, table ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: UpdateSnowflakeTable 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/updatesnowflaketable.md section: Loading & Unloading Data --- # UpdateSnowflakeTable 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-snowflake-processors-nar ## Description Updates the definition of a Snowflake table based on the schema provided in the incoming FlowFile. The schema is expected to be in JSON with the following format, regardless of whether it is provided via FlowFile content or specified as a property: \{ "columns": [ \{ "name": "<column name>", "type": "<column type>", "nullable": <true/false>, "precision": <only for numeric type>, "scale": <only for numeric type> \}, ... ], "primaryKeys": ["<name of first primary key column>", "<name of second primary key column>", ...] \} This processor supports table-only operations: creating, altering, and dropping tables. ## Tags alter, columns, create, ddl, drop, preview, snowflake, table, update ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: UpdateSnowflakeView 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/updatesnowflakeview.md section: Loading & Unloading Data --- # UpdateSnowflakeView 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-snowflake-processors-nar ## Description Creates or replaces Snowflake views based on column mappings provided in the incoming FlowFile. The processor checks if the view exists and only recreates it if the definition has changed. The FlowFile content should contain JSON with column mappings, optional join configuration, and optional flatten configuration: \{ "columns": [ \{ "source_field": "customer_data:id", "destination_column": "customer_id", "type": "VARCHAR" \}, \{ "source_field": "f.value:order_amount", "destination_column": "order_amount", "type": "NUMBER" \}, \{ "expression": "SUM(f.value:order_amount::NUMBER)", "destination_column": "total_amount" \}, \{ "expression": "COUNT(*)", "destination_column": "order_count" \} ], "from": \{ "table": "raw_data", "alias": "rd", "joins": [ \{ "type": "INNER", "table": "customers", "alias": "c", "on": "customer_data:id::VARCHAR = c.customer_id" \} ] \}, "flatten": [ \{ "input": "rd.orders", "alias": "f", "path": null \} ], "where": "active = true AND status ='VALID'", "group_by": ["customer_id", "region"], "order_by": ["order_amount DESC", "customer_id ASC"] \} Column configuration supports: - source_field: Simple field/column reference (supports JSON notation like "data:field" or table aliases like "t.column") - expression: Complex SQL expression (e.g., "SUM(amount)", "COUNT(*)") - destination_column: The output column name in the view (optional - auto-generated if not provided) - type: Snowflake data type for automatic type casting (VARCHAR, NUMBER, BOOLEAN, DATE, TIMESTAMP, etc.) Use either source_field OR expression, not both. When type is specified, automatic type casting is applied. When type is omitted, the expression is used as-is without casting. Flatten configuration supports: - input: The nested field/column to flatten (required) - alias: Alias for the flattened data (required) - path: Optional path within the nested structure The "from" section is required and specifies the source table and optional joins. Optional SQL clauses can be included: - where: WHERE clause condition (e.g., "active = true AND status ='VALID'") - group_by: GROUP BY clause as an array of column names (e.g., ["customer_id", "region"]) - order_by: ORDER BY clause as an array of column/expression with direction (e.g., ["order_amount DESC", "customer_id ASC"]) ## Tags flatten, view ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: UpdateTableState 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/updatetablestate.md section: Loading & Unloading Data --- # UpdateTableState 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-database-cdc-processors-nar ## Description Updates the state of a table in the Table State Service ## Tags snowflake, state, table ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: UpsertMilvus 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/upsertmilvus.md section: Loading & Unloading Data --- # UpsertMilvus 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-milvus-processors-nar ## Description Upserts vectors into Milvus database for a given collection ## Tags chatbot, embeddings, gen ai, genai, generative ai, insert, llm, metadata, milvus, openflow, publish, text, upsert, vector ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## See also - [com.snowflake.openflow.runtime.processors.milvus.DeleteMilvus](/user-guide/data-integration/openflow/processors/deletemilvus) --- title: UpsertPinecone 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/upsertpinecone.md section: Loading & Unloading Data --- # UpsertPinecone 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-pinecone-nar ## Description Publishes vectors, including metadata, and optionally text, to a Pinecone index. ## Tags chatbot, embeddings, gen ai, genai, generative ai, llm, metadata, openflow, pinecone, publish, text, upsert, vector ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Use Cases Involving Other Components | Create embeddings for raw text data, or text that exists in a Record field such as JSON, using OpenAI's embeddings model and publish the vectors to Pinecone. | | ------------------------------------------------------------------------------------------------------------------------------------------------------------- | | Add embeddings for a document to a Pinecone index, replacing any embeddings that already exist for the document. | ## See also - [com.snowflake.openflow.runtime.processors.openai.CreateOpenAiEmbeddings](/user-guide/data-integration/openflow/processors/createopenaiembeddings) - [com.snowflake.openflow.runtime.processors.pinecone.DeletePinecone](/user-guide/data-integration/openflow/processors/deletepinecone) --- title: UpsertSFDCObjects 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/upsertsfdcobjects.md section: Loading & Unloading Data --- # UpsertSFDCObjects 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-salesforce-processors-nar ## Description Upserts the records from the incoming FlowFile into Salesforce ## Tags insert, objects, preview, salesforce, sfdc, update, upsert ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [com.snowflake.openflow.runtime.processors.salesforce.DeleteQueryJob](/user-guide/data-integration/openflow/processors/deletequeryjob) - [com.snowflake.openflow.runtime.processors.salesforce.DescribeSFDCObject](/user-guide/data-integration/openflow/processors/describesfdcobject) - [com.snowflake.openflow.runtime.processors.salesforce.GetQueryJobResult](/user-guide/data-integration/openflow/processors/getqueryjobresult) - [com.snowflake.openflow.runtime.processors.salesforce.SubmitQueryJob](/user-guide/data-integration/openflow/processors/submitqueryjob) --- title: Use Cortex Code with Workday data source: https://docs.snowflake.cn/en/user-guide/data-integration/zero-copy/workday/cortex-code.md section: Loading & Unloading Data --- # Use Cortex Code with Workday data Available to all accounts. - [About Workday Live Data Query for Snowflake](/user-guide/data-integration/zero-copy/about-workday-ldq) - [Connect to Workday and query data from Snowflake](/user-guide/data-integration/zero-copy/workday/connect-and-query) Workday Live Data Query for Snowflake is in Early Adopter (EA) for Workday and in Preview for Snowflake. To request access, contact your Workday account representative. Cortex Code is an AI coding assistant built into Snowflake Workspaces. Because your Workday LDQ notebook runs inside a Workspace, you can use Cortex Code to accelerate your work with Workday data: from writing queries to analyzing results and building visualizations. ## Prerequisites To use Cortex Code, grant the following database roles to your Workday LDQ role: ```sql GRANT DATABASE ROLE SNOWFLAKE.COPILOT_USER TO ROLE WORKDAY_LDQ_TEST_ROLE; GRANT DATABASE ROLE SNOWFLAKE.CORTEX_USER TO ROLE WORKDAY_LDQ_TEST_ROLE; ``` ## Access Cortex Code Click the **Cortex Code** icon in the bottom-right corner of your Workspace. A chat panel opens where you can type natural language prompts. ## Example prompts Complete [Connect to Workday and query data from Snowflake](/user-guide/data-integration/zero-copy/workday/connect-and-query) to establish a working LDQ connection before using the prompts below. ### Explore Workday data > "Write a Python cell that queries `workday_core.public.worker` for all active workers and loads the results into a pandas DataFrame called `workers_df`." ### Analyze and visualize > "Using `workers_df`, create a bar chart showing headcount by management level, sorted descending." > "Summarize the `workers_df` DataFrame: show column types, null counts, and basic statistics." ### Transform and join with Snowflake data > "Write code to save `workers_df` to a Snowflake table called `WORKDAY_LDQ_TEST.LIVEDATA.WORKERS_SNAPSHOT`, then join it with `HR_DB.PUBLIC.DEPARTMENT_BUDGETS` on department name." ### Debug and explain > "Why is my LDQ query returning zero rows? Here is the error: ..." *(paste the error message)* > *(Highlight a code cell)* "Explain what this code does." ## Example questions about your data Once Workday data is loaded into a DataFrame (for example, `workers_df` from [Connect to Workday and query data from Snowflake](/user-guide/data-integration/zero-copy/workday/connect-and-query)), you can ask Cortex Code questions about the data itself. ### Data exploration > "What columns are in `workers_df`? Which ones look like they contain PII?" > "How many unique job titles are there? Show me the top 20 by headcount." > "Are there any workers with missing manager IDs?" ### Business insights > "What's the average tenure by department? Which department has the highest turnover?" > "Show me the distribution of workers hired in the last 12 months, broken down by quarter." > "Compare headcount across management levels. Are we top-heavy?" ### Data quality > "Check `workers_df` for duplicate worker IDs." > "Which columns have more than 10% null values?" > "Find any rows where `hire_date` is in the future." ## Tips - Cortex Code is aware of your notebook's context and can see your existing cells and variables. - It works best after data is loaded into a DataFrame. It can't call the Workday LDQ connector directly, but it can generate the Python code for you to run. - Use the **Fix** button in the results panel if a cell fails. Cortex Code will suggest corrections. - Type `@` in the chat to reference Snowflake tables or views as additional context for your prompts. --- title: Use the Openflow Connector for Google BigQuery source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/google-big-query/use.md section: Loading & Unloading Data --- # Use the %bigqueryof% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About the Openflow Connector for Google BigQuery](/user-guide/data-integration/openflow/connectors/google-big-query/about) - [Setting Up the Openflow Connector for Google BigQuery](/user-guide/data-integration/openflow/connectors/google-big-query/setup) This topic describes tasks you may need to perform after installing and configuring the connector. ## Remove and re-add a table for replication To remove a table from replication: 1. Verify the table's state in the Table State Store. 2. If the state is `INCREMENTAL_IN_PROGRESS`, stop the **Trigger BigQuery Cdc On Incremental** processor. Wait for the state to change to `INCREMENTAL_REPLICATION`. 3. Remove the table from the **Included Table Names** or **Included Table Names Regex** parameters in the BigQuery Ingestion Parameters context. To re-add a table for replication: 1. Drop the destination table in Snowflake. 2. Add the table back to the **Included Table Names** or **Included Table Names Regex** parameters. This approach can also be used to recover from a failed table replication scenario. --- title: Use the Openflow Connector for MongoDB source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/mongodb/use.md section: Loading & Unloading Data --- # Use the %mongodbof% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About the Openflow Connector for MongoDB](/user-guide/data-integration/openflow/connectors/mongodb/about) - [Connect to MongoDB](/user-guide/data-integration/openflow/connectors/mongodb/connect) - [Set up the Openflow Connector for MongoDB](/user-guide/data-integration/openflow/connectors/mongodb/setup) This topic describes how to use the %mongodbof% after you have installed and configured it. ## Tracking data changes in MongoDB The connector uses MongoDB change streams for incremental synchronization, subscribing to data changes across the entire MongoDB deployment (replica sets or sharded clusters). The connector processes changes only after they persist to a majority of replica set members. The connector listens for inserts, updates, and deletes from the change stream and writes them to a journal table in Snowflake. The connector manages these journal tables and uses them to merge data into the destination table. Do not modify journal tables. Manual modifications can disrupt synchronization and compromise data integrity. The merge operation handles changes as follows:
Inserts and updates:
The connector upserts `INSERT` and `UPDATE` operations into the Snowflake table.
Deletes:
The connector uses a soft-delete strategy to preserve history. It updates the target row by setting the `_SNOWFLAKE_DELETED` column to `TRUE` instead of deleting the row.
The connector adds the `_SNOWFLAKE_DELETED` (BOOLEAN) column to the destination table during creation. **Connection recovery** If the connection to a change stream is lost, the connector attempts to reconnect through another cluster node. To ensure data consistency, the connector tracks the resume token of the last processed document. Upon reconnection, it uses this token to retrieve only changes that occurred after the disconnection. The MongoDB Oplog must be large enough to retain change history during downtime. If the connector remains offline longer than the Oplog retention period, the resume token might expire, which requires a full data re-sync. ## Remove and re-add a collection to replication To remove a collection from replication: 1. Remove it from the `Included Collection Names` or `Included Collection Regex` parameters in the MongoDB ingestion parameters context. To re-add a collection to replication: 1. Drop the corresponding destination table in Snowflake. 2. Add the collection back to the `Included Collection Names` or `Included Collection Regex` parameters. This ensures that the replication process starts fresh for the collection. You can also use this remove-and-re-add procedure to recover from a failed replication. ## Check the replication status of a collection Interim failures, such as connection errors, don't prevent collection replication. However, permanent failures, such as unsupported data, prevent collection replication. To troubleshoot replication issues or verify that a collection has been successfully removed from the replication flow, check the Collection State Store: 1. In the Openflow runtime canvas, right-click a processor group and choose **Controller Services**. A table listing controller services displays. 2. Locate the row labeled **Collection State Store**, click the **More** %sf-vertical-more-button% button on the right side of the row, and then choose **View State**. A list of collections and their current states displays. Use the search box to filter the list by collection name. The possible states are: - **NEW**: The collection is scheduled for replication but replication hasn't started. - **SNAPSHOT_REPLICATION**: The connector is copying existing documents. This status displays until all documents are stored in the destination table. - **INCREMENTAL_REPLICATION**: The connector is actively replicating changes. This status displays after snapshot replication ends and continues to display indefinitely until a collection is either removed from replication or replication fails. - **FAILED**: Replication has permanently stopped due to an error. The Openflow runtime canvas doesn't display state changes, only the current state. However, state changes are recorded in logs when they occur. If a permanent failure prevents replication, follow the procedure in the preceding section to remove the collection from replication, address the underlying problem, and then re-add the collection. --- title: Use the Openflow Connector for Veeva Vault source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/connectors/veeva-vault/use.md section: Loading & Unloading Data --- # Use the %veevavaultof% This feature is not available in the People's Republic of China. Snowflake connectors are supported in every region where Snowflake Openflow is available. [Openflow Snowflake deployments](/user-guide/data-integration/openflow/about-spcs) are available to all accounts in AWS, Azure, and GCP Commercial Regions. [Snowflake Openflow on BYOC deployments](/user-guide/data-integration/openflow/about-byoc) are available to all accounts in AWS Commercial Regions only ([](#label-na-general-regions)). This connector is subject to the [Snowflake Connector Terms](https://www.snowflake.cn/legal/snowflake-connector-terms/). - [About the Openflow Connector for Veeva Vault](/user-guide/data-integration/openflow/connectors/veeva-vault/about) - [Setting up the Openflow Connector for Veeva Vault](/user-guide/data-integration/openflow/connectors/veeva-vault/setup) This topic describes tasks you may need to perform after installing and configuring the %veevavaultof%. ## Force a full reload The connector maintains an internal state to track which Direct Data files have already been processed. In some situations, you may need to force the connector to perform a fresh full snapshot, for example, after resolving a data issue or after the connector has been stopped for an extended period. To force a full reload: 1. Stop all processors in the flow by right-clicking on the connector process group and selecting **Stop**. 2. Ensure that no in-flight FlowFiles are being processed. You can verify this by checking that all queues in the flow are empty. 3. Right-click on the canvas and select **Disable all controller services**. 4. Go to **Controller services** and locate the controller service named **Veeva Vault Client Service**. 5. In the processor **List Veeva Vault Files**, select **View state** and then select **Clear state**. 6. Right-click on the canvas and select **Enable all controller services**, then start all processors to resume the connector. The connector treats a cleared state as a fresh start and processes the latest full Direct Data file on the next execution. ## Monitoring To track the amount of data being synced from Veeva Vault to Snowflake, query the event table. The following example query retrieves relevant logs from the last 30 minutes: ```sql SELECT timestamp, Deployment_ID, Runtime_Key, parsed_log:level as log_level, parsed_log:loggerName as logger, parsed_log:formattedMessage as message, parsed_log FROM ( SELECT timestamp, resource_attributes:"openflow.dataplane.id" as Deployment_ID, resource_attributes:"k8s.namespace.name" as Runtime_Key, TRY_PARSE_JSON(value) as parsed_log FROM OPENFLOW.TELEMETRY.EVENTS WHERE true AND timestamp > dateadd('minutes', -30, sysdate()) AND record_type = 'LOG' AND resource_attributes:"k8s.namespace.name" like 'runtime-%' ORDER BY timestamp DESC ) WHERE true AND logger LIKE '%veeva%'; ``` For more information about monitoring Openflow flows, see [Monitor Openflow using telemetry data](/user-guide/data-integration/openflow/monitor). ## Troubleshooting Use the following information to troubleshoot common issues with the connector. ### Direct Data is not enabled If the connector fails with an error indicating that Direct Data files can't be retrieved, verify that Direct Data is enabled on your Vault. Contact your Veeva Vault administrator to enable this feature in the Vault admin settings. ### Authentication failures If the connector reports authentication failures: - Verify that the **Veeva Vault Username** and **Veeva Vault Password** parameters are correct. - Verify that the service account has API access enabled and has the required permissions. - Check whether the account is locked or disabled in Veeva Vault. You can verify the credentials by right-clicking on the canvas, selecting **Controller services**, locating the **Veeva Vault Client Service**, and selecting **Verify Properties**. This triggers a connectivity and authentication check against the configured Vault. ### Session expiration during long operations The connector automatically handles session expiration by re-authenticating when it receives an `INVALID_SESSION_ID` error from Vault API. No manual intervention is required. If you see repeated session expiration messages in the event table, verify that no other process is using the same service account credentials, as concurrent sessions may cause the previous session to be invalidated. ### No new data appearing in Snowflake If the connector is running but no new data appears in Snowflake: - Check that new Direct Data files are being published by Veeva Vault. The connector can only process archives that exist. - Verify that the **Veeva Vault Ingestion Mode** is set correctly. If set to `INCREMENTAL` and no incremental archives exist after the configured start time, no data is processed. - Check the event table for error messages that may indicate failures in the download, unpacking, or loading stages. ### Snowflake permission errors If the connector reports permission errors when creating tables or loading data: - Verify that the execute-as role configured in the connector has `USAGE` on the destination database and schema, `CREATE TABLE` on the schema, and `USAGE` and `OPERATE` on the warehouse. - For %ofbyoc-plural%, verify that the service user has the correct role assigned and that the RSA public key is configured correctly. --- title: Use Workload Identity Federation with Openflow source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/security/workload-identity-federation.md section: Loading & Unloading Data --- # Use Workload Identity Federation with Openflow This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). - [Workload identity federation for Snowflake workloads that access external services](/user-guide/workload-identity-federation-outbound) - [Set up Openflow - Snowflake Deployment: Configure allowed domains for Openflow connectors](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list) - [CREATE SECRET](/sql-reference/sql/create-secret) [Workload Identity Federation](/user-guide/workload-identity-federation-outbound) (WIF) lets an Openflow runtime authenticate to external cloud services on Amazon Web Services (AWS), Microsoft Azure, and Google Cloud without storing long-lived credentials such as access keys, client secrets, or service account keys. Snowflake acts as the OpenID Connect (https://openid.net/specs/openid-connect-core-1_0.html) (OIDC) provider: the runtime obtains a short-lived, signed token from Snowflake and exchanges it for temporary, scoped credentials in your cloud account. This is especially valuable when Openflow runs on Snowpark Container Services (SPCS), where the compute runs in Snowflake's cloud account rather than in your own. Traditional cloud authentication mechanisms that rely on attaching an identity to the compute (for example, AWS instance profiles or IAM roles for service accounts) aren't available, which would otherwise leave static credentials as the only option. Because Snowflake itself issues the identity token, the runtime can federate into your cloud account regardless of where the compute runs, so you never have to store a static secret. This topic describes how to configure Openflow to consume Workload Identity Federation. For the Snowflake concepts behind the feature — the secret object, the trust relationship, and token issuance — see [Workload identity federation for Snowflake workloads that access external services](/user-guide/workload-identity-federation-outbound). ## How it works 1. You create a Snowflake secret of type `WORKLOAD_IDENTITY_FEDERATION`. Snowflake becomes an OIDC provider with a unique issuer URL, and the secret becomes an OIDC client with a unique subject identifier. 2. You establish a trust relationship on the cloud provider side using the issuer URL and subject identifier. 3. In Openflow, the `SnowflakeWorkloadIdentityTokenProvider` controller service obtains a signed token from Snowflake for a configured audience. 4. A cloud-specific credentials controller service exchanges that token for temporary cloud credentials, which the Openflow processors and parameter providers then use to access cloud resources. ## Prerequisites - A Snowflake Deployment (SPCS) of Openflow with a runtime. See [Set up Openflow - Snowflake Deployment - Task overview](/user-guide/data-integration/openflow/setup-openflow-spcs). - Privileges to create secrets, network rules, and external access integrations in Snowflake. - Administrative access to the target cloud provider to configure the trust relationship (AWS IAM, Microsoft Entra ID, or Google Cloud IAM). ## Create the Snowflake secret Create a secret of type `WORKLOAD_IDENTITY_FEDERATION`. Secrets are schema-level objects, so the secret is created in a specific database and schema. ```sql USE ROLE ACCOUNTADMIN; CREATE DATABASE IF NOT EXISTS wif_demo; CREATE SCHEMA IF NOT EXISTS wif_demo.secrets_schema; CREATE SECRET wif_demo.secrets_schema.my_demo TYPE = WORKLOAD_IDENTITY_FEDERATION; ``` For more information, see [CREATE SECRET](/sql-reference/sql/create-secret). Describe the secret to retrieve the two values required to configure the trust relationship on the cloud provider side: ```sql DESC SECRET wif_demo.secrets_schema.my_demo; ``` Record the following values from the output:
| Column | Description | | -------------------------------------- | ---------------------------------------------------------------------------------------- | | `workload_identity_federation_issuer` | Issuer URL of Snowflake as the OIDC provider. Compared to the `iss` claim of the token. | | `workload_identity_federation_subject` | Identifier of the workload as the OIDC client. Compared to the `sub` claim of the token. |
The issuer is unique to a Snowflake account and is the same for every secret created in that account. The subject is unique to each secret. Grant `USAGE` on the database, schema, and secret to the execute-as role assigned to the Openflow runtime: ```sql GRANT USAGE ON DATABASE wif_demo TO ROLE OPENFLOW__EXECUTE_AS_RL; GRANT USAGE ON SCHEMA wif_demo.secrets_schema TO ROLE OPENFLOW__EXECUTE_AS_RL; GRANT USAGE ON SECRET wif_demo.secrets_schema.my_demo TO ROLE OPENFLOW__EXECUTE_AS_RL; ``` ## Set up the common Openflow controller services The following controller services are required for all cloud providers. ### Snowflake Connection Service If you don't already have one (Snowflake-provided connectors include one by default), create an instance of the [SnowflakeConnectionService](/user-guide/data-integration/openflow/controllers/snowflakeconnectionservice) controller service and set **Authentication Strategy** to `Snowflake Managed Token`. Enable the controller service. From the configuration view of a controller service, you can select **Verify** to confirm the configuration is correct before you enable it. ### Snowflake Workload Identity Token Provider Create an instance of the `SnowflakeWorkloadIdentityTokenProvider` controller service with the following configuration: - **Connection Pooling Service**: reference the Snowflake Connection Service. - **Snowflake Secret Name**: the fully qualified name of the secret, for example `wif_demo.secrets_schema.my_demo`. - **Audience**: the audience value configured for the identity provider on the cloud provider side (see the per-cloud sections below). Enable the controller service. ## AWS ### Create the IAM identity provider Create the IAM identity provider only once per Snowflake account. 1. In the AWS console, go to **IAM** %raa% **Identity providers** and select **Add provider**. 2. For **Provider type**, select **OpenID Connect**. 3. For **Provider URL**, enter the `workload_identity_federation_issuer` value. 4. For **Audience**, enter a value of your choice, for example `snowflake`. Use this same value as the **Audience** on the Snowflake Workload Identity Token Provider controller service. 5. Select **Add provider**. ### Create the IAM role and policy 1. In the AWS console, go to **IAM** %raa% **Roles** and select **Create role**. 2. For **Trusted entity type**, select **Web identity**. 3. For **Identity provider**, select the identity provider you created, and select the audience you defined. 4. Add a condition where the key ends with `:sub`, the condition is `StringEquals`, and the value is the `workload_identity_federation_subject` value. This creates a one-to-one relationship between the Snowflake secret and the IAM role. 5. Attach the policies required for the resources the Openflow runtime needs to access, name the role, and create it. Save the Amazon Resource Name (ARN) of the role for the Openflow configuration. You can create a one-to-many mapping between a single secret and multiple IAM roles. For example, to give read-only access to one Snowflake role and read-write access to another, edit the role's trust policy to add a condition on the `sf_rnm` claim, which equals the name of the execute-as role assigned to the Openflow runtime: ```json { "Version": "2012-10-17", "Statement": [ { "Effect": "Allow", "Principal": { "Federated": "arn:aws:iam:::oidc-provider/identity.snowflake.com/oauth2/" }, "Action": "sts:AssumeRoleWithWebIdentity", "Condition": { "StringEquals": { "identity.snowflake.com/oauth2/:sub": "", "identity.snowflake.com/oauth2/:aud": "snowflake", "identity.snowflake.com/oauth2/:sf_rnm": "AWS_RO" } } } ] } ``` ### Configure the external access integration In addition to a network rule for the resource itself, add a network rule that allows access to the AWS Security Token Service (STS) endpoint used to exchange the token. The following example allows access to STS and Amazon SQS: ```sql USE ROLE SECURITYADMIN; USE DATABASE openflow_db; USE SCHEMA openflow_schema; CREATE NETWORK RULE openflow_sqs_network_rule MODE = EGRESS TYPE = HOST_PORT VALUE_LIST = ('sts.eu-central-1.amazonaws.com:443', 'sqs.eu-central-1.amazonaws.com:443'); CREATE EXTERNAL ACCESS INTEGRATION openflow_sqs_eai ALLOWED_NETWORK_RULES = (openflow_sqs_network_rule) ENABLED = TRUE; GRANT USAGE ON INTEGRATION openflow_sqs_eai TO ROLE OPENFLOW__EXECUTE_AS_RL; ``` For Amazon S3 (for example, the `ListS3` or `FetchS3Object` processors), allow STS plus both the regional and global S3 endpoints. The AWS SDK might connect using either the regional or the global S3 endpoint. Snowflake network rules require an exact hostname match, so allow both forms, plus the wildcard variants used by virtual-hosted bucket URLs. In the following example, replace `us-east-1` with your bucket region in each of the regional entries: ```sql USE ROLE SECURITYADMIN; USE DATABASE openflow_db; USE SCHEMA openflow_schema; CREATE NETWORK RULE openflow_s3_network_rule MODE = EGRESS TYPE = HOST_PORT VALUE_LIST = ( 'sts.us-east-1.amazonaws.com:443', 's3.us-east-1.amazonaws.com:443', 's3.amazonaws.com:443', '*.s3.us-east-1.amazonaws.com:443', '*.s3.amazonaws.com:443' ); CREATE EXTERNAL ACCESS INTEGRATION openflow_s3_eai ALLOWED_NETWORK_RULES = (openflow_s3_network_rule) ENABLED = TRUE; GRANT USAGE ON INTEGRATION openflow_s3_eai TO ROLE OPENFLOW__EXECUTE_AS_RL; ``` After you create the external access integration, associate it with your runtime. See [Set up Openflow - Snowflake Deployment: Configure allowed domains for Openflow connectors](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list). ### Configure the AWS Credentials Provider Service For most components to interact with AWS services, configure an [AWSCredentialsProviderControllerService](/user-guide/data-integration/openflow/controllers/awscredentialsprovidercontrollerservice) controller service: - **Assume Role ARN**: the ARN of the IAM role you created. - **Assume Role Session Name**: any descriptive string that identifies the session. - **Assume Role STS Region**: the region for the STS endpoint (the same region as the resources being accessed). - **OAuth2 Access Token Provider**: reference the Snowflake Workload Identity Token Provider controller service. Enable the controller service. ### Configure AWS components Configure the AWS components (for example, `ListS3` or `ConsumeKinesis`) to reference the credentials controller service you created. This also applies to the AWS Secrets Manager parameter provider. However, parameter providers aren't flow-level components: create the controller services at the flow controller level (**Controller Settings** %raa% **Management controller services**) so that the parameter provider can reference them. ### AWS MSK with IAM authentication In the `ConsumeKafka` processor, set the **Kafka Connection Service** property to reference an [AmazonMSKConnectionService](/user-guide/data-integration/openflow/controllers/amazonmskconnectionservice) controller service. In that controller service: - Set **SASL Mechanism** to `AWS_MSK_IAM`. - Set **AWS Role Source** to `Web Identity Provider`, which reveals the following properties: - **AWS Assume Role ARN**: the ARN of the IAM role you created. - **AWS Assume Role Session Name**: any descriptive string that identifies the session. - **AWS Web Identity Token Provider**: reference the Snowflake Workload Identity Token Provider controller service. - **AWS Web Identity STS Region**: the region for the STS endpoint (the same region as the MSK instance). ### AWS RDS for PostgreSQL with IAM authentication 1. Create an `AWSCredentialsProviderControllerService` as described in [Configure the AWS Credentials Provider Service](#label-openflow-wif-aws-creds), using the STS region of the RDS instance. 2. Create an `AwsRdsIamDatabasePasswordProvider` controller service: - **AWS Credentials Provider Service**: reference the credentials controller service from the previous step. - **Region**: the same region as the RDS instance. 3. In the `DBCPConnectionPool` controller service, set **Password Source** to `Password Provider`, then set **Database Password Provider** to reference the `AwsRdsIamDatabasePasswordProvider`. ## Azure ### Register an application in Microsoft Entra ID 1. In Microsoft Entra ID, register a new application and give it a name. 2. Record the application's **Tenant ID** and **Client ID**. 3. Go to **Certificates & secrets** %raa% **Federated credentials** and select **Add credential**. 4. For the scenario, select **Other issuer**. 5. For **Issuer**, enter the `workload_identity_federation_issuer` value. For **Value** (the subject identifier), enter the `workload_identity_federation_subject` value. Give the credential a name, and note the **Audience** — you set this same value as the **Audience** on the Snowflake Workload Identity Token Provider controller service. ### Configure the external access integration In addition to a network rule for the resource itself, add a network rule that allows access to the Microsoft login endpoint (`login.microsoftonline.com`) used to exchange the token. The following example also allows access to an Azure Key Vault: ```sql USE ROLE SECURITYADMIN; CREATE NETWORK RULE openflow_azure_network_rule MODE = EGRESS TYPE = HOST_PORT VALUE_LIST = ('login.microsoftonline.com:443', 'myvault.vault.azure.net:443'); CREATE EXTERNAL ACCESS INTEGRATION openflow_azure_eai ALLOWED_NETWORK_RULES = (openflow_azure_network_rule) ENABLED = TRUE; GRANT USAGE ON INTEGRATION openflow_azure_eai TO ROLE OPENFLOW__EXECUTE_AS_RL; ``` The endpoint required for the token exchange is `login.microsoftonline.com`. Add other endpoints based on the service you access; `myvault.vault.azure.net` is only an example for the Key Vault service. After you create the external access integration, associate it with your runtime. See [Set up Openflow - Snowflake Deployment: Configure allowed domains for Openflow connectors](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list). ### Configure the Azure Identity Federation Token Provider In Openflow, go to **Controller Settings** %raa% **Management controller services** (where you added the Snowflake Connection Service and the Snowflake Workload Identity Token Provider) and add an instance of `StandardAzureIdentityFederationTokenProvider`: - Reference the Snowflake Workload Identity Token Provider controller service. - Set the **Tenant ID** and **Client ID** of your registered Entra application. Select **Verify** to confirm that tokens can be exchanged before you continue. ### Configure the Azure Credentials Controller Service Add a [StandardAzureCredentialsControllerService](/user-guide/data-integration/openflow/controllers/standardazurecredentialscontrollerservice) controller service, select `Identity Federation` for the strategy, and reference the Azure Identity Federation Token Provider controller service. Enable all of the controller services. ### Access secrets with the Azure Key Vault parameter provider 1. Create a Key Vault in Azure and add the secrets you want to use as parameters in Openflow. 2. In the Key Vault, go to **Access control (IAM)** and add a role assignment. Assign the **Key Vault Secrets User** role to your Entra application (a service principal), then review and approve the assignment. 3. In Openflow, go to **Parameter Providers** and add an `AzureKeyVaultSecretsParameterProvider`: - **Credentials Service**: reference the Azure Credentials Controller Service you created. - **Vault URI**: the URI shown on the overview page of your Key Vault. 4. Select **Verify** to confirm access to the secrets. ## GCP ### Create the workload identity pool and provider The workload identity pool and its OIDC provider can be created once and reused across secrets for the Snowflake account. In Google Cloud, create a workload identity pool and add an OpenID Connect (OIDC) provider to that pool. Configure the provider with the following values: - **Issuer (URL)**: the `workload_identity_federation_issuer` value. - **Allowed audiences**: an audience value of your choice. This value must be identical to the **Audience** on the Snowflake Workload Identity Token Provider controller service and the **Audience** on the GCP Credentials Controller Service. A common choice is the provider resource name itself. - **Attribute mapping**: map `google.subject` to `assertion.sub`. This maps the subject claim of the Snowflake token to the principal identity used in IAM bindings. For example, using the gcloud CLI: ```bash gcloud iam workload-identity-pools create openflow-pool \ --location="global" \ --display-name="Openflow WIF pool" gcloud iam workload-identity-pools providers create-oidc snowflake-provider \ --location="global" \ --workload-identity-pool="openflow-pool" \ --issuer-uri="" \ --attribute-mapping="google.subject=assertion.sub" \ --allowed-audiences="//iam.googleapis.com/projects//locations/global/workloadIdentityPools/openflow-pool/providers/snowflake-provider" ``` Record the provider resource name (used as the audience above), because it's required in the Openflow configuration: ```text //iam.googleapis.com/projects//locations/global/workloadIdentityPools/openflow-pool/providers/snowflake-provider ``` ### Grant access to the workload identity principal Service account impersonation isn't currently supported. Grant roles directly to the workload identity principal. Grant the required IAM roles directly to the principal that corresponds to the Snowflake secret. The principal is derived from the `workload_identity_federation_subject` value: ```text principal://iam.googleapis.com/projects//locations/global/workloadIdentityPools/openflow-pool/subject/ ``` For example, to grant read-only access to a Cloud Storage bucket: ```bash gcloud storage buckets add-iam-policy-binding gs:// \ --role="roles/storage.objectViewer" \ --member="principal://iam.googleapis.com/projects//locations/global/workloadIdentityPools/openflow-pool/subject/" ``` Adapt the role and resource to what the Openflow runtime needs to access. ### Configure the external access integration In addition to a network rule for the resource itself, add a network rule that allows access to the Google Security Token Service (STS) endpoint (`sts.googleapis.com`) used to exchange the token. The following example also allows access to Cloud Storage: ```sql USE ROLE SECURITYADMIN; CREATE NETWORK RULE openflow_gcs_network_rule MODE = EGRESS TYPE = HOST_PORT VALUE_LIST = ('sts.googleapis.com:443', 'storage.googleapis.com:443'); CREATE EXTERNAL ACCESS INTEGRATION openflow_gcs_eai ALLOWED_NETWORK_RULES = (openflow_gcs_network_rule) ENABLED = TRUE; GRANT USAGE ON INTEGRATION openflow_gcs_eai TO ROLE OPENFLOW__EXECUTE_AS_RL; ``` `iamcredentials.googleapis.com` isn't required, because service account impersonation isn't used. After you create the external access integration, associate it with your runtime. See [Set up Openflow - Snowflake Deployment: Configure allowed domains for Openflow connectors](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list). ### Configure the GCP Credentials Controller Service Unlike AWS and Azure, GCP uses a single credentials controller service that consumes the Snowflake token directly through its Workload Identity Federation strategy. Add a [GCPCredentialsControllerService](/user-guide/data-integration/openflow/controllers/gcpcredentialscontrollerservice) controller service: - **Authentication Strategy**: `Workload Identity Federation`. - **Audience**: the provider resource name. It must match the allowed audiences configured on the GCP OIDC provider and the **Audience** on the Snowflake Workload Identity Token Provider, for example `//iam.googleapis.com/projects//locations/global/workloadIdentityPools/openflow-pool/providers/snowflake-provider`. - **Subject Token Provider**: reference the Snowflake Workload Identity Token Provider controller service. - **Subject Token Type**: leave the default (`urn:ietf:params:oauth:token-type:jwt`). - **Scope**: leave the default (`https://www.googleapis.com/auth/cloud-platform`) unless a narrower scope is required. - **STS Token Endpoint**: leave the default (`https://sts.googleapis.com/v1/token`). Enable the controller service. Select **Verify** to confirm that tokens can be exchanged. ### Configure GCP components Configure the GCP components (for example, the Cloud Storage or BigQuery processors) to reference the GCP Credentials Controller Service you created. As with the other cloud providers, if you use a parameter provider that requires GCP credentials (parameter providers aren't flow-level components), create the GCP Credentials Controller Service and the Snowflake controller services it depends on at the flow controller level (**Controller Settings** %raa% **Management controller services**), so that the parameter provider can reference them. ## Next steps - [Set up Openflow - Snowflake Deployment: Configure allowed domains for Openflow connectors](/user-guide/data-integration/openflow/setup-openflow-spcs-sf-allow-list) - [Openflow connectors](/user-guide/data-integration/openflow/connectors/about-openflow-connectors) --- title: Validate your BYOC deployment source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/byoc-validate-vpc-config.md section: Loading & Unloading Data --- # Validate your BYOC deployment This feature is not available in the People's Republic of China. Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions). - [Set up Openflow - BYOC](/user-guide/data-integration/openflow/setup-openflow-byoc) This topic describes how to use BYOC Pre-flight Validation to verify your AWS network configuration for Openflow deployments. ## About BYOC Pre-flight Validation BYOC Pre-flight Validation is a script that verifies your AWS network environment is ready for an Openflow deployment. It checks that required networking, connectivity, and access settings are in place. Use this tool to identify and resolve network or access misconfigurations before deployment. This helps prevent failures and ensures a smoother rollout by providing specific feedback and actionable guidance for any issues found. There are two versions of this script:
`byoc-validator.sh`:
Verifies that your AWS environment is ready for a new Openflow deployment.
`byo-vpc-validator.sh`:
Verifies that your existing VPC is configured correctly for Openflow.
## What does BYOC Pre-flight Validation review? BYOC Pre-flight Validation performs a pre-deployment review that verifies your existing AWS setup, identifies issues, and explains what needs to be corrected. BYOC Pre-flight Validation checks the following: - Prerequisites (applies only to existing VPCs) - VPC components such as subnets, gateways, and routing - Network sizing and placement across availability zones - Required resource tags - Network connectivity - Access to Openflow services and endpoints - Image registry access for required containers - Connectivity to core AWS services - Permissions - Security group rules - Required IAM permissions - Encryption key access when needed BYOC Pre-flight Validation checks the resource tags that are required for deployment readiness, such as the subnet tags needed by Openflow. It does not validate your organization's complete cost allocation, governance, or compliance tagging policy. ## When to use BYOC Pre-flight Validation? Use BYOC Pre-flight Validation: - Before your initial Openflow deployment - After AWS networking changes that might impact connectivity - During troubleshooting to confirm your setup - When migrating Openflow to a new VPC or AWS account ## Download the CloudFormation template for BYOC Pre-flight Validation Follow these steps to set up BYOC Pre-flight Validation in your AWS environment: 1. Create a new BYOC deployment in the Openflow Control Plane. 2. Download the CloudFormation template for BYOC Pre-flight Validation. To download the CloudFormation template for BYOC Pre-flight Validation, click **Download Validator** in the confirmation dialog that appears after creating the deployment. 3. Apply the BYOC Pre-flight Validation CloudFormation template in AWS. 4. Access the EC2 instance where BYOC Pre-flight Validation is installed. ## Configure the CloudFormation template for BYOC Pre-flight Validation The CloudFormation template for the BYOC validator includes defaults for all parameters, and those defaults should not be changed. The CloudFormation template for the BYO-VPC validator includes defaults for most parameters, and those defaults should not be changed. However, the following parameters do not have defaults and must be provided, using the inputs you plan to use for the actual deployment:
`InfraVPC`
Select an existing VPC.
`PrivateSubnet1`
The first private subnet for Openflow runtimes.
`PrivateSubnet2`
The second private subnet for the EKS control plane.
`PrivateSecurityGroup`
Security group for the agent instance, EC2 Instance Connect endpoint, and EKS cluster.
`EBSKMSKeyArn`
Optional KMS key ARN for encrypted EBS volumes.
## Run BYOC Pre-flight Validation and view results Follow these steps to run BYOC Pre-flight Validation: 1. Connect to the EC2 instance where BYOC Pre-flight Validation is installed. 2. Run the BYOC Pre-flight Validation script from the home directory: ```bash /home/ec2-user/byoc-validator.sh ``` You can run BYOC Pre-flight Validation as many times as needed. 3. Review the output file in the `home` directory: Each run produces a new, timestamped results file, for example: `/home/ec2-user/byoc-validation-results-YYYYMMDDHHMMSS.txt` 4. Open and inspect the results: Use a tool of your preference to read the output and review pass/fail messages. Follow these steps to run BYOC Pre-flight Validation for an existing VPC: 1. Connect to the EC2 instance where BYOC Pre-flight Validation is installed. 2. Run the BYOC Pre-flight Validation script in the home directory: ```bash /home/ec2-user/byo-vpc-validator.sh ``` You can run BYOC Pre-flight Validation as many times as needed. 3. Review the output file in the `home` directory: Each run produces a new, timestamped results file, for example: `/home/ec2-user/byo-vpc-validation-results-YYYYMMDDHHMMSS.txt` 4. Open and inspect the results: Use a tool of your preference to read the output and review pass/fail messages. ## Example output The following example shows a successful validation output: ```text 2026-01-15 11:43:37,599 - INFO - Starting BYO-VPC validation suite... 2026-01-15 11:43:37,599 - INFO - ============================================================ ... 2026-01-15 11:43:37,599 - INFO - Starting Prerequisites validation... 2026-01-15 11:43:37,704 - INFO - Running validation rule: internet_gateway 2026-01-15 11:43:38,538 - INFO - ✅ internet_gateway: Internet Gateway validation passed ... 2026-01-15 11:43:39,769 - INFO - Prerequisites Summary: 4/4 rules passed 2026-01-15 11:43:39,769 - INFO - -------------------------------------------------- 2026-01-15 11:43:39,769 - INFO - Starting Network validation... 2026-01-15 11:43:39,780 - INFO - Running validation rule: snowflake_authentication 2026-01-15 11:43:41,130 - INFO - ✅ snowflake_authentication: Snowflake OAuth authentication successful ... 2026-01-15 11:43:55,920 - INFO - Network Summary: 7/7 rules passed 2026-01-15 11:43:55,920 - INFO - -------------------------------------------------- 2026-01-15 11:43:55,920 - INFO - Starting Permissions validation... 2026-01-15 11:43:55,946 - INFO - Running validation rule: private_security_group 2026-01-15 11:43:56,766 - INFO - ✅ private_security_group: Private security group validation passed ... 2026-01-15 11:43:57,560 - INFO - Permissions Summary: 2/2 rules passed 2026-01-15 11:43:57,560 - INFO - ============================================================ 2026-01-15 11:43:57,560 - INFO - 🎉 Openflow compatibility checker completed successfully! ``` The output highlights each check with a status icon: - ✅ - The requirement is met. - ❌ - The requirement is not met, and action is needed. ## AWS permissions required The CloudFormation template creates an IAM role with the necessary permissions for the EC2 instance where BYOC Pre-flight Validation is installed. If your organization uses custom IAM controls, ensure the instance role includes the following permissions: - Required to access the Snowflake OAuth secret created by the template: - `secretsmanager:GetSecretValue` - Required to inspect network resources: - `ec2:DescribeInternetGateways` - `ec2:DescribeSubnets` - `ec2:DescribeRouteTables` - `ec2:DescribeNATGateways` - `ec2:DescribeSecurityGroups` - Required only when validating an optional EBS KMS key: - `kms:DescribeKey` - `kms:GetKeyPolicy` The Secrets Manager permission is scoped to the BYOC Pre-flight Validation secret created by the template. The EC2 and KMS actions can be scoped to `*` (read-only metadata). ## Cleanup After validation is complete, you can delete BYOC Pre-flight Validation to avoid ongoing AWS costs. To delete BYOC Pre-flight Validation, delete the CloudFormation stack used to create it. This automatically removes the EC2 instance, the IAM role, and the Secrets Manager secret. --- title: ValidateCsv 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/validatecsv.md section: Loading & Unloading Data --- # ValidateCsv 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Validates the contents of FlowFiles or a FlowFile attribute value against a user-specified CSV schema. Take a look at the additional documentation of this processor for some schema examples. ## Tags csv, schema, validation ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: ValidateJson 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/validatejson.md section: Loading & Unloading Data --- # ValidateJson 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Validates the contents of FlowFiles against a configurable JSON Schema. See json-schema.org for specification standards. This Processor does not support input containing multiple JSON objects, such as newline-delimited JSON. If the input FlowFile contains newline-delimited JSON, only the first line will be validated. ## Tags JSON, schema, validation ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Restrictions
## Relationships
## Writes attributes
--- title: ValidateRecord 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/validaterecord.md section: Loading & Unloading Data --- # ValidateRecord 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Validates the Records of an incoming FlowFile against a given schema. All records that adhere to the schema are routed to the "valid" relationship while records that do not adhere to the schema are routed to the "invalid" relationship. It is therefore possible for a single incoming FlowFile to be split into two individual FlowFiles if some records are valid according to the schema and others are not. Any FlowFile that is routed to the "invalid" relationship will emit a ROUTE Provenance Event with the Details field populated to explain why records were invalid. In addition, to gain further explanation of why records were invalid, DEBUG-level logging can be enabled for the "org.apache.nifi.processors.standard. ValidateRecord" logger. ## Tags record, schema, validate ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: ValidateXml 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/validatexml.md section: Loading & Unloading Data --- # ValidateXml 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Validates XML contained in a FlowFile. By default, the XML is contained in the FlowFile content. If the 'XML Source Attribute' property is set, the XML to be validated is contained in the specified attribute. It is not recommended to use attributes to hold large XML documents; doing so could adversely affect system performance. Full schema validation is performed if the processor is configured with the XSD schema details. Otherwise, the only validation performed is to ensure the XML syntax is correct and well-formed, e.g. all opening tags are properly closed. ## Tags schema, validation, xml, xsd ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Restrictions
## Relationships
## Writes attributes
--- title: VerifyContentMAC 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/verifycontentmac.md section: Loading & Unloading Data --- # VerifyContentMAC 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-cipher-nar ## Description Calculates a Message Authentication Code using the provided Secret Key and compares it with the provided MAC property ## Tags Authentication, HMAC, MAC, Signing ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
--- title: VerifyContentPGP 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/verifycontentpgp.md section: Loading & Unloading Data --- # VerifyContentPGP 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-pgp-nar ## Description Verify signatures using OpenPGP Public Keys ## Tags Encryption, GPG, OpenPGP, PGP, RFC 4880, Signing ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.pgp.DecryptContentPGP](/user-guide/data-integration/openflow/processors/decryptcontentpgp) - [org.apache.nifi.processors.pgp.EncryptContentPGP](/user-guide/data-integration/openflow/processors/encryptcontentpgp) - [org.apache.nifi.processors.pgp.SignContentPGP](/user-guide/data-integration/openflow/processors/signcontentpgp) --- title: Version control for custom flows source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/version-control-custom-flows.md section: Loading & Unloading Data --- # Version control for custom flows This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions). - [Manage Openflow](/user-guide/data-integration/openflow/manage) - [Monitor Openflow using telemetry data](/user-guide/data-integration/openflow/monitor) Openflow supports Registry Clients, including the GitHub Registry Client, which allows you to use a Git repository to store and version your custom flow definitions. This enables standard software development lifecycle (SDLC) practices, such as branching, pull requests, code review, and environment promotion. A common workflow is: - Maintain a `main` branch representing your production flow definitions. - Create feature branches for new development. - Develop and commit changes on the Openflow canvas. - Open pull requests, review with Flow Diff, and merge. ## Prerequisites - A GitHub repository for storing flow definitions. - A GitHub Personal Access Token with `repository` access. - An Openflow Runtime with access to the Openflow canvas. - Appropriate execute-as role privileges on the runtime object. ## Step 1: Create a GitHub Registry Client 1. Create a repository in GitHub to store your flow definitions. 2. Generate a Personal Access Token (PAT) in GitHub with repository access permissions. 3. On the Openflow canvas, navigate to **Controller Settings** and create a new Registry Client. 4. Select **GitHub Registry Client** as the type. 5. Configure the Registry Client with: - Your GitHub repository URL. - The GitHub repository owner. - Your Personal Access Token for authentication. ## Step 2: Create and version a new flow 1. On the Openflow canvas, create a new Process Group for your flow. 2. Build your flow: add processors, configure connections, and set up your data pipeline. 3. Right-click the Process Group and select **Start Version Control**. 4. Choose the GitHub Registry Client you configured in [Step 1](#label-openflow-git-create-registry-client). 5. Provide a flow name and an initial commit message. After you save, the flow definition is committed to your GitHub repository. You can verify by checking the repository in GitHub. ## Step 3: Use branches to manage changes ### Create a development branch In your GitHub repository, create a new branch (for example, `dev` or a feature branch like `feature/add-new-table`). ### Import and develop on the branch 1. On the Openflow canvas, import the flow from the GitHub Registry into a new Process Group by dragging the **Import from Registry** icon from the toolbar to the canvas. 2. When importing, select the target branch (for example, `dev`) to work against. 3. Make your changes to the flow inside the Process Group. 4. Commit your changes in Openflow. This pushes the updated flow definition to the selected branch in GitHub. ### Review and merge via pull request 1. In GitHub, open a pull request from your development branch to `main`. 2. Review the changes. Use the Snowflake Flow Diff GitHub Action (see [Step 4](#label-openflow-git-flow-diff)) for human-readable diffs. 3. Merge the pull request after it's approved. 4. Back on the Openflow canvas, update the `main` Process Group to pull the latest version from the `main` branch. ## Step 4: Set up Snowflake Flow Diff (GitHub Action) Snowflake Flow Diff is a GitHub Action that makes flow changes human-readable by rendering a visual diff of your pipeline changes directly in pull request conversations. ### Set up the workflow file 1. In your GitHub repository, create the file `.github/workflows/flowdiff.yml`. 2. Copy the workflow configuration from the Snowflake Flow Diff repository (https://github.com/Snowflake-Labs/snowflake-flow-diff) (see the Usage section in the README). 3. Commit and push the workflow file. ### Review flow changes 1. When a pull request is opened, the Flow Diff action runs automatically. 2. Navigate to the **Conversations** tab on the pull request and wait for the Flow Diff analysis to appear. 3. The analysis shows a visual, human-readable comparison of flow changes instead of raw JSON diffs. ## Manage parameters across environments Openflow uses Parameters to manage environment-specific values (for example, connection strings, credentials, table names) across different Runtimes. Keep the following concepts in mind: - Parameters are grouped into a Parameter Context, which has a one-to-one mapping with a Process Group. - Parameter Context inheritance allows you to define shared parameters in a parent context and override specific values in child contexts. This is useful for promoting flows across dev, staging, and production environments. - Parameter Contexts can integrate with Secrets Managers to securely handle sensitive credentials without storing them in the flow definition. ## Recommended SDLC workflow 1. **Development environment**: Developers create feature branches, build or modify flows, and commit changes on the Openflow canvas against their feature branch. 2. **Code review**: Open a pull request in GitHub. Use Snowflake Flow Diff for readable reviews. 3. **Merge to main**: After approval, merge the pull request into the `main` branch. 4. **Promote to production**: In your production Runtime, update the Process Group to pull the latest version from `main`. 5. **Parameterize**: Use Parameter Contexts to handle environment-specific configuration without modifying the flow definition itself. --- title: VolatileSchemaCache source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/volatileschemacache.md section: Loading & Unloading Data --- # VolatileSchemaCache This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Provides a Schema Cache that evicts elements based on a Least-Recently-Used algorithm. This cache is not persisted, so any restart of NiFi will result in the cache being cleared. Additionally, the cache will be cleared any time that the Controller Service is stopped and restarted. ## Tags cache, record, schema ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: Wait 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/wait.md section: Loading & Unloading Data --- # Wait 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle org.apache.nifi | nifi-standard-nar ## Description Routes incoming FlowFiles to the 'wait' relationship until a matching release signal is stored in the distributed cache from a corresponding Notify processor. When a matching release signal is identified, a waiting FlowFile is routed to the 'success' relationship. The release signal entry is then removed from the cache. The attributes of the FlowFile that produced the release signal are copied to the waiting FlowFile if the Attribute Cache Regex property of the corresponding Notify processor is set properly. If there are multiple release signals in the cache identified by the Release Signal Identifier, and the Notify processor is configured to copy the FlowFile attributes to the cache, then the FlowFile passing the Wait processor receives the union of the attributes of the FlowFiles that produced the release signals in the cache (identified by Release Signal Identifier). Waiting FlowFiles will be routed to 'expired' if they exceed the Expiration Duration. If you need to wait for more than one signal, specify the desired number of signals via the 'Target Signal Count' property. This is particularly useful with processors that split a source FlowFile into multiple fragments, such as SplitText. In order to wait for all fragments to be processed, connect the 'original' relationship to a Wait processor, and the 'splits' relationship to a corresponding Notify processor. Configure the Notify and Wait processors to use the '$\{fragment.identifier\}' as the value of 'Release Signal Identifier', and specify '$\{fragment.count\}' as the value of 'Target Signal Count' in the Wait processor. It is recommended to use a prioritizer (for instance First In First Out) when using the 'wait' relationship as a loop. ## Tags cache, distributed, hold, map, release, signal, wait ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
## Writes attributes
## See also - [org.apache.nifi.processors.standard.Notify](/user-guide/data-integration/openflow/processors/notify) --- title: WaitForTableState 2025.10.9.21 source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/processors/waitfortablestate.md section: Loading & Unloading Data --- # WaitForTableState 2025.10.9.21 This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All processors (alphabetical)](/user-guide/data-integration/openflow/processors/index)
## Bundle com.snowflake.openflow.runtime | runtime-database-cdc-processors-nar ## Description Blocks incoming FlowFiles until the corresponding table state is not equal to accepted state. Blocked FlowFiles stay in the upstream queue. When table is in terminated state or table is removed from the state then all FlowFiles are routed to the 'failure' relationship. ## Tags cdc, event, jdbc, mysql, postgresql, sql ## Input Requirement REQUIRED ## Supports Sensitive Dynamic Properties false ## Properties
## Relationships
--- title: WindowsEventLogReader source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/windowseventlogreader.md section: Loading & Unloading Data --- # WindowsEventLogReader This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Reads Windows Event Log data as XML content having been generated by ConsumeWindowsEventLog, ParseEvtx, etc. (see Additional Details) and creates Record object(s). If the root tag of the input XML is 'Events', the child content is expected to be a series of 'Event' tags, each of which will constitute a single record. If the root tag is 'Event', the content is expected to be a single 'Event' and thus a single record. No other root tags are valid. Only events of type 'System' are currently supported. ## Tags event, log, parser, reader, record, windows, xml ## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: XMLFileLookupService source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/xmlfilelookupservice.md section: Loading & Unloading Data --- # XMLFileLookupService This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description A reloadable XML file-based lookup service. This service uses Apache Commons Configuration. Example XML configuration file and how to access specific configuration can be found at http://commons.apache.org/proper/commons-configuration/userguide/howto_hierarchical.html (http://commons.apache.org/proper/commons-configuration/userguide/howto_hierarchical.html). External entity processing is disabled. ## Tags cache, enrich, join, key, lookup, reloadable, value, xml ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted ## Restrictions
## System Resource Considerations This component does not specify system resource considerations. --- title: XMLReader source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/xmlreader.md section: Loading & Unloading Data --- # XMLReader This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Reads XML content and creates Record objects. Records are expected in the second level of XML data, embedded in an enclosing root tag. ## Tags parser, reader, record, xml ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: XMLRecordSetWriter source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/xmlrecordsetwriter.md section: Loading & Unloading Data --- # XMLRecordSetWriter This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Writes a RecordSet to XML. The records are wrapped by a root tag. ## Tags record, recordset, resultset, row, serialize, writer, xml ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. --- title: YamlTreeReader source: https://docs.snowflake.cn/en/user-guide/data-integration/openflow/controllers/yamltreereader.md section: Loading & Unloading Data --- # YamlTreeReader This feature is not available in the People's Republic of China. This feature is not available in the People's Republic of China. Openflow Snowflake Deployments are available to all accounts in AWS, Azure, and GCP [](#label-na-general-regions). Openflow BYOC deployments are available to all accounts in AWS [](#label-na-general-regions).
**Related Topics** - [About Openflow](/user-guide/data-integration/openflow/about) - [All controller services (alphabetical)](/user-guide/data-integration/openflow/controllers/index)
## Description Parses YAML into individual Record objects. While the reader expects each record to be well-formed YAML, the content of a FlowFile may consist of many records, each as a well-formed YAML array or YAML object. If an array is encountered, each element in that array will be treated as a separate record. If the schema that is configured contains a field that is not present in the YAML, a null value will be used. If the YAML contains a field that is not present in the schema, that field will be skipped. Please note this controller service does not support resolving the use of YAML aliases. Any alias present will be treated as a string. See the Usage of the Controller Service for more information and examples. ## Tags parser, reader, record, tree, yaml ## Properties In the list below required Properties are shown with an asterisk (*). Other properties are considered optional. The table also indicates any default values, and whether a property supports the NiFi Expression Language.
## State management This component does not store state. ## Restricted This component is not restricted. ## System Resource Considerations This component does not specify system resource considerations. ## Snowflake Cortex (AI & ML) LLM functions, vector search, document AI, Cortex Analyst, and AI-powered features. --- title: Access control and authentication source: https://docs.snowflake.cn/en/user-guide/snowflake-cortex/cortex-agents-setup.md section: Snowflake Cortex (AI & ML) --- # Access control and authentication This feature is not available in the People's Republic of China. - [Inaccessible tool handling](/user-guide/snowflake-cortex/cortex-agents-inaccessible-tool-handling) Access to Cortex Agents is governed by Snowflake's role-based access control. This topic covers the database roles and privileges that let users create, manage, and call agents, along with the authentication methods the API supports. ## API access roles To call the Cortex Agents `agent:run` API, use a role that has been granted one of the following database roles: - **SNOWFLAKE.CORTEX_USER**: Grants access to all Covered AI Features, including Cortex Agents. - **SNOWFLAKE.CORTEX_AGENT_USER**: Grants access to Cortex Agents only. By default, the CORTEX_USER database role is granted to the PUBLIC role, which is automatically granted to all users and roles. If you don't want all users to have this access, use the `ACCOUNTADMIN` role to run the following command: ```sql REVOKE DATABASE ROLE SNOWFLAKE.CORTEX_USER FROM ROLE PUBLIC; ``` You can then grant access to specific roles instead. For more information, see [Cortex LLM privileges](/user-guide/snowflake-cortex/aisql-privileges-and-access#label-cortex-llm-privileges). The Cortex LLM privileges guidance also recommends revoking `IMPORTED PRIVILEGES` on the `SNOWFLAKE` database from the `PUBLIC` role: ```sql REVOKE IMPORTED PRIVILEGES ON DATABASE SNOWFLAKE FROM ROLE PUBLIC; ``` This optional revocation affects more than Cortex: it also removes `PUBLIC`'s access to other objects in the shared `SNOWFLAKE` database, such as `ACCOUNT_USAGE` views. Only run this command if you intend to restrict all of that access. ## User requirements Cortex Agents determines session permissions from the querying user's default role, not the role active in their session. Every user who calls an agent must have: - A default role with the privileges described on this page. - A default warehouse, with `USAGE` on that warehouse granted to the default role. If either is missing, agent calls fail even when the user's current role has the required privileges. At a minimum, the default role must be granted `USAGE` on the agent, on the database and schema that contain it, and on the user's default warehouse: ```sql GRANT USAGE ON DATABASE TO ROLE ; GRANT USAGE ON SCHEMA . TO ROLE ; GRANT USAGE ON AGENT .. TO ROLE ; GRANT USAGE ON WAREHOUSE TO ROLE ; ``` After you set the required privileges, see [Create and manage agents](/user-guide/snowflake-cortex/cortex-agents-manage). ## Limiting access to specific roles To give only a subset of users access to Cortex Agents, use the SNOWFLAKE.CORTEX_AGENT_USER database role. Database roles can't be granted directly to users (see [GRANT DATABASE ROLE](/sql-reference/sql/grant-database-role)), so grant it to a custom role and assign that role to users. The following example, run with the `ACCOUNTADMIN` role, creates the custom role `cortex_agent_user_role`, grants it the CORTEX_AGENT_USER database role, and assigns it to `example_user`: ```sql USE ROLE ACCOUNTADMIN; CREATE ROLE cortex_agent_user_role; GRANT DATABASE ROLE SNOWFLAKE.CORTEX_AGENT_USER TO ROLE cortex_agent_user_role; GRANT ROLE cortex_agent_user_role TO USER example_user; ``` You can also grant the database role to an existing role: ```sql GRANT DATABASE ROLE SNOWFLAKE.CORTEX_AGENT_USER TO ROLE analyst_role; ``` A role that also has the CORTEX_USER database role retains access to all Covered AI Features. To restrict such a role to Cortex Agents only, revoke CORTEX_USER from it using the `ACCOUNTADMIN` role: ```sql REVOKE DATABASE ROLE SNOWFLAKE.CORTEX_USER FROM ROLE analyst_role; ``` ## Agent privileges The following privileges control who can create, manage, and use an agent: For default role and warehouse requirements, see [User requirements](#label-cortex-agents-user-requirements). ## Additional privileges for tools Because the agent runs with the querying user's default role, that role also needs privileges on the objects used by the agent's tools: `USAGE` on the agent isn't sufficient on its own. The user's default role also needs privileges on each tool you expect the agent to use. Grant the privileges in the following table for those tools. By default (`accept`), a missing privilege on a configured tool doesn't reject the entire run. The agent continues with the tools the role can access and reports the rest as warnings. Set `orchestration.tool_not_accessible` to `reject` or `legacy` if you want the run to fail instead. For modes, which tools Snowflake checks, and warning format, see [Inaccessible tool handling](/user-guide/snowflake-cortex/cortex-agents-inaccessible-tool-handling). An `agent_toolset` reference is skipped when the role doesn't have `USAGE` on the referenced agent. ## Authentication Requests to the Cortex Agents API must include an authorization token. Snowflake REST APIs support authentication via programmatic access tokens (PATs), key pair authentication using JSON Web Tokens (JWTs), and OAuth. For details, see [Authenticating Snowflake REST APIs with Snowflake](/developer-guide/snowflake-rest-api/authentication). --- title: Agent skills source: https://docs.snowflake.cn/en/user-guide/snowflake-cortex/cortex-agents-skills.md section: Snowflake Cortex (AI & ML) --- # Agent skills This feature is not available in the People's Republic of China. - [Cortex Agents](/user-guide/snowflake-cortex/cortex-agents) - [Cortex Agents REST API](/user-guide/snowflake-cortex/cortex-agents-rest-api) - [CREATE STAGE](/sql-reference/sql/create-stage) A skill is a modular, portable package of instructions, scripts, and context that gives agents the capability to perform specific, repeatable tasks. You can reference skills stored in a named stage or a Git repository and Cortex Agents discover them automatically for use in orchestration. To create reusable workflows as a business user inside %sf-intelligence%, without authoring `SKILL.md` files, see [User skills](/user-guide/snowflake-cortex/snowflake-cowork/user-skills). ## How skills work When an agent receives a user query, it evaluates the name and description of each configured skill. If the agent identifies a skill as relevant, it retrieves the full instructions and any supporting scripts from the `SKILL.md` file and executes the skill. Skills follow a discovery-and-execution model. The agent doesn't persist a copy of the skill files, it only references the skill files in their original location and reads them on demand during orchestration. ### SKILL.md file structure Each skill is defined by a `SKILL.md` file that contains the following: - A skill name - A description of the skill - Instructions for the agent - Optional script references Each skill folder must contain a `SKILL.md` file at its root. The file defines the skill's identity, instructions, and any associated scripts. The following example shows the structure of the skill folder: ``` skills/ forecaster/ SKILL.md forecaster.py planner/ SKILL.md planner.py ``` The `SKILL.md` file includes the following fields: | Field | Required | Description | | ------------ | -------- | --------------------------------------------------------------------------- | | name | Yes | Unique identifier for the skill | | description | Yes | Brief summary used by the agent during orchestration to determine relevance | | instructions | Yes | Detailed instructions the agent follows when executing the skill | ### Skill discovery Cortex Agents reference the `SKILL.md` files at the root of each skill folder. The agent scans the stage contents for `SKILL.md` files and returns the skill name, description, and file location. ### Skill orchestration During agent invocation, the agent orchestrator uses the name and description of every skill referenced in the agent to decide which skills are relevant to the user's query. If a skill is selected, the agent retrieves the full `SKILL.md` content, including detailed instructions and script paths, from the source location. ## Skill sources You can store skills in one of the two following types of locations: - Named stages - Git repositories ### Named stages The following example shows how to store skill folders in a Snowflake named stage. **%sf-web-interface% UI:** 1. Sign in to %sf-web-interface-link%. 2. Navigate to the database and schema where you want to create the stage. 3. Create a stage named `skill_stage`. 4. Upload the skill files to the stage, placing them in the `skills/forecaster/` path. **SQL:** 1. Create a stage for skills. ```sql CREATE STAGE IF NOT EXISTS db1.schema1.skill_stage; ``` 2. Upload skill files to the stage. ``` PUT file:///path/to/forecaster/SKILL.md @db1.schema1.skill_stage/skills/forecaster/; PUT file:///path/to/forecaster/forecaster.py @db1.schema1.skill_stage/skills/forecaster/; ``` ### Git repositories The following example shows how to reference skills located in a Snowflake Git repository. You can point to a specific commit hash for stability or a tag for automatic updates: **%sf-web-interface% UI:** 1. Sign in to %sf-web-interface-link%. 2. Navigate to the Git repository integration where your skills are stored. 3. Reference the skill at a specific commit hash for stability, or use a tag for automatic updates after a FETCH. **SQL:** ```sql -- Reference a skill at a specific commit @my_db.my_schema.skills_repo/commits/abc123def/skills/forecaster -- Reference a skill at a tag (updates automatically on fetch) @my_db.my_schema.skills_repo/tags/latest/skills/forecaster ``` When you reference a Git tag, the skill updates automatically after the account admin runs a FETCH on the repository. Commit hash references are immutable. ### Cortex Extensions You can reference a [Cortex Extension](/user-guide/cortex-code/cortex-code-skill-plugin-sharing) by fully qualified name (FQN) instead of listing each of its skills individually. At request time, Snowflake expands the reference into the extension's individual skills, so the agent orchestrator sees each member skill directly. Updates to the extension flow to every agent that references it, and access is controlled by the `READ` privilege on the extension object. Set the skill source `type` to `CORTEX_EXTENSION` and `path` to the extension's FQN. For `PLUGIN`-type extensions (which bundle multiple skills), the outer skill `name` is optional because member skill names are derived from the extension's `skills//` subdirectories. For `SKILL`-type extensions (single-skill), `name` is required. | Field | Required | Description | | ------- | -------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | type | Yes | Must be `CORTEX_EXTENSION`. | | path | Yes | The extension FQN in `DATABASE.SCHEMA.EXTENSION_NAME` form. | | version | No | Pins which committed version of the extension to expand. Accepts a concrete version name (for example, `VERSION$2`) or an alias (for example, `LAST`, `DEFAULT`). When omitted, Snowflake uses the extension's default version and falls back to the last committed version. `LIVE` versions are rejected. | At request time, each `skills//` subdirectory in the resolved version expands into a `STAGE` skill whose path encodes the concrete version, for example: ```text snow://cortex_extension/MY_DB.MY_SCHEMA.MY_EXTENSION/versions/VERSION$2/skills/forecaster ``` `DESCRIBE AGENT` returns the unexpanded `CORTEX_EXTENSION` reference as stored in the specification. #### Conflict resolution When a skill name appears in more than one place, the following order applies: - A skill listed explicitly in the `skills` array wins over a skill of the same name contributed by a `CORTEX_EXTENSION` reference. Use this to override a single member skill of a referenced extension. - When two `CORTEX_EXTENSION` references contribute the same skill name, the later entry in the `skills` array wins. ## Manage skills ### List available skills List all skills available in a named stage or git repository: ```sql LS @db1.schema1.stage1/ PATTERN='.*SKILL\.md'; ``` The output shows each skill's name, description, and file location: | Name | Size | Checksum | Last Modified | | ------------------------------- | ---- | ------------- | --------------------------- | | skill_stage/forecaster/SKILL.md | 1008 | 1232131231231 | Tue March 10 2026 02:45 GMT | | skill_stage/planner/SKILL.md | 2001 | 1231231231231 | Tue March 10 2026 02:45 GMT | ### List skills on an agent View all skills configured on a specific agent: ```sql DESCRIBE AGENT db1.schema1.my_agent; ``` The output returns a JSON structure with each skill's name and source URL. ### Add a skill to an agent Add a skill to a Cortex Agent by updating the agent specification. You can use the %sf-web-interface% UI, SQL, or the REST API. The description field is optional. If omitted, Snowflake reads the description from the skill's `SKILL.md` file. **%sf-web-interface% UI:** 1. Sign in to %sf-web-interface-link%. 2. Navigate to the **Skills** tab. 3. Select **Add Skill** and choose **Stage** or **Git** as the source. 4. For a stage source, provide the name of the stage and the skill folder path. 5. For a Git source, provide the repository path to the skill. 6. Select **Add Skill**. **SQL:** To add a skill from a Snowflake named stage: ```sql ALTER AGENT db1.schema1.my_agent MODIFY LIVE VERSION SET SPECIFICATION = $$ { //Please include all existing non-changed fields as well "skills": [ { "name": "forecaster", "source": { "type": "STAGE", "path": "@db1.schema1.stage1/skills/forecaster" } } ] } $$; ``` To add a skill from a Git repository: ```sql ALTER AGENT db1.schema1.my_agent MODIFY LIVE VERSION SET SPECIFICATION = $$ { //Please include all existing non-changed fields as well "skills": [ { "name": "forecaster", "source": { "type": "GIT", "path": "@my_db.my_schema.skills_repo/tags/latest/skills/forecaster" } } ] } $$; ``` To reference a Cortex Extension (private preview), so that all skills bundled in the extension are added to the agent: ```sql ALTER AGENT db1.schema1.my_agent MODIFY LIVE VERSION SET SPECIFICATION = $$ { //Please include all existing non-changed fields as well "skills": [ { "source": { "type": "CORTEX_EXTENSION", "path": "MY_DB.MY_SCHEMA.MY_EXTENSION" } } ] } $$; ``` To pin the extension to a specific committed version, add a `version` field alongside `path`, for example `"version": "VERSION$2"`. **API:** To add a skill from a Snowflake named stage: ``` PUT /api/v2/databases/{database}/schemas/{schema}/agents/{name} { "name": "my_agent", "comment": "Agent with skill capabilities", "spec": { "models": { "orchestration": "claude-sonnet-4-6" }, "instructions": { "response": "Provide concise forecasts and analysis." }, "skills": [ { "name": "forecaster", "source": { "type": "STAGE", "path": "@db1.schema1.stage1/skills/forecaster" } } ] } } ``` To add a skill from a Git repository: ``` PUT /api/v2/databases/{database}/schemas/{schema}/agents/{name} { "name": "my_agent", "comment": "Agent with skill capabilities", "spec": { "models": { "orchestration": "claude-sonnet-4-6" }, "instructions": { "response": "Provide concise forecasts and analysis." }, "skills": [ { "name": "forecaster", "source": { "type": "GIT_INTEGRATION", "path": "@my_db.my_schema.skills_repo/tags/latest/skills/forecaster" } } ] } } ``` To reference a Cortex Extension (private preview) from a persisted agent spec, so that all skills bundled in the extension are added to the agent: ``` PUT /api/v2/databases/{database}/schemas/{schema}/agents/{name} { "name": "my_agent", "spec": { "models": { "orchestration": "claude-sonnet-4-6" }, "skills": [ { "source": { "type": "CORTEX_EXTENSION", "path": "MY_DB.MY_SCHEMA.MY_EXTENSION" } } ] } } ``` You can also pass a `CORTEX_EXTENSION` reference inline to the stateless `agent:run` endpoint, without persisting an agent. Snowflake expands the reference into the extension's individual skills for that single request. The `experimental` field with `ReasoningAgentToolConfig` is required to enable tool use on the stateless endpoint: ``` POST /api/v2/cortex/agent:run { "model": "claude-sonnet-4-6", "messages": [ { "role": "user", "content": [{ "type": "text", "text": "Forecast Q4 revenue." }] } ], "skills": [ { "name": "my-extension", "source": { "type": "CORTEX_EXTENSION", "path": "MY_DB.MY_SCHEMA.MY_EXTENSION", "version": "VERSION$2" } } ], "experimental": { "ReasoningAgentToolConfig": { "OrchestrationType": "reasoning" } } } ``` ### Update a skill To update a skill's content, modify the `SKILL.md` file and any associated scripts at the source location. All agents that reference the skill automatically use the updated version on their next invocation. To update a skill's metadata in the agent specification (for example, the description), use the same PUT endpoint with the updated values. ### Remove a skill from an agent Remove a skill from an agent using the %sf-web-interface% UI, SQL, or the REST API. The remaining skills continue to function. **%sf-web-interface% UI:** 1. Sign in to %sf-web-interface-link%. 2. Navigate to the **Skills** tab. 3. Select the skill you want to remove and delete it. 4. Select **Save**. **SQL:** ```sql ALTER AGENT db1.schema1.my_agent MODIFY LIVE VERSION SET SPECIFICATION = $$ { "skills": [] } $$; ``` **API:** Update the agent specification and omit the skill from the skills array: ``` PUT /api/v2/databases/{database}/schemas/{schema}/agents/{name} { "name": "my_agent", "comment": "Agent with skill capabilities", "spec": { "models": { "orchestration": "claude-sonnet-4-6" }, "instructions": { "response": "Provide concise forecasts and analysis." }, "skills": [ ] } } ``` ### Add an existing skill to another agent You can add the same skill to multiple agents by referencing the same source path in each agent's specification. Because skills are referenced and not copied, updates to the skill files apply to all agents that use the skill. ### Skills with code If your skills need to execute code, you must enable the [code execution tool](/user-guide/snowflake-cortex/cortex-agents-code-execution-tool) on the agent. All scripts referenced by a skill must be located in the same folder as the `SKILL.md` file. To attach stage-based skills to the full Cortex Code sandbox toolset (the `code_toolset_all` tool type), see [Attaching skills](/user-guide/snowflake-cortex/cortex-agents-coding-agent#attaching-skills). ### Use skills in %sf-intelligence% The skills configured on an agent are automatically available in %sf-intelligence%. You can also explicitly select a skill for use by selecting the **+** button and then choosing the skill from the list. ## Access control The following table describes the privileges required for skill operations: | Privilege | Object | Required for | | --------- | ---------------- | ------------------------------------------------ | | USAGE | Stage | Reading skill files from a named stage | | USAGE | Git Integration | Reading skill files from a Git repository | | READ | Cortex Extension | Referencing a Cortex Extension in an agent spec | | MODIFY | Agent | Adding, updating, or removing skills in an agent | | OWNERSHIP | Agent | Full control over the agent configuration | | USAGE | Agent | Invoking the agent and its skills | ## Monitoring Skill invocations are surfaced in the thinking steps during %sf-intelligence% interactions. The monitoring dashboard displays skill invocation details alongside other orchestration information, including which skill was selected, the input provided, and the result returned. ## Limitations The following limitations apply to Cortex Agent skills: - **SKILL.md location:** The `SKILL.md` file must be at the root of the skill folder. Snowflake doesn't search subdirectories. - **Supporting files:** All scripts and supporting files must reside in the same folder as the `SKILL.md` file. - **Git fetch requirement:** Skills referenced by Git tag don't update automatically. The account admin must run a FETCH on the repository for changes to take effect. --- title: Agent toolsets source: https://docs.snowflake.cn/en/user-guide/snowflake-cortex/cortex-agents-toolsets.md section: Snowflake Cortex (AI & ML) --- # Agent toolsets This feature is not available in the People's Republic of China. - [Cortex Agents](/user-guide/snowflake-cortex/cortex-agents) - [Create and manage agents](/user-guide/snowflake-cortex/cortex-agents-manage) - [Access control and authentication](/user-guide/snowflake-cortex/cortex-agents-setup) An agent toolset lets one agent reference another agent by its fully qualified name and inherit that agent's tools at run time. When the calling agent runs, Snowflake resolves the referenced agent, verifies that the caller has USAGE privilege on it, reads the referenced agent's tool configuration, and unions those tools into the calling agent's effective tool set. The orchestrator only ever sees the flat, fully-expanded tools — the `agent_toolset` entry itself is never forwarded. This lets you build modular, composable agent architectures. For example, you can create a "toolkit" agent that bundles a set of related tools (weather lookup, calculator, data fetcher) and then reference it from multiple calling agents without duplicating the tool definitions in each one. ## How agent toolsets work When a calling agent with an `agent_toolset` tool receives a request: 1. Snowflake reads the `tool_resources[].agent_name` field to identify the referenced agent. 2. Snowflake resolves the referenced agent by its fully qualified name and authorizes USAGE under the calling user's role. 3. Snowflake reads the referenced agent's stored specification and extracts its `tools` and `tool_resources`. 4. The referenced agent's tools are unioned into the calling agent's effective configuration. 5. The expanded tool set is sent to the orchestrator. The `agent_toolset` entry is removed. This resolution happens recursively: if a referenced agent itself contains `agent_toolset` references, those are expanded in turn, up to the configured depth and fan-out limits. ### Conflict resolution When the calling agent and a referenced agent both define a tool with the same name, the calling agent's definition takes precedence. This lets you override an inherited tool locally without modifying the referenced agent. ### Recursion prevention To prevent infinite loops, Snowflake enforces the following limits: - **Cycle detection**: A visited-set depth-first search prevents cycles. If agent A references agent B and agent B references agent A, the run fails with a cycle error. - **Maximum depth**: The resolution traverses at most 5 levels of nesting (configurable by the account parameter `CORTEX_AGENT_TOOLSET_MAX_DEPTH`). - **Maximum agents**: A single run expands at most 25 referenced agents total (configurable by the account parameter `CORTEX_AGENT_TOOLSET_MAX_AGENTS`). ### Access failures If the calling user's role lacks USAGE on a referenced agent, or the referenced agent does not exist, the reference is silently skipped. The run still succeeds with the calling agent's own tools. No error or annotation is produced for the dropped reference. ## Configure an agent toolset To add an agent toolset reference, include a tool with `type: agent_toolset` in the agent's specification and provide the referenced agent's fully qualified name in `tool_resources`. ### Spec shape ```yaml tools: - tool_spec: type: agent_toolset name: my_toolset tool_resources: my_toolset: agent_name: MY_DB.MY_SCHEMA.REFERENCED_AGENT ``` The `name` field identifies the toolset reference and must match a key in `tool_resources`. The `agent_name` field is the fully qualified name of the referenced agent (`database.schema.agent_name`). ### Create an agent with a toolset reference **SQL:** ```sql CREATE AGENT my_db.my_schema.my_agent COMMENT = 'Agent that inherits tools from another agent' FROM SPECIFICATION $$ tools: - tool_spec: type: generic name: local_tool - tool_spec: type: agent_toolset name: shared_tools tool_resources: shared_tools: agent_name: MY_DB.MY_SCHEMA.TOOLKIT_AGENT $$; ``` **REST API:** ```bash curl -X POST "$SNOWFLAKE_ACCOUNT_BASE_URL/api/v2/databases/MY_DB/schemas/MY_SCHEMA/agents" \ --header 'Content-Type: application/json' \ --header "Authorization: Bearer $PAT" \ --data '{ "name": "MY_AGENT", "spec": { "models": { "orchestration": "claude-sonnet-4-6" }, "tools": [ {"tool_spec": {"type": "generic", "name": "local_tool"}}, {"tool_spec": {"type": "agent_toolset", "name": "shared_tools"}} ], "tool_resources": { "shared_tools": { "agent_name": "MY_DB.MY_SCHEMA.TOOLKIT_AGENT" } } } }' ``` ### Reference multiple agents You can include multiple `agent_toolset` entries in a single agent. Each one is resolved independently: ```yaml tools: - tool_spec: type: agent_toolset name: analytics_tools - tool_spec: type: agent_toolset name: communication_tools tool_resources: analytics_tools: agent_name: MY_DB.MY_SCHEMA.ANALYTICS_AGENT communication_tools: agent_name: MY_DB.MY_SCHEMA.COMMS_AGENT ``` Tools from `analytics_tools` are expanded first. If `communication_tools` defines a tool with the same name as one already present from `analytics_tools` or the calling agent, the earlier definition wins. ## Access control The calling user's role must have USAGE on both the calling agent and the referenced agent. The referenced agent is resolved under the caller's identity at run time, not at agent creation time. | Privilege | Object | Required for | | --------- | ---------------- | ------------------------------------------------------------- | | USAGE | Calling agent | Running the agent | | USAGE | Referenced agent | Expanding the toolset reference (silently skipped if missing) | | USAGE | Database, schema | Accessing the database and schema containing each agent | Because the referenced agent is resolved at run time, the referenced agent does not need to exist when the calling agent is created. This supports workflows where you create agents in any order and grant privileges later. ## Limitations - **Write-time validation only checks structure**: At creation time, Snowflake validates that the `agent_toolset` tool has a name and that `tool_resources[].agent_name` is non-empty. It does not resolve or authorize the referenced agent. - **Run-time resolution**: If the referenced agent is dropped or privileges are revoked after the calling agent is created, the reference is silently skipped at run time. - **No partial expansion**: I
Display Name API Name Default Value Allowable Values Description
Hostname * hostname Destination hostname or IP address
Port * port Destination port number
Record Writer * record-sink-record-writer Specifies the Controller Service to use for writing out the records.
Sender Threads * sender-threads 2 Number of worker threads allocated for handling socket communication
Property Description
File Filter Only files contained in the archive whose names match the given regular expression will be extracted (tar/zip only)
Filename Character Set If supplied this character set will be supplied to the Zip utility to attempt to decode filenames using the specific character set. If not specified the default platform character set will be used. This is useful if a Zip was created with a different character set than the platform default and the zip uses non standard values to specify.
Packaging Format The Packaging Format used to create the file
Password Password used for decrypting Zip archives encrypted with ZipCrypto or AES. Configuring a password disables support for alternative Zip compression algorithms.
allow-stored-entries-wdd Some zip archives contain stored entries with data descriptors which by spec should not happen. If this property is true they will be read anyway. If false and such an entry is discovered the zip will fail to process.
Name Description
failure The original FlowFile is sent to this relationship when it cannot be unpacked for some reason
original The original FlowFile is sent to this relationship after it has been successfully unpacked
success Unpacked FlowFiles are sent to this relationship
Name Description
mime.type If the FlowFile is successfully unpacked, its MIME Type is no longer known, so the mime.type attribute is set to application/octet-stream.
fragment.identifier All unpacked FlowFiles produced from the same parent FlowFile will have the same randomly generated UUID added for this attribute
fragment.index A one-up number that indicates the ordering of the unpacked FlowFiles that were created from a single parent FlowFile
fragment.count The number of unpacked FlowFiles generated from the parent FlowFile
segment.original.filename The filename of the parent FlowFile. Extensions of .tar, .zip or .pkg are removed because the MergeContent processor automatically adds those extensions if it is used to rebuild the original FlowFile
file.lastModifiedTime The date and time that the unpacked file was last modified (tar and zip only).
file.creationTime The date and time that the file was created. For encrypted zip files this attribute always holds the same value as file.lastModifiedTime. For tar and unencrypted zip files if available it will be returned otherwise this will be the same value asfile.lastModifiedTime.
file.lastMetadataChange The date and time the file's metadata changed (tar only).
file.lastAccessTime The date and time the file was last accessed (tar and unencrypted zip files only)
file.owner The owner of the unpacked file (tar only)
file.group The group owner of the unpacked file (tar only)
file.size The uncompressed size of the unpacked file (tar and zip only)
file.permissions The read/write/execute permissions of the unpacked file (tar and unencrypted zip files only)
file.encryptionMethod The encryption method for entries in Zip archives
Property Description
Delete Attributes Expression Regular expression for attributes to be deleted from FlowFiles. Existing attributes that match will be deleted regardless of whether they are updated by this processor.
Stateful Variables Initial Value If using state to set/reference variables then this value is used to set the initial value of the stateful variable. This will only be used in the @OnScheduled method when state does not contain a value for the variable. This is required if running statefully but can be empty if needed.
Store State Select whether or not state will be stored. Selecting 'Stateless' will offer the default functionality of purely updating the attributes on a FlowFile in a stateless manner. Selecting a stateful option will not only store the attributes on the FlowFile but also in the Processors state. See the 'Stateful Usage' topic of the 'Additional Details'section of this processor's documentation for more information
canonical-value-lookup-cache-size Specifies how many canonical lookup values should be stored in the cache
Scopes Description
LOCAL Gives the option to store values not only on the FlowFile but as stateful variables to be referenced in a recursive manner.
Name Description
success All successful FlowFiles are routed to this relationship
Name Description
See additional details This processor may write or remove zero or more attributes as described in additional details
Property Description
Box Client Service Controller Service used to obtain a Box API connection.
File ID The ID of the file for which to update metadata.
Record Reader The Record Reader to use for parsing the incoming data
Template Key The key of the metadata template to update.
Name Description
failure A FlowFile is routed to this relationship if an error occurs during metadata update.
file not found FlowFiles for which the specified Box file was not found will be routed to this relationship.
success A FlowFile is routed to this relationship after metadata has been successfully updated.
template not found FlowFiles for which the specified metadata template was not found will be routed to this relationship.
Name Description
box.id The ID of the file whose metadata was updated
box.template.name The template name used for metadata update
box.template.scope The template scope used for metadata update
error.code The error code returned by Box
error.message The error message returned by Box
Property Description
Object Type Salesforce object type whose state should be updated
Salesforce Bulk Job State Service Controller Service managing Bulk Jobs state
Status Status to set for the object type
Name Description
failure Incoming FlowFile is routed here if update fails
success Incoming FlowFile is routed here after state update
Property Description
Client Service An Elasticsearch client service to use for running queries.
Index The name of the index to use.
Max JSON Field String Length The maximum allowed length of a string value when parsing a JSON document or attribute.
Query A query in JSON syntax, not Lucene syntax. Ex: \{"query":\{"match":\{"somefield":"somevalue"\}\}\}. If this parameter is not set, the query will be read from the flowfile content. If the query (property and flowfile content) is empty, a default empty JSON Object will be used, which will result in a "match_all" query in Elasticsearch.
Query Attribute If set, the executed query will be set on each result flowfile in the specified attribute.
Query Clause A "query" clause in JSON syntax, not Lucene syntax. Ex: \{"match":\{"somefield":"somevalue"\}\}. If the query is empty, a default JSON Object will be used, which will result in a "match_all" query in Elasticsearch.
Query Definition Style How the JSON Query will be defined for use by the processor.
Script A "script" to execute during the operation, in JSON syntax. Ex: \{"source": "ctx._source.count++", "lang": "painless"\}
Type The type of this document (used by Elasticsearch for indexing and searching).
Name Description
failure If the "by query" operation fails, and a flowfile was read, it will be sent to this relationship.
retry All flowfiles that fail due to server/cluster availability go to this relationship.
success If the "by query" operation succeeds, and a flowfile was read, it will be sent to this relationship.
Name Description
elasticsearch.update.took The amount of time that it took to complete the update operation in ms.
elasticsearch.update.error The error message provided by Elasticsearch if there is an error running the update.
Property Description
counter-name The name of the counter you want to set the value of - supports expression language like $\{counterName\}
delta Adjusts the counter by the specified delta for each flow file received. May be a positive or negative integer.
Name Description
success Counter was updated/retrieved
Property Description
Column Name Translation Pattern Column name will be normalized with this regular expression
Column Name Translation Strategy The strategy used to normalize table column name. Column Name will be uppercased to do case-insensitive matching irrespective of strategy
Database Dialect Service Database Dialect Service for generating statements specific to a particular service or vendor.
db-type Database Type for generating statements specific to a particular service or vendor. The Generic Type supports most cases but selecting a specific type enables optimal processing or additional features.
record-reader The service for reading incoming flow files. The reader is only used to determine the schema of the records, the actual records will not be processed.
updatedatabasetable-catalog-name The name of the catalog that the statement should update. This may not apply for the database that you are updating. In this case, leave the field empty. Note that if the property is set and the database is case-sensitive, the catalog name must match the database's catalog name exactly.
updatedatabasetable-create-table Specifies how to process the target table when it does not exist (create it, fail, e.g.).
updatedatabasetable-dbcp-service The Controller Service that is used to obtain connection(s) to the database
updatedatabasetable-primary-keys A comma-separated list of record field names that uniquely identifies a row in the database. This property is only used if the specified table needs to be created, in which case the Primary Key Fields will be used to specify the primary keys of the newly-created table. IMPORTANT: Primary Key Fields must match the record field names exactly unless 'Quote Column Identifiers' is false and the database allows for case-insensitive column names. In practice it is best to specify Primary Key Fields that exactly match the record field names, and those will become the column names in the created table.
updatedatabasetable-query-timeout Sets the number of seconds the driver will wait for a query to execute. A value of 0 means no timeout. NOTE: Non-zero values may not be supported by the driver.
updatedatabasetable-quoted-column-identifiers Enabling this option will cause all column names to be quoted, allowing you to use reserved words as column names in your tables and/or forcing the record field names to match the column names exactly.
updatedatabasetable-quoted-table-identifiers Enabling this option will cause the table name to be quoted to support the use of special characters in the table name and/or forcing the value of the Table Name property to match the target table name exactly.
updatedatabasetable-record-writer Specifies the Controller Service to use for writing results to a FlowFile. The Record Writer should use Inherit Schema to emulate the inferred schema behavior, i.e. an explicit schema need not be defined in the writer, and will be supplied by the same logic used to infer the schema from the column types. If Create Table Strategy is set 'Create If Not Exists', the Record Writer 's output format must match the Record Reader's format in order for the data to be placed in the created table location. Note that this property is only used if 'Update Field Names' is set to true and the field names do not all match the column names exactly. If no update is needed for any field names (or 'Update Field Names' is false), the Record Writer is not used and instead the input FlowFile is routed to success or failure without modification.
updatedatabasetable-schema-name The name of the database schema that the table belongs to. This may not apply for the database that you are updating. In this case, leave the field empty. Note that if the property is set and the database is case-sensitive, the schema name must match the database's schema name exactly.
updatedatabasetable-table-name The name of the database table to update. If the table does not exist, then it will either be created or an error thrown, depending on the value of the Create Table property.
updatedatabasetable-translate-field-names If true, the Processor will attempt to translate field names into the corresponding column names for the table specified, for the purposes of determining whether the field name exists as a column in the target table. NOTE: If the target table does not exist and is to be created, this property is ignored and the field names will be used as-is. If false, the field names must match the column names exactly, or the column may not be found and instead an error my be reported that the column already exists.
updatedatabasetable-update-field-names This property indicates whether to update the output schema such that the field names are set to the exact column names from the specified table. This should be used if the incoming record field names may not match the table 's column names in terms of upper- and lower-case. For example, this property should be set to true if the output FlowFile is destined for Oracle e.g., which expects the field names to match the column names exactly. NOTE: The value of the'Translate Field Names' property is ignored when updating field names; instead they are updated to match the column name as returned by the database.
Name Description
failure A FlowFile containing records routed to this relationship if the record could not be transmitted to the database.
success A FlowFile containing records routed to this relationship after the record has been successfully transmitted to the database.
Name Description
output.table This attribute is written on the flow files routed to the 'success' and 'failure' relationships, and contains the target table name.
output.path This attribute is written on the flow files routed to the 'success' and 'failure' relationships, and contains the path on the file system to the table (or partition location if the table is partitioned).
mime.type Sets the mime.type attribute to the MIME Type specified by the Record Writer, only if a Record Writer is specified and Update Field Names is 'true'.
record.count Sets the number of records in the FlowFile, only if a Record Writer is specified and Update Field Names is 'true'.
Property Description
Record Reader Specifies the Controller Service to use for reading incoming data
Record Writer Specifies the Controller Service to use for writing out the records
Replacement Value Strategy Specifies how to interpret the configured replacement values
Name Description
failure If a FlowFile cannot be transformed from the configured input format to the configured output format, the unchanged FlowFile will be routed to this relationship
success FlowFiles that are successfully transformed will be routed to this relationship
Name Description
record.index This attribute provides the current row index and is only available inside the literal value expression.
record.error.message This attribute provides on failure the error message encountered by the Reader or Writer.
Property Description
Add Column Strategy The strategy to use when the incoming schema has a column that is not present in the existing table
Add Not Null Strategy The strategy to use when the incoming schema has a not-null constraint that is not present in the existing table
Alter Column Type Strategy The strategy to use when the existing table has a column with a different type than the incoming schema.
Column Name Transformation An optional transformation that can be applied to the names of columns defined in the schema. This transformation is applied to the column names before they are compared to the existing columns in the table. This property can reference the following variables via Expression Language, in addition to attributes: _column.name_, _column.type_, _column.nullable_, _column.precision_, _column.scale_, _column.primaryKey_.
Column Removal Strategy The strategy to use when the existing table has a column that is not present in the incoming schema
Connection Pool The connection pool to use to connect to Snowflake
Create Stream Whether or not to create a Snowflake Stream for the table
Creation Parameters Additional parameters to include in the CREATE TABLE statement. For example, 'CLUSTER BY (column_name)'
Desired Schema The desired schema / table definition
Drop Column Strategy The strategy to use when the existing table has a column that is not present in the incoming schema
Drop Not Null Strategy The strategy to use when the existing table has a not-null constraint that is not present in the incoming schema
Include Default Values Whether or not to include DEFAULT values in CREATE TABLE or ALTER TABLE ADD COLUMN statements
Include Not Null Constraints Whether or not to include NOT NULL constraints in CREATE TABLE or ALTER TABLE ADD COLUMN statements
Include Primary Key Constraints Whether or not to include primary key constraints in the creation statement
Max Batch Size The maximum number of FlowFiles that can be processed in a single execution for a given table.
Modify Primary Key Strategy The strategy to use when the incoming schema has a primary key that differs from the existing primary key. Modifying the Primary Key requires dropping the existing one, if any, and adding a new one.
Record Reader Record Reader to use for obtaining the desired schema
Removed Column Name Suffix The suffix to append to a column that was removed. For example, to rename column 'foo' to 'foo__deleted', the property can be set to ___deleted_
Schema Name The name of the schema to update
Stream Creation Parameters Additional parameters to include in the CREATE STREAM statement. For example, 'APPEND_ONLY=TRUE'
Stream Name The name of the stream
Table Metadata Cache Expiration Time The time in seconds after which the cache entry will be removed
Table Name The name of the table to update or create stream on
Table Schema Strategy Specifies how to obtain the desired schema / table definition
Table Stream Creation Parameters Parameters to include in the CREATE STREAM statement. For example, 'APPEND_ONLY=TRUE'. The stream will be created along with the table as it's source.
Table Stream Name The name of the stream created along with the table. Stream source will be the created table.
Update Type The type of update to perform
Use Table Metadata Cache Whether to cache table's metadata instead of reading it directly from Snowflake. Applies to [Create Table If Not Exists, Alter Table]
Name Description
failure The incoming FlowFile is routed to this relationship if the table cannot be updated
success The incoming FlowFile is routed to this relationship after the table has been updated successfully
Name Description
schema.hash A SHA-256 hash of the final table schema after all updates have been completed. Can be used for change detection and caching purposes.
Property Description
Add Column Strategy The strategy to use when the incoming schema has a column that is not present in the existing table
Alter Column Strategy The strategy to use when a column has different data type in the incoming schema from the existing table
Alter Column Type Strategy The strategy to use when the existing table has a column with a different type than the incoming schema.
Connection Pool The connection pool to use to connect to Snowflake
Desired Schema The desired schema / table definition
Drop Column Strategy The strategy to use when the existing table has a column that is not present in the incoming schema
Max Batch Size The maximum number of FlowFiles that can be processed in a single execution for a given table.
Record Reader Record Reader to use for obtaining the desired schema
Schema Name The name of the schema to update
Table Metadata Cache Expiration Time The time in seconds after which the cache entry will be removed
Table Name The name of the table to update
Table Schema Strategy Specifies how to obtain the desired schema / table definition
Use Table Metadata Cache Whether to cache table's metadata instead of reading it directly from Snowflake
Name Description
failure The incoming FlowFile is routed to this relationship if the table cannot be updated
illegal alteration The incoming FlowFile is routed to this relationship if the update requires an alteration that is configured to fail
success The incoming FlowFile is routed to this relationship after the table has been updated successfully
table not found The incoming FlowFile is routed to this relationship if the specified table does not exist.
Name Description
schema.hash A hexadecimal-encoded SHA-256 hash of the final table schema after all updates have been completed.
Property Description
Connection Pool The connection pool to use to connect to Snowflake
Object Identifier Resolution Controls how source object identifiers (schemas, tables, columns) are stored and queried in Snowflake. This setting determines whether you will need to use double quotes in your SQL queries.
Schema Creation Cache Expiration Time The time after which the cache entry will be removed
Schema Name The name of the schema to create
Use Schema Creation Cache Whether to cache schema's creation instead of executing CREATE SCHEMA IF NOT EXISTS statement for each FlowFile.
Name Description
failure The incoming FlowFile is routed to this relationship if the schema cannot be created
success The incoming FlowFile is routed to this relationship after the schema has been created successfully
Property Description
Connection Pool The connection pool to use to connect to Snowflake
Object Identifier Resolution Controls how source object identifiers (schemas, tables, columns) are stored and queried in Snowflake. This setting determines whether you will need to use double quotes in your SQL queries.
Schema Name The name of the schema containing the stream and/or source table
Source Table Name The name of the source table for the stream
Stream Creation Parameters Additional parameters to include in the CREATE STREAM statement. For example, 'APPEND_ONLY=TRUE SHOW_INITIAL_ROWS=TRUE'
Stream Name The name of the stream to create, drop, or replace
Update Type The type of stream operation to perform
Name Description
failure The incoming FlowFile is routed to this relationship if the stream operation cannot be completed
object not found The incoming FlowFile is routed to this relationship if the specified stream or source table does not exist.
success The incoming FlowFile is routed to this relationship after the stream operation has been completed successfully
Property Description
Add Column Strategy The strategy to use when the incoming schema has a column that is not present in the existing table
Add Not Null Strategy The strategy to use when the incoming schema has a not-null constraint that is not present in the existing table
Alter Column Type Strategy The strategy to use when the existing table has a column with a different type than the incoming schema.
Column Name Transformation An optional transformation that can be applied to the names of columns defined in the schema. This transformation is applied to the column names before they are compared to the existing columns in the table. This property can reference the following variables via Expression Language, in addition to attributes: _column.name_, _column.type_, _column.nullable_, _column.precision_, _column.scale_, _column.primaryKey_.The result of applying transformations based on this property will be treated according to the setting of _Object Name Handling_ property.
Column Removal Strategy The strategy to use when the existing table has a column that is not present in the incoming schema
Connection Pool The connection pool to use to connect to Snowflake
Creation Parameters Additional parameters to include in the CREATE TABLE statement. For example, 'CLUSTER BY (column_name)'
Desired Schema The desired schema / table definition
Drop Column Strategy The strategy to use when the existing table has a column that is not present in the incoming schema
Drop Not Null Strategy The strategy to use when the existing table has a not-null constraint that is not present in the incoming schema
Include Default Values Whether or not to include DEFAULT values in CREATE TABLE or ALTER TABLE ADD COLUMN statements
Include Not Null Constraints Whether or not to include NOT NULL constraints in CREATE TABLE or ALTER TABLE ADD COLUMN statements
Include Primary Key Constraints Whether or not to include primary key constraints in the creation statement
Max Batch Size The maximum number of FlowFiles that can be processed in a single execution for a given table.
Modify Primary Key Strategy The strategy to use when the incoming schema has a primary key that differs from the existing primary key. Modifying the Primary Key requires dropping the existing one, if any, and adding a new one.
Object Identifier Resolution Controls how source object identifiers (schemas, tables, columns) are stored and queried in Snowflake. This setting determines whether you will need to use double quotes in your SQL queries.
Record Reader Record Reader to use for obtaining the desired schema
Removed Column Name Suffix The suffix to append to a column that was removed. For example, to rename column 'foo' to 'foo__deleted', the property can be set to ___deleted_. This property value will behave differently depending on the value of _Object Name Handling_ property, i.e. If _Object Name Handling_ is set to _Case Sensitive Name_, then the suffix will be appended as-is. If _Object Name Handling_ is set to _SQL Identifier_, then the suffix and must consist of only letters, numbers, dollar sign ($), and underscore (_) characters, additionally it will be appended as case-insensitive or case-sensitive depending on the column name it is being appended to is case-insensitive (not double-quoted) or case-sensitive (double-quoted) respectively.
Schema Name The name of the schema containing the table
Table Metadata Cache Expiration Time The time in seconds after which the cache entry will be removed
Table Name The name of the table to update
Table Schema Strategy Specifies how to obtain the desired schema / table definition
Update Type The type of table update to perform
Use Table Metadata Cache Whether to cache table's metadata instead of reading it directly from Snowflake. Applies to [Create Table If Not Exists, Alter Table]
Name Description
failure The incoming FlowFile is routed to this relationship if the table cannot be updated
success The incoming FlowFile is routed to this relationship after the table has been updated successfully
Name Description
schema.hash A SHA-256 hash of the final table schema after all updates have been completed. Can be used for change detection and caching purposes.
Property Description
Connection Pool The connection pool to use to connect to Snowflake
Schema Name The name of the schema where the view will be created
Secure Whether to create a secure view. Secure views hide the view definition from unauthorized users.
View Name The name of the view to create or update
Name Description
failure FlowFiles that failed to be processed
success FlowFiles that were successfully processed
unchanged FlowFiles where the view already exists and hasn't changed
Property Description
CDC Schema Registry When the state of the table is removed, the table will also be removed from the specified CDC Schema Registry.
Desired State The desired state of the table
Overwrite Existing Whether to overwrite the existing state of the table. If false, the state will only be updated if the state is currently unknown.
Schema Name The name of the table's schema
Table Name The name of the table
Table State Service The Table State Service to update
Name Description
comms failure A FlowFile is routed to this relationship if the table state could not be updated due to a communication failure with the Table State Service
state exists A FlowFile is routed to this relationship if the table state was not updated because the state is already known for the table and the 'Overwrite Existing' property is set to 'false'
success A FlowFile is routed to this relationship after the table state has been updated
Name Description
table.state The state of the table after updating the Table State Service
previous.table.state The state of the table before the Table State Service was updated
Property Description
Collection Name The name of the Milvus collection name to use
ID Field Name The name of the field in Milvus to use for storing the IDs of vectors. If a record path is not provided along with the field name the IDs will be generated based on the filename in the format of a string.
ID Record Path The path to the ID field in the record
Max Batch Size If the number of Records in a FlowFile is large, creating a single request to Milvus can consume significant amounts of NiFi heap. In order to avoid this, the Max Batch Size can limit the number of Records to send in a single request.
Metadata Field Name The name of the field to use for storing other metadata associated with the vectors. This data must be in the format of valid json.
Metadata Record Path The path to the metadata field in the record
Milvus Connection Service Connection Service for accessing Milvus Database
Partition Partition of the vector database that you want to perform operations in. If the database has only one partition leave empty.
Record Reader The Record Reader to use for reading the FlowFile
Sparse Vector Field Name The name of the field to use for storing the sparse vectors.
Sparse Vector Indices Path If, Sparse Vectors are to be provided, this RecordPath points to the indices of the sparse data to use.
Sparse Vector Values Path If, Sparse Vectors are to be provided, this RecordPath points to the values of the sparse data to use.
Text Field Name The name of the field in Milvus to use for storing the text associated with the vectors.
Text Record Path The path to the field in the record that contains the text associated with the vectors. If specified, the text will be inserted under the text field in Milvus. If not specified, the text will not be sent to the Milvus database.
Vector Field Name The name of the field in Milvus to use for storing the vectors.
Vector Record Path The path to the vector field in the record
Name Description
failure FlowFiles that cannot be sent to Milvus, and for which a retry is not expected to be successful, are routed to this relationship
retry FlowFiles that fail to be sent to Milvus, but for which a retry may help, are routed to this relationship
success FlowFiles that are successfully sent to Milvus are routed to this relationship
Property Description
ID Record Path The path to the ID field in the record
Max Batch Size If the number of Records in a FlowFile is large, creating a single request to Pinecone can consume significant amounts of NiFi heap. In order to avoid this, the Max Batch Size can limit the number of Records to send in a single request. If the number of Records exceeds this value, multiple requests will be sent to Pinecone.
Metadata Record Path The path to the metadata field in the record
Pinecone API Key The API key for the Pinecone service
Pinecone Index The name of the Pinecone index to use
Pinecone Namespace The name of the Pinecone namespace to use
Record Reader The Record Reader to use for reading the FlowFile
Sparse Vector Indices Path If, Sparse Vectors are to be provided, this RecordPath points to the indices of the sparse data to use.
Sparse Vector Values Path If, Sparse Vectors are to be provided, this RecordPath points to the values of the sparse data to use.
Text Field Name The name of the field in the metadata to use for storing the text associated with the vectors.
Text Record Path The path to the field in the record that contains the text associated with the vectors. If specified, the text will be inserted into the metadata when publishing to Pinecone. If not specified, the text will not be sent to Pinecone.
Vector Record Path The path to the vector field in the record
Web Client Service The Web Client Service to use for communicating with Pinecone
Name Description
failure FlowFiles that cannot be sent to Pinecone, and for which a retry is not expected to be successful, are routed to this relationship
retry FlowFiles that fail to be sent to Pinecone, but for which a retry may help, are routed to this relationship
success FlowFiles that are successfully sent to Pinecone are routed to this relationship
Property Description
Object Name The name of the object type for the records included in the FlowFile.
Record Reader Specifies the Controller Service to use for reading incoming data. Each record will be converted into a JSON object and upserted into Salesforce using a dedicated API call.
Salesforce Client Salesforce Client to interact with the APIs
Name Description
comms.failure The FlowFile is routed to this relationship if any record could not be upserted in Salesforce but the operation might be retried
failure The FlowFile is routed to this relationship if any record could not be upserted in Salesforce
success The FlowFile is routed to this relationship after all records have been successfully upserted
Name Description
sObjectId ID of the created object in Salesforce when using this processor with a single record.
Property Description
CSV Source Attribute The name of the attribute containing CSV data to be validated. If this property is blank, the FlowFile content will be validated.
Max Lines Per Row The maximum number of lines that a row can span before an exception is thrown. This option allows the processor to fail fast when encountering CSV with mismatching quotes - the normal behaviour would be to continue reading until the matching quote is found, which could potentially mean reading the whole file (and exhausting all available memory). Zero value will disable this option.
validate-csv-delimiter Character used as 'delimiter' in the incoming data. Example: ,
validate-csv-eol Symbols used as 'end of line' in the incoming data. Example: n
validate-csv-header True if the incoming flow file contains a header to ignore, false otherwise.
validate-csv-quote Character used as 'quote' in the incoming data. Example: "
validate-csv-schema The schema to be used for validation. Is expected a comma-delimited string representing the cell processors to apply. The following cell processors are allowed in the schema definition: [ParseBigDecimal, ParseBool, ParseChar, ParseDate, ParseDouble, ParseInt, ParseLong, Optional, DMinMax, Equals, ForbidSubStr, LMinMax, NotNull, Null, RequireHashCode, RequireSubStr, Strlen, StrMinMax, StrNotNullOrEmpty, StrRegEx, Unique, UniqueHashCode, IsIncludedIn]. Note: cell processors cannot be nested except with Optional. Schema is required if Header is false.
validate-csv-strategy Strategy to apply when routing input files to output relationships.
validate-csv-violations If true, the validation.error.message attribute would include the list of all the violations for the first invalid line. Note that setting this property to true would slightly decrease the performances as all columns would be validated. If false, a line is invalid as soon as a column is found violating the specified constraint and only this violation for the first invalid line will be included in the validation.error.message attribute.
Name Description
invalid FlowFiles that are not valid according to the specified schema, or no schema or CSV header can be identified, are routed to this relationship
valid FlowFiles that are successfully validated against the schema are routed to this relationship
Name Description
count.valid.lines If line by line validation, number of valid lines extracted from the source data
count.invalid.lines If line by line validation, number of invalid lines extracted from the source data
count.total.lines If line by line validation, total number of lines in the source data
validation.error.message For flow files routed to invalid, message of the first validation error
Property Description
JSON Schema A URL or file path to the JSON schema or the actual JSON schema content
JSON Schema Registry Specifies the Controller Service to use for the JSON Schema Registry
JSON Schema Version The JSON schema specification
Max String Length The maximum allowed length of a string value when parsing the JSON document
Schema Access Strategy Specifies how to obtain the schema that is to be used for interpreting the data.
Schema Name Specifies the name of the schema to lookup in the Schema Registry property
Required Permission Explanation
reference remote resources Schema configuration can reference resources over HTTP
Name Description
failure FlowFiles that cannot be read as JSON are routed to this relationship
invalid FlowFiles that are not valid according to the specified schema are routed to this relationship
valid FlowFiles that are successfully validated against the schema are routed to this relationship
Name Description
json.validation.errors If the flow file is routed to the invalid relationship , this attribute will contain the error message resulting from the validation failure.
Property Description
Schema Access Strategy Specifies how to obtain the schema that should be used to validate records
Schema Branch Specifies the name of the branch to use when looking up the schema in the Schema Registry property. If the chosen Schema Registry does not support branching, this value will be ignored.
Schema Name Specifies the name of the schema to lookup in the Schema Registry property
Schema Registry Specifies the Controller Service to use for the Schema Registry
Schema Text The text of an Avro-formatted Schema
Schema Version Specifies the version of the schema to lookup in the Schema Registry. If not specified then the latest version of the schema will be retrieved.
allow-extra-fields If the incoming data has fields that are not present in the schema, this property determines whether or not the Record is valid. If true, the Record is still valid. If false, the Record will be invalid due to the extra fields.
coerce-types If enabled, the processor will coerce every field to the type specified in the Reader 's schema. If the value of a field cannot be coerced to the type, the field will be skipped (will not be read from the input data), thus will not appear in the output. If not enabled, then every field will appear in the output but their types may differ from what is specified in the schema. For details please see the Additional Details page of the processor's Help. This property controls how the data is read by the specified Record Reader.
invalid-record-writer If specified, this Controller Service will be used to write out any records that are invalid. If not specified, the writer specified by the "Record Writer" property will be used with the schema used to read the input records. This is useful, for example, when the configured Record Writer cannot write data that does not adhere to its schema (as is the case with Avro) or when it is desirable to keep invalid records in their original format while converting valid records to another format.
maximum-validation-details-length Specifies the maximum number of characters that validation details value can have. Any characters beyond the max will be truncated. This property is only used if 'Validation Details Attribute Name' is set
record-reader Specifies the Controller Service to use for reading incoming data
record-writer Specifies the Controller Service to use for writing out the records. Regardless of the Controller Service schema access configuration, the schema that is used to validate record is used to write the valid results.
strict-type-checking If the incoming data has a Record where a field is not of the correct type, this property determines how to handle the Record. If true, the Record will be considered invalid. If false, the Record will be considered valid and the field will be coerced into the correct type (if possible, according to the type coercion supported by the Record Writer). This property controls how the data is validated against the validation schema.
validation-details-attribute-name If specified, when a validation error occurs, this attribute name will be used to leave the details. The number of characters will be limited by the property 'Maximum Validation Details Length'.
Name Description
failure If the records cannot be read, validated, or written, for any reason, the original FlowFile will be routed to this relationship
invalid Records that are not valid according to the schema will be routed to this relationship
valid Records that are valid according to the schema will be routed to this relationship
Name Description
mime.type Sets the mime.type attribute to the MIME Type specified by the Record Writer
record.count The number of records in the FlowFile routed to a relationship
Property Description
Schema File The file path or URL to the XSD Schema file that is to be used for validation. If this property is blank, only XML syntax/structure will be validated.
XML Source Attribute The name of the attribute containing XML to be validated. If this property is blank, the FlowFile content will be validated.
Required Permission Explanation
reference remote resources Schema configuration can reference resources over HTTP
Name Description
invalid FlowFiles that are not valid according to the specified schema or contain invalid XML are routed to this relationship
valid FlowFiles that are successfully validated against the schema, if provided, or verified to be well-formed XML are routed to this relationship
Name Description
validatexml.invalid.error If the flow file is routed to the invalid relationship the attribute will contain the error message resulting from the validation failure.
Property Description
Message Authentication Code The MAC to compare with the calculated value
Message Authentication Code Algorithm Hashed Message Authentication Code Function
Message Authentication Code Encoding Encoding of the Message Authentication Code
Secret Key Secret key to calculate the hash
Secret Key Encoding Encoding of the Secret Key
Name Description
failure Signature Verification Failed
success Signature Verification Succeeded
Name Description
mac.calculated Calculated Message Authentication Code encoded by the selected encoding
mac.encoding The Encoding of the Hashed Message Authentication Code
mac.algorithm Hashed Message Authentication Code Algorithm
Property Description
public-key-service PGP Public Key Service for verifying signatures with Public Key Encryption
Name Description
failure Signature Verification Failed
success Signature Verification Succeeded
Name Description
pgp.literal.data.filename Filename from Literal Data
pgp.literal.data.modified Modified Date Time from Literal Data in milliseconds
pgp.signature.created Signature Creation Time in milliseconds
pgp.signature.algorithm Signature Algorithm including key and hash algorithm names
pgp.signature.hash.algorithm.id Signature Hash Algorithm Identifier
pgp.signature.key.algorithm.id Signature Key Algorithm Identifier
pgp.signature.key.id Signature Public Key Identifier
pgp.signature.type.id Signature Type Identifier
pgp.signature.version Signature Version Number
Display Name API Name Default Value Allowable Values Description
Maximum Cache Size * max-cache-size 100 The maximum number of Schemas to cache.
Property Description
attribute-copy-mode Specifies how to handle attributes copied from FlowFiles entering the Notify processor
distributed-cache-service The Controller Service that is used to check for release signals from a corresponding Notify processor
expiration-duration Indicates the duration after which waiting FlowFiles will be routed to the 'expired' relationship
releasable-flowfile-count A value, or the results of an Attribute Expression Language statement, which will be evaluated against a FlowFile in order to determine the releasable FlowFile count. This specifies how many FlowFiles can be released when a target count reaches target signal count. Zero (0) has a special meaning, any number of FlowFiles can be released as long as signal count matches target.
release-signal-id A value that specifies the key to a specific release signal cache. To decide whether the FlowFile that is being processed by the Wait processor should be sent to the 'success' or the 'wait' relationship, the processor checks the signals in the cache specified by this key.
signal-counter-name Within the cache (specified by the Release Signal Identifier) the signals may belong to different counters. If this property is specified, the processor checks the number of signals in the cache that belong to this particular counter. If not specified, the processor checks the total number of signals in the cache.
target-signal-count The number of signals that need to be in the cache (specified by the Release Signal Identifier) in order for the FlowFile processed by the Wait processor to be sent to the ‘success’ relationship. If the number of signals in the cache has reached this number, the FlowFile is routed to the 'success' relationship and the number of signals in the cache is decreased by this value. If Signal Counter Name is specified, this processor checks a particular counter, otherwise checks against the total number of signals in the cache.
wait-buffer-count Specify the maximum number of incoming FlowFiles that can be buffered to check whether it can move forward. The more buffer can provide the better performance, as it reduces the number of interactions with cache service by grouping FlowFiles by signal identifier. Only a signal identifier can be processed at a processor execution.
wait-mode Specifies how to handle a FlowFile waiting for a notify signal
wait-penalty-duration If configured, after a signal identifier got processed but did not meet the release criteria, the signal identifier is penalized and FlowFiles having the signal identifier will not be processed again for the specified period of time, so that the signal identifier will not block others to be processed. This can be useful for use cases where a Wait processor is expected to process multiple signal identifiers, and each signal identifier has multiple FlowFiles, and also the order of releasing FlowFiles is important within a signal identifier. The FlowFile order can be configured with Prioritizers. IMPORTANT: There is a limitation of number of queued signals can be processed, and Wait processor may not be able to check all queued signal ids. See additional details for the best practice.
Name Description
expired A FlowFile that has exceeded the configured Expiration Duration will be routed to this relationship
failure When the cache cannot be reached, or if the Release Signal Identifier evaluates to null or empty, FlowFiles will be routed to this relationship
success A FlowFile with a matching release signal in the cache will be routed to this relationship
wait A FlowFile with no matching release signal in the cache will be routed to this relationship
Name Description
wait.start.timestamp All FlowFiles will have an attribute 'wait.start.timestamp', which sets the initial epoch timestamp when the file first entered this processor. This is used to determine the expiration time of the FlowFile. This attribute is not written when the FlowFile is transferred to failure, expired or success
wait.counter.<counterName> The name of each counter for which at least one signal has been present in the cache since the last time the cache was empty gets copied to the current FlowFile as an attribute.
Property Description
Accepted State Blocks FlowFiles for a given SourceTableFQN until corresponding state is equal to the Accepted State
Table State Service Manages the state of each replicated table
Name Description
failure FlowFiles for tables in terminal states will be routed to this relationship
success FlowFiles fulfilling a given condition will be routed to this relationship
Display Name API Name Default Value Allowable Values Description
Configuration File * configuration-file A configuration file
Required Permission Explanation
read filesystem Provides operator the ability to read from any file that NiFi has access to.
Display Name API Name Default Value Allowable Values Description
Date Format Date Format Specifies the format to use when reading/writing Date fields. If not specified, Date fields will be assumed to be number of milliseconds since epoch (Midnight, Jan 1, 1970 GMT). If specified, the value must match the Java java.time.format.DateTimeFormatter format (for example, MM/dd/yyyy for a two-digit month, followed by a two-digit day, followed by a four-digit year, all separated by '/' characters, as in 01/01/2017).
Schema Access Strategy * Schema Access Strategy infer-schema - Use 'Schema Name' Property - Use 'Schema Text' Property - Schema Reference Reader - Infer Schema Specifies how to obtain the schema that is to be used for interpreting the data.
Schema Branch Schema Branch Specifies the name of the branch to use when looking up the schema in the Schema Registry property. If the chosen Schema Registry does not support branching, this value will be ignored.
Schema Name Schema Name $\{schema.name\} Specifies the name of the schema to lookup in the Schema Registry property
Schema Reference Reader * Schema Reference Reader Service implementation responsible for reading FlowFile attributes or content to determine the Schema Reference Identifier
Schema Registry Schema Registry Specifies the Controller Service to use for the Schema Registry
Schema Text Schema Text $\{avro.schema\} The text of an Avro-formatted Schema
Schema Version Schema Version Specifies the version of the schema to lookup in the Schema Registry. If not specified then the latest version of the schema will be retrieved.
Time Format Time Format Specifies the format to use when reading/writing Time fields. If not specified, Time fields will be assumed to be number of milliseconds since epoch (Midnight, Jan 1, 1970 GMT). If specified, the value must match the Java java.time.format.DateTimeFormatter format (for example, HH:mm:ss for a two-digit hour in 24-hour format, followed by a two-digit minute, followed by a two-digit second, all separated by ':' characters, as in 18:04:15).
Timestamp Format Timestamp Format Specifies the format to use when reading/writing Timestamp fields. If not specified, Timestamp fields will be assumed to be number of milliseconds since epoch (Midnight, Jan 1, 1970 GMT). If specified, the value must match the Java java.time.format.DateTimeFormatter format (for example, MM/dd/yyyy HH:mm:ss for a two-digit month, followed by a two-digit day, followed by a four-digit year, all separated by '/' characters; and then followed by a two-digit hour in 24-hour format, followed by a two-digit minute, followed by a two-digit second, all separated by ':' characters, as in 01/01/2017 18:04:15).
Attribute Prefix attribute_prefix If this property is set, the name of attributes will be prepended with a prefix when they are added to a record.
Field Name for Content content_field_name If tags with content (e. g. <field>content</field>) are defined as nested records in the schema, the name of the tag will be used as name for the record and the value of this property will be used as name for the field. If tags with content shall be parsed together with attributes (e. g. <field attribute="123">content</field>), they have to be defined as records. In such a case, the name of the tag will be used as the name for the record and the value of this property will be used as the name for the field holding the original content. The name of the attribute will be used to create a new record field, the content of which will be the value of the attribute. For more information, see the 'Additional Details...' section of the XMLReader controller service's documentation.
Parse XML Attributes parse_xml_attributes true - true - false When 'Schema Access Strategy' is 'Infer Schema' and this property is 'true' then XML attributes are parsed and added to the record as new fields. When the schema is inferred but this property is 'false', XML attributes and their values are ignored.
Expect Records as Array * record_format false - false - true - Use attribute 'xml.stream.is.array' This property defines whether the reader expects a FlowFile to consist of a single Record or a series of Records with a "wrapper element". Because XML does not provide for a way to read a series of XML documents from a stream directly, it is common to combine many XML documents by concatenating them and then wrapping the entire XML blob with a "wrapper element". This property dictates whether the reader expects a FlowFile to consist of a single Record or a series of Records with a "wrapper element" that will be ignored.
Schema Inference Cache schema-inference-cache Specifies a Schema Cache to use when inferring the schema. If not populated, the schema will be inferred each time. However, if a cache is specified, the cache will first be consulted and if the applicable schema can be found, it will be used instead of inferring the schema.
Display Name API Name Default Value Allowable Values Description
Character Set * Character Set UTF-8 The Character set to use when writing the data to the FlowFile
Date Format Date Format Specifies the format to use when reading/writing Date fields. If not specified, Date fields will be assumed to be number of milliseconds since epoch (Midnight, Jan 1, 1970 GMT). If specified, the value must match the Java java.time.format.DateTimeFormatter format (for example, MM/dd/yyyy for a two-digit month, followed by a two-digit day, followed by a four-digit year, all separated by '/' characters, as in 01/01/2017).
Schema Access Strategy * Schema Access Strategy inherit-record-schema - Inherit Record Schema - Use 'Schema Name' Property - Use 'Schema Text' Property Specifies how to obtain the schema that is to be used for interpreting the data.
Schema Branch Schema Branch Specifies the name of the branch to use when looking up the schema in the Schema Registry property. If the chosen Schema Registry does not support branching, this value will be ignored.
Schema Cache Schema Cache Specifies a Schema Cache to add the Record Schema to so that Record Readers can quickly lookup the schema.
Schema Name Schema Name $\{schema.name\} Specifies the name of the schema to lookup in the Schema Registry property
Schema Reference Reader * Schema Reference Reader Service implementation responsible for reading FlowFile attributes or content to determine the Schema Reference Identifier
Schema Reference Writer * Schema Reference Writer Service implementation responsible for writing FlowFile attributes or content header with Schema reference information
Schema Registry Schema Registry Specifies the Controller Service to use for the Schema Registry
Schema Text Schema Text $\{avro.schema\} The text of an Avro-formatted Schema
Schema Version Schema Version Specifies the version of the schema to lookup in the Schema Registry. If not specified then the latest version of the schema will be retrieved.
Schema Write Strategy * Schema Write Strategy no-schema - Do Not Write Schema - Set 'schema.name' Attribute - Set 'avro.schema' Attribute - Schema Reference Writer Specifies how the schema for a Record should be added to the data.
Time Format Time Format Specifies the format to use when reading/writing Time fields. If not specified, Time fields will be assumed to be number of milliseconds since epoch (Midnight, Jan 1, 1970 GMT). If specified, the value must match the Java java.time.format.DateTimeFormatter format (for example, HH:mm:ss for a two-digit hour in 24-hour format, followed by a two-digit minute, followed by a two-digit second, all separated by ':' characters, as in 18:04:15).
Timestamp Format Timestamp Format Specifies the format to use when reading/writing Timestamp fields. If not specified, Timestamp fields will be assumed to be number of milliseconds since epoch (Midnight, Jan 1, 1970 GMT). If specified, the value must match the Java java.time.format.DateTimeFormatter format (for example, MM/dd/yyyy HH:mm:ss for a two-digit month, followed by a two-digit day, followed by a four-digit year, all separated by '/' characters; and then followed by a two-digit hour in 24-hour format, followed by a two-digit minute, followed by a two-digit second, all separated by ':' characters, as in 01/01/2017 18:04:15).
Array Tag Name array_tag_name Name of the tag used by property "Wrap Elements of Arrays" to write arrays
Wrap Elements of Arrays * array_wrapping no-wrapping - Use Property as Wrapper - Use Property for Elements - No Wrapping Specifies how the writer wraps elements of fields of type array
Omit XML Declaration * omit_xml_declaration false - true - false Specifies whether or not to include XML declaration
Pretty Print XML * pretty_print_xml false - true - false Specifies whether or not the XML should be pretty printed
Name of Record Tag record_tag_name Specifies the name of the XML record tag wrapping the record fields. If this is not set, the writer will use the record name in the schema.
Name of Root Tag root_tag_name Specifies the name of the XML root tag wrapping the record set. This property has to be defined if the writer is supposed to write multiple records in a single FlowFile.
Suppress Null Values * suppress_nulls never-suppress - Never Suppress - Always Suppress - Suppress Missing Values Specifies how the writer should handle a null field
Display Name API Name Default Value Allowable Values Description
Allow Comments * Allow Comments false - true - false Whether to allow comments when parsing the YAML document
Date Format Date Format Specifies the format to use when reading/writing Date fields. If not specified, Date fields will be assumed to be number of milliseconds since epoch (Midnight, Jan 1, 1970 GMT). If specified, the value must match the Java java.time.format.DateTimeFormatter format (for example, MM/dd/yyyy for a two-digit month, followed by a two-digit day, followed by a four-digit year, all separated by '/' characters, as in 01/01/2017).
Max String Length * Max String Length 20 MB The maximum allowed length of a string value when parsing the YAML document
Schema Access Strategy * Schema Access Strategy infer-schema - Infer Schema - Use 'Schema Name' Property - Use 'Schema Text' Property - Schema Reference Reader Specifies how to obtain the schema that is to be used for interpreting the data.
Schema Branch Schema Branch Specifies the name of the branch to use when looking up the schema in the Schema Registry property. If the chosen Schema Registry does not support branching, this value will be ignored.
Schema Name Schema Name $\{schema.name\} Specifies the name of the schema to lookup in the Schema Registry property
Schema Reference Reader * Schema Reference Reader Service implementation responsible for reading FlowFile attributes or content to determine the Schema Reference Identifier
Schema Registry Schema Registry Specifies the Controller Service to use for the Schema Registry
Schema Text Schema Text $\{avro.schema\} The text of an Avro-formatted Schema
Schema Version Schema Version Specifies the version of the schema to lookup in the Schema Registry. If not specified then the latest version of the schema will be retrieved.
Time Format Time Format Specifies the format to use when reading/writing Time fields. If not specified, Time fields will be assumed to be number of milliseconds since epoch (Midnight, Jan 1, 1970 GMT). If specified, the value must match the Java java.time.format.DateTimeFormatter format (for example, HH:mm:ss for a two-digit hour in 24-hour format, followed by a two-digit minute, followed by a two-digit second, all separated by ':' characters, as in 18:04:15).
Timestamp Format Timestamp Format Specifies the format to use when reading/writing Timestamp fields. If not specified, Timestamp fields will be assumed to be number of milliseconds since epoch (Midnight, Jan 1, 1970 GMT). If specified, the value must match the Java java.time.format.DateTimeFormatter format (for example, MM/dd/yyyy HH:mm:ss for a two-digit month, followed by a two-digit day, followed by a four-digit year, all separated by '/' characters; and then followed by a two-digit hour in 24-hour format, followed by a two-digit minute, followed by a two-digit second, all separated by ':' characters, as in 01/01/2017 18:04:15).
Schema Application Strategy * schema-application-strategy SELECTED_PART - Whole JSON - Selected Part Specifies whether the schema is defined for the whole JSON or for the selected part starting from "Starting Field Name".
Schema Inference Cache schema-inference-cache Specifies a Schema Cache to use when inferring the schema. If not populated, the schema will be inferred each time. However, if a cache is specified, the cache will first be consulted and if the applicable schema can be found, it will be used instead of inferring the schema.
Starting Field Name starting-field-name Skips forward to the given nested field (array or object) to begin processing.
Starting Field Strategy * starting-field-strategy ROOT_NODE - Root Node - Nested Field Start processing from the root node or from a specified nested node.
Privilege Object Notes
CREATE AGENT Schema Required to create an agent.
USAGE Agent Required to query the agent to generate responses. The role also needs `USAGE` on the database and schema containing the agent, along with privileges on the objects used by the agent's tools. See [Additional privileges for tools](#label-cortex-agents-tool-privileges).
USAGE Warehouse Required on the user's default warehouse to run agent queries and tools.
MODIFY Agent Required to update the agent.
MONITOR Agent Required to view the agent's threads, logs, and traces.
OWNERSHIP Agent Automatically granted to the role that creates the agent. Can be transferred to another role with [GRANT OWNERSHIP](/sql-reference/sql/grant-ownership).
Privilege Object Notes
USAGE Cortex Search service Required to run the Cortex Search services configured on the agent. The role also needs `USAGE` on the database and schema containing the service.
USAGE Database, schema, table Required to access the objects referenced in the agent's semantic view.
USAGE Function or stored procedure Required to run a custom tool. Stored procedures run with owner's rights or caller's rights as defined on the procedure. See [Understanding caller's rights and owner's rights stored procedures](/developer-guide/stored-procedure/stored-procedures-rights).
USAGE Referenced agent Required to expand an `agent_toolset` reference. Silently skipped if missing. See [Agent toolsets](/user-guide/snowflake-cortex/cortex-agents-toolsets).